deep-read-summarize 0.6.0 → 0.6.2
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/CHANGELOG.md +41 -0
- package/README.en.md +92 -341
- package/README.md +94 -342
- package/docs/RELEASE.md +3 -1
- package/lib/quality.js +53 -2
- package/lib/workflow-script.txt +12 -6
- package/package.json +1 -1
- package/skills/deep-read-summarize/SKILL.md +2 -2
- package/workflow.js +2 -1
package/CHANGELOG.md
CHANGED
|
@@ -5,6 +5,47 @@ The format is based on [Keep a Changelog](https://keepachangelog.com/).
|
|
|
5
5
|
|
|
6
6
|
## [Unreleased]
|
|
7
7
|
|
|
8
|
+
## [0.6.2] — 2026-11-11
|
|
9
|
+
|
|
10
|
+
修复成稿包含前言或外层 Markdown 围栏时,笔记被误判为格式、篇幅和引用不合格的问题。
|
|
11
|
+
|
|
12
|
+
### Fixed
|
|
13
|
+
|
|
14
|
+
- **成稿包装导致质量误报**:识别唯一、明确的完整 Markdown 笔记,先移除其外层围栏或前言,再对同一份正文执行格式、篇幅和独立原文核验并返回;普通代码块仍不计入正文。无法明确提取时保留原始回复并照常报告质量问题。
|
|
15
|
+
- 可选的 `draftContext` 记录提取方式以及模型在笔记前后附带的说明;主代理向用户说明这些额外文字,它们没有通过笔记的原文核验。
|
|
16
|
+
|
|
17
|
+
### Verification
|
|
18
|
+
|
|
19
|
+
- 回归测试覆盖普通成稿、围栏包装、修订稿、嵌套代码块及提取有歧义的情况。使用 DSH 真实模型精读论文,并在成稿后人为添加围栏,确认格式和篇幅检查不再受外层包装影响;该次笔记的引用核验未通过,真实质量问题仍会照常报告。
|
|
20
|
+
|
|
21
|
+
### Compatibility
|
|
22
|
+
|
|
23
|
+
- 升级无需更改配置;只有识别到可明确提取的笔记时才移除包装,额外文字通过可选的 `draftContext` 返回。
|
|
24
|
+
|
|
25
|
+
### 贡献者与致谢
|
|
26
|
+
|
|
27
|
+
- 感谢 @qneko 报告和复现成稿外层 Markdown 围栏造成的质量误报([Issue #9](https://github.com/PensiveFei/deep-read-summarize/issues/9))。
|
|
28
|
+
|
|
29
|
+
## [0.6.1] — 2026-11-10
|
|
30
|
+
|
|
31
|
+
修复普通执行路径的结果序列化错误,避免已生成的精读笔记在返回宿主时被丢弃。
|
|
32
|
+
|
|
33
|
+
### Fixed
|
|
34
|
+
|
|
35
|
+
- 无缓存复用的成功分支不再返回 `__cacheReads: undefined`:该字段无法通过宿主 workflow 引擎的 JSON 序列化检查(「is not JSON data」),会连已成稿的 `note` 一起被整体丢弃。改为按需展开(仅缓存复用时携带),普通路径的结果不再含内部缓存字段;缓存复用路径返回数组不变。回归测试见 `tests/workflow-regressions.test.js`。
|
|
36
|
+
|
|
37
|
+
### Verification
|
|
38
|
+
|
|
39
|
+
- PR 的七项 CI 检查通过,覆盖 Node.js 18、20、22、24 和 Windows、macOS、Linux。使用 DSH 0.2.2-rc.1 的 workflow 执行器与模拟代理复现原错误,并验证修复后普通路径和缓存路径的返回结果;未进行真实模型端到端调用。
|
|
40
|
+
|
|
41
|
+
### Compatibility
|
|
42
|
+
|
|
43
|
+
- 升级无需更改配置;缓存复用路径保持原有行为。
|
|
44
|
+
|
|
45
|
+
### 贡献者与致谢
|
|
46
|
+
|
|
47
|
+
- 感谢 @Zyx-A 报告、定位并修复结果序列化问题,以及补充回归测试([PR #8](https://github.com/PensiveFei/deep-read-summarize/pull/8))。
|
|
48
|
+
|
|
8
49
|
## [0.6.0] — 2026-11-05
|
|
9
50
|
|
|
10
51
|
新增可配置并发、字符均衡分块与可选的并行原文核验和跨次精读缓存,保留原有默认核验路径。
|
package/README.en.md
CHANGED
|
@@ -7,403 +7,154 @@
|
|
|
7
7
|
[](https://github.com/PensiveFei/deep-read-summarize/actions/workflows/ci.yml)
|
|
8
8
|
[](https://www.npmjs.com/package/deep-read-summarize)
|
|
9
9
|
|
|
10
|
-
|
|
10
|
+
Turn a paper, book, video, or web page into a **Markdown reading note you can keep, edit, and check against the source**.
|
|
11
11
|
|
|
12
|
-
|
|
12
|
+
This third-party plugin runs in [DeepSeek Harness (DSH)](https://github.com/deepseek-ai/deepseek-harness). It attempts to retrieve the source text, reads long material in chunks, and combines the results into a structured note with YAML frontmatter. You can use the note in Obsidian, Logseq, or another Markdown tool.
|
|
13
13
|
|
|
14
|
-
|
|
14
|
+
[See real notes](#see-the-notes) · [Get started](#get-started) · [Quality and limitations](#quality-and-limitations) · [Common options](#common-options)
|
|
15
15
|
|
|
16
|
-
|
|
16
|
+
> AI-generated notes can omit or misinterpret information. Use them as a starting point for reading, and check important claims and quotations against the source.
|
|
17
17
|
|
|
18
|
-
|
|
18
|
+
## See the notes
|
|
19
19
|
|
|
20
|
-
|
|
20
|
+
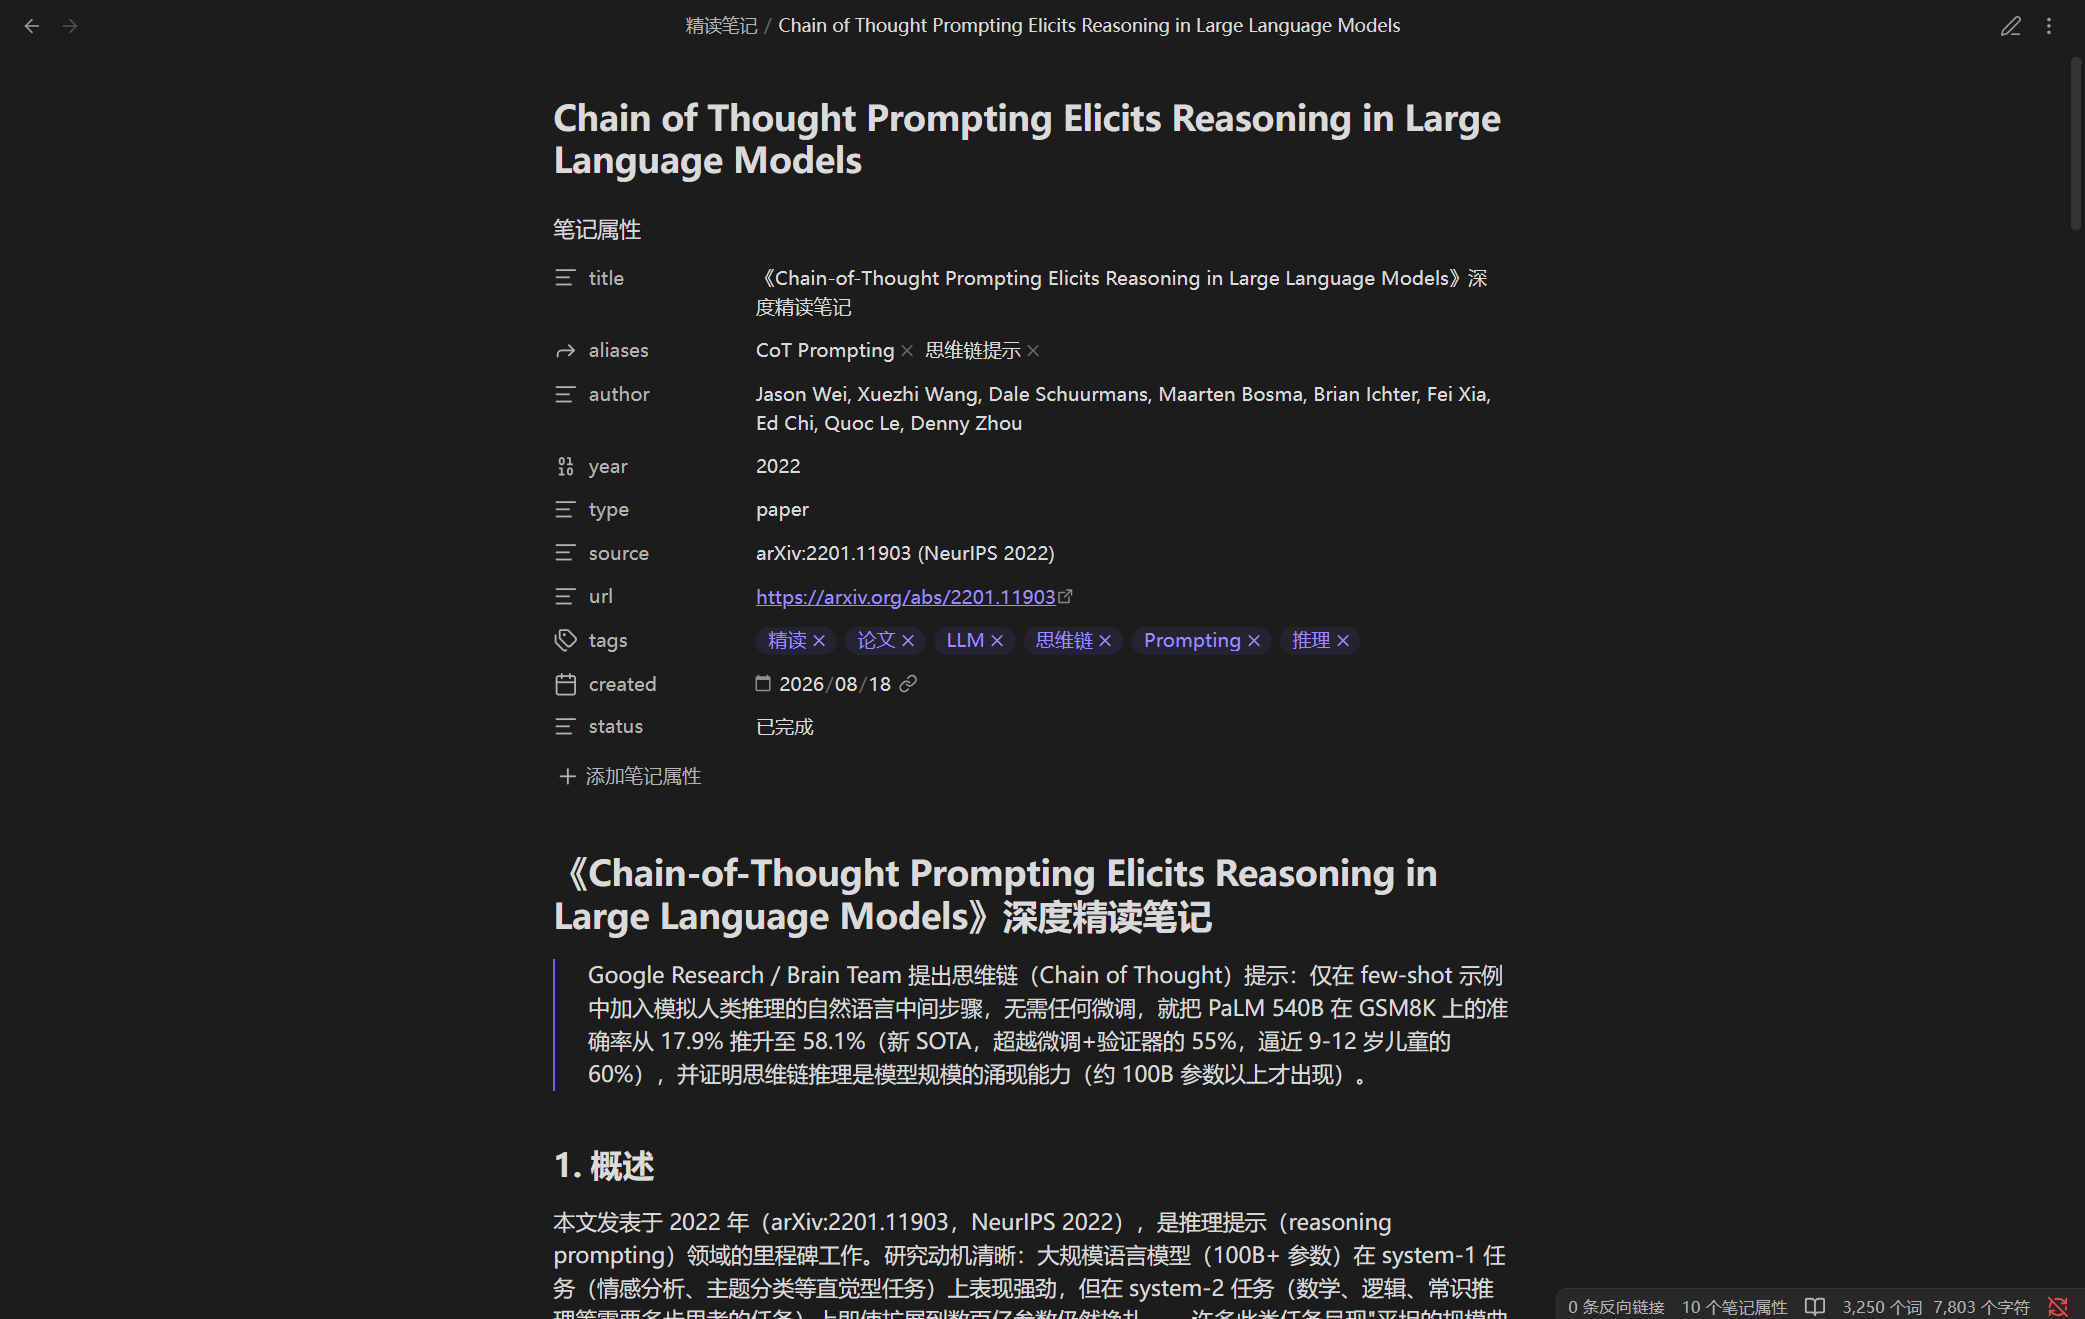
- 📄 [Paper: Emotional Intelligence of Large Language Models](https://github.com/PensiveFei/deep-read-summarize/blob/main/examples/emotional-intelligence.md)
|
|
21
|
+
- 📄 [Paper: Chain-of-Thought Prompting](https://github.com/PensiveFei/deep-read-summarize/blob/main/examples/chain-of-thought.md)
|
|
22
|
+
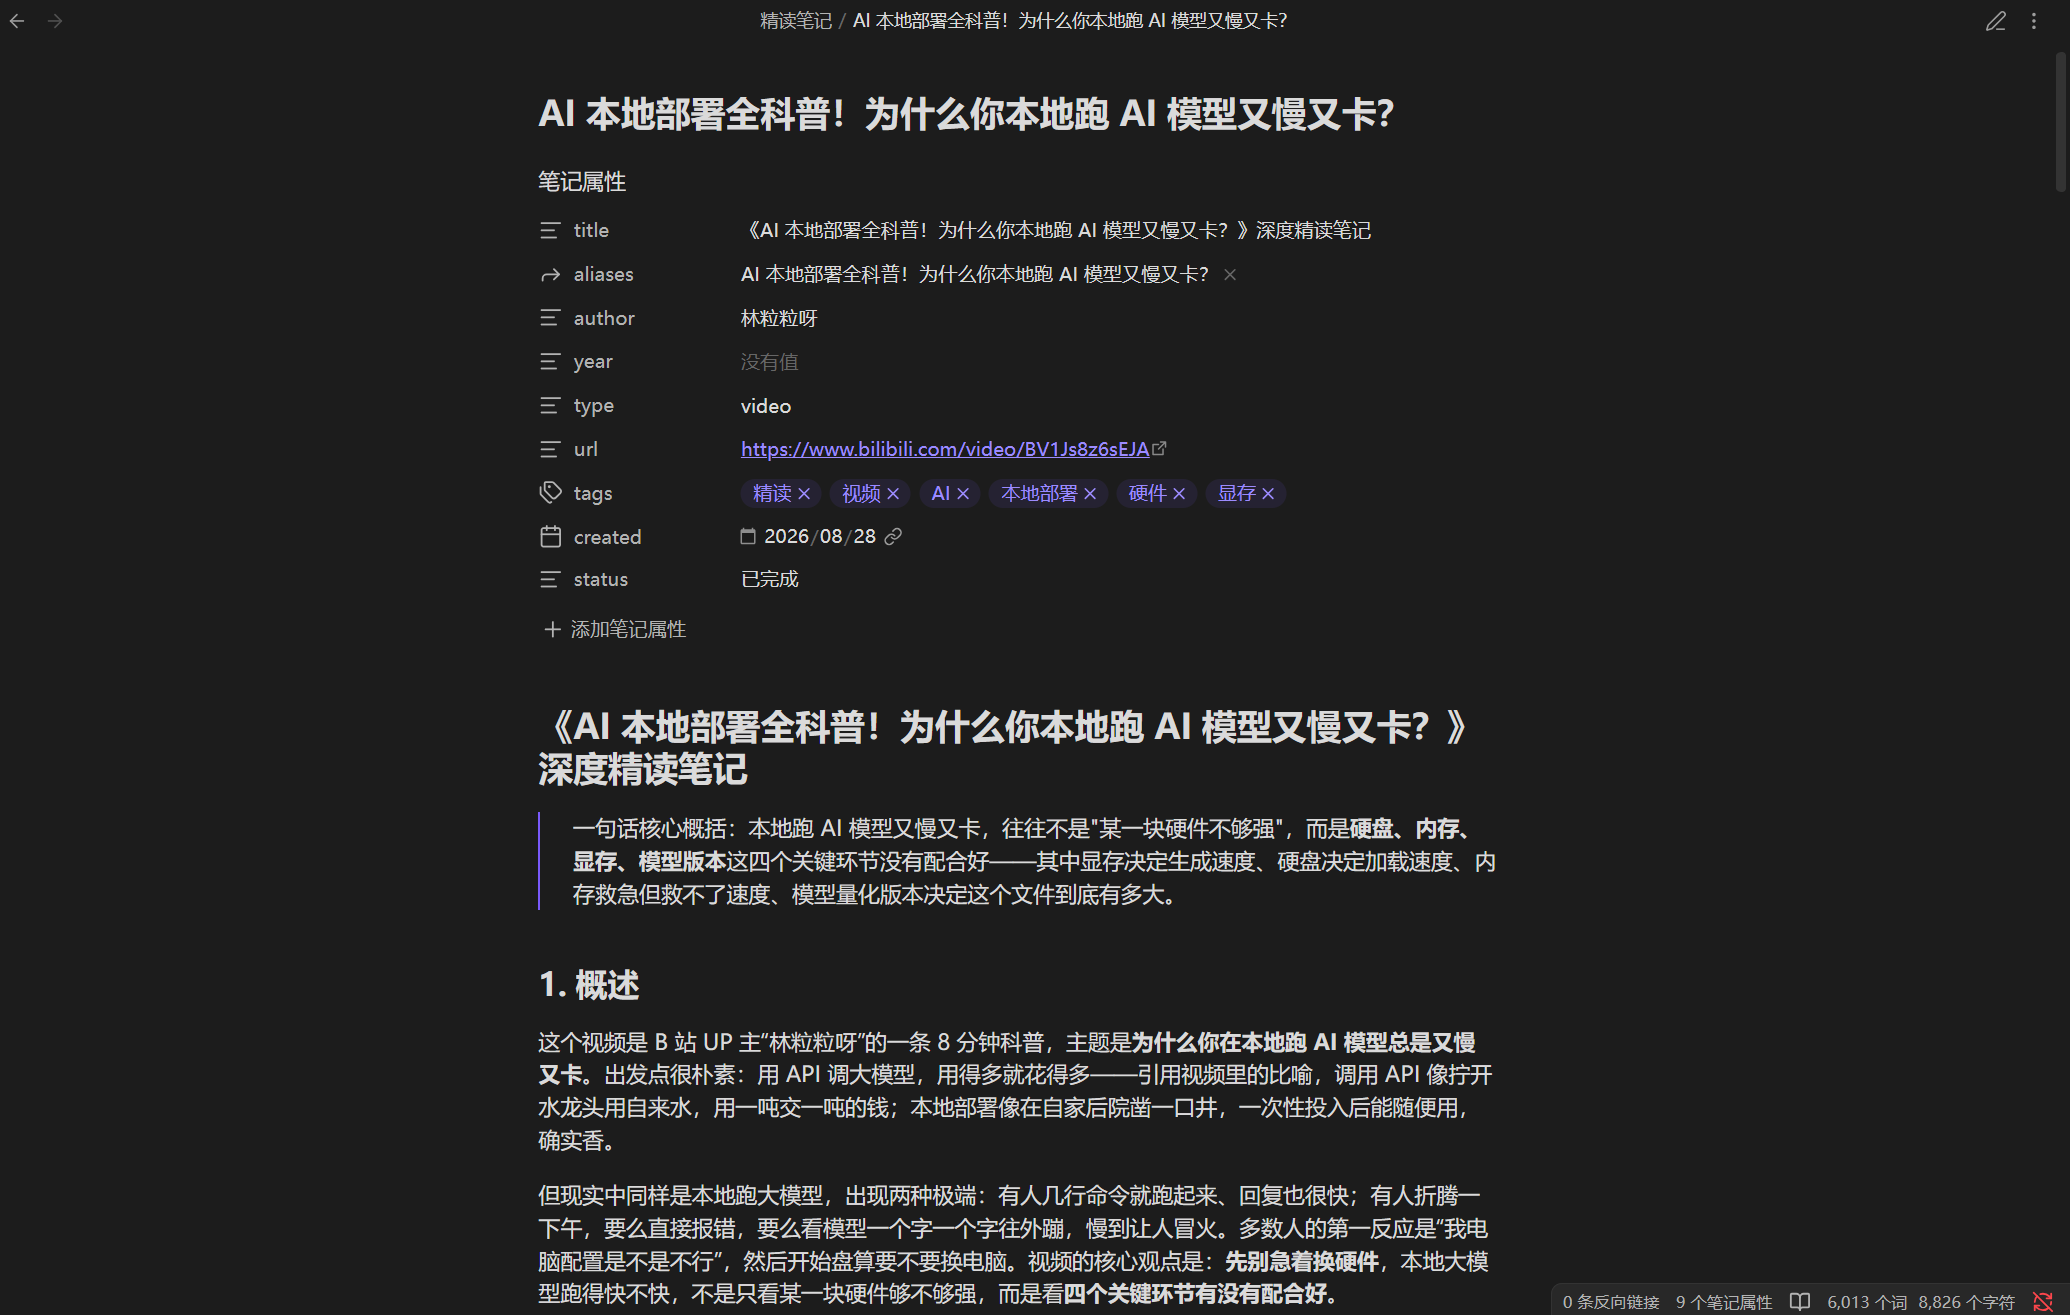
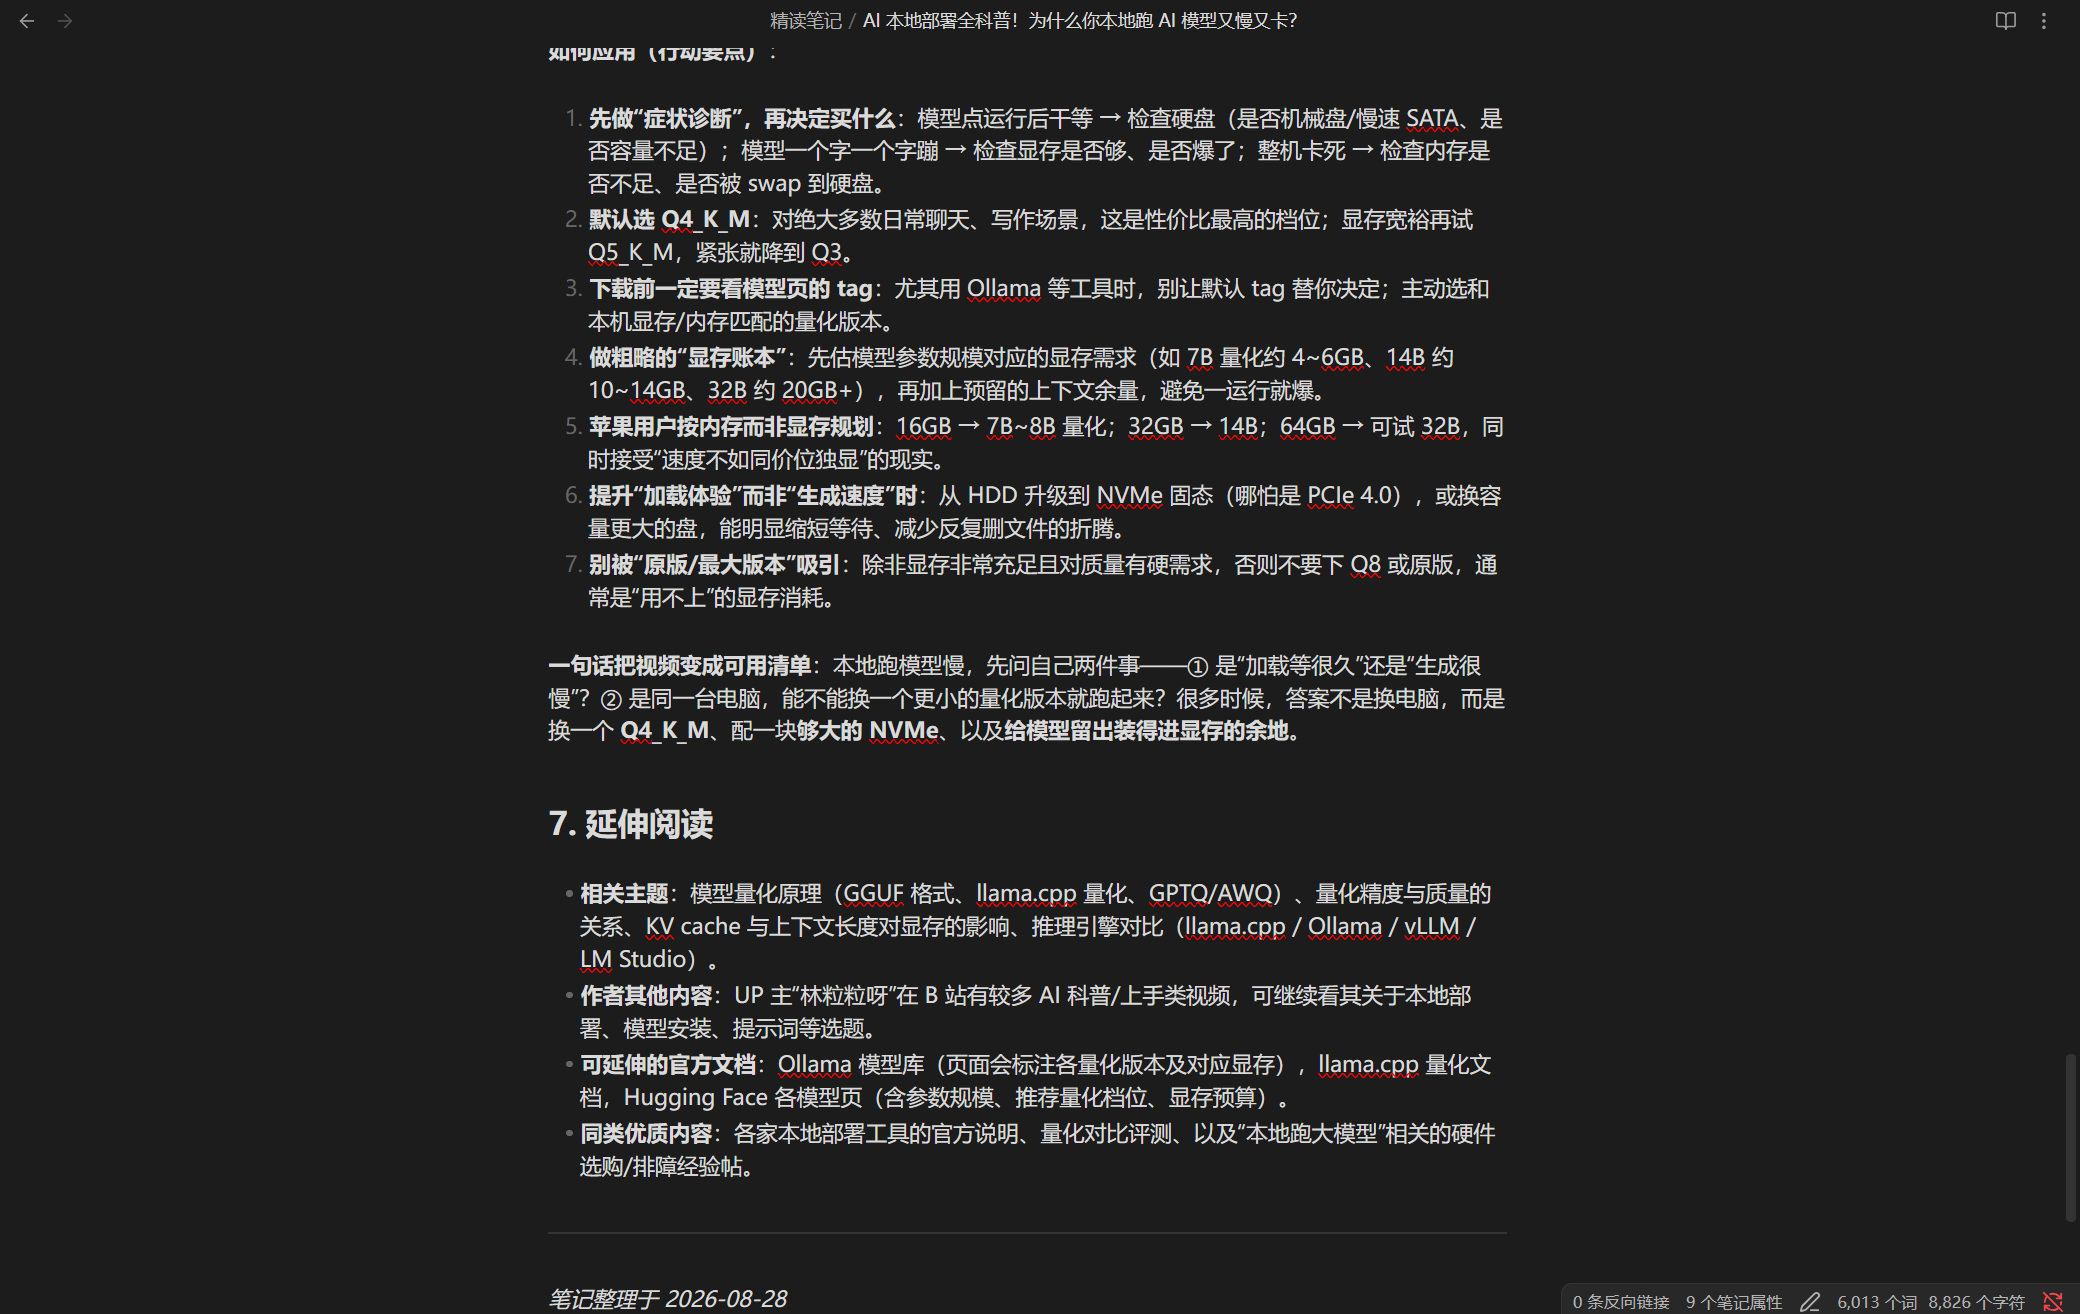
- 🎬 [Video: Andrej Karpathy's introduction to LLMs](https://github.com/PensiveFei/deep-read-summarize/blob/main/examples/intro-to-llms-video.md)
|
|
21
23
|
|
|
22
|
-
|
|
24
|
+
These are historical notes supplied by the maintainer, in Chinese. The paper notes have records of early project runs; how the video note was generated has not been confirmed. Their model, project version, and runtime were not recorded, so they are not performance claims for the current release. Some quotations and timestamps have been spot-checked, and edits to the public copies are documented in the [examples guide](https://github.com/PensiveFei/deep-read-summarize/blob/main/examples/README.md).
|
|
23
25
|
|
|
24
|
-
|
|
25
|
-
|
|
26
|
-
## What it looks like
|
|
27
|
-
|
|
28
|
-
(Images use absolute GitHub URLs so they render on npm too; the PNGs ship with the repository, not inside the npm package.)
|
|
29
|
-
|
|
30
|
-
| Deep-read paper note | Video note metadata |
|
|
31
|
-
| --- | --- |
|
|
32
|
-
|  |  |
|
|
33
|
-
|
|
34
|
-
| Video note action items | In-chat digest |
|
|
35
|
-
| --- | --- |
|
|
36
|
-
|  |  |
|
|
37
|
-
|
|
38
|
-
---
|
|
26
|
+

|
|
39
27
|
|
|
40
28
|
## What it does
|
|
41
29
|
|
|
42
|
-
|
|
43
|
-
|
|
44
|
-
|
|
45
|
-
|
|
46
|
-
|
|
47
|
-
|
|
48
|
-
- Output is **standard Markdown + YAML frontmatter**: the body is plain CommonMark (no wikilinks, no callouts), so Obsidian (with Dataview), Logseq, Jekyll / Hugo / Astro content folders and any Markdown editor can consume it directly
|
|
49
|
-
|
|
50
|
-
---
|
|
51
|
-
|
|
52
|
-
## Structure
|
|
53
|
-
|
|
54
|
-
```
|
|
55
|
-
Input (link or file path)
|
|
56
|
-
│
|
|
57
|
-
▼
|
|
58
|
-
Parser registry ── book / paper / video / web
|
|
59
|
-
│
|
|
60
|
-
▼
|
|
61
|
-
Wave 1 Fetch content → write temp file → build chunk plan
|
|
62
|
-
│
|
|
63
|
-
▼
|
|
64
|
-
Wave 2 N sub-agents deep-read chunks in parallel (Map)
|
|
65
|
-
│
|
|
66
|
-
▼
|
|
67
|
-
Wave 3 Merge draft + quality check (Reduce)
|
|
68
|
-
│
|
|
69
|
-
▼
|
|
70
|
-
Markdown note
|
|
71
|
-
```
|
|
72
|
-
|
|
73
|
-
Three waves, normally N+3 sub-agent calls (fetch, N chunk reads, draft, and quality check). In `auto` mode, ambiguous PDFs, unfamiliar web pages, and text inputs require one additional lightweight classification call. An explicit `type` skips classification.
|
|
74
|
-
|
|
75
|
-
`auto` routes recognized video links, arXiv paper links, and ebook extensions directly to their parsers; columns, channels, and help pages on those sites still require classification. PDFs are classified as books or papers from their content. Failed classification returns `stage: "detect"` and asks for an explicit type. `options.tempDir` is a temporary root: each call creates its own `run-*` subdirectory, keeping fetched text, audio, and transcripts separate from other tasks.
|
|
76
|
-
|
|
77
|
-
Chunk plans are sorted, duplicate ranges trimmed, and gaps filled. Plans above `maxChunks` merge adjacent ranges instead of discarding the document tail. The fetch agent runs a bundled helper to propose character-balanced whole-line boundaries from the saved source, preferring nearby paragraph boundaries when balance remains close. Missing or invalid results fall back to line balancing. Character counts are a workload approximation, not token counts, and a single long line is not split. The returned `coverageComplete` indicates coverage of all declared lines based on a valid `totalLines`; without a line count, known ranges are retained, `qualityPassed` is set to `false`, and the coverage uncertainty is reported.
|
|
78
|
-
|
|
79
|
-
Quality checks combine code and source review. Code validates the supplied scalar/list frontmatter template, required sections, and length (CJK characters plus other words, excluding metadata, code blocks, HTML comments, and link URLs). A separate reviewer reads the current source file and returns per-chunk excerpts and line-bound evidence for verbatim quotations in section 4. A bare `pass: true` cannot override these checks. `qualityChecks` exposes the gates, and `qualityEvidence` exposes the source path and evidence. Source authenticity still depends on the reviewer's actual source reading; uncertainty fails the gate. Empty, rejected, or structurally degraded repairs retain the preceding usable note.
|
|
80
|
-
|
|
81
|
-
Direct workflow options are strict: `minWords` is an integer in 1–100000, `maxChunks` is a positive integer (values above 12 are capped), `readConcurrency` is an integer in 1–12, and `maxRetries` is an integer in 0–3. Invalid values and unknown keys fail before work begins. Plugin profile configuration instead warns per invalid field and uses its default, preserving host startup.
|
|
82
|
-
|
|
83
|
-
```
|
|
84
|
-
parsers/ Parsers for each input type, dispatched by type
|
|
85
|
-
book.js Books: PDF/EPUB/MOBI text extraction, chapter chunking
|
|
86
|
-
paper.js Papers: arXiv/PDF/HTML structure detection
|
|
87
|
-
video.js Video: full transcript (subtitles first; auto-transcribe via scripts/transcribe.js when none)
|
|
88
|
-
web.js Web pages: main-text extraction
|
|
89
|
-
index.js Registry: parser discovery and fallback
|
|
90
|
-
schemas/ JSON Schema for the output contract (injected into the script by workflow.js - single source of truth)
|
|
91
|
-
scripts/ lint (incl. line-ending/whitespace hygiene), security checks, cross-platform transcription bootstrap
|
|
92
|
-
lib/ Small standalone helpers
|
|
93
|
-
cache.js input fingerprint and idempotency records (for callers driving the workflow themselves -- the
|
|
94
|
-
workflow sandbox has no filesystem, so it cannot use this)
|
|
95
|
-
workflow-script.txt the workflow script body (plain text: read and edit it directly, no escaping involved)
|
|
96
|
-
tests/ tests and validation scripts (**not published to npm**, repo only)
|
|
97
|
-
workflow.js the workflow meta and assembly logic (parser inlining, schema injection)
|
|
98
|
-
```
|
|
99
|
-
|
|
100
|
-
> The script body lives in `lib/workflow-script.txt` on purpose: this file was corrupted twice by "escaping on top of escaping". It is plain text now, so reading and editing it needs no encoding step.
|
|
101
|
-
|
|
102
|
-
To override or add a parser, use the package's `custom-parsers/` directory (included in npm packaging), or set the plugin-level `config.customParsersDir` to your own directory. This is not a workflow option. Per-profile directories remain isolated, and rebuilding skill content uses the current registry, including programmatic registrations. Parsers expose `name`, `types`, and `buildPrompt(input, opts)`; registered types are inlined into the workflow and its schema.
|
|
103
|
-
|
|
104
|
-
File parsers bundle their CommonJS modules and literal relative `.js`, `.cjs`, and `.json` dependencies, preserving module constants, helpers, method shorthand, and cycles. Acorn parses JavaScript during script construction and is installed automatically by npm; it does not run in the workflow sandbox. Node built-ins, external packages, and dynamic `require`/`import` are unsupported in sandbox parsers and fail at build time. Programmatically registered functions must be self-contained; use a file parser for module closures.
|
|
105
|
-
|
|
106
|
-
---
|
|
107
|
-
|
|
108
|
-
## Platform support
|
|
109
|
-
|
|
110
|
-
**Windows / macOS / Linux are equally supported** (since 0.3.9). The plugin itself only needs Node (which DSH ships); the extra tools each input type may use are installed per platform:
|
|
111
|
-
|
|
112
|
-
- **Book / paper PDF** → `pdftotext` (poppler): macOS `brew install poppler`, Windows `winget install poppler`, Debian/Ubuntu `apt install poppler-utils`
|
|
113
|
-
- **Bilibili subtitles / audio** → `curl`: already present on Windows 10+, macOS and Linux — nothing to install
|
|
114
|
-
- **YouTube subtitles** → `yt-dlp`: macOS `brew install yt-dlp`, Windows `winget install yt-dlp.yt-dlp`, any platform `pip install -U yt-dlp`
|
|
115
|
-
- **Transcription when there are no subtitles** → `uv` (the script bootstraps a Python 3.12 env and installs faster-whisper): macOS `brew install uv`, Windows `winget install astral-sh.uv`, or the official installer script on macOS / Linux (hand `curl -LsSf https://astral.sh/uv/install.sh` to `sh`)
|
|
116
|
-
|
|
117
|
-
Further notes:
|
|
118
|
-
|
|
119
|
-
- Transcription is the **only** part that needs an extra toolchain, and all three platforms share one Node script and one command: `node scripts/transcribe.js --audio <file> --out <txt>`.
|
|
120
|
-
- Transcription runs on **CPU** by default, so Apple Silicon / Intel Macs and Linux need no CUDA; GPU support needs a CUDA runtime and `options.device: "auto"` will try it and fall back to CPU on failure.
|
|
121
|
-
- Cache location per platform: macOS `~/Library/Caches/deep-read-summarize`, Linux `$XDG_CACHE_HOME/deep-read-summarize`, Windows `%LOCALAPPDATA%\deep-read-summarize`.
|
|
122
|
-
- A **full transcription has been run successfully on real macOS hardware** (since 0.3.12): `uv` bootstraps Python 3.12, installs faster-whisper, downloads the model and writes the transcript — exit code 0. CI's `macos-latest` job separately covers platform path resolution and the whole test suite. If you hit an error on a Mac, please open an issue.
|
|
123
|
-
|
|
124
|
-
---
|
|
125
|
-
## Installation (DSH plugin)
|
|
126
|
-
|
|
127
|
-
deep-read-summarize is a DSH plugin installable via npm or locally:
|
|
128
|
-
|
|
129
|
-
```bash
|
|
130
|
-
# npm install (includes Acorn for parser construction)
|
|
131
|
-
npm install deep-read-summarize
|
|
132
|
-
|
|
133
|
-
# or local install (dsh profile directory)
|
|
134
|
-
pnpm add ./deep-read-summarize-0.3.10.tgz
|
|
135
|
-
# then append to the dsh config's dsh.profile.bundles:
|
|
136
|
-
# - deep-read-summarize
|
|
137
|
-
# restart dsh web (POST /dsh-market/restart)
|
|
138
|
-
```
|
|
139
|
-
|
|
140
|
-
After installation it registers:
|
|
141
|
-
- the `deep_read_summarize` tool when the host provides tools and workflowEngine services; models send only input/type/options
|
|
142
|
-
- the `deep-read-summarize` workflow definition (meta + script), with the existing workflow-tool route retained for older hosts
|
|
143
|
-
- the `deep-read-summarize` skill (`skills/deep-read-summarize/SKILL.md`)
|
|
144
|
-
- four parsers (`parsers/`) and JSON Schemas (`schemas/`)
|
|
145
|
-
|
|
146
|
-
---
|
|
147
|
-
## Quick start (~5 minutes)
|
|
30
|
+
| You provide | The workflow attempts to retrieve | You receive |
|
|
31
|
+
| --- | --- | --- |
|
|
32
|
+
| A book: PDF, EPUB, MOBI | Text and chapters | A reading note organized by topic |
|
|
33
|
+
| A paper: arXiv, PDF, HTML | Paper text and structure | Research question, method, findings, and limitations |
|
|
34
|
+
| A video link | Subtitles first; local transcription when needed and available | A breakdown based on the text obtained |
|
|
35
|
+
| A web page | Page text | Key points, concepts, and source information |
|
|
148
36
|
|
|
149
|
-
|
|
37
|
+
Extraction depends on source accessibility, available tools, the model, and host permissions. Scanned PDFs generally need OCR first; the workflow does not provide automatic OCR. Complex formulas, diagrams, and poor-quality captions or audio may also need manual handling.
|
|
150
38
|
|
|
151
|
-
|
|
152
|
-
# Option A: npm install directly (no clone needed)
|
|
153
|
-
npm install deep-read-summarize
|
|
39
|
+
Notes typically include an overview, structural breakdown, glossary, key quotations, critical analysis, and applications. Their contents are model-generated and may differ between inputs and configurations.
|
|
154
40
|
|
|
155
|
-
|
|
156
|
-
git clone https://github.com/PensiveFei/deep-read-summarize.git
|
|
157
|
-
cd deep-read-summarize
|
|
158
|
-
npm ci # install locked dependencies
|
|
159
|
-
```
|
|
41
|
+
## Get started
|
|
160
42
|
|
|
161
|
-
###
|
|
43
|
+
### 1. Install the plugin
|
|
162
44
|
|
|
163
|
-
|
|
164
|
-
node -e "console.log(require('deep-read-summarize').name)"
|
|
165
|
-
```
|
|
166
|
-
|
|
167
|
-
Seeing `deep-read-summarize` confirms the package loads. Source checkouts can additionally run `npm test` and `npm run test:node`; tests are not included in the npm package.
|
|
168
|
-
|
|
169
|
-
### 3. Feed a demo file with one command
|
|
45
|
+
Install and start DSH Desktop once to initialize its desktop profile. **Quit the application completely**, then use the DSH command bundled with Desktop to install the plugin:
|
|
170
46
|
|
|
171
47
|
```bash
|
|
172
|
-
|
|
48
|
+
dsh plugin --profile desktop add deep-read-summarize
|
|
173
49
|
```
|
|
174
50
|
|
|
175
|
-
|
|
51
|
+
Reopen DSH Desktop when installation finishes. The bundled command may not be on your system PATH; use `resources/runtime/cli/bin/dsh` inside the installation directory (`dsh.cmd` on Windows). Interfaces and commands can change between host versions; see the [official DSH Desktop instructions](https://github.com/deepseek-ai/deepseek-harness/blob/master/apps/desktop/README.md). Do not run `npm install` or `npm update` directly inside a DSH profile directory.
|
|
176
52
|
|
|
177
|
-
|
|
178
|
-
meta: deep-read-summarize
|
|
179
|
-
parsers: book, paper, video, web
|
|
180
|
-
```
|
|
53
|
+
Deep reading also requires a working model and suitable permissions in DSH. Some sources need additional tools: PDF extraction may need `pdftotext`, YouTube captions may need `yt-dlp`, and local transcription of a video without subtitles may require `uv` and a transcription model.
|
|
181
54
|
|
|
182
|
-
###
|
|
55
|
+
### 2. Request a reading note
|
|
183
56
|
|
|
184
|
-
|
|
57
|
+
In a DSH conversation, for example:
|
|
185
58
|
|
|
186
|
-
```
|
|
187
|
-
|
|
59
|
+
```text
|
|
60
|
+
Please read this paper in depth and save a Markdown reading note:
|
|
61
|
+
https://arxiv.org/abs/2307.09042
|
|
188
62
|
```
|
|
189
63
|
|
|
190
|
-
|
|
64
|
+
You can also provide a local file, web page, or video link. If needed, specify an output location, sections to retain, or whether you want timestamps.
|
|
191
65
|
|
|
192
|
-
|
|
66
|
+
Hosts with plugin-tool support register `deep_read_summarize`; older hosts use the bundled skill and workflow entry point. The tool returns the note and a suggested path; **the main agent must write the file**. Check that the file was saved and whether the result reports gaps or quality issues.
|
|
193
67
|
|
|
194
|
-
|
|
195
|
-
## Usage
|
|
68
|
+
When an identifiable note is extracted from a wrapper, the optional `draftContext` field records the extraction and retains any surrounding text. That text is not part of the note reviewed against the source.
|
|
196
69
|
|
|
197
|
-
|
|
70
|
+
<details>
|
|
71
|
+
<summary>Direct tool-call example</summary>
|
|
198
72
|
|
|
199
|
-
```
|
|
73
|
+
```json
|
|
200
74
|
{
|
|
201
|
-
"input": "https://arxiv.org/abs/2307.09042",
|
|
202
|
-
"type": "
|
|
75
|
+
"input": "https://arxiv.org/abs/2307.09042",
|
|
76
|
+
"type": "paper",
|
|
203
77
|
"options": {
|
|
204
|
-
"
|
|
205
|
-
"
|
|
206
|
-
"maxChunks": 4, // chunk limit, 1-12
|
|
207
|
-
"readConcurrency": 3, // concurrent chunk reads and reviews, 1-12
|
|
208
|
-
"parallelQuality": false, // opt in to parallel source review; default retains original review
|
|
209
|
-
"readCache": false, // plugin tool only: opt in to cross-run read caching
|
|
210
|
-
"readCacheIdentity": "", // required when enabled: provider, pinned model version and settings
|
|
211
|
-
"transcribe": true, // video: auto local transcription (faster-whisper) when no subtitles; false skips it — see Video
|
|
212
|
-
"whisperModel": "small", // video ASR tier: small | base | medium
|
|
213
|
-
"language": "zh", // video ASR language: use "en" for English-only videos
|
|
214
|
-
"device": "cpu", // ASR device: cpu (default) | auto | cuda; auto/cuda needs a CUDA runtime and falls back to cpu
|
|
215
|
-
"cpuThreads": 0, // 0 keeps library defaults; 1-64 allows hardware-specific tuning
|
|
216
|
-
"transcriptCache": true, // reuse a verified local transcript for matching audio and settings
|
|
217
|
-
"maxRetries": 0, // quality-check retries (default 0 = no retry; retrying is noticeably slower)
|
|
218
|
-
"frontmatter": "obsidian", // key set: obsidian (default, for Dataview) | generic (drops the keys Hugo reserves) | minimal
|
|
219
|
-
"requireCitations": true, // whether key conclusions must carry citations
|
|
220
|
-
"includeTimestamps": false,
|
|
221
|
-
"outputDir": "./output", // note output directory (can point at your Obsidian vault or a static-site content folder)
|
|
222
|
-
"tempDir": "./.tmp" // temp file directory
|
|
78
|
+
"maxChunks": 4,
|
|
79
|
+
"outputDir": "./output"
|
|
223
80
|
}
|
|
224
81
|
}
|
|
225
82
|
```
|
|
226
83
|
|
|
227
|
-
|
|
84
|
+
`type` can be `auto`, `book`, `paper`, `video`, or `web`. Specifying it can skip classification for ambiguous inputs. The tool-call interface depends on the DSH host; asking in conversation is also supported.
|
|
228
85
|
|
|
229
|
-
|
|
230
|
-
|------|-------|
|
|
231
|
-
| Paper | `https://arxiv.org/abs/2307.09042` |
|
|
232
|
-
| Book | local path, e.g. `~/books/xxx.pdf` |
|
|
233
|
-
| Video | `https://youtube.com/watch?v=xxx` |
|
|
234
|
-
| Web page | `https://example.com/article` |
|
|
86
|
+
</details>
|
|
235
87
|
|
|
236
|
-
|
|
88
|
+
## Quality and limitations
|
|
237
89
|
|
|
238
|
-
|
|
90
|
+
The workflow normalizes chunk ranges and checks coverage of known source line numbers. After drafting, code checks format and length, and an independent review agent reads the obtained text to check chunk coverage and key quotations. Results are available through `qualityPassed`, `qualityChecks`, and `qualityEvidence`.
|
|
239
91
|
|
|
240
|
-
|
|
92
|
+
These checks have limits:
|
|
241
93
|
|
|
242
|
-
|
|
243
|
-
|
|
244
|
-
|
|
245
|
-
|
|
246
|
-
| `author` / `year` | yes | yes | -- |
|
|
247
|
-
| `type` | yes | -- | -- |
|
|
248
|
-
| `docType` | -- | yes | -- |
|
|
249
|
-
| `url` | yes | -- | -- |
|
|
250
|
-
| `sourceUrl` | -- | yes | yes |
|
|
251
|
-
| `tags` | yes | yes | yes |
|
|
252
|
-
| `created` | yes | -- | -- |
|
|
253
|
-
| `date` | -- | yes | yes |
|
|
254
|
-
| `status` | yes | yes | -- |
|
|
94
|
+
- **`qualityPassed` does not prove factual accuracy.** Coverage and source authenticity still depend on the reviewing agent reading and evaluating the source. Check important claims, numbers, and quotations yourself.
|
|
95
|
+
- **Retrieving the full text does not guarantee understanding it.** Complex tables, formulas, images, or extraction errors can affect the result; incomplete sources or failed chunks are reported as gaps.
|
|
96
|
+
- **Captions and transcripts can differ from audio.** Automatic captions and speech recognition can omit words or mishear numbers and negations; checking the note against a transcript does not prove the transcript is accurate.
|
|
97
|
+
- **Video timestamps cannot be inferred reliably.** Locations depend on whether the obtained subtitles or transcript contain time information.
|
|
255
98
|
|
|
256
|
-
|
|
99
|
+
## Common options
|
|
257
100
|
|
|
258
|
-
|
|
259
|
-
|
|
260
|
-
|
|
261
|
-
|
|
262
|
-
|
|
263
|
-
|
|
264
|
-
|
|
265
|
-
|
|
266
|
-
|
|
267
|
-
|
|
268
|
-
|
|
269
|
-
|
|
270
|
-
|
|
271
|
-
|
|
272
|
-
|
|
273
|
-
|
|
274
|
-
|
|
275
|
-
`options.transcribe`: **default `true`** (auto-transcribe when no subtitles); set `false` to skip transcription (use subtitles/desc or degrade).
|
|
276
|
-
|
|
277
|
-
**Transcription toolchain**: `uv` provisions **Python 3.12** and installs **`faster-whisper==1.2.1`** from the Tsinghua mirror; models use `HF_ENDPOINT=https://hf-mirror.com` and the local cache. Healthy cached environments run directly without requiring uv or a separate Python import probe. Actual interpreter and dependency versions are recorded in the cache's `runtime.json`; Python patch releases, uv, and all transitive dependencies are not fully pinned. PyAV decodes audio without a separate ffmpeg. All three platforms use `node scripts/transcribe.js --audio <file> --out <txt>`. CPU is the default; `options.device: "auto"` can try a supplied CUDA runtime and falls back to CPU. Cache roots are `%LOCALAPPDATA%\deep-read-summarize` on Windows, `~/Library/Caches/deep-read-summarize` on macOS, and `$XDG_CACHE_HOME/deep-read-summarize` on Linux (falling back to `~/.cache`). Python provisioning tries a mirror and then direct GitHub; `DRS_UV_PYTHON_MIRROR` overrides it, with an empty value selecting direct downloads.
|
|
278
|
-
|
|
279
|
-
> ⚠️ **The first transcription downloads the model (small ≈ 484 MB, via hf-mirror, not GitHub) and may take a few minutes**. Later runs reuse model files; new audio still requires full inference. Only a verified transcript cache hit skips inference. **Only subtitle-less videos trigger transcription** (subtitled videos use their subtitles directly).
|
|
280
|
-
|
|
281
|
-
**Transcript cache and threads**: `options.transcriptCache` defaults to true. Keys include the audio SHA-256, managed local model snapshots, installed dependencies, and decoding settings. Canonical segments retain real start/end times, so changing timestamp presentation does not repeat inference. Changed content/configuration/models/dependencies, custom local model directories, unknown environments, corrupt entries and expired entries bypass reuse. Cache lookup uses the existing local snapshot and does not check for upstream model updates online. Entries live under `transcripts-v1` in the cache root: 8 MiB per entry, 128 MiB total, 30-day validity, pruned on writes. Audio is not stored, and reading/source review still runs.
|
|
282
|
-
|
|
283
|
-
`options.cpuThreads` accepts integers 0–64. The default `0` preserves the library's CPU thread policy. Compare 4/6/8 on the same audio; more threads are not necessarily faster. CLI controls:
|
|
284
|
-
|
|
285
|
-
```bash
|
|
286
|
-
node scripts/transcribe.js --audio sample.m4a --out transcript.txt --cpu-threads 8
|
|
287
|
-
node scripts/transcribe.js --audio sample.m4a --out transcript.txt --refresh-cache
|
|
288
|
-
node scripts/transcribe.js --audio sample.m4a --out transcript.txt --no-cache
|
|
289
|
-
node scripts/transcribe.js --clear-cache
|
|
290
|
-
```
|
|
291
|
-
|
|
292
|
-
`--clear-cache` removes only transcripts, retaining models and Python. `--refresh-cache` forces inference and updates the cache; `--no-cache` disables reads and writes. Successful calls print one `metrics` JSON line with `cacheHit`, actual device, audio duration, and milliseconds for hashing, environment preparation, dependency installation, Python, publication and total time. Misses also include import, model loading, preparation (including decoding/VAD), and complete lazy-segment iteration. Hits do not reuse previous inference timings.
|
|
293
|
-
|
|
294
|
-
The note's `qualityPassed` checks the note against acquired text; it does not establish ASR accuracy. ASR changes still need audio/reference comparisons for errors, omissions, numbers, negation and timestamps.
|
|
295
|
-
|
|
296
|
-
**Quality/speed**: `small` + `int8` quantization + `VAD` silence filtering gives usable Chinese quality and is CPU-friendly. **Subtitled videos are not transcribed (fast)**; subtitle-less videos are transcribed at roughly 0.5–2× the video length on CPU.
|
|
297
|
-
|
|
298
|
-
**Failure handling**: install/download failures **report an error and degrade** (prompt for a manual transcript), never silently and never blocking for long. Use `options.transcribe: false` to skip transcription.
|
|
299
|
-
|
|
300
|
-
**How to know what source was used**: source info is **not written into the note** (to keep it clean); it surfaces in: ① the run log's `[source] <value> -> <label>` line; ② the `textSource` field in the returned result (`subtitle / transcription / desc / manual`).
|
|
301
|
-
|
|
302
|
-
---
|
|
303
|
-
|
|
304
|
-
## Variance and influencing factors (why length and content may differ)
|
|
305
|
-
|
|
306
|
-
**Output length and content vary noticeably with the model and the input; this is normal.**
|
|
307
|
-
|
|
308
|
-
### Model
|
|
309
|
-
- **ASR model tier**: `small` (default, usable for Chinese) → `base` (faster, slightly lower quality) → `medium` (better, slower). Adjust with `options.whisperModel`; download size and speed grow with the model.
|
|
310
|
-
- **Language/accent**: Chinese/English/mixed language, dialect, accent, stress → **different transcription accuracy and time**; for pure English video you can set `language: "en"`.
|
|
311
|
-
- **Deep-reading LLM**: uses the host DSH model; different context/reasoning models → **different quality, length, and speed**.
|
|
312
|
-
- **Non-determinism**: both the LLM and ASR are stochastic, so **re-running the same input may produce slightly different results** (content/length).
|
|
313
|
-
|
|
314
|
-
### Input
|
|
315
|
-
- **Video**:
|
|
316
|
-
- Whether **public subtitles** exist is the biggest differentiator — public subtitles = seconds-fast; login-only AI subtitles or no subtitles = triggers transcription, **noticeably slower**.
|
|
317
|
-
- **Length**: longer video = longer transcription (≈ 0.5–2× the video length on CPU).
|
|
318
|
-
- **Audio quality/noise/low volume/pure BGM/no voice**: transcription is error-prone or **empty**; supply a transcript manually in that case.
|
|
319
|
-
- **Paper/book/web page**:
|
|
320
|
-
- Format: PDF/EPUB/MOBI/HTML/arXiv; **scanned OCR, broken PDFs, dense formulas/figures** → different extraction quality and time.
|
|
321
|
-
- **Term density/length** → different chunk count and deep-reading depth.
|
|
322
|
-
- **Chunking structure**: different types chunk differently (chapter/topic/paragraph), affecting **output structure** and coverage.
|
|
323
|
-
|
|
324
|
-
### Hardware
|
|
325
|
-
- **GPU vs CPU**: gains depend on hardware, runtime libraries, model and audio. A visible GPU does not prove CUDA inference works; compare actual time and transcript accuracy.
|
|
326
|
-
|
|
327
|
-
### Other
|
|
328
|
-
- **First run vs reuse**: the first run downloads the model (≈ 484 MB); later runs reuse the cache.
|
|
329
|
-
- **Token/cost**: chunk count, length, and citations drive token usage; `fastMode`/`maxChunks` save tokens.
|
|
330
|
-
- **Citation/fabrication**: transcription or OCR errors may be quoted as "original text"; **re-check key citations**.
|
|
331
|
-
- **Boundaries**: pure BGM, distorted audio → empty/poor transcription; no subtitles and transcription unavailable → degrade to a prompt for a manual transcript.
|
|
332
|
-
|
|
333
|
-
---
|
|
334
|
-
|
|
335
|
-
## How failures are handled
|
|
336
|
-
|
|
337
|
-
Two classes:
|
|
338
|
-
|
|
339
|
-
- **Configuration errors** (missing input, invalid type, malformed options): throw immediately and abort — no half-baked output.
|
|
340
|
-
- **Content problems** (fetch failed, a chunk's deep-read failed): return `{ ok: false, stage, fatal: false }` and let the caller decide. A failed chunk is skipped and marked as a gap in the draft; the whole run is not aborted.
|
|
341
|
-
|
|
342
|
-
---
|
|
343
|
-
|
|
344
|
-
## Faster runs with the same quality gates
|
|
345
|
-
|
|
346
|
-
- Prefer `deep_read_summarize` on supported hosts: the model submits parameters instead of reproducing the entire workflow script. Older hosts retain the existing route.
|
|
347
|
-
- All known source lines remain covered. By default up to three reading tasks run concurrently, and each free slot immediately starts another task. Character-balanced chunks are used when available; otherwise the workflow balances by line count.
|
|
348
|
-
- Independent source review remains enabled. With `parallelQuality: true`, source chunks and all quotations are checked in parallel, with a separate global terminology and language review; the original review is the default. Missing line counts, failed reads, and description-only video sources cannot be fixed by rewriting the draft, so those states no longer consume full repair loops.
|
|
349
|
-
- Video `textSource: "desc"` is explicitly degraded and cannot pass as a complete deep read. Bilibili `p` selects the matching CID, part title, and duration.
|
|
350
|
-
- Returned `timings` reports stage durations in milliseconds; `readTimings` reports each chunk’s line range, duration and success. Compare the same sources, model, output size, and quality gates; scheduling simulations are not real LLM speedup measurements.
|
|
351
|
-
- `readConcurrency` controls concurrent chunk reads without changing the chunk plan or quality review requirements; it also limits concurrent review tasks when `parallelQuality` is enabled. It defaults to 3. When at least four chunks exist and the host supports it, try 4 and compare total time, throttling and failures; higher concurrency is not always faster.
|
|
352
|
-
|
|
353
|
-
**Cross-run read caching** is disabled by default and supported only by the `deep_read_summarize` plugin tool, not direct workflow calls. Set `readCache: true` and provide `readCacheIdentity` containing the provider, pinned model version and all output-affecting settings. The host cannot verify that identity; change it when the model or settings change. The cache matches source content, chunk prompt and identity, writes only after quality passes, and still performs independent source review on hits. `readTimings.cacheHit` reports hits. Entries are plaintext under `tempDir/.read-cache-v1` and may contain source excerpts; they expire after 30 days, are capped at 64 MiB total and 1 MiB per entry, and can be deleted by removing that directory.
|
|
101
|
+
| Option | Default | Purpose |
|
|
102
|
+
| --- | --- | --- |
|
|
103
|
+
| `minWords` | `2500` | Minimum length; the check counts Chinese characters and words in other text |
|
|
104
|
+
| `fastMode` | `false` | Omit the critical analysis, personal applications, and further-reading sections |
|
|
105
|
+
| `maxChunks` | `4` | Chunk-count limit, capped at 12; this is not the concurrency setting |
|
|
106
|
+
| `readConcurrency` | `3` | Maximum concurrent chunk reads; higher concurrency is not always faster |
|
|
107
|
+
| `maxRetries` | `0` | Repair attempts after a failed quality check; by default, a successfully drafted note receives one review and no repair |
|
|
108
|
+
| `outputDir` | `./output` | Suggested note directory; the main agent performs the write |
|
|
109
|
+
| `requireCitations` | `true` | Require verifiable source information for key quotations |
|
|
110
|
+
| `includeTimestamps` | `false` | Request timestamps for video notes |
|
|
111
|
+
| `transcribe` | `true` | Attempt local transcription when a video has no usable subtitles |
|
|
112
|
+
| `whisperModel` / `language` | `small` / `zh` | Choose a transcription model and language; set `en` for English when appropriate |
|
|
113
|
+
| `device` / `cpuThreads` | `cpu` / `0` | Select the transcription device and CPU thread policy |
|
|
114
|
+
| `transcriptCache` | `true` | Reuse validated transcripts when the audio and configuration match |
|
|
115
|
+
| `parallelQuality` | `false` | Opt in to parallel source review; the original review path remains the default |
|
|
116
|
+
| `readCache` | `false` | Optional cross-run chunk cache; supported by the plugin tool only |
|
|
354
117
|
|
|
355
|
-
|
|
118
|
+
To enable `readCache`, also set `readCacheIdentity` to include the provider, pinned model version, and output-affecting settings; change it whenever those change. The caller supplies this identity, and the host cannot verify it automatically. Cache entries are local plaintext and may contain source excerpts; cache hits still receive independent source review.
|
|
356
119
|
|
|
357
|
-
|
|
120
|
+
Other options include `frontmatter` (`obsidian`, `generic`, or `minimal`) and `tempDir`. See the [advanced reference](https://github.com/PensiveFei/deep-read-summarize/blob/main/docs/README-reference.en.md) for detailed options, supported formats, and transcription and cache behavior.
|
|
358
121
|
|
|
359
|
-
|
|
122
|
+
## Time, cost, and privacy
|
|
360
123
|
|
|
361
|
-
|
|
124
|
+
- **Time** depends on content length, retrieval, chunk count, model, and host concurrency. A video without subtitles needs extra transcription; the first run may also download a transcription model.
|
|
125
|
+
- **Cost** depends on your model and input/output usage; the project cannot promise fixed time or cost.
|
|
126
|
+
- **Privacy:** speech transcription runs locally, but deep reading uses your configured DSH model. With a cloud model, source text, subtitles, notes, or related context may be sent to its provider; check its data-handling terms first.
|
|
127
|
+
- **Local files:** temporary source text, transcripts, and optional caches may remain on your device. Check directory permissions and cleanup before processing sensitive material.
|
|
362
128
|
|
|
363
|
-
|
|
129
|
+
## Troubleshooting
|
|
364
130
|
|
|
365
|
-
|
|
131
|
+
- **Plugin unavailable:** check the DSH profile, restart Desktop after installation, and check host-version compatibility.
|
|
132
|
+
- **Fetch failure or missing sections:** check source accessibility and required tools; inspect the returned stage, source status, and failed chunks.
|
|
133
|
+
- **Only a video description is available:** a complete subtitle or transcript has not been confirmed. Check subtitle and transcription availability, or provide a transcript.
|
|
134
|
+
- **Quality check failed:** inspect `qualityIssues` and `qualityEvidence` and review the source as needed. Do not treat an unverified note as a complete account.
|
|
366
135
|
|
|
367
|
-
|
|
368
|
-
- Sub-agents need appropriate permissions to write files; if permissions are insufficient, the workflow returns the content and the main agent handles persistence.
|
|
369
|
-
- **Local transcription**: video transcription (faster-whisper) runs **locally**; audio/subtitles **do not leave your machine**; network requests to the corresponding platforms are made only when fetching video metadata/subtitles/audio.
|
|
370
|
-
- This repo contains only the pipeline itself: workflow definitions, parser code, prompt templates, schemas. **It contains no extracted copyrighted content.** Test fixtures are self-written public-domain fables. When you process copyrighted material with this workflow, responsibility for the output is yours.
|
|
136
|
+
For further help, [open a GitHub issue](https://github.com/PensiveFei/deep-read-summarize/issues) with your operating system, DSH and plugin versions, input type, and error details. Remove secrets, private links, and personal data first.
|
|
371
137
|
|
|
372
|
-
|
|
138
|
+
## Development and contributing
|
|
373
139
|
|
|
374
|
-
|
|
140
|
+
Work in a **separate project directory**; do not run npm inside a DSH profile:
|
|
375
141
|
|
|
376
142
|
```bash
|
|
377
|
-
|
|
378
|
-
|
|
379
|
-
npm
|
|
380
|
-
npm
|
|
143
|
+
git clone https://github.com/PensiveFei/deep-read-summarize.git
|
|
144
|
+
cd deep-read-summarize
|
|
145
|
+
npm ci
|
|
146
|
+
npm test
|
|
147
|
+
npm run test:node
|
|
148
|
+
npm run lint
|
|
149
|
+
npm run validate
|
|
381
150
|
```
|
|
382
151
|
|
|
383
|
-
|
|
384
|
-
|
|
385
|
-
See CHANGELOG.md for changes and CONTRIBUTING.md for contribution guidelines.
|
|
386
|
-
|
|
387
|
-
---
|
|
388
|
-
|
|
389
|
-
## Compatibility
|
|
390
|
-
|
|
391
|
-
**Verified host: DSH 0.2.0-rc.2** (Node 24). The dependency surface is exactly two things:
|
|
392
|
-
|
|
393
|
-
| Surface | Current contract | How this repo uses it |
|
|
394
|
-
| --- | --- | --- |
|
|
395
|
-
| workflow script hooks | `agent()` / `pipeline()` / `parallel()` / `phase()` / `log()` / `args` | only `agent/parallel/phase/log/args`; `agent()` options limited to `label/phase/schema` (the engine accepts only `label/phase/schema/provider/model` and treats anything else as fatal) |
|
|
396
|
-
| JSON Schema subset | `type / properties / required / additionalProperties / items / enum / const / oneOf` plus annotation keys | both `agent()` schemas verified against the host's real `assertObjectJsonSchema` |
|
|
397
|
-
|
|
398
|
-
Two contract details that bite:
|
|
399
|
-
|
|
400
|
-
- **The script sandbox has no filesystem, network, timers or `require`** — it coordinates subagents; the caller persists the note (see ⚠️ above).
|
|
401
|
-
- **Breaking the schema subset terminates the run** rather than degrading: the engine raises `UNSUPPORTED_SCHEMA` and the whole workflow fails. `npm test` carries a regression for this, including a reverse assertion so the checker cannot pass vacuously.
|
|
152
|
+
The project uses parsers for different input types and supports custom parsers. See the [repository](https://github.com/PensiveFei/deep-read-summarize), [CHANGELOG](https://github.com/PensiveFei/deep-read-summarize/blob/main/CHANGELOG.md), and [CONTRIBUTING](https://github.com/PensiveFei/deep-read-summarize/blob/main/CONTRIBUTING.md).
|
|
402
153
|
|
|
403
|
-
|
|
154
|
+
The relevant host contracts were previously verified with DSH `0.2.0-rc.2`. DSH interfaces can change; verify other versions against the actual host and compatibility information.
|
|
404
155
|
|
|
405
|
-
|
|
156
|
+
## License and disclaimer
|
|
406
157
|
|
|
407
|
-
|
|
158
|
+
Project code is available under the [MIT License](https://github.com/PensiveFei/deep-read-summarize/blob/main/LICENSE). Papers, video, and short quotations cited in examples remain subject to their respective rights and permissions.
|
|
408
159
|
|
|
409
|
-
|
|
160
|
+
deep-read-summarize is an independent third-party project. It is not affiliated with, endorsed by, or sponsored by DeepSeek or DeepSeek Harness.
|