tileops 0.0.1.dev0__py3-none-any.whl → 0.0.1.dev2__py3-none-any.whl
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- tileops-0.0.1.dev2.dist-info/METADATA +147 -0
- tileops-0.0.1.dev2.dist-info/RECORD +19 -0
- top/__init__.py +4 -6
- top/kernel/__init__.py +15 -0
- top/kernel/bitnet.py +490 -0
- top/kernel/blocksparse_attention.py +605 -0
- top/kernel/gqa.py +1079 -0
- top/kernel/linear_attention/__init__.py +0 -0
- top/kernel/linear_attention/linear_attn.py +490 -0
- top/kernel/mamba_chunk_scan.py +335 -0
- top/kernel/mamba_chunk_state.py +269 -0
- top/kernel/mha.py +920 -0
- top/kernel/mla.py +311 -0
- top/kernel/sparse_mla.py +502 -0
- top/utils/__init__.py +1 -0
- top/utils/utils.py +55 -0
- tileops-0.0.1.dev0.dist-info/METADATA +0 -82
- tileops-0.0.1.dev0.dist-info/RECORD +0 -6
- {tileops-0.0.1.dev0.dist-info → tileops-0.0.1.dev2.dist-info}/WHEEL +0 -0
- {tileops-0.0.1.dev0.dist-info → tileops-0.0.1.dev2.dist-info}/licenses/LICENSE +0 -0
- {tileops-0.0.1.dev0.dist-info → tileops-0.0.1.dev2.dist-info}/top_level.txt +0 -0
|
@@ -0,0 +1,147 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
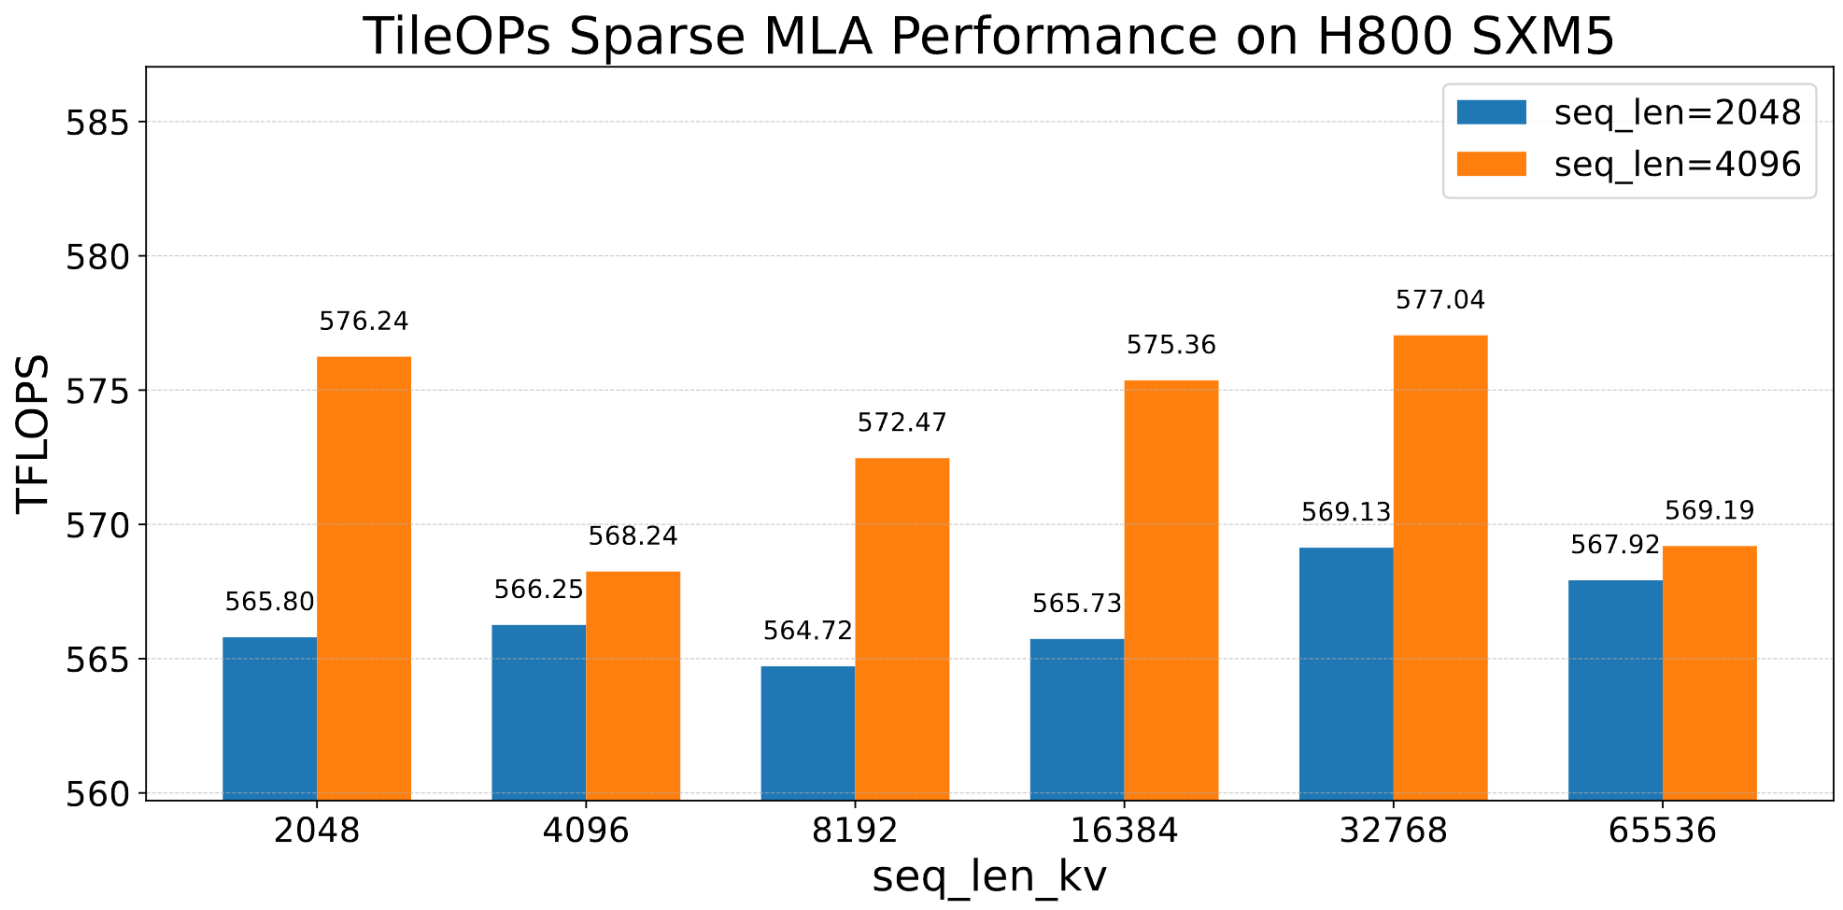
Name: tileops
|
|
3
|
+
Version: 0.0.1.dev2
|
|
4
|
+
Summary: TileOPs kernels for efficient inference
|
|
5
|
+
Author: Tile-AI
|
|
6
|
+
License-Expression: MIT
|
|
7
|
+
Requires-Python: >=3.8
|
|
8
|
+
Description-Content-Type: text/markdown
|
|
9
|
+
License-File: LICENSE
|
|
10
|
+
Requires-Dist: torch>=2.1.0
|
|
11
|
+
Requires-Dist: numpy>=1.23.5
|
|
12
|
+
Requires-Dist: einops>=0.6.0
|
|
13
|
+
Requires-Dist: Cython
|
|
14
|
+
Requires-Dist: tqdm>=4.62.3
|
|
15
|
+
Requires-Dist: typing_extensions>=4.10.0
|
|
16
|
+
Requires-Dist: cloudpickle
|
|
17
|
+
Requires-Dist: ml_dtypes
|
|
18
|
+
Requires-Dist: psutil
|
|
19
|
+
Requires-Dist: tilelang>=0.1.6.post1
|
|
20
|
+
Provides-Extra: dev
|
|
21
|
+
Requires-Dist: yapf==0.40.2; extra == "dev"
|
|
22
|
+
Requires-Dist: toml==0.10.2; extra == "dev"
|
|
23
|
+
Requires-Dist: tomli==2.0.1; extra == "dev"
|
|
24
|
+
Requires-Dist: ruff==0.6.5; extra == "dev"
|
|
25
|
+
Requires-Dist: codespell==2.3.0; extra == "dev"
|
|
26
|
+
Requires-Dist: clang-format==15.0.7; extra == "dev"
|
|
27
|
+
Dynamic: license-file
|
|
28
|
+
|
|
29
|
+
# TileOPs (TOP)
|
|
30
|
+
|
|
31
|
+
**TileOPs (TOP)** is a high-performance machine learning operator collections built on top of [TileLang](https://github.com/tile-ai/tilelang). It offers efficient, modular, and composable implementations optimized for AI workloads.
|
|
32
|
+
|
|
33
|
+
Note: TileOPs is still under rapid development.
|
|
34
|
+
|
|
35
|
+
---
|
|
36
|
+
|
|
37
|
+
|
|
38
|
+
*DeepSeek-V3.2-Exp DeepSeek Sparse Attention (DSA) performance on H800 SXM*
|
|
39
|
+
|
|
40
|
+
## 📦 Installation
|
|
41
|
+
|
|
42
|
+
### Requirements
|
|
43
|
+
|
|
44
|
+
- Python 3.8+
|
|
45
|
+
- PyTorch >= 2.1
|
|
46
|
+
- GLIBCXX_3.4.32
|
|
47
|
+
- [TileLang](https://github.com/tile-ai/tilelang)
|
|
48
|
+
|
|
49
|
+
### Method 1: Install with Pip
|
|
50
|
+
|
|
51
|
+
```bash
|
|
52
|
+
pip install tileops
|
|
53
|
+
```
|
|
54
|
+
|
|
55
|
+
### Method 2: Install from source (editable mode for development)
|
|
56
|
+
|
|
57
|
+
```bash
|
|
58
|
+
git clone https://github.com/tile-ai/TileOPs
|
|
59
|
+
cd TileOPs
|
|
60
|
+
pip install -e '.[dev]' -v # remove -e option if you don't want to install in editable mode, -v for verbose output
|
|
61
|
+
```
|
|
62
|
+
|
|
63
|
+
## 🚀 Quick Usage
|
|
64
|
+
|
|
65
|
+
### Sparse MLA
|
|
66
|
+
|
|
67
|
+
```python
|
|
68
|
+
import torch
|
|
69
|
+
from top import SparseMLAKernel
|
|
70
|
+
|
|
71
|
+
batch_size = 1
|
|
72
|
+
seq_len = 1024
|
|
73
|
+
seq_len_kv = 2048
|
|
74
|
+
q_start_index_s = 1024
|
|
75
|
+
n_heads = 128
|
|
76
|
+
head_dim = 512
|
|
77
|
+
tail_dim = 64
|
|
78
|
+
topk = 2048
|
|
79
|
+
kv_stride = 1
|
|
80
|
+
kv_group = 1
|
|
81
|
+
sm_scale = None
|
|
82
|
+
|
|
83
|
+
sparse_mla = SparseMLAKernel(
|
|
84
|
+
batch=batch_size,
|
|
85
|
+
seq_len=seq_len,
|
|
86
|
+
seq_len_kv=seq_len_kv,
|
|
87
|
+
q_start_index_s=q_start_index_s,
|
|
88
|
+
heads=n_heads,
|
|
89
|
+
dim=head_dim,
|
|
90
|
+
tail_dim=tail_dim,
|
|
91
|
+
topk=topk,
|
|
92
|
+
kv_stride=kv_stride,
|
|
93
|
+
kv_group=kv_group,
|
|
94
|
+
sm_scale=sm_scale,
|
|
95
|
+
is_casual=True,
|
|
96
|
+
dtype=torch.bfloat16,
|
|
97
|
+
device='cuda',
|
|
98
|
+
)
|
|
99
|
+
|
|
100
|
+
# Evaluate the Sparse MLA kernel performance
|
|
101
|
+
sparse_mla.check()
|
|
102
|
+
latency = sparse_mla.profile()
|
|
103
|
+
print(f"Latency: {latency:.4f} ms")
|
|
104
|
+
print(f'fwd tflops = ',
|
|
105
|
+
(batch_size * seq_len * (head_dim + tail_dim + head_dim) * topk * 2 * n_heads) / (latency * 1e-3) / 1e12)
|
|
106
|
+
```
|
|
107
|
+
|
|
108
|
+
### MLA
|
|
109
|
+
|
|
110
|
+
```python
|
|
111
|
+
import torch
|
|
112
|
+
import top
|
|
113
|
+
from top import MLAKernel
|
|
114
|
+
|
|
115
|
+
device = "cuda"
|
|
116
|
+
dtype = torch.float16
|
|
117
|
+
|
|
118
|
+
batch = 128
|
|
119
|
+
heads = 64
|
|
120
|
+
kv_heads = 1
|
|
121
|
+
kv_ctx = 8192
|
|
122
|
+
dim = 512
|
|
123
|
+
pe_dim = 64
|
|
124
|
+
|
|
125
|
+
# Query input: [batch, heads, dim]
|
|
126
|
+
q = torch.randn(batch, heads, dim, device=device, dtype=dtype)
|
|
127
|
+
|
|
128
|
+
# Query positional encoding: [batch, heads, pe_dim]
|
|
129
|
+
q_pe = torch.randn(batch, heads, pe_dim, device=device, dtype=dtype)
|
|
130
|
+
|
|
131
|
+
# KV cache input: [batch, kv_ctx, kv_heads, dim]
|
|
132
|
+
kv = torch.randn(batch, kv_ctx, kv_heads, dim, device=device, dtype=dtype)
|
|
133
|
+
|
|
134
|
+
# KV positional encoding: [batch, kv_ctx, kv_heads, pe_dim]
|
|
135
|
+
k_pe = torch.randn(batch, kv_ctx, kv_heads, pe_dim, device=device, dtype=dtype)
|
|
136
|
+
|
|
137
|
+
# Use MLA kernel
|
|
138
|
+
block_N = 64
|
|
139
|
+
block_H = 64
|
|
140
|
+
num_split = 1
|
|
141
|
+
|
|
142
|
+
mla = MLAKernel(batch, heads, kv_heads, kv_ctx, dim, pe_dim, block_N, block_H, num_split)
|
|
143
|
+
|
|
144
|
+
out = mla(q, q_pe, kv, k_pe)
|
|
145
|
+
```
|
|
146
|
+
|
|
147
|
+
## Acknowledgments
|
|
@@ -0,0 +1,19 @@
|
|
|
1
|
+
tileops-0.0.1.dev2.dist-info/licenses/LICENSE,sha256=hr_8lcbfSW8PTqqDHjB_EfPueXTmbaAz7nDy2F97vl0,1126
|
|
2
|
+
top/__init__.py,sha256=lop9i9TF0vfH-gY0XPTyBvK__TjV2R7jQbhk5PvHqnc,857
|
|
3
|
+
top/kernel/__init__.py,sha256=IVHXz3zMwHXfhm3Rl7PB8c7kFsjEKEyXi7AhfkDzIZ0,735
|
|
4
|
+
top/kernel/bitnet.py,sha256=EIHKwqxi8x85kDuik2d0GeYJyeJfKNVYisF2ix367AI,18011
|
|
5
|
+
top/kernel/blocksparse_attention.py,sha256=EZPtzeFH5LjeGiQzlg8v7ChGEyXozFaS9B841F59DN4,26542
|
|
6
|
+
top/kernel/gqa.py,sha256=Vw5LbN7Jmwo-wUzwOy1SBCOBjkOfM-FsFwkGmjd7C6M,48777
|
|
7
|
+
top/kernel/mamba_chunk_scan.py,sha256=e7Yr-p_fon2JQDoVyg2e-Zp_GWB-4tRGzlQ3Kpgt4LY,15134
|
|
8
|
+
top/kernel/mamba_chunk_state.py,sha256=5nrHr1ltCr4eN22MYD23XDey6AqIwn12Pp0qJbL8Ixk,10973
|
|
9
|
+
top/kernel/mha.py,sha256=OHrn7UnS7cmnRWfHbvhuAiPXYNzsDrgybuJugLzCHho,41561
|
|
10
|
+
top/kernel/mla.py,sha256=2-GNuH98Gm6kDVwvbMXzJWdH9qnmChpnt7TyA8EzcxA,14664
|
|
11
|
+
top/kernel/sparse_mla.py,sha256=r1Ld2BNBwQndwQCEQ7Au3oTLCKqFAUG2ltLc2NrDC9U,23032
|
|
12
|
+
top/kernel/linear_attention/__init__.py,sha256=47DEQpj8HBSa-_TImW-5JCeuQeRkm5NMpJWZG3hSuFU,0
|
|
13
|
+
top/kernel/linear_attention/linear_attn.py,sha256=tR67X8VYmGMjvFbpDcS8_5ok0_5wfnpZRG33URberuE,20593
|
|
14
|
+
top/utils/__init__.py,sha256=pG-YPVG0gJIJ6s4xcAz9S_CnUxpUcz33wl9eNUSgxGk,20
|
|
15
|
+
top/utils/utils.py,sha256=w1a4muz4sIvYqn9fhQw9JdrPloGRnBLcf98vnToXBBs,1837
|
|
16
|
+
tileops-0.0.1.dev2.dist-info/METADATA,sha256=7-VQoOi9KKvzTjwmQ_hC-N8omRX2hevL-NJ-6T2K0sc,3597
|
|
17
|
+
tileops-0.0.1.dev2.dist-info/WHEEL,sha256=_zCd3N1l69ArxyTb8rzEoP9TpbYXkqRFSNOD5OuxnTs,91
|
|
18
|
+
tileops-0.0.1.dev2.dist-info/top_level.txt,sha256=994pR8ZMtkNeFfsr7zWdHtX2NWsq67eyBTXjdykE5ts,4
|
|
19
|
+
tileops-0.0.1.dev2.dist-info/RECORD,,
|
top/__init__.py
CHANGED
|
@@ -1,18 +1,16 @@
|
|
|
1
|
-
# Copyright (c) Tile-AI.
|
|
2
|
-
# Licensed under the MIT License.
|
|
3
|
-
|
|
4
1
|
from .kernel.mha import MHAKernel, MHADecodeKernel
|
|
5
2
|
from .kernel.mla import MLAKernel
|
|
6
3
|
from .kernel.gqa import GQAKernel, GQADecodeKernel
|
|
7
4
|
from .kernel.mamba_chunk_scan import MambaChunkScanKernel
|
|
8
5
|
from .kernel.mamba_chunk_state import MambaChunkStateKernel
|
|
9
6
|
from .kernel.blocksparse_attention import BlockSparseAttentionKernel
|
|
10
|
-
from .kernel.linear_attention.linear_attn import LinearAttentionFusedChunkKernel, LinearAttentionFusedRecurrentKernel
|
|
7
|
+
# from .kernel.linear_attention.linear_attn import LinearAttentionFusedChunkKernel, LinearAttentionFusedRecurrentKernel
|
|
11
8
|
from .kernel.bitnet import Bitnet_158_int8xint2_kernel
|
|
9
|
+
from .kernel.sparse_mla import SparseMLAKernel
|
|
12
10
|
|
|
13
11
|
__all__ = [
|
|
14
12
|
"MHAKernel", "MHADecodeKernel", "MLAKernel", "GQAKernel", "GQADecodeKernel",
|
|
15
13
|
"MambaChunkScanKernel", "MambaChunkStateKernel", "BlockSparseAttentionKernel",
|
|
16
|
-
"LinearAttentionFusedChunkKernel", "LinearAttentionFusedRecurrentKernel",
|
|
17
|
-
"Bitnet_158_int8xint2_kernel"
|
|
14
|
+
# "LinearAttentionFusedChunkKernel", "LinearAttentionFusedRecurrentKernel",
|
|
15
|
+
"Bitnet_158_int8xint2_kernel", "SparseMLAKernel"
|
|
18
16
|
]
|
top/kernel/__init__.py
ADDED
|
@@ -0,0 +1,15 @@
|
|
|
1
|
+
from .mha import MHAKernel, MHADecodeKernel
|
|
2
|
+
from .mla import MLAKernel
|
|
3
|
+
from .gqa import GQAKernel, GQADecodeKernel
|
|
4
|
+
from .mamba_chunk_scan import MambaChunkScanKernel
|
|
5
|
+
from .mamba_chunk_state import MambaChunkStateKernel
|
|
6
|
+
from .blocksparse_attention import BlockSparseAttentionKernel
|
|
7
|
+
# from .linear_attention.linear_attn import LinearAttentionFusedChunkKernel, LinearAttentionFusedRecurrentKernel
|
|
8
|
+
from .bitnet import Bitnet_158_int8xint2_kernel
|
|
9
|
+
|
|
10
|
+
__all__ = [
|
|
11
|
+
"MHAKernel", "MHADecodeKernel", "MLAKernel", "GQAKernel", "GQADecodeKernel",
|
|
12
|
+
"MambaChunkScanKernel", "MambaChunkStateKernel", "BlockSparseAttentionKernel",
|
|
13
|
+
# "LinearAttentionFusedChunkKernel", "LinearAttentionFusedRecurrentKernel",
|
|
14
|
+
"Bitnet_158_int8xint2_kernel"
|
|
15
|
+
]
|
top/kernel/bitnet.py
ADDED
|
@@ -0,0 +1,490 @@
|
|
|
1
|
+
import torch
|
|
2
|
+
import torch.backends
|
|
3
|
+
import tilelang
|
|
4
|
+
import tilelang.language as T
|
|
5
|
+
import torch.nn as nn
|
|
6
|
+
from tilelang import tvm as tvm
|
|
7
|
+
from tvm import DataType
|
|
8
|
+
from tilelang.intrinsics.mma_layout import (
|
|
9
|
+
make_mma_swizzle_layout as make_swizzle_layout,)
|
|
10
|
+
import numpy as np
|
|
11
|
+
|
|
12
|
+
from tilelang.intrinsics.mma_macro_generator import (
|
|
13
|
+
INT4TensorCoreIntrinEmitter,)
|
|
14
|
+
from tilelang.transform import simplify_prim_func
|
|
15
|
+
|
|
16
|
+
try:
|
|
17
|
+
from tilelang.intrinsics.utils import index_to_coordinates
|
|
18
|
+
except ImportError:
|
|
19
|
+
from tilelang.language.utils import index_to_coordinates
|
|
20
|
+
|
|
21
|
+
decode_i2s_to_i8s = """template <typename T1, typename T2>
|
|
22
|
+
__device__ void decode_i2s_to_i8s(T1 *_i2b, T2 *_i8s, const int N = 16)
|
|
23
|
+
{
|
|
24
|
+
// convert 8 int2b_t to 8 int8b_t -> 2 int32
|
|
25
|
+
uint *i8s = reinterpret_cast<uint *>(_i8s);
|
|
26
|
+
|
|
27
|
+
// i2b = {e7,e6,e5,e4,e3,e2,e1,e0}
|
|
28
|
+
// also require interleave {e7,e3,e6,e2,e5,e1,e4,e0}
|
|
29
|
+
uint const i2b = *reinterpret_cast<uint *>(_i2b);
|
|
30
|
+
|
|
31
|
+
// First, we extract the i4s and construct an intermediate fp16 number.
|
|
32
|
+
static constexpr uint immLut = (0xf0 & 0xcc) | 0xaa; // 0b11101010
|
|
33
|
+
static constexpr uint BOTTOM_MASK = 0x03030303; // 0xf -> 0b11 select 0,3
|
|
34
|
+
static constexpr uint I8s_MAGIC_NUM = 0x00000000; // 1024
|
|
35
|
+
static constexpr uint MEDIAN_NUM = 0x02020202;
|
|
36
|
+
#pragma unroll
|
|
37
|
+
for (int i = 0; i < (N / 4); i++)
|
|
38
|
+
{
|
|
39
|
+
asm volatile("lop3.b32 %0, %1, %2, %3, %4;\\n"
|
|
40
|
+
: "=r"(i8s[i])
|
|
41
|
+
: "r"(i2b >> (2 * i)), "n"(BOTTOM_MASK), "n"(I8s_MAGIC_NUM), "n"(immLut));
|
|
42
|
+
i8s[i] = __vsub4(i8s[i], MEDIAN_NUM);
|
|
43
|
+
}
|
|
44
|
+
}
|
|
45
|
+
template <typename T1, typename T2>
|
|
46
|
+
__device__ void decode_i2u_to_i8s(T1 *_i2b, T2 *_i8s, const int N = 16)
|
|
47
|
+
{
|
|
48
|
+
// convert 8 int2b_t to 8 int8b_t -> 2 int32
|
|
49
|
+
uint *i8s = reinterpret_cast<uint *>(_i8s);
|
|
50
|
+
|
|
51
|
+
// i2b = {e7,e6,e5,e4,e3,e2,e1,e0}
|
|
52
|
+
// also require interleave {e7,e3,e6,e2,e5,e1,e4,e0}
|
|
53
|
+
uint const i2b = *reinterpret_cast<uint *>(_i2b);
|
|
54
|
+
|
|
55
|
+
// First, we extract the i4s and construct an intermediate fp16 number.
|
|
56
|
+
static constexpr uint immLut = (0xf0 & 0xcc) | 0xaa; // 0b11101010
|
|
57
|
+
static constexpr uint BOTTOM_MASK = 0x03030303; // 0xf -> 0b11 select 0,3
|
|
58
|
+
static constexpr uint I8s_MAGIC_NUM = 0x00000000; // 1024
|
|
59
|
+
|
|
60
|
+
#pragma unroll
|
|
61
|
+
for (int i = 0; i < (N / 4); i++)
|
|
62
|
+
{
|
|
63
|
+
asm volatile("lop3.b32 %0, %1, %2, %3, %4;\\n"
|
|
64
|
+
: "=r"(i8s[i])
|
|
65
|
+
: "r"(i2b >> (2 * i)), "n"(BOTTOM_MASK), "n"(I8s_MAGIC_NUM), "n"(immLut));
|
|
66
|
+
}
|
|
67
|
+
}
|
|
68
|
+
"""
|
|
69
|
+
|
|
70
|
+
|
|
71
|
+
@simplify_prim_func
|
|
72
|
+
def _bitnet_158_int8xint2_prefill(
|
|
73
|
+
M,
|
|
74
|
+
N,
|
|
75
|
+
K,
|
|
76
|
+
in_dtype,
|
|
77
|
+
out_dtype,
|
|
78
|
+
accum_dtype,
|
|
79
|
+
fast_decoding=True,
|
|
80
|
+
block_row_warps=2,
|
|
81
|
+
block_col_warps=2,
|
|
82
|
+
warp_row_tiles=32,
|
|
83
|
+
warp_col_tiles=32,
|
|
84
|
+
chunk=64,
|
|
85
|
+
):
|
|
86
|
+
assert in_dtype in [
|
|
87
|
+
"float16",
|
|
88
|
+
"int8",
|
|
89
|
+
], "Currently only float16 and int8 are supported"
|
|
90
|
+
assert out_dtype in [
|
|
91
|
+
"float16",
|
|
92
|
+
"float32",
|
|
93
|
+
"int32",
|
|
94
|
+
], "Currently only float16, float32 and int32 are supported"
|
|
95
|
+
|
|
96
|
+
micro_size_x = micro_size_y = micro_size_k = 16
|
|
97
|
+
|
|
98
|
+
if accum_dtype == "int32":
|
|
99
|
+
micro_size_k = 32
|
|
100
|
+
|
|
101
|
+
num_elems_per_byte = 4
|
|
102
|
+
MAX_TRANSACTION_SIZE_IN_BITS = 128
|
|
103
|
+
local_size = MAX_TRANSACTION_SIZE_IN_BITS // DataType(in_dtype).bits
|
|
104
|
+
local_size_compressed = local_size // num_elems_per_byte
|
|
105
|
+
|
|
106
|
+
shared_scope = "shared.dyn"
|
|
107
|
+
storage_dtype = "int8"
|
|
108
|
+
|
|
109
|
+
# Pipeline Stage
|
|
110
|
+
stage = 2
|
|
111
|
+
|
|
112
|
+
block_M = block_row_warps * warp_row_tiles
|
|
113
|
+
block_N = block_col_warps * warp_col_tiles
|
|
114
|
+
block_K = chunk
|
|
115
|
+
|
|
116
|
+
A_shape = (M, K) # int8 storage represents int4*2
|
|
117
|
+
B_shape = (N, K // num_elems_per_byte) # int8 storage represents int4*2
|
|
118
|
+
A_shared_shape = (block_M, block_K)
|
|
119
|
+
B_shared_shape = (block_N, block_K // num_elems_per_byte)
|
|
120
|
+
B_dequantize_shared_shape = (block_N, block_K)
|
|
121
|
+
C_shared_shape = (
|
|
122
|
+
block_M // micro_size_x,
|
|
123
|
+
block_N // micro_size_y,
|
|
124
|
+
micro_size_x,
|
|
125
|
+
micro_size_y,
|
|
126
|
+
)
|
|
127
|
+
|
|
128
|
+
warp_size = 32
|
|
129
|
+
threads = warp_size * (block_row_warps * block_col_warps)
|
|
130
|
+
fragement_size_a = (micro_size_x * micro_size_k) // warp_size
|
|
131
|
+
fragement_size_b = (micro_size_y * micro_size_k) // warp_size
|
|
132
|
+
fragement_size_c = (micro_size_x * micro_size_y) // warp_size
|
|
133
|
+
warp_rows = warp_row_tiles // micro_size_x
|
|
134
|
+
warp_cols = warp_col_tiles // micro_size_y
|
|
135
|
+
|
|
136
|
+
# MMA Wrapper to Auto Generate Code for MMA
|
|
137
|
+
mma_emitter = INT4TensorCoreIntrinEmitter(
|
|
138
|
+
a_dtype=in_dtype,
|
|
139
|
+
b_dtype=in_dtype,
|
|
140
|
+
accum_dtype=accum_dtype,
|
|
141
|
+
a_transposed=False,
|
|
142
|
+
b_transposed=True,
|
|
143
|
+
block_row_warps=block_row_warps,
|
|
144
|
+
block_col_warps=block_col_warps,
|
|
145
|
+
warp_row_tiles=warp_row_tiles,
|
|
146
|
+
warp_col_tiles=warp_col_tiles,
|
|
147
|
+
chunk=chunk,
|
|
148
|
+
)
|
|
149
|
+
|
|
150
|
+
@T.prim_func
|
|
151
|
+
def _bitnet_158_int8xint2_prefill_main(
|
|
152
|
+
A: T.Buffer(A_shape, in_dtype),
|
|
153
|
+
B: T.Buffer(B_shape, storage_dtype),
|
|
154
|
+
C: T.Buffer((M, N), out_dtype),
|
|
155
|
+
):
|
|
156
|
+
with T.Kernel(
|
|
157
|
+
T.ceildiv(N, block_N),
|
|
158
|
+
T.ceildiv(M, block_M),
|
|
159
|
+
threads=threads,
|
|
160
|
+
prelude=decode_i2s_to_i8s,
|
|
161
|
+
) as (bx, by):
|
|
162
|
+
|
|
163
|
+
A_shared = T.alloc_shared(A_shared_shape, in_dtype, scope=shared_scope)
|
|
164
|
+
B_shared = T.alloc_shared(B_shared_shape, storage_dtype, scope=shared_scope)
|
|
165
|
+
B_dequantize_shared = T.alloc_shared(
|
|
166
|
+
B_dequantize_shared_shape, in_dtype, scope=shared_scope)
|
|
167
|
+
C_shared = T.alloc_shared(C_shared_shape, out_dtype, scope=shared_scope)
|
|
168
|
+
A_frag = T.alloc_local((warp_rows * fragement_size_a), in_dtype)
|
|
169
|
+
B_frag = T.alloc_local((warp_cols * fragement_size_b), in_dtype)
|
|
170
|
+
C_frag = T.alloc_local((warp_rows * warp_cols * fragement_size_c), accum_dtype)
|
|
171
|
+
|
|
172
|
+
B_local = T.alloc_local([local_size_compressed], storage_dtype)
|
|
173
|
+
B_dequantize_local = T.alloc_local([local_size], in_dtype)
|
|
174
|
+
|
|
175
|
+
thread_bindings = T.thread_binding(0, threads, "threadIdx.x")
|
|
176
|
+
|
|
177
|
+
T.annotate_layout({
|
|
178
|
+
A_shared: make_swizzle_layout(A_shared),
|
|
179
|
+
B_dequantize_shared: make_swizzle_layout(B_dequantize_shared),
|
|
180
|
+
})
|
|
181
|
+
|
|
182
|
+
# Improve L2 Cache
|
|
183
|
+
T.use_swizzle(panel_size=10)
|
|
184
|
+
|
|
185
|
+
T.clear(C_frag)
|
|
186
|
+
|
|
187
|
+
for ko in T.Pipelined((K // block_K), num_stages=stage):
|
|
188
|
+
|
|
189
|
+
# Load A into shared memory
|
|
190
|
+
for i, k in T.Parallel(block_M, block_K):
|
|
191
|
+
A_shared[i, k] = A[by * block_M + i, ko * block_K + k]
|
|
192
|
+
|
|
193
|
+
# Load B into shared memory
|
|
194
|
+
for j, k in T.Parallel(block_N, block_K // num_elems_per_byte):
|
|
195
|
+
B_shared[j, k] = B[bx * block_N + j, ko * (block_K // num_elems_per_byte) + k]
|
|
196
|
+
|
|
197
|
+
for i in T.serial(block_N * block_K // num_elems_per_byte //
|
|
198
|
+
(threads * local_size_compressed)):
|
|
199
|
+
for v in T.vectorized(0, local_size_compressed):
|
|
200
|
+
index = (
|
|
201
|
+
i * threads * local_size_compressed +
|
|
202
|
+
thread_bindings * local_size_compressed + v)
|
|
203
|
+
vi, vj = index_to_coordinates(index, B_shared_shape)
|
|
204
|
+
B_local[v] = B_shared[vi, vj]
|
|
205
|
+
|
|
206
|
+
T.call_extern(
|
|
207
|
+
"handle",
|
|
208
|
+
"decode_i2u_to_i8s",
|
|
209
|
+
T.address_of(B_local[0]),
|
|
210
|
+
T.address_of(B_dequantize_local[0]),
|
|
211
|
+
)
|
|
212
|
+
|
|
213
|
+
for v in T.vectorized(0, local_size):
|
|
214
|
+
index = (i * threads * local_size + thread_bindings * local_size + v)
|
|
215
|
+
vi, vj = index_to_coordinates(index, B_dequantize_shared_shape)
|
|
216
|
+
B_dequantize_shared[vi, vj] = B_dequantize_local[v]
|
|
217
|
+
|
|
218
|
+
for ki in T.serial(0, (block_K // micro_size_k)):
|
|
219
|
+
|
|
220
|
+
# Load A into fragment
|
|
221
|
+
mma_emitter.ldmatrix_a(
|
|
222
|
+
A_frag,
|
|
223
|
+
A_shared,
|
|
224
|
+
ki,
|
|
225
|
+
)
|
|
226
|
+
|
|
227
|
+
# Load B into fragment
|
|
228
|
+
mma_emitter.ldmatrix_b(
|
|
229
|
+
B_frag,
|
|
230
|
+
B_dequantize_shared,
|
|
231
|
+
ki,
|
|
232
|
+
)
|
|
233
|
+
|
|
234
|
+
# Perform Matrix Multiplication
|
|
235
|
+
mma_emitter.mma(A_frag, B_frag, C_frag)
|
|
236
|
+
|
|
237
|
+
# Perform STMatrix
|
|
238
|
+
mma_emitter.stmatrix(
|
|
239
|
+
C_frag,
|
|
240
|
+
C_shared,
|
|
241
|
+
)
|
|
242
|
+
|
|
243
|
+
# Store shared into global
|
|
244
|
+
for i, j in T.Parallel(block_M, block_N):
|
|
245
|
+
C[by * block_M + i, bx * block_N + j] = C_shared[
|
|
246
|
+
i // micro_size_x,
|
|
247
|
+
j // micro_size_y,
|
|
248
|
+
i % micro_size_x,
|
|
249
|
+
j % micro_size_y,
|
|
250
|
+
]
|
|
251
|
+
|
|
252
|
+
return _bitnet_158_int8xint2_prefill_main
|
|
253
|
+
|
|
254
|
+
|
|
255
|
+
@simplify_prim_func
|
|
256
|
+
def _bitnet_158_int8xint2_decode(
|
|
257
|
+
M,
|
|
258
|
+
N,
|
|
259
|
+
K,
|
|
260
|
+
in_dtype,
|
|
261
|
+
out_dtype,
|
|
262
|
+
accum_dtype,
|
|
263
|
+
fast_decoding=True,
|
|
264
|
+
n_partition=4,
|
|
265
|
+
reduce_thread=32,
|
|
266
|
+
):
|
|
267
|
+
assert in_dtype in [
|
|
268
|
+
"float16",
|
|
269
|
+
"int8",
|
|
270
|
+
], "Currently only float16 and int8 are supported"
|
|
271
|
+
assert out_dtype in [
|
|
272
|
+
"float16",
|
|
273
|
+
"float32",
|
|
274
|
+
"int32",
|
|
275
|
+
], "Currently only float16, float32 and int32 are supported"
|
|
276
|
+
storage_nbit = 8
|
|
277
|
+
num_bits = 2
|
|
278
|
+
A_shape = (M, K)
|
|
279
|
+
B_shape = (N, K // storage_nbit * num_bits)
|
|
280
|
+
C_shape = (M, N)
|
|
281
|
+
|
|
282
|
+
num_elems_per_byte = 4
|
|
283
|
+
MAX_TRANSACTION_SIZE_IN_BITS = 128
|
|
284
|
+
micro_size_k = MAX_TRANSACTION_SIZE_IN_BITS // DataType(in_dtype).bits
|
|
285
|
+
micro_size_k_compressed = micro_size_k // num_elems_per_byte
|
|
286
|
+
storage_dtype = "int8"
|
|
287
|
+
block_K = reduce_thread * micro_size_k
|
|
288
|
+
|
|
289
|
+
use_dp4a = True
|
|
290
|
+
dp4a_size = 4
|
|
291
|
+
|
|
292
|
+
@T.prim_func
|
|
293
|
+
def _bitnet_158_int8xint2_decode_kernel(
|
|
294
|
+
A: T.Buffer(A_shape, in_dtype),
|
|
295
|
+
B: T.Buffer(B_shape, storage_dtype),
|
|
296
|
+
C: T.Buffer(C_shape, out_dtype),
|
|
297
|
+
):
|
|
298
|
+
with T.Kernel(
|
|
299
|
+
T.ceildiv(N, n_partition),
|
|
300
|
+
M,
|
|
301
|
+
threads=(reduce_thread, n_partition),
|
|
302
|
+
) as (
|
|
303
|
+
bx,
|
|
304
|
+
by,
|
|
305
|
+
):
|
|
306
|
+
A_local = T.alloc_local((micro_size_k,), in_dtype)
|
|
307
|
+
B_quant_local = T.alloc_local([micro_size_k_compressed], storage_dtype)
|
|
308
|
+
B_dequantize_local = T.alloc_local([micro_size_k], in_dtype)
|
|
309
|
+
accum_res = T.alloc_local((1,), accum_dtype)
|
|
310
|
+
reduced_accum_res = T.alloc_local((1,), accum_dtype)
|
|
311
|
+
|
|
312
|
+
kr = T.thread_binding(0, reduce_thread, thread="threadIdx.x")
|
|
313
|
+
ni = T.thread_binding(0, n_partition, thread="threadIdx.y")
|
|
314
|
+
|
|
315
|
+
T.import_source(decode_i2s_to_i8s)
|
|
316
|
+
|
|
317
|
+
T.clear(accum_res)
|
|
318
|
+
for ko in T.serial(T.ceildiv(K, block_K)):
|
|
319
|
+
for v in T.vectorized(micro_size_k):
|
|
320
|
+
A_local[v] = A[by, ko * block_K + kr * micro_size_k + v]
|
|
321
|
+
|
|
322
|
+
for v in T.vectorized(micro_size_k_compressed):
|
|
323
|
+
B_quant_local[v] = B[
|
|
324
|
+
bx * n_partition + ni,
|
|
325
|
+
ko * (reduce_thread * micro_size_k_compressed) +
|
|
326
|
+
kr * micro_size_k_compressed + v,
|
|
327
|
+
]
|
|
328
|
+
|
|
329
|
+
T.call_extern(
|
|
330
|
+
"handle",
|
|
331
|
+
"decode_i2u_to_i8s",
|
|
332
|
+
T.address_of(B_quant_local[0]),
|
|
333
|
+
T.address_of(B_dequantize_local[0]),
|
|
334
|
+
)
|
|
335
|
+
|
|
336
|
+
if use_dp4a:
|
|
337
|
+
for ki in T.serial(micro_size_k // dp4a_size):
|
|
338
|
+
T.dp4a(
|
|
339
|
+
A_local[ki * dp4a_size],
|
|
340
|
+
B_dequantize_local[ki * dp4a_size],
|
|
341
|
+
accum_res[0],
|
|
342
|
+
)
|
|
343
|
+
else:
|
|
344
|
+
for ki in T.serial(micro_size_k):
|
|
345
|
+
accum_res[0] += A_local[ki] * B_dequantize_local[ki]
|
|
346
|
+
|
|
347
|
+
with T.attr(
|
|
348
|
+
T.comm_reducer(lambda x, y: x + y, [T.Cast(accum_dtype, 0)]),
|
|
349
|
+
"reduce_scope",
|
|
350
|
+
T.reinterpret(T.uint64(0), dtype="handle"),
|
|
351
|
+
):
|
|
352
|
+
T.evaluate(
|
|
353
|
+
T.tvm_thread_allreduce(
|
|
354
|
+
T.uint32(1),
|
|
355
|
+
accum_res[0],
|
|
356
|
+
True,
|
|
357
|
+
reduced_accum_res[0],
|
|
358
|
+
kr,
|
|
359
|
+
dtype="handle",
|
|
360
|
+
))
|
|
361
|
+
if kr == 0:
|
|
362
|
+
C[by, bx * n_partition + ni] = reduced_accum_res[0]
|
|
363
|
+
|
|
364
|
+
return _bitnet_158_int8xint2_decode_kernel
|
|
365
|
+
|
|
366
|
+
|
|
367
|
+
class Bitnet_158_int8xint2_kernel(nn.Module):
|
|
368
|
+
|
|
369
|
+
def __init__(self,
|
|
370
|
+
M,
|
|
371
|
+
N,
|
|
372
|
+
K,
|
|
373
|
+
in_dtype,
|
|
374
|
+
out_dtype,
|
|
375
|
+
accum_dtype,
|
|
376
|
+
fast_decoding=True):
|
|
377
|
+
super().__init__()
|
|
378
|
+
self.in_dtype = in_dtype
|
|
379
|
+
self.accum_dtype = accum_dtype
|
|
380
|
+
self.prefill_program = _bitnet_158_int8xint2_prefill(M, N, K, in_dtype, out_dtype, accum_dtype, fast_decoding)
|
|
381
|
+
self.prefill_kernel = tilelang.compile(self.prefill_program)
|
|
382
|
+
|
|
383
|
+
self.decode_program = _bitnet_158_int8xint2_decode(M, N, K, in_dtype, out_dtype, accum_dtype, fast_decoding)
|
|
384
|
+
self.decode_kernel = tilelang.compile(self.decode_program)
|
|
385
|
+
|
|
386
|
+
@staticmethod
|
|
387
|
+
def general_compress(lowprecision_weight, source_bits=4, storage_dtype=np.int8):
|
|
388
|
+
elems_per_byte = 8 // source_bits
|
|
389
|
+
if lowprecision_weight.dtype == np.float16:
|
|
390
|
+
lowprecision_weight = lowprecision_weight.astype(dtype=np.int8)
|
|
391
|
+
int8_weight = np.zeros(
|
|
392
|
+
(
|
|
393
|
+
*lowprecision_weight.shape[:-1],
|
|
394
|
+
lowprecision_weight.shape[-1] // elems_per_byte,
|
|
395
|
+
),
|
|
396
|
+
dtype=np.int8,
|
|
397
|
+
)
|
|
398
|
+
for j in range(lowprecision_weight.shape[-1] // elems_per_byte):
|
|
399
|
+
for k in range(elems_per_byte):
|
|
400
|
+
int8_weight[:, j] |= lowprecision_weight[:, j * elems_per_byte + k] << (source_bits * k)
|
|
401
|
+
|
|
402
|
+
return int8_weight.view(storage_dtype)
|
|
403
|
+
|
|
404
|
+
|
|
405
|
+
# interleave weight numpy implementation
|
|
406
|
+
@staticmethod
|
|
407
|
+
def interleave_weight(qweight, nbits=4, target_dtype="float16"):
|
|
408
|
+
assert target_dtype in ["float16", "int8"]
|
|
409
|
+
# reinterpret the data type of qweight to int32
|
|
410
|
+
qweight = qweight.view(np.int32)
|
|
411
|
+
new_qweight = np.zeros_like(qweight)
|
|
412
|
+
bits_stride = 8 if target_dtype == "int8" else 16
|
|
413
|
+
mask = (1 << nbits) - 1 # for 4bit the val is 0x0000000f
|
|
414
|
+
num_groups = 32 // bits_stride
|
|
415
|
+
elems_per_group = bits_stride // nbits
|
|
416
|
+
for i in range(num_groups):
|
|
417
|
+
for j in range(elems_per_group):
|
|
418
|
+
offset = i * elems_per_group + j
|
|
419
|
+
shift = (offset % num_groups) * bits_stride + (offset // num_groups) * nbits
|
|
420
|
+
new_qweight |= ((qweight >> (nbits * offset)) & mask) << shift
|
|
421
|
+
|
|
422
|
+
if nbits == 1 and target_dtype == "int8":
|
|
423
|
+
# special handling for 1b interleave
|
|
424
|
+
n16_weight = new_qweight & np.int32(0xF0F00F0F)
|
|
425
|
+
n16_weight |= ((new_qweight & np.int32(0x000000F0)) >> 4) << 16
|
|
426
|
+
n16_weight |= ((new_qweight & np.int32(0x0000F000)) >> 12) << 24
|
|
427
|
+
n16_weight |= ((new_qweight & np.int32(0x000F0000)) >> 16) << 4
|
|
428
|
+
n16_weight |= ((new_qweight & np.int32(0x0F000000)) >> 24) << 12
|
|
429
|
+
return n16_weight.view(np.int8)
|
|
430
|
+
elif nbits == 2 and target_dtype == "float16":
|
|
431
|
+
n8_weight = new_qweight & np.int32(0xFF0000FF)
|
|
432
|
+
n8_weight |= ((new_qweight & np.int32(0x0000FF00)) >> 8) << 16
|
|
433
|
+
n8_weight |= ((new_qweight & np.int32(0x00FF0000)) >> 16) << 8
|
|
434
|
+
return n8_weight.view(np.int8)
|
|
435
|
+
elif nbits == 1 and target_dtype == "float16":
|
|
436
|
+
n8_weight = new_qweight & 0xF000000F
|
|
437
|
+
n8_weight |= ((new_qweight & 0x000000F0) >> 4) << 8
|
|
438
|
+
n8_weight |= ((new_qweight & 0x00000F00) >> 8) << 16
|
|
439
|
+
n8_weight |= ((new_qweight & 0x0000F000) >> 12) << 24
|
|
440
|
+
n8_weight |= ((new_qweight & 0x000F0000) >> 16) << 4
|
|
441
|
+
n8_weight |= ((new_qweight & 0x00F00000) >> 20) << 12
|
|
442
|
+
n8_weight |= ((new_qweight & 0x0F000000) >> 24) << 20
|
|
443
|
+
|
|
444
|
+
return new_qweight.view(np.int8)
|
|
445
|
+
|
|
446
|
+
def get_B_int8(self, B):
|
|
447
|
+
qw = self.general_compress(B.cpu().numpy(), source_bits=2, storage_dtype=np.int8)
|
|
448
|
+
qw = self.interleave_weight(qw, 2, target_dtype=self.in_dtype)
|
|
449
|
+
qw = torch.from_numpy(qw).to(device="cuda")
|
|
450
|
+
return qw
|
|
451
|
+
|
|
452
|
+
def prefill(self, A, B, C):
|
|
453
|
+
src_code = self.prefill_kernel.get_kernel_source()
|
|
454
|
+
# src_code is the generated cuda source
|
|
455
|
+
assert src_code is not None
|
|
456
|
+
# print(src_code)
|
|
457
|
+
qw = self.get_B_int8(B)
|
|
458
|
+
self.prefill_kernel(A, qw, C)
|
|
459
|
+
return C
|
|
460
|
+
|
|
461
|
+
def decode(self, A, B, C):
|
|
462
|
+
src_code = self.decode_kernel.get_kernel_source()
|
|
463
|
+
# src_code is the generated cuda source
|
|
464
|
+
assert src_code is not None
|
|
465
|
+
# print(src_code)
|
|
466
|
+
qw = self.get_B_int8(B)
|
|
467
|
+
self.decode_kernel(A, qw, C)
|
|
468
|
+
return C
|
|
469
|
+
|
|
470
|
+
def profile(self, warmup=500):
|
|
471
|
+
pass
|
|
472
|
+
# latency = self.bwd_profiler.do_bench(warmup=warmup)
|
|
473
|
+
# return latency
|
|
474
|
+
|
|
475
|
+
def ref_program(self, A, B):
|
|
476
|
+
ref_c = torch.matmul(A.to(torch.float32), B.T.to(torch.float32)).to(getattr(torch, self.accum_dtype))
|
|
477
|
+
return ref_c
|
|
478
|
+
|
|
479
|
+
def check(self, A, B, C, mode):
|
|
480
|
+
if mode == "prefill":
|
|
481
|
+
C = self.prefill(A, B, C)
|
|
482
|
+
elif mode == "decode":
|
|
483
|
+
C = self.decode(A, B, C)
|
|
484
|
+
else:
|
|
485
|
+
raise ValueError("mode should be either 'prefill' or 'decode'")
|
|
486
|
+
|
|
487
|
+
ref_c = self.ref_program(A, B)
|
|
488
|
+
torch.testing.assert_close(C, ref_c, rtol=1e-2, atol=1e-2)
|
|
489
|
+
print(f"Bitnet_158_int8xint2 {mode} kernel check passed!")
|
|
490
|
+
|