skillproof 0.1.0__py3-none-any.whl
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- skillproof/__init__.py +3 -0
- skillproof/__main__.py +3 -0
- skillproof/assertions/__init__.py +62 -0
- skillproof/assertions/base.py +44 -0
- skillproof/assertions/builtin.py +176 -0
- skillproof/assertions/llm_judge.py +24 -0
- skillproof/cli.py +313 -0
- skillproof/config.py +188 -0
- skillproof/engine.py +268 -0
- skillproof/errors.py +72 -0
- skillproof/estimate.py +83 -0
- skillproof/judges/__init__.py +43 -0
- skillproof/judges/anthropic_judge.py +59 -0
- skillproof/judges/base.py +69 -0
- skillproof/judges/mock.py +21 -0
- skillproof/judges/openai_judge.py +58 -0
- skillproof/parsers/__init__.py +6 -0
- skillproof/parsers/claude_code.py +144 -0
- skillproof/parsers/codex.py +112 -0
- skillproof/report/__init__.py +34 -0
- skillproof/report/badge.py +60 -0
- skillproof/report/format.py +75 -0
- skillproof/report/html_report.py +296 -0
- skillproof/report/json_report.py +9 -0
- skillproof/report/markdown.py +78 -0
- skillproof/report/summary.py +216 -0
- skillproof/report/terminal.py +89 -0
- skillproof/results.py +88 -0
- skillproof/runners/__init__.py +33 -0
- skillproof/runners/base.py +102 -0
- skillproof/runners/claude_code.py +117 -0
- skillproof/runners/codex.py +133 -0
- skillproof/runners/mock.py +91 -0
- skillproof/runners/openai_compat.py +238 -0
- skillproof/sandbox.py +85 -0
- skillproof/scaffold.py +153 -0
- skillproof/skill.py +97 -0
- skillproof/stats.py +228 -0
- skillproof-0.1.0.dist-info/METADATA +262 -0
- skillproof-0.1.0.dist-info/RECORD +43 -0
- skillproof-0.1.0.dist-info/WHEEL +4 -0
- skillproof-0.1.0.dist-info/entry_points.txt +2 -0
- skillproof-0.1.0.dist-info/licenses/LICENSE +21 -0
skillproof/stats.py
ADDED
|
@@ -0,0 +1,228 @@
|
|
|
1
|
+
"""Turning trial results into numbers: pass rate, lift, trigger rate, deltas.
|
|
2
|
+
|
|
3
|
+
Conventions:
|
|
4
|
+
* Errored runs (infrastructure failures) are excluded from every rate.
|
|
5
|
+
* Timed-out runs count as failures (the agent didn't finish).
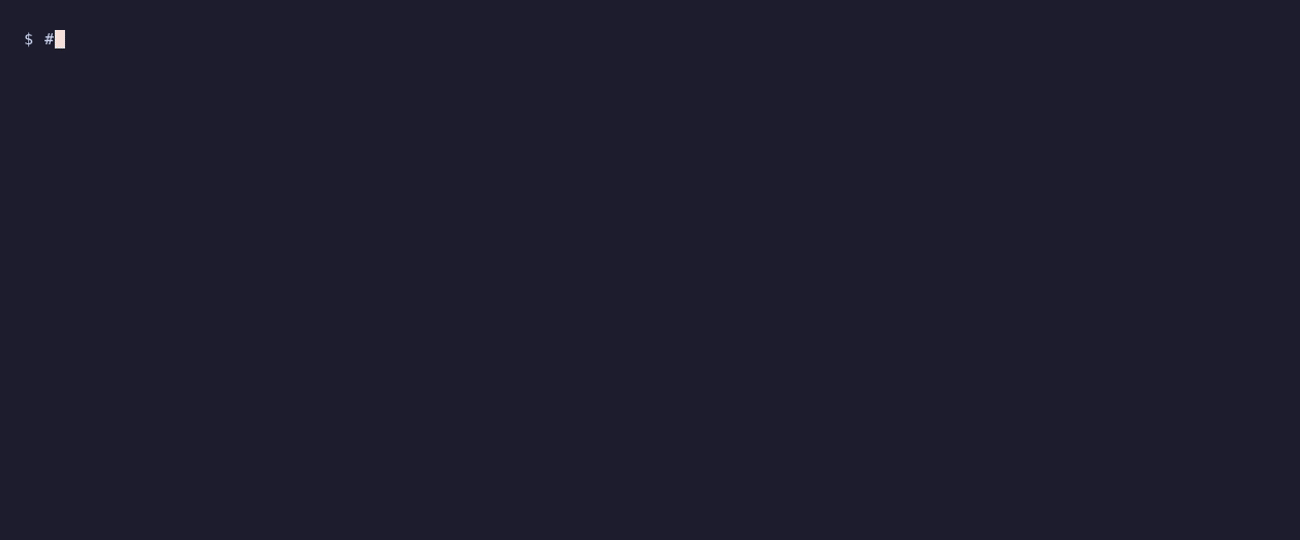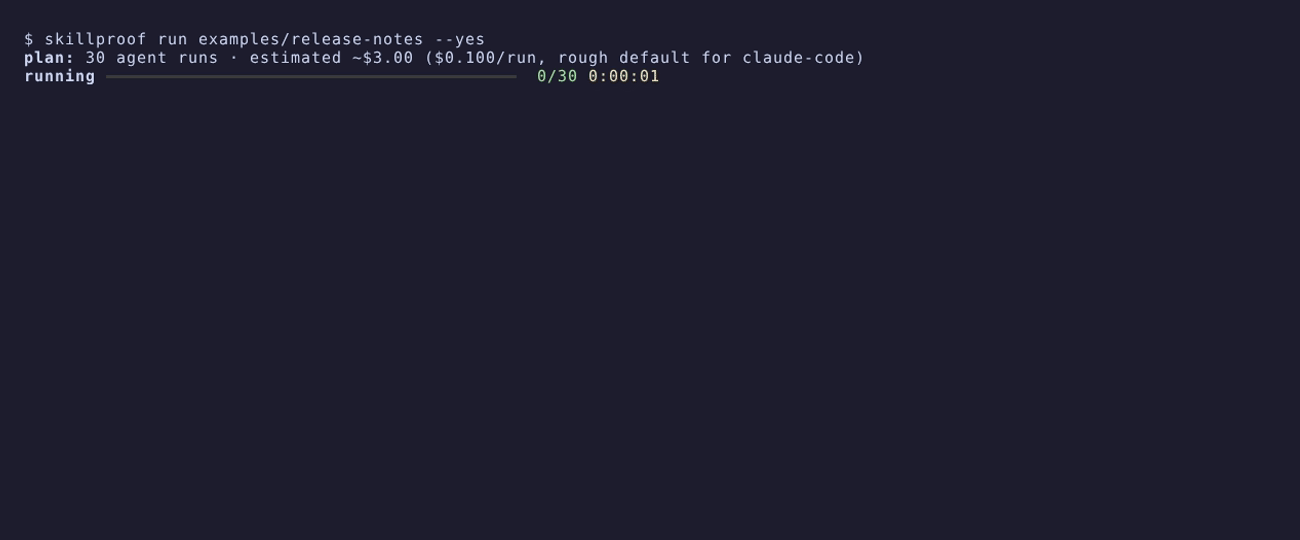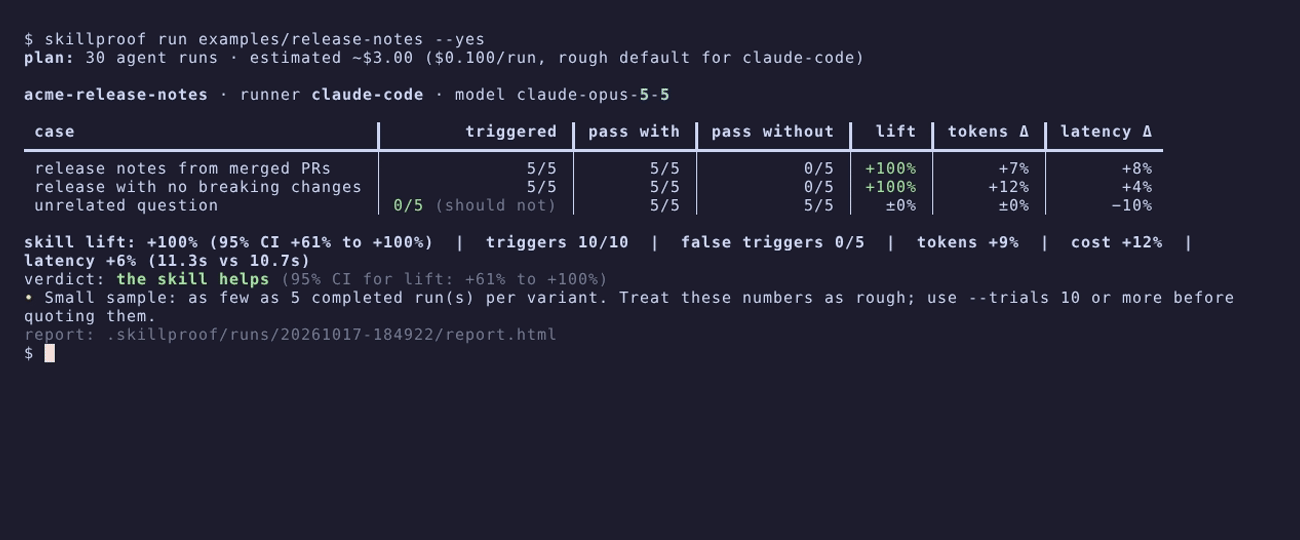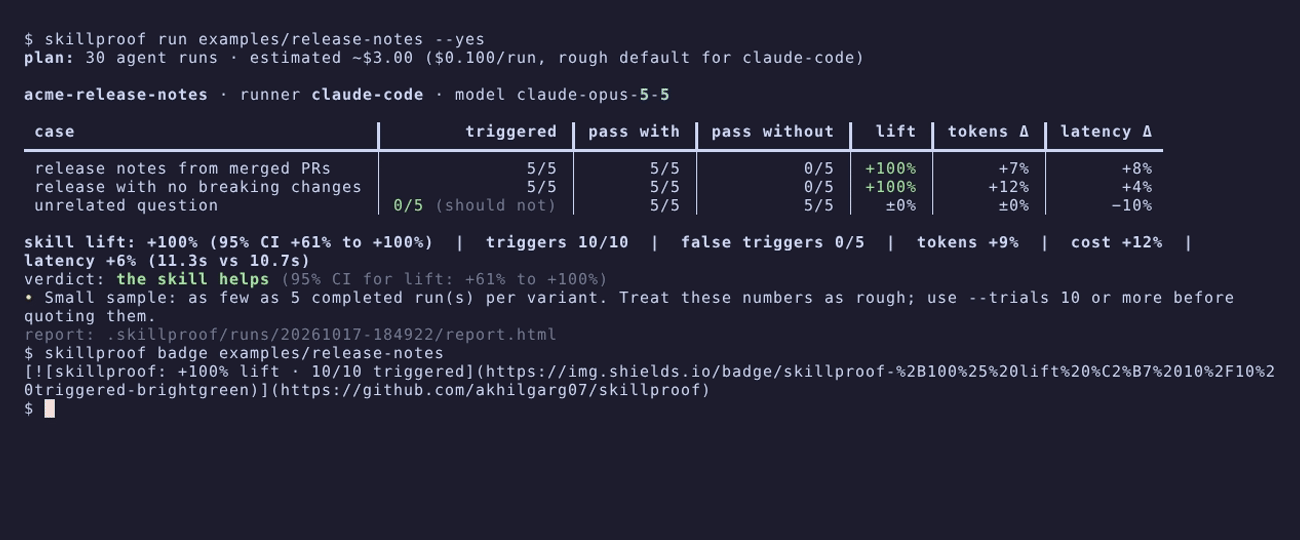
|
|
6
|
+
* Rates are fractions in [0, 1]; lift is a difference of fractions
|
|
7
|
+
(+0.23 means "23 percentage points better with the skill").
|
|
8
|
+
* Token, cost and latency deltas are relative: +0.10 means 10% more with the skill.
|
|
9
|
+
* Intervals are 95%: Wilson score intervals for pass rates and Newcombe's
|
|
10
|
+
method (built from the two Wilson intervals) for the lift. Both behave
|
|
11
|
+
sensibly at small n and at 0% / 100%, unlike the textbook normal formula.
|
|
12
|
+
* The headline (suite-level) lift pools every graded trial of the cases where
|
|
13
|
+
the skill should trigger, treating trials as independent. Negative cases
|
|
14
|
+
(`should_trigger: false`) only check that the skill does no harm, so they
|
|
15
|
+
are reported per case, not mixed into the headline. Cases with very
|
|
16
|
+
different difficulty make pooling approximate.
|
|
17
|
+
"""
|
|
18
|
+
|
|
19
|
+
from __future__ import annotations
|
|
20
|
+
|
|
21
|
+
import math
|
|
22
|
+
from dataclasses import dataclass
|
|
23
|
+
from typing import Literal
|
|
24
|
+
|
|
25
|
+
from skillproof.results import CaseResult, SuiteResult, TrialResult
|
|
26
|
+
|
|
27
|
+
Z_95 = 1.959964
|
|
28
|
+
# Below this many completed runs per variant, results get a "small sample" note.
|
|
29
|
+
MIN_RUNS_FOR_CONFIDENCE = 10
|
|
30
|
+
# Below this many completed runs per variant, no helps/hurts verdict is given at all:
|
|
31
|
+
# with 2/2 vs 0/2 the interval already excludes zero, but nobody should quote that.
|
|
32
|
+
MIN_RUNS_FOR_VERDICT = 5
|
|
33
|
+
|
|
34
|
+
Interval = tuple[float, float]
|
|
35
|
+
Verdict = Literal["helps", "hurts", "no clear effect", "too few runs", "not measured"]
|
|
36
|
+
|
|
37
|
+
|
|
38
|
+
def wilson_interval(successes: int, n: int, z: float = Z_95) -> Interval | None:
|
|
39
|
+
"""95% Wilson score interval for a pass rate."""
|
|
40
|
+
if n == 0:
|
|
41
|
+
return None
|
|
42
|
+
p = successes / n
|
|
43
|
+
denom = 1 + z * z / n
|
|
44
|
+
center = (p + z * z / (2 * n)) / denom
|
|
45
|
+
half = z * math.sqrt(p * (1 - p) / n + z * z / (4 * n * n)) / denom
|
|
46
|
+
return max(0.0, center - half), min(1.0, center + half)
|
|
47
|
+
|
|
48
|
+
|
|
49
|
+
def lift_interval(with_: VariantStats, without: VariantStats) -> Interval | None:
|
|
50
|
+
"""95% interval for (pass rate with) - (pass rate without), Newcombe's hybrid score method."""
|
|
51
|
+
p1, p2 = with_.pass_rate, without.pass_rate
|
|
52
|
+
ci1, ci2 = with_.pass_interval, without.pass_interval
|
|
53
|
+
if p1 is None or p2 is None or ci1 is None or ci2 is None:
|
|
54
|
+
return None
|
|
55
|
+
(l1, u1), (l2, u2) = ci1, ci2
|
|
56
|
+
diff = p1 - p2
|
|
57
|
+
low = diff - math.sqrt((p1 - l1) ** 2 + (u2 - p2) ** 2)
|
|
58
|
+
high = diff + math.sqrt((u1 - p1) ** 2 + (p2 - l2) ** 2)
|
|
59
|
+
return low, high
|
|
60
|
+
|
|
61
|
+
|
|
62
|
+
def verdict(lift: float | None, interval: Interval | None, runs: int) -> Verdict:
|
|
63
|
+
"""`runs` is the smaller number of completed runs of the two variants."""
|
|
64
|
+
if lift is None or interval is None:
|
|
65
|
+
return "not measured"
|
|
66
|
+
if runs < MIN_RUNS_FOR_VERDICT:
|
|
67
|
+
return "too few runs"
|
|
68
|
+
if interval[0] > 0:
|
|
69
|
+
return "helps"
|
|
70
|
+
if interval[1] < 0:
|
|
71
|
+
return "hurts"
|
|
72
|
+
return "no clear effect"
|
|
73
|
+
|
|
74
|
+
|
|
75
|
+
@dataclass
|
|
76
|
+
class VariantStats:
|
|
77
|
+
runs: int # completed runs (errors excluded)
|
|
78
|
+
errors: int
|
|
79
|
+
passed: int
|
|
80
|
+
triggered: int
|
|
81
|
+
trigger_known: int # runs where the runner could tell whether the skill fired
|
|
82
|
+
mean_tokens: float | None
|
|
83
|
+
mean_cost_usd: float | None # None unless every completed run reported a cost
|
|
84
|
+
mean_duration_s: float | None
|
|
85
|
+
|
|
86
|
+
@property
|
|
87
|
+
def pass_rate(self) -> float | None:
|
|
88
|
+
return self.passed / self.runs if self.runs else None
|
|
89
|
+
|
|
90
|
+
@property
|
|
91
|
+
def pass_interval(self) -> Interval | None:
|
|
92
|
+
return wilson_interval(self.passed, self.runs)
|
|
93
|
+
|
|
94
|
+
@property
|
|
95
|
+
def trigger_rate(self) -> float | None:
|
|
96
|
+
return self.triggered / self.trigger_known if self.trigger_known else None
|
|
97
|
+
|
|
98
|
+
|
|
99
|
+
class _Deltas:
|
|
100
|
+
"""Lift and relative deltas shared by case- and suite-level stats."""
|
|
101
|
+
|
|
102
|
+
with_skill: VariantStats
|
|
103
|
+
without_skill: VariantStats
|
|
104
|
+
|
|
105
|
+
@property
|
|
106
|
+
def graded(self) -> bool:
|
|
107
|
+
return True
|
|
108
|
+
|
|
109
|
+
@property
|
|
110
|
+
def lift(self) -> float | None:
|
|
111
|
+
if not self.graded:
|
|
112
|
+
return None
|
|
113
|
+
return _diff(self.with_skill.pass_rate, self.without_skill.pass_rate)
|
|
114
|
+
|
|
115
|
+
@property
|
|
116
|
+
def lift_interval(self) -> Interval | None:
|
|
117
|
+
if not self.graded:
|
|
118
|
+
return None
|
|
119
|
+
return lift_interval(self.with_skill, self.without_skill)
|
|
120
|
+
|
|
121
|
+
@property
|
|
122
|
+
def verdict(self) -> Verdict:
|
|
123
|
+
runs = min(self.with_skill.runs, self.without_skill.runs)
|
|
124
|
+
return verdict(self.lift, self.lift_interval, runs)
|
|
125
|
+
|
|
126
|
+
@property
|
|
127
|
+
def token_delta(self) -> float | None:
|
|
128
|
+
return _relative(self.with_skill.mean_tokens, self.without_skill.mean_tokens)
|
|
129
|
+
|
|
130
|
+
@property
|
|
131
|
+
def cost_delta(self) -> float | None:
|
|
132
|
+
return _relative(self.with_skill.mean_cost_usd, self.without_skill.mean_cost_usd)
|
|
133
|
+
|
|
134
|
+
@property
|
|
135
|
+
def latency_delta(self) -> float | None:
|
|
136
|
+
return _relative(self.with_skill.mean_duration_s, self.without_skill.mean_duration_s)
|
|
137
|
+
|
|
138
|
+
|
|
139
|
+
@dataclass
|
|
140
|
+
class CaseStats(_Deltas):
|
|
141
|
+
name: str
|
|
142
|
+
should_trigger: bool
|
|
143
|
+
has_assertions: bool
|
|
144
|
+
with_skill: VariantStats
|
|
145
|
+
without_skill: VariantStats
|
|
146
|
+
|
|
147
|
+
@property
|
|
148
|
+
def graded(self) -> bool:
|
|
149
|
+
return self.has_assertions
|
|
150
|
+
|
|
151
|
+
|
|
152
|
+
@dataclass
|
|
153
|
+
class SuiteStats(_Deltas):
|
|
154
|
+
cases: list[CaseStats]
|
|
155
|
+
with_skill: VariantStats # pooled over graded should_trigger cases
|
|
156
|
+
without_skill: VariantStats
|
|
157
|
+
triggers: int # skill fired, in with-skill runs of should_trigger cases
|
|
158
|
+
trigger_runs: int
|
|
159
|
+
false_triggers: int # skill fired, in with-skill runs of should_trigger: false cases
|
|
160
|
+
false_trigger_runs: int
|
|
161
|
+
errors: int
|
|
162
|
+
|
|
163
|
+
@property
|
|
164
|
+
def min_runs(self) -> int:
|
|
165
|
+
"""Fewest completed runs in any graded variant: the weakest link for confidence."""
|
|
166
|
+
counts = [
|
|
167
|
+
v.runs for c in self.cases if c.has_assertions for v in (c.with_skill, c.without_skill)
|
|
168
|
+
]
|
|
169
|
+
return min(counts) if counts else 0
|
|
170
|
+
|
|
171
|
+
|
|
172
|
+
def _diff(a: float | None, b: float | None) -> float | None:
|
|
173
|
+
return None if a is None or b is None else a - b
|
|
174
|
+
|
|
175
|
+
|
|
176
|
+
def _relative(a: float | None, b: float | None) -> float | None:
|
|
177
|
+
if a is None or b is None or b == 0:
|
|
178
|
+
return None
|
|
179
|
+
return a / b - 1
|
|
180
|
+
|
|
181
|
+
|
|
182
|
+
def _mean(values: list[float]) -> float | None:
|
|
183
|
+
return sum(values) / len(values) if values else None
|
|
184
|
+
|
|
185
|
+
|
|
186
|
+
def variant_stats(trials: list[TrialResult]) -> VariantStats:
|
|
187
|
+
done = [t for t in trials if not t.errored]
|
|
188
|
+
known = [t for t in done if t.run.triggered is not None]
|
|
189
|
+
costs = [t.run.usage.cost_usd for t in done]
|
|
190
|
+
return VariantStats(
|
|
191
|
+
runs=len(done),
|
|
192
|
+
errors=len(trials) - len(done),
|
|
193
|
+
passed=sum(t.passed for t in done),
|
|
194
|
+
triggered=sum(bool(t.run.triggered) for t in known),
|
|
195
|
+
trigger_known=len(known),
|
|
196
|
+
mean_tokens=_mean([t.run.usage.total_tokens for t in done]),
|
|
197
|
+
mean_cost_usd=None if None in costs else _mean([c for c in costs if c is not None]),
|
|
198
|
+
mean_duration_s=_mean([t.run.duration_s for t in done]),
|
|
199
|
+
)
|
|
200
|
+
|
|
201
|
+
|
|
202
|
+
def case_stats(case: CaseResult) -> CaseStats:
|
|
203
|
+
return CaseStats(
|
|
204
|
+
name=case.name,
|
|
205
|
+
should_trigger=case.should_trigger,
|
|
206
|
+
has_assertions=case.has_assertions,
|
|
207
|
+
with_skill=variant_stats(case.variant("with")),
|
|
208
|
+
without_skill=variant_stats(case.variant("without")),
|
|
209
|
+
)
|
|
210
|
+
|
|
211
|
+
|
|
212
|
+
def suite_stats(suite: SuiteResult) -> SuiteStats:
|
|
213
|
+
cases = [case_stats(c) for c in suite.cases]
|
|
214
|
+
graded = [c for c in suite.cases if c.has_assertions and c.should_trigger]
|
|
215
|
+
if not graded: # only negative cases: fall back to pooling everything graded
|
|
216
|
+
graded = [c for c in suite.cases if c.has_assertions]
|
|
217
|
+
positive = [s.with_skill for s in cases if s.should_trigger]
|
|
218
|
+
negative = [s.with_skill for s in cases if not s.should_trigger]
|
|
219
|
+
return SuiteStats(
|
|
220
|
+
cases=cases,
|
|
221
|
+
with_skill=variant_stats([t for c in graded for t in c.variant("with")]),
|
|
222
|
+
without_skill=variant_stats([t for c in graded for t in c.variant("without")]),
|
|
223
|
+
triggers=sum(v.triggered for v in positive),
|
|
224
|
+
trigger_runs=sum(v.trigger_known for v in positive),
|
|
225
|
+
false_triggers=sum(v.triggered for v in negative),
|
|
226
|
+
false_trigger_runs=sum(v.trigger_known for v in negative),
|
|
227
|
+
errors=sum(s.with_skill.errors + s.without_skill.errors for s in cases),
|
|
228
|
+
)
|
|
@@ -0,0 +1,262 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: skillproof
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: pytest for agent skills: prove your skill actually works.
|
|
5
|
+
Project-URL: Homepage, https://github.com/akhilgarg07/skillproof
|
|
6
|
+
Project-URL: Issues, https://github.com/akhilgarg07/skillproof/issues
|
|
7
|
+
Project-URL: Source, https://github.com/akhilgarg07/skillproof
|
|
8
|
+
Author: Akhil Garg
|
|
9
|
+
License-Expression: MIT
|
|
10
|
+
License-File: LICENSE
|
|
11
|
+
Keywords: agent-skills,claude-code,codex,evals,llm,testing
|
|
12
|
+
Classifier: Development Status :: 3 - Alpha
|
|
13
|
+
Classifier: Environment :: Console
|
|
14
|
+
Classifier: Intended Audience :: Developers
|
|
15
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
16
|
+
Classifier: Programming Language :: Python :: 3
|
|
17
|
+
Classifier: Programming Language :: Python :: 3.10
|
|
18
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
19
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
20
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
21
|
+
Classifier: Topic :: Software Development :: Testing
|
|
22
|
+
Requires-Python: >=3.10
|
|
23
|
+
Requires-Dist: anthropic>=1.15
|
|
24
|
+
Requires-Dist: claude-agent-sdk>=0.2.168
|
|
25
|
+
Requires-Dist: openai>=3.0
|
|
26
|
+
Requires-Dist: pydantic>=2.6
|
|
27
|
+
Requires-Dist: pyyaml>=6.0
|
|
28
|
+
Requires-Dist: rich>=13.7
|
|
29
|
+
Requires-Dist: typer>=0.12
|
|
30
|
+
Provides-Extra: dev
|
|
31
|
+
Requires-Dist: pytest>=8; extra == 'dev'
|
|
32
|
+
Requires-Dist: ruff>=0.6; extra == 'dev'
|
|
33
|
+
Description-Content-Type: text/markdown
|
|
34
|
+
|
|
35
|
+
# skillproof
|
|
36
|
+
|
|
37
|
+
**pytest for agent skills: prove your skill actually works.**
|
|
38
|
+
|
|
39
|
+
[](https://github.com/akhilgarg07/skillproof/actions/workflows/ci.yml)
|
|
40
|
+
[](https://github.com/akhilgarg07/skillproof/blob/main/LICENSE)
|
|
41
|
+
|
|
42
|
+
|
|
43
|
+
<!-- Record with: vhs docs/demo.tape -->
|
|
44
|
+
|
|
45
|
+
```bash
|
|
46
|
+
pip install skillproof
|
|
47
|
+
```
|
|
48
|
+
|
|
49
|
+
**Works with:** Claude Code · Codex · any OpenAI-compatible endpoint
|
|
50
|
+
|
|
51
|
+
---
|
|
52
|
+
|
|
53
|
+
Agent skills (`SKILL.md` folders for Claude Code, Codex, Cursor, Gemini CLI,
|
|
54
|
+
OpenCode...) are everywhere, but almost nobody can show that a skill helps. Often
|
|
55
|
+
it isn't even loaded: the agent never decides to use it. **skillproof** runs your
|
|
56
|
+
tasks N times **with** the skill installed and N times **without** it, then tells
|
|
57
|
+
you:
|
|
58
|
+
|
|
59
|
+
- **Trigger rate**: did the agent actually load the skill?
|
|
60
|
+
- **Lift**: pass rate with the skill minus pass rate without it, with a 95% confidence interval
|
|
61
|
+
- **Cost**: extra (or saved) tokens, dollars and seconds per run
|
|
62
|
+
- **A verdict**: *helps*, *hurts*, *no clear effect*, or *too few runs* to say
|
|
63
|
+
|
|
64
|
+
## 60-second quickstart
|
|
65
|
+
|
|
66
|
+
```bash
|
|
67
|
+
pip install skillproof
|
|
68
|
+
export ANTHROPIC_API_KEY=sk-ant-... # or use your `claude` login
|
|
69
|
+
|
|
70
|
+
skillproof init ./my-skill # writes my-skill/evals.yaml
|
|
71
|
+
# edit evals.yaml: 2-3 real tasks, how to check them, one task the skill should ignore
|
|
72
|
+
skillproof run ./my-skill # prints the plan and cost estimate, then runs
|
|
73
|
+
```
|
|
74
|
+
|
|
75
|
+
`uvx skillproof run ./my-skill` works too, without installing anything.
|
|
76
|
+
|
|
77
|
+
## Example output
|
|
78
|
+
|
|
79
|
+
This is a real run of the [`release-notes`](https://github.com/akhilgarg07/skillproof/blob/main/examples/release-notes/) example
|
|
80
|
+
(Claude Code, 5 trials per variant):
|
|
81
|
+
|
|
82
|
+
```
|
|
83
|
+
acme-release-notes · runner claude-code · model claude-opus-5-5
|
|
84
|
+
|
|
85
|
+
case ┃ triggered ┃ pass with ┃ pass without ┃ lift ┃ tokens Δ ┃ latency Δ
|
|
86
|
+
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━╇━━━━━━━━━━━━━━╇━━━━━━━╇━━━━━━━━━━╇━━━━━━━━━━━
|
|
87
|
+
release notes from merged PRs │ 5/5 │ 5/5 │ 0/5 │ +100% │ +7% │ −3%
|
|
88
|
+
release with no breaking changes │ 5/5 │ 5/5 │ 0/5 │ +100% │ +7% │ +3%
|
|
89
|
+
unrelated question │ 0/5 (should not) │ 4/5 │ 5/5 │ −20% │ ±0% │ −2%
|
|
90
|
+
|
|
91
|
+
skill lift: +100% (95% CI +61% to +100%) | triggers 10/10 | false triggers 0/5 | tokens +7% | cost +10%
|
|
92
|
+
verdict: the skill helps (95% CI for lift: +61% to +100%)
|
|
93
|
+
• Small sample: as few as 5 completed run(s) per variant. Treat these numbers as rough; use --trials 10 or more
|
|
94
|
+
before quoting them.
|
|
95
|
+
```
|
|
96
|
+
|
|
97
|
+
Every run also saves a self-contained **HTML report** (with each run's checks and
|
|
98
|
+
answer), `report.md`, `summary.json` and the full transcripts under
|
|
99
|
+
`.skillproof/runs/<timestamp>/`.
|
|
100
|
+
|
|
101
|
+
[`examples/`](https://github.com/akhilgarg07/skillproof/blob/main/examples/) has skills that **help**, **do nothing** and **hurt**, so
|
|
102
|
+
you can see all three outcomes.
|
|
103
|
+
|
|
104
|
+
## How it works
|
|
105
|
+
|
|
106
|
+
```
|
|
107
|
+
for each case in evals.yaml, N trials, interleaved:
|
|
108
|
+
with skill: fresh temp dir + fixtures + skill installed -> agent -> checks
|
|
109
|
+
without skill: fresh temp dir + fixtures, no skill -> agent -> checks
|
|
110
|
+
```
|
|
111
|
+
|
|
112
|
+
- Every run gets a **fresh temp directory** with your fixtures copied in. Your
|
|
113
|
+
project is never touched.
|
|
114
|
+
- Your **personal** skills, settings and instructions (`~/.claude`, `~/.codex`,
|
|
115
|
+
`~/.agents`) are not loaded for either variant, so the only difference is the skill.
|
|
116
|
+
- The agent can't see your `evals.yaml` or its checks.
|
|
117
|
+
- Transcripts, token usage and tool calls are saved for every run, with API keys redacted.
|
|
118
|
+
|
|
119
|
+
## evals.yaml
|
|
120
|
+
|
|
121
|
+
```yaml
|
|
122
|
+
skill: ./ # folder containing SKILL.md
|
|
123
|
+
runner: claude-code # claude-code | codex | openai-compatible
|
|
124
|
+
# model: claude-sonnet-5-5 # optional; the agent's default otherwise
|
|
125
|
+
trials: 5 # runs per case, per variant
|
|
126
|
+
timeout: 300 # seconds per run
|
|
127
|
+
|
|
128
|
+
cases:
|
|
129
|
+
- name: "summarizes stack trace"
|
|
130
|
+
prompt: "Here is an error log in error.log. What's wrong?" # don't name the skill
|
|
131
|
+
fixtures: ./fixtures/case1/ # copied into each run's temp dir
|
|
132
|
+
assert:
|
|
133
|
+
- type: contains
|
|
134
|
+
value: "NullPointerException"
|
|
135
|
+
- type: file_exists
|
|
136
|
+
path: fix.patch
|
|
137
|
+
- type: command # runs in the temp dir; passes on exit code 0
|
|
138
|
+
run: "python -m pytest -q"
|
|
139
|
+
- type: max_tokens
|
|
140
|
+
value: 20000
|
|
141
|
+
- type: llm_judge # optional; graded by a model from another vendor
|
|
142
|
+
rubric: "States the root cause in the first sentence."
|
|
143
|
+
|
|
144
|
+
- name: "unrelated question" # catches skills that load when they shouldn't
|
|
145
|
+
prompt: "What's the capital of France?"
|
|
146
|
+
should_trigger: false
|
|
147
|
+
assert:
|
|
148
|
+
- {type: contains, value: "Paris"}
|
|
149
|
+
```
|
|
150
|
+
|
|
151
|
+
| assertion | passes when |
|
|
152
|
+
|---|---|
|
|
153
|
+
| `contains` / `not_contains` | the final answer contains / doesn't contain `value` (case-insensitive by default) |
|
|
154
|
+
| `regex` | the final answer matches `pattern` |
|
|
155
|
+
| `file_exists` / `file_contains` | a file in the temp dir exists / contains `value` |
|
|
156
|
+
| `command` | `run` exits 0 in the temp dir (API keys are removed from its environment) |
|
|
157
|
+
| `max_tokens` | the run used at most `value` tokens (input + output + cache) |
|
|
158
|
+
| `llm_judge` | a judge model says the answer meets `rubric` |
|
|
159
|
+
|
|
160
|
+
Use deterministic checks first. `llm_judge` defaults to a judge from a **different
|
|
161
|
+
vendor** than the agent (Claude agents are graded by an OpenAI model and vice
|
|
162
|
+
versa), so no model grades its own family. Change it with
|
|
163
|
+
`judge: {provider: anthropic, model: ...}`.
|
|
164
|
+
|
|
165
|
+
## Runners
|
|
166
|
+
|
|
167
|
+
| runner | how it runs | where the skill goes | how a trigger is detected |
|
|
168
|
+
|---|---|---|---|
|
|
169
|
+
| `claude-code` | [Claude Agent SDK](https://code.claude.com/docs/en/agent-sdk/overview) | `<temp>/.claude/skills/<name>/` | a `Skill` tool call naming the skill |
|
|
170
|
+
| `codex` | `codex exec --json` | `<temp>/.agents/skills/<name>/` | a shell command that reads the skill's folder |
|
|
171
|
+
| `openai-compatible` | a small tool-using loop over Chat Completions | SKILL.md pasted into the system prompt | not measured (**approximate**) |
|
|
172
|
+
|
|
173
|
+
Keys come from environment variables only: `ANTHROPIC_API_KEY` (or your `claude`
|
|
174
|
+
login), `CODEX_API_KEY` / `OPENAI_API_KEY` (or `codex login`). Runner settings go
|
|
175
|
+
under `runner_options:`; see each runner's module docstring.
|
|
176
|
+
|
|
177
|
+
## Reports, CI and badges
|
|
178
|
+
|
|
179
|
+
```bash
|
|
180
|
+
skillproof run ./my-skill --format md -o report.md # also: html, json (to stdout)
|
|
181
|
+
skillproof report # re-render the latest run
|
|
182
|
+
skillproof run ./my-skill --min-lift 0 --min-trigger-rate 80 # exit 1 if not met
|
|
183
|
+
skillproof run ./my-skill --dry-run # plan + cost estimate only
|
|
184
|
+
```
|
|
185
|
+
|
|
186
|
+
**Cost guard:** before every run skillproof prints the number of runs and an
|
|
187
|
+
estimate based on your previous runs. Above $5 it asks first; in CI it refuses
|
|
188
|
+
unless you pass `--yes`. If the first runs all fail (bad key, wrong model), it
|
|
189
|
+
stops and tells you what to fix.
|
|
190
|
+
|
|
191
|
+
**GitHub Action:** comments the results on pull requests and keeps the comment up to date.
|
|
192
|
+
|
|
193
|
+
```yaml
|
|
194
|
+
# .github/workflows/skillproof.yml (full example: action/example-workflow.yml)
|
|
195
|
+
on: pull_request
|
|
196
|
+
permissions: {contents: read, pull-requests: write}
|
|
197
|
+
jobs:
|
|
198
|
+
skillproof:
|
|
199
|
+
runs-on: ubuntu-latest
|
|
200
|
+
steps:
|
|
201
|
+
- uses: actions/checkout@v4
|
|
202
|
+
- uses: akhilgarg07/skillproof@v0
|
|
203
|
+
with: {path: my-skill, trials: "10", min-lift: "0"}
|
|
204
|
+
env: {ANTHROPIC_API_KEY: "${{ secrets.ANTHROPIC_API_KEY }}"}
|
|
205
|
+
```
|
|
206
|
+
|
|
207
|
+
**Badge for your skill's README:**
|
|
208
|
+
|
|
209
|
+
```bash
|
|
210
|
+
skillproof badge ./my-skill
|
|
211
|
+
# [](...)
|
|
212
|
+
```
|
|
213
|
+
|
|
214
|
+
It is green when the skill helps, red when it hurts and grey when the result is
|
|
215
|
+
not significant or comes from fewer than 5 runs per variant. `--json` prints a
|
|
216
|
+
[shields.io endpoint](https://shields.io/badges/endpoint-badge) file instead, so CI
|
|
217
|
+
can keep a badge up to date.
|
|
218
|
+
|
|
219
|
+
## Honest numbers: what this can and can't tell you
|
|
220
|
+
|
|
221
|
+
- **It measures your tasks, not the skill in general.** Lift depends on the prompts
|
|
222
|
+
and checks you write. Publish your `evals.yaml` next to any number you share.
|
|
223
|
+
- **Small samples are noisy.** Every rate comes with a 95% interval (Wilson for pass
|
|
224
|
+
rates, Newcombe for the lift). Below 5 runs per variant there's no verdict at all,
|
|
225
|
+
and below 10 the report says the numbers are rough.
|
|
226
|
+
- **Results depend on the agent and model.** Reports record the model that actually
|
|
227
|
+
ran. In our runs, Claude Code read a library's source, noticed that a skill's docs
|
|
228
|
+
were stale and ignored them ([`examples/stale-docs`](https://github.com/akhilgarg07/skillproof/blob/main/examples/stale-docs/)); a
|
|
229
|
+
weaker model may not.
|
|
230
|
+
- **Trigger detection is per agent and heuristic.** Claude Code has an explicit
|
|
231
|
+
`Skill` tool call. Codex reads skills with ordinary shell commands, so a "trigger"
|
|
232
|
+
there means a command touched the skill's folder.
|
|
233
|
+
- **The `openai-compatible` runner is an approximation.** It pastes SKILL.md into the
|
|
234
|
+
system prompt instead of letting the agent discover and load it, so it can't
|
|
235
|
+
measure trigger rate and overstates how often a skill is "used". Reports label it.
|
|
236
|
+
- **Token deltas include cache reads,** which are cheap. Look at the cost delta when
|
|
237
|
+
the agent reports cost (Claude Code does).
|
|
238
|
+
- **`llm_judge` is a model's opinion.** It's cross-vendor by default, but still noisy;
|
|
239
|
+
prefer deterministic checks.
|
|
240
|
+
- **Agents run real commands.** Runs happen in temp directories, but agents run
|
|
241
|
+
without permission prompts, so a command could still reach other files on your
|
|
242
|
+
machine. Test untrusted skills in a container or VM.
|
|
243
|
+
|
|
244
|
+
## Leaderboard
|
|
245
|
+
|
|
246
|
+
[`leaderboard/`](https://github.com/akhilgarg07/skillproof/blob/main/leaderboard/) runs skillproof over a list of public skills (using
|
|
247
|
+
evals you write, never the repo's own) and renders a markdown leaderboard.
|
|
248
|
+
|
|
249
|
+
## Contributing
|
|
250
|
+
|
|
251
|
+
Contributions are very welcome; see [CONTRIBUTING.md](https://github.com/akhilgarg07/skillproof/blob/main/CONTRIBUTING.md). Good first issues:
|
|
252
|
+
|
|
253
|
+
- **New runners:** Gemini CLI, Cursor (cursor-agent), OpenCode, Aider
|
|
254
|
+
- **New assertions:** `tool_called` (the agent used a given tool), `json_schema`,
|
|
255
|
+
`file_matches` (regex on a file), `max_cost_usd`
|
|
256
|
+
- **`skillproof compare`:** two versions of a skill head to head
|
|
257
|
+
- **Windows support** and a Docker sandbox option for untrusted skills
|
|
258
|
+
- **A local judge:** `llm_judge` over Chat Completions, for local models (Ollama, vLLM)
|
|
259
|
+
|
|
260
|
+
## License
|
|
261
|
+
|
|
262
|
+
MIT
|
|
@@ -0,0 +1,43 @@
|
|
|
1
|
+
skillproof/__init__.py,sha256=urbrGjQfeu1ZUZxK0dyFbSxrMkLH2iPHa0--rCc3Zrs,66
|
|
2
|
+
skillproof/__main__.py,sha256=bR8t5-IAeTrQgsQtfAzuhJldwIb50NjndGXut1PY-tU,40
|
|
3
|
+
skillproof/cli.py,sha256=ib_UkGWnifJfmgPb02qOLpzjk6zP95iG9xZdHDSXe0Q,11629
|
|
4
|
+
skillproof/config.py,sha256=Rev-0dMHmrienEBRKIZVzlJwX-XFvxvUn12eTU7nS-Y,7362
|
|
5
|
+
skillproof/engine.py,sha256=g2GLad4sHow_aXDJoWp2d7P5gZmCWuAYyQN7hTi49yc,10407
|
|
6
|
+
skillproof/errors.py,sha256=iX1u8jfRZdjJn_uf-EGlK91MCHKhpeNaW78v0nxFMv0,2334
|
|
7
|
+
skillproof/estimate.py,sha256=kNSsheS9bvvRxUzmiDGTfWeLlW_suEGT6R5LLyE0ExI,3129
|
|
8
|
+
skillproof/results.py,sha256=jWBqDDeUUcqd70PphXpMxFpjV5RMv-fdhqaws2W37eg,2930
|
|
9
|
+
skillproof/sandbox.py,sha256=9i3UAxJDatlZpAbqaLIaFOavtwWp54RPkSvSuSdyklM,2921
|
|
10
|
+
skillproof/scaffold.py,sha256=agvMzI_1H-g3xrm59XQdE8920ABhET49UsO9cURZ4W4,5482
|
|
11
|
+
skillproof/skill.py,sha256=MpsFMYO-ouCcxgKFt8okEYRETxTkXSMSuCmQp-Z6cCI,3453
|
|
12
|
+
skillproof/stats.py,sha256=QNYiB67Ylup0LU7UiX72aWxDmuITsWuKFumIuQVGJzg,8305
|
|
13
|
+
skillproof/assertions/__init__.py,sha256=aHjMYvr4O7CLu4U9jupBDczvISs2ttuM8GH2PVCj2aY,1837
|
|
14
|
+
skillproof/assertions/base.py,sha256=FaRtX8FTrfzZqV3nvIDKt3DMYz-e8oTU8jIsxujLt-M,1113
|
|
15
|
+
skillproof/assertions/builtin.py,sha256=hfopqq6YbH7DLURQnW7mtc3wtlpc1w_gGll2URZuS14,5843
|
|
16
|
+
skillproof/assertions/llm_judge.py,sha256=LydykyQOTgDEpvAygOPXzq4-a_sGsPf026rDjglIOMQ,873
|
|
17
|
+
skillproof/judges/__init__.py,sha256=CQSZF0Digtmcw44KWk6gpdhgi0JdniF7_ihgzgls92w,1486
|
|
18
|
+
skillproof/judges/anthropic_judge.py,sha256=72ykOlj5MI5Hh51BODJ1ztOxKx90PLzCGhYdY48zp5c,2043
|
|
19
|
+
skillproof/judges/base.py,sha256=6m3XX_6QNu5_1PEb9EN43WRopBIv0OcznfhyNep6n8k,1684
|
|
20
|
+
skillproof/judges/mock.py,sha256=HBkeyKQEFlBz0L1WQd1hOMwUwsWsk2rzQzeXn9K1y-g,759
|
|
21
|
+
skillproof/judges/openai_judge.py,sha256=sRdOzLVlNjDw95FEDqopwFyjh1pGVKdT0xvEMMxVSMI,1730
|
|
22
|
+
skillproof/parsers/__init__.py,sha256=YAnj1fqja9ZIYNYyUc48E6L5ZPCGka46SioXPxA5Wsc,286
|
|
23
|
+
skillproof/parsers/claude_code.py,sha256=BsXwr9gKsVrEexa4vJNKwTShIepSr0-8sSD4gEzu9vo,5883
|
|
24
|
+
skillproof/parsers/codex.py,sha256=VlFEfGx0vWjzrCKQLPjdm75To7t-lvXL64ZZOdlneE8,4304
|
|
25
|
+
skillproof/report/__init__.py,sha256=V-cDXFzrvhkOfov-UgWxmsWyj1VdGvubs4mVVE1-bck,1233
|
|
26
|
+
skillproof/report/badge.py,sha256=mZX9RqC2m4oBd2IO_hj0PjrgxOk-O6-4Fi4_zTykp5g,1851
|
|
27
|
+
skillproof/report/format.py,sha256=sydrWrCSA4QmoF0UtXXosvnjPkRc-7vGUjeFFIAnc10,2265
|
|
28
|
+
skillproof/report/html_report.py,sha256=9GOQQmuvDd2rbCAN06AxnZI7mPkyeN37p9Y3Ukm-uZE,12371
|
|
29
|
+
skillproof/report/json_report.py,sha256=PapAHbg82tTwzC_qnK9MlYmNcXwTN3eSMc8z5FwqnzA,220
|
|
30
|
+
skillproof/report/markdown.py,sha256=3kSfbC8dCku6Mc29W2m3enibxjcvnLkL7EMIjzZQ4FA,2628
|
|
31
|
+
skillproof/report/summary.py,sha256=gKSSkwOey5bw-tXEk1qeEfx4qLVoJ8YW5ivdmu3aMP8,7224
|
|
32
|
+
skillproof/report/terminal.py,sha256=qBOGijakacLa3HINTi8RlB-yo4-9h1WX_B5kStfHrQ4,3123
|
|
33
|
+
skillproof/runners/__init__.py,sha256=CRLktwUUIHfawUGq28ieB9atJsMmN80vbCWriB7op5s,1096
|
|
34
|
+
skillproof/runners/base.py,sha256=xYmKbraA1UhS4aNdqWZpXklCvMRCLV72wlSfIL8bp6s,3692
|
|
35
|
+
skillproof/runners/claude_code.py,sha256=xrzYPuqb1vH2rKD4arHiiK9Xn16FXjlp98rZVNNppF4,4902
|
|
36
|
+
skillproof/runners/codex.py,sha256=oboDOp4wGEVX4NrxGbeso_YT1lLP4eQjH34Ak3oGLPM,5249
|
|
37
|
+
skillproof/runners/mock.py,sha256=wvA9yfZ6n0zLaxuNzWmZJolytHeq5_1iKvYH2Wp4vBk,3200
|
|
38
|
+
skillproof/runners/openai_compat.py,sha256=KCyHMLTPvr-AR4sBuUlJO5mM6G77CFwKw-XAOyxO2-k,8835
|
|
39
|
+
skillproof-0.1.0.dist-info/METADATA,sha256=qLVnDXE_X_cyozPT6NOTW1c7G1Cfa52EDzkoZE_-QDY,12273
|
|
40
|
+
skillproof-0.1.0.dist-info/WHEEL,sha256=W3fkpkm7-wf9vBI5Z-7s0eWkeM-spu78I8Neb98DeEg,87
|
|
41
|
+
skillproof-0.1.0.dist-info/entry_points.txt,sha256=L8Zgf1Nj9c5JBBA2bZ0DbG9nN3uOQ4g5nk2vC-6WR2M,51
|
|
42
|
+
skillproof-0.1.0.dist-info/licenses/LICENSE,sha256=XNNcR1T7eyTKdc3Hw6aXDN0isH9Oj2KacYDhHFfXQ44,1067
|
|
43
|
+
skillproof-0.1.0.dist-info/RECORD,,
|
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Akhil Garg
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|