research-diff 0.1.0__py3-none-any.whl
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- research_diff/__init__.py +2 -0
- research_diff/__main__.py +5 -0
- research_diff/agent.py +141 -0
- research_diff/cli.py +153 -0
- research_diff/compare.py +76 -0
- research_diff/config.py +61 -0
- research_diff/diff.py +106 -0
- research_diff/extract.py +327 -0
- research_diff/graph.py +94 -0
- research_diff/mcp_server.py +112 -0
- research_diff/readme.py +38 -0
- research_diff/suggest.py +154 -0
- research_diff/trackers.py +103 -0
- research_diff/watch.py +69 -0
- research_diff-0.1.0.dist-info/METADATA +111 -0
- research_diff-0.1.0.dist-info/RECORD +19 -0
- research_diff-0.1.0.dist-info/WHEEL +4 -0
- research_diff-0.1.0.dist-info/entry_points.txt +3 -0
- research_diff-0.1.0.dist-info/licenses/LICENSE +21 -0
research_diff/suggest.py
ADDED
|
@@ -0,0 +1,154 @@
|
|
|
1
|
+
"""`research-diff suggest`: your LLM proposes markers for notes and paper files that have none, as a patch.
|
|
2
|
+
|
|
3
|
+
It never writes a file. Every proposal is checked before it reaches the patch: the file is one it was shown, the line
|
|
4
|
+
exists, each new line reads as a marker in that file's own form (a Markdown definition or link line, a `% ` LaTeX
|
|
5
|
+
comment, a `# research-diff:` comment), and a new id is not one the research already uses. Apply the patch with
|
|
6
|
+
`git apply`, or edit it first, or drop it.
|
|
7
|
+
|
|
8
|
+
The LLM is the one your Claude Code uses (its settings, or ANTHROPIC_* in the environment), else an OpenAI-compatible
|
|
9
|
+
gateway exported in your shell (SYSTEM_DIFF_LLM_* or LLM_*), as system-diff's summary finds it. Only the files you
|
|
10
|
+
asked about are sent.
|
|
11
|
+
"""
|
|
12
|
+
from __future__ import annotations
|
|
13
|
+
|
|
14
|
+
import difflib
|
|
15
|
+
import json
|
|
16
|
+
import re
|
|
17
|
+
import urllib.request
|
|
18
|
+
from pathlib import Path
|
|
19
|
+
from typing import Any, Callable, Dict, List, Optional
|
|
20
|
+
|
|
21
|
+
from system_diff.extract import glob_rx
|
|
22
|
+
from system_diff.narrate import claude_llm, shell_llm
|
|
23
|
+
from system_diff.sources import git
|
|
24
|
+
|
|
25
|
+
from . import compare
|
|
26
|
+
from .extract import ATTR_RX, COMMENT_RX, _def_rx
|
|
27
|
+
|
|
28
|
+
SYSTEM = (
|
|
29
|
+
"You add research markers to a researcher's own files so a tool can map their research. A marker is an id and a "
|
|
30
|
+
"title: Q (question), H (hypothesis), E (experiment), R (result), C (claim) and a number, e.g. 'H3: Warm-up removes "
|
|
31
|
+
"the gap', followed by lines such as 'answers: Q1', 'tests: H2', 'of: E1', 'supports: H1', 'weakens: C1', 'relies "
|
|
32
|
+
"on: H1, R2', 'status: open', 'metrics: acc=0.91'. In Markdown write them as headings or plain lines; in LaTeX as "
|
|
33
|
+
"comments starting with '% '; in Python as '# research-diff: E2 tests H2'. Only mark what the text already says: "
|
|
34
|
+
"never invent results, numbers or statuses. Reuse existing ids when the text is about them; new ids must not be in "
|
|
35
|
+
"the list of existing ids. Answer with JSON only: {\"markers\": [{\"file\": path, \"after_line\": n, \"lines\": "
|
|
36
|
+
"[...]}]}, where after_line is the line number the new lines go after (0 for the top)."
|
|
37
|
+
)
|
|
38
|
+
|
|
39
|
+
|
|
40
|
+
def _ask(s: Dict[str, Any], user: str, timeout: int = 120) -> str:
|
|
41
|
+
if s.get("kind") == "openai":
|
|
42
|
+
url, body = s["base_url"] + "/chat/completions", {"model": s["model"], "max_tokens": 4000,
|
|
43
|
+
"messages": [{"role": "system", "content": SYSTEM},
|
|
44
|
+
{"role": "user", "content": user}]}
|
|
45
|
+
headers = {"content-type": "application/json", "authorization": "Bearer " + s["token"]}
|
|
46
|
+
else:
|
|
47
|
+
url, body = s["base_url"] + "/v1/messages", {"model": s["model"], "max_tokens": 4000, "system": SYSTEM,
|
|
48
|
+
"messages": [{"role": "user", "content": user}]}
|
|
49
|
+
headers = {"content-type": "application/json", "anthropic-version": "2023-06-01",
|
|
50
|
+
"authorization": "Bearer " + s["token"], "x-api-key": s["token"]}
|
|
51
|
+
req = urllib.request.Request(url, data=json.dumps(body).encode(), method="POST", headers=headers)
|
|
52
|
+
with urllib.request.urlopen(req, timeout=timeout) as r:
|
|
53
|
+
data = json.loads(r.read())
|
|
54
|
+
if s.get("kind") == "openai":
|
|
55
|
+
return ((data.get("choices") or [{}])[0].get("message") or {}).get("content") or ""
|
|
56
|
+
return "".join(b.get("text", "") for b in data.get("content", []) if b.get("type") == "text")
|
|
57
|
+
|
|
58
|
+
|
|
59
|
+
def default_llm(root: Path) -> Optional[Callable[[str], str]]:
|
|
60
|
+
s = claude_llm(root) or shell_llm()
|
|
61
|
+
return (lambda user: _ask(s, user)) if s else None
|
|
62
|
+
|
|
63
|
+
|
|
64
|
+
def _valid(line: str, path: str, def_rx: re.Pattern) -> bool:
|
|
65
|
+
if path.endswith(".tex"):
|
|
66
|
+
body = line[1:].strip() if line.startswith("%") else None
|
|
67
|
+
return bool(body) and bool(def_rx.match(body) or ATTR_RX.match(body))
|
|
68
|
+
if path.endswith((".py", ".ipynb", ".yaml", ".yml", ".toml")):
|
|
69
|
+
return bool(COMMENT_RX.search(line))
|
|
70
|
+
return bool(def_rx.match(line) or ATTR_RX.match(line) or not line.strip())
|
|
71
|
+
|
|
72
|
+
|
|
73
|
+
def suggest(root: Path, files: List[str], ask: Callable[[str], str], config_path: Optional[str] = None) -> Dict[str, Any]:
|
|
74
|
+
"""{patch, accepted, refused}: the proposals that passed the checks as one unified diff, and why others did not."""
|
|
75
|
+
bp, cfg, _ = compare.read(root, ".", config_path)
|
|
76
|
+
def_rx = _def_rx(cfg["kinds"])
|
|
77
|
+
texts = {f: (root / f).read_text(encoding="utf-8") for f in files if (root / f).is_file()}
|
|
78
|
+
shown = "\n\n".join(f"=== {f}\n" + "\n".join(f"{i:4} {ln}" for i, ln in enumerate(t.splitlines(), 1))
|
|
79
|
+
for f, t in texts.items())
|
|
80
|
+
user = (f"Existing ids: {', '.join(bp['nodes']) or 'none'}\n\nAdd markers to these files (line numbers on the "
|
|
81
|
+
f"left are not part of the files):\n\n{shown[:60000]}")
|
|
82
|
+
raw = ask(user)
|
|
83
|
+
m = re.search(r"\{.*\}", raw, re.S)
|
|
84
|
+
try:
|
|
85
|
+
proposals = json.loads(m.group(0)).get("markers", []) if m else []
|
|
86
|
+
except ValueError:
|
|
87
|
+
proposals = []
|
|
88
|
+
used = set(bp["nodes"])
|
|
89
|
+
inserts: Dict[str, List[tuple]] = {}
|
|
90
|
+
accepted, refused = [], []
|
|
91
|
+
for p in proposals:
|
|
92
|
+
f, at, lines = p.get("file"), p.get("after_line"), [str(x) for x in p.get("lines") or []]
|
|
93
|
+
if f not in texts:
|
|
94
|
+
refused.append(f"{f}: not one of the files it was shown")
|
|
95
|
+
continue
|
|
96
|
+
n = len(texts[f].splitlines())
|
|
97
|
+
if not isinstance(at, int) or not 0 <= at <= n:
|
|
98
|
+
refused.append(f"{f}: line {at} does not exist")
|
|
99
|
+
continue
|
|
100
|
+
bad = [ln for ln in lines if not _valid(ln, f, def_rx)]
|
|
101
|
+
if bad or not lines:
|
|
102
|
+
refused.append(f"{f}:{at}: not a marker: {bad[0] if bad else '(nothing)'}")
|
|
103
|
+
continue
|
|
104
|
+
new_ids = [d.group(1) for ln in lines if (d := def_rx.match(ln.lstrip('% ')))]
|
|
105
|
+
clash = [i for i in new_ids if i in used]
|
|
106
|
+
if clash:
|
|
107
|
+
refused.append(f"{f}:{at}: {clash[0]} is already used")
|
|
108
|
+
continue
|
|
109
|
+
used |= set(new_ids)
|
|
110
|
+
inserts.setdefault(f, []).append((at, lines))
|
|
111
|
+
accepted.append(f"{f}:{at}: " + "; ".join(lines)[:120])
|
|
112
|
+
patch = []
|
|
113
|
+
for f, items in sorted(inserts.items()):
|
|
114
|
+
old = texts[f].splitlines(keepends=True)
|
|
115
|
+
new = list(old)
|
|
116
|
+
for at, lines in sorted(items, key=lambda x: -x[0]): # from the bottom, so line numbers hold
|
|
117
|
+
new[at:at] = [ln + "\n" for ln in lines] + (["\n"] if f.endswith(".md") else [])
|
|
118
|
+
patch += difflib.unified_diff(old, new, f"a/{f}", f"b/{f}")
|
|
119
|
+
return {"patch": "".join(patch), "accepted": accepted, "refused": refused}
|
|
120
|
+
|
|
121
|
+
|
|
122
|
+
def untagged(root: Path, config_path: Optional[str] = None) -> List[str]:
|
|
123
|
+
"""Notes and paper files with no marker yet."""
|
|
124
|
+
bp, cfg, _ = compare.read(root, ".", config_path)
|
|
125
|
+
tagged = {f for n in bp["nodes"].values() for f in n["files"]}
|
|
126
|
+
tracked = git("ls-files", cwd=root).splitlines()
|
|
127
|
+
globs = [glob_rx(g) for g in cfg["notes"] + cfg["paper"]]
|
|
128
|
+
skip = [glob_rx(g) for g in cfg.get("ignore", [])]
|
|
129
|
+
return [f for f in tracked if any(r.match(f) for r in globs) and not any(r.match(f) for r in skip) and f not in tagged]
|
|
130
|
+
|
|
131
|
+
|
|
132
|
+
def run(root: Path, files: List[str], out: str = "", config_path: Optional[str] = None,
|
|
133
|
+
ask: Optional[Callable[[str], str]] = None) -> int:
|
|
134
|
+
files = files or untagged(root, config_path)
|
|
135
|
+
if not files:
|
|
136
|
+
print("every notes and paper file already has markers; name files to read them anyway")
|
|
137
|
+
return 0
|
|
138
|
+
ask = ask or default_llm(root)
|
|
139
|
+
if ask is None:
|
|
140
|
+
print("no LLM to ask: research-diff uses your Claude Code's settings or ANTHROPIC_*, else SYSTEM_DIFF_LLM_*")
|
|
141
|
+
return 1
|
|
142
|
+
got = suggest(root, files, ask, config_path)
|
|
143
|
+
for line in got["refused"]:
|
|
144
|
+
print(f"refused {line}")
|
|
145
|
+
if not got["patch"]:
|
|
146
|
+
print("no marker to suggest")
|
|
147
|
+
return 0
|
|
148
|
+
path = Path(out) if out else Path(git("rev-parse", "--absolute-git-dir", cwd=root).strip()) / "research-diff" / "suggest.patch"
|
|
149
|
+
path.parent.mkdir(parents=True, exist_ok=True)
|
|
150
|
+
path.write_text(got["patch"], encoding="utf-8", newline="\n")
|
|
151
|
+
for line in got["accepted"]:
|
|
152
|
+
print(f"proposed {line}")
|
|
153
|
+
print(f"\nnothing was changed: read {path}, then `git apply {path}` to take it")
|
|
154
|
+
return 0
|
|
@@ -0,0 +1,103 @@
|
|
|
1
|
+
"""Runs from experiment trackers, as results: MLflow's local file store (`mlruns/`) and W&B's local run folders
|
|
2
|
+
(`wandb/`), read with the standard library. A run belongs to an experiment when it is tagged with its id:
|
|
3
|
+
`research-diff.experiment` (or `research_id`) as an MLflow tag or param, or `research_id` in the W&B config.
|
|
4
|
+
|
|
5
|
+
Tracker folders are usually git-ignored, so a checkpoint could not see them. `sync` writes their runs into
|
|
6
|
+
`research/runs.json`, which is tracked: the runs are then on the map, in git, and in the next diff.
|
|
7
|
+
"""
|
|
8
|
+
from __future__ import annotations
|
|
9
|
+
|
|
10
|
+
import json
|
|
11
|
+
import re
|
|
12
|
+
from pathlib import Path
|
|
13
|
+
from typing import Any, Dict, List
|
|
14
|
+
|
|
15
|
+
RUNS = "research/runs.json"
|
|
16
|
+
TAGS = ("research-diff.experiment", "research_id", "research-diff")
|
|
17
|
+
|
|
18
|
+
|
|
19
|
+
def _last_metric(path: Path) -> float:
|
|
20
|
+
"""MLflow keeps one line per step, `timestamp value step`; the last one is the run's value."""
|
|
21
|
+
lines = [ln.split() for ln in path.read_text(encoding="utf-8").splitlines() if ln.strip()]
|
|
22
|
+
return float(lines[-1][1])
|
|
23
|
+
|
|
24
|
+
|
|
25
|
+
def read_mlflow(store: Path) -> List[Dict[str, Any]]:
|
|
26
|
+
out = []
|
|
27
|
+
for meta in sorted(store.glob("*/*/meta.yaml")):
|
|
28
|
+
run = meta.parent
|
|
29
|
+
exp = ""
|
|
30
|
+
for kind in ("tags", "params"):
|
|
31
|
+
for t in TAGS:
|
|
32
|
+
p = run / kind / t
|
|
33
|
+
if p.is_file():
|
|
34
|
+
exp = exp or p.read_text(encoding="utf-8").strip()
|
|
35
|
+
if not exp:
|
|
36
|
+
continue
|
|
37
|
+
metrics = {}
|
|
38
|
+
for m in sorted((run / "metrics").glob("**/*")) if (run / "metrics").is_dir() else []:
|
|
39
|
+
if m.is_file():
|
|
40
|
+
try:
|
|
41
|
+
metrics[m.relative_to(run / "metrics").as_posix()] = _last_metric(m)
|
|
42
|
+
except (ValueError, IndexError):
|
|
43
|
+
continue
|
|
44
|
+
name_file = run / "tags" / "mlflow.runName"
|
|
45
|
+
out.append({"experiment": exp, "source": "mlflow", "run": run.name,
|
|
46
|
+
"name": name_file.read_text(encoding="utf-8").strip() if name_file.is_file() else run.name[:8],
|
|
47
|
+
"metrics": metrics})
|
|
48
|
+
return out
|
|
49
|
+
|
|
50
|
+
|
|
51
|
+
def _wandb_config_value(text: str, key: str) -> str:
|
|
52
|
+
"""W&B's config.yaml keeps each key as `key:\\n desc: …\\n value: X`."""
|
|
53
|
+
m = re.search(rf"^{re.escape(key)}:\s*\n(?:\s+.*\n)*?\s+value:\s*(.+)$", text, re.M)
|
|
54
|
+
return m.group(1).strip().strip("'\"") if m else ""
|
|
55
|
+
|
|
56
|
+
|
|
57
|
+
def read_wandb(folder: Path) -> List[Dict[str, Any]]:
|
|
58
|
+
out = []
|
|
59
|
+
for run in sorted(p for p in folder.glob("*run-*") if p.is_dir()):
|
|
60
|
+
files = run / "files"
|
|
61
|
+
cfg = (files / "config.yaml").read_text(encoding="utf-8") if (files / "config.yaml").is_file() else ""
|
|
62
|
+
exp = next((v for k in TAGS if (v := _wandb_config_value(cfg, k))), "")
|
|
63
|
+
summary = files / "wandb-summary.json"
|
|
64
|
+
if not exp or not summary.is_file():
|
|
65
|
+
continue
|
|
66
|
+
try:
|
|
67
|
+
data = json.loads(summary.read_text(encoding="utf-8"))
|
|
68
|
+
except ValueError:
|
|
69
|
+
continue
|
|
70
|
+
metrics = {k: float(v) for k, v in data.items() if isinstance(v, (int, float)) and not isinstance(v, bool)
|
|
71
|
+
and not k.startswith("_")}
|
|
72
|
+
out.append({"experiment": exp, "source": "wandb", "run": run.name.rsplit("-", 1)[-1], "name": run.name,
|
|
73
|
+
"metrics": metrics})
|
|
74
|
+
return out
|
|
75
|
+
|
|
76
|
+
|
|
77
|
+
def sync(root: Path, mlflow: str = "mlruns", wandb: str = "wandb") -> Dict[str, Any]:
|
|
78
|
+
"""Write the trackers' tagged runs to research/runs.json. Returns {runs, written}; nothing is written when no
|
|
79
|
+
tracker folder exists, and the file only changes when a run does."""
|
|
80
|
+
runs: List[Dict[str, Any]] = []
|
|
81
|
+
if (root / mlflow).is_dir():
|
|
82
|
+
runs += read_mlflow(root / mlflow)
|
|
83
|
+
if (root / wandb).is_dir():
|
|
84
|
+
runs += read_wandb(root / wandb)
|
|
85
|
+
if not runs and not (root / RUNS).is_file():
|
|
86
|
+
return {"runs": 0, "written": False}
|
|
87
|
+
runs.sort(key=lambda r: (r["experiment"], r["source"], r["run"]))
|
|
88
|
+
text = json.dumps({"runs": runs}, indent=1, sort_keys=True) + "\n"
|
|
89
|
+
path = root / RUNS
|
|
90
|
+
if path.is_file() and path.read_text(encoding="utf-8") == text:
|
|
91
|
+
return {"runs": len(runs), "written": False}
|
|
92
|
+
path.parent.mkdir(parents=True, exist_ok=True)
|
|
93
|
+
with open(path, "w", encoding="utf-8", newline="\n") as f:
|
|
94
|
+
f.write(text)
|
|
95
|
+
return {"runs": len(runs), "written": True}
|
|
96
|
+
|
|
97
|
+
|
|
98
|
+
def run_nodes(text: str) -> List[Dict[str, Any]]:
|
|
99
|
+
"""The runs of a runs.json, for extract."""
|
|
100
|
+
try:
|
|
101
|
+
return list(json.loads(text).get("runs") or [])
|
|
102
|
+
except (ValueError, AttributeError):
|
|
103
|
+
return []
|
research_diff/watch.py
ADDED
|
@@ -0,0 +1,69 @@
|
|
|
1
|
+
"""`research-diff watch`: a live page of what changed in the research since the checkpoint, with Mark as seen.
|
|
2
|
+
system-diff's watcher, pointed at the research map: the same page, the same token, one look at a time."""
|
|
3
|
+
from __future__ import annotations
|
|
4
|
+
|
|
5
|
+
import subprocess
|
|
6
|
+
import threading
|
|
7
|
+
import time
|
|
8
|
+
from http.server import ThreadingHTTPServer
|
|
9
|
+
from pathlib import Path
|
|
10
|
+
from typing import Optional
|
|
11
|
+
|
|
12
|
+
from system_diff import watch as base
|
|
13
|
+
from system_diff.compare import worktree_tree
|
|
14
|
+
|
|
15
|
+
from . import compare, graph
|
|
16
|
+
|
|
17
|
+
|
|
18
|
+
class Watcher(base.Watcher):
|
|
19
|
+
def key(self) -> tuple:
|
|
20
|
+
compare.sync_trackers(self.root, self.config_path) # a new tracker run changes research/runs.json
|
|
21
|
+
return worktree_tree(self.root), compare._rev(self.root, compare.CHECKPOINT_REF)
|
|
22
|
+
|
|
23
|
+
def refresh(self) -> None:
|
|
24
|
+
try:
|
|
25
|
+
c = compare.compare(self.root, self.base, ".", self.config_path)
|
|
26
|
+
new = {"headline": c.diff["headline"], "plan": c.diff["plan"],
|
|
27
|
+
"svg": graph.diff_svg(c.diff, c.before, c.after, c.cfg) or "",
|
|
28
|
+
"changes": len(c.diff["changes"]), "base": c.base, "error": ""}
|
|
29
|
+
except (OSError, subprocess.CalledProcessError, ValueError, KeyError) as exc:
|
|
30
|
+
new = {"error": f"{type(exc).__name__}: {exc}"}
|
|
31
|
+
with self.lock:
|
|
32
|
+
self.state.update(new, version=self.state["version"] + 1, at=time.strftime("%H:%M:%S"))
|
|
33
|
+
|
|
34
|
+
def mark_seen(self) -> None:
|
|
35
|
+
with self.busy:
|
|
36
|
+
compare.checkpoint(self.root)
|
|
37
|
+
self.tick(force=True)
|
|
38
|
+
|
|
39
|
+
|
|
40
|
+
PAGE = base.PAGE.replace("<title>System diff</title>", "<title>Research diff</title>").replace(
|
|
41
|
+
"<h1>System diff</h1>", "<h1>Research diff</h1>")
|
|
42
|
+
|
|
43
|
+
|
|
44
|
+
def serve(root: Path, base_point: str = "checkpoint", port: int = 8766, config_path: Optional[str] = None,
|
|
45
|
+
interval: float = 2.0, ready=None) -> None:
|
|
46
|
+
w = Watcher(root, base_point, config_path, interval)
|
|
47
|
+
handler = base.handler(w)
|
|
48
|
+
handler.do_GET_base = handler.do_GET
|
|
49
|
+
|
|
50
|
+
def do_GET(self):
|
|
51
|
+
if self.path in ("/", "/index.html"):
|
|
52
|
+
return self._send(200, PAGE.replace("__TOKEN__", w.token).encode(), "text/html; charset=utf-8")
|
|
53
|
+
return self.do_GET_base()
|
|
54
|
+
|
|
55
|
+
handler.do_GET = do_GET
|
|
56
|
+
server = ThreadingHTTPServer(("127.0.0.1", port), handler)
|
|
57
|
+
threading.Thread(target=w.loop, daemon=True).start()
|
|
58
|
+
url = f"http://127.0.0.1:{server.server_address[1]}/"
|
|
59
|
+
if ready:
|
|
60
|
+
ready(url, server, w)
|
|
61
|
+
else:
|
|
62
|
+
print(f"research-diff watch: {url} (Ctrl-C to stop)", flush=True)
|
|
63
|
+
try:
|
|
64
|
+
server.serve_forever()
|
|
65
|
+
except KeyboardInterrupt:
|
|
66
|
+
pass
|
|
67
|
+
finally:
|
|
68
|
+
w.stop.set()
|
|
69
|
+
server.server_close()
|
|
@@ -0,0 +1,111 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: research-diff
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Maps your research from its notes, experiment configs, results and paper (questions, hypotheses, experiments, results, claims) and shows what each iteration changed. Built for exploring ideas with AI coding agents.
|
|
5
|
+
Project-URL: Homepage, https://github.com/simplifiedmachine/research-diff
|
|
6
|
+
Project-URL: Documentation, https://github.com/simplifiedmachine/research-diff/wiki
|
|
7
|
+
Author: simplifiedmachine
|
|
8
|
+
License-Expression: MIT
|
|
9
|
+
License-File: LICENSE
|
|
10
|
+
Keywords: ai-agents,claude-code,experiment-tracking,hypotheses,mcp,reproducibility,research
|
|
11
|
+
Classifier: Development Status :: 3 - Alpha
|
|
12
|
+
Classifier: Intended Audience :: Science/Research
|
|
13
|
+
Classifier: Programming Language :: Python :: 3 :: Only
|
|
14
|
+
Classifier: Topic :: Scientific/Engineering
|
|
15
|
+
Requires-Python: >=3.11
|
|
16
|
+
Requires-Dist: system-diff==0.1.0
|
|
17
|
+
Provides-Extra: dev
|
|
18
|
+
Requires-Dist: mcp>=1.10; extra == 'dev'
|
|
19
|
+
Requires-Dist: pytest>=8; extra == 'dev'
|
|
20
|
+
Provides-Extra: mcp
|
|
21
|
+
Requires-Dist: mcp>=1.10; extra == 'mcp'
|
|
22
|
+
Description-Content-Type: text/markdown
|
|
23
|
+
|
|
24
|
+
# research-diff
|
|
25
|
+
|
|
26
|
+
Maps your research from its notes, experiment configs, results and paper (questions, hypotheses, experiments,
|
|
27
|
+
results, claims) and shows what each iteration changed. Built for exploring ideas with AI coding agents.
|
|
28
|
+
|
|
29
|
+
<!-- research-map:begin -->
|
|
30
|
+
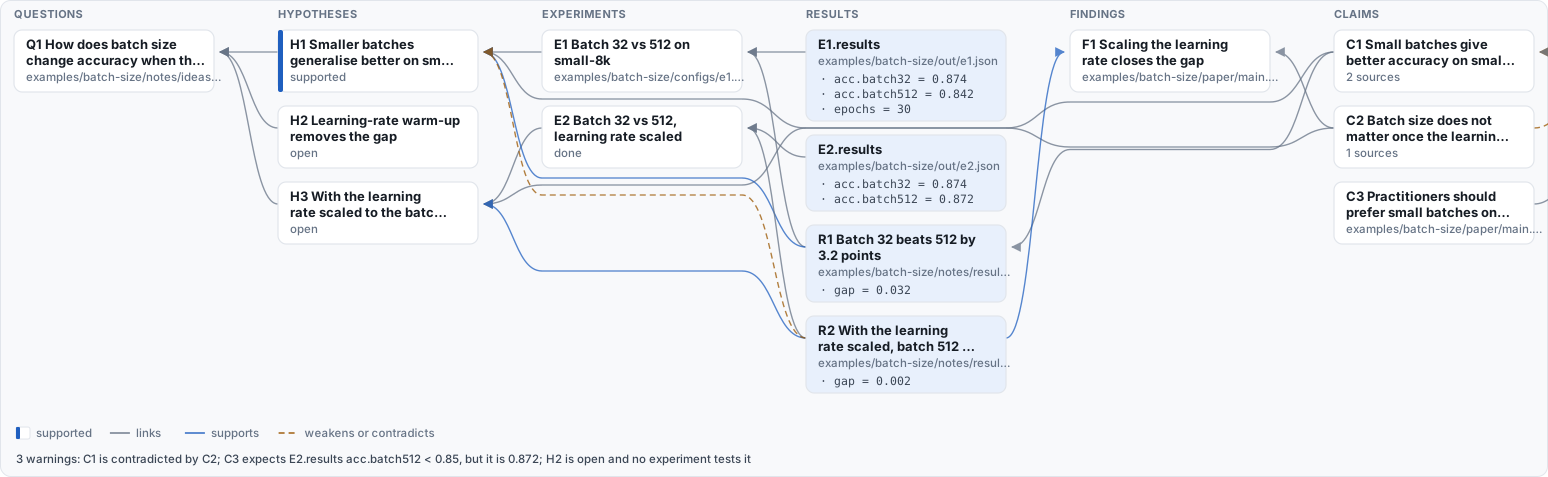
|
|
31
|
+
|
|
32
|
+
<details><summary>1 open warning</summary>
|
|
33
|
+
|
|
34
|
+
- H2 is open and no experiment tests it
|
|
35
|
+
|
|
36
|
+
</details>
|
|
37
|
+
<!-- research-map:end -->
|
|
38
|
+
|
|
39
|
+
The map above is this repository's own example (`examples/batch-size`), regenerated from its files on every change.
|
|
40
|
+
|
|
41
|
+
## What it reads
|
|
42
|
+
|
|
43
|
+
Markers in your own files, in one grammar: an id (`Q` question, `H` hypothesis, `E` experiment, `R` result,
|
|
44
|
+
`C` claim, and a number) and a title, then links and a status on the lines after it.
|
|
45
|
+
|
|
46
|
+
```markdown
|
|
47
|
+
## H2: Learning-rate warm-up removes the gap <- notes (Markdown): a heading or a list item
|
|
48
|
+
answers: Q1
|
|
49
|
+
status: open <- open | supported | refuted | anything you like
|
|
50
|
+
```
|
|
51
|
+
|
|
52
|
+
| Where | How |
|
|
53
|
+
|---|---|
|
|
54
|
+
| Notes (`.md`) | definitions as above; `tests:`, `of:`, `supports:`, `weakens:`, `relies on:`, `metrics: acc=0.91` |
|
|
55
|
+
| Experiment configs (YAML, JSON, TOML) | a `research:` block: `id`, `title`, `tests`, `status`, and `results: out/e1.json`, whose numbers become the result `E1.results` |
|
|
56
|
+
| Scripts and notebooks | a comment: `# research-diff: E2 tests H2` |
|
|
57
|
+
| The paper (LaTeX) | a comment: `% C1: Small batches win` and `% relies on: H1, R1`; the paragraph's `\cite{…}` become its sources; `% expects: E1.results acc.batch32 > 0.85` warns when a result stops meeting it |
|
|
58
|
+
|
|
59
|
+
The map is built from markers only, so the same files always give the same map. It warns when a claim relies on
|
|
60
|
+
nothing or on a refuted hypothesis, when a number no longer meets what a claim `expects:`, when an open hypothesis has no experiment, and when a link points at nothing.
|
|
61
|
+
|
|
62
|
+
## Use
|
|
63
|
+
|
|
64
|
+
```sh
|
|
65
|
+
pipx install research-diff
|
|
66
|
+
research-diff map --out docs # research.svg and research.json
|
|
67
|
+
research-diff diff --base HEAD # what your uncommitted iteration did
|
|
68
|
+
research-diff sync # MLflow / W&B runs into research/runs.json
|
|
69
|
+
research-diff checkpoint # mark what you have understood
|
|
70
|
+
research-diff diff # only what came after that
|
|
71
|
+
```
|
|
72
|
+
|
|
73
|
+
A diff reads like: *Adds 1 hypothesis (H3); H1: open → refuted; E1.results acc.b32: 0.874 → 0.881 (+0.8%); 1 new
|
|
74
|
+
link; 2 new warnings (C1 relies on H1, which is refuted…).* It comes with the exact list (`plan.txt`) and a picture of
|
|
75
|
+
only what changed (`diff.svg`).
|
|
76
|
+
|
|
77
|
+
## With AI coding agents
|
|
78
|
+
|
|
79
|
+
```sh
|
|
80
|
+
pipx inject research-diff mcp
|
|
81
|
+
research-diff setup claude # a Stop hook, a skill and the MCP server (--scope project, --undo)
|
|
82
|
+
research-diff watch # http://127.0.0.1:8766/ : the research diff since your checkpoint, live
|
|
83
|
+
```
|
|
84
|
+
|
|
85
|
+
After every Claude Code turn one line says what changed in the research. The agent's tools: `research_diff`,
|
|
86
|
+
`research_map`, `log_result` (records a run's metrics and what it supports or weakens in `research/log.md`, so it is
|
|
87
|
+
on the map and in git) and `checkpoint`. The pictures, snapshots and live page are
|
|
88
|
+
[system-diff](https://github.com/simplifiedmachine/system-diff)'s.
|
|
89
|
+
|
|
90
|
+
## Experiment trackers
|
|
91
|
+
|
|
92
|
+
Runs logged to MLflow (its local `mlruns/` store) or W&B (its local `wandb/` folders) become results of the experiment
|
|
93
|
+
they are tagged with: `research-diff.experiment` (or `research_id`) as an MLflow tag or param, `research_id` in the W&B
|
|
94
|
+
config. Tracker folders are usually git-ignored, so `research-diff sync` copies their runs into `research/runs.json`,
|
|
95
|
+
which is tracked: the runs are then on the map, in git and in the next diff. The hook, the live page and the MCP tools
|
|
96
|
+
sync on their own.
|
|
97
|
+
|
|
98
|
+
## Markers suggested by your LLM
|
|
99
|
+
|
|
100
|
+
```sh
|
|
101
|
+
research-diff suggest # notes and paper files with no marker yet, or name the files
|
|
102
|
+
git apply .git/research-diff/suggest.patch
|
|
103
|
+
```
|
|
104
|
+
|
|
105
|
+
Your LLM (the one your Claude Code uses) proposes markers for what the text already says. Each proposal is checked
|
|
106
|
+
before it reaches the patch: a real line of a file it was shown, a marker in that file's own form, and no id that is
|
|
107
|
+
already used. Nothing is written until you apply the patch.
|
|
108
|
+
|
|
109
|
+
## License
|
|
110
|
+
|
|
111
|
+
MIT
|
|
@@ -0,0 +1,19 @@
|
|
|
1
|
+
research_diff/__init__.py,sha256=_WBjt6U1_3Zm173407KJ4bNfIcbGsWgvEyi-jUMyN4g,106
|
|
2
|
+
research_diff/__main__.py,sha256=E6Gls0DNz8GQK2K-kOUIx8cYhgANW_CH54VKrfCfs14,52
|
|
3
|
+
research_diff/agent.py,sha256=KdBlJX20FC0d610nbunhgVRxikt2MXNL4oXbPFa6nTw,6700
|
|
4
|
+
research_diff/cli.py,sha256=_XXu8rf2XxOxJpzXno_95Hyk6J3xLwiAWoJ3DORA3Mc,7756
|
|
5
|
+
research_diff/compare.py,sha256=8zJfCp0eJk8d8nn4KM9M7COjxWuWQm2rqsRgif0qrJY,2869
|
|
6
|
+
research_diff/config.py,sha256=67EuoY3yrjaN2iTV5ot2p2WHo-N-3meUhLGaeVrt_xo,2862
|
|
7
|
+
research_diff/diff.py,sha256=ivbNvevLxGhtEzAhDdwhm4_bpbTBgxC9V0Y4qxnpaac,5795
|
|
8
|
+
research_diff/extract.py,sha256=997MlMEEu6MmvKv1-7pE_nZ4Wb33ThDGIxbafS9qo6I,14885
|
|
9
|
+
research_diff/graph.py,sha256=nJa72RrlNByjxFUL6Ni8Rqb7CD5VwnV7SsDAPcB-LpU,4935
|
|
10
|
+
research_diff/mcp_server.py,sha256=STdfXoHCPA8aA_aRgnuzzkwNq8xJTz5Rv_YJGW4SJH4,5344
|
|
11
|
+
research_diff/readme.py,sha256=Q_fsfMRkJuMfYId_bxb7HdHW2d8efBa7eOoAnK5DucA,1785
|
|
12
|
+
research_diff/suggest.py,sha256=lj6upLfo2D-LcOO4b_iuDUJiP1sPbgGds1voORoEUj4,8225
|
|
13
|
+
research_diff/trackers.py,sha256=abm_AegEFuXD4F2dstVjaJ9UxEIPj4qQgzdXM4xdpsg,4522
|
|
14
|
+
research_diff/watch.py,sha256=htjCGKM3BLb01E1TIGxDjNRPi5z-5eHe7q4SKzEhe64,2666
|
|
15
|
+
research_diff-0.1.0.dist-info/METADATA,sha256=DQaQr070mt72PAZYZa6zlpgf0gCKVUduv2Ws5yUizDQ,5400
|
|
16
|
+
research_diff-0.1.0.dist-info/WHEEL,sha256=2iZrJkDIkeDh0k9SikKMqFuRP-ua6mb4Ir1AsER4BEw,87
|
|
17
|
+
research_diff-0.1.0.dist-info/entry_points.txt,sha256=s9GaJAzGrKJPFfyAHtofKzp5cdasuDsquV6v1FXmI0w,90
|
|
18
|
+
research_diff-0.1.0.dist-info/licenses/LICENSE,sha256=QHQ-0t-7_4_K7j92CTlQScHiJiDZ91DcpV6WIOIFYQE,1074
|
|
19
|
+
research_diff-0.1.0.dist-info/RECORD,,
|
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 simplifiedmachine
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|