recursive-llm 0.5.0__py3-none-any.whl
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- recursive_llm-0.5.0.dist-info/METADATA +733 -0
- recursive_llm-0.5.0.dist-info/RECORD +17 -0
- recursive_llm-0.5.0.dist-info/WHEEL +5 -0
- recursive_llm-0.5.0.dist-info/licenses/LICENSE +21 -0
- recursive_llm-0.5.0.dist-info/top_level.txt +1 -0
- rlm/__init__.py +51 -0
- rlm/budget.py +115 -0
- rlm/codex.py +312 -0
- rlm/core.py +1149 -0
- rlm/errors.py +36 -0
- rlm/parser.py +102 -0
- rlm/prompts.py +54 -0
- rlm/repl.py +684 -0
- rlm/results.py +126 -0
- rlm/run_state.py +192 -0
- rlm/stats.py +162 -0
- rlm/types.py +53 -0
|
@@ -0,0 +1,733 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: recursive-llm
|
|
3
|
+
Version: 0.5.0
|
|
4
|
+
Summary: Recursive Language Models for efficient long-context processing
|
|
5
|
+
Author: Grigori Gvadzabia
|
|
6
|
+
License-Expression: MIT
|
|
7
|
+
Project-URL: Homepage, https://github.com/grishahq/recursive-llm
|
|
8
|
+
Project-URL: Documentation, https://github.com/grishahq/recursive-llm
|
|
9
|
+
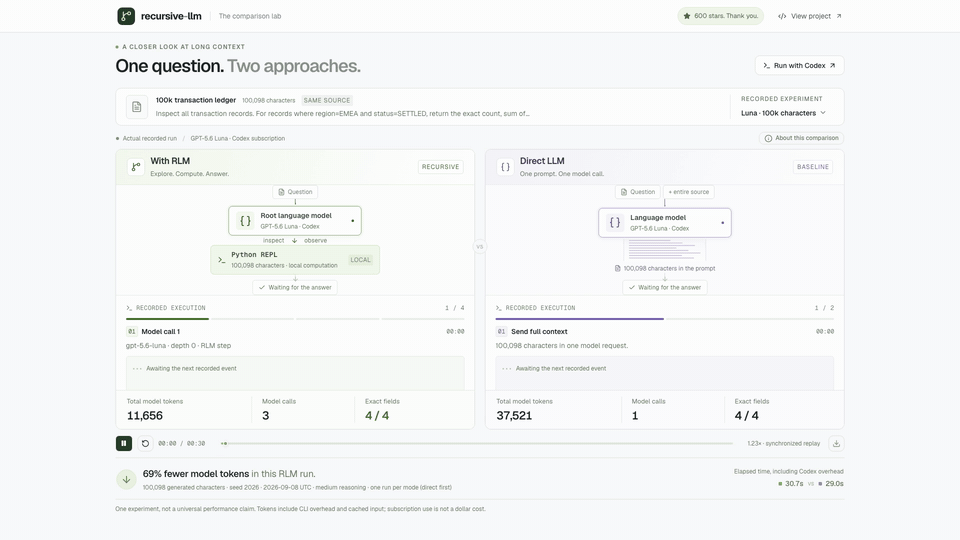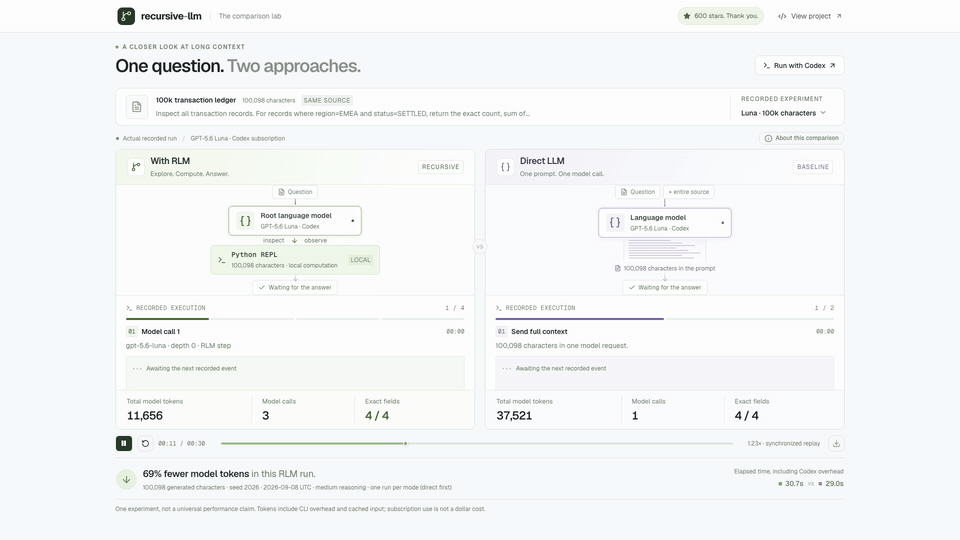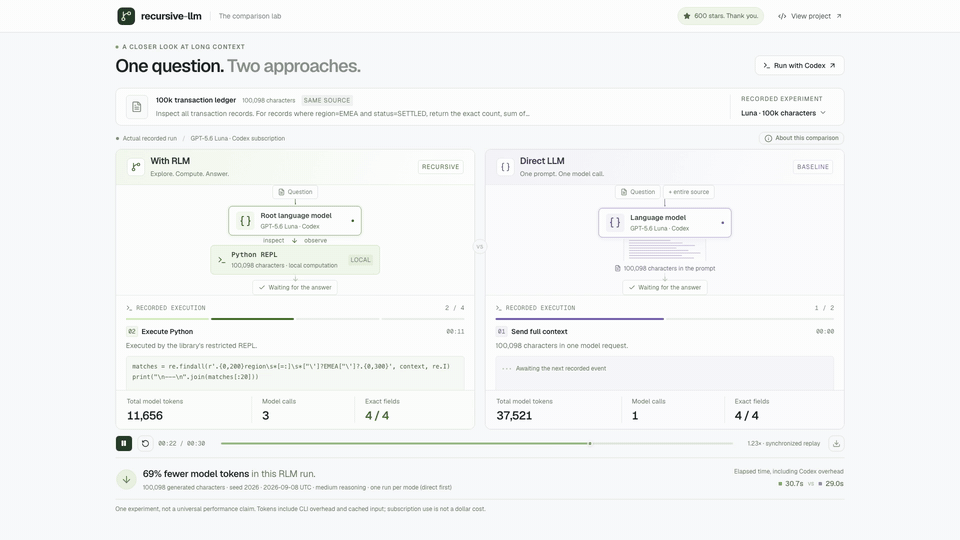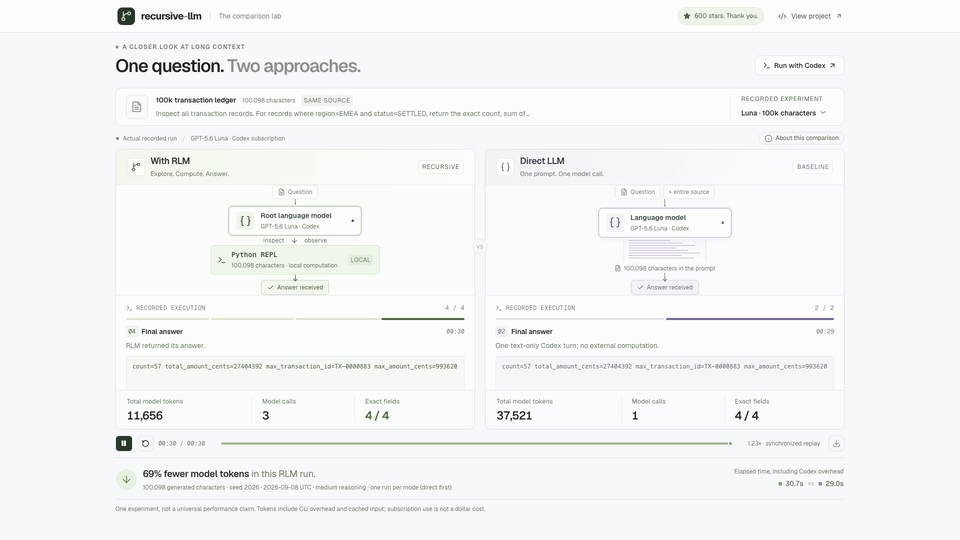
Project-URL: Repository, https://github.com/grishahq/recursive-llm
|
|
10
|
+
Project-URL: Issues, https://github.com/grishahq/recursive-llm/issues
|
|
11
|
+
Project-URL: Changelog, https://github.com/grishahq/recursive-llm/blob/main/CHANGELOG.md
|
|
12
|
+
Keywords: llm,ai,nlp,recursive,language-models
|
|
13
|
+
Classifier: Development Status :: 3 - Alpha
|
|
14
|
+
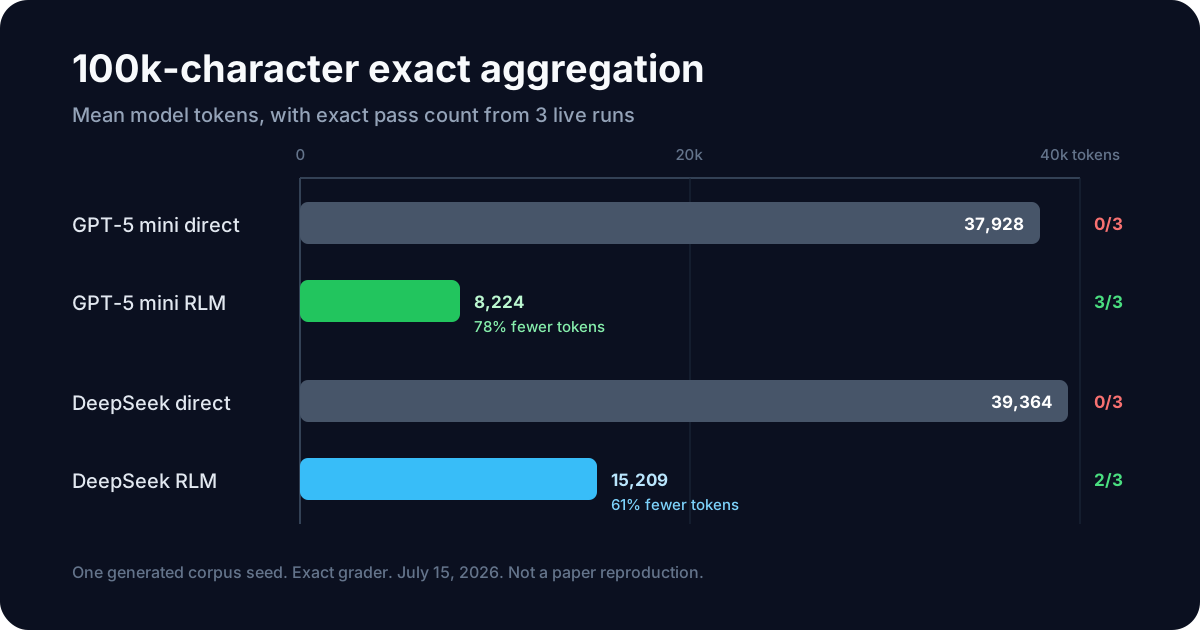
Classifier: Intended Audience :: Developers
|
|
15
|
+
Classifier: Programming Language :: Python :: 3
|
|
16
|
+
Classifier: Programming Language :: Python :: 3.9
|
|
17
|
+
Classifier: Programming Language :: Python :: 3.10
|
|
18
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
19
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
20
|
+
Requires-Python: >=3.9
|
|
21
|
+
Description-Content-Type: text/markdown
|
|
22
|
+
License-File: LICENSE
|
|
23
|
+
Requires-Dist: litellm<1.98.0,>=1.0.0
|
|
24
|
+
Requires-Dist: RestrictedPython>=6.0
|
|
25
|
+
Requires-Dist: python-dotenv>=1.0.0
|
|
26
|
+
Provides-Extra: visualizer
|
|
27
|
+
Requires-Dist: pypdf<7,>=6.18.0; extra == "visualizer"
|
|
28
|
+
Provides-Extra: dev
|
|
29
|
+
Requires-Dist: build>=1.2.0; extra == "dev"
|
|
30
|
+
Requires-Dist: pytest>=7.0.0; extra == "dev"
|
|
31
|
+
Requires-Dist: pytest-asyncio>=0.24.0; extra == "dev"
|
|
32
|
+
Requires-Dist: pytest-cov>=7.0.0; extra == "dev"
|
|
33
|
+
Requires-Dist: coverage[toml]>=7.10.0; extra == "dev"
|
|
34
|
+
Requires-Dist: black==25.11.0; extra == "dev"
|
|
35
|
+
Requires-Dist: ruff==0.16.0; extra == "dev"
|
|
36
|
+
Requires-Dist: mypy<2.0.0,>=1.0.0; extra == "dev"
|
|
37
|
+
Dynamic: license-file
|
|
38
|
+
|
|
39
|
+
# Recursive Language Models (RLM)
|
|
40
|
+
|
|
41
|
+

|
|
42
|
+
|
|
43
|
+
[](https://github.com/grishahq/recursive-llm/actions/workflows/ci.yml)
|
|
44
|
+
[](https://www.python.org/)
|
|
45
|
+
[](https://github.com/grishahq/recursive-llm/blob/main/LICENSE)
|
|
46
|
+
[](https://github.com/grishahq/recursive-llm/releases/latest)
|
|
47
|
+
|
|
48
|
+
Analyze large contexts with bounded cost and inspectable execution. Instead of placing the full
|
|
49
|
+
source in model prompts, RLM keeps it in a restricted Python REPL, where the model can search,
|
|
50
|
+
compute, partition, and send only selected sections to language-model calls.
|
|
51
|
+
|
|
52
|
+
This is an independent Python implementation of the
|
|
53
|
+
[Recursive Language Models paper](https://arxiv.org/abs/2512.24601), focused on practical library
|
|
54
|
+
use: provider portability, tree-wide budgets, structured failures, reproducible benchmarks, and
|
|
55
|
+
complete run trajectories.
|
|
56
|
+
|
|
57
|
+
[Quick start](#quick-start) | [Visual comparison](#visual-comparison) | [Measured results](#measured-results) |
|
|
58
|
+
[Document-format evaluation](https://github.com/grishahq/recursive-llm/blob/main/DOCUMENT_EVALUATION.md) | [Configuration](#configuration) |
|
|
59
|
+
[Security](https://github.com/grishahq/recursive-llm/blob/main/SECURITY.md) |
|
|
60
|
+
[Original implementation](https://github.com/alexzhang13/rlm)
|
|
61
|
+
|
|
62
|
+
## Why use this implementation?
|
|
63
|
+
|
|
64
|
+
| Capability | What it provides |
|
|
65
|
+
| --- | --- |
|
|
66
|
+
| Externalized context | Large source text stays in the REPL instead of being repeated in model prompts |
|
|
67
|
+
| Bounded execution | Tree-wide limits for calls, tokens, estimated cost, elapsed time, and local execution |
|
|
68
|
+
| Observable runs | Per-run statistics, typed failures, versioned JSONL records, and complete trajectories |
|
|
69
|
+
| Provider portability | OpenAI, Anthropic, DeepSeek, local models, and other LiteLLM providers |
|
|
70
|
+
| Reproducible evaluation | Exact graders, generated corpora, pinned public documents, and repeated live runs |
|
|
71
|
+
| Restricted execution | Spawned RestrictedPython worker with hard timeouts and optional POSIX resource limits |
|
|
72
|
+
|
|
73
|
+
## Visual comparison
|
|
74
|
+
|
|
75
|
+
To celebrate 600 stars, the project includes a [side-by-side visualizer](https://github.com/grishahq/recursive-llm/blob/main/visualizer/README.md) of
|
|
76
|
+
real RLM and direct-model runs: synchronized replay, Python steps, call trees, exact grading, and
|
|
77
|
+
exportable recordings. Both sides use GPT-5.6 Luna through a ChatGPT-authenticated Codex CLI.
|
|
78
|
+
|
|
79
|
+
[](https://github.com/grishahq/recursive-llm/blob/main/visualizer/public/rlm-comparison.mp4)
|
|
80
|
+
|
|
81
|
+
On one 100k-character paired experiment, both answers were exact. RLM used 11,656 total CLI model
|
|
82
|
+
tokens versus 37,521 directly, with elapsed times of 30.7 and 29.0 seconds respectively. The 10k
|
|
83
|
+
experiment favored direct completion. See [CODEX_COMPARISON.md](https://github.com/grishahq/recursive-llm/blob/main/CODEX_COMPARISON.md) for both
|
|
84
|
+
outcomes, raw recordings, methodology, and reproduction commands. These are individual experiments,
|
|
85
|
+
not a general performance claim or a measurement of subscription credits saved.
|
|
86
|
+
|
|
87
|
+
```bash
|
|
88
|
+
# Uses the existing ChatGPT login and consumes Codex subscription allowance
|
|
89
|
+
python examples/capture_codex_comparison.py --chars 100000 --output comparison.json
|
|
90
|
+
```
|
|
91
|
+
|
|
92
|
+
To test another model through the same transport, pass its settings explicitly:
|
|
93
|
+
|
|
94
|
+
```bash
|
|
95
|
+
python examples/capture_codex_comparison.py --model gpt-6.1-sol \
|
|
96
|
+
--reasoning-effort low --max-depth 1 --chars 100000 --output comparison-sol.json
|
|
97
|
+
```
|
|
98
|
+
|
|
99
|
+
The web companion keeps the historical Luna/medium/depth-1 defaults. Imported captures record
|
|
100
|
+
their own model, reasoning effort, and depth; changing depth enables subcalls but does not force
|
|
101
|
+
the model to use them.
|
|
102
|
+
|
|
103
|
+
## Measured results
|
|
104
|
+
|
|
105
|
+
The exact 100k-character aggregation benchmark used one generated corpus seed and three live runs
|
|
106
|
+
per configuration. On this task, RLM improved exact correctness while reducing model-token usage.
|
|
107
|
+
|
|
108
|
+
|
|
109
|
+
|
|
110
|
+
| Model and mode | Exact passes | Mean model tokens | Mean estimated cost |
|
|
111
|
+
| --- | ---: | ---: | ---: |
|
|
112
|
+
| GPT-5 mini, direct | 0/3 | 37,928 | $0.0088788 |
|
|
113
|
+
| GPT-5 mini, RLM | 3/3 | 8,224 | $0.0048132 |
|
|
114
|
+
| DeepSeek V4 Flash, direct | 0/3 | 39,364 | $0.0012240 |
|
|
115
|
+
| DeepSeek V4 Flash, RLM | 2/3 | 15,209 | $0.0010156 |
|
|
116
|
+
|
|
117
|
+
These measurements are an engineering check, not a paper reproduction or a universal quality
|
|
118
|
+
claim. Direct completion was faster and cheaper on short tasks. A separate 1M-character RLM scale
|
|
119
|
+
check passed 6/6 exact-graded runs, but those runs used local REPL computation without child RLMs.
|
|
120
|
+
See [BENCHMARK_RESULTS.md](https://github.com/grishahq/recursive-llm/blob/main/BENCHMARK_RESULTS.md) for methodology, raw summaries, public-document
|
|
121
|
+
experiments, limitations, and reproduction commands.
|
|
122
|
+
The separate [document-format evaluation](https://github.com/grishahq/recursive-llm/blob/main/DOCUMENT_EVALUATION.md) compares RLM with direct
|
|
123
|
+
completion on a SHA-pinned TXT book, PDF, CSV, and HTML documentation page and records two
|
|
124
|
+
reliability/performance changes evaluated one at a time.
|
|
125
|
+
|
|
126
|
+
Historical transaction and literary scores used legacy graders. Current graders reject ambiguous
|
|
127
|
+
or contradictory fields and record their version; see the grading-version note in
|
|
128
|
+
[BENCHMARK_RESULTS.md](https://github.com/grishahq/recursive-llm/blob/main/BENCHMARK_RESULTS.md) before comparing old and new runs.
|
|
129
|
+
|
|
130
|
+
## When to use RLM
|
|
131
|
+
|
|
132
|
+
RLM is a good fit when:
|
|
133
|
+
|
|
134
|
+
- the source is too large or too expensive to place in a normal model prompt;
|
|
135
|
+
- the task benefits from search, filtering, exact counting, or local Python computation;
|
|
136
|
+
- selected sections can be delegated to model calls instead of repeatedly sending the full source;
|
|
137
|
+
- call, token, cost, and time limits must apply to the whole recursive run.
|
|
138
|
+
|
|
139
|
+
Prefer direct completion when the context fits comfortably in the model window and the task is
|
|
140
|
+
small. Semantic synthesis across long narrative text remains difficult and should be evaluated on
|
|
141
|
+
your own data before production use.
|
|
142
|
+
|
|
143
|
+
## Execution at a glance
|
|
144
|
+
|
|
145
|
+
```text
|
|
146
|
+
query -> root model -> Python REPL over full context -> selected chunks or child calls -> answer
|
|
147
|
+
| |
|
|
148
|
+
+-- local search/compute +-- shared budgets and trajectory
|
|
149
|
+
```
|
|
150
|
+
|
|
151
|
+
The root model receives the query and instructions, while the source is exposed as the `context`
|
|
152
|
+
variable. REPL state persists across iterations. The model can inspect small regions, perform local
|
|
153
|
+
computation, call a plain LM, or create a child RLM when the configured depth permits it.
|
|
154
|
+
|
|
155
|
+
## Installation
|
|
156
|
+
|
|
157
|
+
Use a fresh virtual environment (recommended), then install the latest release from PyPI:
|
|
158
|
+
|
|
159
|
+
```bash
|
|
160
|
+
pip install recursive-llm
|
|
161
|
+
```
|
|
162
|
+
|
|
163
|
+
`recursive-llm` and `rlms` both provide the `rlm` import namespace. Install only one of them in a
|
|
164
|
+
given environment.
|
|
165
|
+
|
|
166
|
+
For development, install from source:
|
|
167
|
+
|
|
168
|
+
```bash
|
|
169
|
+
git clone https://github.com/grishahq/recursive-llm.git
|
|
170
|
+
cd recursive-llm
|
|
171
|
+
pip install -e .
|
|
172
|
+
```
|
|
173
|
+
|
|
174
|
+
Or install the current GitHub version directly:
|
|
175
|
+
|
|
176
|
+
```bash
|
|
177
|
+
pip install "recursive-llm @ git+https://github.com/grishahq/recursive-llm.git"
|
|
178
|
+
```
|
|
179
|
+
|
|
180
|
+
## Requirements
|
|
181
|
+
|
|
182
|
+
- Python 3.9 or higher
|
|
183
|
+
- An API key for your chosen LLM provider (OpenAI, Anthropic, etc.)
|
|
184
|
+
- Or a local model setup (Ollama, llama.cpp, etc.)
|
|
185
|
+
|
|
186
|
+
## Quick Start
|
|
187
|
+
|
|
188
|
+
Set the provider key, create `quickstart.py`, and point it at a UTF-8 text file:
|
|
189
|
+
|
|
190
|
+
```bash
|
|
191
|
+
export OPENAI_API_KEY="sk-..."
|
|
192
|
+
```
|
|
193
|
+
|
|
194
|
+
```python
|
|
195
|
+
from pathlib import Path
|
|
196
|
+
|
|
197
|
+
from rlm import RLM
|
|
198
|
+
|
|
199
|
+
|
|
200
|
+
def main():
|
|
201
|
+
rlm = RLM(model="gpt-5-mini")
|
|
202
|
+
|
|
203
|
+
result = rlm.complete_result(
|
|
204
|
+
query="What are the main themes in this document?",
|
|
205
|
+
context=Path("document.txt").read_text(encoding="utf-8"),
|
|
206
|
+
)
|
|
207
|
+
print(result.answer)
|
|
208
|
+
print(result.stats)
|
|
209
|
+
|
|
210
|
+
|
|
211
|
+
if __name__ == "__main__":
|
|
212
|
+
main()
|
|
213
|
+
```
|
|
214
|
+
|
|
215
|
+
```bash
|
|
216
|
+
python quickstart.py
|
|
217
|
+
```
|
|
218
|
+
|
|
219
|
+
RLM uses a spawned worker process for isolated REPL execution. Executable Python scripts must use
|
|
220
|
+
the standard `if __name__ == "__main__":` entry-point guard, as shown above. This is required by
|
|
221
|
+
Python multiprocessing on spawn-based platforms; all repository examples follow this pattern.
|
|
222
|
+
|
|
223
|
+
### Usage and Cost Statistics
|
|
224
|
+
|
|
225
|
+
`RLM.stats` aggregates model calls across the complete recursion tree. Token usage comes from
|
|
226
|
+
provider responses, while cost is calculated on a best-effort basis using LiteLLM's model pricing
|
|
227
|
+
metadata.
|
|
228
|
+
|
|
229
|
+
```python
|
|
230
|
+
rlm = RLM(
|
|
231
|
+
model="gpt-5-mini",
|
|
232
|
+
recursive_model="deepseek/deepseek-v4-flash",
|
|
233
|
+
)
|
|
234
|
+
result = rlm.complete(query="Summarize this", context=document)
|
|
235
|
+
|
|
236
|
+
print(rlm.stats)
|
|
237
|
+
# {
|
|
238
|
+
# "llm_calls": 11,
|
|
239
|
+
# "root_calls": 3,
|
|
240
|
+
# "recursive_calls": 8,
|
|
241
|
+
# "leaf_calls": 4,
|
|
242
|
+
# "prompt_tokens": 12500,
|
|
243
|
+
# "completion_tokens": 3200,
|
|
244
|
+
# "cached_tokens": 6000,
|
|
245
|
+
# "estimated_cost_usd": 0.0047,
|
|
246
|
+
# "by_model": {
|
|
247
|
+
# "gpt-5-mini": {"calls": 3, ...},
|
|
248
|
+
# "deepseek/deepseek-v4-flash": {"calls": 8, ...},
|
|
249
|
+
# },
|
|
250
|
+
# }
|
|
251
|
+
```
|
|
252
|
+
|
|
253
|
+
Each root completion receives fresh statistics, so they describe one recursion tree rather than
|
|
254
|
+
lifetime usage.
|
|
255
|
+
`estimated_cost_usd` is `None` when LiteLLM has no pricing metadata for any completed call. Compare
|
|
256
|
+
`priced_calls` with `llm_calls` before treating the estimate as the full run cost.
|
|
257
|
+
|
|
258
|
+
When the same `RLM` instance runs concurrent completions, `RLM.stats` describes whichever root run
|
|
259
|
+
completed most recently. Use the structured result API for exact per-run statistics and trajectory:
|
|
260
|
+
|
|
261
|
+
```python
|
|
262
|
+
result = rlm.complete_result(query="Summarize this", context=document)
|
|
263
|
+
print(result.answer)
|
|
264
|
+
print(result.stats)
|
|
265
|
+
for event in result.trajectory:
|
|
266
|
+
print(event.kind, event.depth, event.node_id, event.parent_id)
|
|
267
|
+
|
|
268
|
+
# Append one complete, versioned run record for later comparison
|
|
269
|
+
result.write_jsonl("runs.jsonl")
|
|
270
|
+
```
|
|
271
|
+
|
|
272
|
+
`acomplete_result` is the asynchronous equivalent. Trajectories include the complete root, child
|
|
273
|
+
RLM, and leaf-call tree. Query, context, model response, code, and output content are represented by
|
|
274
|
+
character counts by default. Set `capture_trajectory_content=True` only when the resulting logs are
|
|
275
|
+
allowed to contain that data. An optional `event_handler` receives events as they occur; handler
|
|
276
|
+
failures do not interrupt model completion.
|
|
277
|
+
|
|
278
|
+
Use the non-raising result API when failed runs must be persisted or compared alongside successful
|
|
279
|
+
runs:
|
|
280
|
+
|
|
281
|
+
```python
|
|
282
|
+
run = rlm.try_complete_result(query="Summarize this", context=document)
|
|
283
|
+
if run.succeeded:
|
|
284
|
+
print(run.answer)
|
|
285
|
+
else:
|
|
286
|
+
print(run.error_type, run.error)
|
|
287
|
+
|
|
288
|
+
# Success and failure records share the same versioned JSONL schema.
|
|
289
|
+
run.write_jsonl("runs.jsonl")
|
|
290
|
+
```
|
|
291
|
+
|
|
292
|
+
`atry_complete_result` is the asynchronous equivalent. Ordinary run failures return a
|
|
293
|
+
`FailedCompletionResult` with exact per-run statistics, secret-free configuration, and the complete
|
|
294
|
+
partial trajectory, including its terminal `run_error` event. Cancellation and other process-control
|
|
295
|
+
exceptions are not converted. The existing `complete`, `acomplete`, `complete_result`, and
|
|
296
|
+
`acomplete_result` APIs keep their exception behavior.
|
|
297
|
+
|
|
298
|
+
Completed JSONL records contain the final answer; failed records contain `answer: null` and a typed
|
|
299
|
+
error. Query, context, intermediate model responses, code, and REPL output follow the same redaction
|
|
300
|
+
setting as the in-memory trajectory.
|
|
301
|
+
|
|
302
|
+
### Live Model Comparison
|
|
303
|
+
|
|
304
|
+
The comparison script uses the same model for both root and recursive calls. It runs one small
|
|
305
|
+
recursive smoke test by default and reports latency, calls, tokens, and estimated cost:
|
|
306
|
+
|
|
307
|
+
```bash
|
|
308
|
+
python benchmarks/compare_same_model.py gpt-5-mini
|
|
309
|
+
python benchmarks/compare_same_model.py deepseek/deepseek-v4-flash
|
|
310
|
+
```
|
|
311
|
+
|
|
312
|
+
Use repeated runs and save raw records before comparing configurations:
|
|
313
|
+
|
|
314
|
+
```bash
|
|
315
|
+
python benchmarks/compare_same_model.py gpt-5-mini --full --runs 3 --jsonl results.jsonl
|
|
316
|
+
python benchmarks/compare_same_model.py gpt-5-mini --full --runs 3 --mode direct
|
|
317
|
+
python benchmarks/compare_same_model.py gpt-5-mini --generated-chars 100000 --seed 2026
|
|
318
|
+
```
|
|
319
|
+
|
|
320
|
+
`--max-depth` compares recursion capabilities; `--mode direct` sends task and context in one normal
|
|
321
|
+
long-context model request. The script reports pass rate, p50/p95 latency, calls, tokens, and
|
|
322
|
+
best-effort cost. Task-specific graders require exact IDs, numeric boundaries, and explicit labeled
|
|
323
|
+
counts rather than accepting arbitrary substrings. Live benchmarks make paid API calls and require
|
|
324
|
+
the corresponding provider keys. `--trace` includes sensitive content-bearing trajectories in the
|
|
325
|
+
JSON output and should be used deliberately.
|
|
326
|
+
|
|
327
|
+
The repository also includes a SHA-pinned real-document benchmark over the public-domain English
|
|
328
|
+
translation of *War and Peace*. The book itself is downloaded separately and is not committed:
|
|
329
|
+
|
|
330
|
+
```bash
|
|
331
|
+
curl -L https://www.gutenberg.org/files/2600/2600-0.txt \
|
|
332
|
+
-o /tmp/war-and-peace-2600-0.txt
|
|
333
|
+
python benchmarks/war_and_peace.py gpt-5-mini /tmp/war-and-peace-2600-0.txt
|
|
334
|
+
python benchmarks/war_and_peace.py deepseek/deepseek-v4-flash \
|
|
335
|
+
/tmp/war-and-peace-2600-0.txt
|
|
336
|
+
```
|
|
337
|
+
|
|
338
|
+
`benchmarks/multi_document.py` extends this to three independently sourced large corpora: *War and
|
|
339
|
+
Peace*, the official 9/11 Commission Report, and the official Python 3.14 text documentation. It
|
|
340
|
+
verifies every prepared artifact by SHA-256 and uses exact labeled-field graders. Download and PDF
|
|
341
|
+
extraction commands, hashes, task definitions, and measured candidate results are in
|
|
342
|
+
[`BENCHMARK_RESULTS.md`](https://github.com/grishahq/recursive-llm/blob/main/BENCHMARK_RESULTS.md).
|
|
343
|
+
|
|
344
|
+
## API Keys Setup
|
|
345
|
+
|
|
346
|
+
Copy the example environment file and add keys only for the providers you use:
|
|
347
|
+
|
|
348
|
+
```bash
|
|
349
|
+
cp .env.example .env
|
|
350
|
+
```
|
|
351
|
+
|
|
352
|
+
```dotenv
|
|
353
|
+
OPENAI_API_KEY=sk-...
|
|
354
|
+
DEEPSEEK_API_KEY=...
|
|
355
|
+
MOONSHOT_API_KEY=...
|
|
356
|
+
```
|
|
357
|
+
|
|
358
|
+
Use the LiteLLM provider prefix for non-OpenAI models, for example
|
|
359
|
+
`deepseek/deepseek-v4-flash` or `moonshot/kimi-k2.6`. This lets a hybrid RLM select the correct API
|
|
360
|
+
key for each model automatically.
|
|
361
|
+
|
|
362
|
+
Or pass directly in code:
|
|
363
|
+
```python
|
|
364
|
+
rlm = RLM(model="gpt-5-mini", api_key="sk-...")
|
|
365
|
+
```
|
|
366
|
+
|
|
367
|
+
## Supported Models
|
|
368
|
+
|
|
369
|
+
Works with 100+ LLM providers via LiteLLM:
|
|
370
|
+
|
|
371
|
+
```python
|
|
372
|
+
# OpenAI
|
|
373
|
+
rlm = RLM(model="gpt-5")
|
|
374
|
+
rlm = RLM(model="gpt-5-mini")
|
|
375
|
+
|
|
376
|
+
# Anthropic
|
|
377
|
+
rlm = RLM(model="claude-sonnet-4")
|
|
378
|
+
rlm = RLM(model="claude-sonnet-4-20250514")
|
|
379
|
+
|
|
380
|
+
# Ollama (local)
|
|
381
|
+
rlm = RLM(model="ollama/llama3.2")
|
|
382
|
+
rlm = RLM(model="ollama/mistral")
|
|
383
|
+
|
|
384
|
+
# llama.cpp (local)
|
|
385
|
+
rlm = RLM(
|
|
386
|
+
model="openai/local",
|
|
387
|
+
api_base="http://localhost:8000/v1"
|
|
388
|
+
)
|
|
389
|
+
|
|
390
|
+
# Azure OpenAI
|
|
391
|
+
rlm = RLM(model="azure/gpt-4-deployment")
|
|
392
|
+
|
|
393
|
+
# And many more via LiteLLM...
|
|
394
|
+
```
|
|
395
|
+
|
|
396
|
+
## Advanced Usage
|
|
397
|
+
|
|
398
|
+
### Two Models (Optimize Cost)
|
|
399
|
+
|
|
400
|
+
Use a cheaper model for recursive calls:
|
|
401
|
+
|
|
402
|
+
```python
|
|
403
|
+
rlm = RLM(
|
|
404
|
+
model="gpt-5", # Root LM (main decisions)
|
|
405
|
+
recursive_model="gpt-5-mini" # Recursive calls (cheaper)
|
|
406
|
+
)
|
|
407
|
+
```
|
|
408
|
+
|
|
409
|
+
### Async API
|
|
410
|
+
|
|
411
|
+
For better performance with parallel recursive calls:
|
|
412
|
+
|
|
413
|
+
```python
|
|
414
|
+
import asyncio
|
|
415
|
+
|
|
416
|
+
async def main():
|
|
417
|
+
rlm = RLM(model="gpt-5-mini")
|
|
418
|
+
result = await rlm.acomplete(query, context)
|
|
419
|
+
print(result)
|
|
420
|
+
|
|
421
|
+
if __name__ == "__main__":
|
|
422
|
+
asyncio.run(main())
|
|
423
|
+
```
|
|
424
|
+
|
|
425
|
+
### Configuration
|
|
426
|
+
|
|
427
|
+
```python
|
|
428
|
+
rlm = RLM(
|
|
429
|
+
model="gpt-5-mini",
|
|
430
|
+
max_depth=2, # One child RLM level, then a plain-LM fallback
|
|
431
|
+
max_iterations=20, # Maximum REPL iterations per RLM
|
|
432
|
+
repl_timeout=5, # Hard timeout for each local Python step
|
|
433
|
+
max_output_chars=2000, # Observation truncation limit
|
|
434
|
+
repl_max_snapshot_bytes=1_000_000, # Parent-copy cap; full state stays in the worker
|
|
435
|
+
max_concurrent_subcalls=4, # Bound batch concurrency
|
|
436
|
+
max_total_calls=24, # Exact provider-call cap for the full recursion tree
|
|
437
|
+
max_total_tokens=100_000, # Stop after reported usage crosses this value
|
|
438
|
+
max_total_cost_usd=0.10, # Stop after reported cost crosses this value
|
|
439
|
+
max_elapsed_seconds=300, # Deadline shared by root and child calls
|
|
440
|
+
max_retries=2, # Retry transient provider failures; default is 0
|
|
441
|
+
retry_backoff_seconds=1.0, # Exponential retry delay; Retry-After is respected
|
|
442
|
+
# Optional LiteLLM params: temperature, timeout, etc.
|
|
443
|
+
)
|
|
444
|
+
```
|
|
445
|
+
|
|
446
|
+
Call limits are reserved atomically before provider requests, including batched and recursive
|
|
447
|
+
subcalls. Token and cost limits are evaluated after each response because providers only report
|
|
448
|
+
those values after generation; the crossing response is included in partial statistics attached to
|
|
449
|
+
`BudgetExceededError`. A deadline also bounds in-flight provider requests and REPL exchanges, and
|
|
450
|
+
prevents a validator result completed after the deadline from being accepted. A synchronous
|
|
451
|
+
validator cannot be forcibly stopped safely, so slow validator code can delay delivery of the
|
|
452
|
+
resulting `BudgetExceededError`; validators should remain fast and independently bounded. All
|
|
453
|
+
limits are optional and are reset for each root completion.
|
|
454
|
+
|
|
455
|
+
Retries are opt-in and share the same call and elapsed-time budgets as the rest of the recursion
|
|
456
|
+
tree. Every retry is counted as a provider call and recorded in statistics and trajectories.
|
|
457
|
+
RLM disables hidden LiteLLM retries to preserve exact accounting; configure `max_retries` on `RLM`
|
|
458
|
+
instead of passing `num_retries` or `max_retries` as a LiteLLM option. Null provider content is
|
|
459
|
+
normalized to an empty response so the existing repair iteration can recover, while malformed
|
|
460
|
+
response structures fail with `ProviderResponseError` or use the bounded retry path when enabled.
|
|
461
|
+
|
|
462
|
+
### Final Answer Validation
|
|
463
|
+
|
|
464
|
+
Applications can reject a syntactically valid final answer and give deterministic feedback to the
|
|
465
|
+
model without leaving the bounded run:
|
|
466
|
+
|
|
467
|
+
```python
|
|
468
|
+
def validate_answer(answer: str):
|
|
469
|
+
if not answer.startswith("count="):
|
|
470
|
+
return "Answer must start with 'count='."
|
|
471
|
+
return None
|
|
472
|
+
|
|
473
|
+
rlm = RLM(
|
|
474
|
+
model="gpt-5-mini",
|
|
475
|
+
final_answer_validator=validate_answer,
|
|
476
|
+
)
|
|
477
|
+
```
|
|
478
|
+
|
|
479
|
+
The validator returns `None` to accept an answer or a non-empty error string to reject it. Rejected
|
|
480
|
+
answers and feedback are represented by lengths in redacted trajectories and by content only when
|
|
481
|
+
`capture_trajectory_content=True`. Validator exceptions abort the run as application errors.
|
|
482
|
+
|
|
483
|
+
`max_depth` is an explicit constructor option so that runs remain reproducible. It is not read from
|
|
484
|
+
an environment variable by the library. Applications may map their own configuration or environment
|
|
485
|
+
variables to this argument.
|
|
486
|
+
|
|
487
|
+
| `max_depth` | Behavior |
|
|
488
|
+
| ---: | --- |
|
|
489
|
+
| `0` | Root RLM and REPL only; no LM subcalls |
|
|
490
|
+
| `1` (default) | Root RLM may call a plain LM |
|
|
491
|
+
| `2` | Root RLM may create one child RLM; the child falls back to a plain LM |
|
|
492
|
+
| `n` | Adds one child RLM level for every increment above `1` |
|
|
493
|
+
|
|
494
|
+
This follows the paper's capability-based depth convention. The root RLM itself is depth `0` and is
|
|
495
|
+
still valid when `max_depth=0`.
|
|
496
|
+
|
|
497
|
+
### REPL Subcall API
|
|
498
|
+
|
|
499
|
+
The model can use these functions from its persistent REPL:
|
|
500
|
+
|
|
501
|
+
```python
|
|
502
|
+
# One plain LM call, without another REPL loop
|
|
503
|
+
llm_query("Extract the date", context[1000:2000])
|
|
504
|
+
|
|
505
|
+
# Child RLM when depth permits; otherwise one plain-LM boundary call
|
|
506
|
+
rlm_query("Analyze this section", context[2000:8000])
|
|
507
|
+
|
|
508
|
+
# Ordered parallel calls, limited by max_concurrent_subcalls
|
|
509
|
+
results = llm_query_batched(queries, chunks)
|
|
510
|
+
```
|
|
511
|
+
|
|
512
|
+
`recursive_llm` remains as a backward-compatible alias for `rlm_query`. A step can finish directly
|
|
513
|
+
through `FINAL(...)`, `FINAL_VAR(...)`, or the mutable `answer` object:
|
|
514
|
+
|
|
515
|
+
```python
|
|
516
|
+
answer["content"] = result
|
|
517
|
+
answer["ready"] = True
|
|
518
|
+
```
|
|
519
|
+
|
|
520
|
+
## How It Works
|
|
521
|
+
|
|
522
|
+
1. **Context is stored as a variable** in a Python REPL environment
|
|
523
|
+
2. **Root LM gets only the query** plus instructions
|
|
524
|
+
3. **LM can explore context** using Python code:
|
|
525
|
+
```python
|
|
526
|
+
# Peek at context
|
|
527
|
+
context[:1000]
|
|
528
|
+
|
|
529
|
+
# Search with regex
|
|
530
|
+
re.findall(r'pattern', context)
|
|
531
|
+
|
|
532
|
+
# Recursive processing with a plain-LM boundary fallback
|
|
533
|
+
rlm_query("extract dates", context[1000:2000])
|
|
534
|
+
```
|
|
535
|
+
4. **Returns the final answer** via a standalone `FINAL("answer")`, `FINAL_VAR(name)`, or `answer`
|
|
536
|
+
publication
|
|
537
|
+
|
|
538
|
+
REPL variables persist between iterations. Each local step executes in an isolated subprocess, its
|
|
539
|
+
final expression is evaluated exactly once, print output is isolated per step, and non-terminating
|
|
540
|
+
local code is terminated by `repl_timeout`. Time spent waiting for model subcalls is not charged to
|
|
541
|
+
the local Python timeout. Imports are limited to the already exposed `re`, `json`, `math`,
|
|
542
|
+
`datetime`, and `collections` helpers; arbitrary modules remain blocked.
|
|
543
|
+
|
|
544
|
+
Ordinary user variables are copied back to the parent after each step only up to
|
|
545
|
+
`repl_max_snapshot_bytes` (1 MB by default), preferring smaller values. Larger values remain intact
|
|
546
|
+
in the persistent worker and are still available to later code and `FINAL_VAR`; the cap avoids
|
|
547
|
+
repeatedly serializing large intermediate lists or strings. Increase the limit only when an
|
|
548
|
+
application directly depends on the parent-side compatibility snapshot.
|
|
549
|
+
|
|
550
|
+
POSIX deployments may also opt in to worker-process limits:
|
|
551
|
+
|
|
552
|
+
```python
|
|
553
|
+
rlm = RLM(
|
|
554
|
+
model="gpt-5-mini",
|
|
555
|
+
repl_memory_limit_mb=512,
|
|
556
|
+
repl_cpu_time_limit_seconds=10,
|
|
557
|
+
repl_max_open_files=64,
|
|
558
|
+
)
|
|
559
|
+
```
|
|
560
|
+
|
|
561
|
+
These values depend on the runtime and workload, so the library does not guess defaults. A
|
|
562
|
+
configured limit that the platform cannot enforce fails worker startup explicitly. RestrictedPython
|
|
563
|
+
and a subprocess are defense-in-depth controls, not a security boundary for hostile code; read
|
|
564
|
+
[SECURITY.md](https://github.com/grishahq/recursive-llm/blob/main/SECURITY.md) before processing untrusted prompts or contexts.
|
|
565
|
+
|
|
566
|
+
## Examples
|
|
567
|
+
|
|
568
|
+
See the `examples/` directory for complete working examples:
|
|
569
|
+
- `basic_usage.py` - Simple complete with OpenAI
|
|
570
|
+
- `ollama_local.py` - Using Ollama locally
|
|
571
|
+
- `two_models.py` - Cost optimization with two models
|
|
572
|
+
- `long_document.py` - Processing 50k+ token documents
|
|
573
|
+
- `data_extraction.py` - Extract structured data from text
|
|
574
|
+
- `multi_file.py` - Process multiple documents
|
|
575
|
+
- `custom_config.py` - Advanced configuration
|
|
576
|
+
|
|
577
|
+
Run an example:
|
|
578
|
+
```bash
|
|
579
|
+
# Set your API key first
|
|
580
|
+
export OPENAI_API_KEY="sk-..."
|
|
581
|
+
|
|
582
|
+
# Run example
|
|
583
|
+
python examples/basic_usage.py
|
|
584
|
+
```
|
|
585
|
+
|
|
586
|
+
## Performance
|
|
587
|
+
|
|
588
|
+
### Paper Results
|
|
589
|
+
|
|
590
|
+
On OOLONG benchmark (132k tokens):
|
|
591
|
+
- GPT-5: baseline
|
|
592
|
+
- RLM(GPT-5-Mini): **33% better than GPT-5** at similar cost
|
|
593
|
+
|
|
594
|
+
### Reproducible Project Benchmark
|
|
595
|
+
|
|
596
|
+
`benchmarks/compare_same_model.py` contains deterministic structured contexts with exact expected
|
|
597
|
+
answers. `benchmarks/generated_long_context.py` creates byte-reproducible transaction corpora with
|
|
598
|
+
seed, SHA-256 identity, and a computed answer key. Model outputs remain stochastic, so use `--runs`
|
|
599
|
+
and compare pass rate plus p50/p95 latency before drawing quality conclusions. See
|
|
600
|
+
[BENCHMARK_RESULTS.md](https://github.com/grishahq/recursive-llm/blob/main/BENCHMARK_RESULTS.md) for the latest checked-in live comparison.
|
|
601
|
+
|
|
602
|
+
`benchmarks/war_and_peace.py` adds exact chapter counting, distant fact retrieval, and narrative
|
|
603
|
+
evidence synthesis over a verified 3.2-million-character real document.
|
|
604
|
+
|
|
605
|
+
## Development
|
|
606
|
+
|
|
607
|
+
```bash
|
|
608
|
+
# Clone repository
|
|
609
|
+
git clone https://github.com/grishahq/recursive-llm.git
|
|
610
|
+
cd recursive-llm
|
|
611
|
+
|
|
612
|
+
# Install with dev dependencies
|
|
613
|
+
pip install -e ".[dev]"
|
|
614
|
+
|
|
615
|
+
# Run tests, branch coverage, and the enforced coverage gate
|
|
616
|
+
pytest
|
|
617
|
+
|
|
618
|
+
# Type checking
|
|
619
|
+
mypy src/rlm
|
|
620
|
+
|
|
621
|
+
# Linting
|
|
622
|
+
ruff check src tests benchmarks examples
|
|
623
|
+
|
|
624
|
+
# Format code
|
|
625
|
+
black src tests examples benchmarks
|
|
626
|
+
|
|
627
|
+
# Build the source distribution and wheel
|
|
628
|
+
python -m build
|
|
629
|
+
```
|
|
630
|
+
|
|
631
|
+
GitHub Actions runs these gates across Python 3.9-3.12 on Linux, plus Python 3.12 on macOS and
|
|
632
|
+
Windows. It also installs the built wheel and runs the offline demo.
|
|
633
|
+
|
|
634
|
+
## Architecture
|
|
635
|
+
|
|
636
|
+
```
|
|
637
|
+
RLM
|
|
638
|
+
├── Core (async completion logic)
|
|
639
|
+
├── Run State (per-invocation budget, usage, and trajectory)
|
|
640
|
+
├── REPL Executor (restricted subprocess, persistent state, hard step timeout)
|
|
641
|
+
├── Prompt Builder (system prompts)
|
|
642
|
+
└── Parser (extract FINAL() answers)
|
|
643
|
+
```
|
|
644
|
+
|
|
645
|
+
Built on top of LiteLLM for universal LLM support.
|
|
646
|
+
|
|
647
|
+
## Limitations
|
|
648
|
+
|
|
649
|
+
- Python REPL steps are sequential; explicit batched LM/RLM subcalls can run concurrently
|
|
650
|
+
- No prefix caching (future enhancement)
|
|
651
|
+
- Recursion depth is limited (configurable via `max_depth`)
|
|
652
|
+
- No streaming support yet
|
|
653
|
+
|
|
654
|
+
## Troubleshooting
|
|
655
|
+
|
|
656
|
+
### "Max iterations exceeded"
|
|
657
|
+
- Increase `max_iterations` parameter
|
|
658
|
+
- Simplify your query
|
|
659
|
+
- Check if the model is getting stuck in a loop
|
|
660
|
+
|
|
661
|
+
### "API key not found"
|
|
662
|
+
- Copy `.env.example` to `.env` and set the appropriate provider variable:
|
|
663
|
+
- `OPENAI_API_KEY` for OpenAI
|
|
664
|
+
- `DEEPSEEK_API_KEY` for DeepSeek
|
|
665
|
+
- `MOONSHOT_API_KEY` for Kimi
|
|
666
|
+
- Or pass `api_key` parameter to RLM constructor
|
|
667
|
+
|
|
668
|
+
### "Model not found"
|
|
669
|
+
- Check model name format for your provider
|
|
670
|
+
- See LiteLLM docs: https://docs.litellm.ai/docs/providers
|
|
671
|
+
|
|
672
|
+
### Using Ollama
|
|
673
|
+
- Make sure Ollama is running: `ollama serve`
|
|
674
|
+
- Pull a model first: `ollama pull llama3.2`
|
|
675
|
+
- Use model format: `ollama/model-name`
|
|
676
|
+
|
|
677
|
+
## Contributing
|
|
678
|
+
|
|
679
|
+
Contributions welcome! Please:
|
|
680
|
+
1. Fork the repository
|
|
681
|
+
2. Create a feature branch
|
|
682
|
+
3. Add tests for new features
|
|
683
|
+
4. Ensure all tests pass (`pytest tests/`)
|
|
684
|
+
5. Follow code style (use `black` and `ruff`)
|
|
685
|
+
6. Submit a pull request
|
|
686
|
+
|
|
687
|
+
## Citation
|
|
688
|
+
|
|
689
|
+
This implementation is based on the RLM paper by Alex L. Zhang, Tim Kraska, and Omar Khattab.
|
|
690
|
+
|
|
691
|
+
**To cite this implementation:**
|
|
692
|
+
```bibtex
|
|
693
|
+
@software{rlm_python,
|
|
694
|
+
title = {recursive-llm: Python Implementation of Recursive Language Models},
|
|
695
|
+
author = {Gvadzabia, Grisha},
|
|
696
|
+
year = {2025},
|
|
697
|
+
url = {https://github.com/grishahq/recursive-llm}
|
|
698
|
+
}
|
|
699
|
+
```
|
|
700
|
+
|
|
701
|
+
**To cite the original paper:**
|
|
702
|
+
```bibtex
|
|
703
|
+
@misc{zhang2025rlm,
|
|
704
|
+
title = {Recursive Language Models},
|
|
705
|
+
author = {Zhang, Alex L. and Kraska, Tim and Khattab, Omar},
|
|
706
|
+
year = {2025},
|
|
707
|
+
url = {https://arxiv.org/abs/2512.24601},
|
|
708
|
+
eprint = {2512.24601},
|
|
709
|
+
archivePrefix = {arXiv}
|
|
710
|
+
}
|
|
711
|
+
```
|
|
712
|
+
|
|
713
|
+
## License
|
|
714
|
+
|
|
715
|
+
MIT License - see LICENSE file for details
|
|
716
|
+
|
|
717
|
+
## Acknowledgments
|
|
718
|
+
|
|
719
|
+
Based on the Recursive Language Models paper by Alex L. Zhang, Tim Kraska, and Omar Khattab.
|
|
720
|
+
|
|
721
|
+
Built using:
|
|
722
|
+
- LiteLLM for universal LLM API support
|
|
723
|
+
- RestrictedPython for restricted code execution
|
|
724
|
+
|
|
725
|
+
## Links
|
|
726
|
+
|
|
727
|
+
- **Paper**: https://alexzhang13.github.io/blog/2025/rlm/
|
|
728
|
+
- **arXiv**: https://arxiv.org/abs/2512.24601
|
|
729
|
+
- **Official implementation**: https://github.com/alexzhang13/rlm
|
|
730
|
+
- **LiteLLM Docs**: https://docs.litellm.ai/
|
|
731
|
+
- **Changelog**: https://github.com/grishahq/recursive-llm/blob/main/CHANGELOG.md
|
|
732
|
+
- **Releases**: https://github.com/grishahq/recursive-llm/releases
|
|
733
|
+
- **Issues**: https://github.com/grishahq/recursive-llm/issues
|