parseoff 0.2.1__py3-none-any.whl
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- parseoff/__init__.py +3 -0
- parseoff/adapters/__init__.py +32 -0
- parseoff/adapters/_common.py +10 -0
- parseoff/adapters/builtin.py +70 -0
- parseoff/adapters/custom.py +69 -0
- parseoff/adapters/optional.py +58 -0
- parseoff/cli.py +183 -0
- parseoff/doctor.py +64 -0
- parseoff/findings.py +146 -0
- parseoff/i18n.py +404 -0
- parseoff/metrics.py +142 -0
- parseoff/model.py +106 -0
- parseoff/py.typed +0 -0
- parseoff/registry.py +149 -0
- parseoff/report_html.py +173 -0
- parseoff/report_text.py +139 -0
- parseoff/runner.py +263 -0
- parseoff/samples.py +164 -0
- parseoff/textlayer.py +46 -0
- parseoff/worker.py +63 -0
- parseoff-0.2.1.dist-info/METADATA +323 -0
- parseoff-0.2.1.dist-info/RECORD +25 -0
- parseoff-0.2.1.dist-info/WHEEL +4 -0
- parseoff-0.2.1.dist-info/entry_points.txt +2 -0
- parseoff-0.2.1.dist-info/licenses/LICENSE +21 -0
|
@@ -0,0 +1,323 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: parseoff
|
|
3
|
+
Version: 0.2.1
|
|
4
|
+
Summary: Compare PDF parsers side by side on your own documents - no ground truth needed.
|
|
5
|
+
Project-URL: Homepage, https://github.com/LeeGyeongPil/parseoff
|
|
6
|
+
Project-URL: Repository, https://github.com/LeeGyeongPil/parseoff
|
|
7
|
+
Project-URL: Issues, https://github.com/LeeGyeongPil/parseoff/issues
|
|
8
|
+
License-Expression: MIT
|
|
9
|
+
License-File: LICENSE
|
|
10
|
+
Keywords: benchmark,document-parsing,evaluation,parser,pdf,rag
|
|
11
|
+
Classifier: Development Status :: 3 - Alpha
|
|
12
|
+
Classifier: Environment :: Console
|
|
13
|
+
Classifier: Intended Audience :: Developers
|
|
14
|
+
Classifier: Programming Language :: Python :: 3
|
|
15
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
16
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
17
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
18
|
+
Classifier: Topic :: Software Development :: Testing
|
|
19
|
+
Classifier: Topic :: Text Processing
|
|
20
|
+
Requires-Python: <3.14,>=3.11
|
|
21
|
+
Requires-Dist: pdfminer-six>=20260107
|
|
22
|
+
Requires-Dist: pdfplumber==0.11.10
|
|
23
|
+
Requires-Dist: pillow>=13.0.0
|
|
24
|
+
Requires-Dist: pypdf==7.0.0
|
|
25
|
+
Requires-Dist: pypdfium2>=5.15.2
|
|
26
|
+
Requires-Dist: reportlab==5.1.0
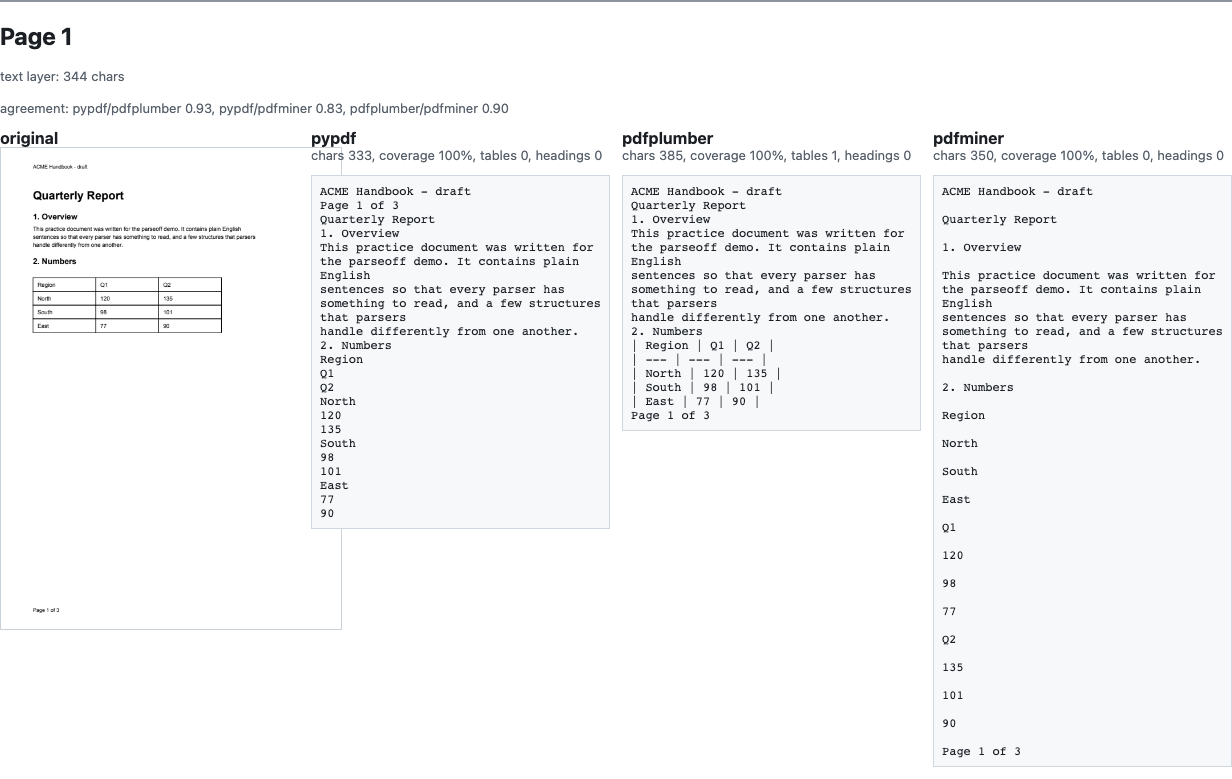
|
|
27
|
+
Provides-Extra: docling
|
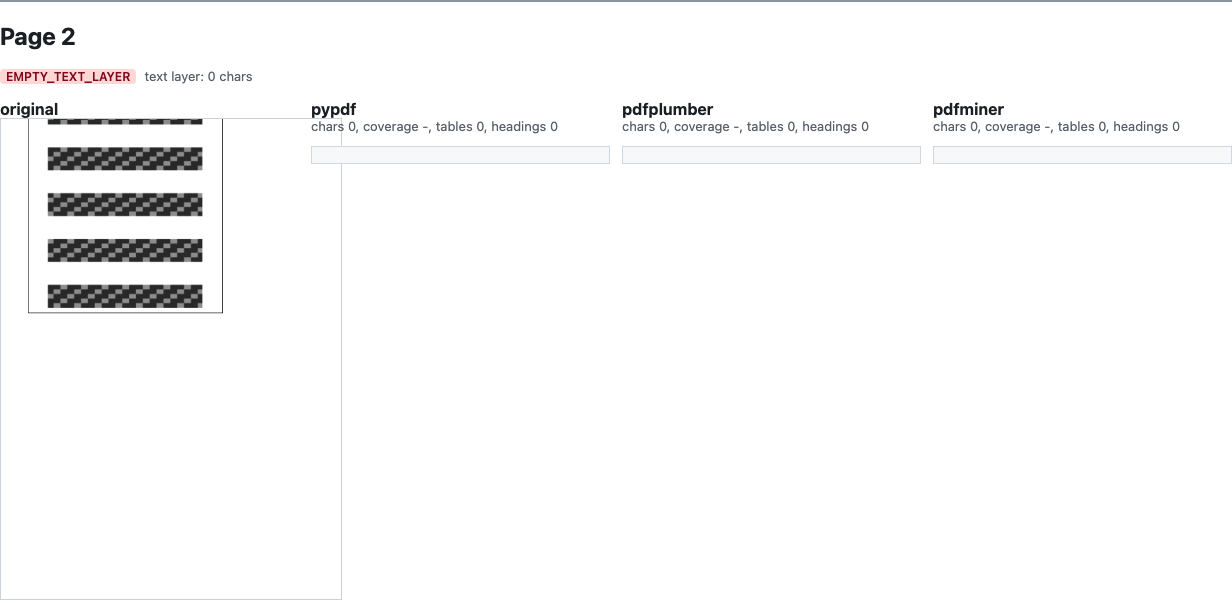
|
28
|
+
Requires-Dist: docling==2.150.0; extra == 'docling'
|
|
29
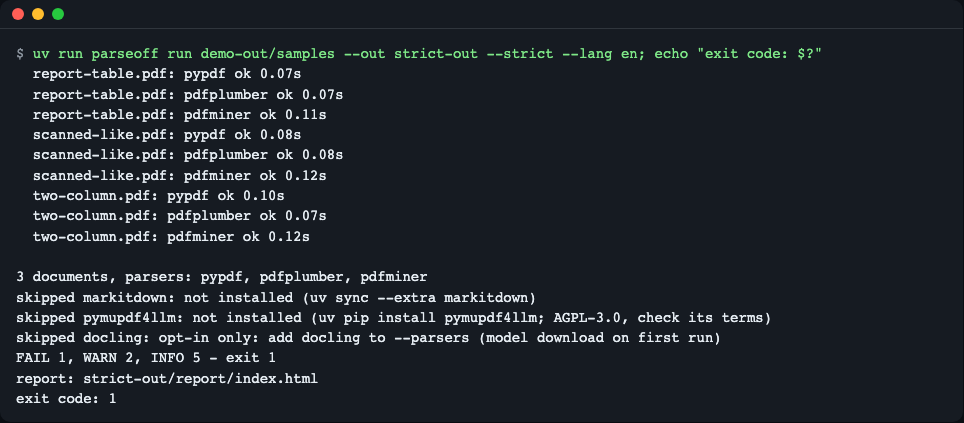
|
+
Provides-Extra: markitdown
|
|
30
|
+
Requires-Dist: markitdown[pdf]==0.1.9; extra == 'markitdown'
|
|
31
|
+
Description-Content-Type: text/markdown
|
|
32
|
+
|
|
33
|
+
# parseoff
|
|
34
|
+
|
|
35
|
+
**English** | [한국어](https://github.com/LeeGyeongPil/parseoff/blob/v0.2.1/README.ko.md)
|
|
36
|
+
|
|
37
|
+
parseoff runs several PDF parsers (pypdf, pdfplumber, pdfminer, and markitdown / pymupdf4llm / docling when installed) on *your own* PDFs and shows their output next to the original page image, with metrics that need no ground truth, plus licence and install-size warnings. One command (`parseoff run ./내폴더`, where `내폴더` means "my folder") replaces writing a script per parser and comparing output files by eye, and everything is processed on your own computer. Use it when you pick a parser for a RAG ingestion step, or before upgrading one. Not on PyPI yet (planned): `git clone` the repo, then `uv run parseoff demo`.
|
|
38
|
+
|
|
39
|
+
|
|
40
|
+
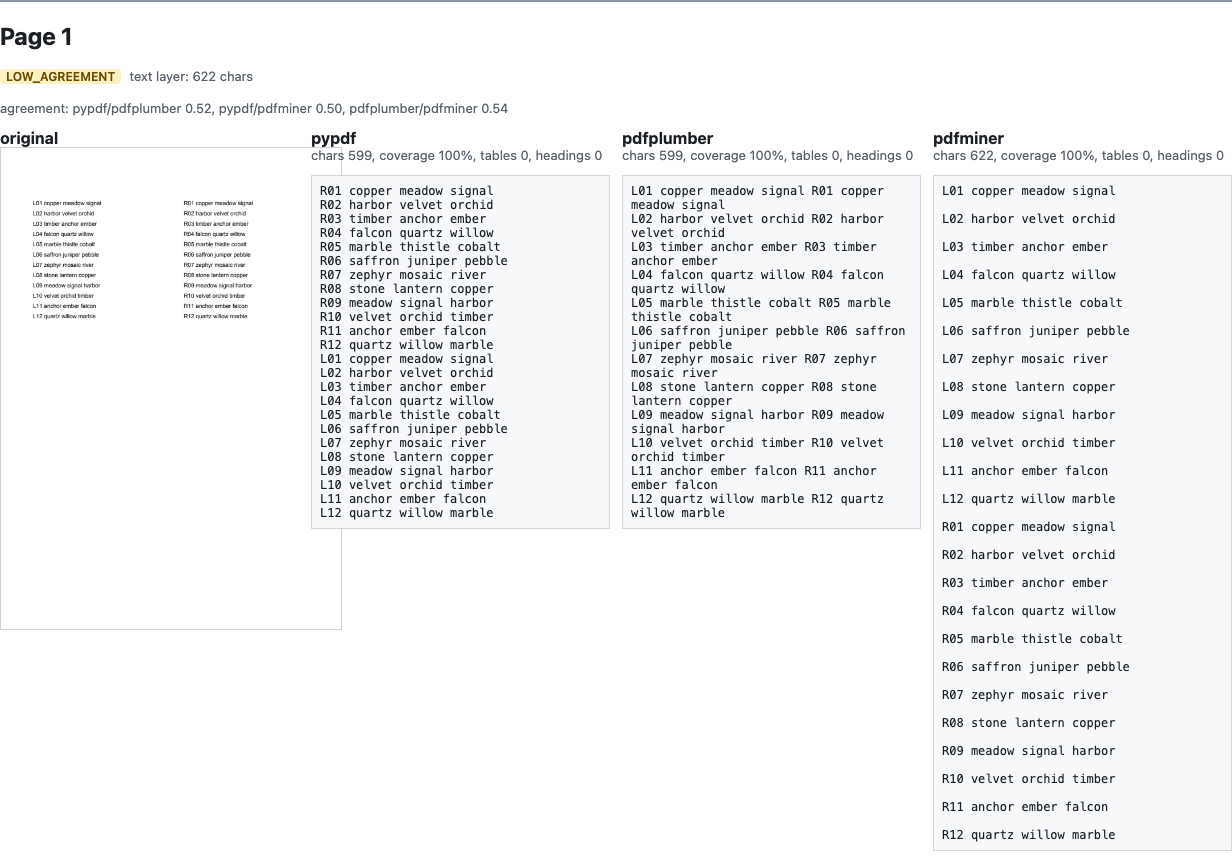
*One page of the report made by `parseoff demo`. The original is on the left and the per-parser results are on the right. It is the same page, but each parser reads it in a different order.*
|
|
41
|
+
|
|
42
|
+
## Who it is for
|
|
43
|
+
- People choosing, for the first time, a parser to turn PDFs into text for RAG or document search
|
|
44
|
+
- People who want to see how results change on their own documents before upgrading a parser version
|
|
45
|
+
- People who cannot upload documents to an external service and need to compare only parsers that run offline
|
|
46
|
+
|
|
47
|
+
## Installation
|
|
48
|
+
|
|
49
|
+
Prerequisites: Python 3.11.5-3.13 (the dev lock file targets 3.11.5 and newer; the repo's `.python-version` is 3.12, so uv picks that version; 3.14 and later are not supported because the optional parsers' dependency packages have no wheels for it), [uv](https://docs.astral.sh/uv/).
|
|
50
|
+
|
|
51
|
+
```bash
|
|
52
|
+
curl -LsSf https://astral.sh/uv/install.sh | sh # if you do not have uv
|
|
53
|
+
git clone https://github.com/LeeGyeongPil/parseoff
|
|
54
|
+
cd parseoff
|
|
55
|
+
uv run parseoff --version
|
|
56
|
+
```
|
|
57
|
+
```text
|
|
58
|
+
parseoff 0.2.1
|
|
59
|
+
```
|
|
60
|
+
|
|
61
|
+
- The method above (clone, then `uv run`) is the confirmed way to install. The first `uv run` downloads the dependency packages.
|
|
62
|
+
- Publishing to PyPI is planned (not yet). Once published, you will run it directly with `uvx parseoff demo`. After the public release, `uv tool install git+https://github.com/LeeGyeongPil/parseoff` will also work.
|
|
63
|
+
- On a minimal Linux environment, you need `git`, `curl` and Python. No other system packages are needed (PDF rendering is included in the `pypdfium2` wheel).
|
|
64
|
+
- Optional parser (not in the default install): `uv sync --extra markitdown` (MIT, about 147 MB installed). See "Adding parsers and licences" below.
|
|
65
|
+
|
|
66
|
+
## Quick start
|
|
67
|
+
|
|
68
|
+
First run `demo`, the **practice (mock) mode**. The code makes 3 synthetic PDFs (so you do not need documents of your own), and the parsers really run. The only difference from the real mode (`run`) is the input documents. The synthetic documents are very simple, so the differences look clearer than on real documents.
|
|
69
|
+
|
|
70
|
+
```bash
|
|
71
|
+
uv run parseoff demo --out demo-out
|
|
72
|
+
```
|
|
73
|
+
```text
|
|
74
|
+
parseoff demo - practice mode: 3 synthetic PDFs, real parsers
|
|
75
|
+
report-table.pdf: pypdf ok 0.09s
|
|
76
|
+
report-table.pdf: pdfplumber ok 0.07s
|
|
77
|
+
...
|
|
78
|
+
two-column.pdf: pdfminer ok 0.10s
|
|
79
|
+
|
|
80
|
+
3 documents, parsers: pypdf, pdfplumber, pdfminer
|
|
81
|
+
skipped markitdown: not installed (uv sync --extra markitdown)
|
|
82
|
+
skipped pymupdf4llm: not installed (uv pip install pymupdf4llm; AGPL-3.0, check its terms)
|
|
83
|
+
skipped docling: opt-in only: add docling to --parsers (model download on first run)
|
|
84
|
+
FAIL 1, WARN 2, INFO 5 - exit 0 (use --strict to fail)
|
|
85
|
+
report: demo-out/report/index.html
|
|
86
|
+
```
|
|
87
|
+
|
|
88
|
+
|
|
89
|
+
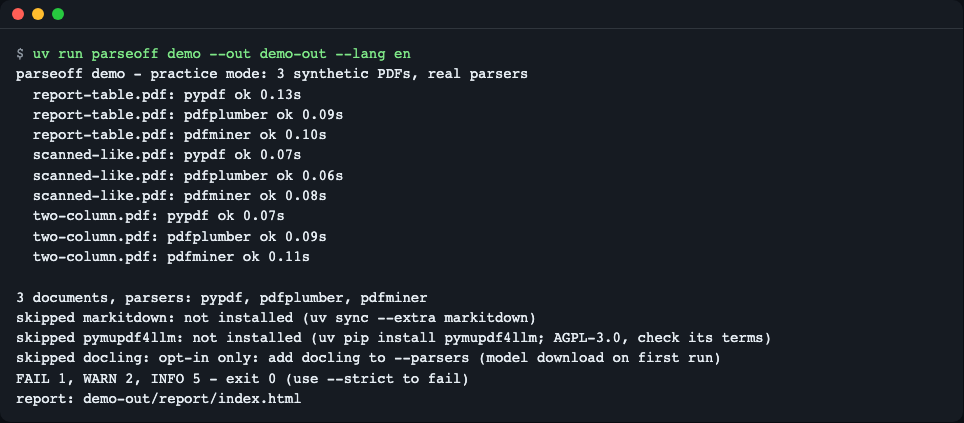
*The run screen. The times (seconds) differ from computer to computer.*
|
|
90
|
+
|
|
91
|
+
- `FAIL 1, WARN 2, INFO 5` are the counts of **findings**. FAIL means "a problem if used as is", WARN means "check by eye", and INFO is for reference.
|
|
92
|
+
- The exit code is 0 even when there are findings (1 only with `--strict`).
|
|
93
|
+
- Open `demo-out/report/index.html` in a browser. It is a static file that needs no server or internet. Directly under the output folder (`demo-out/`), `summary.json` (for machines) and `summary.md` (for people) are also created.
|
|
94
|
+
|
|
95
|
+
To run it on your own documents, just pass a folder (or a single PDF file).
|
|
96
|
+
|
|
97
|
+
```bash
|
|
98
|
+
uv run parseoff run ./내-pdf-폴더 --out my-out --max-pages 20
|
|
99
|
+
```
|
|
100
|
+
(`./내-pdf-폴더` means "my PDF folder".)
|
|
101
|
+
|
|
102
|
+
## Usage
|
|
103
|
+
|
|
104
|
+
| Command / option | What it does | Example |
|
|
105
|
+
|---|---|---|
|
|
106
|
+
| `doctor` | Shows, as a table, whether each of the 6 known parsers is installed, its actual version, licence, install size and warnings | `parseoff doctor` |
|
|
107
|
+
| `demo` | Makes 3 synthetic PDFs and compares them with the default parsers (practice) | `parseoff demo --out demo-out` |
|
|
108
|
+
| `run INPUT` | Compares a PDF file or folder (including subfolders) with all installed parsers | `parseoff run ./docs` |
|
|
109
|
+
| `--out DIR` | Output folder (`run` default `parseoff-out`, `demo` default `demo-out`) | `--out my-out` |
|
|
110
|
+
| `--parsers a,b` | Choose the parsers to run yourself (`docling` runs only if listed here) | `--parsers pypdf,pdfplumber` |
|
|
111
|
+
| `--max-pages N` | Analyze only the first N pages of each document | `--max-pages 20` |
|
|
112
|
+
| `--timeout SEC` | Time limit per (document, parser), default 120 seconds | `--timeout 60` |
|
|
113
|
+
| `--custom NAME=module:function` | Add your own parser to the same report (repeatable) | See below |
|
|
114
|
+
| `--min-coverage X` / `--min-agreement X` | Thresholds for LOW_COVERAGE (default 0.8) / LOW_AGREEMENT (default 0.6) | `--min-agreement 0.7` |
|
|
115
|
+
| `--strict` | Exit code 1 if there are FAIL findings (for CI) | `--strict` |
|
|
116
|
+
| `--fresh` | Ignore cached parser results and run again | `--fresh` |
|
|
117
|
+
| `--no-render` | Do not make page images | `--no-render` |
|
|
118
|
+
| `--lang en\|ko` | Screen language (see "Screen language" below) | `--lang ko` |
|
|
119
|
+
|
|
120
|
+
Exit codes: 0 (normal, even with findings), 1 (`--strict` and there are FAIL findings), 2 (usage error, e.g. a folder that does not exist).
|
|
121
|
+
|
|
122
|
+
### Screen language (English / Korean)
|
|
123
|
+
|
|
124
|
+
The terminal output, `--help`, error messages, the HTML report and `summary.md` come in English or Korean. The language is chosen in this order, and the first one that is set wins:
|
|
125
|
+
|
|
126
|
+
1. `--lang en` or `--lang ko` (accepted before or after the command: `parseoff --lang ko doctor` and `parseoff doctor --lang ko` both work). If `--lang` is given both before and after the command, the first one wins.
|
|
127
|
+
2. the environment variable `PARSEOFF_LANG` (`en` or `ko`). Any other value is treated as English.
|
|
128
|
+
3. the locale: the first non-empty one of `LC_ALL`, `LC_MESSAGES`, `LANG`. A value that starts with `ko` (for example `ko_KR.UTF-8`) means Korean; anything else means English.
|
|
129
|
+
|
|
130
|
+
```bash
|
|
131
|
+
uv run parseoff demo --out demo-out --lang ko
|
|
132
|
+
PARSEOFF_LANG=ko uv run parseoff doctor
|
|
133
|
+
```
|
|
134
|
+
|
|
135
|
+
The HTML report fixes its language when it is generated (`<html lang>` follows it); there is no switch inside the page. If a script compares terminal output or `summary.md` as text, set `PARSEOFF_LANG=en` or read `summary.json`.
|
|
136
|
+
|
|
137
|
+
**What stays in English** (it is data, or it comes from other software):
|
|
138
|
+
- `summary.json` in full (the machine-readable output, byte-identical in every language, including each finding's `message`), finding codes (`LOW_COVERAGE`, ...), levels (`FAIL`/`WARN`/`INFO`), parser names, status words (`ok`/`error`/`timeout`), commands such as `uv sync --extra markitdown`, licence names and the `--version` output
|
|
139
|
+
- error text that a parser or PDF library produces (for example the cause after `mine error`, or `ValueError: the PDF has no pages` in a `cannot open` finding); only the sentence around it is translated
|
|
140
|
+
- argparse messages in `--help` and argument errors that are not in the translation table (for example phrases added by newer Python versions); they appear in English
|
|
141
|
+
- the text of your documents, and code comments
|
|
142
|
+
|
|
143
|
+
The Korean-screen screenshots are used in [README.ko.md](https://github.com/LeeGyeongPil/parseoff/blob/v0.2.1/README.ko.md) (`docs/images/<id>.ko.png`).
|
|
144
|
+
|
|
145
|
+
### 1. Check install status and licences
|
|
146
|
+
|
|
147
|
+
```bash
|
|
148
|
+
uv run parseoff doctor
|
|
149
|
+
```
|
|
150
|
+
```text
|
|
151
|
+
parser installed version license install size* on disk notes
|
|
152
|
+
pypdf yes 7.0.0 BSD-3-Clause 1.8 MB 1.8 MB pure Python; text in content-stream order, no structure
|
|
153
|
+
pdfplumber yes 0.11.10 MIT 41 MB 0.2 MB text by position + tables as GFM (includes pypdfium2, pdfminer.six)
|
|
154
|
+
pdfminer yes 20260107 MIT part of pdfplumber 8.6 MB layout-box text; markitdown's PDF path is pdfminer text extraction
|
|
155
|
+
markitdown no - MIT 147 MB - most of the size is onnxruntime; page-split (one conversion per page); ...
|
|
156
|
+
pymupdf4llm no - AGPL-3.0 or commercial 214 MB - detected only if you installed it; not an extra of parseoff; WARNING copyleft licence; ...
|
|
157
|
+
docling no - MIT not measured (large, torch) - experimental; WARNING model download on first run (local models: not found); ...
|
|
158
|
+
```
|
|
159
|
+
|
|
160
|
+
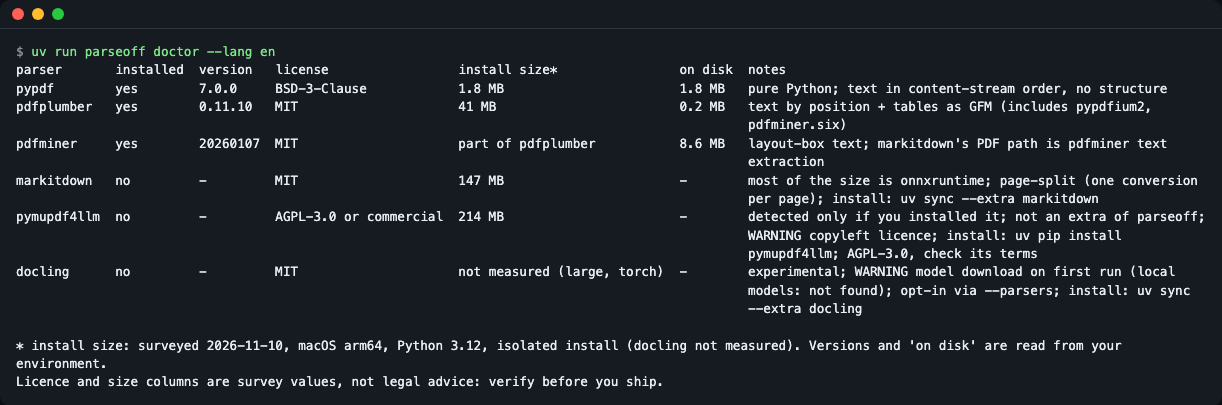
(The `notes` column is long, so it is shortened with `...`.) `install size` is a researched value measured by installing into an isolated environment on 2026-11-10, while `version` and `on disk` are values read from your own environment. Licences and sizes are for reference and are not legal advice.
|
|
161
|
+
|
|
162
|
+
|
|
163
|
+
*The `doctor` screen. Before installing, you can check "is it AGPL? why 200 MB?"*
|
|
164
|
+
|
|
165
|
+
### 2. Reading the report
|
|
166
|
+
|
|
167
|
+
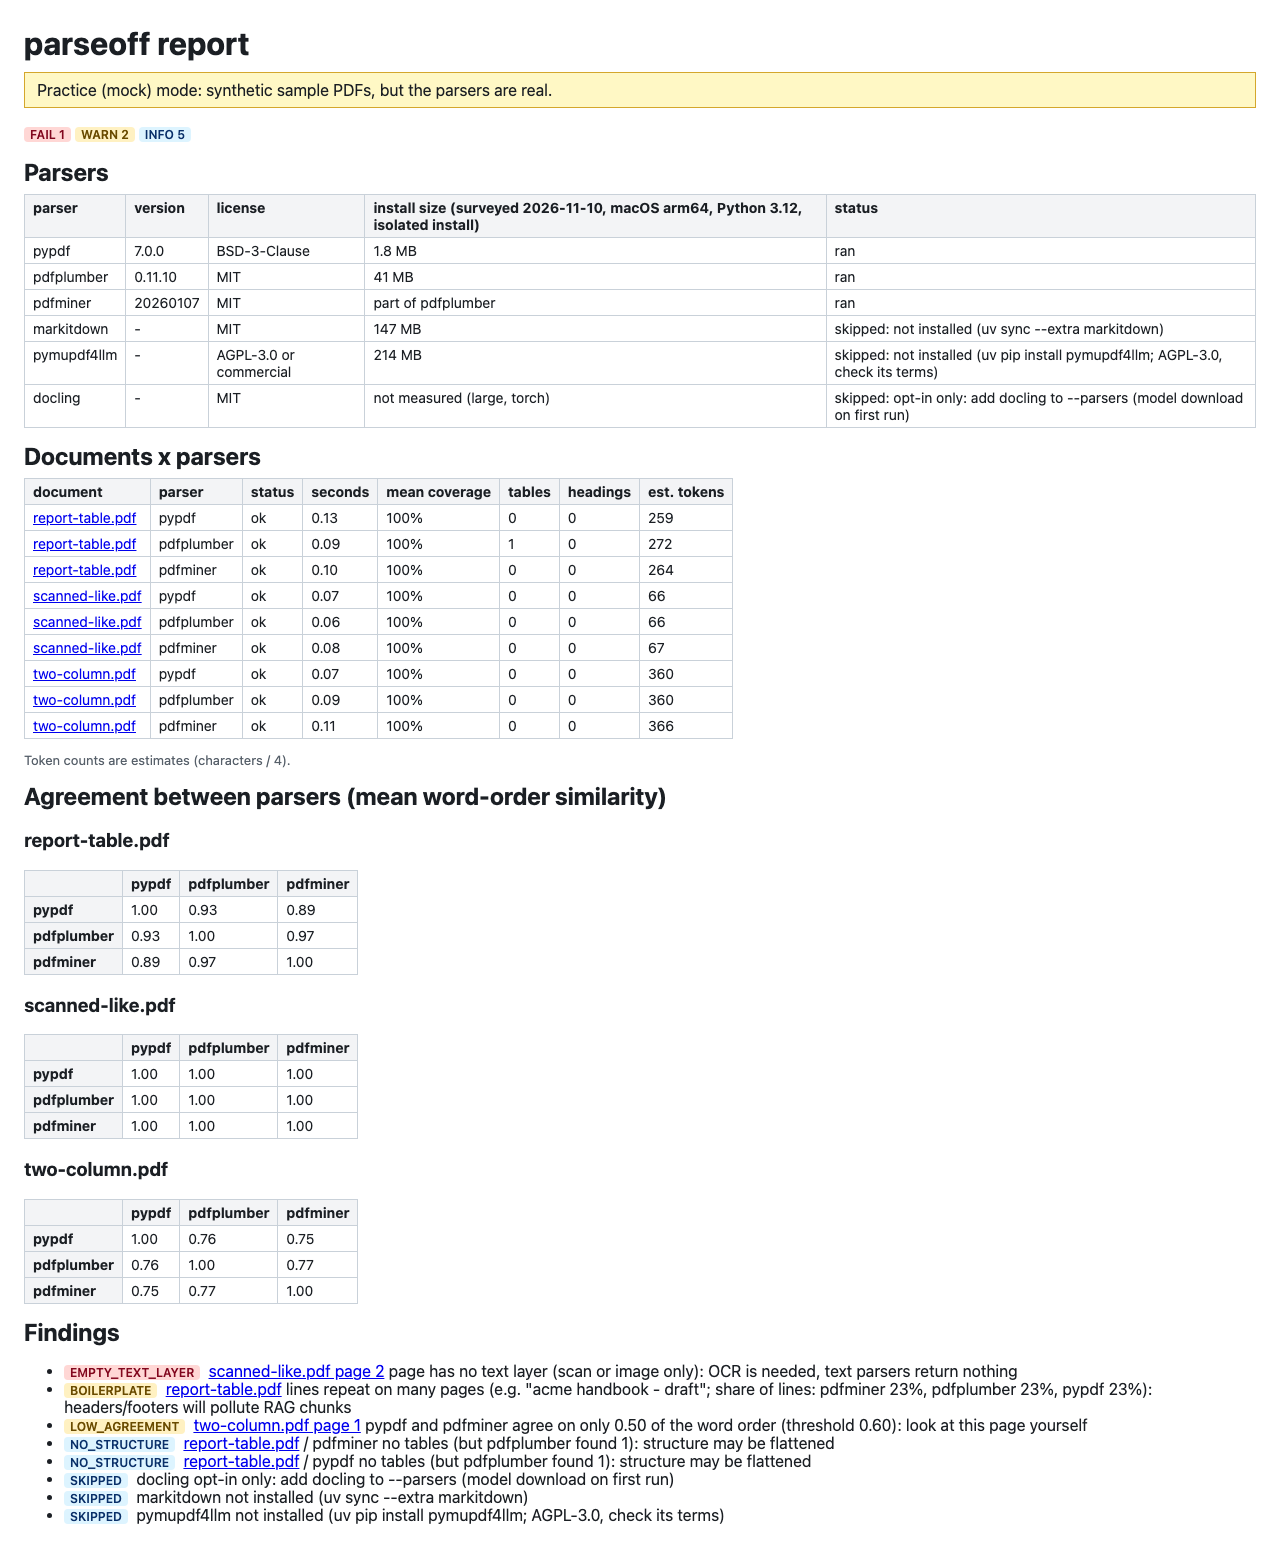
`index.html` has three things: a document x parser table (status, time, coverage, table and heading counts), a pairwise agreement matrix between parsers, and a list of findings. Click a document name and, page by page, the **original image + each parser's result** appear side by side.
|
|
168
|
+
|
|
169
|
+
|
|
170
|
+
*The overview screen. Look at the findings' badges to decide which page of which document to open.*
|
|
171
|
+
|
|
172
|
+
All metrics are computed **without ground truth**. That is why they have limits.
|
|
173
|
+
|
|
174
|
+
| Metric | Meaning | Limit |
|
|
175
|
+
|---|---|---|
|
|
176
|
+
| Coverage | The share of the words in the PDF's own text layer that the parser captured | Can be 100% even when structure (tables, order) is lost |
|
|
177
|
+
| Agreement | How similar the word order of two parsers' outputs is (0-1) | A low value does not mean "someone is wrong". It means **a page to look at by eye** |
|
|
178
|
+
| Table and heading counts | Counts of GFM tables and Markdown headings (`#`) | Not an error if a parser fails to find tables |
|
|
179
|
+
| Repeated-line ratio | The share taken by lines that repeat across pages (headers, footers, page numbers) | Deliberately repeated phrases are counted too |
|
|
180
|
+
| Estimated tokens | Number of characters / 4 (an estimate) | Differs from a real tokenizer |
|
|
181
|
+
|
|
182
|
+
### 3. Three lessons the demo shows
|
|
183
|
+
|
|
184
|
+
The 3 synthetic PDFs of `demo` show one lesson each. The figures below are values obtained by actually running this demo. (They are synthetic documents, so simpler than real ones.)
|
|
185
|
+
|
|
186
|
+
**① Table structure (`report-table.pdf` page 1)** — the table count is 1 for pdfplumber, 0 for pypdf, 0 for pdfminer. Yet coverage is 100% for all three parsers. That means they all took all the characters, but only pdfplumber kept the table shape. It is a real example of the limit that metrics without ground truth cannot show structural loss. The header "ACME Handbook - draft" and the page number repeat, giving a repeated-line ratio of 23% and a BOILERPLATE warning (the header gets mixed into RAG chunks).
|
|
187
|
+
|
|
188
|
+
|
|
189
|
+
*The table page. The same cell values come out as a table or as a list of lines depending on the parser.*
|
|
190
|
+
|
|
191
|
+
**② Two-column reading order (`two-column.pdf` page 1)** — the pairwise agreement between parsers is 0.50-0.54. pypdf reads the right column first, pdfminer reads the left column first, and pdfplumber mixes the two columns line by line (the top image). Coverage is 100% because the words are the same, but reading order matters for RAG. Page 1 is below the threshold (0.6), so a LOW_AGREEMENT warning appears. Page 2, which has one column, has an agreement of 1.00.
|
|
192
|
+
|
|
193
|
+
**③ A page with no text layer (`scanned-like.pdf` page 2)** — a page that is only an image. All three parsers have status `ok` and 0 characters. In that case coverage is recorded as not computable (`null`) rather than 0, and an `EMPTY_TEXT_LAYER` FAIL finding ("OCR needed") is raised. It is not an error but means "a document the parser cannot handle".
|
|
194
|
+
|
|
195
|
+
|
|
196
|
+
*The scanned page. The parser results are empty and a FAIL badge is attached.*
|
|
197
|
+
|
|
198
|
+
### 4. Using it in CI
|
|
199
|
+
|
|
200
|
+
```bash
|
|
201
|
+
uv run parseoff run demo-out/samples --out strict-out --strict; echo "exit code: $?"
|
|
202
|
+
```
|
|
203
|
+
```text
|
|
204
|
+
...
|
|
205
|
+
FAIL 1, WARN 2, INFO 5 - exit 1
|
|
206
|
+
report: strict-out/report/index.html
|
|
207
|
+
exit code: 1
|
|
208
|
+
```
|
|
209
|
+
|
|
210
|
+
|
|
211
|
+
*`--strict` returns exit code 1 only when there are FAIL findings.*
|
|
212
|
+
|
|
213
|
+
### 5. Adding your own parser
|
|
214
|
+
|
|
215
|
+
One function is enough. The arguments are `(pdf_path, page_numbers)` (page numbers start at 1), and it returns a list with one string per requested page. The repository's [`examples/upper_parser.py`](https://github.com/LeeGyeongPil/parseoff/blob/v0.2.1/examples/upper_parser.py):
|
|
216
|
+
|
|
217
|
+
```python
|
|
218
|
+
from pypdf import PdfReader
|
|
219
|
+
|
|
220
|
+
|
|
221
|
+
def to_pages(pdf_path: str, page_numbers: list[int]) -> list[str]:
|
|
222
|
+
reader = PdfReader(pdf_path)
|
|
223
|
+
return [(reader.pages[n - 1].extract_text() or "").upper() for n in page_numbers]
|
|
224
|
+
```
|
|
225
|
+
|
|
226
|
+
```bash
|
|
227
|
+
uv run parseoff run demo-out/samples --out custom-out --parsers pypdf --custom mine=examples.upper_parser:to_pages
|
|
228
|
+
```
|
|
229
|
+
```text
|
|
230
|
+
report-table.pdf: pypdf ok 0.09s
|
|
231
|
+
report-table.pdf: mine ok 0.13s
|
|
232
|
+
...
|
|
233
|
+
3 documents, parsers: pypdf, mine
|
|
234
|
+
FAIL 1, WARN 1, INFO 0 - exit 0 (use --strict to fail)
|
|
235
|
+
report: custom-out/report/index.html
|
|
236
|
+
```
|
|
237
|
+
|
|
238
|
+
The module is looked up in the current folder (or the environment variable `PARSEOFF_PATH`). **The code of the module you specify is run as is, so use only code you trust.** A custom parser's version does not change when its code changes, so its results are not cached.
|
|
239
|
+
|
|
240
|
+
## Configuration
|
|
241
|
+
|
|
242
|
+
There are no configuration files (no API key is needed either). All settings are command arguments. Three environment variables:
|
|
243
|
+
|
|
244
|
+
- `PARSEOFF_LANG` — screen language, `en` or `ko` (`--lang` wins over it; see "Screen language").
|
|
245
|
+
- `PARSEOFF_PATH` — folders where `--custom` modules are looked up (several, separated by the OS path separator).
|
|
246
|
+
- `DOCLING_ARTIFACTS_PATH` — the folder where docling models already exist. `doctor` checks whether the models are present.
|
|
247
|
+
|
|
248
|
+
**Result folder**: `report/` (HTML, page images `img/*.png`), `raw/<document>/<parser>.json` (the parser's raw result, which doubles as the cache), `summary.json`, `summary.md`, `samples/` (demo only). The cache key is the file sha256 + parser name + installed parser version + page list, and only `status ok` is reused. `summary.json` has no timestamps or absolute paths. With the cache, the same input gives the same result files, and when re-running with `--fresh`, only the parser run time (`seconds`) can differ.
|
|
249
|
+
|
|
250
|
+
**Privacy**: all processing happens on your own computer and uses no network (the optional parser docling downloads models on its first run). However, the output folders (`raw/`, `report/`) **contain the document contents and page images as they are.** Do not share reports of sensitive documents.
|
|
251
|
+
|
|
252
|
+
### Adding parsers and licences
|
|
253
|
+
|
|
254
|
+
| Parser | Licence | Install size (researched, 2026-11-10) | Notes | Install |
|
|
255
|
+
|---|---|---|---|---|
|
|
256
|
+
| pypdf | BSD-3-Clause | 1.8 MB | Included by default | Not needed |
|
|
257
|
+
| pdfplumber | MIT | 41 MB | Included by default, tables as GFM | Not needed |
|
|
258
|
+
| pdfminer.six | MIT | Included in pdfplumber | Included by default | Not needed |
|
|
259
|
+
| markitdown | MIT | 147 MB (mostly onnxruntime) | Converts page by page | `uv sync --extra markitdown` |
|
|
260
|
+
| pymupdf4llm | AGPL-3.0 or commercial | 214 MB | Auto-detected if installed. **Not in extras** | `uv pip install pymupdf4llm` (you may need to install it again after `uv sync`) |
|
|
261
|
+
| docling | MIT | Not measured (torch, large) | Experimental. Runs only if listed in `--parsers`, model download on first run | `uv sync --extra docling` |
|
|
262
|
+
|
|
263
|
+
If you run `uv sync --extra …` for one extra at a time, the extras you added earlier are removed. When you use more than one, specify them in a single call, as in `uv sync --extra markitdown --extra docling`.
|
|
264
|
+
|
|
265
|
+
pymupdf4llm is AGPL, so it was not put in parseoff's extras. If you install it yourself, parseoff only calls it, with a badge and a warning (LICENSE_COPYLEFT) attached. Checking the licence is your responsibility. marker is not supported yet because of its model-weight terms.
|
|
266
|
+
|
|
267
|
+
## How it works
|
|
268
|
+
|
|
269
|
+
```mermaid
|
|
270
|
+
flowchart LR
|
|
271
|
+
A["PDF file or folder"] --> B["Per parser<br/>subprocess + timeout"]
|
|
272
|
+
B --> C["raw JSON<br/>cache"]
|
|
273
|
+
A --> D["PDF text layer<br/>+ page PNG"]
|
|
274
|
+
C --> E["Compute metrics"]
|
|
275
|
+
D --> E
|
|
276
|
+
E --> F["Findings<br/>FAIL / WARN / INFO"]
|
|
277
|
+
F --> G["HTML report<br/>summary.json / md"]
|
|
278
|
+
```
|
|
279
|
+
|
|
280
|
+
1. **PDF input** — takes a single file or a folder (including subfolders).
|
|
281
|
+
2. **Subprocess + timeout** — runs each (document, parser) in a separate process (`python -m parseoff.worker`). Even if a parser crashes or hangs, the other parsers' results remain intact, and when time runs out only that process is terminated.
|
|
282
|
+
3. **raw JSON and cache** — results are stored in `raw/` right away, and the same file, parser and version are not run again (ignore with `--fresh`).
|
|
283
|
+
4. **Text layer and page PNG** — pypdfium2 produces the text the PDF holds and the page images. This becomes the baseline for coverage and the report's original image.
|
|
284
|
+
5. **Compute metrics** — coverage, pairwise agreement between parsers (standard library `difflib`), table and heading counts, repeated lines, estimated tokens.
|
|
285
|
+
6. **Findings** — FAIL / WARN / INFO are attached by rules and thresholds.
|
|
286
|
+
7. **Report** — static HTML with no external resources or scripts (all text produced by parsers is HTML-escaped), plus `summary.json` and `summary.md`.
|
|
287
|
+
|
|
288
|
+
## When to use it
|
|
289
|
+
- Use it when: choosing a parser for the first time on your own PDFs, upgrading a parser version, or when you cannot upload documents externally (everything runs locally). Even without ground-truth data, it narrows down "which spots to look at by eye".
|
|
290
|
+
- Use another tool when: if you need a public benchmark that ranks parsers by score against ground-truth Markdown, use a benchmark such as [opendataloader-bench](https://github.com/opendataloader-project/opendataloader-bench); for scanned documents that need OCR, use a parser with OCR (for example [docling](https://github.com/docling-project/docling)) directly. This tool does not do OCR.
|
|
291
|
+
- Not there yet: ground-truth scoring, comparison with a previous run (`diff`) and marker support are planned next. Formats other than PDF, such as HWP and DOCX, are not handled either.
|
|
292
|
+
|
|
293
|
+
## Troubleshooting
|
|
294
|
+
|
|
295
|
+
| Symptom | Cause | Fix |
|
|
296
|
+
|---|---|---|
|
|
297
|
+
| `error: ...: no such file or folder` (exit code 2) | The input path does not exist or the folder has no PDFs | Pass a PDF file or a folder containing PDFs |
|
|
298
|
+
| Coverage is `null` / `EMPTY_TEXT_LAYER` | A scanned or image-only page (no text layer) | OCR is needed. Comparing text parsers will not solve it |
|
|
299
|
+
| Coverage is 100% but the result looks wrong | Coverage counts only characters and cannot see tables or order | Look at agreement and table counts together, and check that page by eye in the report |
|
|
300
|
+
| `skipped markitdown: not installed` | The optional parser is not installed | Run the install command shown in the message. If you cloned the repo, it is `uv sync --extra markitdown` |
|
|
301
|
+
| `skipped pymupdf4llm: not installed` | AGPL, so it is not in extras | `uv pip install pymupdf4llm` (install again after `uv sync`). Check the licence yourself |
|
|
302
|
+
| `skipped docling: opt-in only` | docling is not run automatically | List it explicitly, as in `--parsers pypdf,pdfplumber,docling` (model download on first run) |
|
|
303
|
+
| The same result keeps coming out | Cache (same file, parser and version) | Add `--fresh` |
|
|
304
|
+
| `cannot import module ... for custom parser` | The `--custom` module is not in the current folder | Run from the folder containing the module or set `PARSEOFF_PATH`. In the terminal the cause appears on the line below `mine error`, and the full wording is in the `PARSER_ERROR` finding of `summary.md` |
|
|
305
|
+
| `uv run` prints a hardlink warning | The cache and the project are on different filesystems | Harmless. To hide it, use `UV_LINK_MODE=copy` |
|
|
306
|
+
|
|
307
|
+
## Development and contributing
|
|
308
|
+
|
|
309
|
+
```bash
|
|
310
|
+
uv run pytest -q
|
|
311
|
+
```
|
|
312
|
+
```text
|
|
313
|
+
..................................................................... [100%]
|
|
314
|
+
```
|
|
315
|
+
|
|
316
|
+
The 69 tests pass without network or model downloads, with no optional parsers installed (they take about 10-20 seconds because of the timeout test). Please leave bugs and suggestions as issues. Change history is in [CHANGELOG.md](https://github.com/LeeGyeongPil/parseoff/blob/v0.2.1/CHANGELOG.md).
|
|
317
|
+
|
|
318
|
+
## Learn more
|
|
319
|
+
- [pypdf](https://pypdf.readthedocs.io/) · [pdfplumber](https://github.com/jsvine/pdfplumber) · [pdfminer.six](https://github.com/pdfminer/pdfminer.six) · [markitdown](https://github.com/microsoft/markitdown) · [PyMuPDF4LLM](https://pymupdf.readthedocs.io/en/latest/pymupdf4llm/) · [docling](https://github.com/docling-project/docling) (all official repositories and documentation checked on 2026-11-10)
|
|
320
|
+
- Versions checked: Python 3.12 / pypdf 7.0.0 / pdfplumber 0.11.10 / pdfminer.six 20260107 / reportlab 5.1.0 (macOS arm64, 2026-11-10)
|
|
321
|
+
|
|
322
|
+
## License
|
|
323
|
+
MIT. For the licences of dependent parsers, see the table above (the synthetic PDFs of `demo` are generated directly by code and use no external data).
|
|
@@ -0,0 +1,25 @@
|
|
|
1
|
+
parseoff/__init__.py,sha256=nZOG5QFFKduKw32WH1cI4nYvngPJreSnfAwtPKOCm4Y,96
|
|
2
|
+
parseoff/cli.py,sha256=EWyZAjmeVavwZUFAZdp9noclOGPeM_O60OnieUffJdI,8064
|
|
3
|
+
parseoff/doctor.py,sha256=VpWQz90G9jmI8mG0uamSSkEMjF19are4SAvwBtRr-iA,2196
|
|
4
|
+
parseoff/findings.py,sha256=QJR66Snt4aqX4n2WWKldsfx8qfjKYalNc1k9UWaRuxs,7329
|
|
5
|
+
parseoff/i18n.py,sha256=JXxUzlS9MOBN5h5HvNUtQP18R_1ih8JhsZ4bqQ7hnl8,24162
|
|
6
|
+
parseoff/metrics.py,sha256=onF-eQNI8LoWHmX7y934PP5W7RIvsjwVnSIYZ1YUyMo,5372
|
|
7
|
+
parseoff/model.py,sha256=6I98E5JStqTsxfYvWvtUDKX-BwaTvnzdgubo_k0tWvI,2984
|
|
8
|
+
parseoff/py.typed,sha256=47DEQpj8HBSa-_TImW-5JCeuQeRkm5NMpJWZG3hSuFU,0
|
|
9
|
+
parseoff/registry.py,sha256=Nls3-FCdnb5SPDuYYyjMBmraiuC3w2AGXcH-awHo9gE,5244
|
|
10
|
+
parseoff/report_html.py,sha256=a1xs5D1M4jPzKC1jceIAR4TfK-fPlmLo_pNvItXW3OA,9357
|
|
11
|
+
parseoff/report_text.py,sha256=tefng2woM9YdTgzQ7JaSnC5B6y3kEfw4CttXTjVTVnE,6398
|
|
12
|
+
parseoff/runner.py,sha256=C3P6qIPX1H3Az1DT3hL9ZWioqDkOGLxqSnevygFIhoQ,11186
|
|
13
|
+
parseoff/samples.py,sha256=3YjPw1vhDGuOzVwRTzQ0QhmAmTuibWHZhGY9wAXscZA,6154
|
|
14
|
+
parseoff/textlayer.py,sha256=mxg6Oy84q3wzuOVcU9W7GLnPZN8EK8hhHdsaDlncCBA,1436
|
|
15
|
+
parseoff/worker.py,sha256=IOro-Q6P1GbVNoeQltKwv2ROsdntvsprHX9SJRN6QRY,2473
|
|
16
|
+
parseoff/adapters/__init__.py,sha256=OV0d4U-hzSax9pfvruAFGu8xxOepPnyGbawKH8YyJXI,1045
|
|
17
|
+
parseoff/adapters/_common.py,sha256=8RFz2Z88wz5qV889_TVJ4wjFdkuJp-P3T7DYNdvy-_0,376
|
|
18
|
+
parseoff/adapters/builtin.py,sha256=zZys18Dify-jODG2_Fdp8gW2JzMf8E7m3xhuwKNZBvU,3068
|
|
19
|
+
parseoff/adapters/custom.py,sha256=snZWDZQAXt-0xaFq8w3Is8zUGZG4cE4mZaad7XMud9E,2583
|
|
20
|
+
parseoff/adapters/optional.py,sha256=ZTwDWW7iQmkEsxogA3Y1R0fARxSUhz7VrSw_vaGwl7A,2419
|
|
21
|
+
parseoff-0.2.1.dist-info/METADATA,sha256=FcxWgI5BlXqn01OXJk4GGI_-ooc1mal9ni3zgC2JZk0,23973
|
|
22
|
+
parseoff-0.2.1.dist-info/WHEEL,sha256=2iZrJkDIkeDh0k9SikKMqFuRP-ua6mb4Ir1AsER4BEw,87
|
|
23
|
+
parseoff-0.2.1.dist-info/entry_points.txt,sha256=eQgawH-xqVC8ZPq9vPg00Qz1bCEZ6vMpVhZNDicZhdo,47
|
|
24
|
+
parseoff-0.2.1.dist-info/licenses/LICENSE,sha256=RRsvuvgBgx_uEpuct2Q4NeA9z27j12FFqpzQt1KVHL0,1069
|
|
25
|
+
parseoff-0.2.1.dist-info/RECORD,,
|
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 LeeGyeongPil
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|