openai-api-server-via-codex 0.1.6b1__py3-none-win_amd64.whl
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- openai_api_server_via_codex/__init__.py +5 -0
- openai_api_server_via_codex/__main__.py +4 -0
- openai_api_server_via_codex/bin/openai-api-server-via-codex.exe +0 -0
- openai_api_server_via_codex/launcher.py +44 -0
- openai_api_server_via_codex-0.1.6b1.dist-info/METADATA +786 -0
- openai_api_server_via_codex-0.1.6b1.dist-info/RECORD +10 -0
- openai_api_server_via_codex-0.1.6b1.dist-info/WHEEL +5 -0
- openai_api_server_via_codex-0.1.6b1.dist-info/entry_points.txt +2 -0
- openai_api_server_via_codex-0.1.6b1.dist-info/licenses/LICENSE +201 -0
- openai_api_server_via_codex-0.1.6b1.dist-info/top_level.txt +1 -0
|
Binary file
|
|
@@ -0,0 +1,44 @@
|
|
|
1
|
+
from __future__ import annotations
|
|
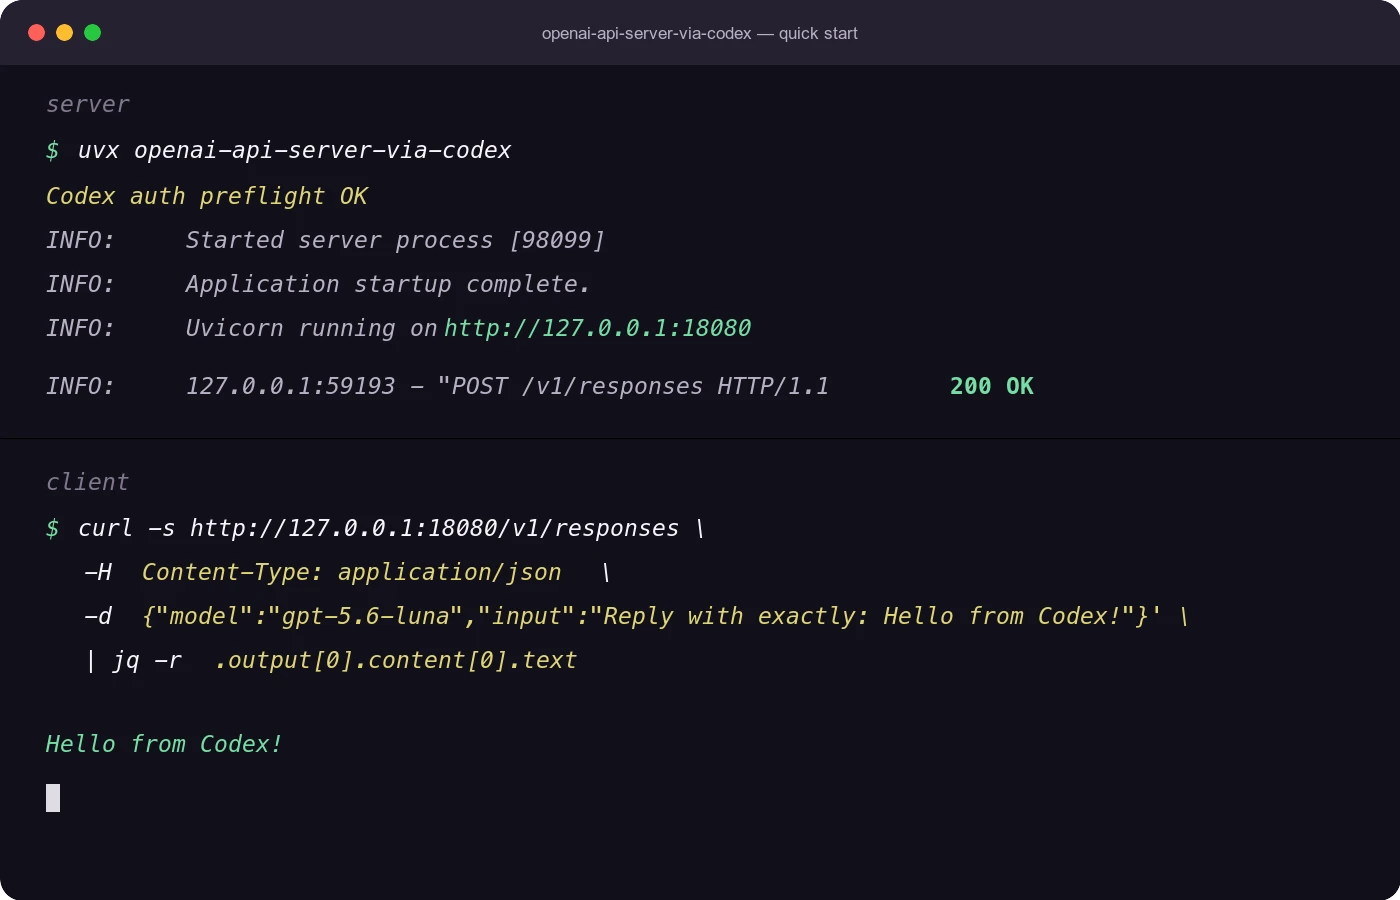
2
|
+
|
|
3
|
+
import os
|
|
4
|
+
import subprocess
|
|
5
|
+
import sys
|
|
6
|
+
from pathlib import Path
|
|
7
|
+
from typing import NoReturn
|
|
8
|
+
|
|
9
|
+
|
|
10
|
+
def bundled_binary(platform_name: str | None = None) -> Path:
|
|
11
|
+
platform_name = os.name if platform_name is None else platform_name
|
|
12
|
+
name = (
|
|
13
|
+
"openai-api-server-via-codex.exe"
|
|
14
|
+
if platform_name == "nt"
|
|
15
|
+
else "openai-api-server-via-codex"
|
|
16
|
+
)
|
|
17
|
+
return Path(__file__).with_name("bin") / name
|
|
18
|
+
|
|
19
|
+
|
|
20
|
+
def _exec_go(binary: Path) -> NoReturn:
|
|
21
|
+
os.execv(str(binary), [str(binary), *sys.argv[1:]])
|
|
22
|
+
|
|
23
|
+
|
|
24
|
+
def _launch_go(binary: Path, platform_name: str | None = None) -> NoReturn:
|
|
25
|
+
platform_name = os.name if platform_name is None else platform_name
|
|
26
|
+
if platform_name == "nt":
|
|
27
|
+
raise SystemExit(subprocess.call([str(binary), *sys.argv[1:]]))
|
|
28
|
+
_exec_go(binary)
|
|
29
|
+
|
|
30
|
+
|
|
31
|
+
def main() -> None:
|
|
32
|
+
binary = bundled_binary()
|
|
33
|
+
if not binary.is_file():
|
|
34
|
+
raise SystemExit(
|
|
35
|
+
"The Go server binary is not bundled for this platform. "
|
|
36
|
+
"Install a supported platform wheel from PyPI or build "
|
|
37
|
+
"./cmd/openai-api-server-via-codex from the source repository."
|
|
38
|
+
)
|
|
39
|
+
if os.name != "nt" and not os.access(binary, os.X_OK):
|
|
40
|
+
raise SystemExit(f"The bundled Go server is not executable: {binary}")
|
|
41
|
+
try:
|
|
42
|
+
_launch_go(binary)
|
|
43
|
+
except OSError as error:
|
|
44
|
+
raise SystemExit(f"Failed to execute the bundled Go server: {error}") from error
|
|
@@ -0,0 +1,786 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: openai-api-server-via-codex
|
|
3
|
+
Version: 0.1.6b1
|
|
4
|
+
Summary: OpenAI-compatible local API server backed by Codex credentials
|
|
5
|
+
Author: hotchpotch
|
|
6
|
+
License-Expression: Apache-2.0
|
|
7
|
+
Project-URL: Homepage, https://github.com/hotchpotch/openai-api-server-via-codex
|
|
8
|
+
Project-URL: Repository, https://github.com/hotchpotch/openai-api-server-via-codex
|
|
9
|
+
Project-URL: Issues, https://github.com/hotchpotch/openai-api-server-via-codex/issues
|
|
10
|
+
Keywords: codex,openai,openai-compatible,uvx,golang
|
|
11
|
+
Classifier: Development Status :: 4 - Beta
|
|
12
|
+
Classifier: Environment :: Console
|
|
13
|
+
Classifier: Intended Audience :: Developers
|
|
14
|
+
Classifier: Programming Language :: Go
|
|
15
|
+
Classifier: Programming Language :: Python :: 3
|
|
16
|
+
Classifier: Programming Language :: Python :: 3.10
|
|
17
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
18
|
+
Classifier: Topic :: Internet :: WWW/HTTP :: HTTP Servers
|
|
19
|
+
Requires-Python: >=3.10
|
|
20
|
+
Description-Content-Type: text/markdown
|
|
21
|
+
License-File: LICENSE
|
|
22
|
+
Dynamic: license-file
|
|
23
|
+
|
|
24
|
+
# OpenAI API Server via Codex
|
|
25
|
+
|
|
26
|
+
💰 Your ChatGPT subscription includes Codex, but that backend normally only
|
|
27
|
+
talks to Codex clients. This server puts an OpenAI-compatible API in front of
|
|
28
|
+
it, so any tool that already speaks to `api.openai.com` can use it by changing
|
|
29
|
+
one environment variable.
|
|
30
|
+
|
|
31
|
+
|
|
32
|
+
|
|
33
|
+
```console
|
|
34
|
+
$ uvx openai-api-server-via-codex
|
|
35
|
+
$ export OPENAI_BASE_URL=http://127.0.0.1:18080/v1
|
|
36
|
+
$ # this server requires no key by default, but the OpenAI SDK
|
|
37
|
+
$ # fails its own validation without one, so any value works
|
|
38
|
+
$ export OPENAI_API_KEY=dummy
|
|
39
|
+
```
|
|
40
|
+
|
|
41
|
+
Existing code keeps working as written:
|
|
42
|
+
|
|
43
|
+
```python
|
|
44
|
+
from openai import OpenAI
|
|
45
|
+
|
|
46
|
+
client = OpenAI()
|
|
47
|
+
response = client.responses.create(model="gpt-5.6-luna", input="Hello")
|
|
48
|
+
```
|
|
49
|
+
|
|
50
|
+
## 🎯 Why use it
|
|
51
|
+
|
|
52
|
+
- **No platform API key, no per-token bill.** Requests go through the Codex
|
|
53
|
+
access already included in your ChatGPT plan, not through OpenAI Platform
|
|
54
|
+
billing.
|
|
55
|
+
- **No client changes.** `openai-python`, LangChain, LiteLLM, and any tool with
|
|
56
|
+
a configurable base URL work as-is.
|
|
57
|
+
- **Both APIs, not just chat.** Responses and Chat Completions, streaming, tool
|
|
58
|
+
calling, structured outputs, image input, and image generation.
|
|
59
|
+
- **Local by default.** It binds to `127.0.0.1` and reads your existing
|
|
60
|
+
`~/.codex/auth.json`. Credentials go to the Codex backend and nowhere else.
|
|
61
|
+
- **One command.** `uvx` runs it without installing anything permanent, and
|
|
62
|
+
supported platform wheels contain a standalone Go server; `start`/`stop`/
|
|
63
|
+
`status` manage it as a background daemon.
|
|
64
|
+
|
|
65
|
+
## Use cases
|
|
66
|
+
|
|
67
|
+
- Call Codex-only models such as GPT-5.6 Luna from a notebook or a throwaway
|
|
68
|
+
script without setting up Platform billing.
|
|
69
|
+
- Run an agent, eval, or batch job you already wrote for the OpenAI SDK against
|
|
70
|
+
Codex models by switching `OPENAI_BASE_URL`.
|
|
71
|
+
- Drive editors and CLI tools that accept an OpenAI-compatible endpoint.
|
|
72
|
+
- Give a trusted machine on your LAN access with
|
|
73
|
+
`--host 0.0.0.0 --api-key ...`.
|
|
74
|
+
|
|
75
|
+
It does not raise or bypass your Codex or ChatGPT plan limits, and it is not the
|
|
76
|
+
official OpenAI Platform API. Use it only with accounts you are allowed to use,
|
|
77
|
+
and follow OpenAI's terms and usage policies. Do not resell access, expose it
|
|
78
|
+
publicly, or point third-party services at it.
|
|
79
|
+
|
|
80
|
+
## Usage
|
|
81
|
+
|
|
82
|
+
### Start with `uvx`
|
|
83
|
+
|
|
84
|
+
If Codex is already logged in on the machine, start the server with one command:
|
|
85
|
+
|
|
86
|
+
```console
|
|
87
|
+
$ uvx openai-api-server-via-codex
|
|
88
|
+
2026/08/12 12:34:56 openai-api-server-via-codex 0.1.6b1 (Go) listening on http://127.0.0.1:18080
|
|
89
|
+
```
|
|
90
|
+
|
|
91
|
+
The default server URL is `http://127.0.0.1:18080`. OpenAI-compatible API
|
|
92
|
+
endpoints are served under `/v1`, for example
|
|
93
|
+
`http://127.0.0.1:18080/v1/responses`.
|
|
94
|
+
|
|
95
|
+
> [!TIP]
|
|
96
|
+
> `uvx` is uv's tool-run command. If you do not have uv installed yet, follow
|
|
97
|
+
> the official uv documentation: <https://docs.astral.sh/uv/>.
|
|
98
|
+
>
|
|
99
|
+
> To force `uvx` to use the latest published package instead of a cached copy,
|
|
100
|
+
> run `uvx --refresh-package openai-api-server-via-codex openai-api-server-via-codex`.
|
|
101
|
+
|
|
102
|
+
> [!NOTE]
|
|
103
|
+
> This is a compatibility server for local or trusted environments. By default,
|
|
104
|
+
> it accepts any incoming OpenAI API key value because `openai-python` requires
|
|
105
|
+
> one even when this server does not. Set `--api-key` if you want the server to
|
|
106
|
+
> authenticate incoming requests, especially when binding to anything other than
|
|
107
|
+
> localhost.
|
|
108
|
+
|
|
109
|
+
### Call the Responses API
|
|
110
|
+
|
|
111
|
+
Point `openai-python` at the local server with the standard OpenAI client
|
|
112
|
+
environment variables:
|
|
113
|
+
|
|
114
|
+
```console
|
|
115
|
+
$ export OPENAI_BASE_URL=http://127.0.0.1:18080/v1
|
|
116
|
+
$ export OPENAI_API_KEY=dummy
|
|
117
|
+
```
|
|
118
|
+
|
|
119
|
+
```python
|
|
120
|
+
from openai import OpenAI
|
|
121
|
+
|
|
122
|
+
client = OpenAI()
|
|
123
|
+
|
|
124
|
+
response = client.responses.create(
|
|
125
|
+
model="gpt-5.6-luna",
|
|
126
|
+
input="Reply in one sentence.",
|
|
127
|
+
reasoning={"effort": "low"},
|
|
128
|
+
)
|
|
129
|
+
print(response.output_text)
|
|
130
|
+
```
|
|
131
|
+
|
|
132
|
+
`OPENAI_API_KEY=dummy` is only a placeholder required by the OpenAI SDK. Unless
|
|
133
|
+
you configure `--api-key`, the local server accepts any incoming API key value.
|
|
134
|
+
|
|
135
|
+
### Use chat completions
|
|
136
|
+
|
|
137
|
+
```python
|
|
138
|
+
chat = client.chat.completions.create(
|
|
139
|
+
model="gpt-5.6-luna",
|
|
140
|
+
messages=[{"role": "user", "content": "Hello"}],
|
|
141
|
+
reasoning_effort="low",
|
|
142
|
+
)
|
|
143
|
+
print(chat.choices[0].message.content)
|
|
144
|
+
```
|
|
145
|
+
|
|
146
|
+
### Stream a response
|
|
147
|
+
|
|
148
|
+
```python
|
|
149
|
+
stream = client.responses.create(
|
|
150
|
+
model="gpt-5.6-luna",
|
|
151
|
+
input="Stream a short reply.",
|
|
152
|
+
stream=True,
|
|
153
|
+
reasoning={"effort": "low"},
|
|
154
|
+
)
|
|
155
|
+
|
|
156
|
+
for event in stream:
|
|
157
|
+
if event.type == "response.output_text.delta":
|
|
158
|
+
print(event.delta, end="")
|
|
159
|
+
```
|
|
160
|
+
|
|
161
|
+
### Generate an image
|
|
162
|
+
|
|
163
|
+
```python
|
|
164
|
+
import base64
|
|
165
|
+
|
|
166
|
+
image = client.images.generate(
|
|
167
|
+
model="gpt-image-2",
|
|
168
|
+
prompt="A cozy pixel art bowl of ramen, no text.",
|
|
169
|
+
size="1024x1024",
|
|
170
|
+
quality="medium",
|
|
171
|
+
output_format="png",
|
|
172
|
+
)
|
|
173
|
+
|
|
174
|
+
png_bytes = base64.b64decode(image.data[0].b64_json)
|
|
175
|
+
with open("ramen.png", "wb") as file:
|
|
176
|
+
file.write(png_bytes)
|
|
177
|
+
```
|
|
178
|
+
|
|
179
|
+
The image generation endpoint returns OpenAI-compatible base64 image results.
|
|
180
|
+
The server does not host generated files or return temporary image URLs. Do not
|
|
181
|
+
pass `response_format`; GPT image generations are returned as `b64_json`.
|
|
182
|
+
|
|
183
|
+
### Run as a background daemon
|
|
184
|
+
|
|
185
|
+
```console
|
|
186
|
+
$ uvx openai-api-server-via-codex start
|
|
187
|
+
Codex auth preflight OK: /home/you/.codex/auth.json (account_id_present=True)
|
|
188
|
+
Started openai-api-server-via-codex on 127.0.0.1:18080
|
|
189
|
+
PID: 12345
|
|
190
|
+
PID file: /home/you/.config/openai-api-server-via-codex/run/server-127.0.0.1-18080.pid
|
|
191
|
+
Log file: /home/you/.config/openai-api-server-via-codex/run/server-127.0.0.1-18080.log
|
|
192
|
+
|
|
193
|
+
$ uvx openai-api-server-via-codex status
|
|
194
|
+
$ uvx openai-api-server-via-codex stop
|
|
195
|
+
```
|
|
196
|
+
|
|
197
|
+
On Linux and macOS, `stop` drains in-flight HTTP requests up to
|
|
198
|
+
`--stop-timeout`. Windows stops the daemon process tree on a best-effort basis;
|
|
199
|
+
in-flight streams may be interrupted.
|
|
200
|
+
|
|
201
|
+
Expose the server to other machines only with access control:
|
|
202
|
+
|
|
203
|
+
```console
|
|
204
|
+
$ uvx openai-api-server-via-codex start \
|
|
205
|
+
--host 0.0.0.0 \
|
|
206
|
+
--api-key local-secret
|
|
207
|
+
```
|
|
208
|
+
|
|
209
|
+
Then connect clients to `http://<server-host>:18080/v1` and pass
|
|
210
|
+
`api_key="local-secret"` to the OpenAI client.
|
|
211
|
+
|
|
212
|
+
## Installation options
|
|
213
|
+
|
|
214
|
+
Run without installing:
|
|
215
|
+
|
|
216
|
+
```console
|
|
217
|
+
$ uvx openai-api-server-via-codex
|
|
218
|
+
```
|
|
219
|
+
|
|
220
|
+
Install the command onto your standard user tool path:
|
|
221
|
+
|
|
222
|
+
```console
|
|
223
|
+
$ uv tool install openai-api-server-via-codex
|
|
224
|
+
$ openai-api-server-via-codex --help
|
|
225
|
+
```
|
|
226
|
+
|
|
227
|
+
Upgrade an installed tool:
|
|
228
|
+
|
|
229
|
+
```console
|
|
230
|
+
$ uv tool upgrade openai-api-server-via-codex
|
|
231
|
+
$ openai-api-server-via-codex --version
|
|
232
|
+
```
|
|
233
|
+
|
|
234
|
+
For development from this checkout:
|
|
235
|
+
|
|
236
|
+
```console
|
|
237
|
+
$ uv sync --dev
|
|
238
|
+
$ uv run openai-api-server-via-codex --help
|
|
239
|
+
```
|
|
240
|
+
|
|
241
|
+
### Run with Docker
|
|
242
|
+
|
|
243
|
+
From this checkout, run the server with nothing but Docker installed:
|
|
244
|
+
|
|
245
|
+
```console
|
|
246
|
+
$ docker compose run --rm --service-ports codex-login # once, if ~/.codex/auth.json does not exist yet
|
|
247
|
+
$ docker compose up --build -d
|
|
248
|
+
$ curl http://127.0.0.1:18080/healthz
|
|
249
|
+
```
|
|
250
|
+
|
|
251
|
+
The Compose setup bind-mounts `~/.codex` so the container borrows the Codex
|
|
252
|
+
login and writes refreshed tokens back. The one-shot `codex-login` helper
|
|
253
|
+
bundles the official Codex CLI for interactive login when Codex is not
|
|
254
|
+
installed on the host; an existing login also works as-is, since `auth.json`
|
|
255
|
+
can be copied from any machine. See [docs/docker.md](docs/docker.md) for the
|
|
256
|
+
login options, configuration, plain `docker run` usage, and permission notes
|
|
257
|
+
for Linux hosts.
|
|
258
|
+
|
|
259
|
+
## Requirements
|
|
260
|
+
|
|
261
|
+
- `uv`
|
|
262
|
+
- A working Codex login, usually at `~/.codex/auth.json`
|
|
263
|
+
|
|
264
|
+
Published wheels include the Go server for Linux (x86_64/ARM64), macOS
|
|
265
|
+
(Intel/Apple silicon), and Windows (x86_64/ARM64). `uvx` installs one small
|
|
266
|
+
platform wheel and its lightweight Python entry point immediately replaces
|
|
267
|
+
itself with the bundled Go executable. A system Go installation is not needed.
|
|
268
|
+
There is no Python server fallback. Source installations and platforms without
|
|
269
|
+
a published wheel require building `./cmd/openai-api-server-via-codex` with Go.
|
|
270
|
+
|
|
271
|
+
Use an explicit Codex auth file when needed:
|
|
272
|
+
|
|
273
|
+
```console
|
|
274
|
+
$ uvx openai-api-server-via-codex --auth-json ~/.codex/auth.json
|
|
275
|
+
$ OPENAI_VIA_CODEX_AUTH_JSON=~/.codex/auth.json uvx openai-api-server-via-codex
|
|
276
|
+
```
|
|
277
|
+
|
|
278
|
+
`serve` and `start` validate the Codex auth file before starting. If the file is
|
|
279
|
+
missing, not valid JSON, not a ChatGPT Codex auth file, missing tokens, expired
|
|
280
|
+
without a refresh token, or fails token refresh, the server exits before it
|
|
281
|
+
binds the HTTP port.
|
|
282
|
+
|
|
283
|
+
> [!NOTE]
|
|
284
|
+
> The incoming OpenAI-compatible API key and the Codex auth file are separate.
|
|
285
|
+
> `--api-key` protects this local server. `--auth-json` selects the Codex
|
|
286
|
+
> credentials used by the server when it calls the Codex backend.
|
|
287
|
+
|
|
288
|
+
## Disclaimer
|
|
289
|
+
|
|
290
|
+
Use this project at your own risk. It is not the official OpenAI Platform API
|
|
291
|
+
and is not endorsed or supported by OpenAI. It forwards requests to the Codex
|
|
292
|
+
HTTP backend used by the Codex CLI and ChatGPT subscription flow instead of
|
|
293
|
+
`api.openai.com`.
|
|
294
|
+
|
|
295
|
+
For reference, Simon Willison describes this route as a
|
|
296
|
+
[semi-official OpenAI Codex backdoor API](https://simonwillison.net/2026/Apr/23/gpt-5-5/).
|
|
297
|
+
That matches this project's practical model: it uses the ChatGPT/Codex backend
|
|
298
|
+
available through your own logged-in Codex credentials, and that backend may
|
|
299
|
+
change without notice.
|
|
300
|
+
|
|
301
|
+
Use this server only with accounts and subscriptions you are allowed to use. Do
|
|
302
|
+
not use it to evade limits, share account access, resell access, or power
|
|
303
|
+
third-party services. Do not expose it to untrusted networks without `--api-key`
|
|
304
|
+
or another access control layer, and follow OpenAI's
|
|
305
|
+
[Terms of Use](https://openai.com/policies/terms-of-use/) and
|
|
306
|
+
[Usage Policies](https://openai.com/policies/usage-policies/).
|
|
307
|
+
|
|
308
|
+
## API endpoints
|
|
309
|
+
|
|
310
|
+
The endpoints below are implemented locally for OpenAI-compatible behavior.
|
|
311
|
+
They normalize Codex HTTP requests, translate streaming events, and maintain
|
|
312
|
+
the in-memory compatibility stores used by Responses and stored Chat
|
|
313
|
+
Completions.
|
|
314
|
+
|
|
315
|
+
| Method | Path |
|
|
316
|
+
| --- | --- |
|
|
317
|
+
| `GET` | `/healthz` |
|
|
318
|
+
| `GET` | `/v1/models` |
|
|
319
|
+
| `POST` | `/v1/responses` |
|
|
320
|
+
| `GET` | `/v1/responses/{response_id}` |
|
|
321
|
+
| `DELETE` | `/v1/responses/{response_id}` |
|
|
322
|
+
| `POST` | `/v1/responses/{response_id}/cancel` |
|
|
323
|
+
| `POST` | `/v1/responses/input_tokens` |
|
|
324
|
+
| `POST` | `/v1/audio/transcriptions` |
|
|
325
|
+
| `POST` | `/v1/images/generations` |
|
|
326
|
+
| `POST` | `/v1/chat/completions` |
|
|
327
|
+
| `GET` | `/v1/chat/completions` |
|
|
328
|
+
| `GET` | `/v1/chat/completions/{completion_id}` |
|
|
329
|
+
| `POST` | `/v1/chat/completions/{completion_id}` |
|
|
330
|
+
| `DELETE` | `/v1/chat/completions/{completion_id}` |
|
|
331
|
+
| `GET` | `/v1/chat/completions/{completion_id}/messages` |
|
|
332
|
+
|
|
333
|
+
For any other `/v1/...` request, the server falls back to a best-effort proxy:
|
|
334
|
+
it forwards the method, path, query string, safe OpenAI-style request headers,
|
|
335
|
+
and raw request body to the Codex HTTP backend, then returns the upstream status,
|
|
336
|
+
body, and safe response headers. This allows endpoints that are not implemented
|
|
337
|
+
locally, including Codex-specific or newly added OpenAI-style paths, to be tried
|
|
338
|
+
without adding a compatibility shim for each endpoint.
|
|
339
|
+
|
|
340
|
+
The fallback proxy uses the local Codex credentials selected by this server. It
|
|
341
|
+
does not forward the incoming `Authorization` header, local `--api-key`, or
|
|
342
|
+
cookies to Codex HTTP. Successful behavior still depends on what the upstream
|
|
343
|
+
Codex HTTP backend accepts for that path; unsupported upstream paths may return
|
|
344
|
+
Codex HTTP errors such as `400`, `403`, or `404`.
|
|
345
|
+
|
|
346
|
+
## Compatibility
|
|
347
|
+
|
|
348
|
+
The server supports both sync and async `openai-python` clients for the main
|
|
349
|
+
OpenAI APIs:
|
|
350
|
+
|
|
351
|
+
- `client.responses.create(...)`
|
|
352
|
+
- `client.chat.completions.create(...)`
|
|
353
|
+
|
|
354
|
+
Supported behavior includes:
|
|
355
|
+
|
|
356
|
+
- `stream=True` for Responses and Chat Completions
|
|
357
|
+
- `previous_response_id` for Responses, backed by local in-memory context
|
|
358
|
+
- standard Chat Completions multi-turn through the `messages` list
|
|
359
|
+
- function and tool calling, including streaming tool-call arguments
|
|
360
|
+
- image generation through `client.images.generate(...)` with base64 image data
|
|
361
|
+
- JSON mode and structured outputs
|
|
362
|
+
- URL and data URL image parts
|
|
363
|
+
- reasoning effort fields where the selected model accepts them
|
|
364
|
+
- stored Chat Completions compatibility APIs backed by local in-memory storage
|
|
365
|
+
|
|
366
|
+
For Codex compatibility, backend requests are normalized to streaming
|
|
367
|
+
Responses calls with `store=false`, low text verbosity by default, automatic
|
|
368
|
+
tool choice defaults, and `reasoning.encrypted_content` included for reasoning
|
|
369
|
+
context. Public `store=true` behavior is implemented locally.
|
|
370
|
+
|
|
371
|
+
Image generations are implemented by translating `client.images.generate(...)`
|
|
372
|
+
requests into a Codex Responses call with the hosted `image_generation` tool,
|
|
373
|
+
then returning the generated image bytes as `data[].b64_json`. The public image
|
|
374
|
+
model parameter is accepted for OpenAI SDK compatibility, but the backend call
|
|
375
|
+
uses this server's configured Codex model because hosted image generation runs
|
|
376
|
+
inside a Responses request. The endpoint supports non-streaming generation only;
|
|
377
|
+
`response_format`, URL results, streamed partial images, `style`, and
|
|
378
|
+
`client.images.edit(...)` are not implemented. `n` is handled by making one
|
|
379
|
+
Codex image generation call per requested image. Supported GPT image controls
|
|
380
|
+
such as `size`, `quality`, `background`, `moderation`, `output_compression`,
|
|
381
|
+
and `output_format` are forwarded directly into the hosted `image_generation`
|
|
382
|
+
tool spec instead of being rewritten into the prompt. Arbitrary `WIDTHxHEIGHT`
|
|
383
|
+
size strings are accepted and forwarded, though the top-level
|
|
384
|
+
OpenAI-compatible response echoes only SDK-compatible standard sizes.
|
|
385
|
+
|
|
386
|
+
> [!NOTE]
|
|
387
|
+
> Model listing is best-effort because the upstream Codex HTTP model catalog can
|
|
388
|
+
> differ from the models that a subscription can actually run. As of
|
|
389
|
+
> 2026-05-06, with a ChatGPT Pro subscription, `gpt-5.3-codex-spark` did not
|
|
390
|
+
> appear in `GET /v1/models` in our live test, but direct requests using
|
|
391
|
+
> `model="gpt-5.3-codex-spark"` succeeded. OpenAI also describes
|
|
392
|
+
> GPT-5.3-Codex-Spark as a research preview for ChatGPT Pro users.
|
|
393
|
+
|
|
394
|
+
## Configuration
|
|
395
|
+
|
|
396
|
+
Generate a default config file:
|
|
397
|
+
|
|
398
|
+
```console
|
|
399
|
+
$ uvx openai-api-server-via-codex config-generate
|
|
400
|
+
$ uvx openai-api-server-via-codex config-generate --stdout
|
|
401
|
+
```
|
|
402
|
+
|
|
403
|
+
The default config path is:
|
|
404
|
+
|
|
405
|
+
```text
|
|
406
|
+
$XDG_CONFIG_HOME/openai-api-server-via-codex/config.toml
|
|
407
|
+
```
|
|
408
|
+
|
|
409
|
+
If `XDG_CONFIG_HOME` is unset, this becomes:
|
|
410
|
+
|
|
411
|
+
```text
|
|
412
|
+
~/.config/openai-api-server-via-codex/config.toml
|
|
413
|
+
```
|
|
414
|
+
|
|
415
|
+
You can also set `OPENAI_VIA_CODEX_CONFIG` or pass `--config` to `serve`,
|
|
416
|
+
`start`, `stop`, and `status`.
|
|
417
|
+
|
|
418
|
+
Resolution order is:
|
|
419
|
+
|
|
420
|
+
```text
|
|
421
|
+
CLI flag -> environment variable -> config file -> default
|
|
422
|
+
```
|
|
423
|
+
|
|
424
|
+
Example config:
|
|
425
|
+
|
|
426
|
+
```toml
|
|
427
|
+
[server]
|
|
428
|
+
host = "127.0.0.1"
|
|
429
|
+
port = 18080
|
|
430
|
+
default_model = "gpt-5.6-luna"
|
|
431
|
+
timeout = 300.0
|
|
432
|
+
verbose = false
|
|
433
|
+
max_stored_items = 1000
|
|
434
|
+
max_concurrent_requests = 10
|
|
435
|
+
# api_key = "change-me"
|
|
436
|
+
|
|
437
|
+
[codex]
|
|
438
|
+
auth_json = "~/.codex/auth.json"
|
|
439
|
+
backend_base_url = "https://chatgpt.com/backend-api/codex"
|
|
440
|
+
client_version = "1.0.0"
|
|
441
|
+
|
|
442
|
+
[compat]
|
|
443
|
+
drop_params = []
|
|
444
|
+
|
|
445
|
+
[daemon]
|
|
446
|
+
state_dir = "~/.config/openai-api-server-via-codex/run"
|
|
447
|
+
# pid_file = "/path/to/openai-api-server-via-codex.pid"
|
|
448
|
+
# log_file = "/path/to/openai-api-server-via-codex.log"
|
|
449
|
+
stop_timeout = 10.0
|
|
450
|
+
```
|
|
451
|
+
|
|
452
|
+
### `server.host`
|
|
453
|
+
|
|
454
|
+
Default: `127.0.0.1`
|
|
455
|
+
|
|
456
|
+
```console
|
|
457
|
+
$ uvx openai-api-server-via-codex --host 0.0.0.0
|
|
458
|
+
```
|
|
459
|
+
|
|
460
|
+
### `server.default_model`
|
|
461
|
+
|
|
462
|
+
Default: `gpt-5.6-luna`
|
|
463
|
+
|
|
464
|
+
This model is used when a Responses or Chat Completions request omits `model`.
|
|
465
|
+
Set `default_model`, `OPENAI_VIA_CODEX_DEFAULT_MODEL`, or `--default-model` to
|
|
466
|
+
override it. Explicit request models are forwarded unchanged.
|
|
467
|
+
|
|
468
|
+
> [!IMPORTANT]
|
|
469
|
+
> If you bind to `0.0.0.0`, set `--api-key` or put the server behind another
|
|
470
|
+
> trusted access-control layer. Otherwise anyone who can reach the port can use
|
|
471
|
+
> your Codex credentials through this server.
|
|
472
|
+
|
|
473
|
+
### `server.port`
|
|
474
|
+
|
|
475
|
+
Default: `18080`
|
|
476
|
+
|
|
477
|
+
```console
|
|
478
|
+
$ uvx openai-api-server-via-codex --port 18080
|
|
479
|
+
```
|
|
480
|
+
|
|
481
|
+
### `server.api_key`
|
|
482
|
+
|
|
483
|
+
Default: unset
|
|
484
|
+
|
|
485
|
+
When unset, incoming `Authorization` headers are accepted and ignored.
|
|
486
|
+
|
|
487
|
+
When set, `/v1/...` routes require:
|
|
488
|
+
|
|
489
|
+
```http
|
|
490
|
+
Authorization: Bearer <api_key>
|
|
491
|
+
```
|
|
492
|
+
|
|
493
|
+
`/healthz` remains unauthenticated.
|
|
494
|
+
|
|
495
|
+
```console
|
|
496
|
+
$ uvx openai-api-server-via-codex --api-key local-secret
|
|
497
|
+
$ OPENAI_VIA_CODEX_API_KEY=local-secret uvx openai-api-server-via-codex
|
|
498
|
+
```
|
|
499
|
+
|
|
500
|
+
`start` passes the API key to the background `serve` process through the child
|
|
501
|
+
environment, not through the child command-line arguments.
|
|
502
|
+
|
|
503
|
+
### `server.max_stored_items`
|
|
504
|
+
|
|
505
|
+
Default: `1000`
|
|
506
|
+
|
|
507
|
+
This bounds the in-memory stores used for Responses context and stored Chat
|
|
508
|
+
Completions compatibility. Older entries are evicted first.
|
|
509
|
+
|
|
510
|
+
Set `0` to disable these stores. That also disables local
|
|
511
|
+
`previous_response_id` chaining and stored-object retrieval.
|
|
512
|
+
|
|
513
|
+
### `server.max_concurrent_requests`
|
|
514
|
+
|
|
515
|
+
Default: `10`
|
|
516
|
+
|
|
517
|
+
This bounds concurrent Codex backend calls. Streaming responses hold a slot
|
|
518
|
+
until the stream ends.
|
|
519
|
+
|
|
520
|
+
Set `0` to remove the local concurrency cap.
|
|
521
|
+
|
|
522
|
+
### `server.timeout`
|
|
523
|
+
|
|
524
|
+
Default: `300.0`
|
|
525
|
+
|
|
526
|
+
Timeout in seconds for Codex backend calls.
|
|
527
|
+
|
|
528
|
+
### `server.verbose`
|
|
529
|
+
|
|
530
|
+
Default: `false`
|
|
531
|
+
|
|
532
|
+
Verbose mode enables Go server debug logs and application diagnostics:
|
|
533
|
+
|
|
534
|
+
- resolved settings
|
|
535
|
+
- request start/end status and latency
|
|
536
|
+
- endpoint-level summaries
|
|
537
|
+
- model-list fallback reasons
|
|
538
|
+
- Codex HTTP stream/auth activity
|
|
539
|
+
|
|
540
|
+
Raw auth tokens are not logged. Token-like values in upstream errors or query
|
|
541
|
+
strings are redacted to a short prefix plus `******`.
|
|
542
|
+
|
|
543
|
+
```console
|
|
544
|
+
$ uvx openai-api-server-via-codex --verbose
|
|
545
|
+
$ uvx openai-api-server-via-codex status --verbose
|
|
546
|
+
$ uvx openai-api-server-via-codex stop --verbose
|
|
547
|
+
```
|
|
548
|
+
|
|
549
|
+
### `codex.auth_json`
|
|
550
|
+
|
|
551
|
+
Default: `~/.codex/auth.json`
|
|
552
|
+
|
|
553
|
+
Selects the Codex ChatGPT OAuth credentials that the server borrows when it
|
|
554
|
+
calls the Codex backend.
|
|
555
|
+
|
|
556
|
+
### `compat.drop_params`
|
|
557
|
+
|
|
558
|
+
Default: no rules
|
|
559
|
+
|
|
560
|
+
Use this setting when the Codex backend rejects otherwise valid top-level
|
|
561
|
+
OpenAI-compatible request parameters:
|
|
562
|
+
|
|
563
|
+
```toml
|
|
564
|
+
[compat]
|
|
565
|
+
drop_params = ["temperature", "top_p"]
|
|
566
|
+
```
|
|
567
|
+
|
|
568
|
+
Configured fields are silently removed from requests for every model before the
|
|
569
|
+
Responses request is sent to Codex, for both native Responses and translated
|
|
570
|
+
Chat Completions requests. Only configure parameters known to be unsupported by
|
|
571
|
+
the Codex backend.
|
|
572
|
+
|
|
573
|
+
### `daemon.state_dir`
|
|
574
|
+
|
|
575
|
+
Default:
|
|
576
|
+
|
|
577
|
+
```text
|
|
578
|
+
~/.config/openai-api-server-via-codex/run
|
|
579
|
+
```
|
|
580
|
+
|
|
581
|
+
`start`, `stop`, and `status` resolve PID and log paths from this directory by
|
|
582
|
+
default. The default PID/log stem is derived from `host` and `port`.
|
|
583
|
+
|
|
584
|
+
If `stop` or `status` is run without `--host` and the exact default PID file is
|
|
585
|
+
missing, the command looks for a single PID file matching the selected port. If
|
|
586
|
+
multiple matches exist, it refuses to guess and asks for `--host` or
|
|
587
|
+
`--pid-file`.
|
|
588
|
+
|
|
589
|
+
## Recipes
|
|
590
|
+
|
|
591
|
+
### Require an API key
|
|
592
|
+
|
|
593
|
+
```console
|
|
594
|
+
$ uvx openai-api-server-via-codex --api-key local-secret
|
|
595
|
+
```
|
|
596
|
+
|
|
597
|
+
```python
|
|
598
|
+
from openai import OpenAI
|
|
599
|
+
|
|
600
|
+
client = OpenAI()
|
|
601
|
+
```
|
|
602
|
+
|
|
603
|
+
Run the client with `OPENAI_BASE_URL=http://127.0.0.1:18080/v1` and
|
|
604
|
+
`OPENAI_API_KEY=local-secret`.
|
|
605
|
+
|
|
606
|
+
### Start on all interfaces
|
|
607
|
+
|
|
608
|
+
```console
|
|
609
|
+
$ uvx openai-api-server-via-codex start \
|
|
610
|
+
--host 0.0.0.0 \
|
|
611
|
+
--port 18080 \
|
|
612
|
+
--api-key local-secret \
|
|
613
|
+
--verbose
|
|
614
|
+
```
|
|
615
|
+
|
|
616
|
+
### Use a custom config
|
|
617
|
+
|
|
618
|
+
```console
|
|
619
|
+
$ uvx openai-api-server-via-codex config-generate --config ./config.toml
|
|
620
|
+
$ uvx openai-api-server-via-codex --config ./config.toml
|
|
621
|
+
```
|
|
622
|
+
|
|
623
|
+
### Use Chat Completions streaming
|
|
624
|
+
|
|
625
|
+
```python
|
|
626
|
+
stream = client.chat.completions.create(
|
|
627
|
+
model="gpt-5.6-luna",
|
|
628
|
+
messages=[{"role": "user", "content": "Stream a short reply."}],
|
|
629
|
+
stream=True,
|
|
630
|
+
reasoning_effort="low",
|
|
631
|
+
)
|
|
632
|
+
|
|
633
|
+
for chunk in stream:
|
|
634
|
+
if chunk.choices and chunk.choices[0].delta.content:
|
|
635
|
+
print(chunk.choices[0].delta.content, end="")
|
|
636
|
+
```
|
|
637
|
+
|
|
638
|
+
### Send image input
|
|
639
|
+
|
|
640
|
+
```python
|
|
641
|
+
response = client.responses.create(
|
|
642
|
+
model="gpt-5.6-luna",
|
|
643
|
+
input=[
|
|
644
|
+
{
|
|
645
|
+
"role": "user",
|
|
646
|
+
"content": [
|
|
647
|
+
{"type": "input_text", "text": "Describe this image."},
|
|
648
|
+
{
|
|
649
|
+
"type": "input_image",
|
|
650
|
+
"image_url": "data:image/png;base64,...",
|
|
651
|
+
},
|
|
652
|
+
],
|
|
653
|
+
}
|
|
654
|
+
],
|
|
655
|
+
)
|
|
656
|
+
```
|
|
657
|
+
|
|
658
|
+
### Use tool calling
|
|
659
|
+
|
|
660
|
+
```python
|
|
661
|
+
response = client.chat.completions.create(
|
|
662
|
+
model="gpt-5.6-luna",
|
|
663
|
+
messages=[{"role": "user", "content": "What is the weather in Tokyo?"}],
|
|
664
|
+
tools=[
|
|
665
|
+
{
|
|
666
|
+
"type": "function",
|
|
667
|
+
"function": {
|
|
668
|
+
"name": "get_weather",
|
|
669
|
+
"description": "Get weather for a city.",
|
|
670
|
+
"parameters": {
|
|
671
|
+
"type": "object",
|
|
672
|
+
"properties": {"city": {"type": "string"}},
|
|
673
|
+
"required": ["city"],
|
|
674
|
+
},
|
|
675
|
+
},
|
|
676
|
+
}
|
|
677
|
+
],
|
|
678
|
+
)
|
|
679
|
+
```
|
|
680
|
+
|
|
681
|
+
## Development
|
|
682
|
+
|
|
683
|
+
Run the full local validation suite:
|
|
684
|
+
|
|
685
|
+
```console
|
|
686
|
+
$ uv run tox
|
|
687
|
+
```
|
|
688
|
+
|
|
689
|
+
Run focused tests while changing request/response compatibility:
|
|
690
|
+
|
|
691
|
+
```console
|
|
692
|
+
$ uv run python -m pytest tests/test_openai_client_contract.py -q
|
|
693
|
+
$ go test ./internal/app
|
|
694
|
+
$ uv run ruff check .
|
|
695
|
+
$ uv run ty check
|
|
696
|
+
```
|
|
697
|
+
|
|
698
|
+
### Go runtime and client compatibility gate
|
|
699
|
+
|
|
700
|
+
The only HTTP server implementation is Go under
|
|
701
|
+
`cmd/openai-api-server-via-codex`. Build and run it directly with:
|
|
702
|
+
|
|
703
|
+
```console
|
|
704
|
+
$ go build -o ./openai-api-server-via-codex-go ./cmd/openai-api-server-via-codex
|
|
705
|
+
$ ./openai-api-server-via-codex-go serve
|
|
706
|
+
```
|
|
707
|
+
|
|
708
|
+
The process-level contract suite starts the real Go binary, puts a deterministic
|
|
709
|
+
fake Codex HTTP backend behind it, and calls every supported route through
|
|
710
|
+
`openai-python`:
|
|
711
|
+
|
|
712
|
+
```console
|
|
713
|
+
$ uv run python -m pytest tests/test_openai_client_contract.py -q
|
|
714
|
+
$ go test ./...
|
|
715
|
+
```
|
|
716
|
+
|
|
717
|
+
Go also owns deterministic HTTP/SSE contracts and a spawned-binary E2E suite.
|
|
718
|
+
These exercise auth refresh, downstream request normalization, Responses and
|
|
719
|
+
Chat lifecycle APIs, streaming, tools, structured outputs, Images, Audio,
|
|
720
|
+
fallback proxying, redaction, concurrency limits, dynamic-port startup, and
|
|
721
|
+
graceful shutdown:
|
|
722
|
+
|
|
723
|
+
```console
|
|
724
|
+
$ go test ./internal/app
|
|
725
|
+
$ go test ./test/e2e -v
|
|
726
|
+
$ go test -race ./...
|
|
727
|
+
```
|
|
728
|
+
|
|
729
|
+
New public API behavior should be added to both the Go contract suite and the
|
|
730
|
+
`openai-python` process suite. The former is the runtime's fast canonical
|
|
731
|
+
wire-level contract; the latter verifies the public SDK surface independently.
|
|
732
|
+
|
|
733
|
+
For proxy CPU, memory, latency, and throughput measurements, see
|
|
734
|
+
[the historical runtime performance report](docs/performance.md).
|
|
735
|
+
|
|
736
|
+
Run live Codex integration tests only when real network/auth testing is
|
|
737
|
+
intended:
|
|
738
|
+
|
|
739
|
+
```console
|
|
740
|
+
$ RUN_CODEX_LIVE_TESTS=1 uv run python -m pytest tests/test_live_integration.py -q
|
|
741
|
+
$ RUN_CODEX_LIVE_TESTS=1 uv run python -m pytest tests/test_live_codex_http_compatibility.py -q -s
|
|
742
|
+
$ RUN_CODEX_LIVE_TESTS=1 go test ./test/live -v -count=1 -timeout=20m
|
|
743
|
+
```
|
|
744
|
+
|
|
745
|
+
The live tests use the machine's existing Codex credentials and make real model
|
|
746
|
+
requests. The main live integration test also exercises image generation through
|
|
747
|
+
`client.images.generate(...)`: it decodes the returned base64 PNG, verifies the
|
|
748
|
+
image dimensions from the PNG header, then sends the generated image back through
|
|
749
|
+
Responses vision input and checks that the model describes the expected subject.
|
|
750
|
+
The Go-authored live matrix starts a freshly built Go binary on an OS-assigned
|
|
751
|
+
port and covers the same major API categories without a Python test runner. Set
|
|
752
|
+
`OPENAI_VIA_CODEX_TEST_MODEL` to override its default live model.
|
|
753
|
+
|
|
754
|
+
The post-removal ownership and test invariants are documented in
|
|
755
|
+
[the Go migration test policy](docs/go-migration.md).
|
|
756
|
+
|
|
757
|
+
## Release
|
|
758
|
+
|
|
759
|
+
The package is released to PyPI through GitHub Actions Trusted Publishing. Use
|
|
760
|
+
the release checklist in [docs/release.md](docs/release.md).
|
|
761
|
+
|
|
762
|
+
The recommended production path is PyPI Trusted Publishing from GitHub Actions
|
|
763
|
+
with the `pypi` environment. Local release work should build, inspect, and smoke
|
|
764
|
+
test the artifacts before the tag is pushed.
|
|
765
|
+
|
|
766
|
+
## License
|
|
767
|
+
|
|
768
|
+
Apache License 2.0. See [LICENSE](LICENSE).
|
|
769
|
+
|
|
770
|
+
## Acknowledgements
|
|
771
|
+
|
|
772
|
+
- Simon Willison's article,
|
|
773
|
+
[A pelican for GPT-5.5 via the semi-official Codex backdoor API](https://simonwillison.net/2026/Apr/23/gpt-5-5/),
|
|
774
|
+
and the implementation described there were the key references for this
|
|
775
|
+
project. Without that article, this approach likely would not have been
|
|
776
|
+
implemented here. Thank you to Simon for documenting the route clearly.
|
|
777
|
+
- [OpenClaw](https://github.com/openclaw/openclaw) was a useful reference for
|
|
778
|
+
understanding Codex backend integration patterns.
|
|
779
|
+
- [Pi Monorepo](https://github.com/badlogic/pi-mono) was a useful reference for
|
|
780
|
+
Codex backend API behavior and compatibility details.
|
|
781
|
+
|
|
782
|
+
## Author
|
|
783
|
+
|
|
784
|
+
- Yuichi Tateno ([@hotchpotch](https://github.com/hotchpotch))
|
|
785
|
+
|
|
786
|
+
<img src="https://secon.dev/images/profile_usa.png" width="64" height="64" alt="Yuichi Tateno" />
|
|
@@ -0,0 +1,10 @@
|
|
|
1
|
+
openai_api_server_via_codex/__init__.py,sha256=w-NevXtXYoCG2Zg_nTvueKkid7mtCBmk5Ul2shmgU-s,125
|
|
2
|
+
openai_api_server_via_codex/__main__.py,sha256=YCgbcXzdcyqg0_oLgtLG-AorilbdQfnpndSqKjlVyPY,66
|
|
3
|
+
openai_api_server_via_codex/bin/openai-api-server-via-codex.exe,sha256=7nPfeoLzjZrSy8lV_BXqPy2jkjOwURDTXFnmy2_35AY,6955520
|
|
4
|
+
openai_api_server_via_codex/launcher.py,sha256=x3zsvrLQZk5eU-6QF6vwdBYROiZj5Rn-1yJTzMWzjMs,1446
|
|
5
|
+
openai_api_server_via_codex-0.1.6b1.dist-info/METADATA,sha256=DB-ehQhS4uc7HfGP3h7z295he4HK9jYx5-ETR7PT5Io,25531
|
|
6
|
+
openai_api_server_via_codex-0.1.6b1.dist-info/WHEEL,sha256=1DeUf1zfVEjq92DemUyHwRuOB03CMwaTv1Na2Z4KPlI,98
|
|
7
|
+
openai_api_server_via_codex-0.1.6b1.dist-info/entry_points.txt,sha256=7YYb_IozKSD6FChjeZLP2Crk-1OlU0s6U-W7nbVqczU,90
|
|
8
|
+
openai_api_server_via_codex-0.1.6b1.dist-info/licenses/LICENSE,sha256=xx0jnfkXJvxRnG63LTGOxlggYnIysveWIZ6H3PNdCrQ,11357
|
|
9
|
+
openai_api_server_via_codex-0.1.6b1.dist-info/top_level.txt,sha256=e1x0ETxax8_NNwxBT-CluV1YQ_zA16q2qVV4dPh9Ku0,28
|
|
10
|
+
openai_api_server_via_codex-0.1.6b1.dist-info/RECORD,,
|
|
@@ -0,0 +1,201 @@
|
|
|
1
|
+
Apache License
|
|
2
|
+
Version 2.0, January 2004
|
|
3
|
+
http://www.apache.org/licenses/
|
|
4
|
+
|
|
5
|
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
|
6
|
+
|
|
7
|
+
1. Definitions.
|
|
8
|
+
|
|
9
|
+
"License" shall mean the terms and conditions for use, reproduction,
|
|
10
|
+
and distribution as defined by Sections 1 through 9 of this document.
|
|
11
|
+
|
|
12
|
+
"Licensor" shall mean the copyright owner or entity authorized by
|
|
13
|
+
the copyright owner that is granting the License.
|
|
14
|
+
|
|
15
|
+
"Legal Entity" shall mean the union of the acting entity and all
|
|
16
|
+
other entities that control, are controlled by, or are under common
|
|
17
|
+
control with that entity. For the purposes of this definition,
|
|
18
|
+
"control" means (i) the power, direct or indirect, to cause the
|
|
19
|
+
direction or management of such entity, whether by contract or
|
|
20
|
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
|
21
|
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
|
22
|
+
|
|
23
|
+
"You" (or "Your") shall mean an individual or Legal Entity
|
|
24
|
+
exercising permissions granted by this License.
|
|
25
|
+
|
|
26
|
+
"Source" form shall mean the preferred form for making modifications,
|
|
27
|
+
including but not limited to software source code, documentation
|
|
28
|
+
source, and configuration files.
|
|
29
|
+
|
|
30
|
+
"Object" form shall mean any form resulting from mechanical
|
|
31
|
+
transformation or translation of a Source form, including but
|
|
32
|
+
not limited to compiled object code, generated documentation,
|
|
33
|
+
and conversions to other media types.
|
|
34
|
+
|
|
35
|
+
"Work" shall mean the work of authorship, whether in Source or
|
|
36
|
+
Object form, made available under the License, as indicated by a
|
|
37
|
+
copyright notice that is included in or attached to the work
|
|
38
|
+
(an example is provided in the Appendix below).
|
|
39
|
+
|
|
40
|
+
"Derivative Works" shall mean any work, whether in Source or Object
|
|
41
|
+
form, that is based on (or derived from) the Work and for which the
|
|
42
|
+
editorial revisions, annotations, elaborations, or other modifications
|
|
43
|
+
represent, as a whole, an original work of authorship. For the purposes
|
|
44
|
+
of this License, Derivative Works shall not include works that remain
|
|
45
|
+
separable from, or merely link (or bind by name) to the interfaces of,
|
|
46
|
+
the Work and Derivative Works thereof.
|
|
47
|
+
|
|
48
|
+
"Contribution" shall mean any work of authorship, including
|
|
49
|
+
the original version of the Work and any modifications or additions
|
|
50
|
+
to that Work or Derivative Works thereof, that is intentionally
|
|
51
|
+
submitted to Licensor for inclusion in the Work by the copyright owner
|
|
52
|
+
or by an individual or Legal Entity authorized to submit on behalf of
|
|
53
|
+
the copyright owner. For the purposes of this definition, "submitted"
|
|
54
|
+
means any form of electronic, verbal, or written communication sent
|
|
55
|
+
to the Licensor or its representatives, including but not limited to
|
|
56
|
+
communication on electronic mailing lists, source code control systems,
|
|
57
|
+
and issue tracking systems that are managed by, or on behalf of, the
|
|
58
|
+
Licensor for the purpose of discussing and improving the Work, but
|
|
59
|
+
excluding communication that is conspicuously marked or otherwise
|
|
60
|
+
designated in writing by the copyright owner as "Not a Contribution."
|
|
61
|
+
|
|
62
|
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
|
63
|
+
on behalf of whom a Contribution has been received by Licensor and
|
|
64
|
+
subsequently incorporated within the Work.
|
|
65
|
+
|
|
66
|
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
|
67
|
+
this License, each Contributor hereby grants to You a perpetual,
|
|
68
|
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
|
69
|
+
copyright license to reproduce, prepare Derivative Works of,
|
|
70
|
+
publicly display, publicly perform, sublicense, and distribute the
|
|
71
|
+
Work and such Derivative Works in Source or Object form.
|
|
72
|
+
|
|
73
|
+
3. Grant of Patent License. Subject to the terms and conditions of
|
|
74
|
+
this License, each Contributor hereby grants to You a perpetual,
|
|
75
|
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
|
76
|
+
(except as stated in this section) patent license to make, have made,
|
|
77
|
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
|
78
|
+
where such license applies only to those patent claims licensable
|
|
79
|
+
by such Contributor that are necessarily infringed by their
|
|
80
|
+
Contribution(s) alone or by combination of their Contribution(s)
|
|
81
|
+
with the Work to which such Contribution(s) was submitted. If You
|
|
82
|
+
institute patent litigation against any entity (including a
|
|
83
|
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
|
84
|
+
or a Contribution incorporated within the Work constitutes direct
|
|
85
|
+
or contributory patent infringement, then any patent licenses
|
|
86
|
+
granted to You under this License for that Work shall terminate
|
|
87
|
+
as of the date such litigation is filed.
|
|
88
|
+
|
|
89
|
+
4. Redistribution. You may reproduce and distribute copies of the
|
|
90
|
+
Work or Derivative Works thereof in any medium, with or without
|
|
91
|
+
modifications, and in Source or Object form, provided that You
|
|
92
|
+
meet the following conditions:
|
|
93
|
+
|
|
94
|
+
(a) You must give any other recipients of the Work or
|
|
95
|
+
Derivative Works a copy of this License; and
|
|
96
|
+
|
|
97
|
+
(b) You must cause any modified files to carry prominent notices
|
|
98
|
+
stating that You changed the files; and
|
|
99
|
+
|
|
100
|
+
(c) You must retain, in the Source form of any Derivative Works
|
|
101
|
+
that You distribute, all copyright, patent, trademark, and
|
|
102
|
+
attribution notices from the Source form of the Work,
|
|
103
|
+
excluding those notices that do not pertain to any part of
|
|
104
|
+
the Derivative Works; and
|
|
105
|
+
|
|
106
|
+
(d) If the Work includes a "NOTICE" text file as part of its
|
|
107
|
+
distribution, then any Derivative Works that You distribute must
|
|
108
|
+
include a readable copy of the attribution notices contained
|
|
109
|
+
within such NOTICE file, excluding those notices that do not
|
|
110
|
+
pertain to any part of the Derivative Works, in at least one
|
|
111
|
+
of the following places: within a NOTICE text file distributed
|
|
112
|
+
as part of the Derivative Works; within the Source form or
|
|
113
|
+
documentation, if provided along with the Derivative Works; or,
|
|
114
|
+
within a display generated by the Derivative Works, if and
|
|
115
|
+
wherever such third-party notices normally appear. The contents
|
|
116
|
+
of the NOTICE file are for informational purposes only and
|
|
117
|
+
do not modify the License. You may add Your own attribution
|
|
118
|
+
notices within Derivative Works that You distribute, alongside
|
|
119
|
+
or as an addendum to the NOTICE text from the Work, provided
|
|
120
|
+
that such additional attribution notices cannot be construed
|
|
121
|
+
as modifying the License.
|
|
122
|
+
|
|
123
|
+
You may add Your own copyright statement to Your modifications and
|
|
124
|
+
may provide additional or different license terms and conditions
|
|
125
|
+
for use, reproduction, or distribution of Your modifications, or
|
|
126
|
+
for any such Derivative Works as a whole, provided Your use,
|
|
127
|
+
reproduction, and distribution of the Work otherwise complies with
|
|
128
|
+
the conditions stated in this License.
|
|
129
|
+
|
|
130
|
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
|
131
|
+
any Contribution intentionally submitted for inclusion in the Work
|
|
132
|
+
by You to the Licensor shall be under the terms and conditions of
|
|
133
|
+
this License, without any additional terms or conditions.
|
|
134
|
+
Notwithstanding the above, nothing herein shall supersede or modify
|
|
135
|
+
the terms of any separate license agreement you may have executed
|
|
136
|
+
with Licensor regarding such Contributions.
|
|
137
|
+
|
|
138
|
+
6. Trademarks. This License does not grant permission to use the trade
|
|
139
|
+
names, trademarks, service marks, or product names of the Licensor,
|
|
140
|
+
except as required for reasonable and customary use in describing the
|
|
141
|
+
origin of the Work and reproducing the content of the NOTICE file.
|
|
142
|
+
|
|
143
|
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
|
144
|
+
agreed to in writing, Licensor provides the Work (and each
|
|
145
|
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
|
146
|
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
|
147
|
+
implied, including, without limitation, any warranties or conditions
|
|
148
|
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
|
149
|
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
|
150
|
+
appropriateness of using or redistributing the Work and assume any
|
|
151
|
+
risks associated with Your exercise of permissions under this License.
|
|
152
|
+
|
|
153
|
+
8. Limitation of Liability. In no event and under no legal theory,
|
|
154
|
+
whether in tort (including negligence), contract, or otherwise,
|
|
155
|
+
unless required by applicable law (such as deliberate and grossly
|
|
156
|
+
negligent acts) or agreed to in writing, shall any Contributor be
|
|
157
|
+
liable to You for damages, including any direct, indirect, special,
|
|
158
|
+
incidental, or consequential damages of any character arising as a
|
|
159
|
+
result of this License or out of the use or inability to use the
|
|
160
|
+
Work (including but not limited to damages for loss of goodwill,
|
|
161
|
+
work stoppage, computer failure or malfunction, or any and all
|
|
162
|
+
other commercial damages or losses), even if such Contributor
|
|
163
|
+
has been advised of the possibility of such damages.
|
|
164
|
+
|
|
165
|
+
9. Accepting Warranty or Additional Liability. While redistributing
|
|
166
|
+
the Work or Derivative Works thereof, You may choose to offer,
|
|
167
|
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
|
168
|
+
or other liability obligations and/or rights consistent with this
|
|
169
|
+
License. However, in accepting such obligations, You may act only
|
|
170
|
+
on Your own behalf and on Your sole responsibility, not on behalf
|
|
171
|
+
of any other Contributor, and only if You agree to indemnify,
|
|
172
|
+
defend, and hold each Contributor harmless for any liability
|
|
173
|
+
incurred by, or claims asserted against, such Contributor by reason
|
|
174
|
+
of your accepting any such warranty or additional liability.
|
|
175
|
+
|
|
176
|
+
END OF TERMS AND CONDITIONS
|
|
177
|
+
|
|
178
|
+
APPENDIX: How to apply the Apache License to your work.
|
|
179
|
+
|
|
180
|
+
To apply the Apache License to your work, attach the following
|
|
181
|
+
boilerplate notice, with the fields enclosed by brackets "[]"
|
|
182
|
+
replaced with your own identifying information. (Don't include
|
|
183
|
+
the brackets!) The text should be enclosed in the appropriate
|
|
184
|
+
comment syntax for the file format. We also recommend that a
|
|
185
|
+
file or class name and description of purpose be included on the
|
|
186
|
+
same "printed page" as the copyright notice for easier
|
|
187
|
+
identification within third-party archives.
|
|
188
|
+
|
|
189
|
+
Copyright [yyyy] [name of copyright owner]
|
|
190
|
+
|
|
191
|
+
Licensed under the Apache License, Version 2.0 (the "License");
|
|
192
|
+
you may not use this file except in compliance with the License.
|
|
193
|
+
You may obtain a copy of the License at
|
|
194
|
+
|
|
195
|
+
http://www.apache.org/licenses/LICENSE-2.0
|
|
196
|
+
|
|
197
|
+
Unless required by applicable law or agreed to in writing, software
|
|
198
|
+
distributed under the License is distributed on an "AS IS" BASIS,
|
|
199
|
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
|
200
|
+
See the License for the specific language governing permissions and
|
|
201
|
+
limitations under the License.
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
openai_api_server_via_codex
|