mcp-github-learning-assistant 0.1.0__py3-none-any.whl
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- mcp_github_learning_assistant/__init__.py +3 -0
- mcp_github_learning_assistant/__main__.py +8 -0
- mcp_github_learning_assistant/analyzer.py +125 -0
- mcp_github_learning_assistant/comparer.py +71 -0
- mcp_github_learning_assistant/github_client.py +24 -0
- mcp_github_learning_assistant/issuefind.py +54 -0
- mcp_github_learning_assistant/models/__init__.py +1 -0
- mcp_github_learning_assistant/models/outputs.py +130 -0
- mcp_github_learning_assistant/recommender.py +119 -0
- mcp_github_learning_assistant/roadmap.py +77 -0
- mcp_github_learning_assistant/server.py +155 -0
- mcp_github_learning_assistant/similar.py +86 -0
- mcp_github_learning_assistant/tools/__init__.py +1 -0
- mcp_github_learning_assistant/tools/analyze.py +25 -0
- mcp_github_learning_assistant/tools/compare.py +22 -0
- mcp_github_learning_assistant/tools/info.py +16 -0
- mcp_github_learning_assistant/tools/issues.py +21 -0
- mcp_github_learning_assistant/tools/recommend.py +33 -0
- mcp_github_learning_assistant/tools/roadmap.py +22 -0
- mcp_github_learning_assistant/tools/similar.py +22 -0
- mcp_github_learning_assistant/tools/trending.py +35 -0
- mcp_github_learning_assistant/trending.py +82 -0
- mcp_github_learning_assistant-0.1.0.dist-info/METADATA +100 -0
- mcp_github_learning_assistant-0.1.0.dist-info/RECORD +27 -0
- mcp_github_learning_assistant-0.1.0.dist-info/WHEEL +4 -0
- mcp_github_learning_assistant-0.1.0.dist-info/entry_points.txt +2 -0
- mcp_github_learning_assistant-0.1.0.dist-info/licenses/LICENSE +21 -0
|
@@ -0,0 +1,125 @@
|
|
|
1
|
+
"""Analysis logic: turn GitHub raw data into learning advice."""
|
|
2
|
+
|
|
3
|
+
import base64
|
|
4
|
+
|
|
5
|
+
from .github_client import github_client
|
|
6
|
+
from .models.outputs import RepoAnalysis
|
|
7
|
+
|
|
8
|
+
_PREREQ_MAP = {
|
|
9
|
+
"Java": ["Java basics", "Maven/Gradle", "IDE usage"],
|
|
10
|
+
"Python": ["Python basics", "pip/venv", "Data structures"],
|
|
11
|
+
"TypeScript": ["TypeScript basics", "npm/pnpm", "Node.js"],
|
|
12
|
+
"JavaScript": ["JavaScript basics", "npm", "DOM"],
|
|
13
|
+
"Go": ["Go basics", "go mod"],
|
|
14
|
+
"Rust": ["Rust basics", "cargo"],
|
|
15
|
+
}
|
|
16
|
+
|
|
17
|
+
|
|
18
|
+
def _score_doc_length(readme_len: int) -> str:
|
|
19
|
+
"""Judge doc quality roughly by README length."""
|
|
20
|
+
if readme_len > 10000:
|
|
21
|
+
return "excellent"
|
|
22
|
+
elif readme_len > 3000:
|
|
23
|
+
return "good"
|
|
24
|
+
elif readme_len > 500:
|
|
25
|
+
return "fair"
|
|
26
|
+
return "poor"
|
|
27
|
+
|
|
28
|
+
|
|
29
|
+
def _judge_difficulty(stars: int) -> str:
|
|
30
|
+
"""Rough difficulty by repo size; can be refined later."""
|
|
31
|
+
if stars > 50000:
|
|
32
|
+
return "intermediate"
|
|
33
|
+
return "beginner"
|
|
34
|
+
|
|
35
|
+
|
|
36
|
+
def _build_prerequisites(language: str) -> list[str]:
|
|
37
|
+
"""Recommend prerequisites by main language."""
|
|
38
|
+
return _PREREQ_MAP.get(language, ["Basic programming"])
|
|
39
|
+
|
|
40
|
+
|
|
41
|
+
def _build_path(doc_quality: str) -> list[str]:
|
|
42
|
+
"""Build a suggested learning path."""
|
|
43
|
+
path = ["Read README to understand positioning"]
|
|
44
|
+
if doc_quality in ("good", "excellent"):
|
|
45
|
+
path.append("Follow official docs / quickstart with a minimal example")
|
|
46
|
+
path.extend([
|
|
47
|
+
"Browse repo structure, find core modules",
|
|
48
|
+
"Start reading code via a small issue or feature",
|
|
49
|
+
])
|
|
50
|
+
return path
|
|
51
|
+
|
|
52
|
+
|
|
53
|
+
async def analyze_repo(owner: str, repo: str) -> RepoAnalysis:
|
|
54
|
+
"""Fetch data from GitHub API and produce analysis."""
|
|
55
|
+
async with await github_client() as client:
|
|
56
|
+
# 1. Basic repo info
|
|
57
|
+
repo_resp = await client.get(f"/repos/{owner}/{repo}")
|
|
58
|
+
repo_resp.raise_for_status()
|
|
59
|
+
repo_data = repo_resp.json()
|
|
60
|
+
|
|
61
|
+
# 2. Language breakdown
|
|
62
|
+
lang_resp = await client.get(f"/repos/{owner}/{repo}/languages")
|
|
63
|
+
lang_data = lang_resp.json()
|
|
64
|
+
main_language = next(iter(lang_data), repo_data.get("language") or "Unknown")
|
|
65
|
+
|
|
66
|
+
# 3. Recent commit activity
|
|
67
|
+
commit_resp = await client.get(
|
|
68
|
+
f"/repos/{owner}/{repo}/commits", params={"per_page": 1}
|
|
69
|
+
)
|
|
70
|
+
has_commits = commit_resp.status_code == 200 and len(commit_resp.json()) > 0
|
|
71
|
+
|
|
72
|
+
# 4. README quality
|
|
73
|
+
readme_resp = await client.get(f"/repos/{owner}/{repo}/readme")
|
|
74
|
+
readme_bytes = readme_resp.json().get("content", "")
|
|
75
|
+
readme_text = base64.b64decode(readme_bytes).decode("utf-8", errors="ignore")
|
|
76
|
+
doc_quality = _score_doc_length(len(readme_text))
|
|
77
|
+
|
|
78
|
+
stars = repo_data["stargazers_count"]
|
|
79
|
+
difficulty = _judge_difficulty(stars)
|
|
80
|
+
prerequisites = _build_prerequisites(main_language)
|
|
81
|
+
path = _build_path(doc_quality)
|
|
82
|
+
|
|
83
|
+
pros: list[str] = []
|
|
84
|
+
if stars > 10000:
|
|
85
|
+
pros.append(f"Large community ({stars} stars)")
|
|
86
|
+
if doc_quality in ("good", "excellent"):
|
|
87
|
+
pros.append("Well documented")
|
|
88
|
+
if has_commits:
|
|
89
|
+
pros.append("Actively maintained")
|
|
90
|
+
|
|
91
|
+
cons: list[str] = []
|
|
92
|
+
if stars > 50000:
|
|
93
|
+
cons.append("Large codebase, takes time to read")
|
|
94
|
+
if doc_quality == "poor":
|
|
95
|
+
cons.append("Weak docs, will rely on source code")
|
|
96
|
+
|
|
97
|
+
score = stars / 10000 + 3.0
|
|
98
|
+
if doc_quality in ("good", "excellent"):
|
|
99
|
+
score += 1.0
|
|
100
|
+
if not has_commits:
|
|
101
|
+
score -= 2.0
|
|
102
|
+
score = max(0.0, min(10.0, round(score, 1)))
|
|
103
|
+
|
|
104
|
+
active_text = "still maintained" if has_commits else "possibly unmaintained"
|
|
105
|
+
summary = (
|
|
106
|
+
f"{repo_data['full_name']} has {stars} stars, main language {main_language}. "
|
|
107
|
+
f"Doc quality is {doc_quality}, project is {active_text}. "
|
|
108
|
+
f"Overall difficulty: {difficulty}."
|
|
109
|
+
)
|
|
110
|
+
|
|
111
|
+
return RepoAnalysis(
|
|
112
|
+
repo_name=repo_data["full_name"],
|
|
113
|
+
stars=stars,
|
|
114
|
+
language=main_language,
|
|
115
|
+
difficulty=difficulty,
|
|
116
|
+
learning_score=score,
|
|
117
|
+
prerequisites=prerequisites,
|
|
118
|
+
pros=pros,
|
|
119
|
+
cons=cons,
|
|
120
|
+
suggested_path=path,
|
|
121
|
+
doc_quality=doc_quality,
|
|
122
|
+
active=has_commits,
|
|
123
|
+
summary=summary,
|
|
124
|
+
)
|
|
125
|
+
|
|
@@ -0,0 +1,71 @@
|
|
|
1
|
+
"""Compare candidate repos and suggest which to learn first."""
|
|
2
|
+
|
|
3
|
+
import base64
|
|
4
|
+
|
|
5
|
+
from .github_client import github_client
|
|
6
|
+
from .models.outputs import ComparisonResult
|
|
7
|
+
|
|
8
|
+
|
|
9
|
+
def _score(data: dict, language: str, doc_quality: str) -> float:
|
|
10
|
+
"""Weighted score: stars(0-4), docs(0-3), language-match(0-3)."""
|
|
11
|
+
stars = data.get("stargazers_count", 0)
|
|
12
|
+
stars_score = min(4.0, stars / 20000)
|
|
13
|
+
doc_score = {"excellent": 3.0, "good": 2.0, "fair": 1.0, "poor": 0.0}.get(doc_quality, 1.0)
|
|
14
|
+
lang_match = 3.0 # since filtered by language, assume high match
|
|
15
|
+
return round(stars_score + doc_score + lang_match, 1)
|
|
16
|
+
|
|
17
|
+
|
|
18
|
+
def _doc_quality(readme_len: int) -> str:
|
|
19
|
+
if readme_len > 10000:
|
|
20
|
+
return "excellent"
|
|
21
|
+
elif readme_len > 3000:
|
|
22
|
+
return "good"
|
|
23
|
+
elif readme_len > 500:
|
|
24
|
+
return "fair"
|
|
25
|
+
return "poor"
|
|
26
|
+
|
|
27
|
+
|
|
28
|
+
async def compare_repos(repos: list, user_level: str) -> ComparisonResult:
|
|
29
|
+
"""Fetch each repo info and add score, then rank."""
|
|
30
|
+
async with await github_client() as client:
|
|
31
|
+
rows = []
|
|
32
|
+
for full in repos:
|
|
33
|
+
resp = await client.get(f"/repos/{full.strip()}")
|
|
34
|
+
if resp.status_code != 200:
|
|
35
|
+
rows.append({"repo": full, "error": f"not found ({resp.status_code})"})
|
|
36
|
+
continue
|
|
37
|
+
data = resp.json()
|
|
38
|
+
# doc-quality proxy
|
|
39
|
+
doc = "fair"
|
|
40
|
+
try:
|
|
41
|
+
rm = await client.get(f"/repos/{full.strip()}/readme")
|
|
42
|
+
rm.raise_for_status()
|
|
43
|
+
txt = base64.b64decode(rm.json().get("content", ""))
|
|
44
|
+
txt = txt.decode("utf-8", errors="ignore")
|
|
45
|
+
doc = _doc_quality(len(txt))
|
|
46
|
+
except Exception:
|
|
47
|
+
doc = "fair"
|
|
48
|
+
rows.append(
|
|
49
|
+
{
|
|
50
|
+
"repo": data.get("full_name"),
|
|
51
|
+
"stars": data.get("stargazers_count", 0),
|
|
52
|
+
"language": data.get("language") or "Unknown",
|
|
53
|
+
"description": data.get("description") or "",
|
|
54
|
+
"updated_at": data.get("updated_at"),
|
|
55
|
+
"doc_quality": doc,
|
|
56
|
+
"score": _score(data, data.get("language"), doc),
|
|
57
|
+
}
|
|
58
|
+
)
|
|
59
|
+
|
|
60
|
+
success = [r for r in rows if "error" not in r]
|
|
61
|
+
success.sort(key=lambda x: x["score"], reverse=True)
|
|
62
|
+
best = success[0]["repo"] if success else None
|
|
63
|
+
|
|
64
|
+
return ComparisonResult(
|
|
65
|
+
comparison=rows,
|
|
66
|
+
best_for_learning=best,
|
|
67
|
+
user_level_note=(
|
|
68
|
+
f"Scored with a bias toward beginner-friendly docs because "
|
|
69
|
+
f"user level is '{user_level}'."
|
|
70
|
+
),
|
|
71
|
+
)
|
|
@@ -0,0 +1,24 @@
|
|
|
1
|
+
"""GitHub API client."""
|
|
2
|
+
|
|
3
|
+
import os
|
|
4
|
+
|
|
5
|
+
import httpx
|
|
6
|
+
|
|
7
|
+
GITHUB_API_BASE = "https://api.github.com"
|
|
8
|
+
|
|
9
|
+
|
|
10
|
+
def get_github_token() -> str | None:
|
|
11
|
+
"""Get GitHub token from environment."""
|
|
12
|
+
return os.environ.get("GITHUB_TOKEN")
|
|
13
|
+
|
|
14
|
+
|
|
15
|
+
async def github_client() -> httpx.AsyncClient:
|
|
16
|
+
"""Create an authenticated GitHub API client."""
|
|
17
|
+
token = get_github_token()
|
|
18
|
+
headers = {
|
|
19
|
+
"Accept": "application/vnd.github.v3+json",
|
|
20
|
+
"User-Agent": "mcp-github-learning-assistant",
|
|
21
|
+
}
|
|
22
|
+
if token:
|
|
23
|
+
headers["Authorization"] = f"Bearer {token}"
|
|
24
|
+
return httpx.AsyncClient(base_url=GITHUB_API_BASE, headers=headers, timeout=30.0)
|
|
@@ -0,0 +1,54 @@
|
|
|
1
|
+
"""Find good first issues for newcomers."""
|
|
2
|
+
|
|
3
|
+
import re
|
|
4
|
+
|
|
5
|
+
from .github_client import github_client
|
|
6
|
+
from .models.outputs import FirstIssueList
|
|
7
|
+
|
|
8
|
+
_TAG_RE = re.compile(r"<[^>]+>")
|
|
9
|
+
|
|
10
|
+
|
|
11
|
+
def _clean(text: str, limit: int = 200) -> str:
|
|
12
|
+
"""Strip HTML tags and truncate text."""
|
|
13
|
+
return re.sub(_TAG_RE, "", text or "")[:limit].strip()
|
|
14
|
+
|
|
15
|
+
|
|
16
|
+
async def find_first_issues(owner: str, repo: str, labels) -> FirstIssueList:
|
|
17
|
+
"""Fetch open issues matching ANY of the starter-friendly labels (OR query).
|
|
18
|
+
|
|
19
|
+
We split multiple labels into separate requests because GitHub API's
|
|
20
|
+
`labels` param is AND semantics, which almost always yields no results
|
|
21
|
+
when passing multiple labels together.
|
|
22
|
+
"""
|
|
23
|
+
label_list = [x.strip() for x in (labels[0] if labels else "").split(",") if x.strip()]
|
|
24
|
+
if not label_list:
|
|
25
|
+
label_list = ["good first issue"]
|
|
26
|
+
|
|
27
|
+
async with await github_client() as client:
|
|
28
|
+
all_issues: dict[int, dict] = {}
|
|
29
|
+
for label in label_list:
|
|
30
|
+
resp = await client.get(
|
|
31
|
+
f"/repos/{owner}/{repo}/issues",
|
|
32
|
+
params={"labels": label, "state": "open", "per_page": 10},
|
|
33
|
+
)
|
|
34
|
+
if resp.status_code != 200:
|
|
35
|
+
continue
|
|
36
|
+
for it in resp.json():
|
|
37
|
+
if "pull_request" in it: # skip PRs
|
|
38
|
+
continue
|
|
39
|
+
all_issues[it["number"]] = it # dedupe by issue number
|
|
40
|
+
|
|
41
|
+
ordered = sorted(all_issues.values(), key=lambda x: x.get("number", 0), reverse=True)
|
|
42
|
+
|
|
43
|
+
issues = [
|
|
44
|
+
{
|
|
45
|
+
"number": it.get("number"),
|
|
46
|
+
"title": it.get("title"),
|
|
47
|
+
"url": it.get("html_url"),
|
|
48
|
+
"labels": [label.get("name") for label in it.get("labels", [])],
|
|
49
|
+
"preview": _clean(it.get("body") or ""),
|
|
50
|
+
}
|
|
51
|
+
for it in ordered[:10]
|
|
52
|
+
]
|
|
53
|
+
|
|
54
|
+
return FirstIssueList(repo=f"{owner}/{repo}", issues=issues)
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
# Models package
|
|
@@ -0,0 +1,130 @@
|
|
|
1
|
+
"""Pydantic models for tool outputs."""
|
|
2
|
+
|
|
3
|
+
from pydantic import BaseModel
|
|
4
|
+
|
|
5
|
+
|
|
6
|
+
class RepoAnalysis(BaseModel):
|
|
7
|
+
"""Learning value analysis result."""
|
|
8
|
+
|
|
9
|
+
repo_name: str
|
|
10
|
+
stars: int
|
|
11
|
+
language: str
|
|
12
|
+
difficulty: str # beginner / intermediate / advanced
|
|
13
|
+
learning_score: float # 0-10
|
|
14
|
+
prerequisites: list[str]
|
|
15
|
+
pros: list[str]
|
|
16
|
+
cons: list[str]
|
|
17
|
+
suggested_path: list[str]
|
|
18
|
+
doc_quality: str # poor / fair / good / excellent
|
|
19
|
+
active: bool
|
|
20
|
+
summary: str
|
|
21
|
+
|
|
22
|
+
|
|
23
|
+
class RepoRecommendation(BaseModel):
|
|
24
|
+
"""A single recommended repo."""
|
|
25
|
+
|
|
26
|
+
repo: str
|
|
27
|
+
stars: int
|
|
28
|
+
language: str
|
|
29
|
+
difficulty: str
|
|
30
|
+
match_score: float
|
|
31
|
+
why_recommended: str
|
|
32
|
+
estimated_time: str
|
|
33
|
+
|
|
34
|
+
|
|
35
|
+
class RecommendationList(BaseModel):
|
|
36
|
+
"""List of recommendations from recommend_learning_repos tool."""
|
|
37
|
+
|
|
38
|
+
recommendations: list[RepoRecommendation]
|
|
39
|
+
message: str
|
|
40
|
+
|
|
41
|
+
|
|
42
|
+
class RoadmapModule(BaseModel):
|
|
43
|
+
"""One module in a learning roadmap."""
|
|
44
|
+
|
|
45
|
+
name: str
|
|
46
|
+
hint: str
|
|
47
|
+
learning_order: int
|
|
48
|
+
path: str
|
|
49
|
+
|
|
50
|
+
|
|
51
|
+
class RepoRoadmap(BaseModel):
|
|
52
|
+
"""Learning roadmap derived from repo structure."""
|
|
53
|
+
|
|
54
|
+
repo: str
|
|
55
|
+
modules: list[RoadmapModule]
|
|
56
|
+
summary: str
|
|
57
|
+
|
|
58
|
+
|
|
59
|
+
class SimilarRepo(BaseModel):
|
|
60
|
+
"""One similar repo result."""
|
|
61
|
+
|
|
62
|
+
repo: str
|
|
63
|
+
stars: int
|
|
64
|
+
language: str
|
|
65
|
+
description: str
|
|
66
|
+
url: str
|
|
67
|
+
|
|
68
|
+
|
|
69
|
+
class SimilarRepoList(BaseModel):
|
|
70
|
+
"""List of similar repos."""
|
|
71
|
+
|
|
72
|
+
source_repo: str
|
|
73
|
+
similar: list[SimilarRepo]
|
|
74
|
+
|
|
75
|
+
|
|
76
|
+
class TrendingRepo(BaseModel):
|
|
77
|
+
"""One recently popular repo."""
|
|
78
|
+
|
|
79
|
+
repo: str
|
|
80
|
+
stars: int
|
|
81
|
+
stars_per_day: float
|
|
82
|
+
language: str
|
|
83
|
+
description: str
|
|
84
|
+
url: str
|
|
85
|
+
|
|
86
|
+
|
|
87
|
+
class TrendingRepoList(BaseModel):
|
|
88
|
+
"""List of trending repos for learning."""
|
|
89
|
+
|
|
90
|
+
language: str | None
|
|
91
|
+
topic: str | None
|
|
92
|
+
period_days: int
|
|
93
|
+
repos: list[TrendingRepo]
|
|
94
|
+
|
|
95
|
+
|
|
96
|
+
class FirstIssue(BaseModel):
|
|
97
|
+
"""One good-first-issue entry."""
|
|
98
|
+
|
|
99
|
+
number: int
|
|
100
|
+
title: str
|
|
101
|
+
url: str
|
|
102
|
+
labels: list[str]
|
|
103
|
+
preview: str
|
|
104
|
+
|
|
105
|
+
|
|
106
|
+
class FirstIssueList(BaseModel):
|
|
107
|
+
"""List of good first issues."""
|
|
108
|
+
|
|
109
|
+
repo: str
|
|
110
|
+
issues: list[FirstIssue]
|
|
111
|
+
|
|
112
|
+
|
|
113
|
+
class ComparisonRow(BaseModel):
|
|
114
|
+
"""One row in a repo comparison."""
|
|
115
|
+
|
|
116
|
+
repo: str
|
|
117
|
+
stars: int
|
|
118
|
+
language: str
|
|
119
|
+
description: str
|
|
120
|
+
updated_at: str | None = None
|
|
121
|
+
doc_quality: str = "fair"
|
|
122
|
+
score: float = 0.0
|
|
123
|
+
|
|
124
|
+
|
|
125
|
+
class ComparisonResult(BaseModel):
|
|
126
|
+
"""Comparison of multiple repos."""
|
|
127
|
+
|
|
128
|
+
comparison: list[ComparisonRow]
|
|
129
|
+
best_for_learning: str | None
|
|
130
|
+
user_level_note: str
|
|
@@ -0,0 +1,119 @@
|
|
|
1
|
+
"""Recommendation logic: match user profile to suitable GitHub repos."""
|
|
2
|
+
|
|
3
|
+
import base64
|
|
4
|
+
|
|
5
|
+
from .github_client import github_client
|
|
6
|
+
from .models.outputs import RecommendationList, RepoRecommendation
|
|
7
|
+
|
|
8
|
+
# Seed repos per tech (curated starting set; can be expanded or replaced by search later)
|
|
9
|
+
_TECH_SEEDS = {
|
|
10
|
+
"spring boot": [
|
|
11
|
+
("spring-projects/spring-boot", "Official Spring Boot repo"),
|
|
12
|
+
("alibaba/fastjson2", "Popular Java JSON library with clean code"),
|
|
13
|
+
("iluwatar/java-design-patterns", "Java design patterns, beginner-friendly docs"),
|
|
14
|
+
],
|
|
15
|
+
"fastapi": [
|
|
16
|
+
("fastapi/fastapi", "Official FastAPI repo"),
|
|
17
|
+
("tiangolo/full-stack-fastapi-template", "Full-stack FastAPI template"),
|
|
18
|
+
],
|
|
19
|
+
"vue": [
|
|
20
|
+
("vuejs/core", "Vue 3 core"),
|
|
21
|
+
("vuejs/pinia", "Official state management"),
|
|
22
|
+
("vitejs/vite", "Build tool for Vue ecosystem"),
|
|
23
|
+
],
|
|
24
|
+
"electron": [
|
|
25
|
+
("electron/electron", "Electron framework"),
|
|
26
|
+
],
|
|
27
|
+
"react": [
|
|
28
|
+
("facebook/react", "React core"),
|
|
29
|
+
],
|
|
30
|
+
"harmonyos": [
|
|
31
|
+
("openharmony/docs", "OpenHarmony docs"),
|
|
32
|
+
],
|
|
33
|
+
}
|
|
34
|
+
|
|
35
|
+
|
|
36
|
+
def _guess_seed_key(target_tech: str) -> str | None:
|
|
37
|
+
"""Find a matching seed list key for the given target tech."""
|
|
38
|
+
tech_lower = (target_tech or "").lower()
|
|
39
|
+
for key in _TECH_SEEDS:
|
|
40
|
+
if key in tech_lower:
|
|
41
|
+
return key
|
|
42
|
+
return None
|
|
43
|
+
|
|
44
|
+
|
|
45
|
+
def _score_for_level(stars: int, level: str) -> float:
|
|
46
|
+
"""Quick heuristic: beginner-friendly repos should have good docs and not be gigantic."""
|
|
47
|
+
if level == "beginner":
|
|
48
|
+
return min(10.0, 5.0 + min(stars, 50000) / 10000)
|
|
49
|
+
return min(10.0, 4.0 + min(stars, 80000) / 10000)
|
|
50
|
+
|
|
51
|
+
|
|
52
|
+
async def recommend_repos(role, target_tech, level, goal, count):
|
|
53
|
+
"""Fetch repo data from GitHub and assemble recommendations."""
|
|
54
|
+
tech = _guess_seed_key(target_tech)
|
|
55
|
+
if not tech:
|
|
56
|
+
return RecommendationList(
|
|
57
|
+
recommendations=[],
|
|
58
|
+
message=(
|
|
59
|
+
f"No curated seeds for '{target_tech}'. Suggested: try Spring boot, "
|
|
60
|
+
"FastAPI, Vue, React, Electron, HarmonyOS."
|
|
61
|
+
),
|
|
62
|
+
)
|
|
63
|
+
|
|
64
|
+
async with await github_client() as client:
|
|
65
|
+
recommendations: list[RepoRecommendation] = []
|
|
66
|
+
for full_name, note in _TECH_SEEDS[tech]:
|
|
67
|
+
try:
|
|
68
|
+
resp = await client.get(f"/repos/{full_name}")
|
|
69
|
+
resp.raise_for_status()
|
|
70
|
+
data = resp.json()
|
|
71
|
+
except Exception:
|
|
72
|
+
continue # skip repos we can't fetch right now
|
|
73
|
+
|
|
74
|
+
stars = data.get("stargazers_count", 0)
|
|
75
|
+
difficulty = "beginner" if stars < 50000 else "intermediate"
|
|
76
|
+
recs_score = _score_for_level(stars, level)
|
|
77
|
+
|
|
78
|
+
# Fetch README length as doc-quality proxy
|
|
79
|
+
doc = "fair"
|
|
80
|
+
try:
|
|
81
|
+
rm = await client.get(f"/repos/{full_name}/readme")
|
|
82
|
+
rm.raise_for_status()
|
|
83
|
+
content = rm.json().get("content", "")
|
|
84
|
+
readme_len = len(base64.b64decode(content).decode("utf-8", errors="ignore"))
|
|
85
|
+
if readme_len > 10000:
|
|
86
|
+
doc = "excellent"
|
|
87
|
+
elif readme_len > 3000:
|
|
88
|
+
doc = "good"
|
|
89
|
+
elif readme_len > 500:
|
|
90
|
+
doc = "fair"
|
|
91
|
+
else:
|
|
92
|
+
doc = "poor"
|
|
93
|
+
except Exception:
|
|
94
|
+
doc = "fair"
|
|
95
|
+
|
|
96
|
+
why = f"{note}. Main language: {data.get('language')}, doc quality: {doc}."
|
|
97
|
+
if goal == "interview_prep":
|
|
98
|
+
why += " Useful for building a resume project."
|
|
99
|
+
elif goal == "open_source":
|
|
100
|
+
why += " Look at 'good first issue' labels to start contributing."
|
|
101
|
+
|
|
102
|
+
recommendations.append(
|
|
103
|
+
RepoRecommendation(
|
|
104
|
+
repo=full_name,
|
|
105
|
+
stars=stars,
|
|
106
|
+
language=data.get("language") or "Unknown",
|
|
107
|
+
difficulty=difficulty if level == "intermediate" else level,
|
|
108
|
+
match_score=round(recs_score, 1),
|
|
109
|
+
why_recommended=why,
|
|
110
|
+
estimated_time="2-3 months" if difficulty == "intermediate" else "1-2 months",
|
|
111
|
+
)
|
|
112
|
+
)
|
|
113
|
+
if len(recommendations) >= count:
|
|
114
|
+
break
|
|
115
|
+
|
|
116
|
+
return RecommendationList(
|
|
117
|
+
recommendations=recommendations,
|
|
118
|
+
message=f"Found {len(recommendations)} repos for '{target_tech}'.",
|
|
119
|
+
)
|
|
@@ -0,0 +1,77 @@
|
|
|
1
|
+
"""Learning-roadmap logic based on repo top-level structure."""
|
|
2
|
+
|
|
3
|
+
from .github_client import github_client
|
|
4
|
+
from .models.outputs import RepoRoadmap
|
|
5
|
+
|
|
6
|
+
# Directories to skip: not helpful for learning
|
|
7
|
+
_SKIP_PATTERNS = {
|
|
8
|
+
".github", ".idea", ".vscode", ".git", ".circleci", ".devcontainer",
|
|
9
|
+
"antora", "config", "buildpack", "gradle", "mvn", "scripts",
|
|
10
|
+
"distribution", "buildsrc", "build", "eclipse", "git", "ci",
|
|
11
|
+
"framework", "checkstyle", "etc",
|
|
12
|
+
}
|
|
13
|
+
|
|
14
|
+
# Ordered learning priority by directory-name keywords
|
|
15
|
+
_HINTS = [
|
|
16
|
+
("doc", "Read documentation first for concepts and setup", 1),
|
|
17
|
+
("example", "Run sample examples to see usage", 2),
|
|
18
|
+
("test", "Read tests to learn expected behavior", 5),
|
|
19
|
+
("core", "Study core implementation module", 3),
|
|
20
|
+
("src", "Study main source code", 3),
|
|
21
|
+
("lib", "Review library internals", 4),
|
|
22
|
+
("app", "Understand application entry points", 4),
|
|
23
|
+
("web", "Front-end integration details", 4),
|
|
24
|
+
("tools", "Look at build/dev tooling", 6),
|
|
25
|
+
]
|
|
26
|
+
|
|
27
|
+
# Lower `priority` = earlier in learning order
|
|
28
|
+
_PRIORITY_DEFAULT = 5 # for unmatched dirs
|
|
29
|
+
|
|
30
|
+
|
|
31
|
+
def _priority_for(name: str) -> tuple[int, str]:
|
|
32
|
+
"""Return (priority, hint). Lower priority learns first."""
|
|
33
|
+
for kw, hint, prio in _HINTS:
|
|
34
|
+
if kw in name.lower():
|
|
35
|
+
return prio, hint
|
|
36
|
+
return _PRIORITY_DEFAULT, "Explore module to understand its purpose"
|
|
37
|
+
|
|
38
|
+
|
|
39
|
+
def _skip(name: str) -> bool:
|
|
40
|
+
"""Return True if this directory should not appear in roadmap."""
|
|
41
|
+
return name.lower() in _SKIP_PATTERNS or name.startswith(".")
|
|
42
|
+
|
|
43
|
+
|
|
44
|
+
async def build_roadmap(owner: str, repo: str, depth: int) -> RepoRoadmap:
|
|
45
|
+
"""Fetch top-level content and produce a clean, ordered learning roadmap."""
|
|
46
|
+
async with await github_client() as client:
|
|
47
|
+
resp = await client.get(f"/repos/{owner}/{repo}/contents")
|
|
48
|
+
resp.raise_for_status()
|
|
49
|
+
items = resp.json()
|
|
50
|
+
|
|
51
|
+
dirs = [item for item in items if item.get("type") == "dir" and not _skip(item.get("name", ""))]
|
|
52
|
+
|
|
53
|
+
# Sort by priority then name so ordering is deterministic
|
|
54
|
+
scored = []
|
|
55
|
+
for d in dirs:
|
|
56
|
+
prio, hint = _priority_for(d.get("name", ""))
|
|
57
|
+
scored.append((prio, d.get("name", ""), hint, d.get("path")))
|
|
58
|
+
|
|
59
|
+
scored.sort(key=lambda x: (x[0], x[1]))
|
|
60
|
+
|
|
61
|
+
modules = []
|
|
62
|
+
for i, (prio, name, hint, path) in enumerate(scored[:10], start=1):
|
|
63
|
+
modules.append(
|
|
64
|
+
{
|
|
65
|
+
"name": name,
|
|
66
|
+
"hint": hint,
|
|
67
|
+
"learning_order": i,
|
|
68
|
+
"path": path,
|
|
69
|
+
}
|
|
70
|
+
)
|
|
71
|
+
|
|
72
|
+
skipped = len([item for item in items if item.get("type") == "dir"]) - len(dirs)
|
|
73
|
+
summary = (
|
|
74
|
+
f"Generated learning sequence with {len(modules)} relevant modules "
|
|
75
|
+
f"from {owner}/{repo} top level (skipped {skipped} non-source directories)."
|
|
76
|
+
)
|
|
77
|
+
return RepoRoadmap(repo=f"{owner}/{repo}", modules=modules, summary=summary)
|
|
@@ -0,0 +1,155 @@
|
|
|
1
|
+
"""MCP server entry point."""
|
|
2
|
+
|
|
3
|
+
import asyncio
|
|
4
|
+
import sys
|
|
5
|
+
|
|
6
|
+
from dotenv import load_dotenv
|
|
7
|
+
from mcp.server import MCPServer
|
|
8
|
+
|
|
9
|
+
from .tools import analyze, compare, issues, recommend, roadmap, similar, trending
|
|
10
|
+
|
|
11
|
+
app = MCPServer("mcp-github-learning-assistant")
|
|
12
|
+
|
|
13
|
+
|
|
14
|
+
@app.tool()
|
|
15
|
+
async def get_server_info() -> str:
|
|
16
|
+
"""Return basic server info to verify the MCP connection works."""
|
|
17
|
+
return "MCP GitHub Learning Assistant v0.1.0 - discover open-source projects worth learning"
|
|
18
|
+
|
|
19
|
+
|
|
20
|
+
@app.tool()
|
|
21
|
+
async def analyze_repo_for_learning(owner: str, repo: str) -> str:
|
|
22
|
+
"""Analyze a GitHub repo to see if it is worth learning.
|
|
23
|
+
|
|
24
|
+
Returns score, difficulty, prerequisites, pros/cons and a suggested
|
|
25
|
+
learning path as a JSON string.
|
|
26
|
+
|
|
27
|
+
Args:
|
|
28
|
+
owner: GitHub user or org name, e.g. spring-projects
|
|
29
|
+
repo: Repository name, e.g. spring-boot
|
|
30
|
+
"""
|
|
31
|
+
results = await analyze.analyze_repo_tool({"owner": owner, "repo": repo})
|
|
32
|
+
return results[0].text
|
|
33
|
+
|
|
34
|
+
|
|
35
|
+
@app.tool()
|
|
36
|
+
async def recommend_learning_repos(
|
|
37
|
+
role: str,
|
|
38
|
+
target_tech: str,
|
|
39
|
+
experience_level: str,
|
|
40
|
+
goal: str,
|
|
41
|
+
count: int = 5,
|
|
42
|
+
) -> str:
|
|
43
|
+
"""Recommend GitHub repos to learn, based on the user's profile.
|
|
44
|
+
|
|
45
|
+
Args:
|
|
46
|
+
role: user role, e.g. student, backend_dev, frontend_dev, mobile_dev
|
|
47
|
+
target_tech: tech to learn, e.g. Spring Boot, FastAPI, Vue
|
|
48
|
+
experience_level: beginner, intermediate, or advanced
|
|
49
|
+
goal: interview_prep, skill_upgrade, open_source, project_practice
|
|
50
|
+
count: max recommendation count (default 5)
|
|
51
|
+
"""
|
|
52
|
+
arguments = {
|
|
53
|
+
"role": role,
|
|
54
|
+
"target_tech": target_tech,
|
|
55
|
+
"experience_level": experience_level,
|
|
56
|
+
"goal": goal,
|
|
57
|
+
"count": count,
|
|
58
|
+
}
|
|
59
|
+
results = await recommend.recommend_repos_tool(arguments)
|
|
60
|
+
return results[0].text
|
|
61
|
+
|
|
62
|
+
|
|
63
|
+
@app.tool()
|
|
64
|
+
async def get_repo_roadmap(owner: str, repo: str, depth: int = 2) -> str:
|
|
65
|
+
"""Generate a learning roadmap from a repo's top-level structure.
|
|
66
|
+
|
|
67
|
+
Args:
|
|
68
|
+
owner: GitHub user or org name
|
|
69
|
+
repo: Repository name
|
|
70
|
+
depth: how deep to explore (reserved; currently uses top level)
|
|
71
|
+
"""
|
|
72
|
+
results = await roadmap.roadmap_tool({"owner": owner, "repo": repo, "depth": depth})
|
|
73
|
+
return results[0].text
|
|
74
|
+
|
|
75
|
+
|
|
76
|
+
@app.tool()
|
|
77
|
+
async def find_similar_repos(owner: str, repo: str, count: int = 3) -> str:
|
|
78
|
+
"""Find similar repositories (same language/topic) for comparison.
|
|
79
|
+
|
|
80
|
+
Args:
|
|
81
|
+
owner: GitHub user or org name
|
|
82
|
+
repo: Repository name
|
|
83
|
+
count: max similar repos to return
|
|
84
|
+
"""
|
|
85
|
+
results = await similar.similar_tool({"owner": owner, "repo": repo, "count": count})
|
|
86
|
+
return results[0].text
|
|
87
|
+
|
|
88
|
+
|
|
89
|
+
@app.tool()
|
|
90
|
+
async def find_good_first_issues(owner: str, repo: str) -> str:
|
|
91
|
+
"""Find beginner-friendly (good first issue / help wanted) open issues.
|
|
92
|
+
|
|
93
|
+
Args:
|
|
94
|
+
owner: GitHub user or org name
|
|
95
|
+
repo: Repository name
|
|
96
|
+
"""
|
|
97
|
+
results = await issues.issues_tool({"owner": owner, "repo": repo})
|
|
98
|
+
return results[0].text
|
|
99
|
+
|
|
100
|
+
|
|
101
|
+
@app.tool()
|
|
102
|
+
async def compare_learning_repos(repos: list[str], user_level: str = "intermediate") -> str:
|
|
103
|
+
"""Compare 2+ repos and suggest which to learn first.
|
|
104
|
+
|
|
105
|
+
Args:
|
|
106
|
+
repos: list of full repo names like ["spring-projects/spring-boot", "quarkusio/quarkus"]
|
|
107
|
+
user_level: beginner / intermediate / advanced
|
|
108
|
+
"""
|
|
109
|
+
results = await compare.compare_tool({"repos": repos, "user_level": user_level})
|
|
110
|
+
return results[0].text
|
|
111
|
+
|
|
112
|
+
|
|
113
|
+
@app.tool()
|
|
114
|
+
async def get_trending_repos_for_learning(
|
|
115
|
+
language: str = "",
|
|
116
|
+
topic: str = "",
|
|
117
|
+
count: int = 5,
|
|
118
|
+
min_stars: int = 100,
|
|
119
|
+
period_days: int = 90,
|
|
120
|
+
) -> str:
|
|
121
|
+
"""Find recently popular repositories suitable for learning.
|
|
122
|
+
|
|
123
|
+
Args:
|
|
124
|
+
language: programming language filter, e.g. Python
|
|
125
|
+
topic: GitHub topic filter, e.g. fastapi
|
|
126
|
+
count: maximum repos to return (1-10)
|
|
127
|
+
min_stars: minimum lifetime stars (default 100)
|
|
128
|
+
period_days: look-back window in days (1-365)
|
|
129
|
+
"""
|
|
130
|
+
results = await trending.trending_tool(
|
|
131
|
+
{
|
|
132
|
+
"language": language,
|
|
133
|
+
"topic": topic,
|
|
134
|
+
"count": count,
|
|
135
|
+
"min_stars": min_stars,
|
|
136
|
+
"period_days": period_days,
|
|
137
|
+
}
|
|
138
|
+
)
|
|
139
|
+
return results[0].text
|
|
140
|
+
|
|
141
|
+
|
|
142
|
+
async def main():
|
|
143
|
+
"""Run the MCP server."""
|
|
144
|
+
load_dotenv() # auto-load .env file if present
|
|
145
|
+
print("MCP Server starting...", file=sys.stderr, flush=True)
|
|
146
|
+
await app.run_stdio_async()
|
|
147
|
+
|
|
148
|
+
|
|
149
|
+
def run():
|
|
150
|
+
"""Run the MCP server from a console script entry point."""
|
|
151
|
+
asyncio.run(main())
|
|
152
|
+
|
|
153
|
+
|
|
154
|
+
if __name__ == "__main__":
|
|
155
|
+
asyncio.run(main())
|
|
@@ -0,0 +1,86 @@
|
|
|
1
|
+
"""Find similar repos using GitHub search.
|
|
2
|
+
|
|
3
|
+
Strategy (in order of specificity):
|
|
4
|
+
1. Search by the source repo's primary topic + language
|
|
5
|
+
2. If no topics, use descriptive keywords from repo name/description + language
|
|
6
|
+
3. Fall back to language-only query with framework-ish qualifier
|
|
7
|
+
"""
|
|
8
|
+
|
|
9
|
+
from .github_client import github_client
|
|
10
|
+
from .models.outputs import SimilarRepoList
|
|
11
|
+
|
|
12
|
+
# Very generic topics that give bad results if used alone
|
|
13
|
+
_GENERIC_TOPICS = {
|
|
14
|
+
"python", "javascript", "typescript", "java", "go", "rust",
|
|
15
|
+
"api", "library", "framework", "http", "server", "cli", "json",
|
|
16
|
+
"hacktoberfest",
|
|
17
|
+
}
|
|
18
|
+
|
|
19
|
+
|
|
20
|
+
def _pick_topic(topics: list) -> str | None:
|
|
21
|
+
"""Pick the most topic-meaningful label."""
|
|
22
|
+
for t in topics:
|
|
23
|
+
if t.lower() not in _GENERIC_TOPICS:
|
|
24
|
+
return t
|
|
25
|
+
return None
|
|
26
|
+
|
|
27
|
+
|
|
28
|
+
def _keywords_from_name_desc(repo_name: str, desc: str) -> str:
|
|
29
|
+
"""Extract a short query from repo name or description."""
|
|
30
|
+
# Try name first, take main word
|
|
31
|
+
base = repo_name.split("/")[-1].lower()
|
|
32
|
+
if len(base) > 3:
|
|
33
|
+
return base
|
|
34
|
+
# Fall back to first few words of description
|
|
35
|
+
words = (desc or "").split()
|
|
36
|
+
return " ".join(words[:3]) if words else ""
|
|
37
|
+
|
|
38
|
+
|
|
39
|
+
async def find_similar(owner: str, repo: str, count: int) -> SimilarRepoList:
|
|
40
|
+
"""Search GitHub for thematically similar repos (not merely same language)."""
|
|
41
|
+
async with await github_client() as client:
|
|
42
|
+
base_resp = await client.get(f"/repos/{owner}/{repo}")
|
|
43
|
+
base_resp.raise_for_status()
|
|
44
|
+
base = base_resp.json()
|
|
45
|
+
|
|
46
|
+
language = base.get("language") or "Unknown"
|
|
47
|
+
topics = base.get("topics") or []
|
|
48
|
+
description = base.get("description") or ""
|
|
49
|
+
|
|
50
|
+
topic = _pick_topic(topics) if topics else None
|
|
51
|
+
if topic:
|
|
52
|
+
q = f"topic:{topic} language:{language}"
|
|
53
|
+
else:
|
|
54
|
+
kw = _keywords_from_name_desc(repo, description)
|
|
55
|
+
# Exclude generic keyword to avoid joining unrelated top-repos
|
|
56
|
+
if kw and len(kw) > 3:
|
|
57
|
+
q = f"{kw} language:{language} stars:>1000"
|
|
58
|
+
else:
|
|
59
|
+
q = f"language:{language} stars:>10000" # last resort
|
|
60
|
+
|
|
61
|
+
search_resp = await client.get(
|
|
62
|
+
"/search/repositories",
|
|
63
|
+
params={"q": q, "sort": "stars", "order": "desc", "per_page": 20},
|
|
64
|
+
)
|
|
65
|
+
search_resp.raise_for_status()
|
|
66
|
+
items = search_resp.json().get("items", [])
|
|
67
|
+
|
|
68
|
+
full = f"{owner}/{repo}"
|
|
69
|
+
results = []
|
|
70
|
+
for item in items:
|
|
71
|
+
name = item.get("full_name")
|
|
72
|
+
if name == full:
|
|
73
|
+
continue
|
|
74
|
+
results.append(
|
|
75
|
+
{
|
|
76
|
+
"repo": name,
|
|
77
|
+
"stars": item.get("stargazers_count", 0),
|
|
78
|
+
"language": item.get("language") or "Unknown",
|
|
79
|
+
"description": item.get("description") or "",
|
|
80
|
+
"url": item.get("html_url") or "",
|
|
81
|
+
}
|
|
82
|
+
)
|
|
83
|
+
if len(results) >= count:
|
|
84
|
+
break
|
|
85
|
+
|
|
86
|
+
return SimilarRepoList(source_repo=full, similar=results)
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
# Tools package
|
|
@@ -0,0 +1,25 @@
|
|
|
1
|
+
"""MCP tool: analyze repo for learning."""
|
|
2
|
+
|
|
3
|
+
from mcp.types import TextContent
|
|
4
|
+
|
|
5
|
+
from ..analyzer import analyze_repo
|
|
6
|
+
|
|
7
|
+
|
|
8
|
+
async def analyze_repo_tool(arguments: dict) -> list[TextContent]:
|
|
9
|
+
"""Entry point called by AI.
|
|
10
|
+
|
|
11
|
+
Args:
|
|
12
|
+
arguments: dict with keys `owner` and `repo`.
|
|
13
|
+
"""
|
|
14
|
+
try:
|
|
15
|
+
owner = arguments["owner"]
|
|
16
|
+
repo = arguments["repo"]
|
|
17
|
+
except KeyError as e:
|
|
18
|
+
return [TextContent(type="text", text=f"Missing required argument: {e}")]
|
|
19
|
+
|
|
20
|
+
try:
|
|
21
|
+
result = await analyze_repo(owner, repo)
|
|
22
|
+
except Exception as e:
|
|
23
|
+
return [TextContent(type="text", text=f"Analysis failed: {e}")]
|
|
24
|
+
|
|
25
|
+
return [TextContent(type="text", text=result.model_dump_json(indent=2))]
|
|
@@ -0,0 +1,22 @@
|
|
|
1
|
+
"""MCP tool: compare candidate repos for learning."""
|
|
2
|
+
|
|
3
|
+
from mcp.types import TextContent
|
|
4
|
+
|
|
5
|
+
from ..comparer import compare_repos
|
|
6
|
+
|
|
7
|
+
|
|
8
|
+
async def compare_tool(arguments: dict) -> list[TextContent]:
|
|
9
|
+
"""Entry point: expects `repos` (list of full names) and optional user_level."""
|
|
10
|
+
repos = arguments.get("repos") or []
|
|
11
|
+
if not isinstance(repos, list) or len(repos) < 2:
|
|
12
|
+
return [TextContent(
|
|
13
|
+
type="text",
|
|
14
|
+
text="Please provide at least 2 repos as list of 'owner/repo'.",
|
|
15
|
+
)]
|
|
16
|
+
level = arguments.get("user_level", "intermediate")
|
|
17
|
+
|
|
18
|
+
try:
|
|
19
|
+
result = await compare_repos(repos, level)
|
|
20
|
+
except Exception as e:
|
|
21
|
+
return [TextContent(type="text", text=f"Comparison failed: {e}")]
|
|
22
|
+
return [TextContent(type="text", text=result.model_dump_json(indent=2))]
|
|
@@ -0,0 +1,16 @@
|
|
|
1
|
+
"""Simple info tool for testing."""
|
|
2
|
+
|
|
3
|
+
from mcp.types import TextContent
|
|
4
|
+
|
|
5
|
+
|
|
6
|
+
async def get_server_info() -> list[TextContent]:
|
|
7
|
+
"""Return server information."""
|
|
8
|
+
return [
|
|
9
|
+
TextContent(
|
|
10
|
+
type="text",
|
|
11
|
+
text=(
|
|
12
|
+
"MCP GitHub Learning Assistant v0.1.0 - "
|
|
13
|
+
"discover open-source projects worth learning"
|
|
14
|
+
),
|
|
15
|
+
)
|
|
16
|
+
]
|
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
"""MCP tool: find good first issues."""
|
|
2
|
+
|
|
3
|
+
from mcp.types import TextContent
|
|
4
|
+
|
|
5
|
+
from ..issuefind import find_first_issues
|
|
6
|
+
|
|
7
|
+
|
|
8
|
+
async def issues_tool(arguments: dict) -> list[TextContent]:
|
|
9
|
+
"""Entry point: expects owner, repo(optional labels)."""
|
|
10
|
+
try:
|
|
11
|
+
owner = arguments["owner"]
|
|
12
|
+
repo = arguments["repo"]
|
|
13
|
+
except KeyError as e:
|
|
14
|
+
return [TextContent(type="text", text=f"Missing required argument: {e}")]
|
|
15
|
+
labels = arguments.get("labels", "good first issue,help wanted")
|
|
16
|
+
|
|
17
|
+
try:
|
|
18
|
+
result = await find_first_issues(owner, repo, [labels])
|
|
19
|
+
except Exception as e:
|
|
20
|
+
return [TextContent(type="text", text=f"Issue-finding failed: {e}")]
|
|
21
|
+
return [TextContent(type="text", text=result.model_dump_json(indent=2))]
|
|
@@ -0,0 +1,33 @@
|
|
|
1
|
+
"""MCP tool: recommend learning repositories based on user profile."""
|
|
2
|
+
|
|
3
|
+
from mcp.types import TextContent
|
|
4
|
+
|
|
5
|
+
from ..recommender import recommend_repos
|
|
6
|
+
|
|
7
|
+
|
|
8
|
+
async def recommend_repos_tool(arguments: dict) -> list[TextContent]:
|
|
9
|
+
"""Entry point called by AI.
|
|
10
|
+
|
|
11
|
+
Expected argument keys:
|
|
12
|
+
role: student / backend_dev / frontend_dev / mobile_dev / ai_dev
|
|
13
|
+
target_tech: e.g. Spring Boot, FastAPI, Vue 3
|
|
14
|
+
experience_level: beginner / intermediate / advanced
|
|
15
|
+
goal: interview_prep / skill_upgrade / open_source / project_practice
|
|
16
|
+
count: max recommendations to return
|
|
17
|
+
"""
|
|
18
|
+
role = arguments.get("role", "student")
|
|
19
|
+
tech = arguments.get("target_tech", "")
|
|
20
|
+
level = arguments.get("experience_level", "beginner")
|
|
21
|
+
goal = arguments.get("goal", "skill_upgrade")
|
|
22
|
+
count = arguments.get("count", 5)
|
|
23
|
+
try:
|
|
24
|
+
count = max(1, min(int(count), 10))
|
|
25
|
+
except (TypeError, ValueError):
|
|
26
|
+
count = 5
|
|
27
|
+
|
|
28
|
+
try:
|
|
29
|
+
recs = await recommend_repos(role, tech, level, goal, count)
|
|
30
|
+
except Exception as e:
|
|
31
|
+
return [TextContent(type="text", text=f"Recommendation failed: {e}")]
|
|
32
|
+
|
|
33
|
+
return [TextContent(type="text", text=recs.model_dump_json(indent=2))]
|
|
@@ -0,0 +1,22 @@
|
|
|
1
|
+
"""MCP tool: generate learning roadmap from repo structure."""
|
|
2
|
+
|
|
3
|
+
from mcp.types import TextContent
|
|
4
|
+
|
|
5
|
+
from ..roadmap import build_roadmap
|
|
6
|
+
|
|
7
|
+
|
|
8
|
+
async def roadmap_tool(arguments: dict) -> list[TextContent]:
|
|
9
|
+
"""Entry point: expects owner, repo, depth(optional)."""
|
|
10
|
+
try:
|
|
11
|
+
owner = arguments["owner"]
|
|
12
|
+
repo = arguments["repo"]
|
|
13
|
+
except KeyError as e:
|
|
14
|
+
return [TextContent(type="text", text=f"Missing required argument: {e}")]
|
|
15
|
+
depth = int(arguments.get("depth", 2))
|
|
16
|
+
depth = max(1, min(depth, 3))
|
|
17
|
+
|
|
18
|
+
try:
|
|
19
|
+
result = await build_roadmap(owner, repo, depth)
|
|
20
|
+
except Exception as e:
|
|
21
|
+
return [TextContent(type="text", text=f"Roadmap failed: {e}")]
|
|
22
|
+
return [TextContent(type="text", text=result.model_dump_json(indent=2))]
|
|
@@ -0,0 +1,22 @@
|
|
|
1
|
+
"""MCP tool: find similar repositories by language & topic."""
|
|
2
|
+
|
|
3
|
+
from mcp.types import TextContent
|
|
4
|
+
|
|
5
|
+
from ..similar import find_similar
|
|
6
|
+
|
|
7
|
+
|
|
8
|
+
async def similar_tool(arguments: dict) -> list[TextContent]:
|
|
9
|
+
"""Entry point: expects owner, repo, count(optional)."""
|
|
10
|
+
try:
|
|
11
|
+
owner = arguments["owner"]
|
|
12
|
+
repo = arguments["repo"]
|
|
13
|
+
except KeyError as e:
|
|
14
|
+
return [TextContent(type="text", text=f"Missing required argument: {e}")]
|
|
15
|
+
count = int(arguments.get("count", 3))
|
|
16
|
+
count = max(1, min(count, 10))
|
|
17
|
+
|
|
18
|
+
try:
|
|
19
|
+
result = await find_similar(owner, repo, count)
|
|
20
|
+
except Exception as e:
|
|
21
|
+
return [TextContent(type="text", text=f"Similar-repos failed: {e}")]
|
|
22
|
+
return [TextContent(type="text", text=result.model_dump_json(indent=2))]
|
|
@@ -0,0 +1,35 @@
|
|
|
1
|
+
"""MCP tool: find recent popular repositories."""
|
|
2
|
+
|
|
3
|
+
from mcp.types import TextContent
|
|
4
|
+
|
|
5
|
+
from ..trending import get_trending_repos
|
|
6
|
+
|
|
7
|
+
|
|
8
|
+
async def trending_tool(arguments: dict) -> list[TextContent]:
|
|
9
|
+
"""Entry point: expects language and/or topic with search options."""
|
|
10
|
+
language = str(arguments.get("language", "")).strip()
|
|
11
|
+
topic = str(arguments.get("topic", "")).strip()
|
|
12
|
+
if not language and not topic:
|
|
13
|
+
return [TextContent(type="text", text="Provide a language and/or topic.")]
|
|
14
|
+
|
|
15
|
+
try:
|
|
16
|
+
count = max(1, min(int(arguments.get("count", 5)), 10))
|
|
17
|
+
min_stars = max(0, int(arguments.get("min_stars", 100)))
|
|
18
|
+
period_days = max(1, min(int(arguments.get("period_days", 90)), 365))
|
|
19
|
+
except (TypeError, ValueError):
|
|
20
|
+
count = 5
|
|
21
|
+
min_stars = 100
|
|
22
|
+
period_days = 90
|
|
23
|
+
|
|
24
|
+
try:
|
|
25
|
+
result = await get_trending_repos(
|
|
26
|
+
language=language.lower(),
|
|
27
|
+
topic=topic.lower(),
|
|
28
|
+
count=count,
|
|
29
|
+
min_stars=min_stars,
|
|
30
|
+
period_days=period_days,
|
|
31
|
+
)
|
|
32
|
+
except Exception as error:
|
|
33
|
+
return [TextContent(type="text", text=f"Trending lookup failed: {error}")]
|
|
34
|
+
|
|
35
|
+
return [TextContent(type="text", text=result.model_dump_json(indent=2))]
|
|
@@ -0,0 +1,82 @@
|
|
|
1
|
+
"""Find recently popular repositories using GitHub search."""
|
|
2
|
+
|
|
3
|
+
from datetime import datetime, timedelta, timezone
|
|
4
|
+
|
|
5
|
+
from .github_client import github_client
|
|
6
|
+
from .models.outputs import TrendingRepo, TrendingRepoList
|
|
7
|
+
|
|
8
|
+
|
|
9
|
+
def _build_query(language: str, topic: str, min_stars: int, created_after: str) -> str:
|
|
10
|
+
"""Build a GitHub repository search query."""
|
|
11
|
+
terms = [
|
|
12
|
+
f"language:{language}" if language else "",
|
|
13
|
+
f"topic:{topic}" if topic else "",
|
|
14
|
+
f"stars:>={min_stars}",
|
|
15
|
+
f"created:>{created_after}",
|
|
16
|
+
"archived:false",
|
|
17
|
+
"fork:false",
|
|
18
|
+
]
|
|
19
|
+
return " ".join(term for term in terms if term)
|
|
20
|
+
|
|
21
|
+
|
|
22
|
+
def _parse_created_at(value: str) -> datetime | None:
|
|
23
|
+
"""Parse an ISO-8601 GitHub timestamp safely."""
|
|
24
|
+
try:
|
|
25
|
+
return datetime.fromisoformat(value.replace("Z", "+00:00"))
|
|
26
|
+
except (AttributeError, TypeError, ValueError):
|
|
27
|
+
return None
|
|
28
|
+
|
|
29
|
+
|
|
30
|
+
async def get_trending_repos(
|
|
31
|
+
language: str,
|
|
32
|
+
topic: str,
|
|
33
|
+
count: int,
|
|
34
|
+
min_stars: int,
|
|
35
|
+
period_days: int,
|
|
36
|
+
) -> TrendingRepoList:
|
|
37
|
+
"""Find high-star repositories created within the requested period."""
|
|
38
|
+
language = language.strip().lower()
|
|
39
|
+
topic = topic.strip().lower()
|
|
40
|
+
period_ended = datetime.now(timezone.utc)
|
|
41
|
+
period_started = period_ended - timedelta(days=period_days)
|
|
42
|
+
created_after = period_started.date().isoformat()
|
|
43
|
+
search_query = _build_query(language, topic, min_stars, created_after)
|
|
44
|
+
|
|
45
|
+
async with await github_client() as client:
|
|
46
|
+
response = await client.get(
|
|
47
|
+
"/search/repositories",
|
|
48
|
+
params={
|
|
49
|
+
"q": search_query,
|
|
50
|
+
"sort": "stars",
|
|
51
|
+
"order": "desc",
|
|
52
|
+
"per_page": count,
|
|
53
|
+
},
|
|
54
|
+
)
|
|
55
|
+
response.raise_for_status()
|
|
56
|
+
items = response.json().get("items", [])
|
|
57
|
+
|
|
58
|
+
repos: list[TrendingRepo] = []
|
|
59
|
+
for item in items:
|
|
60
|
+
created_at = _parse_created_at(item.get("created_at"))
|
|
61
|
+
age_days = max(
|
|
62
|
+
1, (period_ended - created_at).days if created_at else period_days
|
|
63
|
+
)
|
|
64
|
+
stars = item.get("stargazers_count", 0)
|
|
65
|
+
repos.append(
|
|
66
|
+
TrendingRepo(
|
|
67
|
+
repo=item.get("full_name") or "",
|
|
68
|
+
stars=stars,
|
|
69
|
+
stars_per_day=round(stars / age_days, 1),
|
|
70
|
+
language=item.get("language") or "Unknown",
|
|
71
|
+
description=item.get("description") or "",
|
|
72
|
+
url=item.get("html_url") or "",
|
|
73
|
+
)
|
|
74
|
+
)
|
|
75
|
+
|
|
76
|
+
repos.sort(key=lambda repo: repo.stars_per_day, reverse=True)
|
|
77
|
+
return TrendingRepoList(
|
|
78
|
+
language=language or None,
|
|
79
|
+
topic=topic or None,
|
|
80
|
+
period_days=period_days,
|
|
81
|
+
repos=repos,
|
|
82
|
+
)
|
|
@@ -0,0 +1,100 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: mcp-github-learning-assistant
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: An MCP server that helps developers discover and learn from GitHub open-source projects
|
|
5
|
+
Author: iyiook333
|
|
6
|
+
License: MIT
|
|
7
|
+
License-File: LICENSE
|
|
8
|
+
Classifier: Development Status :: 3 - Alpha
|
|
9
|
+
Classifier: Intended Audience :: Developers
|
|
10
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
11
|
+
Classifier: Programming Language :: Python :: 3
|
|
12
|
+
Classifier: Programming Language :: Python :: 3.10
|
|
13
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
14
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
15
|
+
Requires-Python: >=3.10
|
|
16
|
+
Requires-Dist: httpx>=0.27.0
|
|
17
|
+
Requires-Dist: mcp>=1.0.0
|
|
18
|
+
Requires-Dist: pydantic>=2.0.0
|
|
19
|
+
Requires-Dist: python-dotenv>=1.0.0
|
|
20
|
+
Provides-Extra: dev
|
|
21
|
+
Requires-Dist: pytest-asyncio>=0.23.0; extra == 'dev'
|
|
22
|
+
Requires-Dist: pytest>=8.0.0; extra == 'dev'
|
|
23
|
+
Requires-Dist: ruff>=0.6.0; extra == 'dev'
|
|
24
|
+
Description-Content-Type: text/markdown
|
|
25
|
+
|
|
26
|
+
# MCP GitHub Learning Assistant
|
|
27
|
+
|
|
28
|
+
An MCP (Model Context Protocol) server that helps developers discover and learn from open-source projects on GitHub, based on their skill level and goals.
|
|
29
|
+
|
|
30
|
+
## Features
|
|
31
|
+
|
|
32
|
+
8 tools to support every stage of open-source learning:
|
|
33
|
+
|
|
34
|
+
| Tool | Description |
|
|
35
|
+
|------|-------------|
|
|
36
|
+
| `analyze_repo_for_learning` | Score a repo: stars, doc quality, difficulty, prerequisites, suggested learning path |
|
|
37
|
+
| `recommend_learning_repos` | Curated recommendations per tech stack (Spring Boot, FastAPI, Vue, React, Electron, HarmonyOS) |
|
|
38
|
+
| `get_repo_roadmap` | Generate a step-by-step learning roadmap from a repo's directory structure |
|
|
39
|
+
| `find_similar_repos` | Find thematically similar repos (same language/topic) for comparison |
|
|
40
|
+
| `find_good_first_issues` | Find beginner-friendly open issues (good first issue / help wanted) |
|
|
41
|
+
| `compare_learning_repos` | Compare 2+ candidate repos and suggest which to learn first |
|
|
42
|
+
| `get_trending_repos_for_learning` | Find breakout repos created recently by language/topic |
|
|
43
|
+
| `get_server_info` | Verify the MCP server connection |
|
|
44
|
+
|
|
45
|
+
## Screenshots
|
|
46
|
+
|
|
47
|
+
| MCP Inspector - Tools list | MCP Inspector - analyze_repo_for_learning result |
|
|
48
|
+
|:---:|:---:|
|
|
49
|
+
|  | 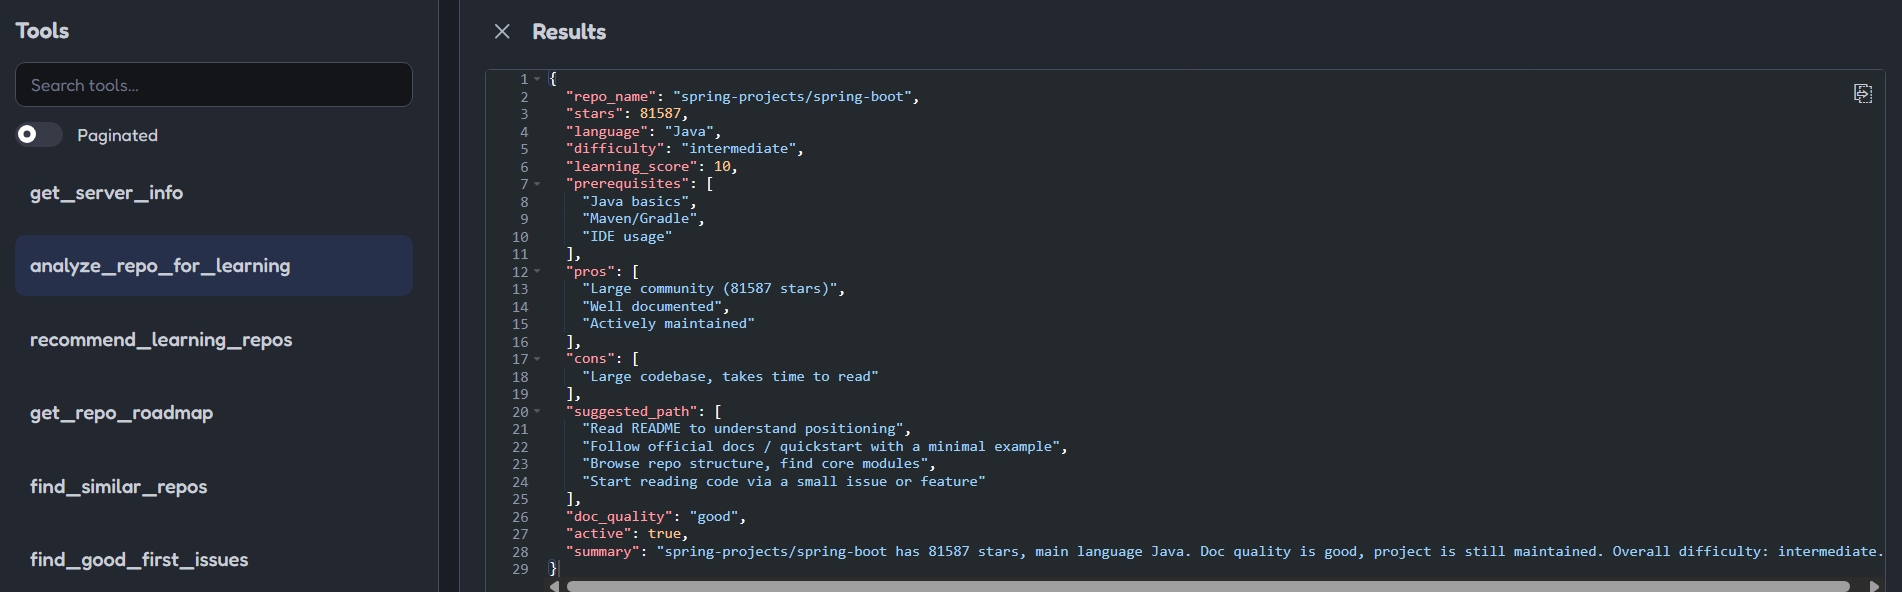 |
|
|
50
|
+
|
|
51
|
+
Screenshots use dark-mode crops under 500KB each.
|
|
52
|
+
|
|
53
|
+
## Installation
|
|
54
|
+
|
|
55
|
+
```bash
|
|
56
|
+
pip install mcp-github-learning-assistant
|
|
57
|
+
```
|
|
58
|
+
|
|
59
|
+
## Configuration
|
|
60
|
+
|
|
61
|
+
Set your GitHub Personal Access Token:
|
|
62
|
+
|
|
63
|
+
```powershell
|
|
64
|
+
# Windows PowerShell
|
|
65
|
+
$env:GITHUB_TOKEN = "your_github_token"
|
|
66
|
+
```
|
|
67
|
+
|
|
68
|
+
```bash
|
|
69
|
+
# Linux / macOS
|
|
70
|
+
export GITHUB_TOKEN=your_github_token
|
|
71
|
+
```
|
|
72
|
+
|
|
73
|
+
Token scope: fine-grained PAT with no special permissions (public repo read-only) is enough.
|
|
74
|
+
|
|
75
|
+
## Usage in MCP Clients
|
|
76
|
+
|
|
77
|
+
### MCP Inspector (development)
|
|
78
|
+
|
|
79
|
+
```bash
|
|
80
|
+
npx @modelcontextprotocol/inspector python -m mcp_github_learning_assistant
|
|
81
|
+
```
|
|
82
|
+
|
|
83
|
+
### Cherry Studio
|
|
84
|
+
|
|
85
|
+
1. Open Cherry Studio, go to Settings -> MCP
|
|
86
|
+
2. Add an MCP server with the command `python -m mcp_github_learning_assistant`
|
|
87
|
+
3. Set the environment variable `GITHUB_TOKEN`
|
|
88
|
+
|
|
89
|
+
## Development
|
|
90
|
+
|
|
91
|
+
```bash
|
|
92
|
+
git clone https://github.com/iyiook333/mcp-github-learning-assistant.git
|
|
93
|
+
cd mcp-github-learning-assistant
|
|
94
|
+
pip install -e .[dev]
|
|
95
|
+
pytest
|
|
96
|
+
```
|
|
97
|
+
|
|
98
|
+
## License
|
|
99
|
+
|
|
100
|
+
MIT
|
|
@@ -0,0 +1,27 @@
|
|
|
1
|
+
mcp_github_learning_assistant/__init__.py,sha256=iYC6R6V4fgqkeCQ-NxBLKxF86ojy1ooAxdkxs3lCKxE,64
|
|
2
|
+
mcp_github_learning_assistant/__main__.py,sha256=pmJap3GHEmTMV2nvIFa4tifa9-10Ow4Gl_LFmAp1Tls,142
|
|
3
|
+
mcp_github_learning_assistant/analyzer.py,sha256=__Wi8zDlmdfyM-LAltHd9j_GpyTw184Ry9P_CAGhmos,4160
|
|
4
|
+
mcp_github_learning_assistant/comparer.py,sha256=743KIizbw0BVSptMPfiEDp7sM8AI7BuIEAWwwtHOc2s,2615
|
|
5
|
+
mcp_github_learning_assistant/github_client.py,sha256=eg98xpGu6aL1O6xCkTSc98qUeYwEkjiogq8Z2Pms-c4,641
|
|
6
|
+
mcp_github_learning_assistant/issuefind.py,sha256=lAKFUjvQ2_Z3J3Ijo7VYC9bQt_-k82HXZ2OXzW1UCms,1875
|
|
7
|
+
mcp_github_learning_assistant/recommender.py,sha256=9J24b3gY5skxLhnBOnb2w0eruqG6A7obIHaTjvt2kJk,4454
|
|
8
|
+
mcp_github_learning_assistant/roadmap.py,sha256=k8kMcd2F6VdsN58DLt6dombciSQxdRL5xQXvWZnHmUo,2872
|
|
9
|
+
mcp_github_learning_assistant/server.py,sha256=lkeaDL0gyQf3uuOdArk8S6cBBELs9UKfBnJbUwLpZ-w,4580
|
|
10
|
+
mcp_github_learning_assistant/similar.py,sha256=mZSThh1rrSFEhqZqKy8y0evClNFgvqGUif4y5AQe9Yw,2990
|
|
11
|
+
mcp_github_learning_assistant/trending.py,sha256=tUn2_we94a-uRIvY0miL7CizBDlQwlwswdlSmDnYIF8,2701
|
|
12
|
+
mcp_github_learning_assistant/models/__init__.py,sha256=Bvq5w7Vj873u7FT9HKvKci2iD-CdRKOii12xgWdfGTE,21
|
|
13
|
+
mcp_github_learning_assistant/models/outputs.py,sha256=_aZF2CvoxI6-DEUOQ68GqlGaWV8GfyZQxPu9_hIscco,2487
|
|
14
|
+
mcp_github_learning_assistant/tools/__init__.py,sha256=CQ-dDaKhiwoYYQnvkb3RDi5XgXnnW8YGHE6JSzuWSDg,20
|
|
15
|
+
mcp_github_learning_assistant/tools/analyze.py,sha256=bAHh_t6dkUGXJPc5gxLpF4xRt_WdLjbDog3e705e9kI,715
|
|
16
|
+
mcp_github_learning_assistant/tools/compare.py,sha256=biIrrM05lvuq4qXy_9eyFT4LkY17KO9oIykezmVDO3M,808
|
|
17
|
+
mcp_github_learning_assistant/tools/info.py,sha256=f448pXWRh_yaqChnwmtxQjznx-hr0rPm9dO1RWNUw2A,390
|
|
18
|
+
mcp_github_learning_assistant/tools/issues.py,sha256=lOIlw8TXLUvtTYwanmSGOhIjnEbs1AgijD7nWQGt_ms,751
|
|
19
|
+
mcp_github_learning_assistant/tools/recommend.py,sha256=oZISqHeeSucggbR8UInYgMHON_jFO5IVlySzl2lLEW0,1207
|
|
20
|
+
mcp_github_learning_assistant/tools/roadmap.py,sha256=_iFv_COY7xZi9UEXkvnSwFSyuv0SNC0izBYZIMFo2tM,764
|
|
21
|
+
mcp_github_learning_assistant/tools/similar.py,sha256=EuRTnUo7Tw0FPyxt9LGOTrNLFL0fwNBkxcuUBnVdfpo,769
|
|
22
|
+
mcp_github_learning_assistant/tools/trending.py,sha256=pn1plw83E68Nw7yGuj7wCsnbpPDcLNSk9h4NsuvpkH0,1237
|
|
23
|
+
mcp_github_learning_assistant-0.1.0.dist-info/METADATA,sha256=_xc4ycc5NvF3G4_PkJt6ArhKi9mGS2iYMLavsuqJbII,3343
|
|
24
|
+
mcp_github_learning_assistant-0.1.0.dist-info/WHEEL,sha256=W3fkpkm7-wf9vBI5Z-7s0eWkeM-spu78I8Neb98DeEg,87
|
|
25
|
+
mcp_github_learning_assistant-0.1.0.dist-info/entry_points.txt,sha256=z1J-_9Ur83GR0UplkNp9gxWFB3wz7xAL0TfnOwUDgfw,91
|
|
26
|
+
mcp_github_learning_assistant-0.1.0.dist-info/licenses/LICENSE,sha256=7tb57gjQnuCyKGlquv4Aim6NrFaR0lueq0wxqGTTGqw,1062
|
|
27
|
+
mcp_github_learning_assistant-0.1.0.dist-info/RECORD,,
|
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 iyiook333
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the Software), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED AS IS, WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|