easyannotate 0.4.0__py3-none-any.whl
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- data_factory/__init__.py +82 -0
- data_factory/__main__.py +6 -0
- data_factory/annotate/__init__.py +15 -0
- data_factory/annotate/attach.py +398 -0
- data_factory/annotate/demo.py +161 -0
- data_factory/annotate/images.py +443 -0
- data_factory/annotate/labels.py +399 -0
- data_factory/annotate/loop.py +359 -0
- data_factory/annotate/projects.py +207 -0
- data_factory/annotate/review.py +471 -0
- data_factory/annotate/schema.sql +171 -0
- data_factory/annotate/shapes.py +488 -0
- data_factory/annotate/store.py +292 -0
- data_factory/annotate/tools/__init__.py +39 -0
- data_factory/annotate/tools/fake.py +170 -0
- data_factory/annotate/tools/install.py +254 -0
- data_factory/annotate/tools/local.py +389 -0
- data_factory/annotate/tools/postprocess.py +175 -0
- data_factory/annotate/tools/protocol.py +238 -0
- data_factory/annotate/tools/registry.py +196 -0
- data_factory/annotate/tools/results.py +83 -0
- data_factory/annotate/tools/serve.py +106 -0
- data_factory/cli/__init__.py +21 -0
- data_factory/cli/main.py +837 -0
- data_factory/cli/menu.py +173 -0
- data_factory/cli/render.py +158 -0
- data_factory/core/__init__.py +11 -0
- data_factory/core/annotations/__init__.py +5 -0
- data_factory/core/annotations/coco.py +394 -0
- data_factory/core/annotations/csvfmt.py +174 -0
- data_factory/core/annotations/dota.py +98 -0
- data_factory/core/annotations/formats.py +626 -0
- data_factory/core/annotations/labelme.py +153 -0
- data_factory/core/annotations/model.py +334 -0
- data_factory/core/annotations/voc.py +231 -0
- data_factory/core/annotations/yolo.py +283 -0
- data_factory/core/bktree.py +89 -0
- data_factory/core/fs.py +245 -0
- data_factory/core/imaging.py +626 -0
- data_factory/core/ops/__init__.py +44 -0
- data_factory/core/ops/analyze.py +383 -0
- data_factory/core/ops/annotate_export.py +326 -0
- data_factory/core/ops/audit.py +274 -0
- data_factory/core/ops/augment.py +454 -0
- data_factory/core/ops/collect.py +241 -0
- data_factory/core/ops/combine.py +582 -0
- data_factory/core/ops/convert.py +212 -0
- data_factory/core/ops/dataset.py +246 -0
- data_factory/core/ops/dedup.py +235 -0
- data_factory/core/ops/export.py +168 -0
- data_factory/core/ops/image.py +407 -0
- data_factory/core/ops/labels.py +215 -0
- data_factory/core/ops/pairing.py +133 -0
- data_factory/core/ops/rename.py +154 -0
- data_factory/core/ops/report.py +323 -0
- data_factory/core/ops/visualize.py +164 -0
- data_factory/core/pairs.py +144 -0
- data_factory/core/parallel.py +191 -0
- data_factory/core/provenance.py +136 -0
- data_factory/core/registry.py +339 -0
- data_factory/core/stats.py +403 -0
- data_factory/core/types.py +148 -0
- data_factory/core/writer.py +194 -0
- data_factory/desktop.py +207 -0
- data_factory/hardware.py +243 -0
- data_factory/pipeline.py +192 -0
- data_factory/py.typed +0 -0
- data_factory/service/__init__.py +26 -0
- data_factory/service/app.py +483 -0
- data_factory/service/binding.py +174 -0
- data_factory/service/deps.py +133 -0
- data_factory/service/jobs.py +177 -0
- data_factory/service/limits.py +71 -0
- data_factory/service/routers/__init__.py +11 -0
- data_factory/service/routers/annotate.py +582 -0
- data_factory/service/routers/local.py +464 -0
- data_factory/service/routers/media.py +154 -0
- data_factory/service/routers/predictions.py +116 -0
- data_factory/service/routers/promote.py +182 -0
- data_factory/service/routers/tools.py +308 -0
- data_factory/service/static/annotate/api.js +246 -0
- data_factory/service/static/annotate/app.js +1696 -0
- data_factory/service/static/annotate/assist.js +106 -0
- data_factory/service/static/annotate/filmstrip.js +286 -0
- data_factory/service/static/annotate/hit.js +146 -0
- data_factory/service/static/annotate/labels.js +197 -0
- data_factory/service/static/annotate/render.js +286 -0
- data_factory/service/static/annotate/scene.js +277 -0
- data_factory/service/static/annotate/shapelist.js +72 -0
- data_factory/service/static/annotate/tools/box.js +96 -0
- data_factory/service/static/annotate/tools/line.js +96 -0
- data_factory/service/static/annotate/tools/obb.js +88 -0
- data_factory/service/static/annotate/tools/point.js +49 -0
- data_factory/service/static/annotate/tools/polygon.js +110 -0
- data_factory/service/static/annotate/tools/select.js +227 -0
- data_factory/service/static/annotate/undo.js +176 -0
- data_factory/service/static/annotate/viewport.js +156 -0
- data_factory/service/static/annotate.html +390 -0
- data_factory/service/static/index.html +632 -0
- data_factory/service/workspace.py +244 -0
- easyannotate/__init__.py +64 -0
- easyannotate/__main__.py +5 -0
- easyannotate/project.py +181 -0
- easyannotate/py.typed +0 -0
- easyannotate-0.4.0.dist-info/METADATA +767 -0
- easyannotate-0.4.0.dist-info/RECORD +109 -0
- easyannotate-0.4.0.dist-info/WHEEL +4 -0
- easyannotate-0.4.0.dist-info/entry_points.txt +4 -0
- easyannotate-0.4.0.dist-info/licenses/LICENSE +21 -0
|
@@ -0,0 +1,767 @@
|
|
|
1
|
+
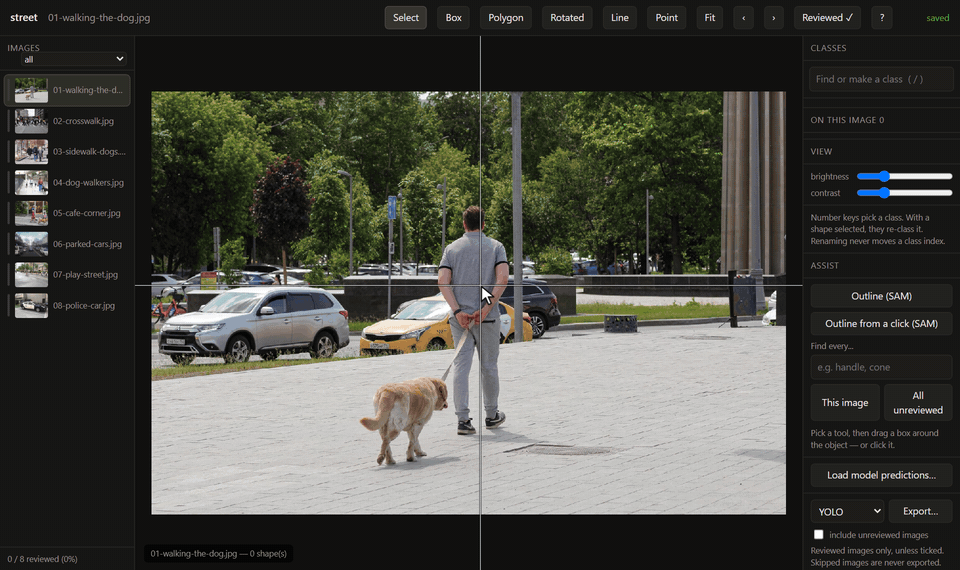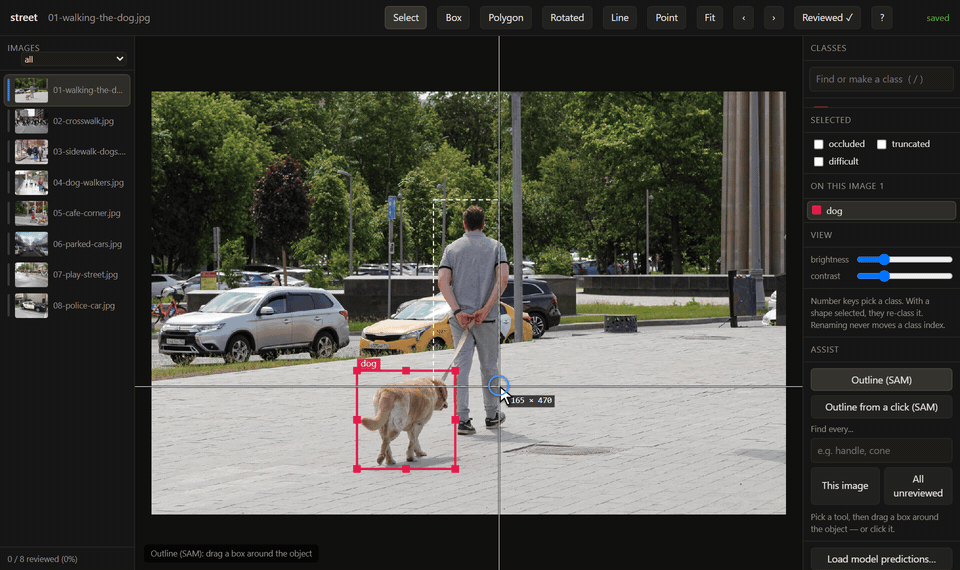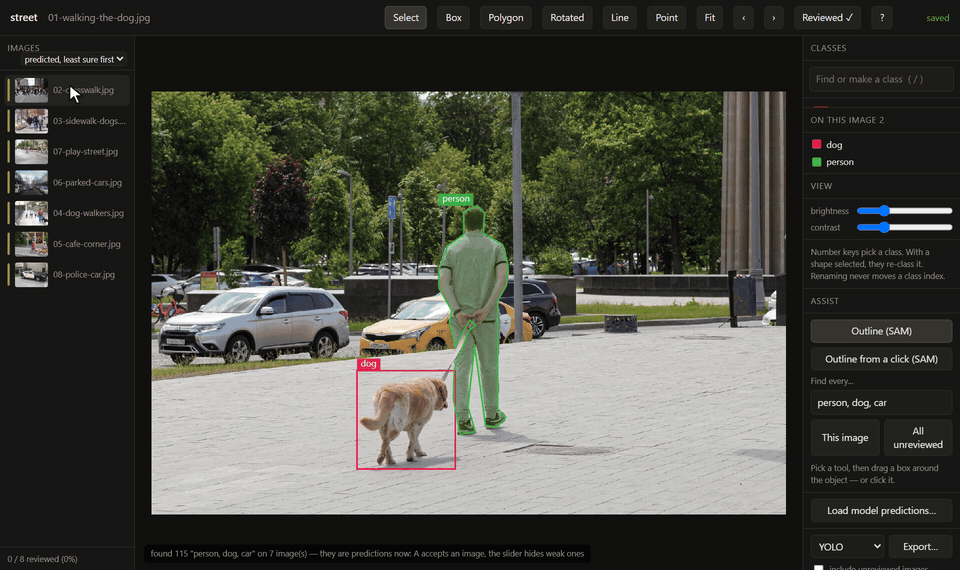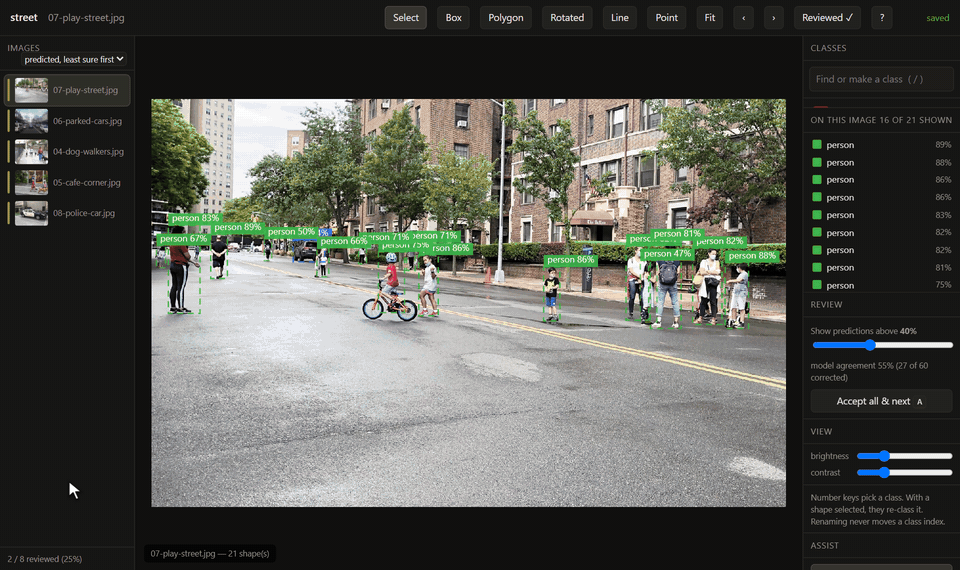
Metadata-Version: 2.5
|
|
2
|
+
Name: easyannotate
|
|
3
|
+
Version: 0.4.0
|
|
4
|
+
Summary: Image annotation with nothing to set up: draw, review model predictions fast, export a correct dataset
|
|
5
|
+
Project-URL: Homepage, https://shivpratapsinghpanwar.github.io/EasyAnnotate/
|
|
6
|
+
Project-URL: Source, https://github.com/shivpratapsinghpanwar/EasyAnnotate
|
|
7
|
+
Project-URL: Issues, https://github.com/shivpratapsinghpanwar/EasyAnnotate/issues
|
|
8
|
+
Project-URL: Changelog, https://github.com/shivpratapsinghpanwar/EasyAnnotate/blob/main/CHANGELOG.md
|
|
9
|
+
Author: Shivpratap Singh Panwar
|
|
10
|
+
License: MIT
|
|
11
|
+
License-File: LICENSE
|
|
12
|
+
Keywords: active-learning,annotation,bounding-box,coco,computer-vision,cvat-alternative,dataset,image-annotation,labeling,labelme,machine-learning,pascal-voc,polygon,yolo
|
|
13
|
+
Classifier: Development Status :: 4 - Beta
|
|
14
|
+
Classifier: Environment :: Console
|
|
15
|
+
Classifier: Intended Audience :: Developers
|
|
16
|
+
Classifier: Intended Audience :: Science/Research
|
|
17
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
18
|
+
Classifier: Operating System :: OS Independent
|
|
19
|
+
Classifier: Programming Language :: Python :: 3
|
|
20
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
21
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
22
|
+
Classifier: Topic :: Scientific/Engineering :: Artificial Intelligence
|
|
23
|
+
Classifier: Topic :: Scientific/Engineering :: Image Processing
|
|
24
|
+
Classifier: Topic :: Utilities
|
|
25
|
+
Classifier: Typing :: Typed
|
|
26
|
+
Requires-Python: >=3.12
|
|
27
|
+
Requires-Dist: fastapi>=0.110
|
|
28
|
+
Requires-Dist: imagehash>=4.3.2
|
|
29
|
+
Requires-Dist: numpy>=2.0
|
|
30
|
+
Requires-Dist: opencv-python-headless>=4.10
|
|
31
|
+
Requires-Dist: pillow>=10.0
|
|
32
|
+
Requires-Dist: python-multipart>=0.0.9
|
|
33
|
+
Requires-Dist: pyyaml>=6.0
|
|
34
|
+
Requires-Dist: uvicorn[standard]>=0.27
|
|
35
|
+
Provides-Extra: desktop
|
|
36
|
+
Requires-Dist: pywebview>=5.0; extra == 'desktop'
|
|
37
|
+
Provides-Extra: dev
|
|
38
|
+
Requires-Dist: build>=1.2; extra == 'dev'
|
|
39
|
+
Requires-Dist: httpx; extra == 'dev'
|
|
40
|
+
Requires-Dist: piexif>=1.1.3; extra == 'dev'
|
|
41
|
+
Requires-Dist: playwright>=1.45; extra == 'dev'
|
|
42
|
+
Requires-Dist: pycocotools>=2.0.7; extra == 'dev'
|
|
43
|
+
Requires-Dist: pytest>=8.0; extra == 'dev'
|
|
44
|
+
Requires-Dist: ruff>=0.6; extra == 'dev'
|
|
45
|
+
Provides-Extra: gui
|
|
46
|
+
Requires-Dist: opencv-python>=4.10; extra == 'gui'
|
|
47
|
+
Provides-Extra: web
|
|
48
|
+
Description-Content-Type: text/markdown
|
|
49
|
+
|
|
50
|
+
# EasyAnnotate
|
|
51
|
+
|
|
52
|
+
|
|
53
|
+
|
|
54
|
+
**Image annotation with nothing to set up.** Open a folder, draw a box, type a
|
|
55
|
+
class name — that is the whole workflow. Load a model's predictions and review
|
|
56
|
+
them at a few images a minute. Export a dataset that is correct by construction.
|
|
57
|
+
|
|
58
|
+
```bash
|
|
59
|
+
pip install easyannotate
|
|
60
|
+
easyannotate demo # a sample project opens in your browser
|
|
61
|
+
easyannotate annotate ./my-images # your own folder: labels are written in place
|
|
62
|
+
easyannotate app # or a desktop window, with an Open-folder button
|
|
63
|
+
```
|
|
64
|
+
|
|
65
|
+
Three ways to run it, one codebase:
|
|
66
|
+
|
|
67
|
+
- **Local web app** — `easyannotate serve` opens a page in your browser that
|
|
68
|
+
talks to a server on *your own machine*. Paste a folder path (or Browse) and
|
|
69
|
+
work on it in place; nothing is uploaded unless you upload a zip yourself.
|
|
70
|
+
The link the launcher opens carries a one-time key, so no other website can
|
|
71
|
+
reach your folders through it.
|
|
72
|
+
- **Headless** — `import easyannotate as ea` for scripts and pipelines, the
|
|
73
|
+
`easyannotate` CLI, or `easyannotate serve --headless` on a GPU box, reached
|
|
74
|
+
through an SSH tunnel.
|
|
75
|
+
- **Desktop app** — its own window, an Open-folder button, everything
|
|
76
|
+
included except the heavy models, which download only when you ask.
|
|
77
|
+
|
|
78
|
+
Or download the desktop app for Windows, macOS or Linux from the
|
|
79
|
+
[releases page](https://github.com/shivpratapsinghpanwar/EasyAnnotate/releases) —
|
|
80
|
+
no Python needed.
|
|
81
|
+
|
|
82
|
+
No account, no server, no Docker, no project template, no label schema. Your
|
|
83
|
+
images never leave your machine. Python 3.12+, Windows, macOS and Linux.
|
|
84
|
+
|
|
85
|
+
*Author: Shivpratap Singh Panwar.*
|
|
86
|
+
|
|
87
|
+
---
|
|
88
|
+
|
|
89
|
+
## Why this exists
|
|
90
|
+
|
|
91
|
+
CVAT makes you create an organisation, then a project, then labels, then a task
|
|
92
|
+
and jobs before you can draw one box. Label Studio wants a labelling config.
|
|
93
|
+
Roboflow wants your images in its cloud. EasyAnnotate's rule, which every
|
|
94
|
+
feature is subordinate to:
|
|
95
|
+
|
|
96
|
+
> **If a feature requires you to configure something before you can draw a
|
|
97
|
+
> box, it does not ship.**
|
|
98
|
+
|
|
99
|
+
What you get instead:
|
|
100
|
+
|
|
101
|
+
- **A class is created by using it.** Draw, type a name, Enter. Typing `open`
|
|
102
|
+
when `Open` exists picks `Open` — the `Close/close` split that ruins real
|
|
103
|
+
datasets cannot happen by accident.
|
|
104
|
+
- **No Save button.** Edits are saved 400ms after you stop and before you
|
|
105
|
+
navigate. Reopening a project resumes on the first unfinished image.
|
|
106
|
+
**Export…** downloads the dataset in any format, from the editor.
|
|
107
|
+
- **The model loop is the product.** Import predictions from any YOLO, COCO,
|
|
108
|
+
VOC or LabelMe run; they arrive dashed with a confidence slider; `A` accepts
|
|
109
|
+
an image. An agreement figure tells you when to retrain and when to stop.
|
|
110
|
+
- **Exports are correct.** YOLO class indices never move when you rename or
|
|
111
|
+
retire a class. Export defaults to reviewed images only, so unreviewed model
|
|
112
|
+
output can never silently become training data.
|
|
113
|
+
- **Five shape kinds, every format.** Boxes, polygons, rotated boxes, lines
|
|
114
|
+
and points. Rotated boxes export as YOLO-OBB and DOTA, points as COCO
|
|
115
|
+
keypoints, everything to LabelMe — and a dataset of any of them still comes
|
|
116
|
+
out as plain boxes when a detector wants boxes.
|
|
117
|
+
- **AI assist that feeds the review loop.** `easyannotate tools install`
|
|
118
|
+
adds SAM 2 (drag a box or click: an editable outline) and text-prompted
|
|
119
|
+
detection: type `handle`, and every handle on every unreviewed image
|
|
120
|
+
arrives as a prediction to review, dashed, with a confidence slider and one
|
|
121
|
+
key to accept. The models run in their own environment, so the editor's
|
|
122
|
+
install never depends on PyTorch, and without them it works unchanged.
|
|
123
|
+
- **Dataset tooling built in.** 28 operations — convert between five formats,
|
|
124
|
+
find duplicates and train/val leakage, health reports, augmentation that
|
|
125
|
+
moves the labels with the pixels — one `pip install` away.
|
|
126
|
+
|
|
127
|
+
---
|
|
128
|
+
|
|
129
|
+
## One core, four front ends
|
|
130
|
+
|
|
131
|
+
The original `Power_tools/` folder held fifteen scripts. Each hardcoded its
|
|
132
|
+
paths at the top, each re-implemented "find the image that matches this XML",
|
|
133
|
+
and they had quietly drifted apart — one moved sidecar labels alongside
|
|
134
|
+
duplicates, another had that code commented out. Same job, different answers.
|
|
135
|
+
|
|
136
|
+
Everything here runs through one core. Pairing an image with its label, moving
|
|
137
|
+
annotations when the pixels move, previewing before writing, and recording what
|
|
138
|
+
happened are solved once, so no operation can forget them.
|
|
139
|
+
|
|
140
|
+
```
|
|
141
|
+
data_factory/
|
|
142
|
+
core/ pure logic — no printing, no argparse, no hardcoded paths
|
|
143
|
+
types.py OpResult / FileAction / Context (progress + cancellation)
|
|
144
|
+
registry.py every operation declares its own parameters
|
|
145
|
+
pairs.py the image + sidecar abstraction all 15 scripts re-invented
|
|
146
|
+
fs.py the single choke point every file mutation passes through
|
|
147
|
+
imaging.py image I/O, and geometry that moves annotations with pixels
|
|
148
|
+
writer.py streaming dataset writer, so augmentation is not memory-bound
|
|
149
|
+
stats.py dataset measurement, and the judgements drawn from it
|
|
150
|
+
parallel.py ordered parallel map for the decode-bound stages
|
|
151
|
+
provenance.py per-dataset lineage, recorded automatically
|
|
152
|
+
bktree.py metric tree behind fast perceptual matching
|
|
153
|
+
annotations/ neutral model + VOC / YOLO / COCO / LabelMe / CSV
|
|
154
|
+
ops/ the operations themselves
|
|
155
|
+
cli/ argparse commands, interactive menu, terminal rendering
|
|
156
|
+
pipeline.py YAML/JSON recipes
|
|
157
|
+
```
|
|
158
|
+
|
|
159
|
+
An operation declares its parameters **once**. The CLI subcommand, the menu
|
|
160
|
+
prompts, the recipe validator and the web form schema are all generated from
|
|
161
|
+
that declaration — adding an operation means writing one file, and it appears
|
|
162
|
+
everywhere.
|
|
163
|
+
|
|
164
|
+
---
|
|
165
|
+
|
|
166
|
+
## Install
|
|
167
|
+
|
|
168
|
+
```bash
|
|
169
|
+
pip install easyannotate # everything: editor, CLI, service
|
|
170
|
+
uv tool install easyannotate # isolated, on PATH
|
|
171
|
+
uvx easyannotate demo # run once, install nothing
|
|
172
|
+
```
|
|
173
|
+
|
|
174
|
+
Python 3.12+. Needs only numpy, Pillow, OpenCV, imagehash, PyYAML and FastAPI —
|
|
175
|
+
deliberately no PyTorch, so it installs in seconds anywhere.
|
|
176
|
+
|
|
177
|
+
**OpenCV is the headless build by default.** The ordinary `opencv-python` wheel
|
|
178
|
+
links against `libGL.so.1`, which slim containers, Cloud Run and most CI images
|
|
179
|
+
do not have — it installs fine and then throws `ImportError` on exactly the
|
|
180
|
+
machines a backend runs on. Only `collect.webcam`'s preview needs a GUI, and it
|
|
181
|
+
falls back to timer capture with a warning. For the preview:
|
|
182
|
+
`pip install "easyannotate[gui]"`.
|
|
183
|
+
|
|
184
|
+
There is deliberately no `sam` extra. Model-backed tools run in a **separate
|
|
185
|
+
process with their own interpreter**, discovered at runtime and absent without
|
|
186
|
+
complaint — so torch's version matrix never has to agree with this package's.
|
|
187
|
+
Point `DATAFACTORY_TOOLS_MODULE` at one to enable it; with none installed,
|
|
188
|
+
`GET /api/tools` returns an empty list and the editor is fully usable.
|
|
189
|
+
|
|
190
|
+
The Python package is `data_factory`, and `easyannotate` still works as a
|
|
191
|
+
command — the tool was named EasyAnnotate before the editor became the point.
|
|
192
|
+
|
|
193
|
+
---
|
|
194
|
+
|
|
195
|
+
## Four ways to drive it
|
|
196
|
+
|
|
197
|
+
**1. Interactive menu** — run it bare. Every path is a prompt, and destructive
|
|
198
|
+
operations preview before they ask.
|
|
199
|
+
|
|
200
|
+
```bash
|
|
201
|
+
easyannotate
|
|
202
|
+
```
|
|
203
|
+
|
|
204
|
+
**2. Command line** — for scripting and repeatability.
|
|
205
|
+
|
|
206
|
+
```bash
|
|
207
|
+
easyannotate list # every operation
|
|
208
|
+
easyannotate explain augment.dataset # full help for one
|
|
209
|
+
|
|
210
|
+
easyannotate convert.detect --folder ./mystery-dataset
|
|
211
|
+
easyannotate inspect.health --folder ./data
|
|
212
|
+
easyannotate convert.dataset --folder ./voc --output ./yolo --to yolo
|
|
213
|
+
easyannotate augment.dataset --folder ./train --output ./aug --multiplier 3 --dry-run
|
|
214
|
+
```
|
|
215
|
+
|
|
216
|
+
**3. Recipes** — a dataset build written down, so it is reproducible.
|
|
217
|
+
|
|
218
|
+
```bash
|
|
219
|
+
easyannotate run recipes/train_ready_yolo.yaml --set root=D:/data --set out=D:/build
|
|
220
|
+
```
|
|
221
|
+
|
|
222
|
+
**4. Browser** — a local web interface, which doubles as the desktop app.
|
|
223
|
+
|
|
224
|
+
```bash
|
|
225
|
+
easyannotate serve # opens http://localhost:8765
|
|
226
|
+
```
|
|
227
|
+
|
|
228
|
+
Drop in a zip, it detects the format, and every operation appears as a form
|
|
229
|
+
generated from the same declaration the CLI reads. Binds to `127.0.0.1` only.
|
|
230
|
+
The same code hosts the service — see [DEPLOYING.md](https://github.com/shivpratapsinghpanwar/EasyAnnotate/blob/main/DEPLOYING.md).
|
|
231
|
+
|
|
232
|
+
---
|
|
233
|
+
|
|
234
|
+
## Annotating
|
|
235
|
+
|
|
236
|
+
`easyannotate serve`, drop in a folder, click **Start annotating**. That is the
|
|
237
|
+
whole setup. There is no organisation to create, no project template, no task,
|
|
238
|
+
no label schema — **a class is created by drawing a box and typing its name.**
|
|
239
|
+
|
|
240
|
+
```
|
|
241
|
+
drag draw a box in the current class -- inside other boxes too
|
|
242
|
+
click select a shape; drag it to move, its handles to resize
|
|
243
|
+
/ find a class by typing (never makes a Close/close variant)
|
|
244
|
+
P polygon: click points, Enter or double-click to close
|
|
245
|
+
O rotated box: drag, then turn it by its handle, or [ and ]
|
|
246
|
+
L K line: click points, Enter · point: one click
|
|
247
|
+
1–0 pick a class — or re-class what is selected
|
|
248
|
+
Alt+click on a vertex: delete it. On an edge midpoint: insert one
|
|
249
|
+
Ctrl+D copy the previous image's shapes (worth more than a model on video)
|
|
250
|
+
R mark reviewed and move on
|
|
251
|
+
S skip — "I can't tell". Never exported
|
|
252
|
+
arrows nudge the selection 1px, Shift 10px
|
|
253
|
+
Tab select the next shape, even one buried under another
|
|
254
|
+
Ctrl+C / Ctrl+V copy shapes, paste onto this image or the next
|
|
255
|
+
H hide every shape to see the bare image
|
|
256
|
+
? every shortcut
|
|
257
|
+
```
|
|
258
|
+
|
|
259
|
+
There is **no Save button**: edits are saved 400ms after you stop and before
|
|
260
|
+
you navigate. Reopening a project **resumes on the first unfinished image**, not
|
|
261
|
+
at the beginning.
|
|
262
|
+
|
|
263
|
+
Existing work comes with you. Promoting an upload imports its VOC, YOLO, COCO
|
|
264
|
+
or LabelMe annotations, and if it carried a `data.yaml` the class order in it is
|
|
265
|
+
**adopted rather than recomputed** — those indices are already baked into label
|
|
266
|
+
files that exist in the world.
|
|
267
|
+
|
|
268
|
+
Export goes back through an ordinary operation, so it has a dry run, progress
|
|
269
|
+
and recipe support like everything else:
|
|
270
|
+
|
|
271
|
+
```bash
|
|
272
|
+
easyannotate annotate.export --database ~/.easyannotate/annotations.db \
|
|
273
|
+
--project <id> --output ./train-set --to yolo
|
|
274
|
+
```
|
|
275
|
+
|
|
276
|
+
It exports **reviewed images only** unless told otherwise. Feeding a model's own
|
|
277
|
+
unreviewed predictions back in as ground truth is how a model poisons itself,
|
|
278
|
+
and nothing about the output looks wrong when it happens.
|
|
279
|
+
|
|
280
|
+
### Annotating a folder in place
|
|
281
|
+
|
|
282
|
+
```bash
|
|
283
|
+
easyannotate annotate ./my-dataset
|
|
284
|
+
```
|
|
285
|
+
|
|
286
|
+
No copy is made. The folder's own label files are **updated as you draw** —
|
|
287
|
+
VOC `.xml`, LabelMe `.json` or YOLO `.txt`, whichever the folder already uses,
|
|
288
|
+
detected on open. A YOLO folder's `data.yaml` is kept in step, and its existing
|
|
289
|
+
class order is inherited rather than recomputed.
|
|
290
|
+
|
|
291
|
+
Writes are atomic, so a save landing while something else reads the folder
|
|
292
|
+
cannot produce a truncated label file. COCO and CSV keep one file for the whole
|
|
293
|
+
dataset, so those open read-only for write-back — it says so, and
|
|
294
|
+
`annotate.export` produces the updated dataset instead.
|
|
295
|
+
|
|
296
|
+
This mode is CLI-only by design: it takes a path, and no HTTP route is ever
|
|
297
|
+
allowed to.
|
|
298
|
+
|
|
299
|
+
### The model loop
|
|
300
|
+
|
|
301
|
+
Annotate a few hundred by hand → train → run inference → **load the predictions
|
|
302
|
+
back in** → fix the wrong ones → export → retrain.
|
|
303
|
+
|
|
304
|
+
Load a zip of YOLO `.txt` (with `--save-conf`), VOC, LabelMe, or a COCO json —
|
|
305
|
+
including the **detection-results form**, the bare JSON list that torchvision,
|
|
306
|
+
mmdetection and Ultralytics evaluation scripts actually emit.
|
|
307
|
+
|
|
308
|
+
Predictions render dashed, and fade with confidence. A slider hides the weak
|
|
309
|
+
ones without deleting them. `A` accepts everything visible, marks the image
|
|
310
|
+
reviewed and moves on — a thousand images in about fifteen minutes when the
|
|
311
|
+
model is mostly right.
|
|
312
|
+
|
|
313
|
+
The import always reports what **didn't** match. Predictions pair with images by
|
|
314
|
+
filename stem, and silently importing zero shapes because `img_001.txt` met
|
|
315
|
+
`IMG_001.jpg` looks exactly like a model that predicted nothing.
|
|
316
|
+
|
|
317
|
+
**Model agreement** is the number to watch: it tells you when to retrain and
|
|
318
|
+
when to stop. It counts only predictions on images a person has actually
|
|
319
|
+
reviewed — otherwise importing a fresh run would make the model look better —
|
|
320
|
+
and it counts deletions, because deleting a false positive is the commonest
|
|
321
|
+
correction there is and ignoring it would score a model that hallucinates boxes
|
|
322
|
+
at 100%.
|
|
323
|
+
|
|
324
|
+
One turn of the loop is written down as a recipe:
|
|
325
|
+
|
|
326
|
+
```bash
|
|
327
|
+
easyannotate run recipes/model_loop.yaml --set project=<id> --set out=./round-2
|
|
328
|
+
```
|
|
329
|
+
|
|
330
|
+
Export reviewed → check classes and health → split → check leakage → convert →
|
|
331
|
+
resize → augment train only → report. Compare this round's report against the
|
|
332
|
+
last one to see whether the loop is actually working.
|
|
333
|
+
|
|
334
|
+
### AI assist
|
|
335
|
+
|
|
336
|
+
```bash
|
|
337
|
+
easyannotate tools install # ~/.datafactory/tools, chosen for this machine
|
|
338
|
+
easyannotate tools install --cpu # skip the GPU build
|
|
339
|
+
easyannotate tools status # what this machine gets, and what is installed
|
|
340
|
+
```
|
|
341
|
+
|
|
342
|
+
From a source checkout, before the first PyPI release:
|
|
343
|
+
`easyannotate tools install --source .` The desktop app has the same thing
|
|
344
|
+
as an "Install AI tools" button.
|
|
345
|
+
|
|
346
|
+
The installer reads the GPU, its memory and its driver. NVIDIA cards get the
|
|
347
|
+
PyTorch CUDA build their driver was made for (12.8 or 12.6; PyTorch 2.7 with
|
|
348
|
+
CUDA 11.8 for drivers older than 560), Apple silicon gets Metal, anything
|
|
349
|
+
else the CPU build. Model sizes follow memory: SAM 2.1 base, small or tiny,
|
|
350
|
+
YOLO-World large, medium or small. Then it runs real work on the device and
|
|
351
|
+
believes only that: on an RTX 2050 with driver 529, PyTorch's CUDA 12.6
|
|
352
|
+
build reported the GPU available and failed every allocation. Measured there
|
|
353
|
+
on CUDA 11.8: SAM 0.044 s a click, a new text prompt about 1 s.
|
|
354
|
+
|
|
355
|
+
Then the Assist panel appears in the editor:
|
|
356
|
+
|
|
357
|
+
- **Outline (SAM)** — drag a box, or click, on an object: SAM 2.1 traces it
|
|
358
|
+
and you get a simplified polygon with draggable vertices.
|
|
359
|
+
- **Find every…** — type a class name (or several: `door, handle`) and run it
|
|
360
|
+
on this image, or on *every unreviewed image* as a job. The results are
|
|
361
|
+
predictions: dashed, scored, filtered by the slider, accepted with `A`,
|
|
362
|
+
counted by the agreement figure, and never exported until reviewed.
|
|
363
|
+
|
|
364
|
+
Weights download on first use. A slow machine is fine: a tool that is still
|
|
365
|
+
working says so and the editor waits, while you keep drawing.
|
|
366
|
+
|
|
367
|
+
### The loop: train, predict, review hardest first
|
|
368
|
+
|
|
369
|
+
```bash
|
|
370
|
+
easyannotate train ./doors # reviewed images -> a YOLO model -> predictions on the rest
|
|
371
|
+
easyannotate predict ./doors --model best.pt # or bring your own Ultralytics model
|
|
372
|
+
```
|
|
373
|
+
|
|
374
|
+
`train` exports exactly what export would (reviewed images, the project's own
|
|
375
|
+
class order, so index 3 means in the model what it means in your files),
|
|
376
|
+
trains in the tools environment, saves the model under
|
|
377
|
+
`~/.datafactory/models`, and predicts every unreviewed image with it. Then pick
|
|
378
|
+
**predicted, least sure first** in the editor's image list: images are ordered
|
|
379
|
+
by how likely their predictions are wrong (ambiguous confidences, and boxes of
|
|
380
|
+
two classes on one object), and `N`, `E` and `A` walk that queue. Each turn of
|
|
381
|
+
the loop needs less of you than the last.
|
|
382
|
+
|
|
383
|
+
Custom models run from the command line only: a `.pt` file is code, and no
|
|
384
|
+
web route will ever load one.
|
|
385
|
+
|
|
386
|
+
### Model-assisted shapes
|
|
387
|
+
|
|
388
|
+
Segmentation models can propose an outline; the editor shows a button for one
|
|
389
|
+
only when a tool is installed **and** healthy, so there are never dead controls.
|
|
390
|
+
With nothing installed, `GET /api/tools` returns an empty list and everything
|
|
391
|
+
else works — that is the default and it is a tested state.
|
|
392
|
+
|
|
393
|
+
Heavy models run in a **separate process**. A CUDA out-of-memory or a native
|
|
394
|
+
segfault kills that process, the tool goes unavailable, and you carry on drawing
|
|
395
|
+
boxes. Turning a mask into an editable outline is done here, not there: contours,
|
|
396
|
+
Douglas-Peucker simplification, then a hard vertex cap. A 512×512 mask has a
|
|
397
|
+
boundary thousands of pixels long, and nobody edits a two-thousand-vertex
|
|
398
|
+
polygon — which is exactly what the script this replaces used to write.
|
|
399
|
+
|
|
400
|
+
### Class indices do not move
|
|
401
|
+
|
|
402
|
+
A YOLO label file stores a class *index*, never a name, so the index-to-name
|
|
403
|
+
table is external state that every exported `.txt` silently depends on. Deriving
|
|
404
|
+
it by sorting the names present at export time means adding one class shifts
|
|
405
|
+
every index at or after it:
|
|
406
|
+
|
|
407
|
+
```
|
|
408
|
+
Monday [Closed, Open] a file reading `1` means Open
|
|
409
|
+
Friday [Closed, Handle, Open] the same file now means Handle
|
|
410
|
+
```
|
|
411
|
+
|
|
412
|
+
Nothing errors. The files still parse. A project's label table allocates an
|
|
413
|
+
index once and never moves it: renaming keeps the index, retiring keeps the
|
|
414
|
+
slot, a new class is appended. For datasets without a project, pass the same
|
|
415
|
+
`--classes` list to `convert.dataset` on every export and the indices hold.
|
|
416
|
+
|
|
417
|
+
---
|
|
418
|
+
|
|
419
|
+
## Operations
|
|
420
|
+
|
|
421
|
+
**Formats** — every direction, because they meet in the middle at one model.
|
|
422
|
+
|
|
423
|
+
| Operation | What it does |
|
|
424
|
+
|---|---|
|
|
425
|
+
| `convert.dataset` | VOC ↔ YOLO ↔ COCO ↔ LabelMe ↔ CSV, boxes and polygons |
|
|
426
|
+
| `convert.detect` | Identify an unknown folder and summarise what is in it |
|
|
427
|
+
| `export.coco` | Pascal VOC → COCO with segmentation and hard negatives |
|
|
428
|
+
|
|
429
|
+
**Preprocessing** — the pixels move, and the annotations move with them.
|
|
430
|
+
|
|
431
|
+
| Operation | What it does |
|
|
432
|
+
|---|---|
|
|
433
|
+
| `image.resize` | Fixed size by letterbox, stretch, crop or fit |
|
|
434
|
+
| `image.autoorient` | Bake EXIF rotation into the pixels, so every reader agrees |
|
|
435
|
+
| `image.tile` | Slice big images into an overlapping grid, reassigning objects |
|
|
436
|
+
| `augment.dataset` | Seeded variants: flips, rotation, colour, blur, noise, cutout |
|
|
437
|
+
|
|
438
|
+
**Analysis** — whether this dataset will train into something that works.
|
|
439
|
+
|
|
440
|
+
| Operation | What it does |
|
|
441
|
+
|---|---|
|
|
442
|
+
| `inspect.health` | Class balance, object size, geometry — ranked findings with fixes |
|
|
443
|
+
| `inspect.leakage` | Near-duplicate images shared between train and val |
|
|
444
|
+
| `inspect.dataset` | Pairing, classes, geometry, corrupt files, duplicates |
|
|
445
|
+
| `inspect.history` | What was done to this dataset, in order, with its settings |
|
|
446
|
+
| `inspect.coco` | Summarise an `instances.json`, flag case-collided categories |
|
|
447
|
+
| `report.html` | One self-contained HTML report, no external assets |
|
|
448
|
+
| `labels.list` | Count classes and objects, surface case-variant class names |
|
|
449
|
+
| `verify.visualize` | Draw boxes and polygons onto copies, colour-coded by class |
|
|
450
|
+
|
|
451
|
+
**Dataset algebra**
|
|
452
|
+
|
|
453
|
+
| Operation | What it does |
|
|
454
|
+
|---|---|
|
|
455
|
+
| `dataset.merge` | Combine datasets, reconciling class drift and name collisions |
|
|
456
|
+
| `dataset.filter` | Subset by class, object count, object size or split |
|
|
457
|
+
| `dataset.sample` | Seeded subset — random, stratified, or capped per class |
|
|
458
|
+
| `dataset.split` | Reproducible, stratified train/val/test split |
|
|
459
|
+
| `dataset.sort` | Group pairs into one folder per class |
|
|
460
|
+
|
|
461
|
+
**Cleaning and collection**
|
|
462
|
+
|
|
463
|
+
| Operation | What it does |
|
|
464
|
+
|---|---|
|
|
465
|
+
| `clean.dedup` | Exact or perceptual duplicates, sidecar labels moved too |
|
|
466
|
+
| `clean.orphans` | Report, quarantine or delete unpaired images and labels |
|
|
467
|
+
| `clean.unannotated` | Move images with no label into an "still to annotate" queue |
|
|
468
|
+
| `clean.rename` | Sequential renaming, pair-safe, retargets the label's filename |
|
|
469
|
+
| `labels.rename` | Bulk rename/drop classes; `--fold-case` unifies case drift |
|
|
470
|
+
| `collect.frames` | Video (or a folder of videos) → numbered JPEG frames |
|
|
471
|
+
| `collect.webcam` | Capture stills from a camera, manually or on a timer |
|
|
472
|
+
|
|
473
|
+
Operations marked `!` in `easyannotate list` write to disk. All accept `--dry-run`.
|
|
474
|
+
|
|
475
|
+
---
|
|
476
|
+
|
|
477
|
+
## Five ideas worth knowing
|
|
478
|
+
|
|
479
|
+
**Pairs.** An image and its label are one thing. Every operation moves, renames
|
|
480
|
+
and splits them together — a property of the core, not something each operation
|
|
481
|
+
remembers to do.
|
|
482
|
+
|
|
483
|
+
**Dry run is the same code path.** Operations build their full list of
|
|
484
|
+
`FileAction`s either way; `--dry-run` only stops the last step from executing. A
|
|
485
|
+
preview is a faithful description of the real run, not an approximation.
|
|
486
|
+
|
|
487
|
+
**Formats meet in the middle.** Readers parse into a neutral `Annotation`;
|
|
488
|
+
writers serialise out of it. Five formats cost five readers and five writers,
|
|
489
|
+
not twenty converters. Adding CreateML is one file, and it converts to and from
|
|
490
|
+
everything already here.
|
|
491
|
+
|
|
492
|
+
**Geometry is solved once.** Resize, tile and augment share one transform layer.
|
|
493
|
+
A box is rebuilt from all four transformed corners, so rotation stays correct
|
|
494
|
+
rather than degenerating into a box of a box; objects that fall out of frame or
|
|
495
|
+
survive only as slivers are dropped rather than becoming three pixels labelled
|
|
496
|
+
"door".
|
|
497
|
+
|
|
498
|
+
**Results are data.** Every operation returns an `OpResult` with counts, an
|
|
499
|
+
audit trail, warnings and structured payload. The terminal renderer is one
|
|
500
|
+
consumer; a web API is another.
|
|
501
|
+
|
|
502
|
+
---
|
|
503
|
+
|
|
504
|
+
## What it catches
|
|
505
|
+
|
|
506
|
+
Run on the real Project_Door V3 set (3,686 images, 3,871 objects):
|
|
507
|
+
|
|
508
|
+
```
|
|
509
|
+
$ easyannotate inspect.health --folder ./pascal_voc
|
|
510
|
+
|
|
511
|
+
[error] Classes differing only by capitalisation
|
|
512
|
+
Open / open; Close / close
|
|
513
|
+
fix: These train as separate classes and split your data in half.
|
|
514
|
+
Fix with labels.rename --fold-case.
|
|
515
|
+
|
|
516
|
+
[note] Mixed image sizes — 811 distinct resolutions.
|
|
517
|
+
[note] No train/val split.
|
|
518
|
+
|
|
519
|
+
Open: 1385 objects / 1316 images
|
|
520
|
+
Close: 1341 objects / 1206 images
|
|
521
|
+
close: 645 objects / 614 images
|
|
522
|
+
open: 500 objects / 499 images
|
|
523
|
+
```
|
|
524
|
+
|
|
525
|
+
That is a dataset with two real classes training as four, and no one had
|
|
526
|
+
noticed. `inspect.leakage` finds the other expensive one — the same photo in
|
|
527
|
+
both train and val, which makes a validation score measure memorisation and
|
|
528
|
+
looks excellent right up until deployment.
|
|
529
|
+
|
|
530
|
+
Running `recipes/train_ready_yolo.yaml` over that same folder end to end:
|
|
531
|
+
|
|
532
|
+
| Step | Result |
|
|
533
|
+
|---|---|
|
|
534
|
+
| `labels.rename --fold-case` | 1,145 objects renamed across 1,088 files — 4 classes → 2 |
|
|
535
|
+
| `dataset.split` | 2,948 / 369 / 369, stratified and seeded |
|
|
536
|
+
| `inspect.leakage` | 0 leaked pairs across 3 splits |
|
|
537
|
+
| `convert.dataset --to yolo` | 3,686 images, 3,871 objects, 2 classes |
|
|
538
|
+
| `image.resize 640 letterbox` | 3,686 resized, 0 objects dropped |
|
|
539
|
+
| `augment.dataset ×2, train only` | 9,582 total images, 10,067 objects |
|
|
540
|
+
| `inspect.health` on the result | **0 errors, 0 warnings, 1 resolution** |
|
|
541
|
+
|
|
542
|
+
The finished dataset is what the health check now has nothing to say about —
|
|
543
|
+
which is the point of the health check.
|
|
544
|
+
|
|
545
|
+
---
|
|
546
|
+
|
|
547
|
+
## As a library, and in a web app
|
|
548
|
+
|
|
549
|
+
```python
|
|
550
|
+
import easyannotate as ea
|
|
551
|
+
|
|
552
|
+
project = ea.open_folder("./doors") # the same project the editor shows
|
|
553
|
+
print(project.counts()) # {'todo': 812, 'reviewed': 200, ...}
|
|
554
|
+
project.import_predictions("runs/predict/labels")
|
|
555
|
+
hardest = project.images(state="predicted", order="uncertain")[:20]
|
|
556
|
+
project.export("./train-set", to="yolo") # reviewed only; class indices never move
|
|
557
|
+
project.train(epochs=30) # needs: easyannotate tools install
|
|
558
|
+
|
|
559
|
+
result = ea.run("inspect.health", {"folder": "./data"})
|
|
560
|
+
for finding in result.data["findings"]:
|
|
561
|
+
print(finding["severity"], finding["issue"], "->", finding["fix"])
|
|
562
|
+
|
|
563
|
+
payload = result.as_dict() # JSON-serialisable, ready to return over HTTP
|
|
564
|
+
```
|
|
565
|
+
|
|
566
|
+
Long runs report progress and can be cancelled — designed for a request that
|
|
567
|
+
outlives a single HTTP round trip:
|
|
568
|
+
|
|
569
|
+
```python
|
|
570
|
+
from data_factory import Context
|
|
571
|
+
|
|
572
|
+
ctx = Context(
|
|
573
|
+
dry_run=False,
|
|
574
|
+
progress=lambda done, total, msg: socket.send({"done": done, "total": total}),
|
|
575
|
+
cancel_check=lambda: job.is_cancelled(),
|
|
576
|
+
)
|
|
577
|
+
df.run("augment.dataset", {"folder": "./train", "output": "./aug"}, ctx)
|
|
578
|
+
```
|
|
579
|
+
|
|
580
|
+
A front-end can build its own forms without importing Python at all:
|
|
581
|
+
|
|
582
|
+
```bash
|
|
583
|
+
easyannotate schema --output schema.json
|
|
584
|
+
```
|
|
585
|
+
|
|
586
|
+
That file describes every operation, every parameter, its kind (`dir`, `int`,
|
|
587
|
+
`choice`, …), defaults, and whether it is destructive. See
|
|
588
|
+
`examples/web_api.py` for a working FastAPI wrapper in about eighty lines.
|
|
589
|
+
|
|
590
|
+
---
|
|
591
|
+
|
|
592
|
+
## Provenance
|
|
593
|
+
|
|
594
|
+
Every operation that writes a dataset appends one line to
|
|
595
|
+
`<output>/.easyannotate/history.jsonl`. It is recorded in `Operation.run`, not by
|
|
596
|
+
the operations themselves, so no operation can forget and a new one gets it
|
|
597
|
+
without asking.
|
|
598
|
+
|
|
599
|
+
```bash
|
|
600
|
+
easyannotate inspect.history --folder ./final
|
|
601
|
+
```
|
|
602
|
+
|
|
603
|
+
It answers the questions that are otherwise unanswerable six weeks later: was
|
|
604
|
+
this augmented, at what seed, was it resized before or after the split, which
|
|
605
|
+
folders went into the merge. Plain JSON Lines — readable without this tool, and
|
|
606
|
+
appended to rather than rewritten, so a build that dies halfway still leaves a
|
|
607
|
+
truthful record.
|
|
608
|
+
|
|
609
|
+
---
|
|
610
|
+
|
|
611
|
+
## Performance
|
|
612
|
+
|
|
613
|
+
**The editor at 20,000 images** (`uv run python docs/bench_scale.py`, a laptop,
|
|
614
|
+
medians; gates set in `docs/PLAN.md` before the editor existed):
|
|
615
|
+
|
|
616
|
+
| What a person waits for | Time | Gate |
|
|
617
|
+
|---|---:|---|
|
|
618
|
+
| Editor open to first image, in a browser | 1.6 s | 2 s |
|
|
619
|
+
| Image list page, first or last of 20,000 | 5–7 ms | 200 ms |
|
|
620
|
+
| "Least sure first" queue page | 6 ms | 200 ms |
|
|
621
|
+
| Open an image's shapes | 2 ms | 300 ms |
|
|
622
|
+
| Save a shape, round trip | 7 ms | 100 ms |
|
|
623
|
+
| Scroll the strip to the last image | 139 ms | 1 s |
|
|
624
|
+
| Strip rows in the DOM | 28 | — |
|
|
625
|
+
| Open a 20,000-image folder, first time | 3.7 s | — |
|
|
626
|
+
|
|
627
|
+
**AI assist on a CPU** (no GPU used), measured in the editor: SAM outline 0.17 s
|
|
628
|
+
per click once the image is encoded (encoding happens ahead, as you look);
|
|
629
|
+
"find every person" 4–5 s per image warm, 46 s the very first time (CLIP
|
|
630
|
+
downloads); `easyannotate train` on 4 reviewed images, 3 epochs, then
|
|
631
|
+
predicting 20 more: 16 s end to end.
|
|
632
|
+
|
|
633
|
+
Decode-bound stages run across threads, in input order, so results stay
|
|
634
|
+
reproducible. Measured on the real Project_Door set:
|
|
635
|
+
|
|
636
|
+
| Stage | Serial | Parallel | |
|
|
637
|
+
|---|---|---|---|
|
|
638
|
+
| `image.resize` — 3,686 images | 186.6s | 24.2s | 7.7× |
|
|
639
|
+
| `clean.dedup` — perceptual, 2,783 images | 95.6s | 33.2s | 2.9× |
|
|
640
|
+
| `augment.dataset` — 5,896 variants | 288.4s | 124.0s | 2.3× |
|
|
641
|
+
| `inspect.health` — 9,582 images | 217.7s | 112.4s | 1.9× |
|
|
642
|
+
|
|
643
|
+
Output is byte-identical either way. Order is preserved deliberately: dedup
|
|
644
|
+
keeps the first image it sees, and COCO image ids follow write order, so a
|
|
645
|
+
result that depended on which thread finished first would not be reproducible.
|
|
646
|
+
Parallelism is confined to pure functions; writing stays on the calling thread.
|
|
647
|
+
|
|
648
|
+
The map used for image work is *bounded* — the hashing map submits every task
|
|
649
|
+
up front, which is right when a result is eight bytes and catastrophic when it
|
|
650
|
+
is a decoded frame, so image stages keep only a few in flight and memory stays
|
|
651
|
+
flat regardless of dataset size.
|
|
652
|
+
|
|
653
|
+
The BK-tree handles the other half — comparing every hash to every other is
|
|
654
|
+
O(n²), about 112 million comparisons on a 15k-image set.
|
|
655
|
+
|
|
656
|
+
Set `--workers N` to override; `0` (the default) picks a sensible count.
|
|
657
|
+
|
|
658
|
+
---
|
|
659
|
+
|
|
660
|
+
## Adding an operation
|
|
661
|
+
|
|
662
|
+
One file, one decorator. It then appears in the CLI, the menu, the schema and
|
|
663
|
+
the recipe validator with no further wiring.
|
|
664
|
+
|
|
665
|
+
```python
|
|
666
|
+
from ..registry import Param, operation
|
|
667
|
+
from ..types import Context, OpResult
|
|
668
|
+
|
|
669
|
+
@operation(
|
|
670
|
+
"clean.mything",
|
|
671
|
+
title="My thing",
|
|
672
|
+
category="clean",
|
|
673
|
+
summary="One line shown in listings.",
|
|
674
|
+
params=(Param("folder", "dir", "Folder to work on.", required=True, must_exist=True),),
|
|
675
|
+
destructive=True,
|
|
676
|
+
safe_when=lambda p: p.get("action") == "report",
|
|
677
|
+
)
|
|
678
|
+
def mything(params: dict, ctx: Context) -> OpResult:
|
|
679
|
+
result = OpResult(op="clean.mything", dry_run=ctx.dry_run)
|
|
680
|
+
...
|
|
681
|
+
return result
|
|
682
|
+
```
|
|
683
|
+
|
|
684
|
+
Then add it to the imports in `data_factory/core/ops/__init__.py`.
|
|
685
|
+
|
|
686
|
+
Adding a **format** is two functions — a reader producing `Annotation` and a
|
|
687
|
+
writer consuming it — plus an entry in `annotations/formats.py`. It then
|
|
688
|
+
converts to and from every other format for free.
|
|
689
|
+
|
|
690
|
+
---
|
|
691
|
+
|
|
692
|
+
## Where the old scripts went
|
|
693
|
+
|
|
694
|
+
| Original script | Now |
|
|
695
|
+
|---|---|
|
|
696
|
+
| `CrossFolder_Duplicate_Removal_WithXML.py` | `clean.dedup --method exact` |
|
|
697
|
+
| `Remove_Duplicates_OneFolderOnly.py` | `clean.dedup --method phash` |
|
|
698
|
+
| `del_orphan_img_xml.py` | `clean.orphans --action delete` |
|
|
699
|
+
| `rename_labels_andFindOrphans.py` | `clean.orphans` + `labels.rename` |
|
|
700
|
+
| `Move_pairs.py` | `clean.unannotated` |
|
|
701
|
+
| `rename_files_and_xmls.py` | `clean.rename` |
|
|
702
|
+
| `Find_label_PVOC.py` | `labels.list` |
|
|
703
|
+
| `video_to_frames.py` | `collect.frames` |
|
|
704
|
+
| `live_webcame_image_saver.txt` (unfinished) | `collect.webcam` |
|
|
705
|
+
| `coco_dataset_generators.py` | `export.coco` / `convert.dataset --to coco` |
|
|
706
|
+
| `draw_BB_from_xml_toNewFolder.py` | `verify.visualize --draw bbox` |
|
|
707
|
+
| `Crosscheck_polygon_coco_data.py` | `verify.visualize --split-by-type` |
|
|
708
|
+
| `Crosscheck_finishedData_pascalvoc.py` | `dataset.sort` + `verify.visualize` |
|
|
709
|
+
|
|
710
|
+
The annotation GUIs (`Polygon_Advanced_Annotation_Tool.py`,
|
|
711
|
+
`Sam2.1_segmentation.py`) stay as they are — they are interactive OpenCV apps,
|
|
712
|
+
not batch operations.
|
|
713
|
+
|
|
714
|
+
### Bugs fixed along the way
|
|
715
|
+
|
|
716
|
+
- **COCO exported four classes where there were two.** Categories were keyed on
|
|
717
|
+
the raw XML string, so `Open` and `open` became separate classes — splitting
|
|
718
|
+
Project_Door V3 as 1341/1385/645/500. Export now folds case by default and
|
|
719
|
+
*reports* every merge; `labels.rename --fold-case` fixes it at the source, and
|
|
720
|
+
`inspect.health` now flags it as an error before you get that far.
|
|
721
|
+
- **SAM polygons exported as empty masks.** The two annotation tools write
|
|
722
|
+
different polygon XML (`<x1>` vs `<pt><x>`) and the converter only read one.
|
|
723
|
+
The reader now accepts both.
|
|
724
|
+
- **Renaming could clobber files.** Renaming through per-file temporary names
|
|
725
|
+
still collides when a target belongs to a file later in the queue. It is now
|
|
726
|
+
done in two global passes.
|
|
727
|
+
- **Renaming left labels pointing at the old image.** The `<filename>` and
|
|
728
|
+
`<path>` fields inside the XML are now retargeted.
|
|
729
|
+
- **Perceptual dedup was O(n²).** ~112 million comparisons on a 15k-image set.
|
|
730
|
+
A BK-tree cuts it to roughly logarithmic per lookup, and decoding now runs
|
|
731
|
+
across threads.
|
|
732
|
+
- **Duplicate removal could discard the annotated copy.** `keep=annotated` now
|
|
733
|
+
keeps the labelled twin by default.
|
|
734
|
+
- **COCO `area` was always the box area,** even for polygons. It is now the true
|
|
735
|
+
polygon area.
|
|
736
|
+
- **Train/test splitting was documented but never implemented.** It exists now,
|
|
737
|
+
stratified and seeded.
|
|
738
|
+
|
|
739
|
+
---
|
|
740
|
+
|
|
741
|
+
## Tests
|
|
742
|
+
|
|
743
|
+
```bash
|
|
744
|
+
uv run pytest # 621 tests
|
|
745
|
+
```
|
|
746
|
+
|
|
747
|
+
Ten of those drive the annotation editor in a real browser and are skipped
|
|
748
|
+
unless Playwright is installed (`pip install playwright && playwright install
|
|
749
|
+
chromium`). A canvas tool with no automated test is one that quietly stops
|
|
750
|
+
working.
|
|
751
|
+
|
|
752
|
+
Fixtures build a small dataset carrying every defect the real one had: case
|
|
753
|
+
variant classes, both polygon dialects, a hard negative, an exact duplicate,
|
|
754
|
+
orphans of both kinds and a corrupt XML.
|
|
755
|
+
|
|
756
|
+
The format tests convert and read back, asserting on what survived — a
|
|
757
|
+
converter's failure mode is not a crash, it is arriving with fewer objects than
|
|
758
|
+
it left with. The geometry tests assert the annotation lands where the pixels
|
|
759
|
+
landed, which is the failure that silently ruins a dataset.
|
|
760
|
+
|
|
761
|
+
---
|
|
762
|
+
|
|
763
|
+
## Datasets in this repository
|
|
764
|
+
|
|
765
|
+
`Projects/Project_Door/` holds the door-state dataset (V3: 3686 images, 3871
|
|
766
|
+
objects) and `Models/Sam2.1_tiny/` the SAM 2.1 tiny checkpoint. Neither is
|
|
767
|
+
tracked by git.
|