drift-drought 0.1.2__py3-none-any.whl
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- drift_drought-0.1.2.dist-info/METADATA +264 -0
- drift_drought-0.1.2.dist-info/RECORD +13 -0
- drift_drought-0.1.2.dist-info/WHEEL +4 -0
- drift_drought-0.1.2.dist-info/licenses/LICENSE +21 -0
- driftdrought/__init__.py +10 -0
- driftdrought/baselines.py +123 -0
- driftdrought/confidence.py +97 -0
- driftdrought/core.py +443 -0
- driftdrought/data/amazon_orinoco_pulses.npz +0 -0
- driftdrought/indices.py +129 -0
- driftdrought/metrics.py +155 -0
- driftdrought/significance.py +101 -0
- driftdrought/synthetic.py +188 -0
|
@@ -0,0 +1,264 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: drift-drought
|
|
3
|
+
Version: 0.1.2
|
|
4
|
+
Summary: DRIFT: space-time drought events selected from the component tree of a deficit field
|
|
5
|
+
Project-URL: Documentation, https://drift-drought.readthedocs.io
|
|
6
|
+
Project-URL: Source, https://github.com/karelsanchez/drift-drought
|
|
7
|
+
Author-email: "Karel A. Sanchez H." <sanchezkarel@gmail.com>
|
|
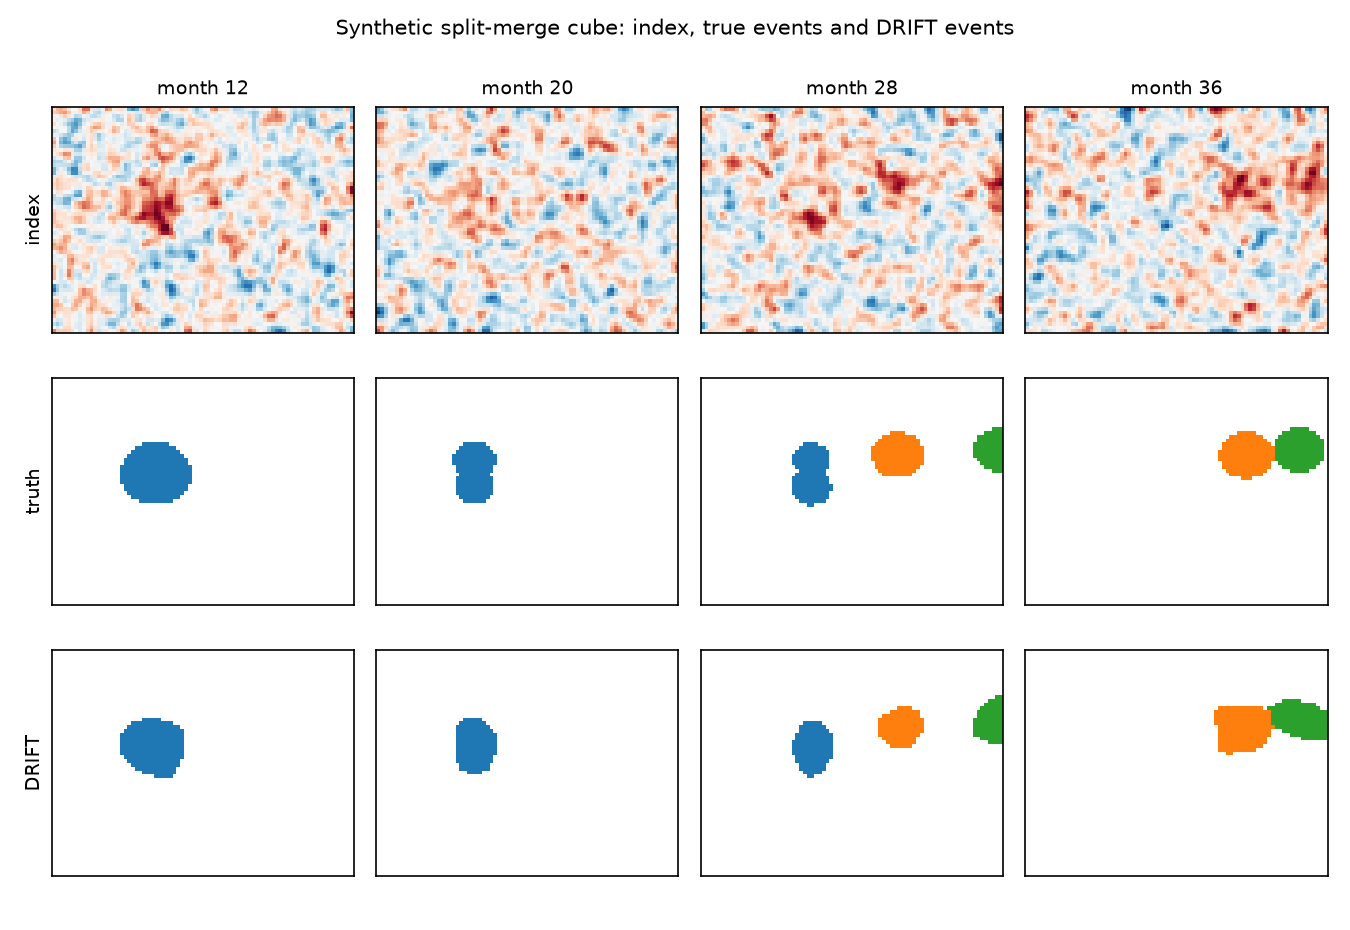
8
|
+
License: MIT License
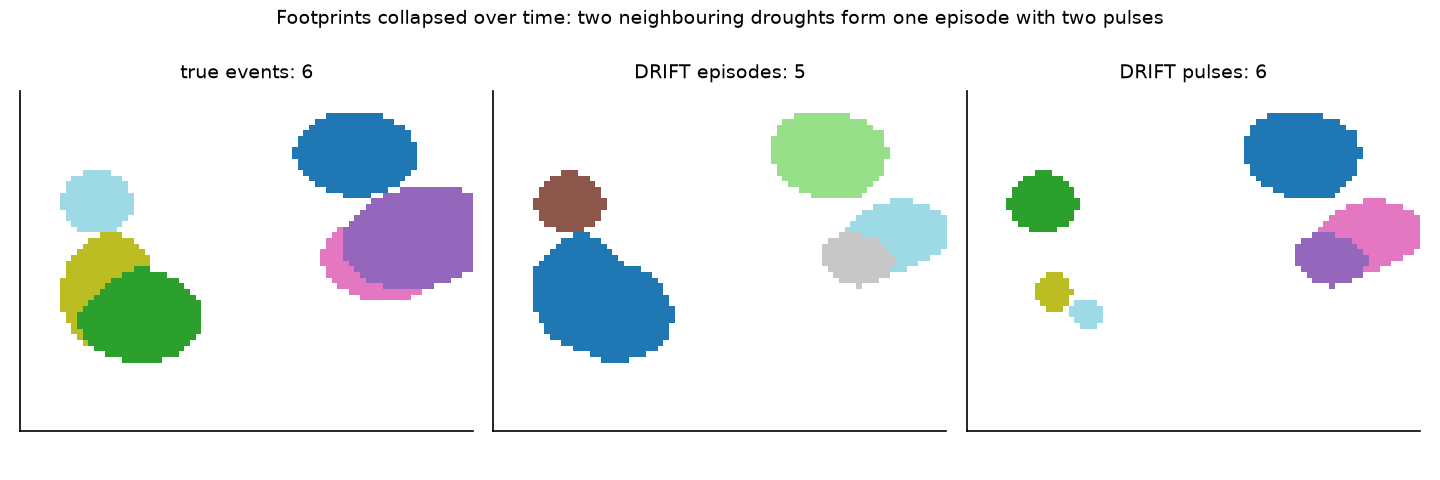
|
|
9
|
+
|
|
10
|
+
Copyright (c) 2026 Karel A. Sanchez H.
|
|
11
|
+
|
|
12
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
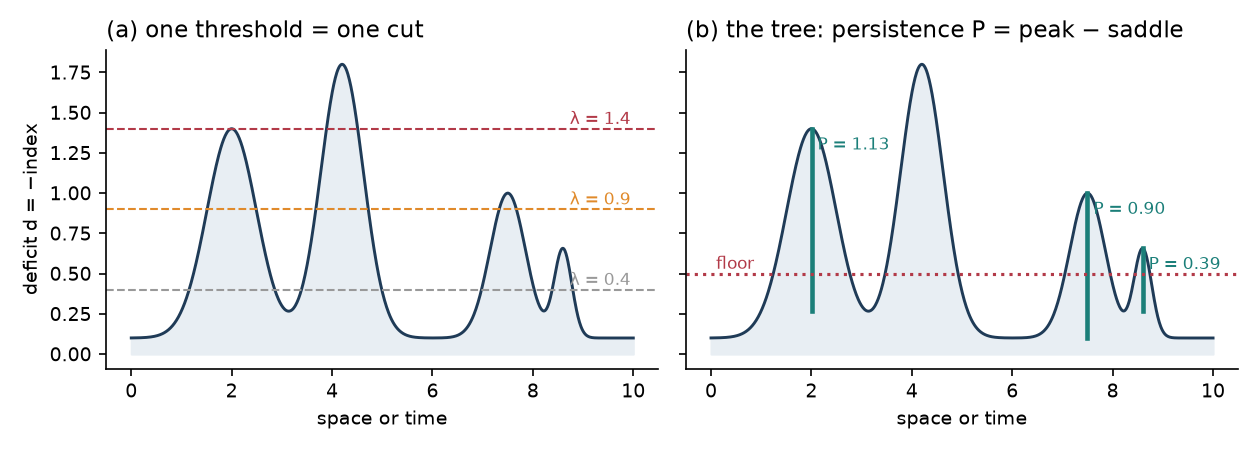
|
|
13
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
14
|
+
in the Software without restriction, including without limitation the rights
|
|
15
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
16
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
17
|
+
furnished to do so, subject to the following conditions:
|
|
18
|
+
|
|
19
|
+
The above copyright notice and this permission notice shall be included in all
|
|
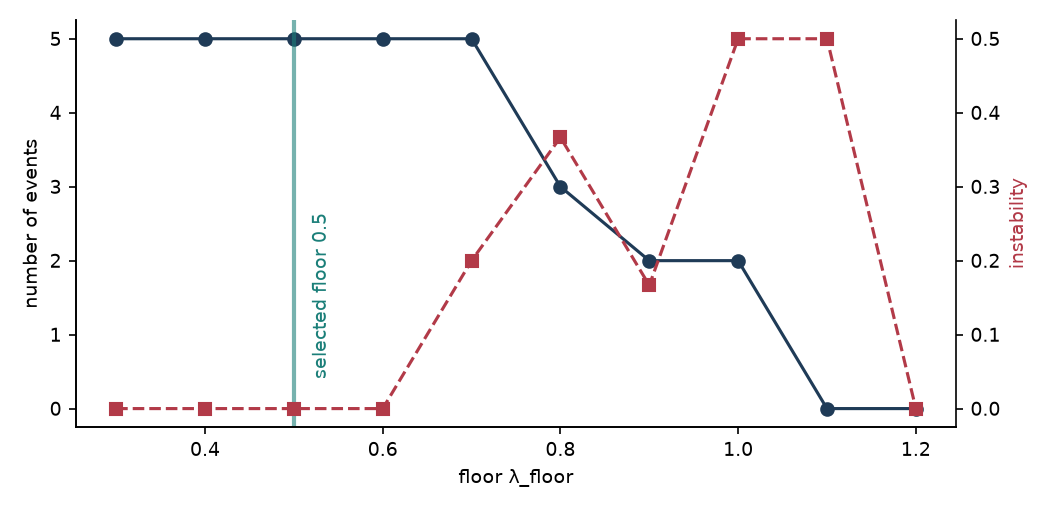
20
|
+
copies or substantial portions of the Software.
|
|
21
|
+
|
|
22
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
23
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
24
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
25
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
26
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
27
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
28
|
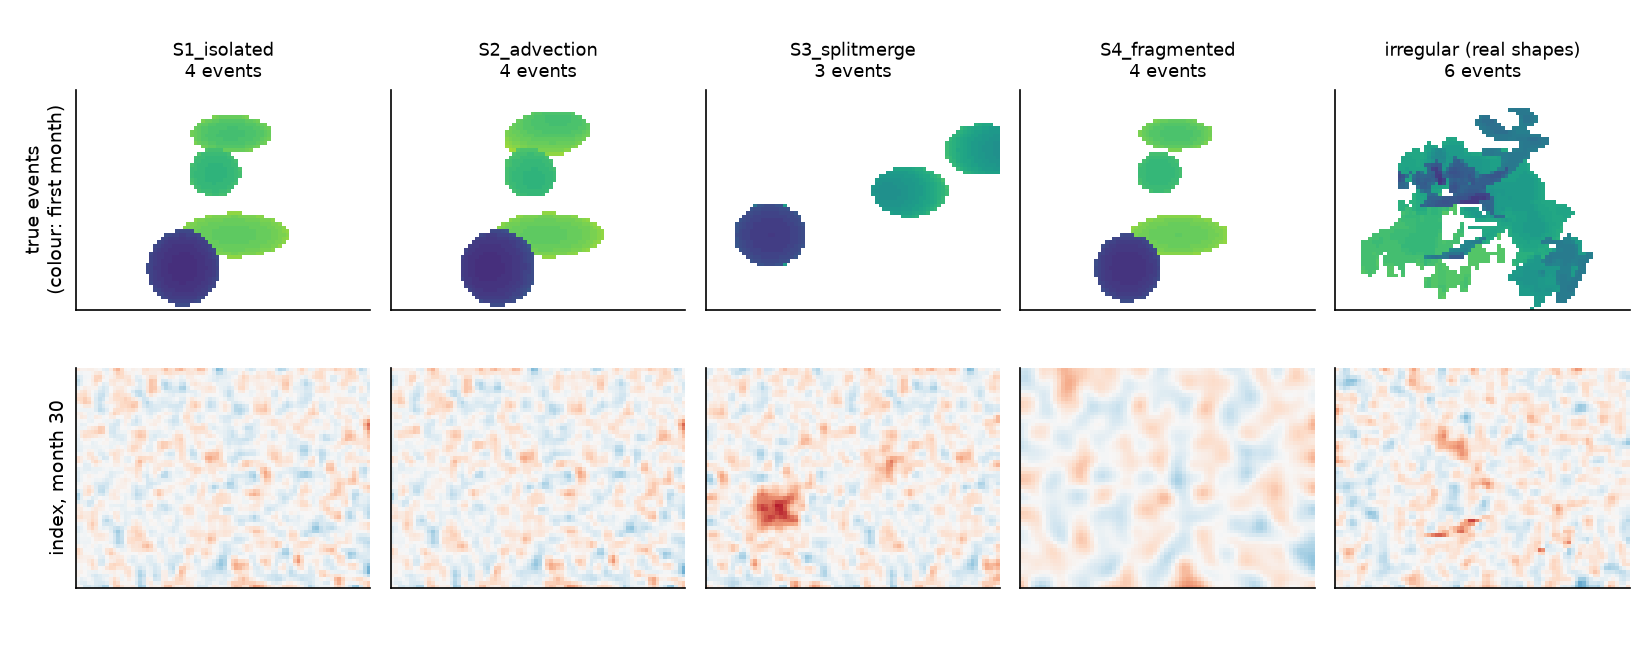
+
SOFTWARE.
|
|
29
|
+
License-File: LICENSE
|
|
30
|
+
Keywords: component tree,drought,event detection,hydrology,topological persistence,tracking
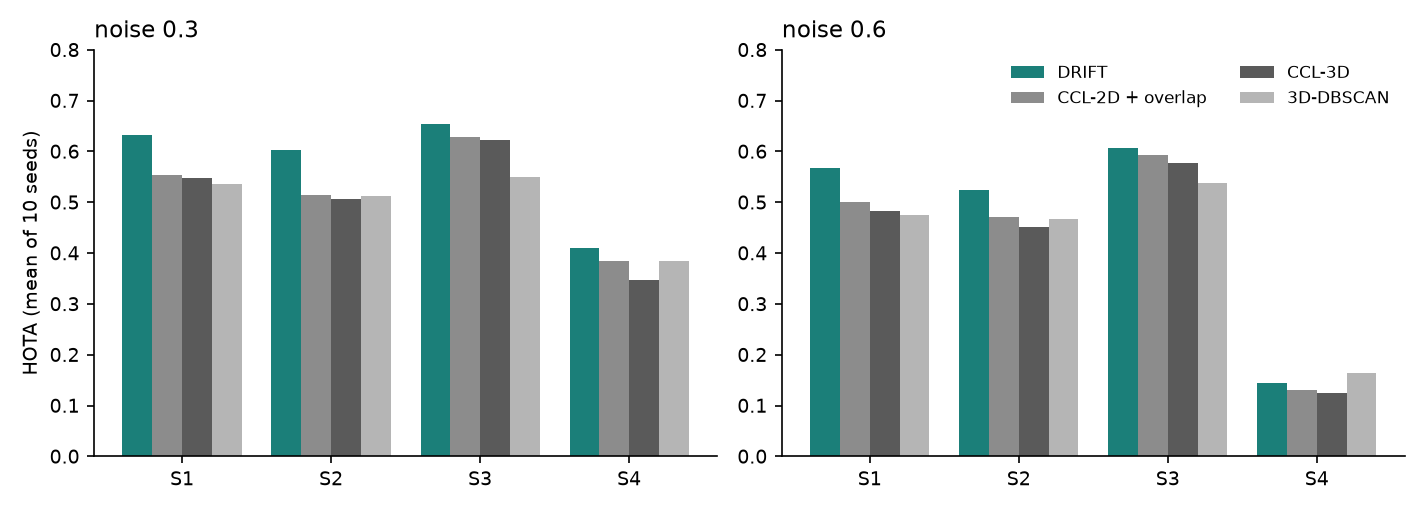
|
|
31
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
32
|
+
Classifier: Programming Language :: Python :: 3
|
|
33
|
+
Classifier: Topic :: Scientific/Engineering :: Atmospheric Science
|
|
34
|
+
Classifier: Topic :: Scientific/Engineering :: Hydrology
|
|
35
|
+
Requires-Python: >=3.10
|
|
36
|
+
Requires-Dist: higra>=0.6
|
|
37
|
+
Requires-Dist: numba>=0.58
|
|
38
|
+
Requires-Dist: numpy>=1.24
|
|
39
|
+
Requires-Dist: pandas>=2.0
|
|
40
|
+
Requires-Dist: scikit-image>=0.21
|
|
41
|
+
Requires-Dist: scikit-learn>=1.3
|
|
42
|
+
Requires-Dist: scipy>=1.10
|
|
43
|
+
Requires-Dist: xarray>=2023.1
|
|
44
|
+
Provides-Extra: docs
|
|
45
|
+
Requires-Dist: matplotlib>=3.7; extra == 'docs'
|
|
46
|
+
Requires-Dist: sphinx-rtd-theme>=2; extra == 'docs'
|
|
47
|
+
Requires-Dist: sphinx>=7; extra == 'docs'
|
|
48
|
+
Provides-Extra: plot
|
|
49
|
+
Requires-Dist: matplotlib>=3.7; extra == 'plot'
|
|
50
|
+
Provides-Extra: test
|
|
51
|
+
Requires-Dist: pytest>=7; extra == 'test'
|
|
52
|
+
Description-Content-Type: text/markdown
|
|
53
|
+
|
|
54
|
+
# DRIFT — drought events from the space–time component tree
|
|
55
|
+
|
|
56
|
+
[](https://github.com/karelsanchez/drift-drought/actions/workflows/tests.yml)
|
|
57
|
+
[](https://drift-drought.readthedocs.io)
|
|
58
|
+
[](https://github.com/karelsanchez/drift-drought/blob/main/LICENSE)
|
|
59
|
+
|
|
60
|
+
[](https://doi.org/10.5281/zenodo.24409548)
|
|
61
|
+
|
|
62
|
+
**DRIFT** (*Drought Regions Identified From the space–time component Tree*) detects drought events in gridded
|
|
63
|
+
standardized indices (SPI, SPEI, soil-moisture percentiles) **without fixing a single threshold**. It builds the
|
|
64
|
+
max-tree of the deficit field over time, latitude and longitude and selects events inside that hierarchy with
|
|
65
|
+
volume-weighted topological persistence, a noise-adaptive persistence threshold and lineage inheritance. One tree
|
|
66
|
+
gives two nested levels: drought **episodes** and the **pulses** they contain.
|
|
67
|
+
|
|
68
|
+
The package also provides everything needed to **test** a drought-event detector: a synthetic benchmark with known
|
|
69
|
+
events (Gaussian scenarios and irregular shapes from real droughts), three reference detectors, tracking metrics
|
|
70
|
+
(HOTA, object F1, partition agreement), event confidence and a surrogate significance test.
|
|
71
|
+
|
|
72
|
+
|
|
73
|
+
|
|
74
|
+
## Contents
|
|
75
|
+
|
|
76
|
+
- [Why DRIFT](#why-drift)
|
|
77
|
+
- [Installation](#installation)
|
|
78
|
+
- [Quickstart](#quickstart)
|
|
79
|
+
- [How it works](#how-it-works)
|
|
80
|
+
- [Evaluation metrics](#evaluation-metrics)
|
|
81
|
+
- [Benchmark](#benchmark)
|
|
82
|
+
- [Tests and validation](#tests-and-validation)
|
|
83
|
+
- [Package structure](#package-structure)
|
|
84
|
+
- [Documentation](#documentation) · [Citation](#citation) · [License](#license)
|
|
85
|
+
|
|
86
|
+
## Why DRIFT
|
|
87
|
+
|
|
88
|
+
A drought catalogue built by labelling connected cells below one threshold (for example SPI ≤ −1) changes with that
|
|
89
|
+
threshold: a strict one breaks droughts into pieces, a lenient one chains separate droughts into multi-year objects.
|
|
90
|
+
DRIFT keeps **all thresholds at once** in a component tree and lets each event take its own effective threshold:
|
|
91
|
+
|
|
92
|
+
|
|
93
|
+
|
|
94
|
+
*(a) Each threshold gives a different set of events. (b) In the tree, each maximum is a branch with a persistence
|
|
95
|
+
P = peak − saddle; shallow branches created by noise are absorbed, droughts separated by deep saddles are kept.*
|
|
96
|
+
|
|
97
|
+
## Installation
|
|
98
|
+
|
|
99
|
+
```bash
|
|
100
|
+
pip install drift-drought
|
|
101
|
+
```
|
|
102
|
+
|
|
103
|
+
Python ≥ 3.10. Dependencies: NumPy, SciPy, pandas, [Higra](https://higra.readthedocs.io) (component trees), Numba,
|
|
104
|
+
scikit-image, scikit-learn and xarray. Extras: `[plot]` (matplotlib), `[test]` (pytest), `[docs]` (Sphinx).
|
|
105
|
+
|
|
106
|
+
## Quickstart
|
|
107
|
+
|
|
108
|
+
```python
|
|
109
|
+
import numpy as np
|
|
110
|
+
import driftdrought as dd
|
|
111
|
+
|
|
112
|
+
# a benchmark cube (60 months x 60 x 80 cells): one drought splits, two converge
|
|
113
|
+
index, truth, meta = dd.synthetic.generate("S3_splitmerge", noise=0.6, seed=3)
|
|
114
|
+
area = np.ones(index.shape[1:]) # unit cells; dd.cell_area_km2() on a lat-lon grid
|
|
115
|
+
|
|
116
|
+
labels, info = dd.detect(dd.smooth(index, 2.5), area, v_min=50, floor=0.5,
|
|
117
|
+
footprint="watershed", ext_floor=0.5)
|
|
118
|
+
|
|
119
|
+
print(dd.metrics.hota(truth, labels, area)) # HOTA 0.574, DetA 0.628, AssA 0.525
|
|
120
|
+
print(dd.metrics.object_match(truth, labels, area, iou_thr=0.25)["f1_iou25"]) # 0.86
|
|
121
|
+
print(dd.event_table(labels, index, area)) # start, end, duration, volume, peak month...
|
|
122
|
+
```
|
|
123
|
+
|
|
124
|
+
On real data:
|
|
125
|
+
|
|
126
|
+
```python
|
|
127
|
+
spi3 = xr.open_dataset("spi3.nc").spi3 # (time, lat, lon), NaN over sea
|
|
128
|
+
area = dd.cell_area_km2(spi3.lat.values, 0.25)[:, None] * np.ones(spi3.lon.size)
|
|
129
|
+
area[np.isnan(spi3.values[0])] = 0
|
|
130
|
+
x = dd.smooth(spi3.values, 2.5)
|
|
131
|
+
floor, scan = dd.select_floor(x, area, v_min=2e6) # event-count stability rule
|
|
132
|
+
episodes, info = dd.detect(x, area, v_min=2e6, floor=floor) # km2 x months
|
|
133
|
+
pulses, _ = dd.detect(x, area, v_min=2e6, floor=floor, selection="leaf")
|
|
134
|
+
```
|
|
135
|
+
|
|
136
|
+
The complete script is [`examples/quickstart.py`](https://github.com/karelsanchez/drift-drought/blob/main/examples/quickstart.py).
|
|
137
|
+
|
|
138
|
+
## How it works
|
|
139
|
+
|
|
140
|
+
| Step | What DRIFT does | Parameter |
|
|
141
|
+
|---|---|---|
|
|
142
|
+
| 1. Deficit field | `d = −index`, optionally smoothed with a 3-D Gaussian | `smooth(index, sigma)` |
|
|
143
|
+
| 2. Component tree | max-tree of `d` with 26-connectivity in time and space | — |
|
|
144
|
+
| 3. Significant nodes | volume ≥ `v_min` and deficit ≥ `floor` | `v_min`, `floor` |
|
|
145
|
+
| 4. Persistence | branch persistence P = peak − saddle; branches with P < π are absorbed | `persistence="auto:k"`: π = k · 1.4826 · MAD of the high-pass residual |
|
|
146
|
+
| 5. Volume weighting | P_V = P · (V / v_min)^γ, so large droughts survive shallow saddles | `pers_gamma` (γ = 1) |
|
|
147
|
+
| 6. Lineage inheritance | an event born inside an older event (share ≥ q of its first footprint) takes its identity | `inherit` (q = 0.75) |
|
|
148
|
+
| 7. Footprint | birth component, or watershed growth into cells with deficit ≥ `ext_floor` | `footprint`, `ext_floor` |
|
|
149
|
+
| 8. Floor | the floor where the number of events is most stable | `select_floor` |
|
|
150
|
+
|
|
151
|
+
**Episodes and pulses.** `selection="persistence_vl"` (default) returns episodes; `selection="leaf"` returns the
|
|
152
|
+
pulses nested in them:
|
|
153
|
+
|
|
154
|
+
|
|
155
|
+
|
|
156
|
+
**Event attributes.** `confidence.parameter_confidence` gives each event a confidence (mean best IoU with runs of
|
|
157
|
+
perturbed parameters; with another precipitation product it becomes a *product confidence*), and
|
|
158
|
+
`significance.surrogate_test` tests each event against phase-randomized surrogates of the field (family-wise and
|
|
159
|
+
Benjamini–Hochberg p-values).
|
|
160
|
+
|
|
161
|
+
|
|
162
|
+
|
|
163
|
+
## Evaluation metrics
|
|
164
|
+
|
|
165
|
+
| Metric | Function | Meaning |
|
|
166
|
+
|---|---|---|
|
|
167
|
+
| **IoU** | — | area-weighted space–time intersection over union of a true and a detected event |
|
|
168
|
+
| **Precision, recall, F1** | `metrics.object_match` | one-to-one matching of events (Hungarian) with IoU ≥ 0.5; `f1_iou25` uses IoU ≥ 0.25 |
|
|
169
|
+
| **Mean IoU, volume error** | `metrics.object_match` | quality of the matched footprints |
|
|
170
|
+
| **Events detected vs true** | `metrics.object_match` (`n_pred`, `n_gt`) | exposes fragmentation (too many) and chaining (too few) |
|
|
171
|
+
| **HOTA** | `metrics.hota` | Higher Order Tracking Accuracy (Luiten et al., 2021): √(DetA · AssA), averaged over IoU thresholds 0.05–0.95 |
|
|
172
|
+
| **DetA** | `metrics.hota` | detection accuracy: drought cells found in the right months |
|
|
173
|
+
| **AssA** | `metrics.hota` | association accuracy: each drought keeps one identity through time |
|
|
174
|
+
| **ARI, VI** | `metrics.partition_agreement` | adjusted Rand index and variation of information between two partitions |
|
|
175
|
+
|
|
176
|
+
Equations and interpretation: [metrics page of the documentation](https://drift-drought.readthedocs.io/en/latest/metrics.html).
|
|
177
|
+
|
|
178
|
+
## Benchmark
|
|
179
|
+
|
|
180
|
+
`synthetic.generate` reproduces the known-truth cubes of the DRIFT article; `synthetic.generate_irregular` places
|
|
181
|
+
**real drought shapes** — from your own catalogue (`build_library`) or from the bundled library of 99 droughts of the
|
|
182
|
+
Amazon and Orinoco basins (`example_library`) — so DRIFT can be tuned to the scale of the target region.
|
|
183
|
+
|
|
184
|
+
|
|
185
|
+
|
|
186
|
+
| Scenario | What it tests |
|
|
187
|
+
|---|---|
|
|
188
|
+
| `S1_isolated` | recovery of separated events |
|
|
189
|
+
| `S2_advection` | continuity of migrating events |
|
|
190
|
+
| `S3_splitmerge` | identity through a split and two converging droughts |
|
|
191
|
+
| `S4_fragmented` | weak events on strongly correlated noise |
|
|
192
|
+
| irregular | non-convex, multi-core events with the geometry of observed droughts |
|
|
193
|
+
|
|
194
|
+
Mini benchmark (`examples/make_figures.py`: four scenarios × two noise levels × ten seeds, configurations selected in
|
|
195
|
+
the article):
|
|
196
|
+
|
|
197
|
+
|
|
198
|
+
|
|
199
|
+
| Method | HOTA (noise 0.3) | HOTA (noise 0.6) | AssA (0.6) | F1, IoU ≥ 0.25 (0.6) | Events detected (0.6; true 4.6) |
|
|
200
|
+
|---|---|---|---|---|---|
|
|
201
|
+
| **DRIFT** | **0.575** | **0.461** | **0.496** | **0.78** | 6.8 |
|
|
202
|
+
| CCL-2D + overlap | 0.520 | 0.424 | 0.460 | 0.67 | 10.8 |
|
|
203
|
+
| CCL-3D | 0.506 | 0.409 | 0.430 | 0.69 | 4.0 |
|
|
204
|
+
| 3D-DBSCAN | 0.496 | 0.411 | 0.447 | 0.68 | 5.3 |
|
|
205
|
+
|
|
206
|
+
In the article (20 seeds, held-out selection of every method) DRIFT reached HOTA 0.579 and 0.459 against at most 0.530
|
|
207
|
+
and 0.428, was best in seven of eight scenario–noise combinations and, re-tuned on irregular events from observed
|
|
208
|
+
droughts, remained best on average. Weak events in strongly correlated noise (S4) are hard for every method, and at
|
|
209
|
+
the smoothing that maximizes HOTA the split in S3 is not reported as a split (DRIFT keeps one identity instead).
|
|
210
|
+
|
|
211
|
+
## Tests and validation
|
|
212
|
+
|
|
213
|
+
The test suite runs on GitHub Actions for Python 3.10, 3.11 and 3.12 on every push.
|
|
214
|
+
|
|
215
|
+
| Test | What it checks |
|
|
216
|
+
|---|---|
|
|
217
|
+
| `test_generator_is_deterministic` | same scenario, noise and seed → same cube and truth |
|
|
218
|
+
| `test_detect_recovers_isolated_events` | HOTA > 0.4 and F1 (IoU ≥ 0.25) > 0.6 on isolated events |
|
|
219
|
+
| `test_all_selection_rules_run` | the five selection rules run and return events |
|
|
220
|
+
| `test_nan_cells_are_never_events` | cells outside the domain are never labelled |
|
|
221
|
+
| `test_merge_branches_joins_a_split` | lineage inheritance gives one identity to a lobe born inside an event |
|
|
222
|
+
| `test_baselines_and_confidence` | reference detectors run; a catalogue has confidence 1 against itself |
|
|
223
|
+
| `test_select_floor_returns_candidate` | the floor rule returns a candidate floor and the full scan |
|
|
224
|
+
| `test_surrogate_test_small` | the significance test returns valid family-wise and FDR p-values |
|
|
225
|
+
| `test_example_library` | the bundled real-shape library loads and builds cubes |
|
|
226
|
+
|
|
227
|
+
```bash
|
|
228
|
+
pip install -e ".[test]"
|
|
229
|
+
pytest -v
|
|
230
|
+
```
|
|
231
|
+
|
|
232
|
+
**Equivalence with the article.** Before release, `detect` was checked against the research implementation used in
|
|
233
|
+
the article on the four benchmark scenarios: the label cubes were identical voxel by voxel.
|
|
234
|
+
|
|
235
|
+
## Package structure
|
|
236
|
+
|
|
237
|
+
| Module | Contents |
|
|
238
|
+
|---|---|
|
|
239
|
+
| `driftdrought.core` | `detect`, `smooth`, `select_floor`, `event_table`, `merge_branches`, `cell_area_km2` |
|
|
240
|
+
| `driftdrought.indices` | SPI, SPEI and soil-moisture index fitted per calendar month |
|
|
241
|
+
| `driftdrought.synthetic` | benchmark cubes (S1–S4), `build_library`, `example_library`, `generate_irregular` |
|
|
242
|
+
| `driftdrought.baselines` | CCL-2D with overlap tracking, CCL-3D, 3D-DBSCAN |
|
|
243
|
+
| `driftdrought.metrics` | HOTA (DetA, AssA), object matching, partition agreement |
|
|
244
|
+
| `driftdrought.confidence` | event confidence against perturbed parameters or another input product |
|
|
245
|
+
| `driftdrought.significance` | phase-randomized surrogate test, family-wise and FDR p-values |
|
|
246
|
+
|
|
247
|
+
## Documentation
|
|
248
|
+
|
|
249
|
+
**https://drift-drought.readthedocs.io** — installation, quickstart, method with equations, metrics, benchmark, tests,
|
|
250
|
+
gallery and the full API reference generated from the docstrings.
|
|
251
|
+
|
|
252
|
+
## Citation
|
|
253
|
+
|
|
254
|
+
If you use DRIFT, please cite the software and the article (see `CITATION.cff`, or "Cite this repository" on GitHub):
|
|
255
|
+
|
|
256
|
+
> Sanchez H., K. A. (2026). *DRIFT: Drought Regions Identified From the space–time component Tree* (software).
|
|
257
|
+
> Zenodo. https://doi.org/10.5281/zenodo.24409548 (all versions; version 0.1.1: https://doi.org/10.5281/zenodo.24409549)
|
|
258
|
+
|
|
259
|
+
> Sanchez H., K. A. (2026). DRIFT for detecting and tracking spatiotemporal drought events with component trees.
|
|
260
|
+
> *Water Resources Research* (submitted).
|
|
261
|
+
|
|
262
|
+
## License
|
|
263
|
+
|
|
264
|
+
MIT © 2026 Karel A. Sanchez H. (see [LICENSE](https://github.com/karelsanchez/drift-drought/blob/main/LICENSE)).
|
|
@@ -0,0 +1,13 @@
|
|
|
1
|
+
driftdrought/__init__.py,sha256=1kYyrR9Zjdl8KuqJCViUNAlOUgXt2pUcji_rgLkH2_E,632
|
|
2
|
+
driftdrought/baselines.py,sha256=sEGJ4xGip04ahUKZwpBQAT5aOUraIfzpTMH9D-BsL08,4527
|
|
3
|
+
driftdrought/confidence.py,sha256=gMqLZUoBgJZpQKOXwTKfLuIHTKxnen1tRX3lQ4O5v54,3664
|
|
4
|
+
driftdrought/core.py,sha256=zUfSCRM8S5optTMtEi1BONJ-ypTC8BTZBWqLBr8OPJo,17604
|
|
5
|
+
driftdrought/indices.py,sha256=Tc9rPptYMJ5HuQYGgWeyx6lVeurKflzGQl9zehT-n4U,4916
|
|
6
|
+
driftdrought/metrics.py,sha256=ERdFtnC-WVw6XQgyRN3Q1wiD6dSOd68ssiJFl3fvoqY,6051
|
|
7
|
+
driftdrought/significance.py,sha256=Vqo-PWvKYBF_2iE0-l4CjY_HA_EeJUMfOoTdoHOH7Nk,4249
|
|
8
|
+
driftdrought/synthetic.py,sha256=Ppeh68rbrgGY4-sa7AoMaMVEez5thM3g6vSBrYORCaE,8002
|
|
9
|
+
driftdrought/data/amazon_orinoco_pulses.npz,sha256=s1KFutnSzaYgcgEK_eauaRpk-2vixP5eQ1cBSyBGyP4,411782
|
|
10
|
+
drift_drought-0.1.2.dist-info/METADATA,sha256=7hb4y6q8oBFfr75N7JhpiEW61DOHpcSinMpuqLOeKzc,14588
|
|
11
|
+
drift_drought-0.1.2.dist-info/WHEEL,sha256=2iZrJkDIkeDh0k9SikKMqFuRP-ua6mb4Ir1AsER4BEw,87
|
|
12
|
+
drift_drought-0.1.2.dist-info/licenses/LICENSE,sha256=n6VmFpiU9PYxqMBJBoUkei7gu07sePEjul5N6Zwj2rU,1076
|
|
13
|
+
drift_drought-0.1.2.dist-info/RECORD,,
|
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Karel A. Sanchez H.
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
driftdrought/__init__.py
ADDED
|
@@ -0,0 +1,10 @@
|
|
|
1
|
+
"""DRIFT — Drought Regions Identified From the space–time component Tree.
|
|
2
|
+
|
|
3
|
+
Detect, characterize and evaluate space–time drought events selected from the component tree of a deficit field.
|
|
4
|
+
"""
|
|
5
|
+
from . import baselines, confidence, indices, metrics, significance, synthetic
|
|
6
|
+
from .core import cell_area_km2, detect, event_table, merge_branches, noise_persistence, select_floor, smooth
|
|
7
|
+
|
|
8
|
+
__version__ = "0.1.2"
|
|
9
|
+
__all__ = ["detect", "smooth", "select_floor", "event_table", "merge_branches", "noise_persistence", "cell_area_km2",
|
|
10
|
+
"baselines", "confidence", "indices", "metrics", "significance", "synthetic", "__version__"]
|
|
@@ -0,0 +1,123 @@
|
|
|
1
|
+
"""Reference detectors used in the DRIFT benchmark.
|
|
2
|
+
|
|
3
|
+
* :func:`ccl2d_overlap` — monthly 8-connected patches linked across months by overlap (Andreadis et al., 2005).
|
|
4
|
+
* :func:`ccl3d` — 26-connected space–time components with a minimum volume (Lloyd-Hughes, 2012; Diaz et al., 2020).
|
|
5
|
+
* :func:`dbscan3d` — density-based clustering of drought voxels (Ester et al., 1996; Cammalleri & Toreti, 2023).
|
|
6
|
+
|
|
7
|
+
All take a standardized index ``(time, y, x)`` (drought negative, NaN outside the domain) and a threshold, and return
|
|
8
|
+
an integer label cube (0 = no event).
|
|
9
|
+
"""
|
|
10
|
+
import numpy as np
|
|
11
|
+
import pandas as pd
|
|
12
|
+
from scipy import ndimage
|
|
13
|
+
|
|
14
|
+
from .core import _relabel
|
|
15
|
+
|
|
16
|
+
__all__ = ["ccl2d_overlap", "ccl3d", "dbscan3d"]
|
|
17
|
+
|
|
18
|
+
|
|
19
|
+
def ccl2d_overlap(index, thr, cell_area, min_frac=0.016, overlap_frac=0.016):
|
|
20
|
+
"""Two-dimensional connected components linked through time by overlap.
|
|
21
|
+
|
|
22
|
+
Parameters
|
|
23
|
+
----------
|
|
24
|
+
index : numpy.ndarray
|
|
25
|
+
Index ``(time, y, x)``.
|
|
26
|
+
thr : float
|
|
27
|
+
Drought threshold (cells with ``index <= thr`` are dry).
|
|
28
|
+
cell_area : numpy.ndarray
|
|
29
|
+
Cell areas ``(y, x)``.
|
|
30
|
+
min_frac : float
|
|
31
|
+
Minimum patch area as a share of the domain area.
|
|
32
|
+
overlap_frac : float
|
|
33
|
+
Minimum overlap between patches of consecutive months, as a share of the domain area.
|
|
34
|
+
"""
|
|
35
|
+
dry = np.nan_to_num(index, nan=0.0) <= thr
|
|
36
|
+
land = np.isfinite(index[0])
|
|
37
|
+
area = np.broadcast_to(np.asarray(cell_area, float), index.shape[1:])
|
|
38
|
+
total = area[land].sum()
|
|
39
|
+
labels = np.zeros(index.shape, dtype=np.int64)
|
|
40
|
+
parent = {}
|
|
41
|
+
|
|
42
|
+
def find(a):
|
|
43
|
+
while parent[a] != a:
|
|
44
|
+
parent[a] = parent[parent[a]]
|
|
45
|
+
a = parent[a]
|
|
46
|
+
return a
|
|
47
|
+
|
|
48
|
+
nxt = 1
|
|
49
|
+
s8 = np.ones((3, 3), bool)
|
|
50
|
+
for t in range(index.shape[0]):
|
|
51
|
+
lab, n = ndimage.label(dry[t], structure=s8)
|
|
52
|
+
if n == 0:
|
|
53
|
+
continue
|
|
54
|
+
a = ndimage.sum(area, lab, index=np.arange(1, n + 1))
|
|
55
|
+
for k in np.where(a >= min_frac * total)[0] + 1:
|
|
56
|
+
labels[t][lab == k] = nxt
|
|
57
|
+
parent[nxt] = nxt
|
|
58
|
+
nxt += 1
|
|
59
|
+
if t == 0:
|
|
60
|
+
continue
|
|
61
|
+
prev, cur = labels[t - 1], labels[t]
|
|
62
|
+
both = (prev > 0) & (cur > 0)
|
|
63
|
+
if not both.any():
|
|
64
|
+
continue
|
|
65
|
+
ov = pd.DataFrame({"p": prev[both], "c": cur[both], "a": area[both]}).groupby(["p", "c"]).a.sum()
|
|
66
|
+
for (p, c), a in ov.items():
|
|
67
|
+
if a >= overlap_frac * total:
|
|
68
|
+
rp, rc = find(p), find(c)
|
|
69
|
+
if rp != rc:
|
|
70
|
+
parent[rc] = rp
|
|
71
|
+
if nxt > 1:
|
|
72
|
+
lut = np.zeros(nxt, dtype=np.int64)
|
|
73
|
+
for k in range(1, nxt):
|
|
74
|
+
lut[k] = find(k)
|
|
75
|
+
labels = lut[labels]
|
|
76
|
+
return _relabel(labels)
|
|
77
|
+
|
|
78
|
+
|
|
79
|
+
def ccl3d(index, thr, cell_area, min_volume_frac=0.0):
|
|
80
|
+
"""26-connected space–time components with a minimum volume.
|
|
81
|
+
|
|
82
|
+
Parameters
|
|
83
|
+
----------
|
|
84
|
+
min_volume_frac : float
|
|
85
|
+
Minimum event volume as a share of (domain area × one time step).
|
|
86
|
+
"""
|
|
87
|
+
dry = np.nan_to_num(index, nan=0.0) <= thr
|
|
88
|
+
lab, n = ndimage.label(dry, structure=np.ones((3, 3, 3), bool))
|
|
89
|
+
if n == 0 or min_volume_frac <= 0:
|
|
90
|
+
return lab.astype(np.int32)
|
|
91
|
+
land = np.isfinite(index[0])
|
|
92
|
+
area = np.broadcast_to(np.asarray(cell_area, float), index.shape[1:])
|
|
93
|
+
vol = ndimage.sum(np.broadcast_to(area, index.shape), lab, index=np.arange(1, n + 1))
|
|
94
|
+
keep = np.zeros(n + 1, bool)
|
|
95
|
+
keep[1:] = vol >= min_volume_frac * area[land].sum()
|
|
96
|
+
return _relabel(np.where(keep[lab], lab, 0))
|
|
97
|
+
|
|
98
|
+
|
|
99
|
+
def dbscan3d(index, thr, s_xy=3, s_t=3, fr_mp=0.25, c_min=50):
|
|
100
|
+
"""Density-based clustering (DBSCAN) of drought voxels in a scaled space–time window.
|
|
101
|
+
|
|
102
|
+
Parameters
|
|
103
|
+
----------
|
|
104
|
+
s_xy, s_t : int
|
|
105
|
+
Half-widths of the search window in cells and time steps.
|
|
106
|
+
fr_mp : float
|
|
107
|
+
Minimum share of the window that must be dry for a core point.
|
|
108
|
+
c_min : int
|
|
109
|
+
Minimum cluster size in voxels.
|
|
110
|
+
"""
|
|
111
|
+
from sklearn.cluster import DBSCAN
|
|
112
|
+
dry = np.nan_to_num(index, nan=0.0) <= thr
|
|
113
|
+
pts = np.argwhere(dry)
|
|
114
|
+
if len(pts) == 0:
|
|
115
|
+
return np.zeros(index.shape, np.int32)
|
|
116
|
+
scaled = pts / np.array([s_t, s_xy, s_xy], float)
|
|
117
|
+
win = (2 * s_t + 1) * (2 * s_xy + 1) ** 2
|
|
118
|
+
db = DBSCAN(eps=1.0, min_samples=max(1, int(round(fr_mp * win))), metric="chebyshev", algorithm="ball_tree").fit(scaled)
|
|
119
|
+
lab = np.zeros(index.shape, np.int64)
|
|
120
|
+
lab[tuple(pts.T)] = db.labels_ + 1
|
|
121
|
+
sizes = np.bincount(lab.ravel())
|
|
122
|
+
lab[np.isin(lab, np.where(sizes < c_min)[0])] = 0
|
|
123
|
+
return _relabel(lab)
|
|
@@ -0,0 +1,97 @@
|
|
|
1
|
+
"""Event confidence: how robust each event is to parameters or to the input product.
|
|
2
|
+
|
|
3
|
+
The confidence of event ``e`` is the mean, over ``K`` alternative catalogues ``L_k``, of the best space–time IoU between
|
|
4
|
+
``e`` and any event of ``L_k`` (Equation 9 of the DRIFT paper). With catalogues from perturbed parameters it measures
|
|
5
|
+
parameter robustness; with a catalogue from another precipitation product it is the *product confidence*.
|
|
6
|
+
"""
|
|
7
|
+
import numpy as np
|
|
8
|
+
|
|
9
|
+
from .core import detect
|
|
10
|
+
|
|
11
|
+
__all__ = ["best_iou", "event_confidence", "parameter_confidence", "consensus"]
|
|
12
|
+
|
|
13
|
+
|
|
14
|
+
def best_iou(ref, other):
|
|
15
|
+
"""Best IoU of every event of ``ref`` with any event of ``other``.
|
|
16
|
+
|
|
17
|
+
Parameters
|
|
18
|
+
----------
|
|
19
|
+
ref, other : numpy.ndarray of int
|
|
20
|
+
Label cubes of equal shape.
|
|
21
|
+
|
|
22
|
+
Returns
|
|
23
|
+
-------
|
|
24
|
+
numpy.ndarray
|
|
25
|
+
Array indexed by the event id of ``ref`` (entry 0 unused).
|
|
26
|
+
"""
|
|
27
|
+
r, m = ref.ravel().astype(np.int64), other.ravel().astype(np.int64)
|
|
28
|
+
n_r, n_m = int(r.max()) + 1, int(m.max()) + 1
|
|
29
|
+
both = (r > 0) & (m > 0)
|
|
30
|
+
inter = np.bincount(r[both] * n_m + m[both], minlength=n_r * n_m).reshape(n_r, n_m)
|
|
31
|
+
union = np.bincount(r, minlength=n_r)[:, None] + np.bincount(m, minlength=n_m)[None, :] - inter
|
|
32
|
+
with np.errstate(invalid="ignore", divide="ignore"):
|
|
33
|
+
iou = np.where(union > 0, inter / union, 0.0)
|
|
34
|
+
iou[:, 0] = 0.0
|
|
35
|
+
return iou.max(axis=1)
|
|
36
|
+
|
|
37
|
+
|
|
38
|
+
def event_confidence(ref, members):
|
|
39
|
+
"""Mean best IoU of each event of ``ref`` over the catalogues ``members``.
|
|
40
|
+
|
|
41
|
+
Returns
|
|
42
|
+
-------
|
|
43
|
+
dict
|
|
44
|
+
``{event_id: confidence}`` with values in [0, 1].
|
|
45
|
+
"""
|
|
46
|
+
conf = np.mean([best_iou(ref, m) for m in members], axis=0)
|
|
47
|
+
return {int(e): float(conf[e]) for e in np.unique(ref[ref > 0])}
|
|
48
|
+
|
|
49
|
+
|
|
50
|
+
def parameter_confidence(index, cell_area, v_min, floor, floors_delta=(-0.1, 0.1), sigma=None, smooth_deltas=(-0.5, 0.5),
|
|
51
|
+
**detect_kwargs):
|
|
52
|
+
"""Confidence of the events of a reference run against runs with perturbed floor (and smoothing).
|
|
53
|
+
|
|
54
|
+
Parameters
|
|
55
|
+
----------
|
|
56
|
+
index : numpy.ndarray
|
|
57
|
+
Raw (unsmoothed) index when ``sigma`` is given, otherwise the already smoothed index.
|
|
58
|
+
sigma : float, optional
|
|
59
|
+
Smoothing width of the reference run; when given, runs with ``sigma + smooth_deltas`` are added.
|
|
60
|
+
|
|
61
|
+
Returns
|
|
62
|
+
-------
|
|
63
|
+
labels : numpy.ndarray
|
|
64
|
+
Reference labels.
|
|
65
|
+
confidence : dict
|
|
66
|
+
``{event_id: confidence}``.
|
|
67
|
+
"""
|
|
68
|
+
from .core import smooth
|
|
69
|
+
base = smooth(index, sigma) if sigma else index
|
|
70
|
+
ref = detect(base, cell_area, v_min, floor, return_info=False, **detect_kwargs)
|
|
71
|
+
members = []
|
|
72
|
+
sigmas = [sigma] + ([sigma + d for d in smooth_deltas] if sigma else [])
|
|
73
|
+
for s in sigmas:
|
|
74
|
+
x = smooth(index, s) if s else index
|
|
75
|
+
for df in (0.0,) + tuple(floors_delta):
|
|
76
|
+
if s == sigma and df == 0.0:
|
|
77
|
+
continue
|
|
78
|
+
members.append(detect(x, cell_area, v_min, floor + df, return_info=False, **detect_kwargs))
|
|
79
|
+
return ref, event_confidence(ref, members)
|
|
80
|
+
|
|
81
|
+
|
|
82
|
+
def consensus(ref, members, q=0.5):
|
|
83
|
+
"""Consensus footprint: cells of ``ref`` labelled as drought in at least a share ``q`` of ``members``.
|
|
84
|
+
|
|
85
|
+
Returns
|
|
86
|
+
-------
|
|
87
|
+
labels : numpy.ndarray
|
|
88
|
+
Consensus labels (events emptied by the rule are dropped).
|
|
89
|
+
confidence : dict
|
|
90
|
+
Event confidence of the remaining events.
|
|
91
|
+
frequency : numpy.ndarray
|
|
92
|
+
Share of members that label each cell.
|
|
93
|
+
"""
|
|
94
|
+
freq = np.mean([m > 0 for m in members], axis=0)
|
|
95
|
+
lab = np.where(freq >= q, ref, 0).astype(np.int32)
|
|
96
|
+
conf = event_confidence(ref, members)
|
|
97
|
+
return lab, {e: c for e, c in conf.items() if (lab == e).any()}, freq
|