costplan 0.1.0__py3-none-any.whl
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- costplan/__init__.py +36 -0
- costplan/_stats.py +109 -0
- costplan/cli.py +165 -0
- costplan/loading.py +264 -0
- costplan/planning.py +416 -0
- costplan-0.1.0.dist-info/METADATA +229 -0
- costplan-0.1.0.dist-info/RECORD +11 -0
- costplan-0.1.0.dist-info/WHEEL +5 -0
- costplan-0.1.0.dist-info/entry_points.txt +2 -0
- costplan-0.1.0.dist-info/licenses/LICENSE +21 -0
- costplan-0.1.0.dist-info/top_level.txt +1 -0
costplan/__init__.py
ADDED
|
@@ -0,0 +1,36 @@
|
|
|
1
|
+
"""How much will my agent cost? Plan agent budgets from a handful of pilot runs."""
|
|
2
|
+
|
|
3
|
+
from .loading import LoadedRuns, load_runs
|
|
4
|
+
from .planning import (
|
|
5
|
+
CapAdvice,
|
|
6
|
+
CostComparison,
|
|
7
|
+
CostSummary,
|
|
8
|
+
SpendProjection,
|
|
9
|
+
compare_cost_per_success,
|
|
10
|
+
guaranteed_stop_rate,
|
|
11
|
+
pilot_runs_for_average,
|
|
12
|
+
project_spend,
|
|
13
|
+
recommend_cap,
|
|
14
|
+
run_cost,
|
|
15
|
+
runs_needed_for_cap,
|
|
16
|
+
summarize,
|
|
17
|
+
)
|
|
18
|
+
|
|
19
|
+
__all__ = [
|
|
20
|
+
"load_runs",
|
|
21
|
+
"LoadedRuns",
|
|
22
|
+
"run_cost",
|
|
23
|
+
"summarize",
|
|
24
|
+
"recommend_cap",
|
|
25
|
+
"runs_needed_for_cap",
|
|
26
|
+
"guaranteed_stop_rate",
|
|
27
|
+
"pilot_runs_for_average",
|
|
28
|
+
"project_spend",
|
|
29
|
+
"compare_cost_per_success",
|
|
30
|
+
"CostSummary",
|
|
31
|
+
"CapAdvice",
|
|
32
|
+
"SpendProjection",
|
|
33
|
+
"CostComparison",
|
|
34
|
+
]
|
|
35
|
+
|
|
36
|
+
__version__ = "0.1.0"
|
costplan/_stats.py
ADDED
|
@@ -0,0 +1,109 @@
|
|
|
1
|
+
"""Small statistics helpers built on the standard library only."""
|
|
2
|
+
|
|
3
|
+
from __future__ import annotations
|
|
4
|
+
|
|
5
|
+
import math
|
|
6
|
+
import random
|
|
7
|
+
from statistics import NormalDist
|
|
8
|
+
from typing import Callable, List, Optional, Sequence, Tuple
|
|
9
|
+
|
|
10
|
+
_NORMAL = NormalDist()
|
|
11
|
+
|
|
12
|
+
|
|
13
|
+
def check_level(value: float, name: str) -> None:
|
|
14
|
+
if not 0 < value < 1:
|
|
15
|
+
raise ValueError(f"{name} must be strictly between 0 and 1, got {value!r}")
|
|
16
|
+
|
|
17
|
+
|
|
18
|
+
def z_two_sided(confidence: float) -> float:
|
|
19
|
+
return _NORMAL.inv_cdf(1 - (1 - confidence) / 2)
|
|
20
|
+
|
|
21
|
+
|
|
22
|
+
def wilson(successes: int, n: int, confidence: float) -> Tuple[float, float]:
|
|
23
|
+
z = z_two_sided(confidence)
|
|
24
|
+
p = successes / n
|
|
25
|
+
denom = 1 + z * z / n
|
|
26
|
+
centre = (p + z * z / (2 * n)) / denom
|
|
27
|
+
half = z / denom * math.sqrt(p * (1 - p) / n + z * z / (4 * n * n))
|
|
28
|
+
return max(0.0, centre - half), min(1.0, centre + half)
|
|
29
|
+
|
|
30
|
+
|
|
31
|
+
def binom_cdf_table(n: int, p: float) -> List[float]:
|
|
32
|
+
"""[P(X <= k) for k = 0..n] for X ~ Binomial(n, p), computed in log space."""
|
|
33
|
+
if p <= 0:
|
|
34
|
+
return [1.0] * (n + 1)
|
|
35
|
+
if p >= 1:
|
|
36
|
+
return [0.0] * n + [1.0]
|
|
37
|
+
log_p, log_q = math.log(p), math.log1p(-p)
|
|
38
|
+
log_n = math.lgamma(n + 1)
|
|
39
|
+
table, total = [], 0.0
|
|
40
|
+
for i in range(n + 1):
|
|
41
|
+
total += math.exp(log_n - math.lgamma(i + 1) - math.lgamma(n - i + 1) + i * log_p + (n - i) * log_q)
|
|
42
|
+
table.append(min(1.0, total))
|
|
43
|
+
return table
|
|
44
|
+
|
|
45
|
+
|
|
46
|
+
def quantile(sorted_values: Sequence[float], p: float) -> float:
|
|
47
|
+
"""Linear interpolation quantile (the usual default in numpy and pandas)."""
|
|
48
|
+
n = len(sorted_values)
|
|
49
|
+
if n == 1:
|
|
50
|
+
return sorted_values[0]
|
|
51
|
+
pos = p * (n - 1)
|
|
52
|
+
lo = math.floor(pos)
|
|
53
|
+
hi = min(lo + 1, n - 1)
|
|
54
|
+
return sorted_values[lo] + (sorted_values[hi] - sorted_values[lo]) * (pos - lo)
|
|
55
|
+
|
|
56
|
+
|
|
57
|
+
def quantile_interval(
|
|
58
|
+
sorted_values: Sequence[float], p: float, confidence: float
|
|
59
|
+
) -> Tuple[Optional[float], Optional[float]]:
|
|
60
|
+
"""Distribution-free interval for the p-th quantile from order statistics.
|
|
61
|
+
|
|
62
|
+
Makes no assumption about the shape of the cost distribution. Either end
|
|
63
|
+
is None when there are too few runs to bound it at this confidence.
|
|
64
|
+
"""
|
|
65
|
+
n = len(sorted_values)
|
|
66
|
+
cdf = binom_cdf_table(n, p)
|
|
67
|
+
tail = (1 - confidence) / 2
|
|
68
|
+
low = None
|
|
69
|
+
for k in range(n, 0, -1): # largest k with P(X_(k) > q) at most the tail
|
|
70
|
+
if cdf[k - 1] <= tail:
|
|
71
|
+
low = sorted_values[k - 1]
|
|
72
|
+
break
|
|
73
|
+
high = upper_quantile_bound(sorted_values, p, 1 - tail, cdf)
|
|
74
|
+
return low, high
|
|
75
|
+
|
|
76
|
+
|
|
77
|
+
def upper_quantile_bound(
|
|
78
|
+
sorted_values: Sequence[float], p: float, confidence: float, cdf: Optional[List[float]] = None
|
|
79
|
+
) -> Optional[float]:
|
|
80
|
+
"""Smallest order statistic that is above the p-th quantile with the given confidence."""
|
|
81
|
+
n = len(sorted_values)
|
|
82
|
+
cdf = cdf or binom_cdf_table(n, p)
|
|
83
|
+
for k in range(1, n + 1):
|
|
84
|
+
if cdf[k - 1] >= confidence:
|
|
85
|
+
return sorted_values[k - 1]
|
|
86
|
+
return None
|
|
87
|
+
|
|
88
|
+
|
|
89
|
+
def bootstrap_interval(
|
|
90
|
+
columns: Sequence[Sequence],
|
|
91
|
+
statistic: Callable[..., Optional[float]],
|
|
92
|
+
confidence: float,
|
|
93
|
+
resamples: int,
|
|
94
|
+
seed: int,
|
|
95
|
+
) -> Tuple[float, float]:
|
|
96
|
+
"""Percentile bootstrap, resampling rows of the given columns together."""
|
|
97
|
+
rng = random.Random(seed)
|
|
98
|
+
n = len(columns[0])
|
|
99
|
+
values: List[float] = []
|
|
100
|
+
for _ in range(resamples):
|
|
101
|
+
idx = [rng.randrange(n) for _ in range(n)]
|
|
102
|
+
value = statistic(*[[col[i] for i in idx] for col in columns])
|
|
103
|
+
if value is not None and math.isfinite(value):
|
|
104
|
+
values.append(value)
|
|
105
|
+
if not values:
|
|
106
|
+
return float("nan"), float("nan")
|
|
107
|
+
values.sort()
|
|
108
|
+
tail = (1 - confidence) / 2
|
|
109
|
+
return quantile(values, tail), quantile(values, 1 - tail)
|
costplan/cli.py
ADDED
|
@@ -0,0 +1,165 @@
|
|
|
1
|
+
"""Command line: ``costplan summary``, ``costplan cap``, ``costplan project`` and more."""
|
|
2
|
+
|
|
3
|
+
from __future__ import annotations
|
|
4
|
+
|
|
5
|
+
import argparse
|
|
6
|
+
import csv
|
|
7
|
+
import sys
|
|
8
|
+
from typing import List, Optional, Tuple
|
|
9
|
+
|
|
10
|
+
from . import (
|
|
11
|
+
LoadedRuns,
|
|
12
|
+
compare_cost_per_success,
|
|
13
|
+
load_runs,
|
|
14
|
+
guaranteed_stop_rate,
|
|
15
|
+
pilot_runs_for_average,
|
|
16
|
+
project_spend,
|
|
17
|
+
recommend_cap,
|
|
18
|
+
runs_needed_for_cap,
|
|
19
|
+
summarize,
|
|
20
|
+
)
|
|
21
|
+
|
|
22
|
+
def read_runs(path: str, args: argparse.Namespace) -> Tuple[List[float], Optional[List[bool]]]:
|
|
23
|
+
loaded = _load(path, args)
|
|
24
|
+
return loaded.costs, loaded.successes
|
|
25
|
+
|
|
26
|
+
|
|
27
|
+
def _load(path: str, args: argparse.Namespace, group_by: Optional[str] = None) -> LoadedRuns:
|
|
28
|
+
loaded = load_runs(
|
|
29
|
+
path,
|
|
30
|
+
cost=args.cost_column,
|
|
31
|
+
input_tokens=args.input_column,
|
|
32
|
+
output_tokens=args.output_column,
|
|
33
|
+
success=args.success_column,
|
|
34
|
+
group_by=group_by if group_by is not None else args.group_by,
|
|
35
|
+
input_price=args.input_price,
|
|
36
|
+
output_price=args.output_price,
|
|
37
|
+
cached_price=args.cached_price,
|
|
38
|
+
)
|
|
39
|
+
if args.verbose:
|
|
40
|
+
print(loaded.report(), file=sys.stderr)
|
|
41
|
+
return loaded
|
|
42
|
+
|
|
43
|
+
|
|
44
|
+
def _cmd_summary(args: argparse.Namespace) -> str:
|
|
45
|
+
costs, flags = read_runs(args.file, args)
|
|
46
|
+
return summarize(costs, flags, args.confidence).summary()
|
|
47
|
+
|
|
48
|
+
|
|
49
|
+
def _cmd_cap(args: argparse.Namespace) -> str:
|
|
50
|
+
costs, _ = read_runs(args.file, args)
|
|
51
|
+
return recommend_cap(costs, args.stop_rate, args.confidence).summary()
|
|
52
|
+
|
|
53
|
+
|
|
54
|
+
def _cmd_project(args: argparse.Namespace) -> str:
|
|
55
|
+
costs, _ = read_runs(args.file, args)
|
|
56
|
+
return project_spend(costs, args.runs, args.confidence).summary()
|
|
57
|
+
|
|
58
|
+
|
|
59
|
+
def _cmd_compare(args: argparse.Namespace) -> str:
|
|
60
|
+
key = args.task_column
|
|
61
|
+
if args.paired and key and not args.group_by:
|
|
62
|
+
# Group by the task column so the two files can be lined up task by task.
|
|
63
|
+
a, b = _load(args.file_a, args, key), _load(args.file_b, args, key)
|
|
64
|
+
else:
|
|
65
|
+
a, b = _load(args.file_a, args), _load(args.file_b, args)
|
|
66
|
+
if a.successes is None or b.successes is None:
|
|
67
|
+
raise ValueError("both files need a success, status or error column to compare cost per success")
|
|
68
|
+
a_costs, a_flags, b_costs, b_flags = a.costs, a.successes, b.costs, b.successes
|
|
69
|
+
if args.paired and a.run_ids is not None and b.run_ids is not None:
|
|
70
|
+
b_index = {run: i for i, run in enumerate(b.run_ids)}
|
|
71
|
+
shared = [i for i, run in enumerate(a.run_ids) if run in b_index]
|
|
72
|
+
if len(shared) < 2:
|
|
73
|
+
raise ValueError("the two files share fewer than two task ids")
|
|
74
|
+
a_costs = [a.costs[i] for i in shared]
|
|
75
|
+
a_flags = [a.successes[i] for i in shared]
|
|
76
|
+
b_costs = [b.costs[b_index[a.run_ids[i]]] for i in shared]
|
|
77
|
+
b_flags = [b.successes[b_index[a.run_ids[i]]] for i in shared]
|
|
78
|
+
names = tuple(args.names) if args.names else (args.file_a, args.file_b)
|
|
79
|
+
return compare_cost_per_success(
|
|
80
|
+
a_costs, a_flags, b_costs, b_flags, names, paired=args.paired, confidence=args.confidence
|
|
81
|
+
).summary()
|
|
82
|
+
|
|
83
|
+
|
|
84
|
+
def _cmd_pilot(args: argparse.Namespace) -> str:
|
|
85
|
+
lines = []
|
|
86
|
+
n = runs_needed_for_cap(args.stop_rate, args.confidence)
|
|
87
|
+
lines.append(
|
|
88
|
+
f"To set a cap that stops at most {args.stop_rate:.1%} of normal runs ({args.confidence:.0%} confidence): "
|
|
89
|
+
f"{n} pilot runs."
|
|
90
|
+
)
|
|
91
|
+
for size in (20, 50, 100):
|
|
92
|
+
if size < n:
|
|
93
|
+
lines.append(f" With {size} runs, the best promise is {guaranteed_stop_rate(size, args.confidence):.1%}.")
|
|
94
|
+
if args.spread is not None:
|
|
95
|
+
m = pilot_runs_for_average(args.spread, args.margin, args.confidence)
|
|
96
|
+
lines.append(f"To pin the average cost to within {args.margin:.0%} (spread {args.spread:g}): {m} pilot runs.")
|
|
97
|
+
return "\n".join(lines)
|
|
98
|
+
|
|
99
|
+
|
|
100
|
+
def build_parser() -> argparse.ArgumentParser:
|
|
101
|
+
parser = argparse.ArgumentParser(
|
|
102
|
+
prog="costplan",
|
|
103
|
+
description="How much will my agent cost? Plan budgets, caps and spend from pilot runs.",
|
|
104
|
+
)
|
|
105
|
+
sub = parser.add_subparsers(dest="command", required=True)
|
|
106
|
+
|
|
107
|
+
def file_options(p: argparse.ArgumentParser) -> None:
|
|
108
|
+
p.add_argument("--cost-column", help="column with each row's dollar cost (found automatically if left out)")
|
|
109
|
+
p.add_argument("--input-column", help="column with input tokens (found automatically if left out)")
|
|
110
|
+
p.add_argument("--output-column", help="column with output tokens (found automatically if left out)")
|
|
111
|
+
p.add_argument("--success-column", help="column with pass/fail (found automatically if left out)")
|
|
112
|
+
p.add_argument("--group-by", help="column naming the run each row belongs to, for exports with one row per model call")
|
|
113
|
+
p.add_argument("-v", "--verbose", action="store_true", help="say which columns were used")
|
|
114
|
+
p.add_argument("--input-price", type=float, help="dollars per million input tokens, if the file has tokens not costs")
|
|
115
|
+
p.add_argument("--output-price", type=float, help="dollars per million output tokens")
|
|
116
|
+
p.add_argument("--cached-price", type=float, help="dollars per million cached input tokens")
|
|
117
|
+
p.add_argument("--confidence", type=float, default=0.95)
|
|
118
|
+
|
|
119
|
+
p = sub.add_parser("summary", help="average, typical and expensive runs, success rate, cost per success")
|
|
120
|
+
p.add_argument("file", help="CSV with one row per pilot run")
|
|
121
|
+
file_options(p)
|
|
122
|
+
p.set_defaults(run=_cmd_summary)
|
|
123
|
+
|
|
124
|
+
p = sub.add_parser("cap", help="what per-run budget cap to set")
|
|
125
|
+
p.add_argument("file")
|
|
126
|
+
p.add_argument("--stop-rate", type=float, default=0.02, help="largest share of normal runs the cap may stop")
|
|
127
|
+
file_options(p)
|
|
128
|
+
p.set_defaults(run=_cmd_cap)
|
|
129
|
+
|
|
130
|
+
p = sub.add_parser("project", help="total spend for a number of future runs")
|
|
131
|
+
p.add_argument("file")
|
|
132
|
+
p.add_argument("--runs", type=int, required=True, help="number of future runs, e.g. a month of traffic")
|
|
133
|
+
file_options(p)
|
|
134
|
+
p.set_defaults(run=_cmd_project)
|
|
135
|
+
|
|
136
|
+
p = sub.add_parser("compare", help="which setup is cheaper per successful task")
|
|
137
|
+
p.add_argument("file_a")
|
|
138
|
+
p.add_argument("file_b")
|
|
139
|
+
p.add_argument("--names", nargs=2, metavar=("A", "B"))
|
|
140
|
+
p.add_argument("--paired", action="store_true", help="both files ran the same tasks; compare task by task")
|
|
141
|
+
p.add_argument("--task-column", help="column with a task id, to line up the two files when --paired")
|
|
142
|
+
file_options(p)
|
|
143
|
+
p.set_defaults(run=_cmd_compare)
|
|
144
|
+
|
|
145
|
+
p = sub.add_parser("pilot", help="how many pilot runs to collect")
|
|
146
|
+
p.add_argument("--stop-rate", type=float, default=0.02)
|
|
147
|
+
p.add_argument("--spread", type=float, help="cost spread (standard deviation / average), from a small pilot")
|
|
148
|
+
p.add_argument("--margin", type=float, default=0.10, help="relative precision wanted for the average")
|
|
149
|
+
p.add_argument("--confidence", type=float, default=0.95)
|
|
150
|
+
p.set_defaults(run=_cmd_pilot)
|
|
151
|
+
return parser
|
|
152
|
+
|
|
153
|
+
|
|
154
|
+
def main(argv: Optional[List[str]] = None) -> int:
|
|
155
|
+
args = build_parser().parse_args(argv)
|
|
156
|
+
try:
|
|
157
|
+
print(args.run(args))
|
|
158
|
+
except (ValueError, OSError) as exc:
|
|
159
|
+
print(f"costplan: {exc}", file=sys.stderr)
|
|
160
|
+
return 2
|
|
161
|
+
return 0
|
|
162
|
+
|
|
163
|
+
|
|
164
|
+
if __name__ == "__main__":
|
|
165
|
+
sys.exit(main())
|
costplan/loading.py
ADDED
|
@@ -0,0 +1,264 @@
|
|
|
1
|
+
"""Read run costs straight from tracing and usage exports.
|
|
2
|
+
|
|
3
|
+
Exports come in two shapes:
|
|
4
|
+
|
|
5
|
+
* **One row per run** (a trace, a session, a task), with the run's total
|
|
6
|
+
cost already added up. Load it as it is.
|
|
7
|
+
* **One row per model call**, with a column naming the run each call belongs
|
|
8
|
+
to. Pass ``group_by`` with that column, and the calls are added up into runs.
|
|
9
|
+
|
|
10
|
+
Do not group an export that already has run totals, or the same cost is
|
|
11
|
+
counted twice. Some tools export both a run and its calls in one file; filter
|
|
12
|
+
it to one or the other first.
|
|
13
|
+
|
|
14
|
+
Column names are found automatically from common spellings (for example
|
|
15
|
+
``cost``, ``total_cost``, ``totalCost``, ``calculatedTotalCost``,
|
|
16
|
+
``prompt_tokens``, ``input_tokens``, ``usage.input``, ``trace_id``,
|
|
17
|
+
``traceId``). Pass the column names yourself whenever the guess is wrong.
|
|
18
|
+
"""
|
|
19
|
+
|
|
20
|
+
from __future__ import annotations
|
|
21
|
+
|
|
22
|
+
import csv
|
|
23
|
+
import json
|
|
24
|
+
import re
|
|
25
|
+
from dataclasses import dataclass, field
|
|
26
|
+
from pathlib import Path
|
|
27
|
+
from typing import Any, Dict, Iterable, List, Optional, Tuple
|
|
28
|
+
|
|
29
|
+
from .planning import run_cost
|
|
30
|
+
|
|
31
|
+
COST_NAMES = ["cost", "totalcost", "calculatedtotalcost", "costusd", "usd", "totalcostusd"]
|
|
32
|
+
INPUT_NAMES = ["inputtokens", "prompttokens", "usageinput", "usageinputtokens", "usageprompttokens"]
|
|
33
|
+
OUTPUT_NAMES = ["outputtokens", "completiontokens", "usageoutput", "usageoutputtokens", "usagecompletiontokens"]
|
|
34
|
+
CACHED_NAMES = ["cachedtokens", "cachereadinputtokens", "cachereadtokens"]
|
|
35
|
+
SUCCESS_NAMES = ["success", "succeeded", "passed", "pass", "issuccess", "ok"]
|
|
36
|
+
STATUS_NAMES = ["status"]
|
|
37
|
+
ERROR_NAMES = ["error"]
|
|
38
|
+
|
|
39
|
+
_TRUE = {"1", "true", "t", "yes", "y", "pass", "passed", "success", "succeeded", "ok", "completed", "done"}
|
|
40
|
+
_FALSE = {"0", "false", "f", "no", "n", "fail", "failed", "failure", "error", "errored", "cancelled", "timeout"}
|
|
41
|
+
|
|
42
|
+
|
|
43
|
+
def _norm(name: str) -> str:
|
|
44
|
+
return re.sub(r"[^a-z0-9]", "", name.lower())
|
|
45
|
+
|
|
46
|
+
|
|
47
|
+
def _flatten(record: Dict[str, Any], prefix: str = "") -> Dict[str, Any]:
|
|
48
|
+
out: Dict[str, Any] = {}
|
|
49
|
+
for key, value in record.items():
|
|
50
|
+
full = f"{prefix}.{key}" if prefix else str(key)
|
|
51
|
+
if isinstance(value, dict):
|
|
52
|
+
out.update(_flatten(value, full))
|
|
53
|
+
else:
|
|
54
|
+
out[full] = value
|
|
55
|
+
return out
|
|
56
|
+
|
|
57
|
+
|
|
58
|
+
def _read_records(path: Path) -> List[Dict[str, Any]]:
|
|
59
|
+
text = path.read_text(encoding="utf-8-sig")
|
|
60
|
+
suffix = path.suffix.lower()
|
|
61
|
+
if suffix == ".csv":
|
|
62
|
+
return [dict(row) for row in csv.DictReader(text.splitlines())]
|
|
63
|
+
if suffix in {".jsonl", ".ndjson"}:
|
|
64
|
+
records = [json.loads(line) for line in text.splitlines() if line.strip()]
|
|
65
|
+
elif suffix == ".json":
|
|
66
|
+
data = json.loads(text)
|
|
67
|
+
if isinstance(data, dict):
|
|
68
|
+
for key in ("data", "runs", "traces", "observations", "items", "results"):
|
|
69
|
+
if isinstance(data.get(key), list):
|
|
70
|
+
data = data[key]
|
|
71
|
+
break
|
|
72
|
+
if not isinstance(data, list):
|
|
73
|
+
raise ValueError(f"{path}: expected a list of records, or an object with a 'data' list")
|
|
74
|
+
records = data
|
|
75
|
+
else:
|
|
76
|
+
raise ValueError(f"{path}: use a .csv, .json or .jsonl file")
|
|
77
|
+
if not all(isinstance(r, dict) for r in records):
|
|
78
|
+
raise ValueError(f"{path}: every record must be an object")
|
|
79
|
+
return [_flatten(r) for r in records]
|
|
80
|
+
|
|
81
|
+
|
|
82
|
+
def _find(columns: Iterable[str], names: List[str]) -> Optional[str]:
|
|
83
|
+
"""First column whose full name, or last dotted part, matches one of the spellings."""
|
|
84
|
+
columns = list(columns)
|
|
85
|
+
for wanted in names:
|
|
86
|
+
for col in columns:
|
|
87
|
+
if _norm(col) == wanted:
|
|
88
|
+
return col
|
|
89
|
+
for wanted in names:
|
|
90
|
+
for col in columns:
|
|
91
|
+
if "." in col and _norm(col.rsplit(".", 1)[-1]) == wanted:
|
|
92
|
+
return col
|
|
93
|
+
return None
|
|
94
|
+
|
|
95
|
+
|
|
96
|
+
def _number(value: Any, what: str, where: str) -> Optional[float]:
|
|
97
|
+
if value is None:
|
|
98
|
+
return None
|
|
99
|
+
if isinstance(value, (int, float)) and not isinstance(value, bool):
|
|
100
|
+
return float(value)
|
|
101
|
+
text = str(value).strip().lstrip("$").replace(",", "")
|
|
102
|
+
if text == "" or text.lower() in {"none", "null", "nan"}:
|
|
103
|
+
return None
|
|
104
|
+
try:
|
|
105
|
+
return float(text)
|
|
106
|
+
except ValueError:
|
|
107
|
+
raise ValueError(f"{where}: cannot read {what} {value!r} as a number") from None
|
|
108
|
+
|
|
109
|
+
|
|
110
|
+
def _outcome(row: Dict[str, Any], success_col, status_col, error_col, where: str) -> Optional[bool]:
|
|
111
|
+
if success_col is not None:
|
|
112
|
+
cell = str(row.get(success_col, "")).strip().lower()
|
|
113
|
+
if cell in _TRUE:
|
|
114
|
+
return True
|
|
115
|
+
if cell in _FALSE:
|
|
116
|
+
return False
|
|
117
|
+
if cell in {"", "none", "null"}:
|
|
118
|
+
return None
|
|
119
|
+
raise ValueError(f"{where}: cannot read {row.get(success_col)!r} as success or failure")
|
|
120
|
+
if status_col is not None:
|
|
121
|
+
cell = str(row.get(status_col, "")).strip().lower()
|
|
122
|
+
if cell in _TRUE:
|
|
123
|
+
return True
|
|
124
|
+
if cell in _FALSE:
|
|
125
|
+
return False
|
|
126
|
+
return None
|
|
127
|
+
if error_col is not None:
|
|
128
|
+
value = row.get(error_col)
|
|
129
|
+
return value is None or str(value).strip().lower() in {"", "none", "null", "false"}
|
|
130
|
+
return None
|
|
131
|
+
|
|
132
|
+
|
|
133
|
+
@dataclass
|
|
134
|
+
class LoadedRuns:
|
|
135
|
+
"""Run costs and outcomes read from an export, plus what was used to read them."""
|
|
136
|
+
|
|
137
|
+
costs: List[float]
|
|
138
|
+
successes: Optional[List[bool]]
|
|
139
|
+
run_ids: Optional[List[str]]
|
|
140
|
+
rows: int
|
|
141
|
+
columns_used: Dict[str, str] = field(default_factory=dict)
|
|
142
|
+
rows_without_cost: int = 0
|
|
143
|
+
|
|
144
|
+
def report(self) -> str:
|
|
145
|
+
used = ", ".join(f"{k} from '{v}'" for k, v in self.columns_used.items())
|
|
146
|
+
lines = [f"Read {self.rows} rows into {len(self.costs)} runs ({used})."]
|
|
147
|
+
if self.rows_without_cost:
|
|
148
|
+
lines.append(
|
|
149
|
+
f"{self.rows_without_cost} rows had no cost and count as $0. If your tool could not price "
|
|
150
|
+
"those calls, pass token columns and prices instead."
|
|
151
|
+
)
|
|
152
|
+
if self.successes is None:
|
|
153
|
+
lines.append("No success column found, so cost per successful task is not available.")
|
|
154
|
+
return "\n".join(lines)
|
|
155
|
+
|
|
156
|
+
|
|
157
|
+
def load_runs(
|
|
158
|
+
path,
|
|
159
|
+
*,
|
|
160
|
+
cost: Optional[str] = None,
|
|
161
|
+
input_tokens: Optional[str] = None,
|
|
162
|
+
output_tokens: Optional[str] = None,
|
|
163
|
+
cached_tokens: Optional[str] = None,
|
|
164
|
+
success: Optional[str] = None,
|
|
165
|
+
group_by: Optional[str] = None,
|
|
166
|
+
input_price: Optional[float] = None,
|
|
167
|
+
output_price: Optional[float] = None,
|
|
168
|
+
cached_price: Optional[float] = None,
|
|
169
|
+
) -> LoadedRuns:
|
|
170
|
+
"""Read run costs from a CSV, JSON or JSON Lines export.
|
|
171
|
+
|
|
172
|
+
Args:
|
|
173
|
+
path: the export file.
|
|
174
|
+
cost, input_tokens, output_tokens, cached_tokens, success: column
|
|
175
|
+
names, if the automatic guess is wrong. Nested JSON fields are
|
|
176
|
+
named with dots, for example ``usage.prompt_tokens``.
|
|
177
|
+
group_by: column naming the run each row belongs to, for exports with
|
|
178
|
+
one row per model call. Costs are added up per run, and a run
|
|
179
|
+
fails if any of its rows failed.
|
|
180
|
+
input_price, output_price, cached_price: dollars per million tokens,
|
|
181
|
+
used when there is no cost column, or for rows with no cost.
|
|
182
|
+
|
|
183
|
+
Without a success column, ``status`` (success or error) or ``error``
|
|
184
|
+
(empty means success) are used if present.
|
|
185
|
+
"""
|
|
186
|
+
path = Path(path)
|
|
187
|
+
records = _read_records(path)
|
|
188
|
+
if not records:
|
|
189
|
+
raise ValueError(f"{path} has no rows")
|
|
190
|
+
columns = list({k: None for r in records for k in r}.keys())
|
|
191
|
+
|
|
192
|
+
def pick(explicit, names, label):
|
|
193
|
+
if explicit is None:
|
|
194
|
+
return _find(columns, names)
|
|
195
|
+
if explicit not in columns:
|
|
196
|
+
raise ValueError(f"{path} has no {label} column named {explicit!r}")
|
|
197
|
+
return explicit
|
|
198
|
+
|
|
199
|
+
cost_col = pick(cost, COST_NAMES, "cost")
|
|
200
|
+
in_col = pick(input_tokens, INPUT_NAMES, "input token")
|
|
201
|
+
out_col = pick(output_tokens, OUTPUT_NAMES, "output token")
|
|
202
|
+
cached_col = pick(cached_tokens, CACHED_NAMES, "cached token")
|
|
203
|
+
success_col = pick(success, SUCCESS_NAMES, "success")
|
|
204
|
+
status_col = _find(columns, STATUS_NAMES) if success_col is None else None
|
|
205
|
+
error_col = _find(columns, ERROR_NAMES) if success_col is None and status_col is None else None
|
|
206
|
+
if group_by is not None and group_by not in columns:
|
|
207
|
+
raise ValueError(f"{path} has no column named {group_by!r} to group by")
|
|
208
|
+
have_prices = input_price is not None and output_price is not None
|
|
209
|
+
if cost_col is None and not (in_col and out_col and have_prices):
|
|
210
|
+
if in_col and out_col:
|
|
211
|
+
raise ValueError(
|
|
212
|
+
f"{path} has token columns but no cost column: give prices in dollars per million tokens "
|
|
213
|
+
"(--input-price and --output-price, or input_price and output_price in Python)"
|
|
214
|
+
)
|
|
215
|
+
raise ValueError(
|
|
216
|
+
f"{path}: found no cost column and no token columns. Columns are: {', '.join(columns[:15])}"
|
|
217
|
+
)
|
|
218
|
+
|
|
219
|
+
per_row: List[Tuple[Optional[str], float, Optional[bool]]] = []
|
|
220
|
+
missing = priced_by_tokens = 0
|
|
221
|
+
for i, row in enumerate(records, start=1):
|
|
222
|
+
where = f"{path}, row {i}"
|
|
223
|
+
value = _number(row.get(cost_col), "cost", where) if cost_col else None
|
|
224
|
+
if value is None and in_col and out_col and have_prices:
|
|
225
|
+
tokens_in = _number(row.get(in_col), "input tokens", where) or 0.0
|
|
226
|
+
tokens_out = _number(row.get(out_col), "output tokens", where) or 0.0
|
|
227
|
+
tokens_cached = (_number(row.get(cached_col), "cached tokens", where) or 0.0) if cached_col else 0.0
|
|
228
|
+
value = run_cost(tokens_in, tokens_out, input_price, output_price, min(tokens_cached, tokens_in), cached_price)
|
|
229
|
+
priced_by_tokens += 1
|
|
230
|
+
if value is None:
|
|
231
|
+
missing += 1
|
|
232
|
+
value = 0.0
|
|
233
|
+
if value < 0:
|
|
234
|
+
raise ValueError(f"{where}: cost must not be negative")
|
|
235
|
+
run = str(row.get(group_by)) if group_by else None
|
|
236
|
+
per_row.append((run, value, _outcome(row, success_col, status_col, error_col, where)))
|
|
237
|
+
|
|
238
|
+
if group_by:
|
|
239
|
+
totals: Dict[str, float] = {}
|
|
240
|
+
outcomes: Dict[str, Optional[bool]] = {}
|
|
241
|
+
for run, value, ok in per_row:
|
|
242
|
+
totals[run] = totals.get(run, 0.0) + value
|
|
243
|
+
if ok is not None:
|
|
244
|
+
outcomes[run] = (outcomes.get(run, True) and ok)
|
|
245
|
+
run_ids = list(totals)
|
|
246
|
+
costs = [totals[r] for r in run_ids]
|
|
247
|
+
flags = [outcomes[r] for r in run_ids] if len(outcomes) == len(run_ids) else None
|
|
248
|
+
else:
|
|
249
|
+
run_ids = None
|
|
250
|
+
costs = [value for _, value, _ in per_row]
|
|
251
|
+
flags_raw = [ok for _, _, ok in per_row]
|
|
252
|
+
flags = flags_raw if all(ok is not None for ok in flags_raw) else None
|
|
253
|
+
|
|
254
|
+
used: Dict[str, str] = {}
|
|
255
|
+
if cost_col:
|
|
256
|
+
used["cost"] = cost_col
|
|
257
|
+
if priced_by_tokens:
|
|
258
|
+
used["tokens"] = f"{in_col} and {out_col}"
|
|
259
|
+
for label, col in (("success", success_col), ("status", status_col), ("error", error_col)):
|
|
260
|
+
if col and flags is not None:
|
|
261
|
+
used[label] = col
|
|
262
|
+
if group_by:
|
|
263
|
+
used["runs"] = group_by
|
|
264
|
+
return LoadedRuns(costs, flags, run_ids, len(records), used, missing)
|
costplan/planning.py
ADDED
|
@@ -0,0 +1,416 @@
|
|
|
1
|
+
"""Plan what an agent costs from a handful of pilot runs.
|
|
2
|
+
|
|
3
|
+
Agent costs are lopsided: most runs are cheap, and a few loop, retry or read
|
|
4
|
+
long documents and cost many times more. That makes averages slow to settle
|
|
5
|
+
and makes "what cap should I set?" a question about the tail, not the middle.
|
|
6
|
+
The methods here make no assumption about the shape of the costs: quantiles
|
|
7
|
+
use order statistics, and intervals for averages and ratios use the bootstrap.
|
|
8
|
+
"""
|
|
9
|
+
|
|
10
|
+
from __future__ import annotations
|
|
11
|
+
|
|
12
|
+
import math
|
|
13
|
+
from dataclasses import dataclass
|
|
14
|
+
from statistics import fmean, stdev
|
|
15
|
+
from typing import Iterable, List, Optional, Sequence, Tuple
|
|
16
|
+
|
|
17
|
+
from ._stats import (
|
|
18
|
+
bootstrap_interval,
|
|
19
|
+
check_level,
|
|
20
|
+
quantile,
|
|
21
|
+
quantile_interval,
|
|
22
|
+
upper_quantile_bound,
|
|
23
|
+
wilson,
|
|
24
|
+
z_two_sided,
|
|
25
|
+
)
|
|
26
|
+
|
|
27
|
+
|
|
28
|
+
def run_cost(
|
|
29
|
+
input_tokens: float,
|
|
30
|
+
output_tokens: float,
|
|
31
|
+
input_price: float,
|
|
32
|
+
output_price: float,
|
|
33
|
+
cached_tokens: float = 0,
|
|
34
|
+
cached_price: Optional[float] = None,
|
|
35
|
+
) -> float:
|
|
36
|
+
"""Dollar cost of one call or one run from token counts.
|
|
37
|
+
|
|
38
|
+
Prices are in dollars per million tokens, as providers list them.
|
|
39
|
+
``cached_tokens`` are the part of ``input_tokens`` served from the
|
|
40
|
+
provider's prompt cache, billed at ``cached_price`` (defaults to the input
|
|
41
|
+
price). costplan ships no price table, because prices change; take them
|
|
42
|
+
from your provider's pricing page.
|
|
43
|
+
|
|
44
|
+
>>> round(run_cost(12_000, 800, input_price=3.0, output_price=15.0), 4)
|
|
45
|
+
0.048
|
|
46
|
+
"""
|
|
47
|
+
for name, value in [("input_tokens", input_tokens), ("output_tokens", output_tokens), ("cached_tokens", cached_tokens)]:
|
|
48
|
+
if value < 0:
|
|
49
|
+
raise ValueError(f"{name} must not be negative")
|
|
50
|
+
if cached_tokens > input_tokens:
|
|
51
|
+
raise ValueError("cached_tokens are part of input_tokens, so cannot exceed them")
|
|
52
|
+
if cached_price is None:
|
|
53
|
+
cached_price = input_price
|
|
54
|
+
fresh = input_tokens - cached_tokens
|
|
55
|
+
return (fresh * input_price + cached_tokens * cached_price + output_tokens * output_price) / 1_000_000
|
|
56
|
+
|
|
57
|
+
|
|
58
|
+
def _clean(costs: Iterable[float], successes: Optional[Iterable]) -> Tuple[List[float], Optional[List[bool]]]:
|
|
59
|
+
values = [float(c) for c in costs]
|
|
60
|
+
if not values:
|
|
61
|
+
raise ValueError("need at least one run")
|
|
62
|
+
if any(not math.isfinite(c) or c < 0 for c in values):
|
|
63
|
+
raise ValueError("costs must be finite and not negative")
|
|
64
|
+
flags = None
|
|
65
|
+
if successes is not None:
|
|
66
|
+
flags = [bool(s) for s in successes]
|
|
67
|
+
if len(flags) != len(values):
|
|
68
|
+
raise ValueError("successes needs one value per run, in the same order as costs")
|
|
69
|
+
return values, flags
|
|
70
|
+
|
|
71
|
+
|
|
72
|
+
def _cost_per_success(costs: Sequence[float], flags: Sequence[bool]) -> Optional[float]:
|
|
73
|
+
wins = sum(flags)
|
|
74
|
+
return sum(costs) / wins if wins else None
|
|
75
|
+
|
|
76
|
+
|
|
77
|
+
def _fmt(x: Optional[float]) -> str:
|
|
78
|
+
if x is None:
|
|
79
|
+
return "n/a"
|
|
80
|
+
return f"${x:,.4f}" if x < 1 else f"${x:,.2f}"
|
|
81
|
+
|
|
82
|
+
|
|
83
|
+
@dataclass(frozen=True)
|
|
84
|
+
class CostSummary:
|
|
85
|
+
n: int
|
|
86
|
+
mean: float
|
|
87
|
+
mean_interval: Tuple[float, float]
|
|
88
|
+
median: float
|
|
89
|
+
median_interval: Tuple[Optional[float], Optional[float]]
|
|
90
|
+
p95: float
|
|
91
|
+
p95_interval: Tuple[Optional[float], Optional[float]]
|
|
92
|
+
max: float
|
|
93
|
+
spread: float
|
|
94
|
+
success_rate: Optional[float]
|
|
95
|
+
success_interval: Optional[Tuple[float, float]]
|
|
96
|
+
cost_per_success: Optional[float]
|
|
97
|
+
cost_per_success_interval: Optional[Tuple[float, float]]
|
|
98
|
+
confidence: float
|
|
99
|
+
|
|
100
|
+
def summary(self) -> str:
|
|
101
|
+
c = f"{self.confidence:.0%}"
|
|
102
|
+
|
|
103
|
+
def rng(pair):
|
|
104
|
+
lo, hi = pair
|
|
105
|
+
return f"{_fmt(lo)} to {_fmt(hi)}" if lo is not None and hi is not None else "needs more runs"
|
|
106
|
+
|
|
107
|
+
lines = [
|
|
108
|
+
f"{self.n} runs.",
|
|
109
|
+
f" Average cost per run: {_fmt(self.mean)} ({c} interval {rng(self.mean_interval)})",
|
|
110
|
+
f" Typical run (median): {_fmt(self.median)} ({c} interval {rng(self.median_interval)})",
|
|
111
|
+
f" 1 in 20 runs costs more than: {_fmt(self.p95)} ({c} interval {rng(self.p95_interval)})",
|
|
112
|
+
f" Most expensive run: {_fmt(self.max)}",
|
|
113
|
+
]
|
|
114
|
+
if self.success_rate is not None:
|
|
115
|
+
lo, hi = self.success_interval
|
|
116
|
+
lines.append(f" Success rate: {self.success_rate:.1%} ({c} interval {lo:.1%} to {hi:.1%})")
|
|
117
|
+
if self.cost_per_success is None:
|
|
118
|
+
lines.append(" Cost per successful task: n/a (no successful runs)")
|
|
119
|
+
else:
|
|
120
|
+
lines.append(
|
|
121
|
+
f" Cost per successful task: {_fmt(self.cost_per_success)} "
|
|
122
|
+
f"({c} interval {rng(self.cost_per_success_interval)})"
|
|
123
|
+
)
|
|
124
|
+
return "\n".join(lines)
|
|
125
|
+
|
|
126
|
+
def __str__(self) -> str:
|
|
127
|
+
return self.summary()
|
|
128
|
+
|
|
129
|
+
|
|
130
|
+
def summarize(
|
|
131
|
+
costs: Iterable[float],
|
|
132
|
+
successes: Optional[Iterable] = None,
|
|
133
|
+
confidence: float = 0.95,
|
|
134
|
+
resamples: int = 2000,
|
|
135
|
+
seed: int = 0,
|
|
136
|
+
) -> CostSummary:
|
|
137
|
+
"""What do these runs cost, and how sure can we be?
|
|
138
|
+
|
|
139
|
+
Args:
|
|
140
|
+
costs: dollar cost of each pilot run.
|
|
141
|
+
successes: optional pass/fail for each run, to get the success rate
|
|
142
|
+
and the cost per successful task.
|
|
143
|
+
confidence: level for every interval.
|
|
144
|
+
resamples, seed: bootstrap settings. The seed makes results repeatable.
|
|
145
|
+
|
|
146
|
+
Intervals for the average and the cost per success use the percentile
|
|
147
|
+
bootstrap, which is rough below about 30 runs. Quantile intervals make no
|
|
148
|
+
assumption about the shape of the costs.
|
|
149
|
+
"""
|
|
150
|
+
check_level(confidence, "confidence")
|
|
151
|
+
values, flags = _clean(costs, successes)
|
|
152
|
+
ordered = sorted(values)
|
|
153
|
+
n = len(values)
|
|
154
|
+
mean = fmean(values)
|
|
155
|
+
spread = stdev(values) / mean if n > 1 and mean > 0 else 0.0
|
|
156
|
+
mean_ci = bootstrap_interval([values], lambda c: fmean(c), confidence, resamples, seed) if n > 1 else (mean, mean)
|
|
157
|
+
rate = rate_ci = cps = cps_ci = None
|
|
158
|
+
if flags is not None:
|
|
159
|
+
wins = sum(flags)
|
|
160
|
+
rate = wins / n
|
|
161
|
+
rate_ci = wilson(wins, n, confidence)
|
|
162
|
+
cps = _cost_per_success(values, flags)
|
|
163
|
+
if cps is not None and n > 1:
|
|
164
|
+
cps_ci = bootstrap_interval([values, flags], _cost_per_success, confidence, resamples, seed)
|
|
165
|
+
return CostSummary(
|
|
166
|
+
n=n,
|
|
167
|
+
mean=mean,
|
|
168
|
+
mean_interval=mean_ci,
|
|
169
|
+
median=quantile(ordered, 0.5),
|
|
170
|
+
median_interval=quantile_interval(ordered, 0.5, confidence),
|
|
171
|
+
p95=quantile(ordered, 0.95),
|
|
172
|
+
p95_interval=quantile_interval(ordered, 0.95, confidence),
|
|
173
|
+
max=ordered[-1],
|
|
174
|
+
spread=spread,
|
|
175
|
+
success_rate=rate,
|
|
176
|
+
success_interval=rate_ci,
|
|
177
|
+
cost_per_success=cps,
|
|
178
|
+
cost_per_success_interval=cps_ci,
|
|
179
|
+
confidence=confidence,
|
|
180
|
+
)
|
|
181
|
+
|
|
182
|
+
|
|
183
|
+
# ---------------------------------------------------------------- budget caps
|
|
184
|
+
|
|
185
|
+
|
|
186
|
+
def runs_needed_for_cap(stop_rate: float = 0.02, confidence: float = 0.95) -> int:
|
|
187
|
+
"""Pilot runs needed before a cap can promise to stop at most ``stop_rate`` of normal runs.
|
|
188
|
+
|
|
189
|
+
With this many runs, setting the cap at the most expensive pilot run
|
|
190
|
+
keeps the share of normal runs that hit the cap at or below
|
|
191
|
+
``stop_rate``, with the given confidence, whatever the cost distribution.
|
|
192
|
+
|
|
193
|
+
>>> runs_needed_for_cap(0.02, 0.95)
|
|
194
|
+
149
|
|
195
|
+
"""
|
|
196
|
+
check_level(stop_rate, "stop_rate")
|
|
197
|
+
check_level(confidence, "confidence")
|
|
198
|
+
return math.ceil(math.log(1 - confidence) / math.log(1 - stop_rate) - 1e-9)
|
|
199
|
+
|
|
200
|
+
|
|
201
|
+
def guaranteed_stop_rate(n_runs: int, confidence: float = 0.95) -> float:
|
|
202
|
+
"""The best promise a cap at the most expensive of ``n_runs`` pilot runs can make.
|
|
203
|
+
|
|
204
|
+
>>> round(guaranteed_stop_rate(30), 3)
|
|
205
|
+
0.095
|
|
206
|
+
"""
|
|
207
|
+
if n_runs < 1:
|
|
208
|
+
raise ValueError("n_runs must be at least 1")
|
|
209
|
+
check_level(confidence, "confidence")
|
|
210
|
+
return 1 - (1 - confidence) ** (1 / n_runs)
|
|
211
|
+
|
|
212
|
+
|
|
213
|
+
def _pct_label(p: float) -> str:
|
|
214
|
+
value = round(p * 100, 1)
|
|
215
|
+
return f"{value:g}th"
|
|
216
|
+
|
|
217
|
+
|
|
218
|
+
@dataclass(frozen=True)
|
|
219
|
+
class CapAdvice:
|
|
220
|
+
n: int
|
|
221
|
+
stop_rate: float
|
|
222
|
+
confidence: float
|
|
223
|
+
estimate: float
|
|
224
|
+
safe_cap: Optional[float]
|
|
225
|
+
runs_needed: int
|
|
226
|
+
best_promise: float
|
|
227
|
+
max_cost: float
|
|
228
|
+
|
|
229
|
+
def summary(self) -> str:
|
|
230
|
+
head = (
|
|
231
|
+
f"Goal: a cap that stops at most {self.stop_rate:.1%} of normal runs "
|
|
232
|
+
f"({self.confidence:.0%} confidence), from {self.n} pilot runs."
|
|
233
|
+
)
|
|
234
|
+
if self.safe_cap is not None:
|
|
235
|
+
return (
|
|
236
|
+
f"{head}\n Recommended cap: {_fmt(self.safe_cap)} per run.\n"
|
|
237
|
+
f" Best single guess for the {_pct_label(1 - self.stop_rate)} percentile: {_fmt(self.estimate)}. "
|
|
238
|
+
"The recommended cap is set higher so the promise holds even if the pilot was lucky."
|
|
239
|
+
)
|
|
240
|
+
return (
|
|
241
|
+
f"{head}\n Not enough runs to promise that yet: it takes {self.runs_needed}.\n"
|
|
242
|
+
f" With {self.n} runs, a cap at the most expensive run ({_fmt(self.max_cost)}) can only promise to stop "
|
|
243
|
+
f"at most {self.best_promise:.1%} of runs.\n"
|
|
244
|
+
f" Best single guess for the {_pct_label(1 - self.stop_rate)} percentile: {_fmt(self.estimate)} "
|
|
245
|
+
"(a guess, not a promise)."
|
|
246
|
+
)
|
|
247
|
+
|
|
248
|
+
def __str__(self) -> str:
|
|
249
|
+
return self.summary()
|
|
250
|
+
|
|
251
|
+
|
|
252
|
+
def recommend_cap(costs: Iterable[float], stop_rate: float = 0.02, confidence: float = 0.95) -> CapAdvice:
|
|
253
|
+
"""What per-run budget cap to set, so it rarely stops a normal run.
|
|
254
|
+
|
|
255
|
+
The cap is an upper confidence bound on the ``1 - stop_rate`` quantile of
|
|
256
|
+
run cost, from order statistics, so it makes no assumption about the cost
|
|
257
|
+
distribution. If there are too few runs to make that promise, the advice
|
|
258
|
+
says how many are needed and what the current pilot can promise instead.
|
|
259
|
+
"""
|
|
260
|
+
check_level(stop_rate, "stop_rate")
|
|
261
|
+
check_level(confidence, "confidence")
|
|
262
|
+
values, _ = _clean(costs, None)
|
|
263
|
+
ordered = sorted(values)
|
|
264
|
+
n = len(ordered)
|
|
265
|
+
return CapAdvice(
|
|
266
|
+
n=n,
|
|
267
|
+
stop_rate=stop_rate,
|
|
268
|
+
confidence=confidence,
|
|
269
|
+
estimate=quantile(ordered, 1 - stop_rate),
|
|
270
|
+
safe_cap=upper_quantile_bound(ordered, 1 - stop_rate, confidence),
|
|
271
|
+
runs_needed=runs_needed_for_cap(stop_rate, confidence),
|
|
272
|
+
best_promise=guaranteed_stop_rate(n, confidence),
|
|
273
|
+
max_cost=ordered[-1],
|
|
274
|
+
)
|
|
275
|
+
|
|
276
|
+
|
|
277
|
+
# --------------------------------------------------------- pilot size, spend
|
|
278
|
+
|
|
279
|
+
|
|
280
|
+
def pilot_runs_for_average(spread: float, margin: float = 0.10, confidence: float = 0.95) -> int:
|
|
281
|
+
"""Pilot runs needed to pin the average cost to within ``margin`` (relative).
|
|
282
|
+
|
|
283
|
+
``spread`` is the coefficient of variation: standard deviation divided by
|
|
284
|
+
the average. Agent costs often have a spread of 1 or more, because of the
|
|
285
|
+
occasional runaway run. Get it from a small pilot with ``summarize``.
|
|
286
|
+
|
|
287
|
+
>>> pilot_runs_for_average(spread=1.2, margin=0.10)
|
|
288
|
+
554
|
|
289
|
+
"""
|
|
290
|
+
if spread < 0:
|
|
291
|
+
raise ValueError("spread must not be negative")
|
|
292
|
+
check_level(margin, "margin")
|
|
293
|
+
check_level(confidence, "confidence")
|
|
294
|
+
z = z_two_sided(confidence)
|
|
295
|
+
return max(2, math.ceil((z * spread / margin) ** 2 - 1e-9))
|
|
296
|
+
|
|
297
|
+
|
|
298
|
+
@dataclass(frozen=True)
|
|
299
|
+
class SpendProjection:
|
|
300
|
+
runs: int
|
|
301
|
+
expected: float
|
|
302
|
+
low: float
|
|
303
|
+
high: float
|
|
304
|
+
confidence: float
|
|
305
|
+
|
|
306
|
+
def summary(self) -> str:
|
|
307
|
+
return (
|
|
308
|
+
f"{self.runs:,} runs: about {_fmt(self.expected)} "
|
|
309
|
+
f"({self.confidence:.0%} range {_fmt(self.low)} to {_fmt(self.high)})."
|
|
310
|
+
)
|
|
311
|
+
|
|
312
|
+
def __str__(self) -> str:
|
|
313
|
+
return self.summary()
|
|
314
|
+
|
|
315
|
+
|
|
316
|
+
def project_spend(costs: Iterable[float], runs: int, confidence: float = 0.95) -> SpendProjection:
|
|
317
|
+
"""Total spend for ``runs`` future runs, given pilot run costs.
|
|
318
|
+
|
|
319
|
+
The range includes both run to run variation and the uncertainty in the
|
|
320
|
+
average learned from the pilot. For large volumes the second one
|
|
321
|
+
dominates, so a bigger pilot narrows the range more than anything else.
|
|
322
|
+
"""
|
|
323
|
+
if runs < 1:
|
|
324
|
+
raise ValueError("runs must be at least 1")
|
|
325
|
+
check_level(confidence, "confidence")
|
|
326
|
+
values, _ = _clean(costs, None)
|
|
327
|
+
n = len(values)
|
|
328
|
+
if n < 2:
|
|
329
|
+
raise ValueError("need at least two pilot runs to project spend")
|
|
330
|
+
mean, sd = fmean(values), stdev(values)
|
|
331
|
+
se_total = math.sqrt(runs * runs * sd * sd / n + runs * sd * sd)
|
|
332
|
+
half = z_two_sided(confidence) * se_total
|
|
333
|
+
expected = mean * runs
|
|
334
|
+
return SpendProjection(runs, expected, max(0.0, expected - half), expected + half, confidence)
|
|
335
|
+
|
|
336
|
+
|
|
337
|
+
# --------------------------------------------------------------- comparison
|
|
338
|
+
|
|
339
|
+
|
|
340
|
+
@dataclass(frozen=True)
|
|
341
|
+
class CostComparison:
|
|
342
|
+
a: str
|
|
343
|
+
b: str
|
|
344
|
+
a_cost_per_success: Optional[float]
|
|
345
|
+
b_cost_per_success: Optional[float]
|
|
346
|
+
ratio: Optional[float]
|
|
347
|
+
ratio_interval: Optional[Tuple[float, float]]
|
|
348
|
+
confidence: float
|
|
349
|
+
paired: bool = False
|
|
350
|
+
|
|
351
|
+
def summary(self) -> str:
|
|
352
|
+
if self.ratio is None:
|
|
353
|
+
return f"Cannot compare: {self.a} or {self.b} has no successful runs."
|
|
354
|
+
lo, hi = self.ratio_interval
|
|
355
|
+
if hi < 1:
|
|
356
|
+
verdict = f"{self.b} is reliably cheaper per success."
|
|
357
|
+
elif lo > 1:
|
|
358
|
+
verdict = f"{self.b} is reliably more expensive per success."
|
|
359
|
+
else:
|
|
360
|
+
verdict = "The difference could be noise."
|
|
361
|
+
return (
|
|
362
|
+
f"Cost per successful task: {self.a} {_fmt(self.a_cost_per_success)}, {self.b} {_fmt(self.b_cost_per_success)}.\n"
|
|
363
|
+
f" {self.b} costs {self.ratio:.2f} times as much as {self.a} per success "
|
|
364
|
+
f"({self.confidence:.0%} interval {lo:.2f} to {hi:.2f}, "
|
|
365
|
+
f"{'same tasks, compared task by task' if self.paired else 'separate pilots'}). {verdict}"
|
|
366
|
+
)
|
|
367
|
+
|
|
368
|
+
def __str__(self) -> str:
|
|
369
|
+
return self.summary()
|
|
370
|
+
|
|
371
|
+
|
|
372
|
+
def compare_cost_per_success(
|
|
373
|
+
a_costs: Iterable[float],
|
|
374
|
+
a_successes: Iterable,
|
|
375
|
+
b_costs: Iterable[float],
|
|
376
|
+
b_successes: Iterable,
|
|
377
|
+
names: Tuple[str, str] = ("A", "B"),
|
|
378
|
+
paired: bool = False,
|
|
379
|
+
confidence: float = 0.95,
|
|
380
|
+
resamples: int = 2000,
|
|
381
|
+
seed: int = 0,
|
|
382
|
+
) -> CostComparison:
|
|
383
|
+
"""Which setup is cheaper per successful task?
|
|
384
|
+
|
|
385
|
+
A cheaper model that fails more often can cost more per task that gets
|
|
386
|
+
done. The interval is a bootstrap of the ratio of costs per success.
|
|
387
|
+
|
|
388
|
+
Args:
|
|
389
|
+
paired: True when both setups ran the same tasks, in the same order.
|
|
390
|
+
Hard tasks are expensive for both, so comparing task by task
|
|
391
|
+
removes that variation and gives a much tighter interval from the
|
|
392
|
+
same number of runs. False when the two pilots ran different tasks.
|
|
393
|
+
"""
|
|
394
|
+
import random
|
|
395
|
+
|
|
396
|
+
check_level(confidence, "confidence")
|
|
397
|
+
ac, af = _clean(a_costs, a_successes)
|
|
398
|
+
bc, bf = _clean(b_costs, b_successes)
|
|
399
|
+
if paired and len(ac) != len(bc):
|
|
400
|
+
raise ValueError("a paired comparison needs the same tasks for both setups, so the same number of runs")
|
|
401
|
+
a_cps, b_cps = _cost_per_success(ac, af), _cost_per_success(bc, bf)
|
|
402
|
+
if a_cps is None or b_cps is None:
|
|
403
|
+
return CostComparison(names[0], names[1], a_cps, b_cps, None, None, confidence, paired)
|
|
404
|
+
rng = random.Random(seed)
|
|
405
|
+
ratios = []
|
|
406
|
+
for _ in range(resamples):
|
|
407
|
+
ia = [rng.randrange(len(ac)) for _ in ac]
|
|
408
|
+
ib = ia if paired else [rng.randrange(len(bc)) for _ in bc]
|
|
409
|
+
ra = _cost_per_success([ac[i] for i in ia], [af[i] for i in ia])
|
|
410
|
+
rb = _cost_per_success([bc[i] for i in ib], [bf[i] for i in ib])
|
|
411
|
+
if ra and rb is not None:
|
|
412
|
+
ratios.append(rb / ra)
|
|
413
|
+
ratios.sort()
|
|
414
|
+
tail = (1 - confidence) / 2
|
|
415
|
+
interval = (quantile(ratios, tail), quantile(ratios, 1 - tail))
|
|
416
|
+
return CostComparison(names[0], names[1], a_cps, b_cps, b_cps / a_cps, interval, confidence, paired)
|
|
@@ -0,0 +1,229 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: costplan
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: How much will my agent cost? Plan AI agent budgets, caps and spend from a handful of pilot runs
|
|
5
|
+
Author: Meenal Asesh
|
|
6
|
+
License-Expression: MIT
|
|
7
|
+
Project-URL: Homepage, https://github.com/ai-with-md/costplan
|
|
8
|
+
Project-URL: Calculator, https://ai-with-md.github.io/costplan/
|
|
9
|
+
Project-URL: Issues, https://github.com/ai-with-md/costplan/issues
|
|
10
|
+
Keywords: llm,ai agents,cost,budget,token cost,llm cost,cost per task,statistics,forecasting
|
|
11
|
+
Classifier: Programming Language :: Python :: 3
|
|
12
|
+
Classifier: Operating System :: OS Independent
|
|
13
|
+
Classifier: Topic :: Scientific/Engineering :: Artificial Intelligence
|
|
14
|
+
Requires-Python: >=3.9
|
|
15
|
+
Description-Content-Type: text/markdown
|
|
16
|
+
License-File: LICENSE
|
|
17
|
+
Provides-Extra: dev
|
|
18
|
+
Requires-Dist: pytest; extra == "dev"
|
|
19
|
+
Dynamic: license-file
|
|
20
|
+
|
|
21
|
+
# costplan
|
|
22
|
+
|
|
23
|
+
**How much will my agent cost?** Plan AI agent budgets, caps and spend from a handful of pilot runs, with a [calculator that runs in your browser](https://ai-with-md.github.io/costplan/).
|
|
24
|
+
|
|
25
|
+
[](https://pypi.org/project/costplan/)
|
|
26
|
+
[](https://github.com/ai-with-md/costplan/actions/workflows/tests.yml)
|
|
27
|
+

|
|
28
|
+

|
|
29
|
+
|
|
30
|
+
[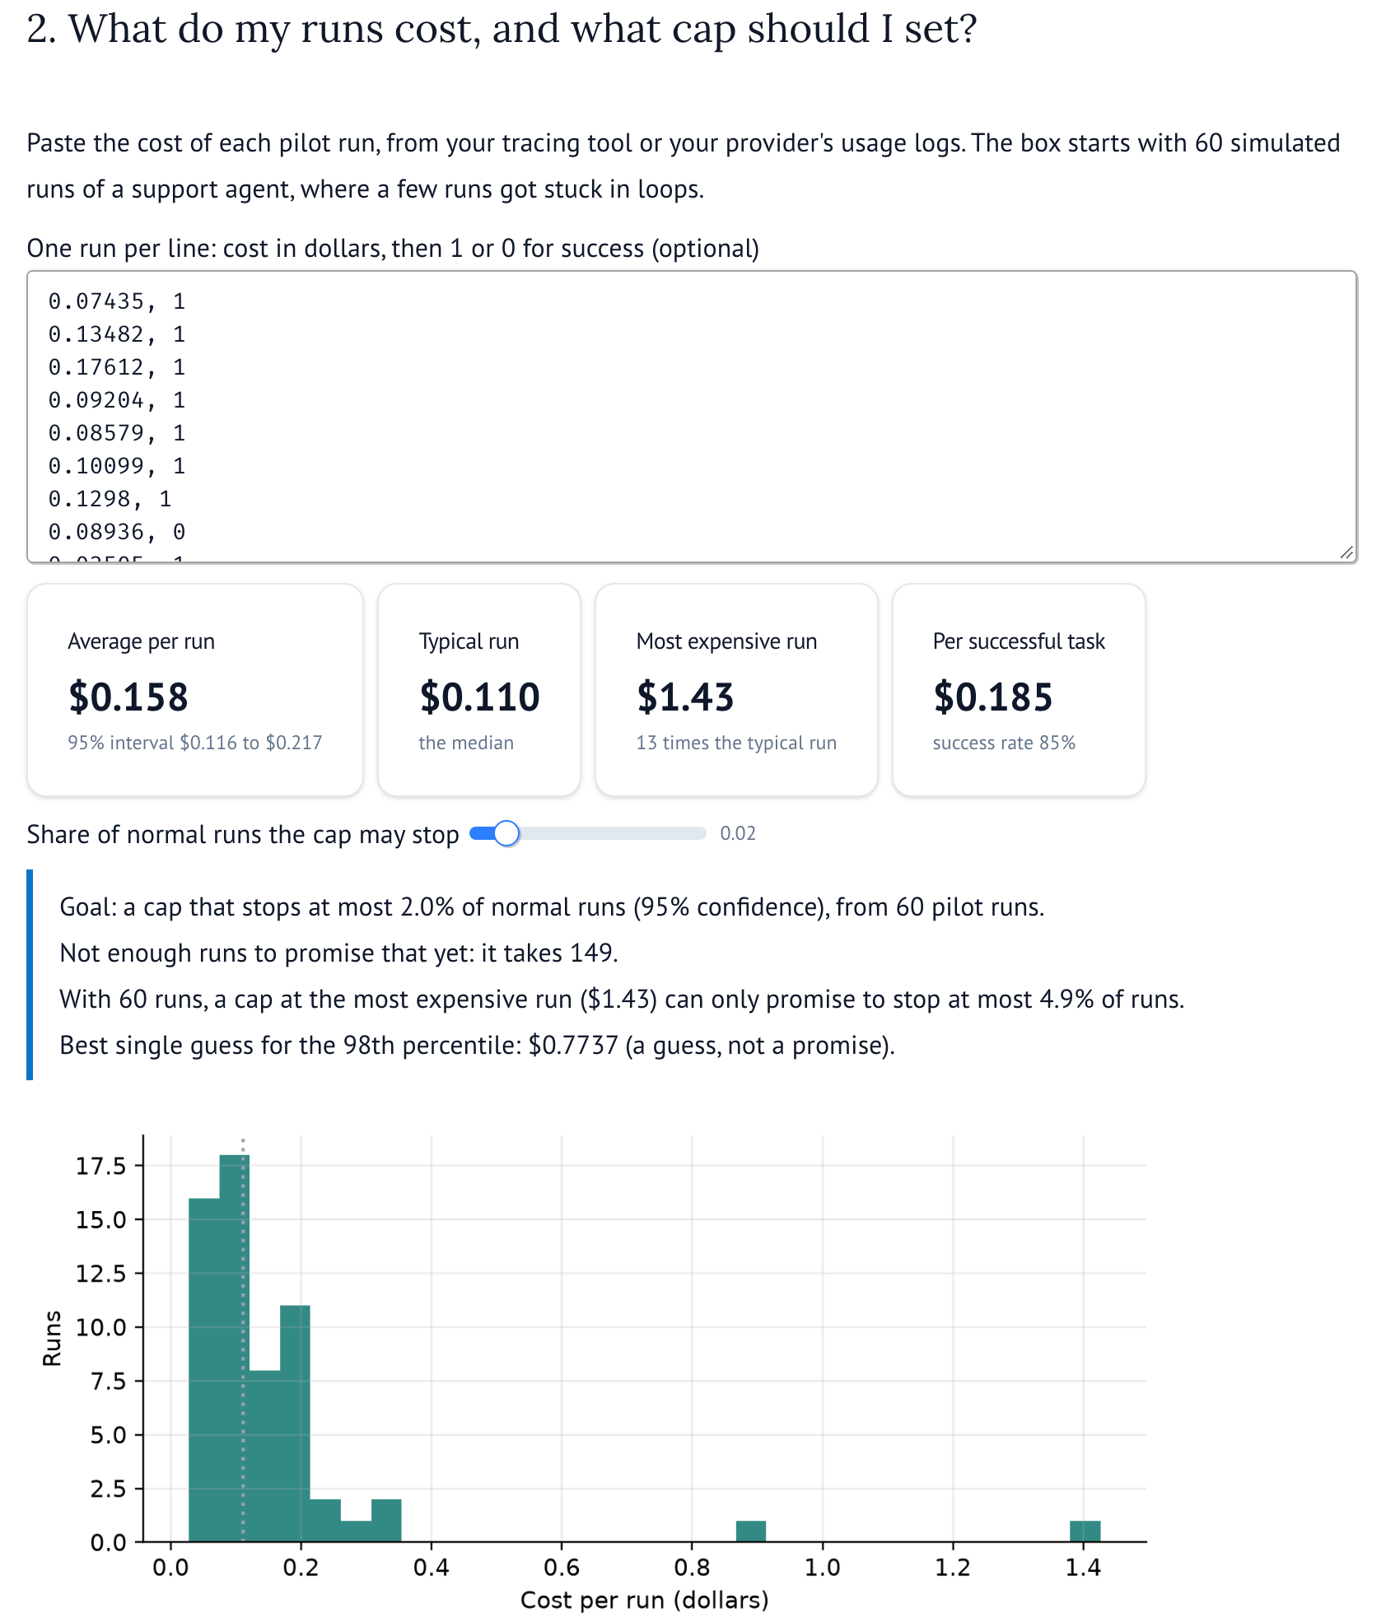](https://ai-with-md.github.io/costplan/)
|
|
31
|
+
|
|
32
|
+
Agent costs are lopsided. Most runs take a few tool calls and cost a few cents. A few get stuck in a loop, retry, or read a long document, and cost ten times more. In the example pilot above, the typical run costs $0.11 and the most expensive one $1.43. That makes averages slow to settle, and it makes "what budget cap should I set?" a question about the rare expensive runs, not the typical ones.
|
|
33
|
+
|
|
34
|
+
costplan answers the planning questions from a pilot:
|
|
35
|
+
|
|
36
|
+
1. What does a run really cost, and what does a **finished task** cost?
|
|
37
|
+
2. What per-run budget cap should I set, so it almost never stops a normal run?
|
|
38
|
+
3. How many pilot runs do I need before I can trust those numbers?
|
|
39
|
+
4. What will it cost at 10,000 runs a day?
|
|
40
|
+
5. Is the cheaper model actually cheaper per finished task?
|
|
41
|
+
|
|
42
|
+
## The number most people get wrong
|
|
43
|
+
|
|
44
|
+
To set a budget cap that stops at most 2% of normal runs, and be 95% sure of it, you need **149 pilot runs**. Fewer runs simply cannot rule out a rare expensive run that a tighter cap would cut off. Set the cap at the most expensive pilot run and this is the best you can promise:
|
|
45
|
+
|
|
46
|
+
| Pilot runs | Cap stops at most |
|
|
47
|
+
|---|---|
|
|
48
|
+
| 20 | 13.9% of normal runs |
|
|
49
|
+
| 30 | 9.5% |
|
|
50
|
+
| 50 | 5.8% |
|
|
51
|
+
| 100 | 3.0% |
|
|
52
|
+
| 149 | 2.0% |
|
|
53
|
+
| 300 | 1.0% |
|
|
54
|
+
|
|
55
|
+
These numbers hold whatever the shape of your costs. costplan tells you what your current pilot can promise, and how many more runs the promise you want would take.
|
|
56
|
+
|
|
57
|
+
## Try it
|
|
58
|
+
|
|
59
|
+
**In the browser:** [ai-with-md.github.io/costplan](https://ai-with-md.github.io/costplan/). Paste your run costs, nothing to install.
|
|
60
|
+
|
|
61
|
+
**In Python:**
|
|
62
|
+
|
|
63
|
+
```bash
|
|
64
|
+
pip install costplan
|
|
65
|
+
```
|
|
66
|
+
|
|
67
|
+
No dependencies beyond the standard library. Python 3.9 or newer.
|
|
68
|
+
|
|
69
|
+
## Use
|
|
70
|
+
|
|
71
|
+
### Reading your exports
|
|
72
|
+
|
|
73
|
+
`load_runs` reads a CSV, JSON or JSON Lines export from your tracing tool or provider and finds the cost, token, success and run columns by their common names (`cost`, `total_cost`, `totalCost`, `calculatedTotalCost`, `prompt_tokens`, `input_tokens`, `usage.input`, `status`, `error`, `trace_id`, `traceId` and others).
|
|
74
|
+
|
|
75
|
+
```python
|
|
76
|
+
import costplan as cp
|
|
77
|
+
|
|
78
|
+
runs = cp.load_runs("calls_export.jsonl", group_by="trace_id")
|
|
79
|
+
print(runs.report())
|
|
80
|
+
# Read 318 rows into 40 runs (cost from 'cost', status from 'status', runs from 'trace_id').
|
|
81
|
+
|
|
82
|
+
costs, successes = runs.costs, runs.successes
|
|
83
|
+
```
|
|
84
|
+
|
|
85
|
+
- **One row per model call?** Pass `group_by` with the column that names the run (a trace or session id). Calls are added up into runs, and a run counts as failed if any of its calls failed.
|
|
86
|
+
- **One row per run, already totalled?** Load it as it is. Grouping it again would count costs twice.
|
|
87
|
+
- **No cost column, or calls your tool could not price?** Pass `input_price` and `output_price` in dollars per million tokens and costplan prices them from the token columns. costplan ships no price table, because prices change; take them from your provider's pricing page or a list such as [tokencost](https://github.com/AgentOps-AI/tokencost).
|
|
88
|
+
- **Names not found?** Pass them yourself: `cost="spend"`, `success="passed"`, and dotted names for nested JSON such as `"usage.prompt_tokens"`.
|
|
89
|
+
|
|
90
|
+
The column guesses are tested on files shaped like LangSmith run exports and Langfuse observation exports, using the field names in their documentation. Check `runs.report()` the first time you load a new kind of file.
|
|
91
|
+
|
|
92
|
+
`run_cost` does the same pricing for a single call:
|
|
93
|
+
|
|
94
|
+
```python
|
|
95
|
+
cp.run_cost(input_tokens=12_000, output_tokens=800, input_price=3.0, output_price=15.0)
|
|
96
|
+
# 0.048
|
|
97
|
+
```
|
|
98
|
+
|
|
99
|
+
### 1. What does a run cost?
|
|
100
|
+
|
|
101
|
+
```python
|
|
102
|
+
print(cp.summarize(costs, successes))
|
|
103
|
+
# 60 runs.
|
|
104
|
+
# Average cost per run: $0.1577 (95% interval $0.1160 to $0.2167)
|
|
105
|
+
# Typical run (median): $0.1100 (95% interval $0.0920 to $0.1371)
|
|
106
|
+
# 1 in 20 runs costs more than: $0.3272 (95% interval needs more runs)
|
|
107
|
+
# Most expensive run: $1.43
|
|
108
|
+
# Success rate: 85.0% (95% interval 73.9% to 91.9%)
|
|
109
|
+
# Cost per successful task: $0.1855 (95% interval $0.1308 to $0.2677)
|
|
110
|
+
```
|
|
111
|
+
|
|
112
|
+
The cost per successful task is the number that matters for a product: failed runs cost money too.
|
|
113
|
+
|
|
114
|
+
### 2. What cap should I set?
|
|
115
|
+
|
|
116
|
+
```python
|
|
117
|
+
print(cp.recommend_cap(costs, stop_rate=0.02))
|
|
118
|
+
# Goal: a cap that stops at most 2.0% of normal runs (95% confidence), from 60 pilot runs.
|
|
119
|
+
# Not enough runs to promise that yet: it takes 149.
|
|
120
|
+
# With 60 runs, a cap at the most expensive run ($1.43) can only promise to stop at most 4.9% of runs.
|
|
121
|
+
# Best single guess for the 98th percentile: $0.7737 (a guess, not a promise).
|
|
122
|
+
```
|
|
123
|
+
|
|
124
|
+
With enough runs, it returns a recommended cap. That cap is an upper confidence bound on the cost percentile, so it holds even if the pilot happened to miss some expensive runs. Enforce it with your agent framework, your own code, or a library such as [AgentBudget](https://github.com/AgentBudget/agentbudget).
|
|
125
|
+
|
|
126
|
+
### 3. How many pilot runs do I need?
|
|
127
|
+
|
|
128
|
+
```python
|
|
129
|
+
cp.runs_needed_for_cap(stop_rate=0.02) # 149
|
|
130
|
+
cp.guaranteed_stop_rate(n_runs=30) # 0.095
|
|
131
|
+
cp.pilot_runs_for_average(spread=1.0, margin=0.10) # 385 runs to pin the average within 10%
|
|
132
|
+
```
|
|
133
|
+
|
|
134
|
+
`spread` is the standard deviation divided by the average. Agent costs often have a spread near 1 or above because of the runaway runs, which is why averages need hundreds of runs to settle.
|
|
135
|
+
|
|
136
|
+
### 4. What will it cost at scale?
|
|
137
|
+
|
|
138
|
+
```python
|
|
139
|
+
print(cp.project_spend(costs, runs=300_000))
|
|
140
|
+
# 300,000 runs: about $47,301.75 (95% range $31,765.55 to $62,837.95).
|
|
141
|
+
```
|
|
142
|
+
|
|
143
|
+
At high volume the run to run variation averages out, and nearly all of the range comes from how well the pilot pinned down the average. A bigger pilot narrows it more than anything else.
|
|
144
|
+
|
|
145
|
+
### 5. Is the cheaper model cheaper per finished task?
|
|
146
|
+
|
|
147
|
+
```python
|
|
148
|
+
print(cp.compare_cost_per_success(large_costs, large_ok, small_costs, small_ok, names=("large model", "small model")))
|
|
149
|
+
# Cost per successful task: large model $0.1855, small model $0.2197.
|
|
150
|
+
# small model costs 1.18 times as much as large model per success (95% interval 0.71 to 2.02, separate pilots). The difference could be noise.
|
|
151
|
+
```
|
|
152
|
+
|
|
153
|
+
In this example the small model is about 30% cheaper per run, but it fails and loops more often, so it probably costs more per finished task. With 60 runs each, costplan correctly says the difference is not yet certain.
|
|
154
|
+
|
|
155
|
+
**Run both models on the same tasks if you can.** Hard tasks are expensive for every model, so comparing task by task removes that variation. With `paired=True` the same 60 tasks give an answer that separate pilots cannot:
|
|
156
|
+
|
|
157
|
+
```python
|
|
158
|
+
cp.compare_cost_per_success(large_costs, large_ok, small_costs, small_ok, names=("large model", "small model"))
|
|
159
|
+
# small model costs 0.73 times as much as large model per success (95% interval 0.49 to 1.08, separate pilots). The difference could be noise.
|
|
160
|
+
|
|
161
|
+
cp.compare_cost_per_success(large_costs, large_ok, small_costs, small_ok, names=("large model", "small model"), paired=True)
|
|
162
|
+
# small model costs 0.73 times as much as large model per success (95% interval 0.61 to 0.88, same tasks, compared task by task). small model is reliably cheaper per success.
|
|
163
|
+
```
|
|
164
|
+
|
|
165
|
+
In simulation, pairing gives intervals about half as wide from the same number of runs.
|
|
166
|
+
|
|
167
|
+
## Command line
|
|
168
|
+
|
|
169
|
+
```bash
|
|
170
|
+
costplan summary runs.csv
|
|
171
|
+
costplan cap runs.csv --stop-rate 0.02
|
|
172
|
+
costplan project runs.csv --runs 300000
|
|
173
|
+
costplan compare large.csv small.csv --names "large model" "small model"
|
|
174
|
+
costplan compare large.csv small.csv --paired --task-column task_id
|
|
175
|
+
costplan summary calls_export.jsonl --group-by trace_id -v
|
|
176
|
+
costplan pilot --stop-rate 0.02 --spread 1.0
|
|
177
|
+
```
|
|
178
|
+
|
|
179
|
+
Files can be CSV, JSON or JSON Lines, with the same automatic column finding as `load_runs`. Use `--cost-column`, `--success-column` and similar options when the guess is wrong, `--input-price` and `--output-price` for files with tokens but no costs, and `-v` to see which columns were used. Try it on the simulated files in [`examples/`](https://github.com/ai-with-md/costplan/tree/main/examples).
|
|
180
|
+
|
|
181
|
+
## How the numbers are checked
|
|
182
|
+
|
|
183
|
+
The test suite simulates thousands of pilots with lopsided costs where the truth is known, and checks each promise:
|
|
184
|
+
|
|
185
|
+
| Promise | Held in simulation |
|
|
186
|
+
|---|---|
|
|
187
|
+
| The recommended cap stops at most 2% of runs | 98.5% of pilots (95% promised) |
|
|
188
|
+
| A cap at the most expensive of 149 runs stops at most 2% | 94.8% |
|
|
189
|
+
| The interval for cost per successful task covers the truth | 93% |
|
|
190
|
+
| The spend projection covers the real bill | 92% |
|
|
191
|
+
| The interval for the average cost covers the truth | 92% |
|
|
192
|
+
| The paired comparison interval covers the true ratio | 96% |
|
|
193
|
+
| Paired vs separate pilots, same number of runs | interval about half as wide |
|
|
194
|
+
|
|
195
|
+
The caps and quantiles make no assumption about the shape of costs and keep their promise. The intervals for averages run slightly short of 95% on lopsided costs, which is typical for the bootstrap; treat them as a little optimistic, especially below about 30 runs. See [`tests/test_simulation.py`](https://github.com/ai-with-md/costplan/blob/main/tests/test_simulation.py).
|
|
196
|
+
|
|
197
|
+
## How it compares
|
|
198
|
+
|
|
199
|
+
- **[AgentBudget](https://github.com/AgentBudget/agentbudget)** and similar tools enforce a dollar limit while an agent runs. costplan tells you what limit to set, and what you will spend. They work well together.
|
|
200
|
+
- **Price calculators and price lists** such as [tokencost](https://github.com/AgentOps-AI/tokencost) cost out a single request. costplan works on whole runs, including the expensive tail, retries and failures.
|
|
201
|
+
- **Tracing tools** (Langfuse, LangSmith and others) record what runs cost. costplan turns those records into planning numbers with honest uncertainty.
|
|
202
|
+
|
|
203
|
+
## Limits
|
|
204
|
+
|
|
205
|
+
- The pilot must look like real traffic: the same prompts, tools, models and mix of requests. Change any of them and run a new pilot.
|
|
206
|
+
- Caps and projections assume future runs behave like pilot runs. A new kind of request that triggers long loops will not show up in a pilot that never saw it.
|
|
207
|
+
- The spend projection uses a normal approximation, which is a little narrow for very lopsided costs.
|
|
208
|
+
|
|
209
|
+
## More tools
|
|
210
|
+
|
|
211
|
+
Small, free tools for building and checking AI systems:
|
|
212
|
+
|
|
213
|
+
- **[sturdytools](https://github.com/ai-with-md/sturdytools)**: retries, timeouts, rate limits and circuit breakers for the tools an AI agent calls.
|
|
214
|
+
- **[evalsize](https://github.com/ai-with-md/evalsize)**: how many eval examples you need before a difference between prompts or models means anything.
|
|
215
|
+
|
|
216
|
+
## Development
|
|
217
|
+
|
|
218
|
+
```bash
|
|
219
|
+
python -m venv .venv
|
|
220
|
+
source .venv/bin/activate
|
|
221
|
+
pip install -e ".[dev]"
|
|
222
|
+
pytest
|
|
223
|
+
```
|
|
224
|
+
|
|
225
|
+
The calculator is a [marimo](https://marimo.io) notebook in [`app/calculator.py`](https://github.com/ai-with-md/costplan/blob/main/app/calculator.py), published to GitHub Pages as a WebAssembly app on every push to `main`.
|
|
226
|
+
|
|
227
|
+
## License
|
|
228
|
+
|
|
229
|
+
MIT
|
|
@@ -0,0 +1,11 @@
|
|
|
1
|
+
costplan/__init__.py,sha256=yDI4XKayQG9O8iG8h09ApV96XpJVn1_Cov-P3LbyYXo,749
|
|
2
|
+
costplan/_stats.py,sha256=UB2QyfcFDTby3iNhTYRehht2tPfghI-yGU3aSDhV-Eo,3683
|
|
3
|
+
costplan/cli.py,sha256=jgQ3HLAHoLR_XKimV-Snwz5aneYiQedkuxQeC2g-tKE,7170
|
|
4
|
+
costplan/loading.py,sha256=Y0offWXr0m42rdob1_8782tnmQV_c5U4cnJ-8yWXrKo,11031
|
|
5
|
+
costplan/planning.py,sha256=DqB77HFo2guXYeYD_HjrScnxbTGZiJLypuu1K5UwabU,15582
|
|
6
|
+
costplan-0.1.0.dist-info/licenses/LICENSE,sha256=HS_Pp1J0NNKF4niTKA1MdskkGwByEasM-oJb8NcpaGE,1069
|
|
7
|
+
costplan-0.1.0.dist-info/METADATA,sha256=3l6bTfiWk-hpRZRMY8P6ga4QdJJ16h4n4fsXEYohDLE,12235
|
|
8
|
+
costplan-0.1.0.dist-info/WHEEL,sha256=mOdXR9C3wMVov7cSY8PY-XCzo3SmmWCHvGQr5csJoao,91
|
|
9
|
+
costplan-0.1.0.dist-info/entry_points.txt,sha256=fC2SC_ksmyycIaDe8HQPOUs2wdKWOthgJOidhsIsnyE,47
|
|
10
|
+
costplan-0.1.0.dist-info/top_level.txt,sha256=s9Jb01a6gxXW-NvYZvOmWABKLMGyWtjuWFhgftzq1P0,9
|
|
11
|
+
costplan-0.1.0.dist-info/RECORD,,
|
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Meenal Asesh
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
costplan
|