block-streamer 0.1.0__py3-none-any.whl
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- block_streamer/__init__.py +5 -0
- block_streamer/_autograd.py +233 -0
- block_streamer-0.1.0.dist-info/METADATA +298 -0
- block_streamer-0.1.0.dist-info/RECORD +9 -0
- block_streamer-0.1.0.dist-info/WHEEL +5 -0
- block_streamer-0.1.0.dist-info/licenses/LICENSE +202 -0
- block_streamer-0.1.0.dist-info/top_level.txt +3 -0
- memory_pool.py +191 -0
- streamer.py +234 -0
|
@@ -0,0 +1,233 @@
|
|
|
1
|
+
"""Recompute one block at a time; return CPU parameter gradients to autograd."""
|
|
2
|
+
|
|
3
|
+
from __future__ import annotations
|
|
4
|
+
|
|
5
|
+
from dataclasses import dataclass
|
|
6
|
+
from typing import TYPE_CHECKING, Any
|
|
7
|
+
|
|
8
|
+
import torch
|
|
9
|
+
from torch import Tensor
|
|
10
|
+
from torch.autograd.function import once_differentiable
|
|
11
|
+
from torch.utils._pytree import TreeSpec, tree_flatten, tree_unflatten
|
|
12
|
+
|
|
13
|
+
from memory_pool import tensor_bytes
|
|
14
|
+
|
|
15
|
+
if TYPE_CHECKING:
|
|
16
|
+
from streamer import StreamedModel
|
|
17
|
+
|
|
18
|
+
|
|
19
|
+
@dataclass
|
|
20
|
+
class TensorTree:
|
|
21
|
+
"""Store structural metadata without retaining live tensor references."""
|
|
22
|
+
|
|
23
|
+
leaves: list[Any]
|
|
24
|
+
positions: list[int]
|
|
25
|
+
spec: TreeSpec
|
|
26
|
+
|
|
27
|
+
@classmethod
|
|
28
|
+
def split(cls, value: Any) -> tuple[TensorTree, list[Tensor]]:
|
|
29
|
+
leaves, spec = tree_flatten(value)
|
|
30
|
+
positions = [i for i, leaf in enumerate(leaves) if isinstance(leaf, Tensor)]
|
|
31
|
+
tensors = [leaves[i] for i in positions]
|
|
32
|
+
for i in positions:
|
|
33
|
+
leaves[i] = None
|
|
34
|
+
return cls(leaves, positions, spec), tensors
|
|
35
|
+
|
|
36
|
+
def merge(self, tensors: list[Tensor] | tuple[Tensor, ...]) -> Any:
|
|
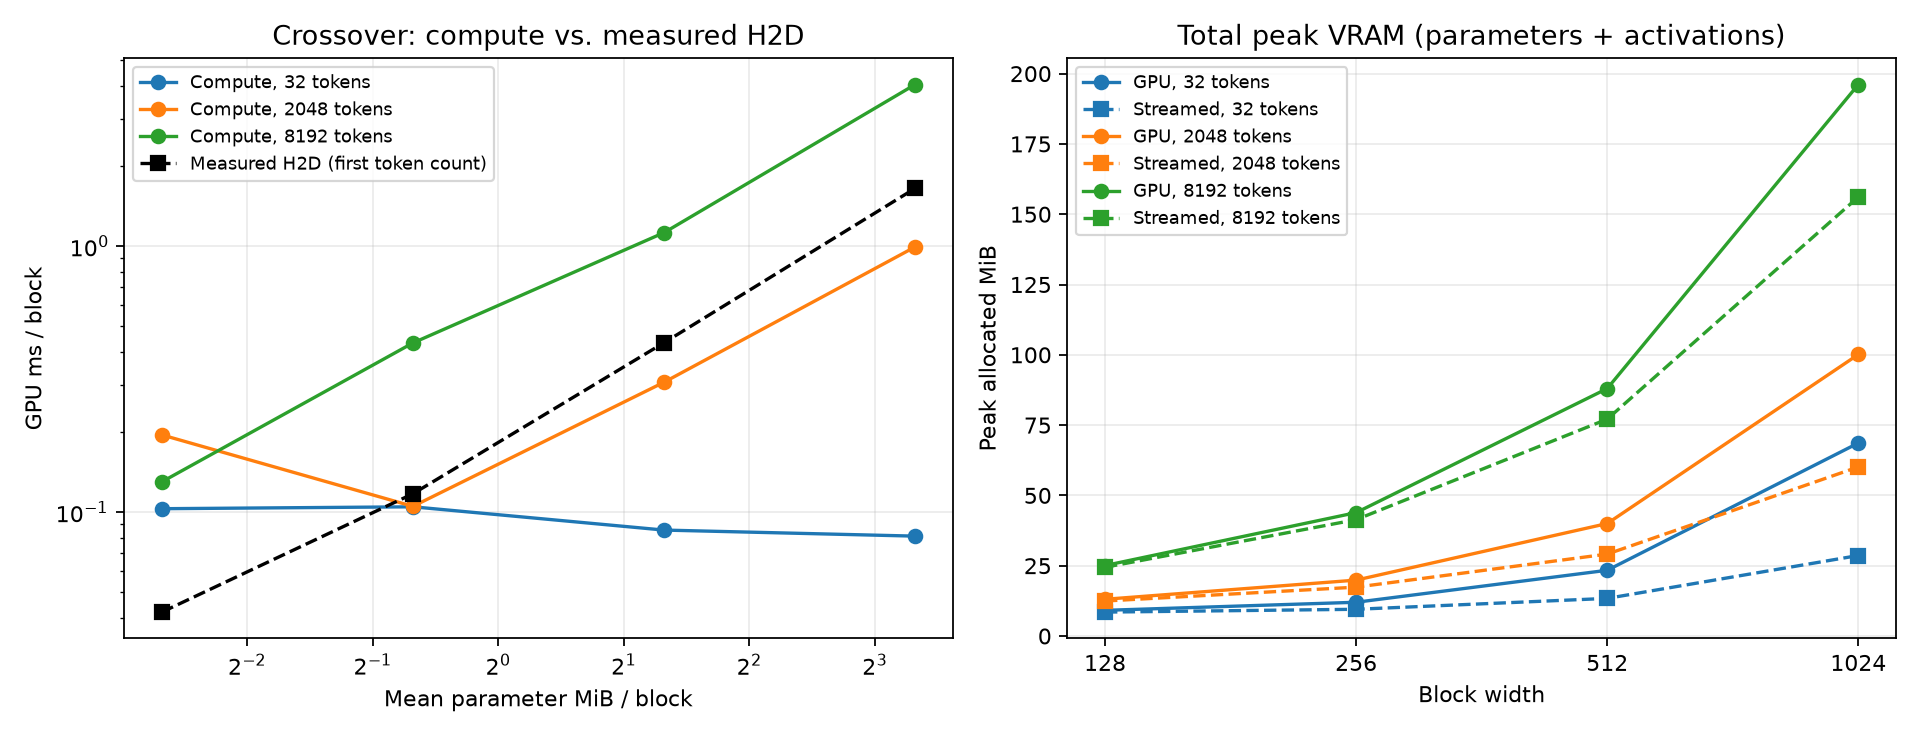
37
|
+
leaves = self.leaves.copy()
|
|
38
|
+
for index, tensor in zip(self.positions, tensors, strict=True):
|
|
39
|
+
leaves[index] = tensor
|
|
40
|
+
return tree_unflatten(leaves, self.spec)
|
|
41
|
+
|
|
42
|
+
|
|
43
|
+
@dataclass
|
|
44
|
+
class Invocation:
|
|
45
|
+
inputs: TensorTree
|
|
46
|
+
input_count: int
|
|
47
|
+
output: TensorTree | None = None
|
|
48
|
+
|
|
49
|
+
|
|
50
|
+
class _StreamAutograd(torch.autograd.Function):
|
|
51
|
+
@staticmethod
|
|
52
|
+
def forward(
|
|
53
|
+
ctx: Any,
|
|
54
|
+
model: StreamedModel,
|
|
55
|
+
call: Invocation,
|
|
56
|
+
*tensors: Tensor,
|
|
57
|
+
) -> tuple[Tensor, ...]:
|
|
58
|
+
from streamer import hidden_tensor
|
|
59
|
+
|
|
60
|
+
ctx.set_materialize_grads(False)
|
|
61
|
+
ctx.model = model
|
|
62
|
+
ctx.call = call
|
|
63
|
+
ctx.configuration_version = model._configuration_version
|
|
64
|
+
ctx.training_modes = tuple(module.training for module in model.modules())
|
|
65
|
+
ctx.input_count = call.input_count
|
|
66
|
+
ctx.master_count = len(tensors) - call.input_count
|
|
67
|
+
ctx.input_grad_flags = [tensor.requires_grad for tensor in tensors]
|
|
68
|
+
ctx.autocast = torch.is_autocast_enabled("cuda")
|
|
69
|
+
ctx.autocast_dtype = torch.get_autocast_dtype("cuda")
|
|
70
|
+
ctx.rng = []
|
|
71
|
+
hidden, args, kwargs = call.inputs.merge(tensors[: call.input_count])
|
|
72
|
+
saved_inputs: list[Tensor] = []
|
|
73
|
+
result: Any = hidden
|
|
74
|
+
|
|
75
|
+
def run(index: int, state: dict[str, Tensor]) -> None:
|
|
76
|
+
nonlocal result
|
|
77
|
+
current = hidden_tensor(result)
|
|
78
|
+
saved_inputs.append(current)
|
|
79
|
+
ctx.rng.append(
|
|
80
|
+
(torch.get_rng_state(), torch.cuda.get_rng_state(model.device))
|
|
81
|
+
)
|
|
82
|
+
result = model._call_block(index, state, current, args, kwargs)
|
|
83
|
+
|
|
84
|
+
model._execute(list(range(len(model.blocks))), run, (hidden, args, kwargs))
|
|
85
|
+
# Saving CPU master tensors also detects ordinary optimizer/in-place updates
|
|
86
|
+
# between forward and backward, before stale weights can be re-fetched.
|
|
87
|
+
ctx.save_for_backward(*tensors, *saved_inputs)
|
|
88
|
+
call.output, outputs = TensorTree.split(result)
|
|
89
|
+
ctx.mark_non_differentiable(
|
|
90
|
+
*[
|
|
91
|
+
out
|
|
92
|
+
for out in outputs
|
|
93
|
+
if not (out.is_floating_point() or out.is_complex())
|
|
94
|
+
]
|
|
95
|
+
)
|
|
96
|
+
return tuple(outputs)
|
|
97
|
+
|
|
98
|
+
@staticmethod
|
|
99
|
+
@once_differentiable
|
|
100
|
+
def backward(ctx: Any, *output_grads: Tensor | None) -> tuple[Any, ...]:
|
|
101
|
+
from streamer import hidden_tensor
|
|
102
|
+
|
|
103
|
+
model: StreamedModel = ctx.model
|
|
104
|
+
if model._configuration_version != ctx.configuration_version:
|
|
105
|
+
raise RuntimeError("Do not call to() between training forward and backward")
|
|
106
|
+
if tuple(module.training for module in model.modules()) != ctx.training_modes:
|
|
107
|
+
raise RuntimeError("Do not change train/eval mode before backward")
|
|
108
|
+
saved = ctx.saved_tensors
|
|
109
|
+
count = ctx.input_count
|
|
110
|
+
masters = saved[count : count + ctx.master_count]
|
|
111
|
+
block_inputs = saved[count + ctx.master_count :]
|
|
112
|
+
master_indices = {id(tensor): index for index, tensor in enumerate(masters)}
|
|
113
|
+
input_leaves = [
|
|
114
|
+
tensor.detach().requires_grad_(ctx.input_grad_flags[index])
|
|
115
|
+
for index, tensor in enumerate(saved[:count])
|
|
116
|
+
]
|
|
117
|
+
_, args, kwargs = ctx.call.inputs.merge(input_leaves)
|
|
118
|
+
extra_indices = [
|
|
119
|
+
index for index in range(1, count) if input_leaves[index].requires_grad
|
|
120
|
+
]
|
|
121
|
+
extra_grads: list[Tensor | None] = [None] * count
|
|
122
|
+
cpu_contributions: list[tuple[int, Tensor]] = []
|
|
123
|
+
incoming: Tensor | None = None
|
|
124
|
+
|
|
125
|
+
def run(index: int, state: dict[str, Tensor]) -> None:
|
|
126
|
+
nonlocal incoming
|
|
127
|
+
with (
|
|
128
|
+
torch.enable_grad(),
|
|
129
|
+
torch.random.fork_rng(devices=[model.device.index]),
|
|
130
|
+
):
|
|
131
|
+
torch.set_rng_state(ctx.rng[index][0])
|
|
132
|
+
torch.cuda.set_rng_state(ctx.rng[index][1], model.device)
|
|
133
|
+
hidden = block_inputs[index].detach().requires_grad_(True)
|
|
134
|
+
names = [
|
|
135
|
+
name
|
|
136
|
+
for name, parameter in model.blocks[index].named_parameters()
|
|
137
|
+
if parameter.requires_grad
|
|
138
|
+
]
|
|
139
|
+
targets = (
|
|
140
|
+
[hidden]
|
|
141
|
+
+ [input_leaves[i] for i in extra_indices]
|
|
142
|
+
+ [state[name] for name in names]
|
|
143
|
+
)
|
|
144
|
+
with torch.autocast(
|
|
145
|
+
"cuda",
|
|
146
|
+
enabled=ctx.autocast,
|
|
147
|
+
dtype=ctx.autocast_dtype,
|
|
148
|
+
# An outer autocast scope must not cache converted weights
|
|
149
|
+
# after this block retires, defeating parameter residency.
|
|
150
|
+
cache_enabled=False,
|
|
151
|
+
):
|
|
152
|
+
result = model._call_block(index, state, hidden, args, kwargs)
|
|
153
|
+
if index == len(model.blocks) - 1:
|
|
154
|
+
_, outputs = TensorTree.split(result)
|
|
155
|
+
pairs = [
|
|
156
|
+
(out, grad)
|
|
157
|
+
for out, grad in zip(outputs, output_grads, strict=True)
|
|
158
|
+
if out.requires_grad and grad is not None
|
|
159
|
+
]
|
|
160
|
+
else:
|
|
161
|
+
out = hidden_tensor(result)
|
|
162
|
+
pairs = (
|
|
163
|
+
[(out, incoming)]
|
|
164
|
+
if out.requires_grad and incoming is not None
|
|
165
|
+
else []
|
|
166
|
+
)
|
|
167
|
+
if pairs:
|
|
168
|
+
gradients = torch.autograd.grad(
|
|
169
|
+
[pair[0] for pair in pairs],
|
|
170
|
+
targets,
|
|
171
|
+
[pair[1] for pair in pairs],
|
|
172
|
+
allow_unused=True,
|
|
173
|
+
)
|
|
174
|
+
else:
|
|
175
|
+
gradients = (None,) * len(targets)
|
|
176
|
+
incoming = gradients[0]
|
|
177
|
+
for input_index, gradient in zip(
|
|
178
|
+
extra_indices, gradients[1:], strict=False
|
|
179
|
+
):
|
|
180
|
+
if gradient is not None:
|
|
181
|
+
previous = extra_grads[input_index]
|
|
182
|
+
extra_grads[input_index] = (
|
|
183
|
+
gradient if previous is None else previous + gradient
|
|
184
|
+
)
|
|
185
|
+
parameters = dict(model.blocks[index].named_parameters())
|
|
186
|
+
for name, gradient in zip(
|
|
187
|
+
names, gradients[1 + len(extra_indices) :], strict=True
|
|
188
|
+
):
|
|
189
|
+
if gradient is None:
|
|
190
|
+
continue
|
|
191
|
+
parameter = parameters[name]
|
|
192
|
+
cpu = torch.empty_like(parameter, device="cpu", pin_memory=True)
|
|
193
|
+
# D2H runs on compute after the gradient kernels. Slot retirement's
|
|
194
|
+
# completion event also proves these pinned destinations are readable.
|
|
195
|
+
cpu.copy_(gradient, non_blocking=True)
|
|
196
|
+
gradient.record_stream(model.compute_stream)
|
|
197
|
+
model.gradient_transfer_bytes += tensor_bytes(gradient)
|
|
198
|
+
cpu_contributions.append((master_indices[id(parameter)], cpu))
|
|
199
|
+
|
|
200
|
+
model._execute(
|
|
201
|
+
list(reversed(range(len(model.blocks)))),
|
|
202
|
+
run,
|
|
203
|
+
(block_inputs, input_leaves, output_grads),
|
|
204
|
+
grad=True,
|
|
205
|
+
)
|
|
206
|
+
# _execute has retired all completion events, including the D2H copies.
|
|
207
|
+
master_grads: list[Tensor | None] = [None] * len(masters)
|
|
208
|
+
for index, gradient in cpu_contributions:
|
|
209
|
+
if master_grads[index] is None:
|
|
210
|
+
master_grads[index] = gradient
|
|
211
|
+
else:
|
|
212
|
+
master_grads[index].add_(gradient)
|
|
213
|
+
extra_grads[0] = incoming if ctx.input_grad_flags[0] else None
|
|
214
|
+
return (None, None, *extra_grads, *master_grads)
|
|
215
|
+
|
|
216
|
+
|
|
217
|
+
def training_forward(
|
|
218
|
+
model: StreamedModel,
|
|
219
|
+
hidden: Tensor,
|
|
220
|
+
args: tuple[Any, ...],
|
|
221
|
+
kwargs: dict[str, Any],
|
|
222
|
+
) -> Any:
|
|
223
|
+
if not model.blocks:
|
|
224
|
+
return hidden
|
|
225
|
+
if not hidden.is_floating_point():
|
|
226
|
+
raise TypeError("Training requires floating-point hidden states")
|
|
227
|
+
tree, inputs = TensorTree.split((hidden, args, kwargs))
|
|
228
|
+
call = Invocation(tree, len(inputs))
|
|
229
|
+
# Include buffers in saved state so registered-state changes are version checked.
|
|
230
|
+
masters = list(model.parameters()) + list(model.buffers())
|
|
231
|
+
outputs = _StreamAutograd.apply(model, call, *inputs, *masters)
|
|
232
|
+
assert call.output is not None
|
|
233
|
+
return call.output.merge(outputs)
|
|
@@ -0,0 +1,298 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: block-streamer
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Bounded, asynchronous parameter streaming for PyTorch blocks
|
|
5
|
+
License-Expression: Apache-2.0
|
|
6
|
+
Project-URL: Repository, https://github.com/hareramray/BlockStreamer
|
|
7
|
+
Project-URL: Issues, https://github.com/hareramray/BlockStreamer/issues
|
|
8
|
+
Keywords: pytorch,cuda,offloading,inference,training
|
|
9
|
+
Classifier: Development Status :: 3 - Alpha
|
|
10
|
+
Classifier: Intended Audience :: Developers
|
|
11
|
+
Classifier: Programming Language :: Python :: 3
|
|
12
|
+
Classifier: Topic :: Scientific/Engineering :: Artificial Intelligence
|
|
13
|
+
Requires-Python: >=3.11
|
|
14
|
+
Description-Content-Type: text/markdown
|
|
15
|
+
License-File: LICENSE
|
|
16
|
+
Requires-Dist: torch>=2.4
|
|
17
|
+
Provides-Extra: dev
|
|
18
|
+
Requires-Dist: pytest>=8; extra == "dev"
|
|
19
|
+
Requires-Dist: ruff>=0.9; extra == "dev"
|
|
20
|
+
Requires-Dist: matplotlib>=3.8; extra == "dev"
|
|
21
|
+
Dynamic: license-file
|
|
22
|
+
|
|
23
|
+
# BlockStreamer
|
|
24
|
+
|
|
25
|
+
Licensed under the [Apache License 2.0](https://github.com/hareramray/BlockStreamer/blob/main/LICENSE).
|
|
26
|
+
|
|
27
|
+
Execute ordered PyTorch blocks with pinned CPU master weights, asynchronous CUDA
|
|
28
|
+
prefetch, and at most `prefetch_ahead + 1` resident blocks. Includes inference,
|
|
29
|
+
first-order training with backward re-fetch, correctness tests, and a measured
|
|
30
|
+
transfer/compute crossover benchmark.
|
|
31
|
+
|
|
32
|
+
## Prior art and binding decision
|
|
33
|
+
|
|
34
|
+
Accelerate's `cpu_offload_with_hook` leaves a module on the execution device until
|
|
35
|
+
its offload hook runs; BlockStreamer instead schedules an explicit bounded window
|
|
36
|
+
of individual blocks and transfer-ready events.
|
|
37
|
+
[Accelerate documentation](https://huggingface.co/docs/accelerate/en/package_reference/big_modeling#accelerate.cpu_offload_with_hook)
|
|
38
|
+
ZeRO-Infinity is a broader training system that spans GPU, CPU, and NVMe memory;
|
|
39
|
+
this project targets one GPU, CPU parameter storage, and an ordered block list.
|
|
40
|
+
[ZeRO-Infinity paper](https://arxiv.org/abs/2104.07857)
|
|
41
|
+
FSDP `CPUOffload` moves parameters and gradients to CPU within FSDP's sharding and
|
|
42
|
+
distributed training machinery; this library has no distributed collectives or
|
|
43
|
+
parameter sharding.
|
|
44
|
+
[FSDP documentation](https://docs.pytorch.org/docs/stable/fsdp.html#torch.distributed.fsdp.CPUOffload)
|
|
45
|
+
BlockStreamer's smaller scope makes the residency policy explicit, at the cost of
|
|
46
|
+
less general model execution and substantial Python/event overhead for tiny blocks.
|
|
47
|
+
|
|
48
|
+
**Binding mechanism: `torch.func.functional_call`.** Each block executes with a
|
|
49
|
+
dictionary of its staged GPU parameters and buffers, with strict key checking and
|
|
50
|
+
PyTorch's tied-weight handling. Registered parameters stay on pinned CPU storage.
|
|
51
|
+
Construction and `.to()` replace CPU storage to pin/convert it while preserving
|
|
52
|
+
`Parameter` identity; `.data` is never used to bind staged GPU weights for compute.
|
|
53
|
+
[Functional-call documentation](https://docs.pytorch.org/docs/stable/generated/torch.func.functional_call.html)
|
|
54
|
+
|
|
55
|
+
The tradeoff is functional state discipline: blocks must not mutate registered
|
|
56
|
+
parameters or buffers, retain staged tensors, or use custom kernels that cache
|
|
57
|
+
parameter pointers outside module lookups. Detected registered-state mutation
|
|
58
|
+
raises an error. Python attributes, global state, hooks, and opaque external caches
|
|
59
|
+
cannot all be audited automatically; callers must keep those free of side effects.
|
|
60
|
+
Training BatchNorm's running-state updates and mutable KV caches are unsupported.
|
|
61
|
+
Ordinary dropout is supported through RNG replay during recomputation.
|
|
62
|
+
|
|
63
|
+
## Install and run
|
|
64
|
+
|
|
65
|
+
Requires Python 3.11+, PyTorch 2.4+, and a CUDA GPU. Install a CUDA-enabled PyTorch
|
|
66
|
+
wheel suitable for your GPU first. For the published package:
|
|
67
|
+
|
|
68
|
+
```bash
|
|
69
|
+
python -m pip install block-streamer
|
|
70
|
+
```
|
|
71
|
+
|
|
72
|
+
For development, clone the repository and install from its root:
|
|
73
|
+
|
|
74
|
+
```bash
|
|
75
|
+
python -m pip install -e ".[dev]"
|
|
76
|
+
python -m pytest -q
|
|
77
|
+
```
|
|
78
|
+
|
|
79
|
+
The development environment here uses `.venv` with the preinstalled CUDA PyTorch
|
|
80
|
+
available through system site packages. On this Windows workspace:
|
|
81
|
+
|
|
82
|
+
```powershell
|
|
83
|
+
.venv/Scripts/python.exe -m pytest -q
|
|
84
|
+
.venv/Scripts/python.exe benchmark.py --widths 128 256 512 1024 --tokens 32 2048 8192 --runs 10 --warmup 4
|
|
85
|
+
```
|
|
86
|
+
|
|
87
|
+
```python
|
|
88
|
+
import torch
|
|
89
|
+
from torch import nn
|
|
90
|
+
from block_streamer import StreamedModel
|
|
91
|
+
|
|
92
|
+
blocks = nn.Sequential(nn.Linear(256, 512), nn.GELU(), nn.Linear(512, 256))
|
|
93
|
+
x = torch.randn(16, 256, device="cuda:0", dtype=torch.bfloat16)
|
|
94
|
+
|
|
95
|
+
with StreamedModel(
|
|
96
|
+
blocks, device="cuda:0", prefetch_ahead=1, dtype=torch.bfloat16
|
|
97
|
+
) as streamed:
|
|
98
|
+
out = streamed(x)
|
|
99
|
+
print(streamed.stats())
|
|
100
|
+
```
|
|
101
|
+
|
|
102
|
+
Construction takes ownership of the supplied `Sequential`, `ModuleList`, or list
|
|
103
|
+
of modules, pins their parameters **and buffers** on CPU, and defaults to `.eval()`.
|
|
104
|
+
Make a deepcopy first if another model must retain independent state. Evaluation
|
|
105
|
+
forwards disable autograd, including when the caller did not use `no_grad()`.
|
|
106
|
+
Call `.train()` to enable the training path. `.eval()` propagates to every block.
|
|
107
|
+
|
|
108
|
+
Inputs must already be on the execution device and have a suitable dtype. Additional
|
|
109
|
+
positional and keyword arguments are passed unchanged to **every** block:
|
|
110
|
+
|
|
111
|
+
```python
|
|
112
|
+
out = streamed(x, attention_mask=mask, position_ids=positions)
|
|
113
|
+
```
|
|
114
|
+
|
|
115
|
+
Every block must accept the supplied arguments. A block may return a tensor or a
|
|
116
|
+
tuple whose first element is the next hidden state. Intermediate auxiliary tuple
|
|
117
|
+
elements are discarded; the final block's entire result is returned. Tensor leaves
|
|
118
|
+
in ordinary tuple/list/dict output trees are cloned so a returned parameter view
|
|
119
|
+
cannot keep staged weights resident. There is no automatic per-layer KV-cache
|
|
120
|
+
selection or collection; use adapter blocks to express that policy. Read-only
|
|
121
|
+
attention masks, positions, rotary tensors, and cache values can pass through.
|
|
122
|
+
|
|
123
|
+
`streamed.to(device="cuda:0", dtype=torch.float16)` changes execution placement and
|
|
124
|
+
repins CPU state. Perform conversion before constructing an optimizer or a pending
|
|
125
|
+
training graph. CPU execution and inherited `.cuda()`, `.cpu()`, `.half()`, and
|
|
126
|
+
parent-module conversions are rejected; use this wrapper's `.to()` instead.
|
|
127
|
+
`close()` and context exit drain outstanding work; the wrapper remains reusable.
|
|
128
|
+
|
|
129
|
+
## Streams, residency, and memory budget
|
|
130
|
+
|
|
131
|
+
The engine uses two streams: the compute stream active at construction and a
|
|
132
|
+
separate transfer stream. Borrowing the compute stream avoids creating persistent
|
|
133
|
+
cuBLAS workspaces for every new wrapper. A call made on another CUDA stream is
|
|
134
|
+
bridged to the compute stream, with input storage protected by `record_stream()`.
|
|
135
|
+
|
|
136
|
+
The scheduler initially stages up to `prefetch_ahead + 1` blocks. Compute waits on
|
|
137
|
+
each block's H2D-ready event. **Every transfer-created tensor consumed by compute
|
|
138
|
+
calls `record_stream(compute_stream)` in `BufferPool.acquire()`**, protecting it
|
|
139
|
+
from premature caching-allocator reuse.
|
|
140
|
+
[PyTorch allocator documentation](https://docs.pytorch.org/docs/stable/generated/torch.Tensor.record_stream.html)
|
|
141
|
+
A compute-completion event is host-synchronized before eviction and replacement
|
|
142
|
+
staging. This conservative retirement rule enforces the actual live-block limit,
|
|
143
|
+
including in-flight transfers, and introduces host scheduling overhead. The forward
|
|
144
|
+
returns after its work completes; H2D and compute can still overlap within it.
|
|
145
|
+
|
|
146
|
+
The GPU pool uses PyTorch's caching allocator with event-retired slots. Allocations
|
|
147
|
+
are sized per block, so heterogeneous shapes, integer buffers, and mixed state
|
|
148
|
+
dtypes require no homogeneous-buffer fallback. `prefetch_ahead=0` is supported;
|
|
149
|
+
`1` provides two slots. Parameter-free blocks still count as logical slots.
|
|
150
|
+
CUDA **reserved** cache memory may exceed live tensor payload and is not the
|
|
151
|
+
residency invariant. For heterogeneous models the byte bound is the largest live
|
|
152
|
+
window's summed state size, not a fixed number of bytes per block.
|
|
153
|
+
|
|
154
|
+
Set `buffer_budget_bytes=...` for a per-slot parameter-plus-buffer payload limit.
|
|
155
|
+
An oversized block raises a clear error before its copy. This is not a total-VRAM
|
|
156
|
+
budget: activations, CUDA library workspaces, gradients, and allocator rounding
|
|
157
|
+
are additional. Every H2D source is checked for pinned CPU storage immediately
|
|
158
|
+
before copying; an unpinned source fails loudly. Meta/sparse state and distinct
|
|
159
|
+
tensor objects sharing backing storage are rejected. Weight tying by sharing the
|
|
160
|
+
same `Parameter` object is supported within and across blocks.
|
|
161
|
+
|
|
162
|
+
`stats()` reports cumulative H2D bytes/time, D2H gradient bytes, GPU transfer-wait
|
|
163
|
+
time (`stall_ms`), host eviction wait time, current/peak resident blocks, and peak
|
|
164
|
+
parameter/state payload bytes. GPU stall time measures event waits on the compute
|
|
165
|
+
stream; it excludes host launch delays. Host eviction wait can include compute
|
|
166
|
+
and transfer waiting, so these two times must not be added as independent costs.
|
|
167
|
+
`residency_history` retains the last 4,096 transitions; an optional
|
|
168
|
+
`residency_observer` receives every transition. `reset_stats()` resets all counters.
|
|
169
|
+
|
|
170
|
+
## Training design and usage
|
|
171
|
+
|
|
172
|
+
The inference suite passed on CUDA before the training implementation was added.
|
|
173
|
+
The training design makes these choices:
|
|
174
|
+
|
|
175
|
+
1. **Re-fetch weights during backward.** Keeping forward weights would require
|
|
176
|
+
O(all blocks) parameter VRAM. Instead, save block inputs on GPU, discard staged
|
|
177
|
+
weights, and re-fetch/recompute one block at a time during backward. A training
|
|
178
|
+
step transfers each block's state twice and performs an extra forward compute.
|
|
179
|
+
Saved activations remain O(depth); activation offloading is outside this project.
|
|
180
|
+
2. **Offload gradients after each block.** Compute that block's gradients on GPU,
|
|
181
|
+
copy them into pinned CPU tensors on the compute stream, and make CPU reads wait
|
|
182
|
+
for the completion event. Return CPU parameter gradients through autograd so
|
|
183
|
+
normal `.grad` accumulation works. Peak GPU memory also includes one block's
|
|
184
|
+
gradients and recomputation graph, plus saved activations and input gradients.
|
|
185
|
+
Shared parameters' CPU gradient contributions are summed after copies finish.
|
|
186
|
+
3. **CPU optimizer and state.** Use an ordinary CPU optimizer on `model.parameters()`.
|
|
187
|
+
The optimizer step runs on CPU and does not stream to GPU. This incurs host RAM
|
|
188
|
+
for all gradients/optimizer state. No automatic fp32 master-weight conversion,
|
|
189
|
+
fused offloaded optimizer, or integrated loss scaling is provided.
|
|
190
|
+
4. **Custom `torch.autograd.Function`.** It owns the forward/backward schedule,
|
|
191
|
+
saves version-checked master state and block inputs, then visits blocks in
|
|
192
|
+
reverse with the same bounded prefetch window. Block N-1 is fetched ahead of
|
|
193
|
+
its recompute/backward while block N executes. This avoids relying on module
|
|
194
|
+
hook order and explicitly returns gradients for tensor arguments and weights.
|
|
195
|
+
|
|
196
|
+
```python
|
|
197
|
+
streamed = StreamedModel(blocks, dtype=torch.float32).train()
|
|
198
|
+
optimizer = torch.optim.Adam(streamed.parameters(), lr=1e-3)
|
|
199
|
+
x = torch.randn(16, 256, device="cuda")
|
|
200
|
+
target = torch.zeros_like(x)
|
|
201
|
+
|
|
202
|
+
for _ in range(10):
|
|
203
|
+
optimizer.zero_grad(set_to_none=True)
|
|
204
|
+
loss = (streamed(x) - target).float().square().mean()
|
|
205
|
+
loss.backward()
|
|
206
|
+
optimizer.step() # CPU parameters, CPU gradients, CPU optimizer state
|
|
207
|
+
```
|
|
208
|
+
|
|
209
|
+
Recomputation restores PyTorch CPU/CUDA RNG states and CUDA autocast settings.
|
|
210
|
+
Backward does not advance the caller's RNG. First-order gradients, frozen/unused
|
|
211
|
+
parameters, tied weights, extra tensor arguments, and final tuple-output losses
|
|
212
|
+
are supported. Higher-order differentiation, `torch.compile`, CUDA graph capture,
|
|
213
|
+
distributed execution, and concurrent/reentrant calls are unsupported. Modules
|
|
214
|
+
must not modify block inputs in place, change execution behavior between forward
|
|
215
|
+
and backward, or retain GPU weights in external state. Normal in-place changes to
|
|
216
|
+
saved tensors are version-checked; edits through `.data` bypass PyTorch's protection.
|
|
217
|
+
|
|
218
|
+
## Measured crossover and memory
|
|
219
|
+
|
|
220
|
+
|
|
221
|
+
|
|
222
|
+
Local measurement: NVIDIA GeForce RTX 5050 Laptop GPU (8 GB), Windows WDDM,
|
|
223
|
+
PyTorch 2.11.0+cu128 / CUDA runtime 12.8, bf16, six heterogeneous MLP blocks,
|
|
224
|
+
`prefetch_ahead=1`, four warmups and ten timed runs. These are measurements on this
|
|
225
|
+
machine, not predictions for a desktop PCIe Gen4 x16 link. The benchmark records
|
|
226
|
+
31.5 GB/s as the nominal Gen4 x16 reference but uses **measured pinned H2D time**
|
|
227
|
+
for its conclusions. See [the complete report](https://github.com/hareramray/BlockStreamer/blob/main/results/benchmark.json).
|
|
228
|
+
|
|
229
|
+
**Headline:** at 32 and 2,048 tokens, the sampled compute/H2D crossover falls
|
|
230
|
+
between widths 128 and 256. At 8,192 tokens, compute time exceeds H2D time at every
|
|
231
|
+
sampled width; no width crossover was observed. At width 1,024, increasing tokens
|
|
232
|
+
from 2,048 to 8,192 changes the measured regime from bandwidth-bound to compute-bound.
|
|
233
|
+
Small-block CUDA event intervals include host launch gaps; the small-width
|
|
234
|
+
"compute-bound" label means the measured compute path takes longer than H2D,
|
|
235
|
+
not that GPU arithmetic units are saturated. This sweep is an empirical roofline
|
|
236
|
+
diagnostic, not a hardware FLOP/s roofline or a universal crossover constant.
|
|
237
|
+
|
|
238
|
+
| Width / tokens | GPU median ms | Streamed median ms | GPU peak MiB | Streamed peak MiB | Activation/workspace increment MiB |
|
|
239
|
+
| --- | ---: | ---: | ---: | ---: | ---: |
|
|
240
|
+
| 1,024 / 32 | 0.569 | 10.524 | 68.625 | 28.625 | 0.438 |
|
|
241
|
+
| 1,024 / 2,048 | 5.915 | 14.883 | 100.125 | 60.125 | 28.000 |
|
|
242
|
+
| 1,024 / 8,192 | 24.304 | 29.825 | 196.125 | 156.125 | 112.000 |
|
|
243
|
+
|
|
244
|
+
For these width-1,024 cases, baseline parameter payload is 60 MiB and streamed
|
|
245
|
+
peak parameter payload is 20 MiB. The 8,192-token activation/workspace increment
|
|
246
|
+
alone is 112 MiB: parameter streaming does not eliminate activation-dominated VRAM.
|
|
247
|
+
This implementation saves memory but **was slower in every sampled case**.
|
|
248
|
+
|
|
249
|
+
The benchmark reports raw `torch.cuda.max_memory_allocated()` for total peak VRAM,
|
|
250
|
+
exact parameter/state tensor payload maxima, and an **independently measured**
|
|
251
|
+
activation/workspace increment: peak baseline allocation above the warmed baseline
|
|
252
|
+
with weights already resident. Existing input/library allocations are also recorded.
|
|
253
|
+
Separate maxima occur at different times; subtracting peak parameter payload from
|
|
254
|
+
total peak does not produce an exact activation peak. PyTorch's aggregate allocator
|
|
255
|
+
counter also cannot distinguish an activation from a temporary workspace.
|
|
256
|
+
Therefore an exact additive parameter-versus-activation split is not claimed.
|
|
257
|
+
|
|
258
|
+
Latency uses synchronized wall-clock intervals and reports medians, means,
|
|
259
|
+
population variance, minima, and maxima. The requested overlap score is:
|
|
260
|
+
|
|
261
|
+
```text
|
|
262
|
+
1 - (streamed_median_ms - all_on_GPU_median_ms) / isolated_H2D_ms
|
|
263
|
+
```
|
|
264
|
+
|
|
265
|
+
It is not clamped: Python, event, cloning, and scheduling overhead can make it
|
|
266
|
+
negative; noise can put it above one. The score is 0.454 for width 1,024 / 8,192
|
|
267
|
+
tokens in this run. Kernel overlap cannot fully hide transfer when per-block H2D
|
|
268
|
+
time exceeds compute time. Increasing token count changes arithmetic intensity;
|
|
269
|
+
increasing width alone need not produce a crossover.
|
|
270
|
+
|
|
271
|
+
## Profiler and validation status
|
|
272
|
+
|
|
273
|
+
`benchmark.py` exports `results/trace.json`, readable by Chrome tracing or Perfetto,
|
|
274
|
+
and checks whether GPU activities are present. On this machine CUPTI initialization
|
|
275
|
+
returned `CUPTI_ERROR_INVALID_DEVICE`, so the exported trace contains **CPU events
|
|
276
|
+
only** and `trace_gpu_activity` is `false`. GPU timeline overlap is therefore **not
|
|
277
|
+
visually verified here**. CUDA-event timing, real GPU parity tests, and memory
|
|
278
|
+
measurements did run. Re-run on a compatible CUPTI/driver setup to capture GPU
|
|
279
|
+
kernels and copies; `--no-trace` explicitly skips profiler collection.
|
|
280
|
+
|
|
281
|
+
The final local suite passed **32 tests** on CUDA, with Ruff lint/format checks
|
|
282
|
+
also passing. Tests cover inference in fp32/bf16/fp16 at prefetch depths 0–3,
|
|
283
|
+
heterogeneous blocks and nonpersistent buffers, extra arguments and tuple results,
|
|
284
|
+
every residency transition, a 100-iteration bandwidth-starved allocator stress,
|
|
285
|
+
nondefault caller streams, inference mode, output aliases, tied weights, unpinned
|
|
286
|
+
and over-budget errors, and exception cleanup. Training tests cover fp32/bf16/fp16
|
|
287
|
+
gradient parity at depths 1–3, CPU pinned gradients, extra-input gradients, dropout
|
|
288
|
+
RNG replay, unused/shared parameters, accumulation, autocast with frozen weights,
|
|
289
|
+
CPU Adam state placement, and a 12-step SGD toy loss curve.
|
|
290
|
+
|
|
291
|
+
Inference `atol=rtol` is `1e-5` for fp32, `8e-3` for bf16, and `1e-3` for fp16,
|
|
292
|
+
allowing roughly one low-precision rounding unit at unit scale. Backward
|
|
293
|
+
`(atol, rtol)` is `(2e-5, 2e-4)`, `(2e-3, 3e-2)`, and `(5e-4, 5e-3)` respectively;
|
|
294
|
+
backward includes reductions and multiple gradient contributions. The convergence
|
|
295
|
+
curves use fp32 with `(2e-6, 2e-5)` tolerances and must decrease by at least 10%.
|
|
296
|
+
These checks are evidence for the tested workloads, not proof for arbitrary custom
|
|
297
|
+
modules or hardware. The environment emitted a Triton CUDA-toolkit discovery
|
|
298
|
+
warning; the tests use PyTorch CUDA operations and do not require Triton compilation.
|
|
@@ -0,0 +1,9 @@
|
|
|
1
|
+
memory_pool.py,sha256=0WZRxiW40QskJyozR3sLYM605Xav8krExLcb7SGKJU4,7787
|
|
2
|
+
streamer.py,sha256=Z6q3lXutVqRHTXPxgeGu32je-bJxS89L69HnUqb6Bb0,9387
|
|
3
|
+
block_streamer/__init__.py,sha256=oyBCIsDinH6UddoTM5dcUcSXUWm-Mz5A-f_7sUcbvfA,97
|
|
4
|
+
block_streamer/_autograd.py,sha256=P5N6PrNFfKq5aqywdqpCGinfxHM57HKt2lWaBjYmQbI,9438
|
|
5
|
+
block_streamer-0.1.0.dist-info/licenses/LICENSE,sha256=z8d0m5b2O9McPEK1xHG_dWgUBT6EfBDz6wA0F7xSPTA,11358
|
|
6
|
+
block_streamer-0.1.0.dist-info/METADATA,sha256=0ApH7YgRl9A4eg6J3EJAUdbZniVNBB5wLfbAtsvUg_U,17177
|
|
7
|
+
block_streamer-0.1.0.dist-info/WHEEL,sha256=YVMoNqKzERt-wjUZwJ33xBGAwnFl-4cqbYkTtWa4itE,91
|
|
8
|
+
block_streamer-0.1.0.dist-info/top_level.txt,sha256=BpKpp9UuLaPkcBAweNHk_qJ0OpO37rcLzlI5jTofnKM,36
|
|
9
|
+
block_streamer-0.1.0.dist-info/RECORD,,
|
|
@@ -0,0 +1,202 @@
|
|
|
1
|
+
|
|
2
|
+
Apache License
|
|
3
|
+
Version 2.0, January 2004
|
|
4
|
+
http://www.apache.org/licenses/
|
|
5
|
+
|
|
6
|
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
|
7
|
+
|
|
8
|
+
1. Definitions.
|
|
9
|
+
|
|
10
|
+
"License" shall mean the terms and conditions for use, reproduction,
|
|
11
|
+
and distribution as defined by Sections 1 through 9 of this document.
|
|
12
|
+
|
|
13
|
+
"Licensor" shall mean the copyright owner or entity authorized by
|
|
14
|
+
the copyright owner that is granting the License.
|
|
15
|
+
|
|
16
|
+
"Legal Entity" shall mean the union of the acting entity and all
|
|
17
|
+
other entities that control, are controlled by, or are under common
|
|
18
|
+
control with that entity. For the purposes of this definition,
|
|
19
|
+
"control" means (i) the power, direct or indirect, to cause the
|
|
20
|
+
direction or management of such entity, whether by contract or
|
|
21
|
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
|
22
|
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
|
23
|
+
|
|
24
|
+
"You" (or "Your") shall mean an individual or Legal Entity
|
|
25
|
+
exercising permissions granted by this License.
|
|
26
|
+
|
|
27
|
+
"Source" form shall mean the preferred form for making modifications,
|
|
28
|
+
including but not limited to software source code, documentation
|
|
29
|
+
source, and configuration files.
|
|
30
|
+
|
|
31
|
+
"Object" form shall mean any form resulting from mechanical
|
|
32
|
+
transformation or translation of a Source form, including but
|
|
33
|
+
not limited to compiled object code, generated documentation,
|
|
34
|
+
and conversions to other media types.
|
|
35
|
+
|
|
36
|
+
"Work" shall mean the work of authorship, whether in Source or
|
|
37
|
+
Object form, made available under the License, as indicated by a
|
|
38
|
+
copyright notice that is included in or attached to the work
|
|
39
|
+
(an example is provided in the Appendix below).
|
|
40
|
+
|
|
41
|
+
"Derivative Works" shall mean any work, whether in Source or Object
|
|
42
|
+
form, that is based on (or derived from) the Work and for which the
|
|
43
|
+
editorial revisions, annotations, elaborations, or other modifications
|
|
44
|
+
represent, as a whole, an original work of authorship. For the purposes
|
|
45
|
+
of this License, Derivative Works shall not include works that remain
|
|
46
|
+
separable from, or merely link (or bind by name) to the interfaces of,
|
|
47
|
+
the Work and Derivative Works thereof.
|
|
48
|
+
|
|
49
|
+
"Contribution" shall mean any work of authorship, including
|
|
50
|
+
the original version of the Work and any modifications or additions
|
|
51
|
+
to that Work or Derivative Works thereof, that is intentionally
|
|
52
|
+
submitted to Licensor for inclusion in the Work by the copyright owner
|
|
53
|
+
or by an individual or Legal Entity authorized to submit on behalf of
|
|
54
|
+
the copyright owner. For the purposes of this definition, "submitted"
|
|
55
|
+
means any form of electronic, verbal, or written communication sent
|
|
56
|
+
to the Licensor or its representatives, including but not limited to
|
|
57
|
+
communication on electronic mailing lists, source code control systems,
|
|
58
|
+
and issue tracking systems that are managed by, or on behalf of, the
|
|
59
|
+
Licensor for the purpose of discussing and improving the Work, but
|
|
60
|
+
excluding communication that is conspicuously marked or otherwise
|
|
61
|
+
designated in writing by the copyright owner as "Not a Contribution."
|
|
62
|
+
|
|
63
|
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
|
64
|
+
on behalf of whom a Contribution has been received by Licensor and
|
|
65
|
+
subsequently incorporated within the Work.
|
|
66
|
+
|
|
67
|
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
|
68
|
+
this License, each Contributor hereby grants to You a perpetual,
|
|
69
|
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
|
70
|
+
copyright license to reproduce, prepare Derivative Works of,
|
|
71
|
+
publicly display, publicly perform, sublicense, and distribute the
|
|
72
|
+
Work and such Derivative Works in Source or Object form.
|
|
73
|
+
|
|
74
|
+
3. Grant of Patent License. Subject to the terms and conditions of
|
|
75
|
+
this License, each Contributor hereby grants to You a perpetual,
|
|
76
|
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
|
77
|
+
(except as stated in this section) patent license to make, have made,
|
|
78
|
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
|
79
|
+
where such license applies only to those patent claims licensable
|
|
80
|
+
by such Contributor that are necessarily infringed by their
|
|
81
|
+
Contribution(s) alone or by combination of their Contribution(s)
|
|
82
|
+
with the Work to which such Contribution(s) was submitted. If You
|
|
83
|
+
institute patent litigation against any entity (including a
|
|
84
|
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
|
85
|
+
or a Contribution incorporated within the Work constitutes direct
|
|
86
|
+
or contributory patent infringement, then any patent licenses
|
|
87
|
+
granted to You under this License for that Work shall terminate
|
|
88
|
+
as of the date such litigation is filed.
|
|
89
|
+
|
|
90
|
+
4. Redistribution. You may reproduce and distribute copies of the
|
|
91
|
+
Work or Derivative Works thereof in any medium, with or without
|
|
92
|
+
modifications, and in Source or Object form, provided that You
|
|
93
|
+
meet the following conditions:
|
|
94
|
+
|
|
95
|
+
(a) You must give any other recipients of the Work or
|
|
96
|
+
Derivative Works a copy of this License; and
|
|
97
|
+
|
|
98
|
+
(b) You must cause any modified files to carry prominent notices
|
|
99
|
+
stating that You changed the files; and
|
|
100
|
+
|
|
101
|
+
(c) You must retain, in the Source form of any Derivative Works
|
|
102
|
+
that You distribute, all copyright, patent, trademark, and
|
|
103
|
+
attribution notices from the Source form of the Work,
|
|
104
|
+
excluding those notices that do not pertain to any part of
|
|
105
|
+
the Derivative Works; and
|
|
106
|
+
|
|
107
|
+
(d) If the Work includes a "NOTICE" text file as part of its
|
|
108
|
+
distribution, then any Derivative Works that You distribute must
|
|
109
|
+
include a readable copy of the attribution notices contained
|
|
110
|
+
within such NOTICE file, excluding those notices that do not
|
|
111
|
+
pertain to any part of the Derivative Works, in at least one
|
|
112
|
+
of the following places: within a NOTICE text file distributed
|
|
113
|
+
as part of the Derivative Works; within the Source form or
|
|
114
|
+
documentation, if provided along with the Derivative Works; or,
|
|
115
|
+
within a display generated by the Derivative Works, if and
|
|
116
|
+
wherever such third-party notices normally appear. The contents
|
|
117
|
+
of the NOTICE file are for informational purposes only and
|
|
118
|
+
do not modify the License. You may add Your own attribution
|
|
119
|
+
notices within Derivative Works that You distribute, alongside
|
|
120
|
+
or as an addendum to the NOTICE text from the Work, provided
|
|
121
|
+
that such additional attribution notices cannot be construed
|
|
122
|
+
as modifying the License.
|
|
123
|
+
|
|
124
|
+
You may add Your own copyright statement to Your modifications and
|
|
125
|
+
may provide additional or different license terms and conditions
|
|
126
|
+
for use, reproduction, or distribution of Your modifications, or
|
|
127
|
+
for any such Derivative Works as a whole, provided Your use,
|
|
128
|
+
reproduction, and distribution of the Work otherwise complies with
|
|
129
|
+
the conditions stated in this License.
|
|
130
|
+
|
|
131
|
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
|
132
|
+
any Contribution intentionally submitted for inclusion in the Work
|
|
133
|
+
by You to the Licensor shall be under the terms and conditions of
|
|
134
|
+
this License, without any additional terms or conditions.
|
|
135
|
+
Notwithstanding the above, nothing herein shall supersede or modify
|
|
136
|
+
the terms of any separate license agreement you may have executed
|
|
137
|
+
with Licensor regarding such Contributions.
|
|
138
|
+
|
|
139
|
+
6. Trademarks. This License does not grant permission to use the trade
|
|
140
|
+
names, trademarks, service marks, or product names of the Licensor,
|
|
141
|
+
except as required for reasonable and customary use in describing the
|
|
142
|
+
origin of the Work and reproducing the content of the NOTICE file.
|
|
143
|
+
|
|
144
|
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
|
145
|
+
agreed to in writing, Licensor provides the Work (and each
|
|
146
|
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
|
147
|
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
|
148
|
+
implied, including, without limitation, any warranties or conditions
|
|
149
|
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
|
150
|
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
|
151
|
+
appropriateness of using or redistributing the Work and assume any
|
|
152
|
+
risks associated with Your exercise of permissions under this License.
|
|
153
|
+
|
|
154
|
+
8. Limitation of Liability. In no event and under no legal theory,
|
|
155
|
+
whether in tort (including negligence), contract, or otherwise,
|
|
156
|
+
unless required by applicable law (such as deliberate and grossly
|
|
157
|
+
negligent acts) or agreed to in writing, shall any Contributor be
|
|
158
|
+
liable to You for damages, including any direct, indirect, special,
|
|
159
|
+
incidental, or consequential damages of any character arising as a
|
|
160
|
+
result of this License or out of the use or inability to use the
|
|
161
|
+
Work (including but not limited to damages for loss of goodwill,
|
|
162
|
+
work stoppage, computer failure or malfunction, or any and all
|
|
163
|
+
other commercial damages or losses), even if such Contributor
|
|
164
|
+
has been advised of the possibility of such damages.
|
|
165
|
+
|
|
166
|
+
9. Accepting Warranty or Additional Liability. While redistributing
|
|
167
|
+
the Work or Derivative Works thereof, You may choose to offer,
|
|
168
|
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
|
169
|
+
or other liability obligations and/or rights consistent with this
|
|
170
|
+
License. However, in accepting such obligations, You may act only
|
|
171
|
+
on Your own behalf and on Your sole responsibility, not on behalf
|
|
172
|
+
of any other Contributor, and only if You agree to indemnify,
|
|
173
|
+
defend, and hold each Contributor harmless for any liability
|
|
174
|
+
incurred by, or claims asserted against, such Contributor by reason
|
|
175
|
+
of your accepting any such warranty or additional liability.
|
|
176
|
+
|
|
177
|
+
END OF TERMS AND CONDITIONS
|
|
178
|
+
|
|
179
|
+
APPENDIX: How to apply the Apache License to your work.
|
|
180
|
+
|
|
181
|
+
To apply the Apache License to your work, attach the following
|
|
182
|
+
boilerplate notice, with the fields enclosed by brackets "[]"
|
|
183
|
+
replaced with your own identifying information. (Don't include
|
|
184
|
+
the brackets!) The text should be enclosed in the appropriate
|
|
185
|
+
comment syntax for the file format. We also recommend that a
|
|
186
|
+
file or class name and description of purpose be included on the
|
|
187
|
+
same "printed page" as the copyright notice for easier
|
|
188
|
+
identification within third-party archives.
|
|
189
|
+
|
|
190
|
+
Copyright [yyyy] [name of copyright owner]
|
|
191
|
+
|
|
192
|
+
Licensed under the Apache License, Version 2.0 (the "License");
|
|
193
|
+
you may not use this file except in compliance with the License.
|
|
194
|
+
You may obtain a copy of the License at
|
|
195
|
+
|
|
196
|
+
http://www.apache.org/licenses/LICENSE-2.0
|
|
197
|
+
|
|
198
|
+
Unless required by applicable law or agreed to in writing, software
|
|
199
|
+
distributed under the License is distributed on an "AS IS" BASIS,
|
|
200
|
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
|
201
|
+
See the License for the specific language governing permissions and
|
|
202
|
+
limitations under the License.
|
memory_pool.py
ADDED
|
@@ -0,0 +1,191 @@
|
|
|
1
|
+
"""Pinned canonical state and bounded, event-retired CUDA allocations."""
|
|
2
|
+
|
|
3
|
+
from __future__ import annotations
|
|
4
|
+
|
|
5
|
+
import time
|
|
6
|
+
from collections import deque
|
|
7
|
+
from collections.abc import Callable
|
|
8
|
+
from dataclasses import dataclass
|
|
9
|
+
|
|
10
|
+
import torch
|
|
11
|
+
from torch import Tensor, nn
|
|
12
|
+
|
|
13
|
+
|
|
14
|
+
def tensor_bytes(tensor: Tensor) -> int:
|
|
15
|
+
return tensor.numel() * tensor.element_size()
|
|
16
|
+
|
|
17
|
+
|
|
18
|
+
def module_state(module: nn.Module) -> dict[str, Tensor]:
|
|
19
|
+
"""Include nonpersistent buffers; functional_call needs those too."""
|
|
20
|
+
return dict(list(module.named_parameters()) + list(module.named_buffers()))
|
|
21
|
+
|
|
22
|
+
|
|
23
|
+
def pin_modules(blocks: nn.ModuleList, dtype: torch.dtype | None) -> None:
|
|
24
|
+
"""Preserve Parameter identity and shared objects when creating CPU storage."""
|
|
25
|
+
if dtype is not None and not dtype.is_floating_point:
|
|
26
|
+
raise TypeError("dtype must be a floating-point torch.dtype")
|
|
27
|
+
storage_owners: dict[tuple[torch.device, int], int] = {}
|
|
28
|
+
tensors = list(blocks.parameters()) + list(blocks.buffers())
|
|
29
|
+
for tensor in tensors:
|
|
30
|
+
if tensor.is_meta or tensor.layout != torch.strided:
|
|
31
|
+
raise ValueError("Only materialized, dense strided state is supported")
|
|
32
|
+
if tensor.numel():
|
|
33
|
+
key = (tensor.device, tensor.untyped_storage().data_ptr())
|
|
34
|
+
if key in storage_owners and storage_owners[key] != id(tensor):
|
|
35
|
+
raise ValueError(
|
|
36
|
+
"Distinct state tensors sharing storage are unsupported; "
|
|
37
|
+
"tie weights by sharing the same Parameter object instead"
|
|
38
|
+
)
|
|
39
|
+
storage_owners[key] = id(tensor)
|
|
40
|
+
seen: set[int] = set()
|
|
41
|
+
for tensor in tensors:
|
|
42
|
+
if id(tensor) in seen:
|
|
43
|
+
continue
|
|
44
|
+
seen.add(id(tensor))
|
|
45
|
+
if tensor.is_meta or tensor.layout != torch.strided:
|
|
46
|
+
raise ValueError("Only materialized, dense strided state is supported")
|
|
47
|
+
target_dtype = dtype if tensor.is_floating_point() else None
|
|
48
|
+
cpu = tensor.detach().to(device="cpu", dtype=target_dtype).pin_memory()
|
|
49
|
+
tensor.data = cpu
|
|
50
|
+
if isinstance(tensor, nn.Parameter) and tensor.grad is not None:
|
|
51
|
+
tensor.grad = tensor.grad.to(device="cpu", dtype=cpu.dtype).pin_memory()
|
|
52
|
+
|
|
53
|
+
|
|
54
|
+
@dataclass
|
|
55
|
+
class Resident:
|
|
56
|
+
state: dict[str, Tensor]
|
|
57
|
+
ready: torch.cuda.Event
|
|
58
|
+
start: torch.cuda.Event
|
|
59
|
+
nbytes: int
|
|
60
|
+
parameter_bytes: int
|
|
61
|
+
|
|
62
|
+
|
|
63
|
+
class BufferPool:
|
|
64
|
+
"""Each live slot owns one block, regardless of shape or dtype.
|
|
65
|
+
|
|
66
|
+
Allocations use PyTorch's caching allocator rather than shape-specific slabs.
|
|
67
|
+
A slot is freed only after its compute completion event has completed. Cached
|
|
68
|
+
(reserved) allocator memory is not live parameter residency.
|
|
69
|
+
"""
|
|
70
|
+
|
|
71
|
+
def __init__(
|
|
72
|
+
self,
|
|
73
|
+
device: torch.device,
|
|
74
|
+
capacity: int,
|
|
75
|
+
transfer_stream: torch.cuda.Stream,
|
|
76
|
+
compute_stream: torch.cuda.Stream,
|
|
77
|
+
budget_bytes: int | None = None,
|
|
78
|
+
observer: Callable[[int], None] | None = None,
|
|
79
|
+
) -> None:
|
|
80
|
+
self.device = device
|
|
81
|
+
self.capacity = capacity
|
|
82
|
+
self.transfer_stream = transfer_stream
|
|
83
|
+
self.compute_stream = compute_stream
|
|
84
|
+
self.budget_bytes = budget_bytes
|
|
85
|
+
self.observer = observer
|
|
86
|
+
self.live: dict[int, Resident] = {}
|
|
87
|
+
self.reset_stats()
|
|
88
|
+
|
|
89
|
+
def reset_stats(self) -> None:
|
|
90
|
+
if self.live:
|
|
91
|
+
raise RuntimeError("Cannot reset statistics while blocks are resident")
|
|
92
|
+
self.transfer_bytes = 0
|
|
93
|
+
self.transfer_ms = 0.0
|
|
94
|
+
self.stall_ms = 0.0
|
|
95
|
+
self.eviction_wait_ms = 0.0
|
|
96
|
+
self.peak_resident_blocks = 0
|
|
97
|
+
self.peak_state_bytes = 0
|
|
98
|
+
self.peak_parameter_bytes = 0
|
|
99
|
+
self.history: deque[int] = deque(maxlen=4096)
|
|
100
|
+
self.wait_events: list[tuple[torch.cuda.Event, torch.cuda.Event]] = []
|
|
101
|
+
|
|
102
|
+
def check(self) -> None:
|
|
103
|
+
count = len(self.live)
|
|
104
|
+
assert count <= self.capacity, "GPU block residency exceeded capacity"
|
|
105
|
+
self.history.append(count)
|
|
106
|
+
self.peak_resident_blocks = max(self.peak_resident_blocks, count)
|
|
107
|
+
self.peak_state_bytes = max(
|
|
108
|
+
self.peak_state_bytes, sum(item.nbytes for item in self.live.values())
|
|
109
|
+
)
|
|
110
|
+
self.peak_parameter_bytes = max(
|
|
111
|
+
self.peak_parameter_bytes,
|
|
112
|
+
sum(item.parameter_bytes for item in self.live.values()),
|
|
113
|
+
)
|
|
114
|
+
if self.observer is not None:
|
|
115
|
+
self.observer(count)
|
|
116
|
+
|
|
117
|
+
def stage(self, index: int, module: nn.Module, grad: bool = False) -> None:
|
|
118
|
+
if index in self.live:
|
|
119
|
+
return
|
|
120
|
+
if len(self.live) >= self.capacity:
|
|
121
|
+
raise RuntimeError("No free GPU block slot; retire completed compute first")
|
|
122
|
+
source = module_state(module)
|
|
123
|
+
for name, tensor in source.items():
|
|
124
|
+
if tensor.device.type != "cpu" or not tensor.is_pinned():
|
|
125
|
+
raise RuntimeError(
|
|
126
|
+
f"Block {index} tensor {name!r} is not pinned CPU memory"
|
|
127
|
+
)
|
|
128
|
+
nbytes = sum(tensor_bytes(tensor) for tensor in source.values())
|
|
129
|
+
if self.budget_bytes is not None and nbytes > self.budget_bytes:
|
|
130
|
+
raise ValueError(
|
|
131
|
+
f"Block {index} requires {nbytes} bytes, exceeding per-slot buffer "
|
|
132
|
+
f"budget {self.budget_bytes} bytes"
|
|
133
|
+
)
|
|
134
|
+
parameters = dict(module.named_parameters())
|
|
135
|
+
with torch.cuda.stream(self.transfer_stream):
|
|
136
|
+
start = torch.cuda.Event(enable_timing=True)
|
|
137
|
+
ready = torch.cuda.Event(enable_timing=True)
|
|
138
|
+
start.record(self.transfer_stream)
|
|
139
|
+
state = {
|
|
140
|
+
name: tensor.detach().to(self.device, non_blocking=True)
|
|
141
|
+
for name, tensor in source.items()
|
|
142
|
+
}
|
|
143
|
+
if grad:
|
|
144
|
+
for name, parameter in parameters.items():
|
|
145
|
+
state[name].requires_grad_(parameter.requires_grad)
|
|
146
|
+
ready.record(self.transfer_stream)
|
|
147
|
+
self.live[index] = Resident(
|
|
148
|
+
state,
|
|
149
|
+
ready,
|
|
150
|
+
start,
|
|
151
|
+
nbytes,
|
|
152
|
+
sum(tensor_bytes(tensor) for tensor in parameters.values()),
|
|
153
|
+
)
|
|
154
|
+
self.transfer_bytes += nbytes
|
|
155
|
+
self.check()
|
|
156
|
+
|
|
157
|
+
def acquire(self, index: int) -> dict[str, Tensor]:
|
|
158
|
+
item = self.live[index]
|
|
159
|
+
before = torch.cuda.Event(enable_timing=True)
|
|
160
|
+
after = torch.cuda.Event(enable_timing=True)
|
|
161
|
+
before.record(self.compute_stream)
|
|
162
|
+
# Compute must not read weights until their H2D copies have finished.
|
|
163
|
+
self.compute_stream.wait_event(item.ready)
|
|
164
|
+
after.record(self.compute_stream)
|
|
165
|
+
self.wait_events.append((before, after))
|
|
166
|
+
for tensor in item.state.values():
|
|
167
|
+
# CRITICAL allocator guard: transfer-created storage remains protected
|
|
168
|
+
# while compute consumes it, even if Python drops its final reference.
|
|
169
|
+
tensor.record_stream(self.compute_stream)
|
|
170
|
+
return item.state
|
|
171
|
+
|
|
172
|
+
def evict(self, index: int, done: torch.cuda.Event) -> None:
|
|
173
|
+
start = time.perf_counter()
|
|
174
|
+
# Host retirement proves compute is complete BEFORE allocating a new slot;
|
|
175
|
+
# merely enqueueing a wait would permit too many live parameter blocks.
|
|
176
|
+
done.synchronize()
|
|
177
|
+
self.eviction_wait_ms += (time.perf_counter() - start) * 1000
|
|
178
|
+
item = self.live.pop(index)
|
|
179
|
+
self.transfer_ms += item.start.elapsed_time(item.ready)
|
|
180
|
+
item.state.clear()
|
|
181
|
+
self.check()
|
|
182
|
+
|
|
183
|
+
def drain(self) -> None:
|
|
184
|
+
# On exceptions, both pending copies and consumers must finish before free.
|
|
185
|
+
self.transfer_stream.synchronize()
|
|
186
|
+
self.compute_stream.synchronize()
|
|
187
|
+
self.live.clear()
|
|
188
|
+
self.check()
|
|
189
|
+
for before, after in self.wait_events:
|
|
190
|
+
self.stall_ms += before.elapsed_time(after)
|
|
191
|
+
self.wait_events.clear()
|
streamer.py
ADDED
|
@@ -0,0 +1,234 @@
|
|
|
1
|
+
"""Blockwise functional execution with bounded CUDA parameter residency."""
|
|
2
|
+
|
|
3
|
+
from __future__ import annotations
|
|
4
|
+
|
|
5
|
+
from collections.abc import Callable, Sequence
|
|
6
|
+
from typing import Any, Self
|
|
7
|
+
|
|
8
|
+
import torch
|
|
9
|
+
from torch import Tensor, nn
|
|
10
|
+
from torch.func import functional_call
|
|
11
|
+
from torch.utils._pytree import tree_map
|
|
12
|
+
|
|
13
|
+
from memory_pool import BufferPool, pin_modules
|
|
14
|
+
|
|
15
|
+
|
|
16
|
+
def hidden_tensor(result: Any) -> Tensor:
|
|
17
|
+
hidden = result[0] if isinstance(result, tuple) else result
|
|
18
|
+
if not isinstance(hidden, Tensor):
|
|
19
|
+
raise TypeError(
|
|
20
|
+
"A block must return a Tensor or a tuple beginning with a Tensor"
|
|
21
|
+
)
|
|
22
|
+
return hidden
|
|
23
|
+
|
|
24
|
+
|
|
25
|
+
class StreamedModel(nn.Module):
|
|
26
|
+
"""Sequential block streaming. Intermediate tuple[0] feeds the next block.
|
|
27
|
+
|
|
28
|
+
Additional positional/keyword arguments are supplied unchanged to every block;
|
|
29
|
+
the final block's entire result is returned. Inputs must already be on device.
|
|
30
|
+
Construction takes ownership of the supplied modules and pins their CPU state.
|
|
31
|
+
"""
|
|
32
|
+
|
|
33
|
+
def __init__(
|
|
34
|
+
self,
|
|
35
|
+
blocks: nn.Sequential | nn.ModuleList | Sequence[nn.Module],
|
|
36
|
+
device: str | torch.device = "cuda:0",
|
|
37
|
+
prefetch_ahead: int = 1,
|
|
38
|
+
dtype: torch.dtype | None = None,
|
|
39
|
+
buffer_budget_bytes: int | None = None,
|
|
40
|
+
residency_observer: Callable[[int], None] | None = None,
|
|
41
|
+
) -> None:
|
|
42
|
+
super().__init__()
|
|
43
|
+
if isinstance(prefetch_ahead, bool) or not isinstance(prefetch_ahead, int):
|
|
44
|
+
raise TypeError("prefetch_ahead must be an integer")
|
|
45
|
+
if prefetch_ahead < 0:
|
|
46
|
+
raise ValueError("prefetch_ahead must be nonnegative")
|
|
47
|
+
if buffer_budget_bytes is not None and buffer_budget_bytes <= 0:
|
|
48
|
+
raise ValueError("buffer_budget_bytes must be positive")
|
|
49
|
+
self.device = self._cuda_device(device)
|
|
50
|
+
self.blocks = nn.ModuleList(list(blocks))
|
|
51
|
+
self.prefetch_ahead = prefetch_ahead
|
|
52
|
+
self.dtype = dtype
|
|
53
|
+
self.buffer_budget_bytes = buffer_budget_bytes
|
|
54
|
+
self.residency_observer = residency_observer
|
|
55
|
+
self._busy = False
|
|
56
|
+
self._configuration_version = 0
|
|
57
|
+
self.gradient_transfer_bytes = 0
|
|
58
|
+
pin_modules(self.blocks, dtype)
|
|
59
|
+
self._make_engine()
|
|
60
|
+
self.eval()
|
|
61
|
+
|
|
62
|
+
@staticmethod
|
|
63
|
+
def _cuda_device(device: str | torch.device) -> torch.device:
|
|
64
|
+
result = torch.device(device)
|
|
65
|
+
if result.type != "cuda":
|
|
66
|
+
raise ValueError("StreamedModel requires a CUDA execution device")
|
|
67
|
+
if not torch.cuda.is_available():
|
|
68
|
+
raise RuntimeError(
|
|
69
|
+
"CUDA is unavailable; install a CUDA-enabled PyTorch build"
|
|
70
|
+
)
|
|
71
|
+
index = torch.cuda.current_device() if result.index is None else result.index
|
|
72
|
+
if not 0 <= index < torch.cuda.device_count():
|
|
73
|
+
raise ValueError(f"CUDA device index {index} is unavailable")
|
|
74
|
+
return torch.device("cuda", index)
|
|
75
|
+
|
|
76
|
+
def _make_engine(self) -> None:
|
|
77
|
+
# Borrow the construction stream. A new compute stream per wrapper would
|
|
78
|
+
# create a persistent cuBLAS workspace per instance in PyTorch's handle pool.
|
|
79
|
+
self.compute_stream = torch.cuda.current_stream(device=self.device)
|
|
80
|
+
self.transfer_stream = torch.cuda.Stream(device=self.device)
|
|
81
|
+
self.pool = BufferPool(
|
|
82
|
+
self.device,
|
|
83
|
+
self.prefetch_ahead + 1,
|
|
84
|
+
self.transfer_stream,
|
|
85
|
+
self.compute_stream,
|
|
86
|
+
self.buffer_budget_bytes,
|
|
87
|
+
self.residency_observer,
|
|
88
|
+
)
|
|
89
|
+
|
|
90
|
+
def _execute(
|
|
91
|
+
self,
|
|
92
|
+
order: list[int],
|
|
93
|
+
callback: Callable[[int, dict[str, Tensor]], None],
|
|
94
|
+
inputs: Any,
|
|
95
|
+
grad: bool = False,
|
|
96
|
+
) -> None:
|
|
97
|
+
if self._busy:
|
|
98
|
+
raise RuntimeError("Concurrent or reentrant execution is unsupported")
|
|
99
|
+
self._busy = True
|
|
100
|
+
caller = torch.cuda.current_stream(self.device)
|
|
101
|
+
# Inputs may have been produced on the caller stream just before forward.
|
|
102
|
+
self.compute_stream.wait_stream(caller)
|
|
103
|
+
|
|
104
|
+
def protect(value: Any) -> Any:
|
|
105
|
+
if isinstance(value, Tensor) and value.is_cuda:
|
|
106
|
+
if value.device != self.device:
|
|
107
|
+
raise ValueError(
|
|
108
|
+
f"Input is on {value.device}, expected {self.device}"
|
|
109
|
+
)
|
|
110
|
+
value.record_stream(self.compute_stream)
|
|
111
|
+
return value
|
|
112
|
+
|
|
113
|
+
try:
|
|
114
|
+
tree_map(protect, inputs)
|
|
115
|
+
for index in order[: self.pool.capacity]:
|
|
116
|
+
self.pool.stage(index, self.blocks[index], grad)
|
|
117
|
+
for offset, index in enumerate(order):
|
|
118
|
+
with torch.cuda.stream(self.compute_stream):
|
|
119
|
+
callback(index, self.pool.acquire(index))
|
|
120
|
+
done = torch.cuda.Event()
|
|
121
|
+
done.record(self.compute_stream)
|
|
122
|
+
self.pool.evict(index, done)
|
|
123
|
+
next_offset = offset + self.pool.capacity
|
|
124
|
+
if next_offset < len(order):
|
|
125
|
+
upcoming = order[next_offset]
|
|
126
|
+
self.pool.stage(upcoming, self.blocks[upcoming], grad)
|
|
127
|
+
finally:
|
|
128
|
+
self.pool.drain()
|
|
129
|
+
# Returning tensors to caller must not race their production on compute.
|
|
130
|
+
caller.wait_stream(self.compute_stream)
|
|
131
|
+
self._busy = False
|
|
132
|
+
|
|
133
|
+
def _call_block(
|
|
134
|
+
self,
|
|
135
|
+
index: int,
|
|
136
|
+
state: dict[str, Tensor],
|
|
137
|
+
hidden: Tensor,
|
|
138
|
+
args: tuple[Any, ...],
|
|
139
|
+
kwargs: dict[str, Any],
|
|
140
|
+
) -> Any:
|
|
141
|
+
versions = {name: value._version for name, value in state.items()}
|
|
142
|
+
identities = {name: id(value) for name, value in state.items()}
|
|
143
|
+
result = functional_call(
|
|
144
|
+
self.blocks[index],
|
|
145
|
+
state,
|
|
146
|
+
(hidden, *args),
|
|
147
|
+
kwargs,
|
|
148
|
+
strict=True,
|
|
149
|
+
)
|
|
150
|
+
if any(
|
|
151
|
+
value._version != versions[name] or id(value) != identities[name]
|
|
152
|
+
for name, value in state.items()
|
|
153
|
+
):
|
|
154
|
+
raise RuntimeError(
|
|
155
|
+
"Blocks must not mutate parameters or registered buffers"
|
|
156
|
+
)
|
|
157
|
+
hidden_tensor(result)
|
|
158
|
+
# A block may return a view of a weight. Clone outputs so eviction really
|
|
159
|
+
# releases the staged state and callers cannot retain the pool's storage.
|
|
160
|
+
return tree_map(
|
|
161
|
+
lambda value: value.clone() if isinstance(value, Tensor) else value, result
|
|
162
|
+
)
|
|
163
|
+
|
|
164
|
+
def forward(self, hidden_states: Tensor, *args: Any, **kwargs: Any) -> Any:
|
|
165
|
+
if hidden_states.device != self.device:
|
|
166
|
+
raise ValueError(f"hidden_states must be on {self.device}")
|
|
167
|
+
if self.training and torch.is_grad_enabled():
|
|
168
|
+
from block_streamer._autograd import training_forward
|
|
169
|
+
|
|
170
|
+
return training_forward(self, hidden_states, args, kwargs)
|
|
171
|
+
result: Any = hidden_states
|
|
172
|
+
|
|
173
|
+
def run(index: int, state: dict[str, Tensor]) -> None:
|
|
174
|
+
nonlocal result
|
|
175
|
+
result = self._call_block(index, state, hidden_tensor(result), args, kwargs)
|
|
176
|
+
|
|
177
|
+
with torch.inference_mode(False), torch.no_grad():
|
|
178
|
+
self._execute(
|
|
179
|
+
list(range(len(self.blocks))), run, (hidden_states, args, kwargs)
|
|
180
|
+
)
|
|
181
|
+
return result
|
|
182
|
+
|
|
183
|
+
def to(self, *args: Any, **kwargs: Any) -> Self:
|
|
184
|
+
"""Change execution device/dtype while retaining pinned CPU master state."""
|
|
185
|
+
if self._busy:
|
|
186
|
+
raise RuntimeError("Cannot move the model during execution")
|
|
187
|
+
device, dtype, _, memory_format = torch._C._nn._parse_to(*args, **kwargs)
|
|
188
|
+
if memory_format is not None:
|
|
189
|
+
raise ValueError("memory_format conversion is unsupported")
|
|
190
|
+
target = self.device if device is None else self._cuda_device(device)
|
|
191
|
+
self.close()
|
|
192
|
+
self._configuration_version += 1
|
|
193
|
+
pin_modules(self.blocks, dtype)
|
|
194
|
+
self.device = target
|
|
195
|
+
if dtype is not None:
|
|
196
|
+
self.dtype = dtype
|
|
197
|
+
self._make_engine()
|
|
198
|
+
return self
|
|
199
|
+
|
|
200
|
+
def _apply(self, fn: Callable[[Tensor], Tensor], recurse: bool = True) -> Self:
|
|
201
|
+
raise RuntimeError(
|
|
202
|
+
"Use StreamedModel.to(device=..., dtype=...) to preserve pinned CPU state; "
|
|
203
|
+
"inherited cpu/cuda/half/bfloat16 and parent-module conversions are unsupported"
|
|
204
|
+
)
|
|
205
|
+
|
|
206
|
+
def stats(self) -> dict[str, Any]:
|
|
207
|
+
"""Cumulative since construction/reset; byte counts are tensor payloads."""
|
|
208
|
+
return {
|
|
209
|
+
"transfer_bytes": self.pool.transfer_bytes,
|
|
210
|
+
"gradient_transfer_bytes": self.gradient_transfer_bytes,
|
|
211
|
+
"transfer_ms": self.pool.transfer_ms,
|
|
212
|
+
"stall_ms": self.pool.stall_ms,
|
|
213
|
+
"eviction_wait_ms": self.pool.eviction_wait_ms,
|
|
214
|
+
"resident_blocks": len(self.pool.live),
|
|
215
|
+
"peak_resident_blocks": self.pool.peak_resident_blocks,
|
|
216
|
+
"peak_state_bytes": self.pool.peak_state_bytes,
|
|
217
|
+
"peak_parameter_bytes": self.pool.peak_parameter_bytes,
|
|
218
|
+
"residency_history": tuple(self.pool.history),
|
|
219
|
+
}
|
|
220
|
+
|
|
221
|
+
def reset_stats(self) -> None:
|
|
222
|
+
self.pool.reset_stats()
|
|
223
|
+
self.gradient_transfer_bytes = 0
|
|
224
|
+
|
|
225
|
+
def close(self) -> None:
|
|
226
|
+
if self._busy:
|
|
227
|
+
raise RuntimeError("Cannot close the model during execution")
|
|
228
|
+
self.pool.drain()
|
|
229
|
+
|
|
230
|
+
def __enter__(self) -> Self:
|
|
231
|
+
return self
|
|
232
|
+
|
|
233
|
+
def __exit__(self, *exc: object) -> None:
|
|
234
|
+
self.close()
|