bioai-evidence-validator 0.5.0__py3-none-any.whl → 0.7.0__py3-none-any.whl
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {bioai_evidence_validator-0.5.0.dist-info → bioai_evidence_validator-0.7.0.dist-info}/METADATA +65 -13
- bioai_evidence_validator-0.7.0.dist-info/RECORD +15 -0
- bioevidence_validator/__init__.py +1 -1
- bioevidence_validator/cli.py +77 -1
- bioevidence_validator/draft.py +9 -6
- bioevidence_validator/engine.py +2 -2
- bioevidence_validator/review.py +388 -0
- bioevidence_validator/schema/bioevidence_core.yaml +18 -4
- bioai_evidence_validator-0.5.0.dist-info/RECORD +0 -14
- {bioai_evidence_validator-0.5.0.dist-info → bioai_evidence_validator-0.7.0.dist-info}/WHEEL +0 -0
- {bioai_evidence_validator-0.5.0.dist-info → bioai_evidence_validator-0.7.0.dist-info}/entry_points.txt +0 -0
- {bioai_evidence_validator-0.5.0.dist-info → bioai_evidence_validator-0.7.0.dist-info}/licenses/LICENSE +0 -0
{bioai_evidence_validator-0.5.0.dist-info → bioai_evidence_validator-0.7.0.dist-info}/METADATA
RENAMED
|
@@ -1,9 +1,9 @@
|
|
|
1
1
|
Metadata-Version: 2.5
|
|
2
2
|
Name: bioai-evidence-validator
|
|
3
|
-
Version: 0.
|
|
3
|
+
Version: 0.7.0
|
|
4
4
|
Summary: Standards-aligned evidence policy validation for AI-assisted biological curation
|
|
5
5
|
Project-URL: Homepage, https://github.com/NingyuSUN/bioai-evidence-validator
|
|
6
|
-
Project-URL: Documentation, https://github.
|
|
6
|
+
Project-URL: Documentation, https://ningyusun.github.io/bioai-evidence-validator/
|
|
7
7
|
Project-URL: Changelog, https://github.com/NingyuSUN/bioai-evidence-validator/blob/main/CHANGELOG.md
|
|
8
8
|
Project-URL: Issues, https://github.com/NingyuSUN/bioai-evidence-validator/issues
|
|
9
9
|
Author: Ningyu Sun
|
|
@@ -25,7 +25,13 @@ Requires-Dist: jsonschema<5,>=4.23
|
|
|
25
25
|
Requires-Dist: linkml<2,>=1.8
|
|
26
26
|
Requires-Dist: pyyaml<7,>=6.0
|
|
27
27
|
Provides-Extra: dev
|
|
28
|
+
Requires-Dist: mypy<3,>=2.3; extra == 'dev'
|
|
29
|
+
Requires-Dist: openpyxl<4,>=3.1; extra == 'dev'
|
|
30
|
+
Requires-Dist: pytest-cov<8,>=7; extra == 'dev'
|
|
28
31
|
Requires-Dist: pytest<9,>=8; extra == 'dev'
|
|
32
|
+
Requires-Dist: ruff<0.17,>=0.16; extra == 'dev'
|
|
33
|
+
Requires-Dist: types-jsonschema; extra == 'dev'
|
|
34
|
+
Requires-Dist: types-pyyaml; extra == 'dev'
|
|
29
35
|
Description-Content-Type: text/markdown
|
|
30
36
|
|
|
31
37
|
# BioAI Evidence Validator
|
|
@@ -35,6 +41,7 @@ Description-Content-Type: text/markdown
|
|
|
35
41
|
[](https://github.com/NingyuSUN/bioai-evidence-validator/blob/main/pyproject.toml)
|
|
36
42
|
[](https://github.com/NingyuSUN/bioai-evidence-validator/blob/main/LICENSE)
|
|
37
43
|
[](https://colab.research.google.com/github/NingyuSUN/bioai-evidence-validator/blob/main/examples/quickstart.ipynb)
|
|
44
|
+
[](https://ningyusun.github.io/bioai-evidence-validator/)
|
|
38
45
|
|
|
39
46
|
**Stop AI-extracted biological claims from entering your knowledge base or
|
|
40
47
|
training set before their evidence is good enough for that use.**
|
|
@@ -52,6 +59,7 @@ pip install bioai-evidence-validator
|
|
|
52
59
|
|
|
53
60
|
Or try it in the browser, nothing to install:
|
|
54
61
|
[quickstart notebook on Colab](https://colab.research.google.com/github/NingyuSUN/bioai-evidence-validator/blob/main/examples/quickstart.ipynb).
|
|
62
|
+
Full documentation: **[ningyusun.github.io/bioai-evidence-validator](https://ningyusun.github.io/bioai-evidence-validator/)**.
|
|
55
63
|
|
|
56
64
|
## 30-second example
|
|
57
65
|
|
|
@@ -103,9 +111,12 @@ record is trustworthy enough for a particular purpose.
|
|
|
103
111
|
| Provenance consistency (source hashes, resolved references, scope) | — | ✅ |
|
|
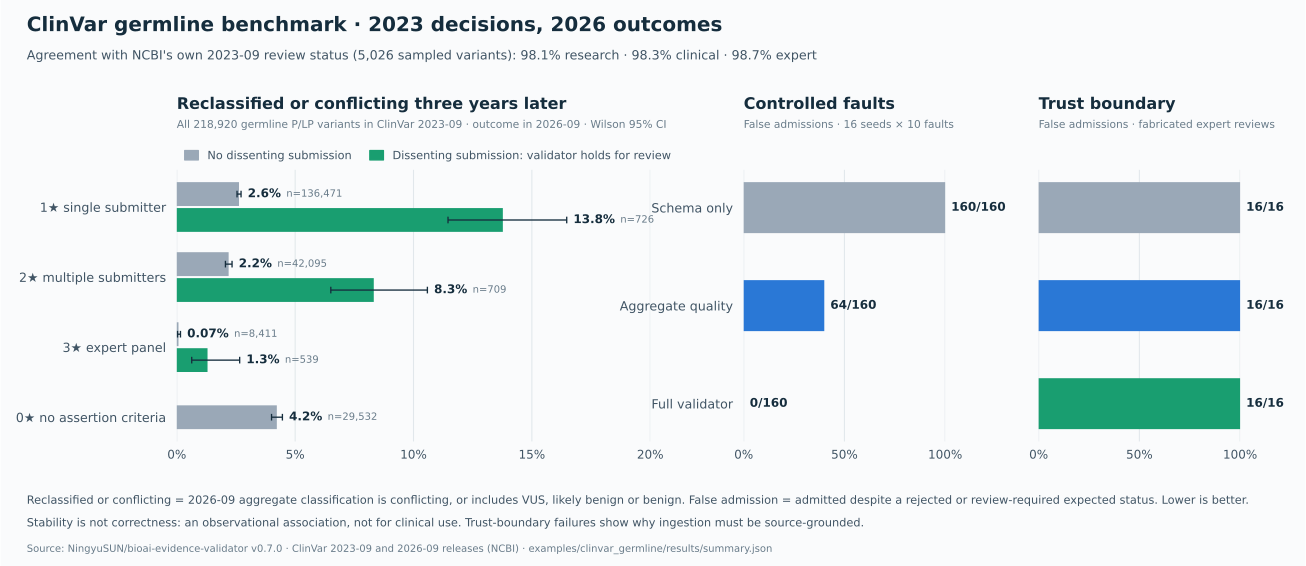
104
112
|
| Human adjudications bound to a specific statement and use | — | ✅ |
|
|
105
113
|
| Machine-readable audit report with hashes of input, schema and profile | — | ✅ |
|
|
114
|
+
| Mapped to ECO, Biolink and GA4GH VA-Spec ([standards alignment](https://github.com/NingyuSUN/bioai-evidence-validator/blob/main/docs/STANDARDS.md)) | — | ✅ |
|
|
106
115
|
|
|
107
|
-
On
|
|
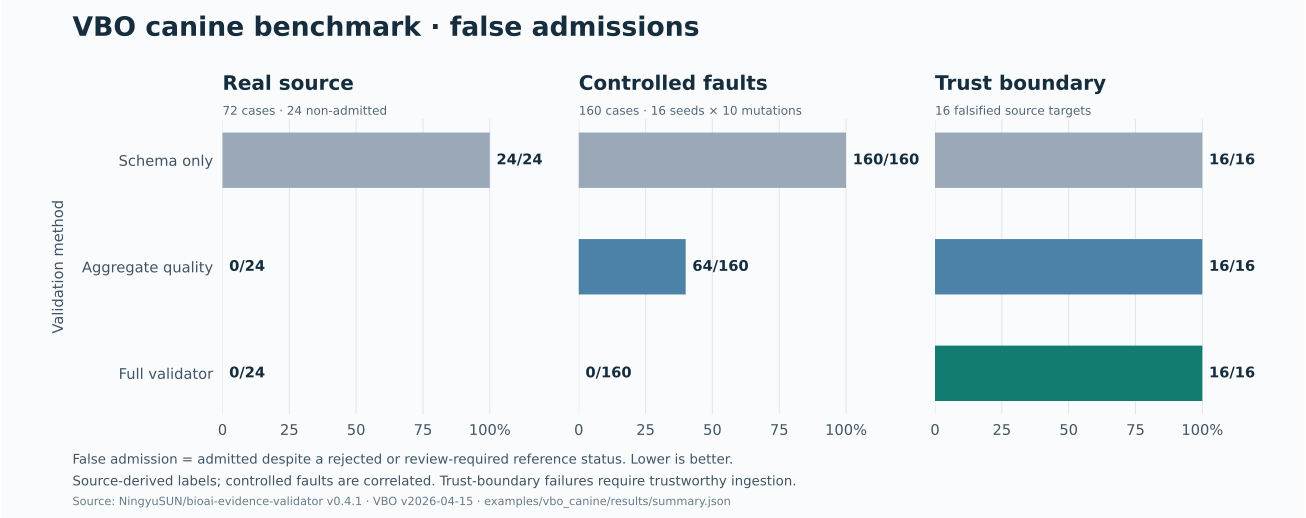
108
|
-
injected faults; the full validator admitted **0/160**.
|
|
116
|
+
On both real-data benchmarks below, schema-only checks admitted **160/160**
|
|
117
|
+
injected faults; the full validator admitted **0/160**. On ClinVar, 1★ and 2★ variants
|
|
118
|
+
the validator holds back were **about 4–5× more likely** to be reclassified or put in
|
|
119
|
+
conflict three years later.
|
|
109
120
|
|
|
110
121
|
## Use it
|
|
111
122
|
|
|
@@ -178,7 +189,7 @@ jobs:
|
|
|
178
189
|
runs-on: ubuntu-latest
|
|
179
190
|
steps:
|
|
180
191
|
- uses: actions/checkout@v4
|
|
181
|
-
- uses: NingyuSUN/bioai-evidence-validator@v0.
|
|
192
|
+
- uses: NingyuSUN/bioai-evidence-validator@v0.7.0
|
|
182
193
|
with:
|
|
183
194
|
files: records/**/*.yaml # whitespace-separated globs
|
|
184
195
|
format: draft # or: record (default)
|
|
@@ -250,7 +261,36 @@ Use the [annotation templates](https://github.com/NingyuSUN/bioai-evidence-valid
|
|
|
250
261
|
source version and intended use. Document reviewer roles and whether labels are
|
|
251
262
|
single-reviewed or independently reviewed by multiple people.
|
|
252
263
|
|
|
253
|
-
## Real-data
|
|
264
|
+
## Real-data cases
|
|
265
|
+
|
|
266
|
+
### ClinVar germline classifications, three years later
|
|
267
|
+
|
|
268
|
+
The [ClinVar case](https://github.com/NingyuSUN/bioai-evidence-validator/blob/main/examples/clinvar_germline/README.md)
|
|
269
|
+
turns every 2023-09 lab submission into evidence, validates 5,026 sampled variants with a
|
|
270
|
+
ClinVar-style profile, and checks what happened to them by 2026-09.
|
|
271
|
+
|
|
272
|
+
|
|
273
|
+
|
|
274
|
+
- **Policy reproduction:** the profile matches NCBI's own 2023-09 review status on 98–99% of
|
|
275
|
+
decisions; every disagreement is listed with its cause.
|
|
276
|
+
- **Where the validator is stricter, classifications were less stable.** It sends any P/LP
|
|
277
|
+
variant with a dissenting submission to review, even when ClinVar's aggregate does not.
|
|
278
|
+
Across all 218,920 germline P/LP variants, the share later reclassified or put in conflict:
|
|
279
|
+
|
|
280
|
+
| 2023-09 ClinVar review status | No dissenting submission | With one (validator: review) |
|
|
281
|
+
|---|---:|---:|
|
|
282
|
+
| 1★ single submitter | 2.63% (2.54–2.71) | **13.77%** (11.46–16.47) |
|
|
283
|
+
| 2★ multiple submitters | 2.19% (2.05–2.33) | **8.32%** (6.51–10.59) |
|
|
284
|
+
| 3★ expert panel | 0.07% (0.03–0.16) | **1.30%** (0.63–2.66) |
|
|
285
|
+
|
|
286
|
+
Wilson 95% intervals. Stability is not correctness, and this is observational; see the
|
|
287
|
+
case's interpretation limits. Not for clinical use.
|
|
288
|
+
|
|
289
|
+
```bash
|
|
290
|
+
uv run python examples/clinvar_germline/run.py --output artifacts/clinvar
|
|
291
|
+
```
|
|
292
|
+
|
|
293
|
+
### VBO canine name mapping
|
|
254
294
|
|
|
255
295
|
[VBO canine name mapping](https://github.com/NingyuSUN/bioai-evidence-validator/blob/main/examples/vbo_canine/README.md) uses a frozen public ontology:
|
|
256
296
|
72 real-name cases, 160 controlled errors, and 16 separately reported trust-boundary
|
|
@@ -261,7 +301,7 @@ per-required-evidence-type validation. Source-derived labels are not expert anno
|
|
|
261
301
|
uv run python examples/vbo_canine/run.py --output artifacts/vbo-canine
|
|
262
302
|
```
|
|
263
303
|
|
|
264
|
-
|
|
304
|
+
#### Benchmark results (v0.4.1)
|
|
265
305
|
|
|
266
306
|
|
|
267
307
|
|
|
@@ -271,20 +311,31 @@ On 72 real-source name mappings, the full validator admitted all 48 unambiguous
|
|
|
271
311
|
|
|
272
312
|
## Scope
|
|
273
313
|
|
|
274
|
-
The VBO
|
|
314
|
+
The VBO and ClinVar cases use attributed public data; other fixtures are synthetic.
|
|
275
315
|
Admission means **the supplied record meets the selected
|
|
276
316
|
profile**, not that a biological claim is true. The toolkit does not retrieve papers,
|
|
277
|
-
verify reviewer identities, train models, or measure prediction accuracy. The generic core compares supplied hashes; the VBO
|
|
278
|
-
|
|
317
|
+
verify reviewer identities, train models, or measure prediction accuracy. The generic core compares supplied hashes; the VBO and ClinVar importers also hash their local source
|
|
318
|
+
projections. External source truth and cohort independence require upstream verification.
|
|
319
|
+
Neither benchmark has independent expert annotation yet; a blinded [expert-review kit](https://github.com/NingyuSUN/bioai-evidence-validator/tree/main/evaluation/clinvar_review) for the ClinVar case is ready for reviewers.
|
|
279
320
|
|
|
280
321
|
## Versions and branches
|
|
281
322
|
|
|
282
|
-
`main` is the domain-neutral framework (0.
|
|
283
|
-
and SQLite adapter from 0.3
|
|
284
|
-
[`canine-
|
|
323
|
+
`main` is the domain-neutral framework (0.7.0). The complete canine implementation
|
|
324
|
+
and SQLite adapter from 0.3 are preserved at the
|
|
325
|
+
[`canine-0.3` tag](https://github.com/NingyuSUN/bioai-evidence-validator/tree/canine-0.3)
|
|
326
|
+
(also the `canine-breed` branch);
|
|
285
327
|
see the [0.4 migration guide](https://github.com/NingyuSUN/bioai-evidence-validator/blob/main/docs/MIGRATION-0.4.md) and
|
|
286
328
|
[changelog](https://github.com/NingyuSUN/bioai-evidence-validator/blob/main/CHANGELOG.md).
|
|
287
329
|
|
|
330
|
+
## Contributing
|
|
331
|
+
|
|
332
|
+
Bug reports, domain profiles and new benchmarks are welcome. See
|
|
333
|
+
[CONTRIBUTING.md](https://github.com/NingyuSUN/bioai-evidence-validator/blob/main/CONTRIBUTING.md),
|
|
334
|
+
the [community profiles](https://github.com/NingyuSUN/bioai-evidence-validator/tree/main/community/profiles)
|
|
335
|
+
and issues labelled [`good first issue`](https://github.com/NingyuSUN/bioai-evidence-validator/labels/good%20first%20issue).
|
|
336
|
+
Report security problems privately as described in
|
|
337
|
+
[SECURITY.md](https://github.com/NingyuSUN/bioai-evidence-validator/blob/main/SECURITY.md).
|
|
338
|
+
|
|
288
339
|
## Citing
|
|
289
340
|
|
|
290
341
|
If you use this toolkit in research, please cite it using the metadata in
|
|
@@ -293,6 +344,7 @@ If you use this toolkit in research, please cite it using the metadata in
|
|
|
293
344
|
|
|
294
345
|
[Create a profile](https://github.com/NingyuSUN/bioai-evidence-validator/blob/main/docs/PROFILES.md) ·
|
|
295
346
|
[Draft format](https://github.com/NingyuSUN/bioai-evidence-validator/blob/main/docs/DRAFTS.md) ·
|
|
347
|
+
[Standards alignment](https://github.com/NingyuSUN/bioai-evidence-validator/blob/main/docs/STANDARDS.md) ·
|
|
296
348
|
[Engineering contract](https://github.com/NingyuSUN/bioai-evidence-validator/blob/main/docs/ENGINEERING.md) ·
|
|
297
349
|
[Design case study](https://github.com/NingyuSUN/bioai-evidence-validator/blob/main/docs/CASE_STUDY.md) ·
|
|
298
350
|
[Architecture decision](https://github.com/NingyuSUN/bioai-evidence-validator/blob/main/docs/ADR-002-domain-neutral-main.md) ·
|
|
@@ -0,0 +1,15 @@
|
|
|
1
|
+
bioevidence_validator/__init__.py,sha256=PsEzz-ifHjfLOJX7KkUqMFNbniIQMNPKRFxgNdoF3JI,312
|
|
2
|
+
bioevidence_validator/cli.py,sha256=7TxCuCN0jcbFwUnim0QiIARJC3XPQcsYN5qBcT7EFF0,9965
|
|
3
|
+
bioevidence_validator/config.py,sha256=Ahc9eRPNR_ArqnbnJkdZsPFq9yERTYied0oGwUkANYI,1110
|
|
4
|
+
bioevidence_validator/draft.py,sha256=2ge9l1BA44e-_ukO_Nnz9UZAV_RS8yqj3Ujr86eFxtY,13631
|
|
5
|
+
bioevidence_validator/engine.py,sha256=OSH9Zd-UqCVqYRU6eLkyoavRWAJGzz8Q6mcCNkhW48I,14989
|
|
6
|
+
bioevidence_validator/review.py,sha256=yp9DI2TafTiZqZmNTejtUb9oHeeXPEjZHXx3fe2qCGI,20293
|
|
7
|
+
bioevidence_validator/profiles/dataset-label.yaml,sha256=4utz9YcFFF2UnaLjIb0ATb-27hF8Smw7zmv0sBTaQdM,843
|
|
8
|
+
bioevidence_validator/profiles/general.yaml,sha256=i9fJCWovJZ2e2d4rbn0Bx7mrhumNb2zjS9TOarkBWZw,778
|
|
9
|
+
bioevidence_validator/profiles/literature-claim.yaml,sha256=7l82gX3oGGyYFq9B29-1qGXeL4LRcMhJi8Y9fieVE0c,612
|
|
10
|
+
bioevidence_validator/schema/bioevidence_core.yaml,sha256=c2YIBOhuT6v7j4MDsMScImdyLZCMy-3X--ExCB_IYu8,7514
|
|
11
|
+
bioai_evidence_validator-0.7.0.dist-info/METADATA,sha256=mt7dqba6hjGQjYBUoBRTS_09bvyD7GU3x1c_RmK4amg,18818
|
|
12
|
+
bioai_evidence_validator-0.7.0.dist-info/WHEEL,sha256=W3fkpkm7-wf9vBI5Z-7s0eWkeM-spu78I8Neb98DeEg,87
|
|
13
|
+
bioai_evidence_validator-0.7.0.dist-info/entry_points.txt,sha256=6oufzT2x1nIhTqM5B6y4aWubExKAoFb_wXXTdz3mBQQ,63
|
|
14
|
+
bioai_evidence_validator-0.7.0.dist-info/licenses/LICENSE,sha256=z8d0m5b2O9McPEK1xHG_dWgUBT6EfBDz6wA0F7xSPTA,11358
|
|
15
|
+
bioai_evidence_validator-0.7.0.dist-info/RECORD,,
|
bioevidence_validator/cli.py
CHANGED
|
@@ -9,8 +9,9 @@ from pathlib import Path
|
|
|
9
9
|
|
|
10
10
|
import yaml
|
|
11
11
|
|
|
12
|
+
from . import review as review_module
|
|
12
13
|
from .draft import build_record, draft_json_schema, load_draft
|
|
13
|
-
from .engine import default_schema_path, generate_json_schema,
|
|
14
|
+
from .engine import default_schema_path, generate_json_schema, list_profiles, profile_path, validate_record
|
|
14
15
|
|
|
15
16
|
|
|
16
17
|
def parser() -> argparse.ArgumentParser:
|
|
@@ -31,6 +32,36 @@ def parser() -> argparse.ArgumentParser:
|
|
|
31
32
|
generate.add_argument("--output", type=Path, required=True)
|
|
32
33
|
generate.add_argument("--schema", type=Path, default=default_schema_path())
|
|
33
34
|
commands.add_parser("profiles", help="List built-in profiles and their use contracts")
|
|
35
|
+
|
|
36
|
+
review = commands.add_parser("review", help="Independent human review: agreement, adjudication, scoring")
|
|
37
|
+
steps = review.add_subparsers(dest="step", required=True)
|
|
38
|
+
check = steps.add_parser("check", help="Check annotations (and adjudications) against the protocol format")
|
|
39
|
+
check.add_argument("annotations", type=Path)
|
|
40
|
+
check.add_argument("--adjudications", type=Path)
|
|
41
|
+
agree = steps.add_parser("agreement", help="Inter-reviewer agreement per use, before adjudication")
|
|
42
|
+
agree.add_argument("annotations", type=Path)
|
|
43
|
+
agree.add_argument("--output", type=Path)
|
|
44
|
+
sheet = steps.add_parser("adjudication-sheet", help="Blank adjudication rows for every disagreement")
|
|
45
|
+
sheet.add_argument("annotations", type=Path)
|
|
46
|
+
sheet.add_argument("--output", type=Path, required=True)
|
|
47
|
+
sheet.add_argument("--min-reviewers", type=int, default=2)
|
|
48
|
+
scoring = steps.add_parser("score", help="Compare predictions with the resolved reference labels")
|
|
49
|
+
scoring.add_argument("--annotations", type=Path, required=True)
|
|
50
|
+
scoring.add_argument("--adjudications", type=Path, required=True)
|
|
51
|
+
scoring.add_argument("--predictions", type=Path, required=True)
|
|
52
|
+
scoring.add_argument("--split", default="test", choices=sorted(review_module.SPLITS))
|
|
53
|
+
scoring.add_argument("--min-reviewers", type=int, default=2)
|
|
54
|
+
scoring.add_argument("--output", type=Path)
|
|
55
|
+
frozen = steps.add_parser("freeze", help="Write a frozen manifest for a completed reference set")
|
|
56
|
+
frozen.add_argument("--manifest", type=Path, required=True, help="Draft manifest to complete")
|
|
57
|
+
frozen.add_argument("--annotations", type=Path, required=True)
|
|
58
|
+
frozen.add_argument("--adjudications", type=Path, required=True)
|
|
59
|
+
frozen.add_argument("--file", type=Path, action="append", default=[], help="Extra file to hash (repeatable)")
|
|
60
|
+
frozen.add_argument("--dataset-id", required=True)
|
|
61
|
+
frozen.add_argument("--version", required=True)
|
|
62
|
+
frozen.add_argument("--frozen-at", required=True, help="ISO 8601 time of the freeze")
|
|
63
|
+
frozen.add_argument("--min-reviewers", type=int, default=2)
|
|
64
|
+
frozen.add_argument("--output", type=Path, required=True)
|
|
34
65
|
return result
|
|
35
66
|
|
|
36
67
|
|
|
@@ -88,6 +119,9 @@ def _run(args) -> int:
|
|
|
88
119
|
print(json.dumps(list_profiles(), indent=2))
|
|
89
120
|
return 0
|
|
90
121
|
|
|
122
|
+
if args.command == "review":
|
|
123
|
+
return _review(args)
|
|
124
|
+
|
|
91
125
|
if args.command in {"build", "draft-schema"}:
|
|
92
126
|
if args.command == "build":
|
|
93
127
|
if args.output and args.output.resolve() == args.draft.resolve():
|
|
@@ -123,6 +157,48 @@ def _run(args) -> int:
|
|
|
123
157
|
return 0
|
|
124
158
|
|
|
125
159
|
|
|
160
|
+
def _review(args) -> int:
|
|
161
|
+
rv = review_module
|
|
162
|
+
annotations = rv.load_annotations(args.annotations)
|
|
163
|
+
if args.step == "check":
|
|
164
|
+
adjudications = rv.load_adjudications(args.adjudications, annotations) if args.adjudications else []
|
|
165
|
+
units = {(a["case_id"], a["requested_use"]) for a in annotations}
|
|
166
|
+
print(f"OK: {len(annotations)} annotations, {len(units)} case-use units, "
|
|
167
|
+
f"{len({a['reviewer_id'] for a in annotations})} reviewers, {len(adjudications)} adjudications")
|
|
168
|
+
return 0
|
|
169
|
+
if args.step == "agreement":
|
|
170
|
+
report = rv.agreement(annotations)
|
|
171
|
+
if args.output:
|
|
172
|
+
_write_json(args.output, report)
|
|
173
|
+
print(rv.render_agreement(report), end="")
|
|
174
|
+
return 0
|
|
175
|
+
if args.step == "adjudication-sheet":
|
|
176
|
+
if args.output.exists():
|
|
177
|
+
raise ValueError(f"{args.output} exists; refusing to overwrite adjudication work")
|
|
178
|
+
rows, incomplete = rv.adjudication_sheet(annotations, min_reviewers=args.min_reviewers)
|
|
179
|
+
rv.write_csv(args.output, rows, rv.ADJUDICATION_COLUMNS)
|
|
180
|
+
print(f"{len(rows)} disagreement(s) to adjudicate; {len(incomplete)} unit(s) with too few reviews")
|
|
181
|
+
return 0
|
|
182
|
+
adjudications = rv.load_adjudications(args.adjudications, annotations)
|
|
183
|
+
final = rv.resolve(annotations, adjudications, min_reviewers=args.min_reviewers)
|
|
184
|
+
if args.step == "score":
|
|
185
|
+
report = rv.score(final, rv.load_predictions(args.predictions), split=args.split)
|
|
186
|
+
if args.output:
|
|
187
|
+
_write_json(args.output, report)
|
|
188
|
+
print(rv.render_score(report), end="")
|
|
189
|
+
return 0
|
|
190
|
+
manifest = json.loads(args.manifest.read_text(encoding="utf-8"))
|
|
191
|
+
files = [args.annotations, args.adjudications, *args.file]
|
|
192
|
+
if args.output.resolve() in {f.resolve() for f in [args.manifest, *files]}:
|
|
193
|
+
raise ValueError("Output must not overwrite an input")
|
|
194
|
+
frozen = rv.freeze(manifest, final, annotations, files, dataset_id=args.dataset_id,
|
|
195
|
+
version=args.version, frozen_at=args.frozen_at)
|
|
196
|
+
_write_json(args.output, frozen)
|
|
197
|
+
print(f"Frozen {frozen['reviewed_case_use_count']} case-use labels from "
|
|
198
|
+
f"{frozen['independent_human_reviewer_count']} reviewers ({frozen['reference_type']})")
|
|
199
|
+
return 0
|
|
200
|
+
|
|
201
|
+
|
|
126
202
|
def main(argv: list[str] | None = None) -> int:
|
|
127
203
|
args = parser().parse_args(argv)
|
|
128
204
|
try:
|
bioevidence_validator/draft.py
CHANGED
|
@@ -80,8 +80,6 @@ def _entity(value: Any, path: str) -> dict:
|
|
|
80
80
|
|
|
81
81
|
def _source(value: Any, path: str, base_dir: Path) -> tuple[str, dict]:
|
|
82
82
|
source = _fields(value, SOURCE_KEYS, path)
|
|
83
|
-
if "sha256" not in source and "file" not in source:
|
|
84
|
-
raise ValueError(f"{path} needs sha256, file, or both")
|
|
85
83
|
artifact = {"title": _text(source["title"], path + ".title"),
|
|
86
84
|
"source_type": _text(source["type"], path + ".type", SOURCE_TYPES)}
|
|
87
85
|
if "uri" in source:
|
|
@@ -96,8 +94,12 @@ def _source(value: Any, path: str, base_dir: Path) -> tuple[str, dict]:
|
|
|
96
94
|
observed = hashlib.sha256(file.read_bytes()).hexdigest()
|
|
97
95
|
# A stated hash is the frozen reference; a file hash is what was observed now.
|
|
98
96
|
# With both, validation reports a mismatch (BEV002) instead of trusting either.
|
|
99
|
-
|
|
100
|
-
|
|
97
|
+
stated = _text(source["sha256"], path + ".sha256").lower() if "sha256" in source else None
|
|
98
|
+
frozen = stated or observed
|
|
99
|
+
if frozen is None:
|
|
100
|
+
raise ValueError(f"{path} needs sha256, file, or both")
|
|
101
|
+
artifact["sha256"] = frozen
|
|
102
|
+
if stated is not None and observed is not None:
|
|
101
103
|
artifact["observed_sha256"] = observed
|
|
102
104
|
return _text(source["id"], path + ".id"), artifact
|
|
103
105
|
|
|
@@ -129,14 +131,15 @@ def build_record(draft: dict, *, base_dir: Path | str = ".") -> dict[str, Any]:
|
|
|
129
131
|
local_ids[name] = f"{record_id}/source/{name}"
|
|
130
132
|
sources.append({"id": local_ids[name], **artifact})
|
|
131
133
|
|
|
132
|
-
items,
|
|
134
|
+
items: list[dict[str, Any]] = []
|
|
135
|
+
lines: dict[str, list[str]] = {}
|
|
133
136
|
for index, row in enumerate(_rows(draft["evidence"], "draft.evidence")):
|
|
134
137
|
path = f"draft.evidence[{index}]"
|
|
135
138
|
evidence = _fields(row, EVIDENCE_KEYS, path)
|
|
136
139
|
source = _text(evidence["source"], path + ".source")
|
|
137
140
|
if source not in local_ids:
|
|
138
141
|
raise ValueError(f"{path}.source {source!r} is not a declared source id")
|
|
139
|
-
item = {"id": f"{record_id}/evidence/{index + 1}", "source_artifact_id": local_ids[source],
|
|
142
|
+
item: dict[str, Any] = {"id": f"{record_id}/evidence/{index + 1}", "source_artifact_id": local_ids[source],
|
|
140
143
|
"locator": _text(evidence["locator"], path + ".locator")}
|
|
141
144
|
if "text" in evidence:
|
|
142
145
|
item["extracted_text"] = _text(evidence["text"], path + ".text")
|
bioevidence_validator/engine.py
CHANGED
|
@@ -3,7 +3,7 @@ from __future__ import annotations
|
|
|
3
3
|
import hashlib
|
|
4
4
|
import json
|
|
5
5
|
from dataclasses import asdict, dataclass
|
|
6
|
-
from datetime import
|
|
6
|
+
from datetime import UTC, datetime
|
|
7
7
|
from pathlib import Path
|
|
8
8
|
from typing import Any
|
|
9
9
|
|
|
@@ -255,7 +255,7 @@ class RecordValidator:
|
|
|
255
255
|
"profile_sha256": self.profile_sha256,
|
|
256
256
|
"schema_version": self.schema_version, "schema_sha256": self.schema_sha256,
|
|
257
257
|
"schema_sources": [dict(source) for source in self.schema_sources],
|
|
258
|
-
"input_sha256": sha256_bytes(canonical), "validated_at": datetime.now(
|
|
258
|
+
"input_sha256": sha256_bytes(canonical), "validated_at": datetime.now(UTC).isoformat(),
|
|
259
259
|
"schema_valid": not any(f.rule_id == "SCHEMA" for f in findings),
|
|
260
260
|
"overall_status": overall, "findings": [asdict(f) for f in findings], "use_decisions": decisions,
|
|
261
261
|
}
|
|
@@ -0,0 +1,388 @@
|
|
|
1
|
+
"""Independent human review: check annotations, measure agreement, adjudicate, score and freeze.
|
|
2
|
+
|
|
3
|
+
Implements the workflow in docs/GOLD_STANDARD.md for the CSV formats in evaluation/gold_standard/.
|
|
4
|
+
Reference labels live here, never in the engine: they evaluate decisions, they do not make them.
|
|
5
|
+
"""
|
|
6
|
+
from __future__ import annotations
|
|
7
|
+
|
|
8
|
+
import csv
|
|
9
|
+
import datetime as dt
|
|
10
|
+
import hashlib
|
|
11
|
+
import json
|
|
12
|
+
import math
|
|
13
|
+
import random
|
|
14
|
+
import re
|
|
15
|
+
from collections import Counter, defaultdict
|
|
16
|
+
from collections.abc import Sequence
|
|
17
|
+
from pathlib import Path
|
|
18
|
+
from typing import Any
|
|
19
|
+
|
|
20
|
+
ANNOTATION_COLUMNS = [
|
|
21
|
+
"annotation_id", "case_id", "record_sha256", "profile_id", "profile_sha256", "requested_use", "group_id",
|
|
22
|
+
"split", "reviewer_id", "reviewer_qualification", "annotated_at", "mapping_label", "mapping_rationale",
|
|
23
|
+
"admission_label", "admission_rationale", "evidence_refs_json",
|
|
24
|
+
]
|
|
25
|
+
OPTIONAL_ANNOTATION_COLUMNS = ["later_information_seen", "minutes_spent"]
|
|
26
|
+
ADJUDICATION_COLUMNS = [
|
|
27
|
+
"adjudication_id", "case_id", "record_sha256", "profile_sha256", "requested_use", "annotation_ids_json",
|
|
28
|
+
"mapping_label", "admission_label", "adjudicator_id", "adjudicated_at", "mapping_rationale",
|
|
29
|
+
"admission_rationale", "evidence_refs_json",
|
|
30
|
+
]
|
|
31
|
+
PREDICTION_COLUMNS = ["case_id", "requested_use", "record_sha256", "profile_sha256", "method", "predicted_status"]
|
|
32
|
+
MAPPING_LABELS = ["correct", "incorrect", "uncertain"]
|
|
33
|
+
ADMISSION_LABELS = ["admitted", "review_required", "rejected"]
|
|
34
|
+
PREDICTED = ADMISSION_LABELS + ["not_admitted"] # binary baselines predict admitted / not_admitted
|
|
35
|
+
SPLITS = {"development", "test"}
|
|
36
|
+
HEX64 = re.compile(r"^[0-9a-f]{64}$")
|
|
37
|
+
|
|
38
|
+
Unit = tuple[str, str] # (case_id, requested_use)
|
|
39
|
+
|
|
40
|
+
|
|
41
|
+
def _read_csv(path: Path, required: list[str], optional: Sequence[str] = ()) -> list[dict[str, str]]:
|
|
42
|
+
with Path(path).open(encoding="utf-8-sig", newline="") as handle: # tolerate Excel's BOM
|
|
43
|
+
reader = csv.DictReader(handle)
|
|
44
|
+
header = reader.fieldnames or []
|
|
45
|
+
missing = [c for c in required if c not in header]
|
|
46
|
+
unknown = [c for c in header if c not in required and c not in optional]
|
|
47
|
+
if missing or unknown:
|
|
48
|
+
raise ValueError(f"{path}: missing columns {missing}, unknown columns {unknown}")
|
|
49
|
+
return [dict(row) for row in reader]
|
|
50
|
+
|
|
51
|
+
|
|
52
|
+
def _iso(value: str, where: str) -> None:
|
|
53
|
+
try:
|
|
54
|
+
dt.datetime.fromisoformat(value.replace("Z", "+00:00"))
|
|
55
|
+
except ValueError:
|
|
56
|
+
raise ValueError(f"{where}: not an ISO 8601 time: {value!r}") from None
|
|
57
|
+
|
|
58
|
+
|
|
59
|
+
def _json_list(value: str, where: str) -> list:
|
|
60
|
+
try:
|
|
61
|
+
parsed = json.loads(value)
|
|
62
|
+
except json.JSONDecodeError:
|
|
63
|
+
raise ValueError(f"{where}: not valid JSON: {value!r}") from None
|
|
64
|
+
if not isinstance(parsed, list) or not all(isinstance(x, str) and x.strip() for x in parsed):
|
|
65
|
+
raise ValueError(f"{where}: must be a JSON array of nonblank strings")
|
|
66
|
+
return parsed
|
|
67
|
+
|
|
68
|
+
|
|
69
|
+
def load_annotations(path: Path) -> list[dict[str, str]]:
|
|
70
|
+
"""Read and strictly check an annotations CSV; raise ValueError listing the first problems."""
|
|
71
|
+
rows = _read_csv(path, ANNOTATION_COLUMNS, OPTIONAL_ANNOTATION_COLUMNS)
|
|
72
|
+
errors: list[str] = []
|
|
73
|
+
seen_ids: set[str] = set()
|
|
74
|
+
seen_reviews: set[tuple[str, str, str]] = set()
|
|
75
|
+
bindings: dict[Unit, tuple[str, ...]] = {}
|
|
76
|
+
for number, row in enumerate(rows, start=2): # line 1 is the header
|
|
77
|
+
where = f"{path}:{number}"
|
|
78
|
+
blank = [c for c in ANNOTATION_COLUMNS
|
|
79
|
+
if c not in ("mapping_rationale", "admission_rationale") and not (row[c] or "").strip()]
|
|
80
|
+
if blank:
|
|
81
|
+
errors.append(f"{where}: blank {blank}")
|
|
82
|
+
continue
|
|
83
|
+
if row["annotation_id"] in seen_ids:
|
|
84
|
+
errors.append(f"{where}: duplicate annotation_id {row['annotation_id']!r}")
|
|
85
|
+
seen_ids.add(row["annotation_id"])
|
|
86
|
+
review = (row["case_id"], row["requested_use"], row["reviewer_id"])
|
|
87
|
+
if review in seen_reviews:
|
|
88
|
+
errors.append(f"{where}: reviewer {row['reviewer_id']!r} labelled {review[:2]} twice")
|
|
89
|
+
seen_reviews.add(review)
|
|
90
|
+
if row["mapping_label"] not in MAPPING_LABELS:
|
|
91
|
+
errors.append(f"{where}: mapping_label must be one of {MAPPING_LABELS}")
|
|
92
|
+
if row["admission_label"] not in ADMISSION_LABELS:
|
|
93
|
+
errors.append(f"{where}: admission_label must be one of {ADMISSION_LABELS}")
|
|
94
|
+
if row["split"] not in SPLITS:
|
|
95
|
+
errors.append(f"{where}: split must be one of {sorted(SPLITS)}")
|
|
96
|
+
for column in ("record_sha256", "profile_sha256"):
|
|
97
|
+
if not HEX64.match(row[column]):
|
|
98
|
+
errors.append(f"{where}: {column} must be 64 lowercase hex characters")
|
|
99
|
+
try:
|
|
100
|
+
_iso(row["annotated_at"], where)
|
|
101
|
+
_json_list(row["evidence_refs_json"], where)
|
|
102
|
+
except ValueError as exc:
|
|
103
|
+
errors.append(str(exc))
|
|
104
|
+
binding = (row["record_sha256"], row["profile_sha256"], row["profile_id"], row["group_id"], row["split"])
|
|
105
|
+
if bindings.setdefault(review[:2], binding) != binding:
|
|
106
|
+
errors.append(f"{where}: reviewers of {review[:2]} saw a different record, profile, group or split")
|
|
107
|
+
if errors:
|
|
108
|
+
raise ValueError("Invalid annotations:\n" + "\n".join(errors[:20]))
|
|
109
|
+
return rows
|
|
110
|
+
|
|
111
|
+
|
|
112
|
+
def load_adjudications(path: Path, annotations: list[dict[str, str]]) -> list[dict[str, str]]:
|
|
113
|
+
rows = _read_csv(path, ADJUDICATION_COLUMNS)
|
|
114
|
+
by_id = {a["annotation_id"]: a for a in annotations}
|
|
115
|
+
errors, units = [], set()
|
|
116
|
+
for number, row in enumerate(rows, start=2):
|
|
117
|
+
where = f"{path}:{number}"
|
|
118
|
+
blank = [c for c in ADJUDICATION_COLUMNS if not (row[c] or "").strip()]
|
|
119
|
+
if blank:
|
|
120
|
+
errors.append(f"{where}: blank {blank}")
|
|
121
|
+
continue
|
|
122
|
+
unit = (row["case_id"], row["requested_use"])
|
|
123
|
+
if unit in units:
|
|
124
|
+
errors.append(f"{where}: {unit} adjudicated twice")
|
|
125
|
+
units.add(unit)
|
|
126
|
+
if row["mapping_label"] not in MAPPING_LABELS or row["admission_label"] not in ADMISSION_LABELS:
|
|
127
|
+
errors.append(f"{where}: labels must be from {MAPPING_LABELS} and {ADMISSION_LABELS}")
|
|
128
|
+
try:
|
|
129
|
+
_iso(row["adjudicated_at"], where)
|
|
130
|
+
_json_list(row["evidence_refs_json"], where)
|
|
131
|
+
linked = _json_list(row["annotation_ids_json"], where)
|
|
132
|
+
except ValueError as exc:
|
|
133
|
+
errors.append(str(exc))
|
|
134
|
+
continue
|
|
135
|
+
for annotation_id in linked:
|
|
136
|
+
original = by_id.get(annotation_id)
|
|
137
|
+
if original is None or (original["case_id"], original["requested_use"]) != unit:
|
|
138
|
+
errors.append(f"{where}: {annotation_id!r} is not an annotation of {unit}")
|
|
139
|
+
elif (original["record_sha256"], original["profile_sha256"]) != (row["record_sha256"], row["profile_sha256"]):
|
|
140
|
+
errors.append(f"{where}: record or profile hash differs from annotation {annotation_id!r}")
|
|
141
|
+
if errors:
|
|
142
|
+
raise ValueError("Invalid adjudications:\n" + "\n".join(errors[:20]))
|
|
143
|
+
return rows
|
|
144
|
+
|
|
145
|
+
|
|
146
|
+
def _units(annotations: list[dict[str, str]], field: str, use: str | None = None) -> dict[Unit, dict[str, str]]:
|
|
147
|
+
units: dict[Unit, dict[str, str]] = defaultdict(dict)
|
|
148
|
+
for row in annotations:
|
|
149
|
+
if use is None or row["requested_use"] == use:
|
|
150
|
+
units[(row["case_id"], row["requested_use"])][row["reviewer_id"]] = row[field]
|
|
151
|
+
return units
|
|
152
|
+
|
|
153
|
+
|
|
154
|
+
def krippendorff_alpha_nominal(units: list[list[str]]) -> float | None:
|
|
155
|
+
"""Krippendorff's alpha for nominal data; units with fewer than two values are not pairable.
|
|
156
|
+
|
|
157
|
+
Returns None when there is no variation to measure agreement against (expected disagreement is 0).
|
|
158
|
+
"""
|
|
159
|
+
coincidence: dict[tuple[str, str], float] = defaultdict(float)
|
|
160
|
+
for values in units:
|
|
161
|
+
if len(values) < 2:
|
|
162
|
+
continue
|
|
163
|
+
for i, c in enumerate(values):
|
|
164
|
+
for j, k in enumerate(values):
|
|
165
|
+
if i != j:
|
|
166
|
+
coincidence[(c, k)] += 1 / (len(values) - 1)
|
|
167
|
+
totals: dict[str, float] = defaultdict(float)
|
|
168
|
+
for (c, _), weight in coincidence.items():
|
|
169
|
+
totals[c] += weight
|
|
170
|
+
n = sum(totals.values())
|
|
171
|
+
observed = sum(w for (c, k), w in coincidence.items() if c != k)
|
|
172
|
+
expected = (n * n - sum(t * t for t in totals.values())) / (n - 1) if n > 1 else 0.0
|
|
173
|
+
return None if expected == 0 else 1 - observed / expected
|
|
174
|
+
|
|
175
|
+
|
|
176
|
+
def cohen_kappa(pairs: list[tuple[str, str]]) -> float | None:
|
|
177
|
+
if not pairs:
|
|
178
|
+
return None
|
|
179
|
+
n = len(pairs)
|
|
180
|
+
observed = sum(a == b for a, b in pairs) / n
|
|
181
|
+
first, second = Counter(a for a, _ in pairs), Counter(b for _, b in pairs)
|
|
182
|
+
expected = sum(first[c] * second[c] for c in set(first) | set(second)) / (n * n)
|
|
183
|
+
return None if expected == 1 else (observed - expected) / (1 - expected)
|
|
184
|
+
|
|
185
|
+
|
|
186
|
+
def wilson(events: int, n: int, z: float = 1.959963984540054) -> list[float] | None:
|
|
187
|
+
if not n:
|
|
188
|
+
return None
|
|
189
|
+
p = events / n
|
|
190
|
+
centre = (p + z * z / (2 * n)) / (1 + z * z / n)
|
|
191
|
+
half = z * math.sqrt(p * (1 - p) / n + z * z / (4 * n * n)) / (1 + z * z / n)
|
|
192
|
+
return [round(max(0.0, centre - half), 6), round(min(1.0, centre + half), 6)]
|
|
193
|
+
|
|
194
|
+
|
|
195
|
+
def _bootstrap_alpha(units: list[list[str]], resamples: int, seed: int) -> list[float] | None:
|
|
196
|
+
rng = random.Random(seed)
|
|
197
|
+
values = []
|
|
198
|
+
for _ in range(resamples):
|
|
199
|
+
alpha = krippendorff_alpha_nominal([units[rng.randrange(len(units))] for _ in units])
|
|
200
|
+
if alpha is not None:
|
|
201
|
+
values.append(alpha)
|
|
202
|
+
if len(values) < resamples * 0.9:
|
|
203
|
+
return None # too many resamples without variation for a meaningful interval
|
|
204
|
+
values.sort()
|
|
205
|
+
last = len(values) - 1
|
|
206
|
+
return [round(values[int(0.025 * last)], 4), round(values[math.ceil(0.975 * last)], 4)]
|
|
207
|
+
|
|
208
|
+
|
|
209
|
+
def agreement(annotations: list[dict[str, str]], *, resamples: int = 2000, seed: int = 20260925) -> dict[str, Any]:
|
|
210
|
+
"""Inter-reviewer agreement per requested use, before adjudication."""
|
|
211
|
+
reviewers = sorted({row["reviewer_id"] for row in annotations})
|
|
212
|
+
result: dict[str, Any] = {"reviewers": reviewers, "uses": {}}
|
|
213
|
+
for use in sorted({row["requested_use"] for row in annotations}):
|
|
214
|
+
per_field = {}
|
|
215
|
+
for field in ("admission_label", "mapping_label"):
|
|
216
|
+
units = _units(annotations, field, use)
|
|
217
|
+
multi = [list(v.values()) for v in units.values() if len(v) >= 2]
|
|
218
|
+
alpha = krippendorff_alpha_nominal(multi)
|
|
219
|
+
entry: dict[str, Any] = {
|
|
220
|
+
"units": len(units), "units_with_2plus_reviews": len(multi),
|
|
221
|
+
"percent_agreement": round(sum(len(set(v)) == 1 for v in multi) / len(multi), 4) if multi else None,
|
|
222
|
+
"krippendorff_alpha": None if alpha is None else round(alpha, 4),
|
|
223
|
+
"alpha_95_bootstrap": _bootstrap_alpha(multi, resamples, seed) if multi else None,
|
|
224
|
+
}
|
|
225
|
+
if len(reviewers) == 2:
|
|
226
|
+
a, b = reviewers
|
|
227
|
+
pairs = [(v[a], v[b]) for v in units.values() if a in v and b in v]
|
|
228
|
+
kappa = cohen_kappa(pairs)
|
|
229
|
+
entry["cohen_kappa"] = None if kappa is None else round(kappa, 4)
|
|
230
|
+
entry["confusion"] = {f"{x}|{y}": n for (x, y), n in sorted(Counter(pairs).items())}
|
|
231
|
+
per_field[field] = entry
|
|
232
|
+
result["uses"][use] = per_field
|
|
233
|
+
return result
|
|
234
|
+
|
|
235
|
+
|
|
236
|
+
def adjudication_sheet(annotations: list[dict[str, str]], *, min_reviewers: int = 2) -> tuple[list[dict], list[Unit]]:
|
|
237
|
+
"""Blank adjudication rows for every disagreement, plus units that still lack enough reviews."""
|
|
238
|
+
grouped: dict[Unit, list[dict[str, str]]] = defaultdict(list)
|
|
239
|
+
for row in annotations:
|
|
240
|
+
grouped[(row["case_id"], row["requested_use"])].append(row)
|
|
241
|
+
rows, incomplete = [], []
|
|
242
|
+
for unit, reviews in sorted(grouped.items()):
|
|
243
|
+
if len(reviews) < min_reviewers:
|
|
244
|
+
incomplete.append(unit)
|
|
245
|
+
continue
|
|
246
|
+
if len({r["admission_label"] for r in reviews}) > 1 or len({r["mapping_label"] for r in reviews}) > 1:
|
|
247
|
+
first = reviews[0]
|
|
248
|
+
rows.append({"adjudication_id": f"adj:{unit[0]}:{unit[1]}", "case_id": unit[0],
|
|
249
|
+
"record_sha256": first["record_sha256"], "profile_sha256": first["profile_sha256"],
|
|
250
|
+
"requested_use": unit[1],
|
|
251
|
+
"annotation_ids_json": json.dumps(sorted(r["annotation_id"] for r in reviews)),
|
|
252
|
+
**{c: "" for c in ADJUDICATION_COLUMNS[6:]}})
|
|
253
|
+
return rows, incomplete
|
|
254
|
+
|
|
255
|
+
|
|
256
|
+
def resolve(annotations: list[dict[str, str]], adjudications: list[dict[str, str]], *,
|
|
257
|
+
min_reviewers: int = 2) -> dict[Unit, dict[str, str]]:
|
|
258
|
+
"""Final reference labels: unanimous reviews, or the adjudicated label where reviewers disagreed."""
|
|
259
|
+
grouped: dict[Unit, list[dict[str, str]]] = defaultdict(list)
|
|
260
|
+
for row in annotations:
|
|
261
|
+
grouped[(row["case_id"], row["requested_use"])].append(row)
|
|
262
|
+
decided = {(a["case_id"], a["requested_use"]): a for a in adjudications}
|
|
263
|
+
final, problems = {}, []
|
|
264
|
+
for unit, reviews in sorted(grouped.items()):
|
|
265
|
+
first = reviews[0]
|
|
266
|
+
base = {"record_sha256": first["record_sha256"], "profile_sha256": first["profile_sha256"],
|
|
267
|
+
"split": first["split"], "group_id": first["group_id"], "reviews": str(len(reviews))}
|
|
268
|
+
if unit in decided:
|
|
269
|
+
final[unit] = {**base, "admission_label": decided[unit]["admission_label"],
|
|
270
|
+
"mapping_label": decided[unit]["mapping_label"], "resolution": "adjudicated"}
|
|
271
|
+
elif len(reviews) < min_reviewers:
|
|
272
|
+
problems.append(f"{unit}: {len(reviews)} review(s), {min_reviewers} required")
|
|
273
|
+
elif len({r["admission_label"] for r in reviews}) == 1 and len({r["mapping_label"] for r in reviews}) == 1:
|
|
274
|
+
final[unit] = {**base, "admission_label": first["admission_label"],
|
|
275
|
+
"mapping_label": first["mapping_label"], "resolution": "unanimous"}
|
|
276
|
+
else:
|
|
277
|
+
problems.append(f"{unit}: reviewers disagree and there is no adjudication")
|
|
278
|
+
unknown = sorted(set(decided) - set(grouped))
|
|
279
|
+
problems += [f"{unit}: adjudicated but never reviewed" for unit in unknown]
|
|
280
|
+
if problems:
|
|
281
|
+
raise ValueError("Unresolved reference labels:\n" + "\n".join(problems[:20]))
|
|
282
|
+
return final
|
|
283
|
+
|
|
284
|
+
|
|
285
|
+
def load_predictions(path: Path) -> list[dict[str, str]]:
|
|
286
|
+
rows = _read_csv(path, PREDICTION_COLUMNS, ["subset"])
|
|
287
|
+
seen = set()
|
|
288
|
+
for number, row in enumerate(rows, start=2):
|
|
289
|
+
key = (row["case_id"], row["requested_use"], row["method"])
|
|
290
|
+
if key in seen:
|
|
291
|
+
raise ValueError(f"{path}:{number}: duplicate prediction for {key}")
|
|
292
|
+
seen.add(key)
|
|
293
|
+
if row["predicted_status"] not in PREDICTED:
|
|
294
|
+
raise ValueError(f"{path}:{number}: predicted_status must be one of {PREDICTED}")
|
|
295
|
+
return rows
|
|
296
|
+
|
|
297
|
+
|
|
298
|
+
def score(final: dict[Unit, dict[str, str]], predictions: list[dict[str, str]], *, split: str = "test") -> dict[str, Any]:
|
|
299
|
+
"""Compare predictions with reference labels on one split; hashes must match the reviewed records."""
|
|
300
|
+
selected = {u: v for u, v in final.items() if v["split"] == split}
|
|
301
|
+
if not selected:
|
|
302
|
+
raise ValueError(f"No reference labels in split {split!r}")
|
|
303
|
+
rows: dict[tuple[str, str], list[tuple[str, str]]] = defaultdict(list) # (method, subset) -> (gold, predicted)
|
|
304
|
+
for p in predictions:
|
|
305
|
+
unit = (p["case_id"], p["requested_use"])
|
|
306
|
+
if unit not in final:
|
|
307
|
+
continue
|
|
308
|
+
gold = final[unit]
|
|
309
|
+
if (p["record_sha256"], p["profile_sha256"]) != (gold["record_sha256"], gold["profile_sha256"]):
|
|
310
|
+
raise ValueError(f"{unit}: prediction was made on a different record or profile than was reviewed")
|
|
311
|
+
if unit in selected:
|
|
312
|
+
for subset in {"all", p.get("subset") or "all"}:
|
|
313
|
+
rows[(p["method"], subset)].append((gold["admission_label"], p["predicted_status"]))
|
|
314
|
+
predicted = {(p["method"], p["case_id"], p["requested_use"]) for p in predictions}
|
|
315
|
+
missing = [(m, u) for m in sorted({p["method"] for p in predictions}) for u in sorted(selected)
|
|
316
|
+
if (m, *u) not in predicted]
|
|
317
|
+
if missing:
|
|
318
|
+
raise ValueError(f"Missing predictions for {len(missing)} reviewed unit(s), e.g. {missing[0]}")
|
|
319
|
+
report: dict[str, Any] = {"split": split, "reference_units": len(selected), "methods": {}}
|
|
320
|
+
for (method, subset), pairs in sorted(rows.items()):
|
|
321
|
+
positives = [p for g, p in pairs if g == "admitted"]
|
|
322
|
+
negatives = [p for g, p in pairs if g != "admitted"]
|
|
323
|
+
false_admissions = sum(p == "admitted" for p in negatives)
|
|
324
|
+
false_blocks = sum(p != "admitted" for p in positives)
|
|
325
|
+
report["methods"].setdefault(method, {})[subset] = {
|
|
326
|
+
"n": len(pairs), "reference_admitted": len(positives), "reference_not_admitted": len(negatives),
|
|
327
|
+
"false_admissions": false_admissions, "false_admission_rate_wilson_95": wilson(false_admissions, len(negatives)),
|
|
328
|
+
"false_blocks": false_blocks, "false_block_rate_wilson_95": wilson(false_blocks, len(positives)),
|
|
329
|
+
"admission_agreement": sum((g == "admitted") == (p == "admitted") for g, p in pairs),
|
|
330
|
+
"exact_matches": sum(g == p for g, p in pairs),
|
|
331
|
+
"confusion": {f"{g}|{p}": n for (g, p), n in sorted(Counter(pairs).items())},
|
|
332
|
+
}
|
|
333
|
+
return report
|
|
334
|
+
|
|
335
|
+
|
|
336
|
+
def sha256_file(path: Path) -> str:
|
|
337
|
+
return hashlib.sha256(Path(path).read_bytes()).hexdigest()
|
|
338
|
+
|
|
339
|
+
|
|
340
|
+
def freeze(manifest: dict[str, Any], final: dict[Unit, dict[str, str]], annotations: list[dict[str, str]],
|
|
341
|
+
files: list[Path], *, dataset_id: str, version: str, frozen_at: str) -> dict[str, Any]:
|
|
342
|
+
"""Fill a manifest for a completed reference set. Hashes identify files; they do not prove review happened."""
|
|
343
|
+
_iso(frozen_at, "frozen_at")
|
|
344
|
+
reviewers = {row["reviewer_id"] for row in annotations}
|
|
345
|
+
single = all(v["reviews"] == "1" for v in final.values())
|
|
346
|
+
return {**manifest, "dataset_id": dataset_id, "version": version, "status": "frozen",
|
|
347
|
+
"reference_type": "single-reviewer reference set" if single else "independently reviewed reference set",
|
|
348
|
+
"reviewed_case_use_count": len(final), "independent_human_reviewer_count": len(reviewers),
|
|
349
|
+
"resolution_counts": dict(sorted(Counter(v["resolution"] for v in final.values()).items())),
|
|
350
|
+
"split_groups": sorted({v["group_id"] for v in final.values()}),
|
|
351
|
+
"files": {Path(f).name: sha256_file(f) for f in files}, "frozen_at": frozen_at,
|
|
352
|
+
"gold_standard_metrics_available": True}
|
|
353
|
+
|
|
354
|
+
|
|
355
|
+
def _fmt(value: Any) -> str:
|
|
356
|
+
return "–" if value is None else str(value)
|
|
357
|
+
|
|
358
|
+
|
|
359
|
+
def render_agreement(report: dict[str, Any]) -> str:
|
|
360
|
+
lines = [f"Reviewers: {', '.join(report['reviewers'])}", "",
|
|
361
|
+
"| Use | Label | Units (2+ reviews) | % agreement | Krippendorff α (95% bootstrap) | Cohen κ |",
|
|
362
|
+
"|---|---|---:|---:|---|---:|"]
|
|
363
|
+
for use, fields in report["uses"].items():
|
|
364
|
+
for field, e in fields.items():
|
|
365
|
+
ci = e["alpha_95_bootstrap"]
|
|
366
|
+
alpha = _fmt(e["krippendorff_alpha"]) + (f" ({ci[0]}–{ci[1]})" if ci else "")
|
|
367
|
+
lines.append(f"| {use} | {field} | {e['units_with_2plus_reviews']} | {_fmt(e['percent_agreement'])} | "
|
|
368
|
+
f"{alpha} | {_fmt(e.get('cohen_kappa'))} |")
|
|
369
|
+
return "\n".join(lines) + "\n"
|
|
370
|
+
|
|
371
|
+
|
|
372
|
+
def render_score(report: dict[str, Any]) -> str:
|
|
373
|
+
lines = [f"Split: {report['split']} · reference units: {report['reference_units']}", "",
|
|
374
|
+
"| Method | Subset | n | False admissions | False blocks | Admission agreement | Exact |",
|
|
375
|
+
"|---|---|---:|---:|---:|---:|---:|"]
|
|
376
|
+
for method, subsets in report["methods"].items():
|
|
377
|
+
for subset, m in subsets.items():
|
|
378
|
+
lines.append(f"| {method} | {subset} | {m['n']} | {m['false_admissions']}/{m['reference_not_admitted']} | "
|
|
379
|
+
f"{m['false_blocks']}/{m['reference_admitted']} | {m['admission_agreement']}/{m['n']} | "
|
|
380
|
+
f"{m['exact_matches']}/{m['n']} |")
|
|
381
|
+
return "\n".join(lines) + "\n"
|
|
382
|
+
|
|
383
|
+
|
|
384
|
+
def write_csv(path: Path, rows: list[dict[str, str]], columns: list[str]) -> None:
|
|
385
|
+
with Path(path).open("w", encoding="utf-8", newline="") as handle:
|
|
386
|
+
writer = csv.DictWriter(handle, fieldnames=columns, lineterminator="\n")
|
|
387
|
+
writer.writeheader()
|
|
388
|
+
writer.writerows(rows)
|
|
@@ -10,6 +10,8 @@ prefixes:
|
|
|
10
10
|
linkml: https://w3id.org/linkml/
|
|
11
11
|
prov: http://www.w3.org/ns/prov#
|
|
12
12
|
sepio: http://purl.obolibrary.org/obo/SEPIO_
|
|
13
|
+
ECO: http://purl.obolibrary.org/obo/ECO_
|
|
14
|
+
biolink: https://w3id.org/biolink/vocab/
|
|
13
15
|
default_prefix: bioev
|
|
14
16
|
default_range: string
|
|
15
17
|
imports:
|
|
@@ -33,12 +35,24 @@ enums:
|
|
|
33
35
|
supports: null
|
|
34
36
|
contradicts: null
|
|
35
37
|
neutral: null
|
|
38
|
+
# How an evidence item was produced. Meanings are the closest ECO terms (release
|
|
39
|
+
# 2026-07-10); see docs/STANDARDS.md for Biolink agent types and caveats. Kept as a
|
|
40
|
+
# comment so the compiled JSON Schema, and every report's schema_sha256, are unchanged.
|
|
36
41
|
ExtractionMethod:
|
|
37
42
|
permissible_values:
|
|
38
|
-
deterministic_parser:
|
|
39
|
-
|
|
40
|
-
|
|
41
|
-
|
|
43
|
+
deterministic_parser:
|
|
44
|
+
description: Rule-based import of an existing source record.
|
|
45
|
+
meaning: ECO:0000313
|
|
46
|
+
manual_curation:
|
|
47
|
+
description: A person read the source and recorded the evidence.
|
|
48
|
+
meaning: ECO:0000352
|
|
49
|
+
normalized_string_match:
|
|
50
|
+
description: Matching normalized strings, e.g. names to identifiers.
|
|
51
|
+
meaning: ECO:0008021
|
|
52
|
+
llm_extraction:
|
|
53
|
+
description: A language model extracted the evidence from text. ECO has no
|
|
54
|
+
LLM-specific term; the machine-learning term is the closest.
|
|
55
|
+
meaning: ECO:0008004
|
|
42
56
|
StatementStatus:
|
|
43
57
|
permissible_values:
|
|
44
58
|
proposed: null
|
|
@@ -1,14 +0,0 @@
|
|
|
1
|
-
bioevidence_validator/__init__.py,sha256=O0lprvrrJN270yZxpMRi7jF6CTawvgc-f36QbAm0HgU,312
|
|
2
|
-
bioevidence_validator/cli.py,sha256=50z5Aj6y6L3L9bwI_KZLMMYvtNHpWfwWY2O_XXGNVNI,5442
|
|
3
|
-
bioevidence_validator/config.py,sha256=Ahc9eRPNR_ArqnbnJkdZsPFq9yERTYied0oGwUkANYI,1110
|
|
4
|
-
bioevidence_validator/draft.py,sha256=8m5Yh68advpWrDb3m6ivkWa0Cq2SEM8CCbevBqXoRec,13552
|
|
5
|
-
bioevidence_validator/engine.py,sha256=fm1gIOySsLiBbI3SklbEStiMD93RrhR3lA0vqdLJJXQ,15003
|
|
6
|
-
bioevidence_validator/profiles/dataset-label.yaml,sha256=4utz9YcFFF2UnaLjIb0ATb-27hF8Smw7zmv0sBTaQdM,843
|
|
7
|
-
bioevidence_validator/profiles/general.yaml,sha256=i9fJCWovJZ2e2d4rbn0Bx7mrhumNb2zjS9TOarkBWZw,778
|
|
8
|
-
bioevidence_validator/profiles/literature-claim.yaml,sha256=7l82gX3oGGyYFq9B29-1qGXeL4LRcMhJi8Y9fieVE0c,612
|
|
9
|
-
bioevidence_validator/schema/bioevidence_core.yaml,sha256=18MMngua0jlu4VnAbpb7SfI3numnCdjO986bZP6-Xn4,6700
|
|
10
|
-
bioai_evidence_validator-0.5.0.dist-info/METADATA,sha256=1gG5J1j0CxRTbQJDYGBYz7vhMMzqqy7K_uqLE6cQ9ds,15360
|
|
11
|
-
bioai_evidence_validator-0.5.0.dist-info/WHEEL,sha256=W3fkpkm7-wf9vBI5Z-7s0eWkeM-spu78I8Neb98DeEg,87
|
|
12
|
-
bioai_evidence_validator-0.5.0.dist-info/entry_points.txt,sha256=6oufzT2x1nIhTqM5B6y4aWubExKAoFb_wXXTdz3mBQQ,63
|
|
13
|
-
bioai_evidence_validator-0.5.0.dist-info/licenses/LICENSE,sha256=z8d0m5b2O9McPEK1xHG_dWgUBT6EfBDz6wA0F7xSPTA,11358
|
|
14
|
-
bioai_evidence_validator-0.5.0.dist-info/RECORD,,
|
|
File without changes
|
|
File without changes
|
|
File without changes
|