articutapi 1.0.6__py3-none-any.whl
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- ArticutAPI-1.0.6.dist-info/LICENSE +21 -0
- ArticutAPI-1.0.6.dist-info/METADATA +425 -0
- ArticutAPI-1.0.6.dist-info/RECORD +9 -0
- ArticutAPI-1.0.6.dist-info/WHEEL +5 -0
- ArticutAPI-1.0.6.dist-info/top_level.txt +1 -0
- src/ArticutAPI.py +498 -0
- src/MP_ArticutAPI.py +387 -0
- src/WS_ArticutAPI.py +393 -0
- src/__init__.py +3 -0
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2019 Droidtown Linguistic. Tech. Co., Ltd.
|
|
4
|
+
|
|
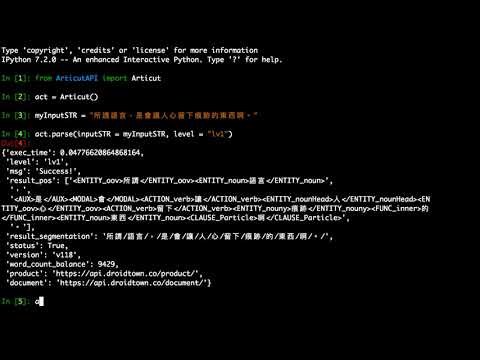
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,425 @@
|
|
|
1
|
+
Metadata-Version: 2.1
|
|
2
|
+
Name: ArticutAPI
|
|
3
|
+
Version: 1.0.6
|
|
4
|
+
Summary: Articut NLP system provides not only finest results on Chinese word segmentaion (CWS), Part-of-Speech tagging (POS) and Named Entity Recogintion tagging (NER), but also the fastest online API service in the NLP industry.
|
|
5
|
+
Home-page: https://github.com/Droidtown/ArticutAPI
|
|
6
|
+
Author: Droidtown Linguistic Tech. Co. Ltd.
|
|
7
|
+
Author-email: info@droidtown.co
|
|
8
|
+
License: UNKNOWN
|
|
9
|
+
Platform: UNKNOWN
|
|
10
|
+
Classifier: Programming Language :: Python :: 3
|
|
11
|
+
Classifier: Programming Language :: Python :: 3 :: Only
|
|
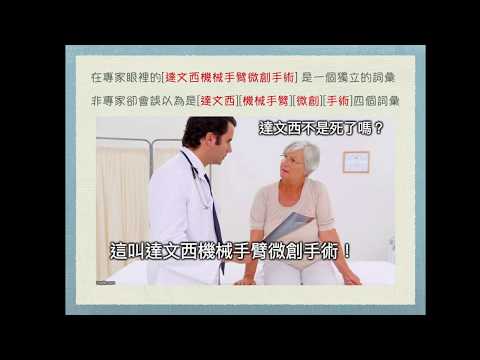
12
|
+
Classifier: Programming Language :: Python :: 3.6
|
|
13
|
+
Classifier: Programming Language :: Python :: 3.7
|
|
14
|
+
Classifier: Programming Language :: Python :: 3.8
|
|
15
|
+
Classifier: Programming Language :: Python :: 3.9
|
|
16
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
17
|
+
Classifier: Operating System :: OS Independent
|
|
18
|
+
Classifier: Development Status :: 5 - Production/Stable
|
|
19
|
+
Classifier: Intended Audience :: Developers
|
|
20
|
+
Classifier: Intended Audience :: Customer Service
|
|
21
|
+
Classifier: Intended Audience :: Information Technology
|
|
22
|
+
Classifier: Natural Language :: Chinese (Traditional)
|
|
23
|
+
Classifier: Topic :: Software Development :: Libraries :: Python Modules
|
|
24
|
+
Classifier: Topic :: Text Processing
|
|
25
|
+
Classifier: Topic :: Text Processing :: Linguistic
|
|
26
|
+
Classifier: Topic :: Text Processing :: Markup :: XML
|
|
27
|
+
Classifier: Topic :: Text Processing :: Filters
|
|
28
|
+
Classifier: Topic :: Utilities
|
|
29
|
+
Requires-Python: >=3.6.1
|
|
30
|
+
Description-Content-Type: text/markdown
|
|
31
|
+
Requires-Dist: requests (>=2.25.1)
|
|
32
|
+
|
|
33
|
+
# Articut 中文斷詞暨詞性標記服務
|
|
34
|
+
## [依語法結構計算,而非統計方法的中文斷詞。]
|
|
35
|
+
|
|
36
|
+
### [Articut API Website](https://api.droidtown.co/)
|
|
37
|
+
### [Document](https://api.droidtown.co/ArticutAPI/document/)
|
|
38
|
+
### [](https://youtu.be/AnvdKmVLlcA "Articut Demo")
|
|
39
|
+
|
|
40
|
+
## Benchmark
|
|
41
|
+
### 設計目標
|
|
42
|
+
名稱 | ArticutAPI | MP_ArticutAPI | WS_ArticutAPI |
|
|
43
|
+
:----------:|:-------------------:|:-------------------:|:------------------:|
|
|
44
|
+
產品 | Online / Docker | Docker | Docker |
|
|
45
|
+
技術 | HTTP Request | MultiProcessing | WebSocket |
|
|
46
|
+
特色 | 簡單易用 | 批次處理 | 即時處理 |
|
|
47
|
+
適用情景 | 任何 | 文本分析 | 聊天機器人 |
|
|
48
|
+
|
|
49
|
+
### 處理速度
|
|
50
|
+
名稱 | ArticutAPI | MP_ArticutAPI | WS_ArticutAPI |
|
|
51
|
+
:----------:|-------------:|-------------------:|-------------------:|
|
|
52
|
+
時間 | 0.1252 秒 | 0.1206 秒 | 0.0677 秒 |
|
|
53
|
+
|
|
54
|
+
### 大量文本
|
|
55
|
+
句數 | ArticutAPI | MP_ArticutAPI | WS_ArticutAPI |
|
|
56
|
+
:----------:|--------------:|-------------------:|------------------:|
|
|
57
|
+
方法 | parse() | bulk_parse(20) | parse() |
|
|
58
|
+
1K | 155 秒 | 8 秒 | 18 秒 |
|
|
59
|
+
2K | 306 秒 | 14 秒 | 35 秒 |
|
|
60
|
+
3K | 455 秒 | 17 秒 | 43 秒 |
|
|
61
|
+
|
|
62
|
+
- 測試平台爲 4 核心 CPU 並使用 4 個 Process。
|
|
63
|
+
- `MP_ArticutAPI`使用 bulk_parse(bulkSize=20) 方法。
|
|
64
|
+
- `WS_ArticutAPI`使用 parse() 方法。
|
|
65
|
+
|
|
66
|
+
----------------------
|
|
67
|
+
|
|
68
|
+
# ArticutAPI
|
|
69
|
+
|
|
70
|
+
## 安裝方法
|
|
71
|
+
```sh
|
|
72
|
+
pip3 install ArticutAPI
|
|
73
|
+
```
|
|
74
|
+
|
|
75
|
+
## 說明文件
|
|
76
|
+
函數說明請參閱 Docs/index.html
|
|
77
|
+
|
|
78
|
+
## 使用方法
|
|
79
|
+
### Articut CWS (Chinese word segmentation)
|
|
80
|
+
```
|
|
81
|
+
from ArticutAPI import Articut
|
|
82
|
+
from pprint import pprint
|
|
83
|
+
|
|
84
|
+
articut = Articut()
|
|
85
|
+
inputSTR = "會被大家盯上,才證明你有實力。"
|
|
86
|
+
result = articut.parse(inputSTR)
|
|
87
|
+
pprint(result)
|
|
88
|
+
```
|
|
89
|
+
### 回傳結果
|
|
90
|
+
```
|
|
91
|
+
{"exec_time": 0.06723856925964355,
|
|
92
|
+
"level": "lv2",
|
|
93
|
+
"msg": "Success!",
|
|
94
|
+
|
|
95
|
+
"result_pos": ["<MODAL>會</MODAL><ACTION_lightVerb>被</ACTION_lightVerb><ENTITY_nouny>大家</ENTITY_nouny><ACTION_verb>盯上</ACTION_verb>",
|
|
96
|
+
",",
|
|
97
|
+
"<MODAL>才</MODAL><ACTION_verb>證明</ACTION_verb><ENTITY_pronoun>你</ENTITY_pronoun><ACTION_verb>有</ACTION_verb><ENTITY_noun>實力</ENTITY_noun>",
|
|
98
|
+
"。"],
|
|
99
|
+
"result_segmentation": "會/被/大家/盯上/,/才/證明/你/有/實力/。/",
|
|
100
|
+
"status": True,
|
|
101
|
+
"version": "v118",
|
|
102
|
+
"word_count_balance": 9985,
|
|
103
|
+
"product": "https://api.droidtown.co/product/",
|
|
104
|
+
"document": "https://api.droidtown.co/document/"
|
|
105
|
+
}
|
|
106
|
+
```
|
|
107
|
+
|
|
108
|
+
### 列出斷詞結果所有詞性標記的內容詞 ###
|
|
109
|
+
可以依需求找出「名詞」、「動詞」或是「形容詞」…等詞彙語意本身已經完整的詞彙。
|
|
110
|
+
```
|
|
111
|
+
inputSTR = "你計劃過地球人類補完計劃"
|
|
112
|
+
result = articut.parse(inputSTR, level="lv1")
|
|
113
|
+
pprint(result["result_pos"])
|
|
114
|
+
|
|
115
|
+
#列出所有的 content word.
|
|
116
|
+
contentWordLIST = articut.getContentWordLIST(result)
|
|
117
|
+
pprint(contentWordLIST)
|
|
118
|
+
|
|
119
|
+
#列出所有的 verb word. (動詞)
|
|
120
|
+
verbStemLIST = articut.getVerbStemLIST(result)
|
|
121
|
+
pprint(verbStemLIST)
|
|
122
|
+
|
|
123
|
+
#列出所有的 noun word. (名詞)
|
|
124
|
+
nounStemLIST = articut.getNounStemLIST(result)
|
|
125
|
+
pprint(nounStemLIST)
|
|
126
|
+
|
|
127
|
+
#列出所有的 location word. (地方名稱)
|
|
128
|
+
locationStemLIST = articut.getLocationStemLIST(result)
|
|
129
|
+
pprint(locationStemLIST)
|
|
130
|
+
```
|
|
131
|
+
|
|
132
|
+
### 回傳結果 ###
|
|
133
|
+
```
|
|
134
|
+
#result["result_pos"]
|
|
135
|
+
["<ENTITY_pronoun>你</ENTITY_pronoun><ACTION_verb>計劃</ACTION_verb><ASPECT>過</ASPECT><LOCATION>地球</LOCATION><ENTITY_oov>人類</ENTITY_oov><ACTION_verb>補完</ACTION_verb><ENTITY_nounHead>計劃</ENTITY_nounHead>"]
|
|
136
|
+
|
|
137
|
+
#列出所有的 content word.
|
|
138
|
+
[[(177, 179, "計劃"), (144, 146, "補完"), (116, 118, "人類"), (47, 49, "計劃")]]
|
|
139
|
+
|
|
140
|
+
#列出所有的 verb word. (動詞)
|
|
141
|
+
[[(144, 146, "補完"), (47, 49, "計劃")]]
|
|
142
|
+
|
|
143
|
+
#列出所有的 noun word. (名詞)
|
|
144
|
+
[[(177, 179, "計劃"), (116, 118, "人類")]]
|
|
145
|
+
|
|
146
|
+
#列出所有的 location word. (地方名稱)
|
|
147
|
+
[[(91, 93, "地球")]]
|
|
148
|
+
```
|
|
149
|
+
|
|
150
|
+
### 取得 Articut 版本列表
|
|
151
|
+
```
|
|
152
|
+
result = articut.versions()
|
|
153
|
+
pprint(result)
|
|
154
|
+
```
|
|
155
|
+
### 回傳結果
|
|
156
|
+
```
|
|
157
|
+
{"msg": "Success!",
|
|
158
|
+
"status": True,
|
|
159
|
+
"versions": [{"level": ["lv1", "lv2"],
|
|
160
|
+
"release_date": "2019-04-25",
|
|
161
|
+
"version": "latest"},
|
|
162
|
+
{"level": ["lv1", "lv2"],
|
|
163
|
+
"release_date": "2019-04-25",
|
|
164
|
+
"version": "v118"},
|
|
165
|
+
{"level": ["lv1", "lv2"],
|
|
166
|
+
"release_date": "2019-04-24",
|
|
167
|
+
"version": "v117"},...
|
|
168
|
+
}
|
|
169
|
+
```
|
|
170
|
+
|
|
171
|
+
----------------------
|
|
172
|
+
|
|
173
|
+
## 進階用法
|
|
174
|
+
### 進階用法01 >> Articut Level :斷詞的深度。數字愈小,切得愈細 (預設: lv2)。
|
|
175
|
+
```
|
|
176
|
+
inputSTR = "小紅帽"
|
|
177
|
+
result = articut.parse(inputSTR, level="lv1")
|
|
178
|
+
pprint(result)
|
|
179
|
+
```
|
|
180
|
+
### 回傳結果 lv1
|
|
181
|
+
極致斷詞,適合 NLU 或機器自動翻譯使用。呈現結果將句子中的每個元素都儘量細分出來。
|
|
182
|
+
```
|
|
183
|
+
{"exec_time": 0.04814624786376953,
|
|
184
|
+
"level": "lv1",
|
|
185
|
+
"msg": "Success!",
|
|
186
|
+
"result_pos": ["<MODIFIER>小</MODIFIER><MODIFIER_color>紅</MODIFIER_color><ENTITY_nounHead>帽</ENTITY_nounHead>"],
|
|
187
|
+
"result_segmentation": "小/紅/帽/",
|
|
188
|
+
"status": True,
|
|
189
|
+
"version": "v118",
|
|
190
|
+
"word_count_balance": 9997,...}
|
|
191
|
+
```
|
|
192
|
+
|
|
193
|
+
### 回傳結果 lv2
|
|
194
|
+
詞組斷詞,適合文本分析、特徵值計算、關鍵字擷取…等應用。呈現結果將以具意義的最小單位呈現。
|
|
195
|
+
```
|
|
196
|
+
{"exec_time": 0.04195523262023926,
|
|
197
|
+
"level": "lv2",
|
|
198
|
+
"msg": "Success!",
|
|
199
|
+
"result_pos": ["<ENTITY_nouny>小紅帽</ENTITY_nouny>"],
|
|
200
|
+
"result_segmentation": "小紅帽/",
|
|
201
|
+
"status": True,
|
|
202
|
+
"version": "v118",
|
|
203
|
+
"word_count_balance": 9997,...}
|
|
204
|
+
```
|
|
205
|
+
|
|
206
|
+
----------------------
|
|
207
|
+
### 進階用法 02 >> UserDefinedDictFile :使用者自定詞典。
|
|
208
|
+
[](https://youtu.be/fOyyQyVkZ2k "Articut UserDefined Demo")
|
|
209
|
+
|
|
210
|
+
因為 Articut 只處理「語言知識」而不處理「百科知識」。
|
|
211
|
+
我們提供「使用者自定義」詞彙表的功能,使用 Dictionary 格式,請自行編寫。
|
|
212
|
+
|
|
213
|
+
UserDefinedFile.json
|
|
214
|
+
```
|
|
215
|
+
{"雷姆":["小老婆"],
|
|
216
|
+
"艾蜜莉亞":["大老婆"],
|
|
217
|
+
"初音未來": ["初音", "只是個軟體"],
|
|
218
|
+
"李敏鎬": ["全民歐巴", "歐巴"]}
|
|
219
|
+
```
|
|
220
|
+
|
|
221
|
+
runArticut.py
|
|
222
|
+
```
|
|
223
|
+
from ArticutAPI import Articut
|
|
224
|
+
from pprint import pprint
|
|
225
|
+
|
|
226
|
+
articut = Articut()
|
|
227
|
+
userDefined = "./UserDefinedFile.json"
|
|
228
|
+
inputSTR = "我的最愛是小老婆,不是初音未來。"
|
|
229
|
+
|
|
230
|
+
# 使用自定義詞典
|
|
231
|
+
result = articut.parse(inputSTR, userDefinedDictFILE=userDefined)
|
|
232
|
+
pprint(result)
|
|
233
|
+
|
|
234
|
+
# 未使用自定義詞典
|
|
235
|
+
result = articut.parse(inputSTR)
|
|
236
|
+
pprint(result)
|
|
237
|
+
```
|
|
238
|
+
|
|
239
|
+
### 回傳結果
|
|
240
|
+
```
|
|
241
|
+
# 使用自定義詞典
|
|
242
|
+
{"result_pos": ["<ENTITY_pronoun>我</ENTITY_pronoun><FUNC_inner>的</FUNC_inner><ACTION_verb>最愛</ACTION_verb><AUX>是</AUX><UserDefined>小老婆</UserDefined>",
|
|
243
|
+
",",
|
|
244
|
+
"<FUNC_negation>不</FUNC_negation><AUX>是</AUX><UserDefined>初音未來</UserDefined>",
|
|
245
|
+
"。"],
|
|
246
|
+
"result_segmentation": "我/的/最愛/是/小老婆/,/不/是/初音未來/。/",...}
|
|
247
|
+
|
|
248
|
+
# 未使用自定義詞典
|
|
249
|
+
{"result_pos": ["<ENTITY_pronoun>我</ENTITY_pronoun><FUNC_inner>的</FUNC_inner><ACTION_verb>最愛</ACTION_verb><AUX>是</AUX><ENTITY_nouny>小老婆</ENTITY_nouny>",
|
|
250
|
+
",",
|
|
251
|
+
"<FUNC_negation>不</FUNC_negation><AUX>是</AUX><ENTITY_nouny>初音</ENTITY_nouny><TIME_justtime>未來</TIME_justtime>",
|
|
252
|
+
"。"],
|
|
253
|
+
"result_segmentation": "我/的/最愛/是/小老婆/,/不/是/初音/未來/。/",...}
|
|
254
|
+
```
|
|
255
|
+
----------------------
|
|
256
|
+
### 進階用法 03 - 調用資料觀光資訊資料庫
|
|
257
|
+
政府開放平台中存有「交通部觀光局蒐集各政府機關所發佈空間化觀光資訊」。Articut 可取用其中的資訊,並標記為 \<KNOWLEDGE_place>
|
|
258
|
+
|
|
259
|
+
**上傳內容 (JSON 格式)**
|
|
260
|
+
```
|
|
261
|
+
{
|
|
262
|
+
"username": "test@email.com",
|
|
263
|
+
"api_key": "anapikeyfordocthatdoesnwork@all",
|
|
264
|
+
"input_str": "花蓮的原野牧場有一間餐廳",
|
|
265
|
+
"version": "v137",
|
|
266
|
+
"level": "lv1",
|
|
267
|
+
"opendata_place": true
|
|
268
|
+
}
|
|
269
|
+
```
|
|
270
|
+
|
|
271
|
+
**回傳內容 (JSON 格式)**
|
|
272
|
+
```
|
|
273
|
+
{
|
|
274
|
+
"exec_time": 0.013453006744384766,
|
|
275
|
+
"level": "lv1",
|
|
276
|
+
"msg": "Success!",
|
|
277
|
+
"result_pos": ["<LOCATION>花蓮</LOCATION><FUNC_inner>的</FUNC_inner><KNOWLEDGE_place>原野牧場</KNOWLEDGE_place><ACTION_verb>有</ACTION_verb><ENTITY_classifier>一間</ENTITY_classifier><ENTITY_noun>餐廳</ENTITY_noun>"],
|
|
278
|
+
"result_segmentation": "花蓮/的/原野牧場/有/一間/餐廳/",
|
|
279
|
+
"status": True,
|
|
280
|
+
"version": "v137",
|
|
281
|
+
"word_count_balance": 99987
|
|
282
|
+
}
|
|
283
|
+
```
|
|
284
|
+
----------------------
|
|
285
|
+
|
|
286
|
+
### 進階用法 04 - 基於 TF-IDF 算法的關鍵詞抽取
|
|
287
|
+
|
|
288
|
+
* articut.analyse.extract_tags(sentence, topK=20, withWeight=False, allowPOS=())
|
|
289
|
+
* sentence 為要提取關鍵詞的文本
|
|
290
|
+
* topK 為提取幾個 TF-IDF 的關鍵詞,預設值為 20
|
|
291
|
+
* withWeight 為是否返回關鍵詞權重值,預設值為 False
|
|
292
|
+
* allowPOS 僅抽取指定詞性的詞,預設值為空,亦即全部抽取
|
|
293
|
+
* articut.analyse.TFIDF(idf\_path=None) 新建 TFIDF 物件,idf_path 為 IDF 語料庫路徑
|
|
294
|
+
|
|
295
|
+
使用範例:
|
|
296
|
+
<https://github.com/Droidtown/ArticutAPI/blob/master/ArticutAPI.py#L624>
|
|
297
|
+
|
|
298
|
+
---
|
|
299
|
+
|
|
300
|
+
### 進階用法 05 - 基於 TextRank 算法的關鍵詞抽取
|
|
301
|
+
|
|
302
|
+
* articut.analyse.textrank(sentence, topK=20, withWeight=False, allowPOS=())
|
|
303
|
+
* sentence 為要提取關鍵詞的文本
|
|
304
|
+
* topK 為提取幾個 TF-IDF 的關鍵詞,預設值為 20
|
|
305
|
+
* withWeight 為是否返回關鍵詞權重值,預設值為 False
|
|
306
|
+
* allowPOS 僅抽取指定詞性的詞,預設值為空,亦即全部抽取
|
|
307
|
+
* articut.analyse.TextRank() 新建 TextRank 物件
|
|
308
|
+
|
|
309
|
+
算法論文:[TextRank: Bringing Order into Texts](http://web.eecs.umich.edu/~mihalcea/papers/mihalcea.emnlp04.pdf)
|
|
310
|
+
|
|
311
|
+
### 基本思想:
|
|
312
|
+
|
|
313
|
+
1. 將待抽取關鍵詞的文本斷詞
|
|
314
|
+
2. 以固定的窗格大小 (預設值為 5,通過 span 屬性調整),詞之間的共現關係,建構出不帶權圖
|
|
315
|
+
3. 計算途中節點的 PageRank
|
|
316
|
+
|
|
317
|
+
使用範例:
|
|
318
|
+
<https://github.com/Droidtown/ArticutAPI/blob/master/ArticutAPI.py#L629>
|
|
319
|
+
|
|
320
|
+
---
|
|
321
|
+
|
|
322
|
+
### 進階用法 06 - 使用 GraphQL 查詢斷詞結果
|
|
323
|
+
[](https://youtu.be/0Ubx08WJ7rU)
|
|
324
|
+
|
|
325
|
+
### 使用 GraphiQL 工具
|
|
326
|
+
|
|
327
|
+
**環境需求**
|
|
328
|
+
|
|
329
|
+
```
|
|
330
|
+
Python 3.6.1
|
|
331
|
+
$ pip install graphene
|
|
332
|
+
$ pip install starlette
|
|
333
|
+
$ pip install jinja2
|
|
334
|
+
$ pip install uvicorn
|
|
335
|
+
```
|
|
336
|
+
|
|
337
|
+
執行 ArticutGraphQL.py 帶入 Articut 斷詞結果檔案路徑,並開啟瀏覽器輸入網址 http://0.0.0.0:8000/
|
|
338
|
+
|
|
339
|
+
```
|
|
340
|
+
$ python ArticutGraphQL.py articutResult.json
|
|
341
|
+
```
|
|
342
|
+
|
|
343
|
+
### 使用範例 01
|
|
344
|
+

|
|
345
|
+
|
|
346
|
+
### 使用範例 02
|
|
347
|
+

|
|
348
|
+
|
|
349
|
+
### 使用 Articut-GraphQL
|
|
350
|
+
|
|
351
|
+
安裝 graphene 模組
|
|
352
|
+
|
|
353
|
+
```
|
|
354
|
+
$ pip install graphene
|
|
355
|
+
```
|
|
356
|
+
### 使用範例 01
|
|
357
|
+
```
|
|
358
|
+
inputSTR = "地址:宜蘭縣宜蘭市縣政北七路六段55巷1號2樓"
|
|
359
|
+
result = articut.parse(inputSTR)
|
|
360
|
+
with open("articutResult.json", "w", encoding="utf-8") as resultFile:
|
|
361
|
+
json.dump(result, resultFile, ensure_ascii=False)
|
|
362
|
+
|
|
363
|
+
graphQLResult = articut.graphQL.query(
|
|
364
|
+
filePath="articutResult.json",
|
|
365
|
+
query="""
|
|
366
|
+
{
|
|
367
|
+
meta {
|
|
368
|
+
lang
|
|
369
|
+
description
|
|
370
|
+
}
|
|
371
|
+
doc {
|
|
372
|
+
text
|
|
373
|
+
tokens {
|
|
374
|
+
text
|
|
375
|
+
pos_
|
|
376
|
+
tag_
|
|
377
|
+
isStop
|
|
378
|
+
isEntity
|
|
379
|
+
isVerb
|
|
380
|
+
isTime
|
|
381
|
+
isClause
|
|
382
|
+
isKnowledge
|
|
383
|
+
}
|
|
384
|
+
}
|
|
385
|
+
}""")
|
|
386
|
+
pprint(graphQLResult)
|
|
387
|
+
```
|
|
388
|
+
|
|
389
|
+
### 回傳結果
|
|
390
|
+

|
|
391
|
+
|
|
392
|
+
### 使用範例 02
|
|
393
|
+
```
|
|
394
|
+
inputSTR = "劉克襄在本次活動當中,分享了台北中山北路一日遊路線。他表示當初自己領著柯文哲一同探索了雙連市場與中山捷運站的小吃與商圈,還有商圈內的文創商店與日系雜物店鋪,都令柯文哲留下深刻的印象。劉克襄也認為,雙連市場內的魯肉飯、圓仔湯與切仔麵,還有九條通的日式店家、居酒屋等特色,也能讓人感受到台北舊城區不一樣的魅力。"
|
|
395
|
+
result = articut.parse(inputSTR)
|
|
396
|
+
with open("articutResult.json", "w", encoding="utf-8") as resultFile:
|
|
397
|
+
json.dump(result, resultFile, ensure_ascii=False)
|
|
398
|
+
|
|
399
|
+
graphQLResult = articut.graphQL.query(
|
|
400
|
+
filePath="articutResult.json",
|
|
401
|
+
query="""
|
|
402
|
+
{
|
|
403
|
+
meta {
|
|
404
|
+
lang
|
|
405
|
+
description
|
|
406
|
+
}
|
|
407
|
+
doc {
|
|
408
|
+
text
|
|
409
|
+
ents {
|
|
410
|
+
persons {
|
|
411
|
+
text
|
|
412
|
+
pos_
|
|
413
|
+
tag_
|
|
414
|
+
}
|
|
415
|
+
}
|
|
416
|
+
}
|
|
417
|
+
}""")
|
|
418
|
+
pprint(graphQLResult)
|
|
419
|
+
```
|
|
420
|
+
|
|
421
|
+
### 回傳結果
|
|
422
|
+

|
|
423
|
+
|
|
424
|
+
|
|
425
|
+
|
|
@@ -0,0 +1,9 @@
|
|
|
1
|
+
src/ArticutAPI.py,sha256=Mwy0dRSimfg-9ZHRUWw0m4PI2SOeurZglfA2LZSe9nM,19974
|
|
2
|
+
src/MP_ArticutAPI.py,sha256=CaG1LZ2u_nT6injCNIZA_wpSfQXEzq8BxorBECjhioU,16273
|
|
3
|
+
src/WS_ArticutAPI.py,sha256=jEJibT-Ykl5e7lu9cPn3lqc35m3Rk4SJa20tnhuk89g,16737
|
|
4
|
+
src/__init__.py,sha256=N44fBugnVq4zd8Oi2Tp0hlGcasG2gs002NTRqgNhejY,94
|
|
5
|
+
ArticutAPI-1.0.6.dist-info/LICENSE,sha256=aOMTpG-tNkZYAUAiqryrWI1EMqRxzPDIiBJKboFIZIc,1094
|
|
6
|
+
ArticutAPI-1.0.6.dist-info/METADATA,sha256=V73JOBu_xBWGwYgPC-2O0Mtx0Y_paFPFltt-0T42Zco,14137
|
|
7
|
+
ArticutAPI-1.0.6.dist-info/WHEEL,sha256=OqRkF0eY5GHssMorFjlbTIq072vpHpF60fIQA6lS9xA,92
|
|
8
|
+
ArticutAPI-1.0.6.dist-info/top_level.txt,sha256=74rtVfumQlgAPzR5_2CgYN24MB0XARCg0t-gzk6gTrM,4
|
|
9
|
+
ArticutAPI-1.0.6.dist-info/RECORD,,
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
src
|