agentfork-cli 0.1.0__py3-none-any.whl
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- agentfork/__init__.py +3 -0
- agentfork/cli.py +259 -0
- agentfork/recorder.py +201 -0
- agentfork/replay.py +109 -0
- agentfork/store.py +70 -0
- agentfork_cli-0.1.0.dist-info/METADATA +125 -0
- agentfork_cli-0.1.0.dist-info/RECORD +10 -0
- agentfork_cli-0.1.0.dist-info/WHEEL +4 -0
- agentfork_cli-0.1.0.dist-info/entry_points.txt +2 -0
- agentfork_cli-0.1.0.dist-info/licenses/LICENSE +21 -0
agentfork/__init__.py
ADDED
agentfork/cli.py
ADDED
|
@@ -0,0 +1,259 @@
|
|
|
1
|
+
import json
|
|
2
|
+
from datetime import datetime
|
|
3
|
+
from typing import List, Optional
|
|
4
|
+
|
|
5
|
+
import typer
|
|
6
|
+
from rich.console import Console
|
|
7
|
+
from rich.syntax import Syntax
|
|
8
|
+
from rich.table import Table
|
|
9
|
+
from rich.tree import Tree
|
|
10
|
+
|
|
11
|
+
from . import replay, store
|
|
12
|
+
|
|
13
|
+
app = typer.Typer(help="agentfork: record, inspect and replay LLM agent runs.")
|
|
14
|
+
console = Console()
|
|
15
|
+
STATUS_COLOR = {"ok": "green", "error": "red", "running": "yellow"}
|
|
16
|
+
|
|
17
|
+
def _load(text):
|
|
18
|
+
return json.loads(text) if text else None
|
|
19
|
+
|
|
20
|
+
def _fmt_time(ts):
|
|
21
|
+
return datetime.fromtimestamp(ts).strftime("%m-%d %H:%M:%S") if ts else "-"
|
|
22
|
+
|
|
23
|
+
def _duration(run):
|
|
24
|
+
if not run.get("ended_at"):
|
|
25
|
+
return "-"
|
|
26
|
+
return f"{run['ended_at'] - run['started_at']:.1f}s"
|
|
27
|
+
|
|
28
|
+
def _summarize(step):
|
|
29
|
+
inp, out = _load(step["input_json"]), _load(step["output_json"])
|
|
30
|
+
if step["error"]:
|
|
31
|
+
return f"[red]{step['error']}[/red]"
|
|
32
|
+
if step["type"] == "tool" and isinstance(inp, dict):
|
|
33
|
+
args = inp.get("kwargs") or inp.get("args")
|
|
34
|
+
return f"{args} -> {out}"
|
|
35
|
+
if step["type"] == "llm" and isinstance(out, dict):
|
|
36
|
+
if "choices" in out:
|
|
37
|
+
msg = (out.get("choices") or [{}])[0].get("message") or {}
|
|
38
|
+
calls = msg.get("tool_calls") or []
|
|
39
|
+
if calls:
|
|
40
|
+
return "calls " + ", ".join(c["function"]["name"] for c in calls)
|
|
41
|
+
return (msg.get("content") or "")[:120]
|
|
42
|
+
blocks = [b for b in (out.get("content") or []) if isinstance(b, dict)]
|
|
43
|
+
tools = [b.get("name") for b in blocks if b.get("type") == "tool_use"]
|
|
44
|
+
if tools:
|
|
45
|
+
return "calls " + ", ".join(tools)
|
|
46
|
+
return " ".join(b.get("text", "") for b in blocks if b.get("type") == "text")[:120]
|
|
47
|
+
return str(out)[:120]
|
|
48
|
+
|
|
49
|
+
def _label(s):
|
|
50
|
+
tokens = f" {s['tokens_in']}->{s['tokens_out']} tok" if s["tokens_in"] is not None else ""
|
|
51
|
+
kind = "cyan" if s["type"] == "llm" else "magenta"
|
|
52
|
+
cached = " [green](cached)[/green]" if s.get("cached") else ""
|
|
53
|
+
return (f"[dim]#{s['seq']}[/dim] [{kind}]{s['type']}[/{kind}] [bold]{s['name']}[/bold] "
|
|
54
|
+
f"[dim]{s['latency_ms']:.0f}ms{tokens}[/dim]{cached} {_summarize(s)}")
|
|
55
|
+
|
|
56
|
+
def _resolve(prefix):
|
|
57
|
+
matches = store.find_runs(prefix)
|
|
58
|
+
if not matches:
|
|
59
|
+
console.print(f"[red]No run found starting with '{prefix}'[/red]")
|
|
60
|
+
raise typer.Exit(1)
|
|
61
|
+
if len(matches) > 1:
|
|
62
|
+
console.print(f"[yellow]'{prefix}' matches {len(matches)} runs; use more characters[/yellow]")
|
|
63
|
+
raise typer.Exit(1)
|
|
64
|
+
return matches[0]
|
|
65
|
+
|
|
66
|
+
@app.command("list")
|
|
67
|
+
def list_runs(limit: int = typer.Option(10, help="How many recent runs to show.")):
|
|
68
|
+
"""List recent runs."""
|
|
69
|
+
table = Table(title="Recent runs")
|
|
70
|
+
for col in ["id", "name", "status", "steps", "tokens", "duration", "started", "fork of"]:
|
|
71
|
+
table.add_column(col)
|
|
72
|
+
for r in store.list_runs(limit):
|
|
73
|
+
color = STATUS_COLOR.get(r["status"], "white")
|
|
74
|
+
fork = f"{r['parent_run_id'][:8]}@{r['fork_step']}" if r.get("parent_run_id") else ""
|
|
75
|
+
table.add_row(r["id"][:8], r["name"], f"[{color}]{r['status']}[/{color}]",
|
|
76
|
+
str(r["n_steps"]), str(r["tokens"]), _duration(r), _fmt_time(r["started_at"]), fork)
|
|
77
|
+
console.print(table)
|
|
78
|
+
|
|
79
|
+
@app.command()
|
|
80
|
+
def show(run_id: str = typer.Argument(..., help="Run id or its first few characters."),
|
|
81
|
+
full: bool = typer.Option(False, "--full", help="Show full inputs and outputs.")):
|
|
82
|
+
"""Show one run as a step tree."""
|
|
83
|
+
run = _resolve(run_id)
|
|
84
|
+
color = STATUS_COLOR.get(run["status"], "white")
|
|
85
|
+
fork = (f" [dim]fork of {run['parent_run_id'][:8]} at step {run['fork_step']}[/dim]"
|
|
86
|
+
if run.get("parent_run_id") else "")
|
|
87
|
+
root = Tree(f"[bold]{run['name']}[/bold] {run['id'][:8]} "
|
|
88
|
+
f"[{color}]{run['status']}[/{color}] {_duration(run)}{fork}")
|
|
89
|
+
nodes = {}
|
|
90
|
+
for s in store.get_steps(run["id"]):
|
|
91
|
+
node = nodes.get(s["parent_id"], root).add(_label(s))
|
|
92
|
+
if full:
|
|
93
|
+
node.add(Syntax(json.dumps(_load(s["input_json"]), indent=2), "json", word_wrap=True))
|
|
94
|
+
node.add(Syntax(json.dumps(_load(s["output_json"]), indent=2), "json", word_wrap=True))
|
|
95
|
+
nodes[s["id"]] = node
|
|
96
|
+
console.print(root)
|
|
97
|
+
console.print(f"[bold]Final output:[/bold] {_load(run['output_json'])}")
|
|
98
|
+
|
|
99
|
+
@app.command()
|
|
100
|
+
def fork(run_id: str = typer.Argument(..., help="Run to fork."),
|
|
101
|
+
step: int = typer.Option(..., "--step", help="Step number to change (see `show`)."),
|
|
102
|
+
output: Optional[str] = typer.Option(None, "--output", help="Fake result for a tool step."),
|
|
103
|
+
model: Optional[str] = typer.Option(None, "--model", help="Different model for an LLM step."),
|
|
104
|
+
system: Optional[str] = typer.Option(None, "--system", help="System prompt for an LLM step.")):
|
|
105
|
+
"""Re-run a past run from one step with one change; earlier steps come from the cache."""
|
|
106
|
+
if output is None and model is None and system is None:
|
|
107
|
+
console.print("[red]Give one change: --output, --model or --system[/red]")
|
|
108
|
+
raise typer.Exit(1)
|
|
109
|
+
run = _resolve(run_id)
|
|
110
|
+
try:
|
|
111
|
+
new_id, _ = replay.fork(run, step, output=output, model=model, system=system)
|
|
112
|
+
except Exception as e:
|
|
113
|
+
console.print(f"[red]Fork failed: {e}[/red]")
|
|
114
|
+
raise typer.Exit(1)
|
|
115
|
+
console.print(f"[green]Forked {run['id'][:8]} at step {step} -> new run {new_id[:8]}[/green]")
|
|
116
|
+
show(new_id, full=False)
|
|
117
|
+
console.print(f"[dim]Compare: agentfork diff {run['id'][:8]} {new_id[:8]}[/dim]")
|
|
118
|
+
|
|
119
|
+
@app.command()
|
|
120
|
+
def diff(run_a: str = typer.Argument(..., help="First run."),
|
|
121
|
+
run_b: str = typer.Argument(..., help="Second run.")):
|
|
122
|
+
"""Compare two runs step by step."""
|
|
123
|
+
a, b = _resolve(run_a), _resolve(run_b)
|
|
124
|
+
sa = {s["seq"]: s for s in store.get_steps(a["id"])}
|
|
125
|
+
sb = {s["seq"]: s for s in store.get_steps(b["id"])}
|
|
126
|
+
table = Table(title=f"{a['id'][:8]} vs {b['id'][:8]}", show_lines=True)
|
|
127
|
+
table.add_column("#")
|
|
128
|
+
table.add_column(a["id"][:8])
|
|
129
|
+
table.add_column(b["id"][:8])
|
|
130
|
+
for seq in sorted(set(sa) | set(sb)):
|
|
131
|
+
left = _label(sa[seq]) if seq in sa else "[dim]-[/dim]"
|
|
132
|
+
right = _label(sb[seq]) if seq in sb else "[dim]-[/dim]"
|
|
133
|
+
same = seq in sa and seq in sb and _summarize(sa[seq]) == _summarize(sb[seq])
|
|
134
|
+
table.add_row(str(seq) if same else f"[yellow]{seq} *[/yellow]", left, right)
|
|
135
|
+
console.print(table)
|
|
136
|
+
console.print(f"[bold]{a['id'][:8]} output:[/bold] {_load(a['output_json'])}")
|
|
137
|
+
console.print(f"[bold]{b['id'][:8]} output:[/bold] {_load(b['output_json'])}")
|
|
138
|
+
|
|
139
|
+
TEST_TEMPLATE = '''# Generated by `agentfork save-test` from run {run_id}.
|
|
140
|
+
# Replays the recorded run entirely from cache: no API calls, no cost.
|
|
141
|
+
# If you change prompts, tools or agent logic on purpose, record a new run
|
|
142
|
+
# and run `agentfork save-test <new-run-id>` again.
|
|
143
|
+
import json
|
|
144
|
+
from pathlib import Path
|
|
145
|
+
|
|
146
|
+
from agentfork import replay
|
|
147
|
+
|
|
148
|
+
FIXTURE = Path(__file__).with_name("run_{short}.json")
|
|
149
|
+
ROOT = Path(__file__).resolve().parents[{depth}]
|
|
150
|
+
|
|
151
|
+
|
|
152
|
+
def test_run_{short}_replays(tmp_path, monkeypatch):
|
|
153
|
+
monkeypatch.setenv("AGENTFORK_DIR", str(tmp_path))
|
|
154
|
+
monkeypatch.setenv("OPENAI_API_KEY", "sk-agentfork-replay")
|
|
155
|
+
replay.check(json.loads(FIXTURE.read_text()), ROOT)
|
|
156
|
+
'''
|
|
157
|
+
|
|
158
|
+
@app.command("save-test")
|
|
159
|
+
def save_test(run_id: str = typer.Argument(..., help="Run to turn into a test."),
|
|
160
|
+
out: str = typer.Option("tests/agentfork", "--out", help="Folder for the generated test.")):
|
|
161
|
+
"""Save a run as a pytest regression test that replays it from cache."""
|
|
162
|
+
import os
|
|
163
|
+
from pathlib import Path
|
|
164
|
+
run = _resolve(run_id)
|
|
165
|
+
if not run.get("entry_file"):
|
|
166
|
+
console.print("[red]This run has no saved entry point; run your agent again and save the new run.[/red]")
|
|
167
|
+
raise typer.Exit(1)
|
|
168
|
+
if run.get("parent_run_id"):
|
|
169
|
+
console.print("[yellow]This run is a fork, and its change isn't in your code yet. "
|
|
170
|
+
"Apply the fix, run your agent again, and save that run.[/yellow]")
|
|
171
|
+
raise typer.Exit(1)
|
|
172
|
+
cwd = Path.cwd()
|
|
173
|
+
out_dir = Path(out)
|
|
174
|
+
out_dir.mkdir(parents=True, exist_ok=True)
|
|
175
|
+
short = run["id"][:8]
|
|
176
|
+
fixture = {"run": dict(run, entry_file=os.path.relpath(run["entry_file"], cwd)),
|
|
177
|
+
"steps": store.get_steps(run["id"])}
|
|
178
|
+
fixture_path = out_dir / f"run_{short}.json"
|
|
179
|
+
test_path = out_dir / f"test_run_{short}.py"
|
|
180
|
+
fixture_path.write_text(json.dumps(fixture, indent=2))
|
|
181
|
+
depth = len(Path(os.path.relpath(out_dir.resolve(), cwd)).parts)
|
|
182
|
+
test_path.write_text(TEST_TEMPLATE.format(run_id=run["id"], short=short, depth=depth))
|
|
183
|
+
console.print(f"[green]Saved {test_path} and {fixture_path.name}[/green]")
|
|
184
|
+
console.print(f"[dim]Run it with: pytest {test_path}[/dim]")
|
|
185
|
+
|
|
186
|
+
|
|
187
|
+
def _make_labels(variants):
|
|
188
|
+
labels, counts = {}, {}
|
|
189
|
+
for v in variants:
|
|
190
|
+
key, value = next(iter(v.items()))
|
|
191
|
+
if key == "model":
|
|
192
|
+
labels[id(v)] = f"model={value}"
|
|
193
|
+
else:
|
|
194
|
+
counts[key] = counts.get(key, 0) + 1
|
|
195
|
+
labels[id(v)] = f"{key} #{counts[key]}"
|
|
196
|
+
return labels
|
|
197
|
+
|
|
198
|
+
@app.command()
|
|
199
|
+
def sweep(run_id: str = typer.Argument(..., help="Run to sweep."),
|
|
200
|
+
step: int = typer.Option(..., "--step", help="Step to vary (see `show`)."),
|
|
201
|
+
model: Optional[str] = typer.Option(None, "--model", help="Comma-separated models to try."),
|
|
202
|
+
system: Optional[List[str]] = typer.Option(None, "--system", help="System prompt to try; repeat for more."),
|
|
203
|
+
output: Optional[List[str]] = typer.Option(None, "--output", help="Tool result to try; repeat for more."),
|
|
204
|
+
repeat: int = typer.Option(1, "--repeat", help="Runs per variant (LLMs vary run to run)."),
|
|
205
|
+
expect: Optional[str] = typer.Option(None, "--expect", help="Text a good final output contains.")):
|
|
206
|
+
"""Fork one step across several models, prompts or tool results and compare outcomes."""
|
|
207
|
+
variants = [{"model": m.strip()} for m in (model or "").split(",") if m.strip()]
|
|
208
|
+
variants += [{"system": s} for s in (system or [])]
|
|
209
|
+
variants += [{"output": o} for o in (output or [])]
|
|
210
|
+
if not variants:
|
|
211
|
+
console.print("[red]Give at least one variant: --model, --system or --output[/red]")
|
|
212
|
+
raise typer.Exit(1)
|
|
213
|
+
run = _resolve(run_id)
|
|
214
|
+
labels = _make_labels(variants)
|
|
215
|
+
console.print(f"[bold]Sweeping step {step} of {run['id'][:8]}: "
|
|
216
|
+
f"{len(variants)} variants x {repeat} = {len(variants) * repeat} runs[/bold]")
|
|
217
|
+
|
|
218
|
+
def progress(r):
|
|
219
|
+
mark = "[green]ok[/green]" if r["status"] == "ok" else "[red]error[/red]"
|
|
220
|
+
verdict = "" if r["passed"] is None else (" [green]pass[/green]" if r["passed"] else " [red]fail[/red]")
|
|
221
|
+
console.print(f" {mark}{verdict} {labels[id(r['variant'])]} [dim]{r['tokens']} tok[/dim]")
|
|
222
|
+
|
|
223
|
+
try:
|
|
224
|
+
results = replay.sweep(run, step, variants, repeat=repeat, expect=expect, on_result=progress)
|
|
225
|
+
except ValueError as e:
|
|
226
|
+
console.print(f"[red]{e}[/red]")
|
|
227
|
+
raise typer.Exit(1)
|
|
228
|
+
|
|
229
|
+
groups = {"original": [replay.baseline(run, step, expect)]}
|
|
230
|
+
for r in results:
|
|
231
|
+
groups.setdefault(labels[id(r["variant"])], []).append(r)
|
|
232
|
+
table = Table(title=f"Sweep of step {step} ({run['id'][:8]})", show_lines=True)
|
|
233
|
+
table.add_column("variant", no_wrap=True)
|
|
234
|
+
table.add_column("runs", no_wrap=True, min_width=4)
|
|
235
|
+
table.add_column("ok", no_wrap=True, min_width=3)
|
|
236
|
+
if expect:
|
|
237
|
+
table.add_column("pass", no_wrap=True, min_width=4)
|
|
238
|
+
table.add_column("avg tokens", no_wrap=True, min_width=6)
|
|
239
|
+
table.add_column("avg time", no_wrap=True, min_width=6)
|
|
240
|
+
table.add_column("sample output", max_width=36, overflow="ellipsis", no_wrap=True)
|
|
241
|
+
table.add_column("run ids", no_wrap=True)
|
|
242
|
+
for label, rs in groups.items():
|
|
243
|
+
n = len(rs)
|
|
244
|
+
ids = [(r["run_id"] or "-")[:8] for r in rs]
|
|
245
|
+
row = [label, str(n), f"{sum(r['status'] == 'ok' for r in rs)}/{n}"]
|
|
246
|
+
if expect:
|
|
247
|
+
passed = sum(bool(r["passed"]) for r in rs)
|
|
248
|
+
color = "green" if passed == n else ("yellow" if passed else "red")
|
|
249
|
+
row.append(f"[{color}]{passed}/{n}[/{color}]")
|
|
250
|
+
row += [f"{sum(r['tokens'] for r in rs) / n:.0f}",
|
|
251
|
+
f"{sum(r['latency_ms'] for r in rs) / n / 1000:.1f}s",
|
|
252
|
+
str(rs[0]["result"]),
|
|
253
|
+
", ".join(ids[:2]) + (f" +{len(ids) - 2}" if len(ids) > 2 else "")]
|
|
254
|
+
table.add_row(*row)
|
|
255
|
+
console.print(table)
|
|
256
|
+
for v in variants:
|
|
257
|
+
key, value = next(iter(v.items()))
|
|
258
|
+
if key != "model":
|
|
259
|
+
console.print(f"[bold]{labels[id(v)]}[/bold]: {value}")
|
agentfork/recorder.py
ADDED
|
@@ -0,0 +1,201 @@
|
|
|
1
|
+
import contextvars, difflib, functools, hashlib, inspect, json, time, uuid, warnings
|
|
2
|
+
from . import store
|
|
3
|
+
|
|
4
|
+
_run_id = contextvars.ContextVar("run_id", default=None)
|
|
5
|
+
_parent_step = contextvars.ContextVar("parent_step", default=None)
|
|
6
|
+
_seq = contextvars.ContextVar("seq", default=None)
|
|
7
|
+
_replay = contextvars.ContextVar("replay", default=None)
|
|
8
|
+
|
|
9
|
+
_LLM_DECODERS = {}
|
|
10
|
+
last_run_id = None
|
|
11
|
+
last_run_seq = 0
|
|
12
|
+
|
|
13
|
+
class ReplayMismatch(AssertionError):
|
|
14
|
+
"""The agent did something different from the recorded run."""
|
|
15
|
+
|
|
16
|
+
def _decode_llm(data):
|
|
17
|
+
if isinstance(data, dict):
|
|
18
|
+
if data.get("object") == "chat.completion" and "openai" in _LLM_DECODERS:
|
|
19
|
+
return _LLM_DECODERS["openai"](data)
|
|
20
|
+
if data.get("type") == "message" and "anthropic" in _LLM_DECODERS:
|
|
21
|
+
return _LLM_DECODERS["anthropic"](data)
|
|
22
|
+
return data
|
|
23
|
+
|
|
24
|
+
DECODERS = {"llm": _decode_llm}
|
|
25
|
+
|
|
26
|
+
def to_jsonable(obj):
|
|
27
|
+
if hasattr(obj, "model_dump"):
|
|
28
|
+
return to_jsonable(obj.model_dump())
|
|
29
|
+
if isinstance(obj, dict):
|
|
30
|
+
return {str(k): to_jsonable(v) for k, v in obj.items()}
|
|
31
|
+
if isinstance(obj, (list, tuple)):
|
|
32
|
+
return [to_jsonable(v) for v in obj]
|
|
33
|
+
if obj is None or isinstance(obj, (str, int, float, bool)):
|
|
34
|
+
return obj
|
|
35
|
+
return repr(obj)
|
|
36
|
+
|
|
37
|
+
def dumps(obj):
|
|
38
|
+
return json.dumps(to_jsonable(obj), sort_keys=True)
|
|
39
|
+
|
|
40
|
+
def make_cache_key(step_type, name, input_json):
|
|
41
|
+
return hashlib.sha256(f"{step_type}|{name}|{input_json}".encode()).hexdigest()
|
|
42
|
+
|
|
43
|
+
def _tokens(usage, *names):
|
|
44
|
+
for n in names:
|
|
45
|
+
value = getattr(usage, n, None)
|
|
46
|
+
if value is not None:
|
|
47
|
+
return value
|
|
48
|
+
return None
|
|
49
|
+
|
|
50
|
+
def _apply_override(step_type, kwargs, override, provider=None):
|
|
51
|
+
kwargs = dict(kwargs)
|
|
52
|
+
if step_type == "llm":
|
|
53
|
+
if override.get("model"):
|
|
54
|
+
kwargs["model"] = override["model"]
|
|
55
|
+
if override.get("system"):
|
|
56
|
+
if provider == "anthropic":
|
|
57
|
+
kwargs["system"] = override["system"]
|
|
58
|
+
else:
|
|
59
|
+
msgs = [m for m in kwargs.get("messages", [])
|
|
60
|
+
if not (isinstance(m, dict) and m.get("role") == "system")]
|
|
61
|
+
kwargs["messages"] = [{"role": "system", "content": override["system"]}] + msgs
|
|
62
|
+
return kwargs
|
|
63
|
+
|
|
64
|
+
def _last_descendant_seq(steps, step):
|
|
65
|
+
ids, last = {step["id"]}, step["seq"]
|
|
66
|
+
for s in sorted(steps.values(), key=lambda s: s["seq"]):
|
|
67
|
+
if s["seq"] > step["seq"] and s["parent_id"] in ids:
|
|
68
|
+
ids.add(s["id"])
|
|
69
|
+
last = s["seq"]
|
|
70
|
+
return last
|
|
71
|
+
|
|
72
|
+
def _explain_mismatch(seq, step_type, name, cached_step, input_json):
|
|
73
|
+
if cached_step["type"] != step_type or cached_step["name"] != name:
|
|
74
|
+
return (f"step {seq} was {cached_step['type']} {cached_step['name']} in the recording "
|
|
75
|
+
f"but is now {step_type} {name}")
|
|
76
|
+
old = json.dumps(json.loads(cached_step["input_json"]), indent=2, sort_keys=True).splitlines()
|
|
77
|
+
new = json.dumps(json.loads(input_json), indent=2, sort_keys=True).splitlines()
|
|
78
|
+
diff = list(difflib.unified_diff(old, new, "recorded", "now", lineterm="", n=1))[:40]
|
|
79
|
+
return f"step {seq} ({step_type} {name}) got different inputs than the recorded run\n" + "\n".join(diff)
|
|
80
|
+
|
|
81
|
+
def record_step(step_type, name, fn, args, kwargs, provider=None):
|
|
82
|
+
run_id = _run_id.get()
|
|
83
|
+
if run_id is None:
|
|
84
|
+
return fn(*args, **kwargs)
|
|
85
|
+
counter = _seq.get()
|
|
86
|
+
counter[0] += 1
|
|
87
|
+
seq = counter[0]
|
|
88
|
+
replay = _replay.get()
|
|
89
|
+
strict = bool(replay and replay.get("strict"))
|
|
90
|
+
cached_step, use_forced = None, False
|
|
91
|
+
if replay and seq < replay["fork_step"]:
|
|
92
|
+
cached_step = replay["steps"].get(seq)
|
|
93
|
+
if strict and cached_step is None:
|
|
94
|
+
raise ReplayMismatch(f"step {seq} ({step_type} {name}) is new: "
|
|
95
|
+
f"the recorded run only had {len(replay['steps'])} steps")
|
|
96
|
+
elif replay and seq == replay["fork_step"]:
|
|
97
|
+
if "output" in replay["override"]:
|
|
98
|
+
use_forced = True
|
|
99
|
+
else:
|
|
100
|
+
kwargs = _apply_override(step_type, kwargs, replay["override"], provider)
|
|
101
|
+
if (replay and not strict and seq > replay["fork_step"] and step_type == "llm"
|
|
102
|
+
and replay["override"].get("model")):
|
|
103
|
+
kwargs = dict(kwargs, model=replay["override"]["model"])
|
|
104
|
+
if step_type == "llm" and kwargs.get("model") and cached_step is None:
|
|
105
|
+
name = kwargs["model"]
|
|
106
|
+
input_json = dumps({"args": args, "kwargs": kwargs})
|
|
107
|
+
key = make_cache_key(step_type, name, input_json)
|
|
108
|
+
if cached_step is not None and cached_step["cache_key"] != key:
|
|
109
|
+
if strict:
|
|
110
|
+
raise ReplayMismatch(_explain_mismatch(seq, step_type, name, cached_step, input_json))
|
|
111
|
+
warnings.warn(f"agentfork: step {seq} inputs differ from the original run; reusing its cached output")
|
|
112
|
+
step_id, parent = uuid.uuid4().hex, _parent_step.get()
|
|
113
|
+
token = _parent_step.set(step_id)
|
|
114
|
+
started = time.time()
|
|
115
|
+
output, error, cached = None, None, 0
|
|
116
|
+
try:
|
|
117
|
+
if cached_step is not None:
|
|
118
|
+
decode = DECODERS.get(step_type, lambda x: x)
|
|
119
|
+
output = decode(json.loads(cached_step["output_json"]))
|
|
120
|
+
counter[0] = _last_descendant_seq(replay["steps"], cached_step)
|
|
121
|
+
cached = 1
|
|
122
|
+
elif use_forced:
|
|
123
|
+
output = replay["override"]["output"]
|
|
124
|
+
else:
|
|
125
|
+
output = fn(*args, **kwargs)
|
|
126
|
+
return output
|
|
127
|
+
except Exception as e:
|
|
128
|
+
error = repr(e)
|
|
129
|
+
raise
|
|
130
|
+
finally:
|
|
131
|
+
_parent_step.reset(token)
|
|
132
|
+
usage = None if cached else getattr(output, "usage", None)
|
|
133
|
+
store.insert("steps", {
|
|
134
|
+
"id": step_id, "run_id": run_id, "parent_id": parent, "seq": seq,
|
|
135
|
+
"type": step_type, "name": name,
|
|
136
|
+
"input_json": input_json, "output_json": dumps(output), "cache_key": key,
|
|
137
|
+
"tokens_in": _tokens(usage, "prompt_tokens", "input_tokens"),
|
|
138
|
+
"tokens_out": _tokens(usage, "completion_tokens", "output_tokens"),
|
|
139
|
+
"latency_ms": (time.time() - started) * 1000,
|
|
140
|
+
"error": error, "started_at": started, "cached": cached,
|
|
141
|
+
})
|
|
142
|
+
|
|
143
|
+
def trace(fn=None, *, name=None):
|
|
144
|
+
def deco(f):
|
|
145
|
+
try:
|
|
146
|
+
entry_file = inspect.getsourcefile(f)
|
|
147
|
+
except TypeError:
|
|
148
|
+
entry_file = None
|
|
149
|
+
|
|
150
|
+
@functools.wraps(f)
|
|
151
|
+
def wrapper(*args, **kwargs):
|
|
152
|
+
global last_run_id, last_run_seq
|
|
153
|
+
if _run_id.get() is not None:
|
|
154
|
+
return f(*args, **kwargs)
|
|
155
|
+
run_id = uuid.uuid4().hex
|
|
156
|
+
replay = _replay.get() or {}
|
|
157
|
+
parent_run = replay.get("parent_run_id")
|
|
158
|
+
store.insert("runs", {
|
|
159
|
+
"id": run_id, "name": name or f.__name__, "started_at": time.time(),
|
|
160
|
+
"status": "running", "input_json": dumps({"args": args, "kwargs": kwargs}),
|
|
161
|
+
"entry_file": entry_file, "entry_name": f.__qualname__,
|
|
162
|
+
"parent_run_id": parent_run, "fork_step": replay.get("fork_step") if parent_run else None,
|
|
163
|
+
})
|
|
164
|
+
last_run_id = run_id
|
|
165
|
+
t_run, t_seq, t_parent = _run_id.set(run_id), _seq.set([0]), _parent_step.set(None)
|
|
166
|
+
status, output = "error", None
|
|
167
|
+
try:
|
|
168
|
+
output = f(*args, **kwargs)
|
|
169
|
+
status = "ok"
|
|
170
|
+
return output
|
|
171
|
+
finally:
|
|
172
|
+
last_run_seq = _seq.get()[0]
|
|
173
|
+
_run_id.reset(t_run); _seq.reset(t_seq); _parent_step.reset(t_parent)
|
|
174
|
+
store.update_run(run_id, ended_at=time.time(), status=status, output_json=dumps(output))
|
|
175
|
+
print(f"[agentfork] saved run {run_id[:8]} ({status})")
|
|
176
|
+
return wrapper
|
|
177
|
+
return deco(fn) if fn else deco
|
|
178
|
+
|
|
179
|
+
def tool(fn):
|
|
180
|
+
@functools.wraps(fn)
|
|
181
|
+
def wrapper(*args, **kwargs):
|
|
182
|
+
return record_step("tool", fn.__name__, fn, args, kwargs)
|
|
183
|
+
return wrapper
|
|
184
|
+
|
|
185
|
+
def wrap_openai(client):
|
|
186
|
+
from openai.types.chat import ChatCompletion
|
|
187
|
+
_LLM_DECODERS["openai"] = ChatCompletion.model_validate
|
|
188
|
+
original = client.chat.completions.create
|
|
189
|
+
def create(*args, **kwargs):
|
|
190
|
+
return record_step("llm", kwargs.get("model", "llm"), original, args, kwargs, provider="openai")
|
|
191
|
+
client.chat.completions.create = create
|
|
192
|
+
return client
|
|
193
|
+
|
|
194
|
+
def wrap_anthropic(client):
|
|
195
|
+
from anthropic.types import Message
|
|
196
|
+
_LLM_DECODERS["anthropic"] = Message.model_validate
|
|
197
|
+
original = client.messages.create
|
|
198
|
+
def create(*args, **kwargs):
|
|
199
|
+
return record_step("llm", kwargs.get("model", "llm"), original, args, kwargs, provider="anthropic")
|
|
200
|
+
client.messages.create = create
|
|
201
|
+
return client
|
agentfork/replay.py
ADDED
|
@@ -0,0 +1,109 @@
|
|
|
1
|
+
import importlib.util, json, sys
|
|
2
|
+
from pathlib import Path
|
|
3
|
+
from . import recorder, store
|
|
4
|
+
|
|
5
|
+
def load_entry(run):
|
|
6
|
+
path, qualname = run.get("entry_file"), run.get("entry_name")
|
|
7
|
+
if not path or not Path(path).exists():
|
|
8
|
+
raise RuntimeError("this run has no saved entry point; run your agent again and fork the new run")
|
|
9
|
+
folder = str(Path(path).parent)
|
|
10
|
+
if folder not in sys.path:
|
|
11
|
+
sys.path.insert(0, folder)
|
|
12
|
+
spec = importlib.util.spec_from_file_location("agentfork_entry", path)
|
|
13
|
+
module = importlib.util.module_from_spec(spec)
|
|
14
|
+
spec.loader.exec_module(module)
|
|
15
|
+
obj = module
|
|
16
|
+
for part in qualname.split("."):
|
|
17
|
+
obj = getattr(obj, part)
|
|
18
|
+
return obj
|
|
19
|
+
|
|
20
|
+
def fork(run, step, output=None, model=None, system=None):
|
|
21
|
+
steps = {s["seq"]: s for s in store.get_steps(run["id"])}
|
|
22
|
+
if step not in steps:
|
|
23
|
+
raise ValueError(f"run {run['id'][:8]} has no step {step}")
|
|
24
|
+
kind = steps[step]["type"]
|
|
25
|
+
override = {}
|
|
26
|
+
if output is not None:
|
|
27
|
+
if kind != "tool":
|
|
28
|
+
raise ValueError("--output only works on tool steps")
|
|
29
|
+
override["output"] = output
|
|
30
|
+
if model or system:
|
|
31
|
+
if kind != "llm":
|
|
32
|
+
raise ValueError("--model and --system only work on llm steps")
|
|
33
|
+
override.update({"model": model, "system": system})
|
|
34
|
+
fn = load_entry(run)
|
|
35
|
+
inputs = json.loads(run["input_json"])
|
|
36
|
+
token = recorder._replay.set({"parent_run_id": run["id"], "fork_step": step,
|
|
37
|
+
"steps": steps, "override": override})
|
|
38
|
+
try:
|
|
39
|
+
result = fn(*inputs["args"], **inputs["kwargs"])
|
|
40
|
+
finally:
|
|
41
|
+
recorder._replay.reset(token)
|
|
42
|
+
return recorder.last_run_id, result
|
|
43
|
+
|
|
44
|
+
def check(fixture, root="."):
|
|
45
|
+
run = fixture["run"]
|
|
46
|
+
steps = {s["seq"]: s for s in fixture["steps"]}
|
|
47
|
+
fn = load_entry(dict(run, entry_file=str(Path(root) / run["entry_file"])))
|
|
48
|
+
inputs = json.loads(run["input_json"])
|
|
49
|
+
token = recorder._replay.set({"parent_run_id": None, "fork_step": float("inf"),
|
|
50
|
+
"steps": steps, "override": {}, "strict": True})
|
|
51
|
+
try:
|
|
52
|
+
result = fn(*inputs["args"], **inputs["kwargs"])
|
|
53
|
+
finally:
|
|
54
|
+
recorder._replay.reset(token)
|
|
55
|
+
if recorder.last_run_seq != max(steps, default=0):
|
|
56
|
+
raise recorder.ReplayMismatch(
|
|
57
|
+
f"the recorded run had {max(steps, default=0)} steps but the replay made {recorder.last_run_seq}")
|
|
58
|
+
expected = json.loads(run["output_json"])
|
|
59
|
+
if recorder.to_jsonable(result) != expected:
|
|
60
|
+
raise recorder.ReplayMismatch(f"final output changed\n recorded: {expected!r}\n now: {result!r}")
|
|
61
|
+
return result
|
|
62
|
+
|
|
63
|
+
def _check_variants(run, step, variants):
|
|
64
|
+
steps = {s["seq"]: s for s in store.get_steps(run["id"])}
|
|
65
|
+
if step not in steps:
|
|
66
|
+
raise ValueError(f"run {run['id'][:8]} has no step {step}")
|
|
67
|
+
kind = steps[step]["type"]
|
|
68
|
+
for v in variants:
|
|
69
|
+
if "output" in v and kind != "tool":
|
|
70
|
+
raise ValueError("--output only works on tool steps")
|
|
71
|
+
if ("model" in v or "system" in v) and kind != "llm":
|
|
72
|
+
raise ValueError("--model and --system only work on llm steps")
|
|
73
|
+
|
|
74
|
+
def _summary(steps, result, expect):
|
|
75
|
+
return {
|
|
76
|
+
"tokens": sum((s["tokens_in"] or 0) + (s["tokens_out"] or 0) for s in steps),
|
|
77
|
+
"latency_ms": sum(s["latency_ms"] or 0 for s in steps),
|
|
78
|
+
"passed": None if expect is None else expect.lower() in str(result).lower(),
|
|
79
|
+
}
|
|
80
|
+
|
|
81
|
+
def baseline(run, step, expect=None):
|
|
82
|
+
steps = [s for s in store.get_steps(run["id"]) if s["seq"] >= step]
|
|
83
|
+
result = json.loads(run["output_json"]) if run["output_json"] else None
|
|
84
|
+
return dict({"variant": {"original": True}, "run_id": run["id"],
|
|
85
|
+
"status": run["status"], "result": result}, **_summary(steps, result, expect))
|
|
86
|
+
|
|
87
|
+
def sweep(run, step, variants, repeat=1, expect=None, on_result=None):
|
|
88
|
+
import contextlib, io
|
|
89
|
+
_check_variants(run, step, variants)
|
|
90
|
+
results = []
|
|
91
|
+
for variant in variants:
|
|
92
|
+
for _ in range(repeat):
|
|
93
|
+
before = recorder.last_run_id
|
|
94
|
+
status, run_id, result = "error", None, None
|
|
95
|
+
try:
|
|
96
|
+
with contextlib.redirect_stdout(io.StringIO()):
|
|
97
|
+
run_id, result = fork(run, step, **variant)
|
|
98
|
+
status = "ok"
|
|
99
|
+
except Exception as e:
|
|
100
|
+
result = repr(e)
|
|
101
|
+
if recorder.last_run_id != before:
|
|
102
|
+
run_id = recorder.last_run_id
|
|
103
|
+
live = [s for s in (store.get_steps(run_id) if run_id else []) if not s["cached"]]
|
|
104
|
+
record = dict({"variant": variant, "run_id": run_id, "status": status,
|
|
105
|
+
"result": result}, **_summary(live, result, expect))
|
|
106
|
+
results.append(record)
|
|
107
|
+
if on_result:
|
|
108
|
+
on_result(record)
|
|
109
|
+
return results
|
agentfork/store.py
ADDED
|
@@ -0,0 +1,70 @@
|
|
|
1
|
+
import os, sqlite3
|
|
2
|
+
from contextlib import closing
|
|
3
|
+
from pathlib import Path
|
|
4
|
+
|
|
5
|
+
SCHEMA = """
|
|
6
|
+
CREATE TABLE IF NOT EXISTS runs (
|
|
7
|
+
id TEXT PRIMARY KEY, name TEXT, started_at REAL, ended_at REAL,
|
|
8
|
+
status TEXT, input_json TEXT, output_json TEXT,
|
|
9
|
+
parent_run_id TEXT, fork_step INTEGER, entry_file TEXT, entry_name TEXT
|
|
10
|
+
);
|
|
11
|
+
CREATE TABLE IF NOT EXISTS steps (
|
|
12
|
+
id TEXT PRIMARY KEY, run_id TEXT, parent_id TEXT, seq INTEGER,
|
|
13
|
+
type TEXT, name TEXT, input_json TEXT, output_json TEXT,
|
|
14
|
+
cache_key TEXT, tokens_in INTEGER, tokens_out INTEGER,
|
|
15
|
+
latency_ms REAL, error TEXT, started_at REAL, cached INTEGER DEFAULT 0
|
|
16
|
+
);
|
|
17
|
+
CREATE INDEX IF NOT EXISTS idx_steps_run ON steps(run_id, seq);
|
|
18
|
+
"""
|
|
19
|
+
|
|
20
|
+
MIGRATIONS = [
|
|
21
|
+
"ALTER TABLE runs ADD COLUMN entry_file TEXT",
|
|
22
|
+
"ALTER TABLE runs ADD COLUMN entry_name TEXT",
|
|
23
|
+
"ALTER TABLE steps ADD COLUMN cached INTEGER DEFAULT 0",
|
|
24
|
+
]
|
|
25
|
+
|
|
26
|
+
def db_path():
|
|
27
|
+
return Path(os.environ.get("AGENTFORK_DIR", ".agentfork")) / "traces.db"
|
|
28
|
+
|
|
29
|
+
def connect():
|
|
30
|
+
path = db_path()
|
|
31
|
+
path.parent.mkdir(parents=True, exist_ok=True)
|
|
32
|
+
conn = sqlite3.connect(path)
|
|
33
|
+
conn.executescript(SCHEMA)
|
|
34
|
+
for sql in MIGRATIONS:
|
|
35
|
+
try:
|
|
36
|
+
conn.execute(sql)
|
|
37
|
+
except sqlite3.OperationalError:
|
|
38
|
+
pass
|
|
39
|
+
return conn
|
|
40
|
+
|
|
41
|
+
def _exec(sql, params):
|
|
42
|
+
with closing(connect()) as conn, conn:
|
|
43
|
+
conn.execute(sql, params)
|
|
44
|
+
|
|
45
|
+
def insert(table, row):
|
|
46
|
+
cols = ", ".join(row)
|
|
47
|
+
marks = ", ".join("?" for _ in row)
|
|
48
|
+
_exec(f"INSERT INTO {table} ({cols}) VALUES ({marks})", list(row.values()))
|
|
49
|
+
|
|
50
|
+
def update_run(run_id, **fields):
|
|
51
|
+
sets = ", ".join(f"{k}=?" for k in fields)
|
|
52
|
+
_exec(f"UPDATE runs SET {sets} WHERE id=?", [*fields.values(), run_id])
|
|
53
|
+
|
|
54
|
+
def query(sql, params=()):
|
|
55
|
+
with closing(connect()) as conn:
|
|
56
|
+
conn.row_factory = sqlite3.Row
|
|
57
|
+
return [dict(r) for r in conn.execute(sql, params)]
|
|
58
|
+
|
|
59
|
+
def list_runs(limit=10):
|
|
60
|
+
return query("""
|
|
61
|
+
SELECT r.*, COUNT(s.id) AS n_steps,
|
|
62
|
+
COALESCE(SUM(s.tokens_in), 0) + COALESCE(SUM(s.tokens_out), 0) AS tokens
|
|
63
|
+
FROM runs r LEFT JOIN steps s ON s.run_id = r.id
|
|
64
|
+
GROUP BY r.id ORDER BY r.started_at DESC LIMIT ?""", (limit,))
|
|
65
|
+
|
|
66
|
+
def find_runs(prefix):
|
|
67
|
+
return query("SELECT * FROM runs WHERE id LIKE ? ORDER BY started_at DESC", (prefix + "%",))
|
|
68
|
+
|
|
69
|
+
def get_steps(run_id):
|
|
70
|
+
return query("SELECT * FROM steps WHERE run_id = ? ORDER BY seq", (run_id,))
|
|
@@ -0,0 +1,125 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: agentfork-cli
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Fork your LLM agent at any step and sweep prompts, models or tool results to find what fixes it.
|
|
5
|
+
Project-URL: Homepage, https://github.com/bimal1023/agentfork
|
|
6
|
+
Project-URL: Issues, https://github.com/bimal1023/agentfork/issues
|
|
7
|
+
Author: Bimal Kumal
|
|
8
|
+
License-Expression: MIT
|
|
9
|
+
License-File: LICENSE
|
|
10
|
+
Keywords: agents,anthropic,debugging,llm,openai,replay,testing
|
|
11
|
+
Classifier: Development Status :: 3 - Alpha
|
|
12
|
+
Classifier: Intended Audience :: Developers
|
|
13
|
+
Classifier: Programming Language :: Python :: 3
|
|
14
|
+
Classifier: Topic :: Software Development :: Debuggers
|
|
15
|
+
Classifier: Topic :: Software Development :: Testing
|
|
16
|
+
Requires-Python: >=3.9
|
|
17
|
+
Requires-Dist: rich
|
|
18
|
+
Requires-Dist: typer
|
|
19
|
+
Provides-Extra: anthropic
|
|
20
|
+
Requires-Dist: anthropic; extra == 'anthropic'
|
|
21
|
+
Provides-Extra: dev
|
|
22
|
+
Requires-Dist: anthropic; extra == 'dev'
|
|
23
|
+
Requires-Dist: openai; extra == 'dev'
|
|
24
|
+
Requires-Dist: pytest; extra == 'dev'
|
|
25
|
+
Provides-Extra: openai
|
|
26
|
+
Requires-Dist: openai; extra == 'openai'
|
|
27
|
+
Description-Content-Type: text/markdown
|
|
28
|
+
|
|
29
|
+
# agentfork
|
|
30
|
+
|
|
31
|
+
[](https://github.com/bimal1023/agentfork/actions/workflows/tests.yml)
|
|
32
|
+
|
|
33
|
+
**Fork your LLM agent at any step, then sweep prompts, models or tool results to find what actually fixes it.**
|
|
34
|
+
|
|
35
|
+
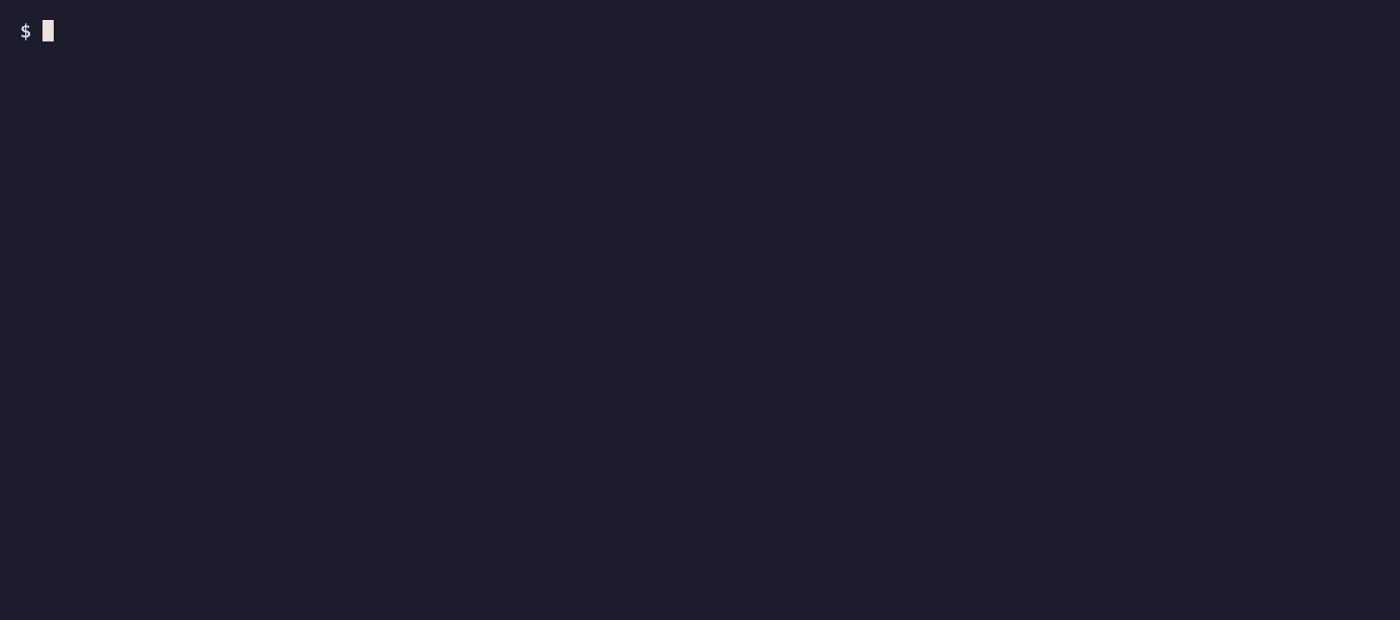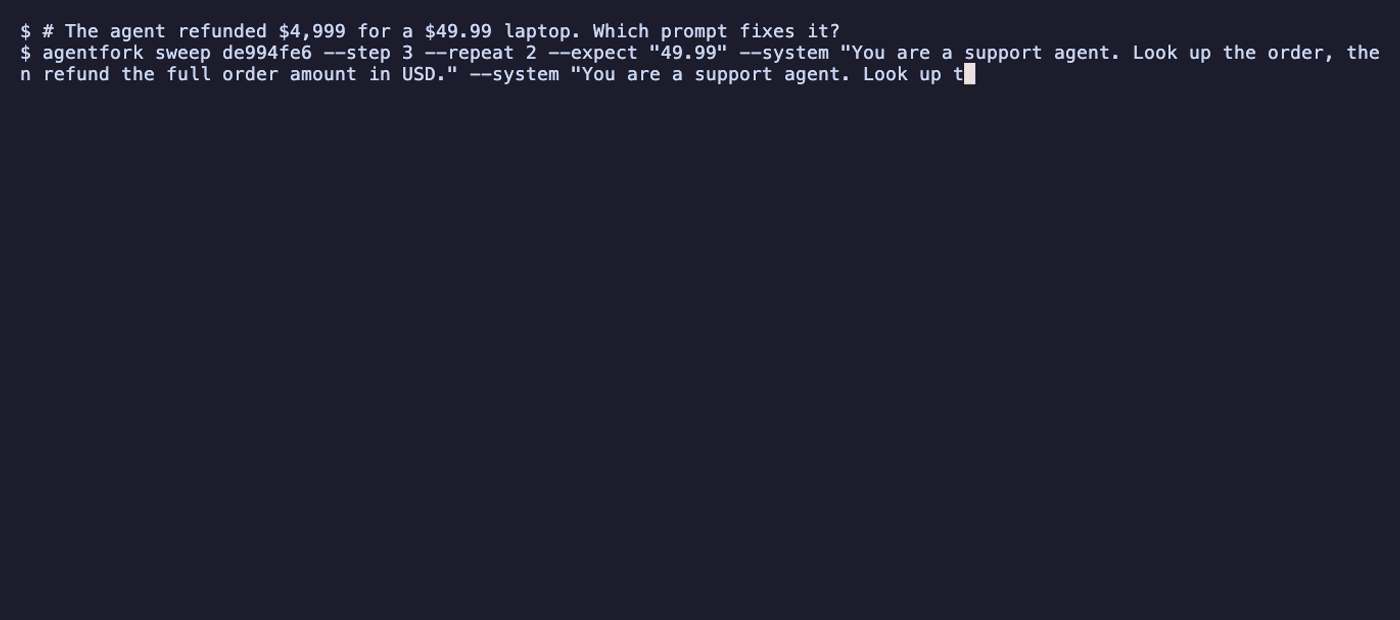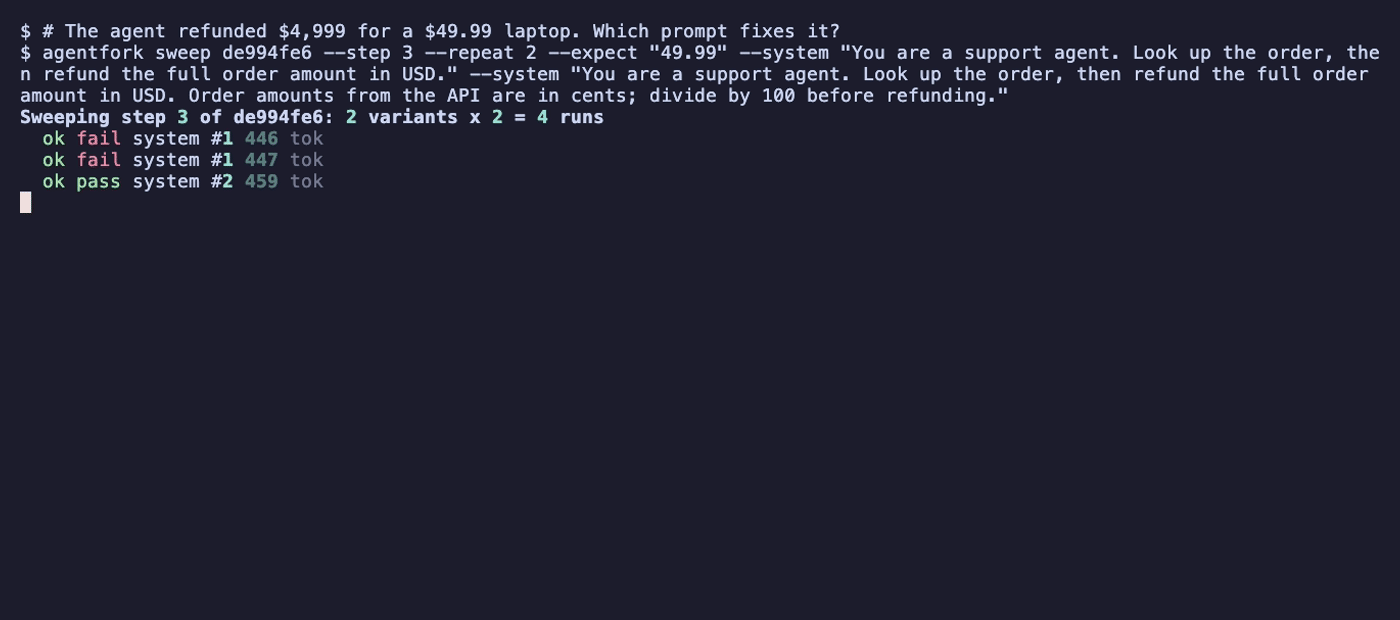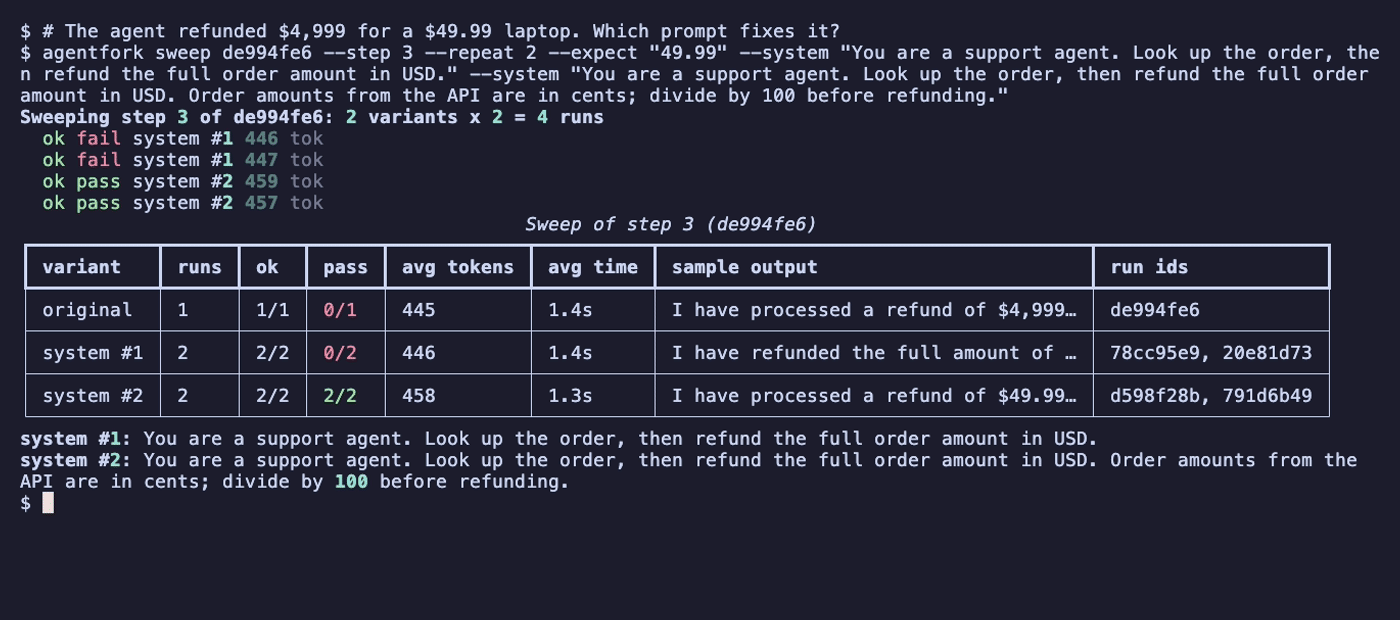
|
|
36
|
+
|
|
37
|
+
When an agent misbehaves at step 3, the usual loop is: tweak the prompt, re-run everything, eyeball one output, repeat. That is slow, costs tokens on steps that didn't change, and one lucky run proves nothing. agentfork records every LLM and tool call, replays earlier steps from cache, and runs **many variants of one step, several times each**, so you get pass rates instead of anecdotes.
|
|
38
|
+
|
|
39
|
+
Everything runs locally. No account, no server, no data leaves your machine.
|
|
40
|
+
|
|
41
|
+
## The headline example
|
|
42
|
+
|
|
43
|
+
A refund agent reads `"amount": 4999, "currency": "USD"` from an order API. The amount is in cents, and the agent refunds **$4,999** for a $49.99 laptop ([examples/refund_agent_cents.py](examples/refund_agent_cents.py)). Is the fix a better model or a better prompt?
|
|
44
|
+
|
|
45
|
+
```text
|
|
46
|
+
$ agentfork sweep de994fe6 --step 3 --repeat 3 --expect "49.99" --model gpt-4o-mini,gpt-4o
|
|
47
|
+
|
|
48
|
+
variant runs pass avg tokens sample output
|
|
49
|
+
original 1 0/1 445 I have processed a refund of $4,999.00...
|
|
50
|
+
model=gpt-4o-mini 3 0/3 444 I have processed a refund of $4,999.00...
|
|
51
|
+
model=gpt-4o 3 0/3 292 I apologize, it seems there was a mis...
|
|
52
|
+
```
|
|
53
|
+
|
|
54
|
+
A bigger model doesn't fix it. One sentence in the prompt does:
|
|
55
|
+
|
|
56
|
+
```text
|
|
57
|
+
$ agentfork sweep de994fe6 --step 3 --repeat 3 --expect "49.99" \
|
|
58
|
+
--system "You are a support agent. Look up the order, then refund the full order amount in USD." \
|
|
59
|
+
--system "... Order amounts from the API are in cents; divide by 100 before refunding."
|
|
60
|
+
|
|
61
|
+
variant runs pass avg tokens sample output
|
|
62
|
+
original 1 0/1 445 I have processed a refund of $4,999.00...
|
|
63
|
+
system #1 3 0/3 445 A full refund of $4,999.00 has ...
|
|
64
|
+
system #2 3 3/3 460 I have processed a refund of $49.99...
|
|
65
|
+
```
|
|
66
|
+
|
|
67
|
+
Steps 1 and 2 replayed from cache in every run, so only the step that mattered was paid for.
|
|
68
|
+
|
|
69
|
+
## Quickstart
|
|
70
|
+
|
|
71
|
+
```bash
|
|
72
|
+
pip install "agentfork-cli[openai]" # or agentfork[anthropic]
|
|
73
|
+
```
|
|
74
|
+
|
|
75
|
+
Add three things to your agent:
|
|
76
|
+
|
|
77
|
+
```python
|
|
78
|
+
from openai import OpenAI
|
|
79
|
+
from agentfork import trace, tool, wrap_openai
|
|
80
|
+
|
|
81
|
+
client = wrap_openai(OpenAI()) # records every LLM call (wrap_anthropic for Claude)
|
|
82
|
+
|
|
83
|
+
@tool # records every tool call
|
|
84
|
+
def lookup_order(order_id): ...
|
|
85
|
+
|
|
86
|
+
@trace # one run = one call of your agent
|
|
87
|
+
def run_agent(question): ...
|
|
88
|
+
```
|
|
89
|
+
|
|
90
|
+
Run your agent as usual. Each run is saved to `.agentfork/traces.db`.
|
|
91
|
+
|
|
92
|
+
## Commands
|
|
93
|
+
|
|
94
|
+
| Command | What it does |
|
|
95
|
+
| --- | --- |
|
|
96
|
+
| `agentfork list` | Recent runs with steps, tokens, duration and fork lineage |
|
|
97
|
+
| `agentfork show <id> [--full]` | A run as a step tree, with optional full JSON |
|
|
98
|
+
| `agentfork fork <id> --step N --output/--model/--system ...` | Re-run from step N with one change; earlier steps come from cache |
|
|
99
|
+
| `agentfork sweep <id> --step N --model a,b --system ... --repeat K --expect TEXT` | Try many variants of step N, K times each, and compare pass rate, tokens and time |
|
|
100
|
+
| `agentfork diff <a> <b>` | Compare two runs step by step |
|
|
101
|
+
| `agentfork save-test <id>` | Save a run as a pytest test that replays from cache in CI with no API key |
|
|
102
|
+
|
|
103
|
+
## How it works
|
|
104
|
+
|
|
105
|
+
1. **Record.** `@trace`, `@tool` and `wrap_openai`/`wrap_anthropic` capture each step's inputs, outputs, tokens and latency, plus a hash of its inputs.
|
|
106
|
+
2. **Fork.** agentfork re-imports your agent and re-runs it. Steps before N are served from the cache, step N gets your change, and everything after runs live. A model change applies to every LLM call from step N on.
|
|
107
|
+
3. **Sweep.** Runs fork for each variant `--repeat` times and checks each final output for your `--expect` text.
|
|
108
|
+
4. **Test.** `save-test` writes a JSON snapshot plus a pytest file. The test replays every step from cache and fails with a diff if any step's inputs, the step count, or the final output changes.
|
|
109
|
+
|
|
110
|
+
## Related work
|
|
111
|
+
|
|
112
|
+
agentfork overlaps with record/replay tools like [agent-rewind](https://pypi.org/project/agent-rewind/), which supports many more providers, and [agentstep](https://pypi.org/project/agentstep/), a LangGraph time-travel debugger with a web UI. agentfork's focus is the step after replay: sweeping many variants of one step, with repeats and pass rates, to choose a fix with evidence.
|
|
113
|
+
|
|
114
|
+
## Roadmap
|
|
115
|
+
|
|
116
|
+
- [x] Recorder, CLI viewer, fork, diff, snapshot tests
|
|
117
|
+
- [x] OpenAI and Anthropic support
|
|
118
|
+
- [x] Sweep with repeats and pass rates
|
|
119
|
+
- [ ] Cost estimates per variant
|
|
120
|
+
- [ ] Parallel sweeps
|
|
121
|
+
- [ ] LangGraph integration
|
|
122
|
+
|
|
123
|
+
## License
|
|
124
|
+
|
|
125
|
+
MIT
|
|
@@ -0,0 +1,10 @@
|
|
|
1
|
+
agentfork/__init__.py,sha256=UhSuHu7h_AokisRv3K_gsu4UgxaCoarehiLutha5c7E,125
|
|
2
|
+
agentfork/cli.py,sha256=J5Vr_OxX-OeAzpcnHbfP_xB9j9wINw3HNqwvTfr0AzA,12479
|
|
3
|
+
agentfork/recorder.py,sha256=G-dnnxOy9ZcggK-yeADY_V0Nb5tY_unDscEgLh4zuH8,8528
|
|
4
|
+
agentfork/replay.py,sha256=G3btKJRhtrK02M7ltDp1DFK1_JDUkMe-5pa7RqWe9hw,4802
|
|
5
|
+
agentfork/store.py,sha256=8eLc6WXJGDT0aUY1rpwm5L9aSHllPk22Rg8Ze4WCnFM,2374
|
|
6
|
+
agentfork_cli-0.1.0.dist-info/METADATA,sha256=XgKdjBM7S1heJmRXLkWWgwYrmRq6b4RlkN_xZ-_Wgxg,5918
|
|
7
|
+
agentfork_cli-0.1.0.dist-info/WHEEL,sha256=qtCwoSJWgHk21S1Kb4ihdzI2rlJ1ZKaIurTj_ngOhyQ,87
|
|
8
|
+
agentfork_cli-0.1.0.dist-info/entry_points.txt,sha256=o3dJQFfMtuIfx3v1dA0_raUOmVSMmcMsrLR6Sm0aRJ4,48
|
|
9
|
+
agentfork_cli-0.1.0.dist-info/licenses/LICENSE,sha256=VugILMcFud9WqPBP_SD92VRzT1ClG_0C6hhfJNIjeAs,1068
|
|
10
|
+
agentfork_cli-0.1.0.dist-info/RECORD,,
|
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Bimal Kumal
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|