usearch 2.8.9 → 2.8.10
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/CITATION.cff +1 -1
- package/Cargo.toml +1 -1
- package/README.md +54 -30
- package/VERSION +1 -1
- package/conanfile.py +1 -1
- package/include/usearch/index.hpp +1 -1
- package/include/usearch/index_plugins.hpp +1 -0
- package/package.json +1 -1
- package/pyproject.toml +1 -1
- package/setup.py +7 -14
- package/simsimd/README.md +9 -8
- package/simsimd/include/simsimd/binary.h +5 -2
- package/simsimd/include/simsimd/probability.h +5 -2
- package/simsimd/include/simsimd/simsimd.h +5 -1
- package/simsimd/include/simsimd/spatial.h +4 -1
- package/simsimd/include/simsimd/types.h +34 -40
- package/simsimd/package.json +1 -1
- package/wasmer.toml +1 -1
package/CITATION.cff
CHANGED
package/Cargo.toml
CHANGED
package/README.md
CHANGED
|
@@ -50,6 +50,7 @@ Linux • MacOS • Windows • iOS • WebAssembly
|
|
|
50
50
|
- ✅ [20x faster than][faster-than-faiss] [FAISS][faiss] implementation of [HNSW algorithm][hnsw-algorithm].
|
|
51
51
|
- ✅ Simple and extensible [single C++11 header][usearch-header] implementation.
|
|
52
52
|
- ✅ Compatible with a dozen programming languages out of the box.
|
|
53
|
+
- ✅ [Trusted](#integrations) by some of the most loved Datalakes and Databases, like [ClickHouse][clickhouse-docs].
|
|
53
54
|
- ✅ [SIMD][simd]-optimized and [user-defined metrics](#user-defined-functions) with JIT compilation.
|
|
54
55
|
- ✅ Hardware-agnostic `f16` & `i8` - [half-precision & quarter-precision support](#memory-efficiency-downcasting-and-quantization).
|
|
55
56
|
- ✅ [View large indexes from disk](#serving-index-from-disk) without loading into RAM.
|
|
@@ -67,6 +68,17 @@ Linux • MacOS • Windows • iOS • WebAssembly
|
|
|
67
68
|
[hnsw-algorithm]: https://arxiv.org/abs/1603.09320
|
|
68
69
|
[simd]: https://en.wikipedia.org/wiki/Single_instruction,_multiple_data
|
|
69
70
|
[faster-than-faiss]: https://www.unum.cloud/blog/2023-11-07-scaling-vector-search-with-intel
|
|
71
|
+
[clickhouse-docs]: https://clickhouse.com/docs/en/engines/table-engines/mergetree-family/annindexes#usearch
|
|
72
|
+
|
|
73
|
+
__Technical Insights__ and related articles:
|
|
74
|
+
|
|
75
|
+
- [Uses Horner's method for polynomial approximations, beating GCC 12 by 119x](https://ashvardanian.com/posts/gcc-12-vs-avx512fp16/).
|
|
76
|
+
- [Uses Arm SVE and x86 AVX-512's masked loads to eliminate tail `for`-loops](https://ashvardanian.com/posts/simsimd-faster-scipy/#tails-of-the-past-the-significance-of-masked-loads).
|
|
77
|
+
- [Uses AVX-512 FP16 for half-precision operations, that few compilers vectorize](https://ashvardanian.com/posts/simsimd-faster-scipy/#the-challenge-of-f16).
|
|
78
|
+
- [Substitutes LibC's `sqrt` calls with bithacks using Jan Kadlec's constant](https://ashvardanian.com/posts/simsimd-faster-scipy/#bonus-section-bypassing-sqrt-and-libc-dependencies).
|
|
79
|
+
- [For every language implements a custom separate binding](https://ashvardanian.com/posts/porting-cpp-library-to-ten-languages/).
|
|
80
|
+
- [For Python avoids slow PyBind11, and even `PyArg_ParseTuple` for speed](https://ashvardanian.com/posts/pybind11-cpython-tutorial/).
|
|
81
|
+
- [For JavaScript uses typed arrays and NAPI for zero-copy calls](https://ashvardanian.com/posts/javascript-ai-vector-search/).
|
|
70
82
|
|
|
71
83
|
## Comparison with FAISS
|
|
72
84
|
|
|
@@ -132,34 +144,6 @@ index = Index(
|
|
|
132
144
|
)
|
|
133
145
|
```
|
|
134
146
|
|
|
135
|
-
## User-Defined Functions
|
|
136
|
-
|
|
137
|
-
While most vector search packages concentrate on just a few metrics - "Inner Product distance" and "Euclidean distance," USearch extends this list to include any user-defined metrics.
|
|
138
|
-
This flexibility allows you to customize your search for various applications, from computing geospatial coordinates with the rare [Haversine][haversine] distance to creating custom metrics for composite embeddings from multiple AI models.
|
|
139
|
-
|
|
140
|
-
|
|
141
|
-
|
|
142
|
-
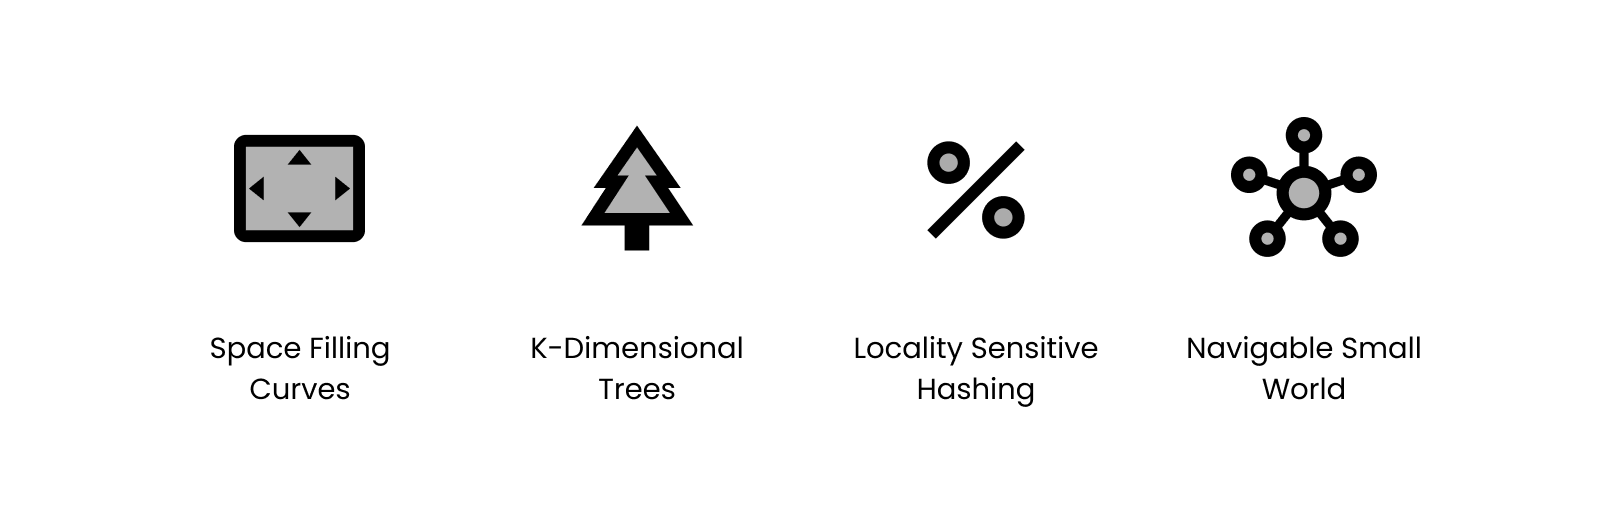
Unlike older approaches indexing high-dimensional spaces, like KD-Trees and Locality Sensitive Hashing, HNSW doesn't require vectors to be identical in length.
|
|
143
|
-
They only have to be comparable.
|
|
144
|
-
So you can apply it in [obscure][obscure] applications, like searching for similar sets or fuzzy text matching, using [GZip][gzip-similarity] as a distance function.
|
|
145
|
-
|
|
146
|
-
> Read more about [JIT and UDF in USearch Python SDK](https://unum-cloud.github.io/usearch/python#user-defined-metrics-and-jit-in-python).
|
|
147
|
-
|
|
148
|
-
[haversine]: https://ashvardanian.com/posts/abusing-vector-search#geo-spatial-indexing
|
|
149
|
-
[obscure]: https://ashvardanian.com/posts/abusing-vector-search
|
|
150
|
-
[gzip-similarity]: https://twitter.com/LukeGessler/status/1679211291292889100?s=20
|
|
151
|
-
|
|
152
|
-
## Memory Efficiency, Downcasting, and Quantization
|
|
153
|
-
|
|
154
|
-
Training a quantization model and dimension-reduction is a common approach to accelerate vector search.
|
|
155
|
-
Those, however, are only sometimes reliable, can significantly affect the statistical properties of your data, and require regular adjustments if your distribution shifts.
|
|
156
|
-
|
|
157
|
-
|
|
158
|
-
|
|
159
|
-
Instead, we have focused on high-precision arithmetic over low-precision downcasted vectors.
|
|
160
|
-
The same index, and `add` and `search` operations will automatically down-cast or up-cast between `f32_t`, `f16_t`, `f64_t`, and `i8_t` representations, even if the hardware doesn't natively support it.
|
|
161
|
-
Continuing the topic of memory efficiency, we provide a `uint40_t` to allow collection with over 4B+ vectors without allocating 8 bytes for every neighbor reference in the proximity graph.
|
|
162
|
-
|
|
163
147
|
## Serialization & Serving `Index` from Disk
|
|
164
148
|
|
|
165
149
|
USearch supports multiple forms of serialization:
|
|
@@ -275,16 +259,56 @@ pairs: dict = men.join(women, max_proposals=0, exact=False)
|
|
|
275
259
|
|
|
276
260
|
> Read more in the post: [Combinatorial Stable Marriages for Semantic Search 💍](https://ashvardanian.com/posts/searching-stable-marriages)
|
|
277
261
|
|
|
262
|
+
## User-Defined Functions
|
|
263
|
+
|
|
264
|
+
While most vector search packages concentrate on just a few metrics - "Inner Product distance" and "Euclidean distance," USearch extends this list to include any user-defined metrics.
|
|
265
|
+
This flexibility allows you to customize your search for various applications, from computing geospatial coordinates with the rare [Haversine][haversine] distance to creating custom metrics for composite embeddings from multiple AI models.
|
|
266
|
+
|
|
267
|
+

|
|
268
|
+
|
|
269
|
+
Unlike older approaches indexing high-dimensional spaces, like KD-Trees and Locality Sensitive Hashing, HNSW doesn't require vectors to be identical in length.
|
|
270
|
+
They only have to be comparable.
|
|
271
|
+
So you can apply it in [obscure][obscure] applications, like searching for similar sets or fuzzy text matching, using [GZip][gzip-similarity] as a distance function.
|
|
272
|
+
|
|
273
|
+
> Read more about [JIT and UDF in USearch Python SDK](https://unum-cloud.github.io/usearch/python#user-defined-metrics-and-jit-in-python).
|
|
274
|
+
|
|
275
|
+
[haversine]: https://ashvardanian.com/posts/abusing-vector-search#geo-spatial-indexing
|
|
276
|
+
[obscure]: https://ashvardanian.com/posts/abusing-vector-search
|
|
277
|
+
[gzip-similarity]: https://twitter.com/LukeGessler/status/1679211291292889100?s=20
|
|
278
|
+
|
|
279
|
+
## Memory Efficiency, Downcasting, and Quantization
|
|
280
|
+
|
|
281
|
+
Training a quantization model and dimension-reduction is a common approach to accelerate vector search.
|
|
282
|
+
Those, however, are only sometimes reliable, can significantly affect the statistical properties of your data, and require regular adjustments if your distribution shifts.
|
|
283
|
+
Instead, we have focused on high-precision arithmetic over low-precision downcasted vectors.
|
|
284
|
+
The same index, and `add` and `search` operations will automatically down-cast or up-cast between `f64_t`, `f32_t`, `f16_t`, `i8_t`, and single-bit representations.
|
|
285
|
+
You can use the following command to check, if hardware acceleration is enabled:
|
|
286
|
+
|
|
287
|
+
```sh
|
|
288
|
+
$ python -c 'from usearch.index import Index; print(Index(ndim=768, metric="cos", dtype="f16").hardware_acceleration)'
|
|
289
|
+
> avx512+f16
|
|
290
|
+
$ python -c 'from usearch.index import Index; print(Index(ndim=166, metric="tanimoto").hardware_acceleration)'
|
|
291
|
+
> avx512+popcnt
|
|
292
|
+
```
|
|
293
|
+
|
|
294
|
+
Using smaller numeric types will save you RAM needed to store the vectors, but you can also compress the neighbors lists forming our proximity graphs.
|
|
295
|
+
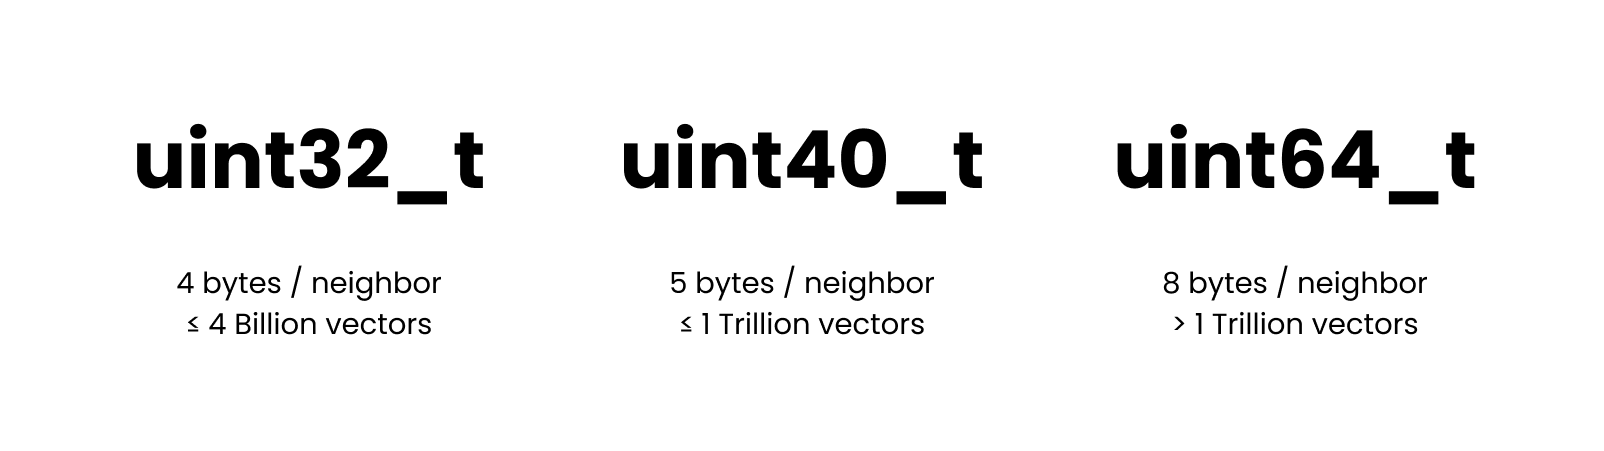
By default, 32-bit `uint32_t` is used to enumerate those, which is not enough if you need to address over 4 Billion entries.
|
|
296
|
+
For such cases we provide a custom `uint40_t` type, that will still be 37.5% more space-efficient than the commonly used 8-byte integers, and will scale up to 1 Trillion entries.
|
|
297
|
+
|
|
298
|
+

|
|
299
|
+
|
|
278
300
|
## Functionality
|
|
279
301
|
|
|
280
302
|
By now, the core functionality is supported across all bindings.
|
|
281
303
|
Broader functionality is ported per request.
|
|
304
|
+
In some cases, like Batch operations, feature parity is meaningless, as the host language has full multi-threading capabilities and the USearch index structure is concurrent by design, so the users can implement batching/scheduling/load-balancing in the most optimal way for their applications.
|
|
282
305
|
|
|
283
306
|
| | C++ 11 | Python 3 | C 99 | Java | JavaScript | Rust | GoLang | Swift |
|
|
284
307
|
| :---------------------- | :----: | :------: | :---: | :---: | :--------: | :---: | :----: | :---: |
|
|
285
|
-
| Add, search
|
|
308
|
+
| Add, search, remove | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
|
|
286
309
|
| Save, load, view | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
|
|
287
310
|
| User-defined metrics | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
|
|
311
|
+
| Batch operations | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | ❌ |
|
|
288
312
|
| Joins | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
|
|
289
313
|
| Variable-length vectors | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
|
|
290
314
|
| 4B+ capacities | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
|
|
@@ -400,7 +424,7 @@ doi = {10.5281/zenodo.7949416},
|
|
|
400
424
|
author = {Vardanian, Ash},
|
|
401
425
|
title = {{USearch by Unum Cloud}},
|
|
402
426
|
url = {https://github.com/unum-cloud/usearch},
|
|
403
|
-
version = {2.8.
|
|
427
|
+
version = {2.8.10},
|
|
404
428
|
year = {2023},
|
|
405
429
|
month = oct,
|
|
406
430
|
}
|
package/VERSION
CHANGED
|
@@ -1 +1 @@
|
|
|
1
|
-
2.8.
|
|
1
|
+
2.8.10
|
package/conanfile.py
CHANGED
|
@@ -7,7 +7,7 @@ required_conan_version = ">=1.53.0"
|
|
|
7
7
|
class USearchConan(ConanFile):
|
|
8
8
|
|
|
9
9
|
name = "usearch"
|
|
10
|
-
version = '2.8.
|
|
10
|
+
version = '2.8.10'
|
|
11
11
|
license = "Apache-2.0"
|
|
12
12
|
description = "Smaller & Faster Single-File Vector Search Engine from Unum"
|
|
13
13
|
homepage = "https://github.com/unum-cloud/usearch"
|
|
@@ -1402,6 +1402,7 @@ class metric_punned_t {
|
|
|
1402
1402
|
case metric_kind_t::cos_k: kind = simsimd_metric_cos_k; break;
|
|
1403
1403
|
case metric_kind_t::l2sq_k: kind = simsimd_metric_l2sq_k; break;
|
|
1404
1404
|
case metric_kind_t::hamming_k: kind = simsimd_metric_hamming_k; break;
|
|
1405
|
+
case metric_kind_t::tanimoto_k: kind = simsimd_metric_jaccard_k; break;
|
|
1405
1406
|
case metric_kind_t::jaccard_k: kind = simsimd_metric_jaccard_k; break;
|
|
1406
1407
|
default: break;
|
|
1407
1408
|
}
|
package/package.json
CHANGED
package/pyproject.toml
CHANGED
|
@@ -9,7 +9,7 @@ xfail_strict = true
|
|
|
9
9
|
filterwarnings = ["error"]
|
|
10
10
|
|
|
11
11
|
# Avoid running tests, as everything is happening in a super slow container
|
|
12
|
-
#
|
|
12
|
+
# We have already run all the relavent Python tests in `prerelease.yml`
|
|
13
13
|
# test-requires = ["pytest", "numpy"]
|
|
14
14
|
# test-command = "pytest {project}/python/scripts"
|
|
15
15
|
[tool.cibuildwheel]
|
package/setup.py
CHANGED
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
import os
|
|
2
2
|
import sys
|
|
3
|
-
import
|
|
3
|
+
import platform
|
|
4
4
|
from setuptools import setup
|
|
5
5
|
|
|
6
6
|
from pybind11.setup_helpers import Pybind11Extension
|
|
@@ -14,28 +14,19 @@ def get_bool_env(name: str, preference: bool) -> bool:
|
|
|
14
14
|
return os.environ.get(name, "1" if preference else "0") == "1"
|
|
15
15
|
|
|
16
16
|
|
|
17
|
-
def get_bool_env_w_name(name: str, preference: bool) ->
|
|
18
|
-
return name, get_bool_env(name, preference)
|
|
19
|
-
|
|
20
|
-
|
|
21
|
-
def get_is_gcc():
|
|
22
|
-
try:
|
|
23
|
-
compiler_version = subprocess.check_output(
|
|
24
|
-
["c++", "--version"], universal_newlines=True
|
|
25
|
-
)
|
|
26
|
-
return "gcc" in compiler_version.lower()
|
|
27
|
-
except Exception:
|
|
28
|
-
return False
|
|
17
|
+
def get_bool_env_w_name(name: str, preference: bool) -> tuple:
|
|
18
|
+
return name, "1" if get_bool_env(name, preference) else "0"
|
|
29
19
|
|
|
30
20
|
|
|
31
21
|
# Check the environment variables
|
|
22
|
+
is_gcc = "GCC" in platform.python_compiler().upper()
|
|
32
23
|
is_linux: bool = sys.platform == "linux"
|
|
33
24
|
is_macos: bool = sys.platform == "darwin"
|
|
34
25
|
is_windows: bool = sys.platform == "win32"
|
|
35
26
|
|
|
36
27
|
prefer_simsimd: bool = is_linux or is_macos
|
|
37
28
|
prefer_fp16lib: bool = True
|
|
38
|
-
prefer_openmp: bool = is_linux and
|
|
29
|
+
prefer_openmp: bool = is_linux and is_gcc
|
|
39
30
|
|
|
40
31
|
use_simsimd: bool = get_bool_env("USEARCH_USE_SIMSIMD", prefer_simsimd)
|
|
41
32
|
use_fp16lib: bool = get_bool_env("USEARCH_USE_FP16LIB", prefer_fp16lib)
|
|
@@ -123,6 +114,8 @@ if is_windows:
|
|
|
123
114
|
]
|
|
124
115
|
)
|
|
125
116
|
|
|
117
|
+
print("macros_args", macros_args)
|
|
118
|
+
|
|
126
119
|
ext_modules = [
|
|
127
120
|
Pybind11Extension(
|
|
128
121
|
"usearch.compiled",
|
package/simsimd/README.md
CHANGED
|
@@ -24,6 +24,15 @@ SimSIMD leverages SIMD intrinsics, capabilities that only select compilers effec
|
|
|
24
24
|
[scipy]: https://docs.scipy.org/doc/scipy/reference/spatial.distance.html#module-scipy.spatial.distance
|
|
25
25
|
[numpy]: https://numpy.org/doc/stable/reference/generated/numpy.inner.html
|
|
26
26
|
|
|
27
|
+
__Technical Insights__ and related articles:
|
|
28
|
+
|
|
29
|
+
- [Uses Horner's method for polynomial approximations, beating GCC 12 by 119x](https://ashvardanian.com/posts/gcc-12-vs-avx512fp16/).
|
|
30
|
+
- [Uses Arm SVE and x86 AVX-512's masked loads to eliminate tail `for`-loops](https://ashvardanian.com/posts/simsimd-faster-scipy/#tails-of-the-past-the-significance-of-masked-loads).
|
|
31
|
+
- [Uses AVX-512 FP16 for half-precision operations, that few compilers vectorize](https://ashvardanian.com/posts/simsimd-faster-scipy/#the-challenge-of-f16).
|
|
32
|
+
- [Substitutes LibC's `sqrt` calls with bithacks using Jan Kadlec's constant](https://ashvardanian.com/posts/simsimd-faster-scipy/#bonus-section-bypassing-sqrt-and-libc-dependencies).
|
|
33
|
+
- [For Python avoids slow PyBind11, SWIG, and even `PyArg_ParseTuple` for speed](https://ashvardanian.com/posts/pybind11-cpython-tutorial/).
|
|
34
|
+
- [For JavaScript uses typed arrays and NAPI for zero-copy calls](https://ashvardanian.com/posts/javascript-ai-vector-search/).
|
|
35
|
+
|
|
27
36
|
## Benchmarks
|
|
28
37
|
|
|
29
38
|
### Apple M2 Pro
|
|
@@ -48,14 +57,6 @@ On the Intel Sapphire Rapids platform, SimSIMD was benchmarked against auto-vect
|
|
|
48
57
|
| Inner Product | 3.81 M/s | _192.02 k/s_ | _5.99 M/s_ | __31 x__ |
|
|
49
58
|
| Jensen Shannon | 1.18 M/s | _18.13 k/s_ | _2.14 M/s_ | __118 x__ |
|
|
50
59
|
|
|
51
|
-
__Technical Insights__:
|
|
52
|
-
|
|
53
|
-
- [Uses Arm SVE and x86 AVX-512's masked loads to eliminate tail `for`-loops](https://ashvardanian.com/posts/simsimd-faster-scipy/#tails-of-the-past-the-significance-of-masked-loads).
|
|
54
|
-
- [Uses AVX-512 FP16 for half-precision operations, that few compilers vectorize](https://ashvardanian.com/posts/simsimd-faster-scipy/#the-challenge-of-f16).
|
|
55
|
-
- [Substitutes LibC's `sqrt` calls with bithacks using Jan Kadlec's constant](https://ashvardanian.com/posts/simsimd-faster-scipy/#bonus-section-bypassing-sqrt-and-libc-dependencies).
|
|
56
|
-
- Avoids slow PyBind11 and SWIG, directly using the CPython C API.
|
|
57
|
-
- Avoids slow `PyArg_ParseTuple` and manually unpacks argument tuples.
|
|
58
|
-
|
|
59
60
|
__Broader Benchmarking Results__:
|
|
60
61
|
|
|
61
62
|
- [Apple M2 Pro](https://ashvardanian.com/posts/simsimd-faster-scipy/#appendix-1-performance-on-apple-m2-pro).
|
|
@@ -17,8 +17,9 @@
|
|
|
17
17
|
* x86 intrinsics: https://www.intel.com/content/www/us/en/docs/intrinsics-guide/
|
|
18
18
|
* Arm intrinsics: https://developer.arm.com/architectures/instruction-sets/intrinsics/
|
|
19
19
|
*/
|
|
20
|
+
#ifndef SIMSIMD_BINARY_H
|
|
21
|
+
#define SIMSIMD_BINARY_H
|
|
20
22
|
|
|
21
|
-
#pragma once
|
|
22
23
|
#include "types.h"
|
|
23
24
|
|
|
24
25
|
#ifdef __cplusplus
|
|
@@ -195,4 +196,6 @@ simsimd_avx512_b8_jaccard_cycle:
|
|
|
195
196
|
|
|
196
197
|
#ifdef __cplusplus
|
|
197
198
|
}
|
|
198
|
-
#endif
|
|
199
|
+
#endif
|
|
200
|
+
|
|
201
|
+
#endif
|
|
@@ -18,8 +18,9 @@
|
|
|
18
18
|
* x86 intrinsics: https://www.intel.com/content/www/us/en/docs/intrinsics-guide/
|
|
19
19
|
* Arm intrinsics: https://developer.arm.com/architectures/instruction-sets/intrinsics/
|
|
20
20
|
*/
|
|
21
|
+
#ifndef SIMSIMD_PROBABILITY_H
|
|
22
|
+
#define SIMSIMD_PROBABILITY_H
|
|
21
23
|
|
|
22
|
-
#pragma once
|
|
23
24
|
#include "types.h"
|
|
24
25
|
|
|
25
26
|
#define SIMSIMD_MAKE_KL(name, input_type, accumulator_type, converter, epsilon) \
|
|
@@ -539,4 +540,6 @@ simsimd_avx512_f16_js_cycle:
|
|
|
539
540
|
|
|
540
541
|
#ifdef __cplusplus
|
|
541
542
|
}
|
|
542
|
-
#endif
|
|
543
|
+
#endif
|
|
544
|
+
|
|
545
|
+
#endif
|
|
@@ -11,7 +11,9 @@
|
|
|
11
11
|
* Detecting target CPU features at compile time: https://stackoverflow.com/a/28939692/2766161
|
|
12
12
|
*/
|
|
13
13
|
|
|
14
|
-
#
|
|
14
|
+
#ifndef SIMSIMD_SIMSIMD_H
|
|
15
|
+
#define SIMSIMD_SIMSIMD_H
|
|
16
|
+
|
|
15
17
|
#include "binary.h" // Hamming, Jaccard
|
|
16
18
|
#include "probability.h" // Kullback-Leibler, Jensen–Shannon
|
|
17
19
|
#include "spatial.h" // L2, Inner Product, Cosine
|
|
@@ -423,3 +425,5 @@ inline static simsimd_metric_punned_t simsimd_metric_punned( //
|
|
|
423
425
|
#ifdef __cplusplus
|
|
424
426
|
}
|
|
425
427
|
#endif
|
|
428
|
+
|
|
429
|
+
#endif
|
|
@@ -20,8 +20,9 @@
|
|
|
20
20
|
* x86 intrinsics: https://www.intel.com/content/www/us/en/docs/intrinsics-guide/
|
|
21
21
|
* Arm intrinsics: https://developer.arm.com/architectures/instruction-sets/intrinsics/
|
|
22
22
|
*/
|
|
23
|
+
#ifndef SIMSIMD_SPATIAL_H
|
|
24
|
+
#define SIMSIMD_SPATIAL_H
|
|
23
25
|
|
|
24
|
-
#pragma once
|
|
25
26
|
#include "types.h"
|
|
26
27
|
|
|
27
28
|
#define SIMSIMD_MAKE_L2SQ(name, input_type, accumulator_type, converter) \
|
|
@@ -1000,4 +1001,6 @@ simsimd_avx512_i8_ip(simsimd_i8_t const* a, simsimd_i8_t const* b, simsimd_size_
|
|
|
1000
1001
|
|
|
1001
1002
|
#ifdef __cplusplus
|
|
1002
1003
|
}
|
|
1004
|
+
#endif
|
|
1005
|
+
|
|
1003
1006
|
#endif
|
|
@@ -1,67 +1,59 @@
|
|
|
1
|
-
#
|
|
1
|
+
#ifndef SIMSIMD_TYPES_H
|
|
2
|
+
#define SIMSIMD_TYPES_H
|
|
2
3
|
|
|
3
4
|
// Compiling for Arm: SIMSIMD_TARGET_ARM
|
|
5
|
+
#if !defined(SIMSIMD_TARGET_ARM)
|
|
4
6
|
#if defined(__aarch64__) || defined(_M_ARM64)
|
|
5
7
|
#define SIMSIMD_TARGET_ARM 1
|
|
8
|
+
#else
|
|
9
|
+
#define SIMSIMD_TARGET_ARM 0
|
|
10
|
+
#endif // defined(__aarch64__) || defined(_M_ARM64)
|
|
11
|
+
#endif // !defined(SIMSIMD_TARGET_ARM)
|
|
12
|
+
|
|
13
|
+
// Compiling for x86: SIMSIMD_TARGET_X86
|
|
14
|
+
#if !defined(SIMSIMD_TARGET_X86)
|
|
15
|
+
#if defined(__x86_64__) || defined(_M_X64)
|
|
16
|
+
#define SIMSIMD_TARGET_X86 1
|
|
17
|
+
#else
|
|
18
|
+
#define SIMSIMD_TARGET_X86 0
|
|
19
|
+
#endif // defined(__x86_64__) || defined(_M_X64)
|
|
20
|
+
#endif // !defined(SIMSIMD_TARGET_X86)
|
|
6
21
|
|
|
7
22
|
// Compiling for Arm: SIMSIMD_TARGET_ARM_NEON
|
|
8
|
-
#if !defined(SIMSIMD_TARGET_ARM_NEON)
|
|
23
|
+
#if !defined(SIMSIMD_TARGET_ARM_NEON) || !SIMSIMD_TARGET_ARM
|
|
9
24
|
#if defined(__ARM_NEON)
|
|
10
|
-
#define SIMSIMD_TARGET_ARM_NEON
|
|
25
|
+
#define SIMSIMD_TARGET_ARM_NEON SIMSIMD_TARGET_ARM
|
|
11
26
|
#else
|
|
12
27
|
#define SIMSIMD_TARGET_ARM_NEON 0
|
|
13
|
-
#endif
|
|
14
|
-
#endif
|
|
28
|
+
#endif // defined(__ARM_NEON)
|
|
29
|
+
#endif // !defined(SIMSIMD_TARGET_ARM_NEON)
|
|
15
30
|
|
|
16
31
|
// Compiling for Arm: SIMSIMD_TARGET_ARM_SVE
|
|
17
|
-
#if !defined(SIMSIMD_TARGET_ARM_SVE)
|
|
32
|
+
#if !defined(SIMSIMD_TARGET_ARM_SVE) || !SIMSIMD_TARGET_ARM
|
|
18
33
|
#if defined(__ARM_FEATURE_SVE)
|
|
19
|
-
#define SIMSIMD_TARGET_ARM_SVE
|
|
34
|
+
#define SIMSIMD_TARGET_ARM_SVE SIMSIMD_TARGET_ARM
|
|
20
35
|
#else
|
|
21
36
|
#define SIMSIMD_TARGET_ARM_SVE 0
|
|
22
|
-
#endif
|
|
23
|
-
#endif
|
|
24
|
-
|
|
25
|
-
#undef SIMSIMD_TARGET_X86
|
|
26
|
-
#undef SIMSIMD_TARGET_X86_AVX2
|
|
27
|
-
#undef SIMSIMD_TARGET_X86_AVX512
|
|
28
|
-
#define SIMSIMD_TARGET_X86 0
|
|
29
|
-
#define SIMSIMD_TARGET_X86_AVX2 0
|
|
30
|
-
#define SIMSIMD_TARGET_X86_AVX512 0
|
|
31
|
-
|
|
32
|
-
// Compiling for x86: SIMSIMD_TARGET_X86
|
|
33
|
-
#elif defined(__x86_64__) || defined(_M_X64)
|
|
34
|
-
#define SIMSIMD_TARGET_X86 1
|
|
37
|
+
#endif // defined(__ARM_FEATURE_SVE)
|
|
38
|
+
#endif // !defined(SIMSIMD_TARGET_ARM_SVE)
|
|
35
39
|
|
|
36
40
|
// Compiling for x86: SIMSIMD_TARGET_X86_AVX2
|
|
37
|
-
#if !defined(SIMSIMD_TARGET_X86_AVX2)
|
|
41
|
+
#if !defined(SIMSIMD_TARGET_X86_AVX2) || !SIMSIMD_TARGET_X86
|
|
38
42
|
#if defined(__AVX2__)
|
|
39
43
|
#define SIMSIMD_TARGET_X86_AVX2 1
|
|
40
44
|
#else
|
|
41
45
|
#define SIMSIMD_TARGET_X86_AVX2 0
|
|
42
|
-
#endif
|
|
43
|
-
#endif
|
|
46
|
+
#endif // defined(__AVX2__)
|
|
47
|
+
#endif // !defined(SIMSIMD_TARGET_X86_AVX2)
|
|
44
48
|
|
|
45
49
|
// Compiling for x86: SIMSIMD_TARGET_X86_AVX512
|
|
46
|
-
#if !defined(SIMSIMD_TARGET_X86_AVX512)
|
|
47
|
-
#if defined(__AVX512F__)
|
|
50
|
+
#if !defined(SIMSIMD_TARGET_X86_AVX512) || !SIMSIMD_TARGET_X86
|
|
51
|
+
#if defined(__AVX512F__) && defined(__AVX512FP16__) && defined(__AVX512VNNI__) && defined(__AVX512VPOPCNTDQ__)
|
|
48
52
|
#define SIMSIMD_TARGET_X86_AVX512 1
|
|
49
53
|
#else
|
|
50
54
|
#define SIMSIMD_TARGET_X86_AVX512 0
|
|
51
|
-
#endif
|
|
52
|
-
#endif
|
|
53
|
-
|
|
54
|
-
#undef SIMSIMD_TARGET_ARM
|
|
55
|
-
#undef SIMSIMD_TARGET_ARM_NEON
|
|
56
|
-
#undef SIMSIMD_TARGET_ARM_SVE
|
|
57
|
-
#define SIMSIMD_TARGET_ARM 0
|
|
58
|
-
#define SIMSIMD_TARGET_ARM_NEON 0
|
|
59
|
-
#define SIMSIMD_TARGET_ARM_SVE 0
|
|
60
|
-
|
|
61
|
-
// Compiling for unknown hardware architecture
|
|
62
|
-
#else
|
|
63
|
-
#error Unknown hardware architecture!
|
|
64
|
-
#endif
|
|
55
|
+
#endif // defined(__AVX512F__) && defined(__AVX512FP16__) && defined(__AVX512VNNI__) && defined(__AVX512VPOPCNTDQ__)
|
|
56
|
+
#endif // !defined(SIMSIMD_TARGET_X86_AVX512)
|
|
65
57
|
|
|
66
58
|
#ifdef _MSC_VER
|
|
67
59
|
#include <intrin.h>
|
|
@@ -206,4 +198,6 @@ inline static float simsimd_uncompress_f16(unsigned short x) {
|
|
|
206
198
|
|
|
207
199
|
#ifdef __cplusplus
|
|
208
200
|
} // extern "C"
|
|
209
|
-
#endif
|
|
201
|
+
#endif
|
|
202
|
+
|
|
203
|
+
#endif
|
package/simsimd/package.json
CHANGED