usearch 0.22.3 → 1.1.0
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/.github/workflows/prerelease.yml +3 -3
- package/.releaserc +10 -2
- package/.vscode/launch.json +10 -10
- package/.vscode/settings.json +9 -1
- package/.vscode/tasks.json +4 -4
- package/CMakeLists.txt +6 -1
- package/Cargo.toml +2 -2
- package/README.md +35 -41
- package/build.rs +2 -2
- package/c/CMakeLists.txt +48 -0
- package/c/README.md +34 -0
- package/c/lib.cpp +83 -72
- package/c/test.c +20 -20
- package/c/usearch.h +132 -32
- package/conanfile.py +1 -1
- package/cpp/CMakeLists.txt +3 -1
- package/cpp/README.md +16 -16
- package/cpp/bench.cpp +50 -126
- package/cpp/test.cpp +164 -80
- package/docs/benchmarks.md +26 -5
- package/docs/c/reference.rst +3 -3
- package/docs/compilation.md +31 -49
- package/docs/cpp/index.rst +1 -1
- package/docs/cpp/reference.rst +4 -4
- package/golang/lib.go +275 -141
- package/golang/lib_test.go +105 -0
- package/include/usearch/index.hpp +1681 -1656
- package/include/usearch/index_dense.hpp +1400 -0
- package/include/usearch/index_plugins.hpp +1263 -0
- package/java/README.md +1 -1
- package/java/cloud/unum/usearch/Index.java +10 -10
- package/java/cloud/unum/usearch/cloud_unum_usearch_Index.cpp +34 -37
- package/java/test/IndexTest.java +1 -1
- package/javascript/README.md +6 -6
- package/javascript/lib.cpp +156 -55
- package/javascript/test.js +26 -11
- package/javascript/usearch.d.ts +102 -0
- package/javascript/usearch.js +2 -118
- package/objc/USearchObjective.mm +57 -31
- package/objc/include/USearchObjective.h +32 -22
- package/package.json +5 -3
- package/python/README.md +23 -14
- package/python/lib.cpp +468 -444
- package/python/scripts/bench.ipynb +3 -2
- package/python/scripts/bench.py +4 -4
- package/python/scripts/index_faiss.py +5 -5
- package/python/scripts/join.py +4 -4
- package/python/scripts/test.py +152 -61
- package/python/scripts/test_jit.py +10 -12
- package/python/scripts/test_sparse.py +32 -0
- package/python/usearch/client.py +26 -28
- package/python/usearch/eval.py +73 -23
- package/python/usearch/index.py +520 -228
- package/python/usearch/io.py +57 -25
- package/python/usearch/numba.py +4 -4
- package/python/usearch/server.py +10 -10
- package/rust/lib.cpp +34 -30
- package/rust/lib.hpp +14 -12
- package/rust/lib.rs +8 -7
- package/setup.py +5 -2
- package/simsimd/.github/workflows/prerelease.yml +73 -0
- package/simsimd/.github/workflows/release.yml +110 -0
- package/simsimd/.github/workflows/update_version.sh +3 -0
- package/simsimd/.releaserc +77 -0
- package/simsimd/.vscode/launch.json +27 -1
- package/simsimd/.vscode/settings.json +22 -1
- package/simsimd/.vscode/tasks.json +6 -0
- package/simsimd/CMakeLists.txt +3 -2
- package/simsimd/README.md +82 -46
- package/simsimd/bench.cxx +63 -24
- package/simsimd/include/simsimd/simsimd.h +88 -66
- package/simsimd/include/simsimd/simsimd_chem.h +126 -0
- package/simsimd/package.json +8 -0
- package/simsimd/pyproject.toml +42 -0
- package/simsimd/python/python.c +81 -0
- package/simsimd/python/run.sh +1 -0
- package/simsimd/python/test.c +109 -0
- package/simsimd/python/test.py +23 -0
- package/simsimd/setup.py +44 -0
- package/swift/Index+Sugar.swift +75 -23
- package/swift/README.md +26 -2
- package/swift/Test.swift +19 -7
- package/swift/USearch.swift +2 -2
- package/tsconfig.json +8 -0
- package/wasm/CMakeLists.txt +1 -0
- package/wasmer.toml +1 -1
- package/wolfram/CMakeLists.txt +1 -0
- package/wolfram/lib.cpp +11 -13
- package/golang/usearch.h +0 -9
- package/golang/usearch_par_test.go +0 -40
- package/golang/usearch_test.go +0 -82
- package/include/usearch/index_punned_dense.hpp +0 -1001
- package/include/usearch/index_punned_helpers.hpp +0 -676
|
@@ -17,8 +17,8 @@ permissions:
|
|
|
17
17
|
|
|
18
18
|
jobs:
|
|
19
19
|
|
|
20
|
-
|
|
21
|
-
name: Test
|
|
20
|
+
test_cpp:
|
|
21
|
+
name: Test C++
|
|
22
22
|
runs-on: ubuntu-latest
|
|
23
23
|
steps:
|
|
24
24
|
- uses: actions/checkout@v3
|
|
@@ -163,7 +163,7 @@ jobs:
|
|
|
163
163
|
- name: Build USearch by Emscripten
|
|
164
164
|
run: |
|
|
165
165
|
./emsdk/emsdk activate latest && source ./emsdk/emsdk_env.sh
|
|
166
|
-
emcmake cmake -B ./build -DCMAKE_CXX_FLAGS="${CMAKE_CXX_FLAGS} -s TOTAL_MEMORY=64MB" && emmake make -C ./build
|
|
166
|
+
emcmake cmake -DUSEARCH_BUILD_BENCHMARK=0 -DUSEARCH_BUILD_WASM=1 -B ./build -DCMAKE_CXX_FLAGS="${CMAKE_CXX_FLAGS} -s TOTAL_MEMORY=64MB" && emmake make -C ./build
|
|
167
167
|
- name: Run tests
|
|
168
168
|
run: node ./build/test.js
|
|
169
169
|
|
package/.releaserc
CHANGED
|
@@ -11,6 +11,10 @@
|
|
|
11
11
|
{
|
|
12
12
|
"preset": "eslint",
|
|
13
13
|
"releaseRules": [
|
|
14
|
+
{
|
|
15
|
+
"tag": "Break",
|
|
16
|
+
"release": "major"
|
|
17
|
+
},
|
|
14
18
|
{
|
|
15
19
|
"tag": "Add",
|
|
16
20
|
"release": "minor"
|
|
@@ -35,6 +39,10 @@
|
|
|
35
39
|
{
|
|
36
40
|
"preset": "eslint",
|
|
37
41
|
"releaseRules": [
|
|
42
|
+
{
|
|
43
|
+
"tag": "Break",
|
|
44
|
+
"release": "major"
|
|
45
|
+
},
|
|
38
46
|
{
|
|
39
47
|
"tag": "Add",
|
|
40
48
|
"release": "minor"
|
|
@@ -69,10 +77,10 @@
|
|
|
69
77
|
"conanfile.py",
|
|
70
78
|
"package.json",
|
|
71
79
|
"Cargo.toml",
|
|
72
|
-
"wasmer.toml"
|
|
80
|
+
"wasmer.toml"
|
|
73
81
|
],
|
|
74
82
|
"message": "Build: Released ${nextRelease.version} [skip ci]\n\n${nextRelease.notes}"
|
|
75
83
|
}
|
|
76
84
|
]
|
|
77
85
|
]
|
|
78
|
-
}
|
|
86
|
+
}
|
package/.vscode/launch.json
CHANGED
|
@@ -22,16 +22,16 @@
|
|
|
22
22
|
],
|
|
23
23
|
"stopAtEntry": false,
|
|
24
24
|
"linux": {
|
|
25
|
-
"preLaunchTask": "Linux Build C++
|
|
25
|
+
"preLaunchTask": "Linux Build C++ Debug",
|
|
26
26
|
"MIMode": "gdb"
|
|
27
27
|
},
|
|
28
28
|
"osx": {
|
|
29
|
-
"preLaunchTask": "MacOS Build C++
|
|
29
|
+
"preLaunchTask": "MacOS Build C++ Debug",
|
|
30
30
|
"MIMode": "lldb"
|
|
31
31
|
}
|
|
32
32
|
},
|
|
33
33
|
{
|
|
34
|
-
"name": "Debug C++
|
|
34
|
+
"name": "Debug C++ on Wiki 1M @Cos",
|
|
35
35
|
"type": "cppdbg",
|
|
36
36
|
"request": "launch",
|
|
37
37
|
"program": "${workspaceFolder}/build_debug/bench",
|
|
@@ -53,7 +53,7 @@
|
|
|
53
53
|
],
|
|
54
54
|
"stopAtEntry": false,
|
|
55
55
|
"linux": {
|
|
56
|
-
"preLaunchTask": "Linux Build C++
|
|
56
|
+
"preLaunchTask": "Linux Build C++ Debug",
|
|
57
57
|
"MIMode": "gdb",
|
|
58
58
|
"environment": [
|
|
59
59
|
{
|
|
@@ -63,12 +63,12 @@
|
|
|
63
63
|
]
|
|
64
64
|
},
|
|
65
65
|
"osx": {
|
|
66
|
-
"preLaunchTask": "MacOS Build C++
|
|
66
|
+
"preLaunchTask": "MacOS Build C++ Debug",
|
|
67
67
|
"MIMode": "lldb"
|
|
68
68
|
}
|
|
69
69
|
},
|
|
70
70
|
{
|
|
71
|
-
"name": "Debug C++
|
|
71
|
+
"name": "Debug C++ on Text-to-Image 1B @Cos",
|
|
72
72
|
"type": "cppdbg",
|
|
73
73
|
"request": "launch",
|
|
74
74
|
"program": "${workspaceFolder}/build_debug/bench",
|
|
@@ -90,16 +90,16 @@
|
|
|
90
90
|
],
|
|
91
91
|
"stopAtEntry": false,
|
|
92
92
|
"linux": {
|
|
93
|
-
"preLaunchTask": "Linux Build C++
|
|
93
|
+
"preLaunchTask": "Linux Build C++ Debug",
|
|
94
94
|
"MIMode": "gdb"
|
|
95
95
|
},
|
|
96
96
|
"osx": {
|
|
97
|
-
"preLaunchTask": "MacOS Build C++
|
|
97
|
+
"preLaunchTask": "MacOS Build C++ Debug",
|
|
98
98
|
"MIMode": "lldb"
|
|
99
99
|
}
|
|
100
100
|
},
|
|
101
101
|
{
|
|
102
|
-
"name": "Run C++
|
|
102
|
+
"name": "Run C++ on Text-to-Image 1M @Cos",
|
|
103
103
|
"type": "cppdbg",
|
|
104
104
|
"request": "launch",
|
|
105
105
|
"program": "${workspaceFolder}/build_release/bench",
|
|
@@ -113,7 +113,7 @@
|
|
|
113
113
|
"datasets/t2i_1M/groundtruth.public.100K.ibin",
|
|
114
114
|
],
|
|
115
115
|
"stopAtEntry": false,
|
|
116
|
-
"preLaunchTask": "Linux Build C++
|
|
116
|
+
"preLaunchTask": "Linux Build C++ Release",
|
|
117
117
|
"MIMode": "gdb"
|
|
118
118
|
},
|
|
119
119
|
{
|
package/.vscode/settings.json
CHANGED
|
@@ -153,6 +153,14 @@
|
|
|
153
153
|
"python.testing.pytestArgs": [
|
|
154
154
|
"python"
|
|
155
155
|
],
|
|
156
|
+
"python.analysis.diagnosticSeverityOverrides": {
|
|
157
|
+
"reportMissingImports": "none"
|
|
158
|
+
},
|
|
156
159
|
"python.testing.unittestEnabled": false,
|
|
157
|
-
"python.testing.pytestEnabled": true
|
|
160
|
+
"python.testing.pytestEnabled": true,
|
|
161
|
+
"[go]": {
|
|
162
|
+
"editor.insertSpaces": true,
|
|
163
|
+
"editor.formatOnSave": true,
|
|
164
|
+
"editor.defaultFormatter": "golang.go"
|
|
165
|
+
},
|
|
158
166
|
}
|
package/.vscode/tasks.json
CHANGED
|
@@ -2,7 +2,7 @@
|
|
|
2
2
|
"version": "2.0.0",
|
|
3
3
|
"tasks": [
|
|
4
4
|
{
|
|
5
|
-
"label": "Linux Build C++
|
|
5
|
+
"label": "Linux Build C++ Debug",
|
|
6
6
|
"command": "cmake -DCMAKE_CXX_COMPILER=gcc-12 -DCMAKE_CXX_COMPILER=g++-12 -DCMAKE_BUILD_TYPE=Debug -B ./build_debug && make -C ./build_debug",
|
|
7
7
|
"args": [],
|
|
8
8
|
"type": "shell",
|
|
@@ -11,7 +11,7 @@
|
|
|
11
11
|
]
|
|
12
12
|
},
|
|
13
13
|
{
|
|
14
|
-
"label": "Linux Build C++
|
|
14
|
+
"label": "Linux Build C++ Release",
|
|
15
15
|
"command": "cmake -DCMAKE_CXX_COMPILER=gcc-12 -DCMAKE_CXX_COMPILER=g++-12 -DCMAKE_BUILD_TYPE=RelWithDebInfo -B ./build_release && make -C ./build_release",
|
|
16
16
|
"args": [],
|
|
17
17
|
"type": "shell",
|
|
@@ -20,13 +20,13 @@
|
|
|
20
20
|
]
|
|
21
21
|
},
|
|
22
22
|
{
|
|
23
|
-
"label": "MacOS Build C++
|
|
23
|
+
"label": "MacOS Build C++ Debug",
|
|
24
24
|
"command": "cmake -DCMAKE_C_COMPILER=/opt/homebrew/opt/llvm/bin/clang -DCMAKE_CXX_COMPILER=/opt/homebrew/opt/llvm/bin/clang++ -DCMAKE_BUILD_TYPE=Debug -B ./build_debug && make -C ./build_debug",
|
|
25
25
|
"args": [],
|
|
26
26
|
"type": "shell",
|
|
27
27
|
},
|
|
28
28
|
{
|
|
29
|
-
"label": "MacOS Build C++
|
|
29
|
+
"label": "MacOS Build C++ Release",
|
|
30
30
|
"command": "cmake -DCMAKE_C_COMPILER=/opt/homebrew/opt/llvm/bin/clang -DCMAKE_CXX_COMPILER=/opt/homebrew/opt/llvm/bin/clang++ -DCMAKE_BUILD_TYPE=RelWithDebInfo -B ./build_release && make -C ./build_release",
|
|
31
31
|
"args": [],
|
|
32
32
|
"type": "shell"
|
package/CMakeLists.txt
CHANGED
|
@@ -1,7 +1,7 @@
|
|
|
1
1
|
# This CMake file is heavily inspired by following `usearch` CMake:
|
|
2
2
|
# https://github.com/nlohmann/json/blob/develop/CMakeLists.txt
|
|
3
3
|
cmake_minimum_required(VERSION 3.1)
|
|
4
|
-
project(usearch VERSION 0.6.0 LANGUAGES CXX)
|
|
4
|
+
project(usearch VERSION 0.6.0 LANGUAGES C CXX)
|
|
5
5
|
|
|
6
6
|
# Determine if USearch is built as a subproject (using `add_subdirectory`) or if it is the main project
|
|
7
7
|
set(USEARCH_IS_MAIN_PROJECT OFF)
|
|
@@ -14,6 +14,7 @@ option(USEARCH_INSTALL "Install CMake targets" OFF)
|
|
|
14
14
|
option(USEARCH_BUILD_TEST "Compile a native unit test in C++" ${USEARCH_IS_MAIN_PROJECT})
|
|
15
15
|
option(USEARCH_BUILD_BENCHMARK "Compile a native benchmark in C++" ${USEARCH_IS_MAIN_PROJECT})
|
|
16
16
|
option(USEARCH_BUILD_WOLFRAM "Compile Wolfram Language bindings" OFF)
|
|
17
|
+
option(USEARCH_BUILD_CLIB "Compile a native library for the C 99 interface" OFF)
|
|
17
18
|
|
|
18
19
|
# Includes
|
|
19
20
|
set(CMAKE_MODULE_PATH ${CMAKE_CURRENT_SOURCE_DIR}/cmake ${CMAKE_MODULE_PATH})
|
|
@@ -122,3 +123,7 @@ endif()
|
|
|
122
123
|
if(${USEARCH_BUILD_WASM})
|
|
123
124
|
add_subdirectory(wasm)
|
|
124
125
|
endif()
|
|
126
|
+
|
|
127
|
+
if (${USEARCH_BUILD_CLIB})
|
|
128
|
+
add_subdirectory(c)
|
|
129
|
+
endif()
|
package/Cargo.toml
CHANGED
|
@@ -1,7 +1,7 @@
|
|
|
1
1
|
[package]
|
|
2
2
|
name = "usearch"
|
|
3
|
-
version = "
|
|
4
|
-
authors = ["
|
|
3
|
+
version = "1.1.0"
|
|
4
|
+
authors = ["Ash Vardanian <1983160+ashvardanian@users.noreply.github.com>"]
|
|
5
5
|
description = "Smaller & Faster Single-File Vector Search Engine from Unum"
|
|
6
6
|
edition = "2021"
|
|
7
7
|
license = "Apache-2.0"
|
package/README.md
CHANGED
|
@@ -38,15 +38,14 @@ Linux • MacOS • Windows • Docker • WebAssembly
|
|
|
38
38
|
|
|
39
39
|
- ✅ Benchmark-topping performance.
|
|
40
40
|
- ✅ Simple and extensible [single C++11 header][usearch-header] implementation.
|
|
41
|
-
- ✅ SIMD-optimized and [user-defined metrics](#user-defined-functions) with JIT
|
|
41
|
+
- ✅ SIMD-optimized and [user-defined metrics](#user-defined-functions) with JIT compilation.
|
|
42
42
|
- ✅ Variable dimensionality vectors for unique applications, including search over compressed data.
|
|
43
43
|
- ✅ Bitwise Tanimoto and Sorensen coefficients for [Genomics and Chemistry applications](#usearch--rdkit--molecular-search).
|
|
44
|
-
- ✅ Hardware-
|
|
44
|
+
- ✅ Hardware-agnostic `f16` & `i8` - [half-precision & quarter-precision support](#memory-efficiency-downcasting-and-quantization).
|
|
45
45
|
- ✅ [View large indexes from disk](#disk-based-indexes) without loading into RAM.
|
|
46
46
|
- ✅ Space-efficient point-clouds with `uint40_t`, accommodating 4B+ size.
|
|
47
47
|
- ✅ Compatible with OpenMP and custom "executors", for fine-grained control over CPU utilization.
|
|
48
|
-
- ✅
|
|
49
|
-
- ✅ On-the-fly deletions.
|
|
48
|
+
- ✅ Heterogeneous lookups, renaming/relabeling, and on-the-fly deletions.
|
|
50
49
|
- ✅ [Semantic Search](#usearch--ai--multi-modal-semantic-search) and [Joins](#joins).
|
|
51
50
|
|
|
52
51
|
[usearch-header]: https://github.com/unum-cloud/usearch/blob/main/include/usearch/index.hpp
|
|
@@ -69,7 +68,7 @@ USearch is compact and broadly compatible without sacrificing performance, with
|
|
|
69
68
|
|
|
70
69
|
[sloc]: https://en.wikipedia.org/wiki/Source_lines_of_code
|
|
71
70
|
|
|
72
|
-
Base functionality is identical to FAISS, and the interface must be familiar if you have ever investigated Approximate Nearest
|
|
71
|
+
Base functionality is identical to FAISS, and the interface must be familiar if you have ever investigated Approximate Nearest Neighbors search:
|
|
73
72
|
|
|
74
73
|
```py
|
|
75
74
|
$ pip install usearch numpy
|
|
@@ -80,7 +79,7 @@ from usearch.index import Index
|
|
|
80
79
|
index = Index(
|
|
81
80
|
ndim=3, # Define the number of dimensions in input vectors
|
|
82
81
|
metric='cos', # Choose 'l2sq', 'haversine' or other metric, default = 'ip'
|
|
83
|
-
dtype='f32', # Quantize to 'f16' or '
|
|
82
|
+
dtype='f32', # Quantize to 'f16' or 'i8' if needed, default = 'f32'
|
|
84
83
|
connectivity=16, # Optional: How frequent should the connections in the graph be
|
|
85
84
|
expansion_add=128, # Optional: Control the recall of indexing
|
|
86
85
|
expansion_search=64, # Optional: Control the quality of search
|
|
@@ -88,12 +87,12 @@ index = Index(
|
|
|
88
87
|
|
|
89
88
|
vector = np.array([0.2, 0.6, 0.4])
|
|
90
89
|
index.add(42, vector)
|
|
91
|
-
matches
|
|
90
|
+
matches: Matches = index.search(vector, 10)
|
|
92
91
|
|
|
93
92
|
assert len(index) == 1
|
|
94
|
-
assert
|
|
95
|
-
assert matches[0] == 42
|
|
96
|
-
assert
|
|
93
|
+
assert len(matches) == 1
|
|
94
|
+
assert matches[0].key == 42
|
|
95
|
+
assert matches[0].distance <= 0.001
|
|
97
96
|
assert np.allclose(index[42], vector)
|
|
98
97
|
```
|
|
99
98
|
|
|
@@ -108,7 +107,7 @@ Unlike older approaches indexing high-dimensional spaces, like KD-Trees and Loca
|
|
|
108
107
|
They only have to be comparable.
|
|
109
108
|
So you can apply it in [obscure][obscure] applications, like searching for similar sets or fuzzy text matching, using [GZip][gzip-similarity] as a distance function.
|
|
110
109
|
|
|
111
|
-
> Read more about [JIT and UDF in USearch Python SDK]().
|
|
110
|
+
> Read more about [JIT and UDF in USearch Python SDK](https://unum-cloud.github.io/usearch/python#user-defined-metrics-and-jit-in-python).
|
|
112
111
|
|
|
113
112
|
[haversine]: https://ashvardanian.com/posts/abusing-vector-search#geo-spatial-indexing
|
|
114
113
|
[obscure]: https://ashvardanian.com/posts/abusing-vector-search
|
|
@@ -122,10 +121,10 @@ Those, however, are only sometimes reliable, can significantly affect the statis
|
|
|
122
121
|
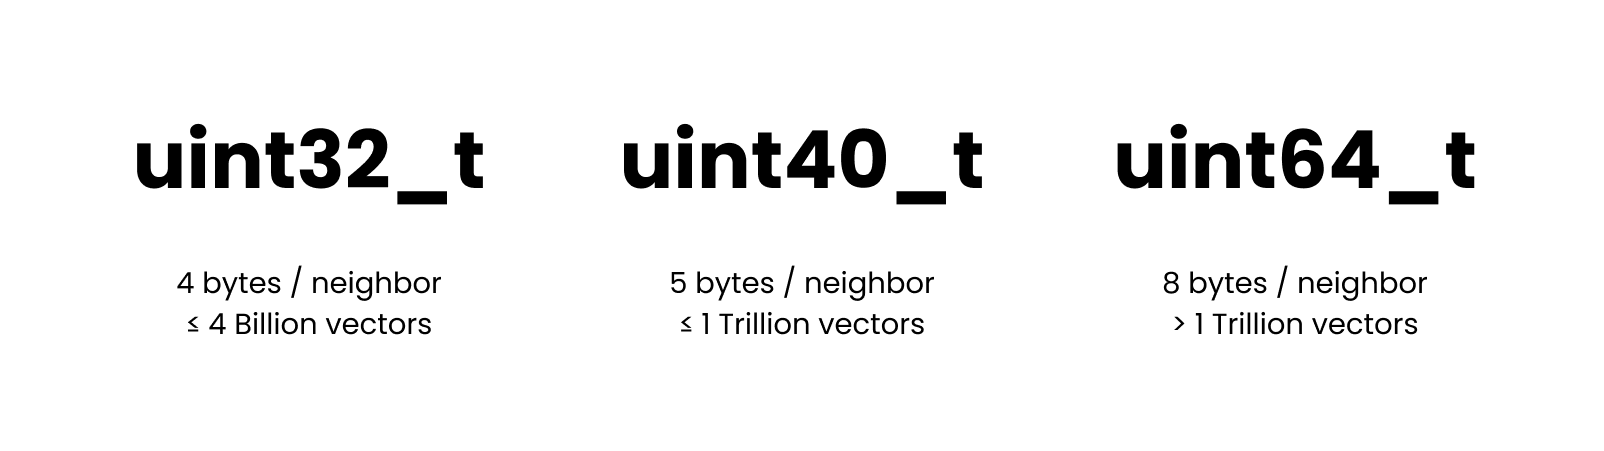
|
|
123
122
|
|
|
124
123
|
Instead, we have focused on high-precision arithmetic over low-precision downcasted vectors.
|
|
125
|
-
The same index, and `add` and `search` operations will automatically down-cast or up-cast between `f32_t`, `f16_t`, `f64_t`, and `
|
|
126
|
-
Continuing the topic of memory
|
|
124
|
+
The same index, and `add` and `search` operations will automatically down-cast or up-cast between `f32_t`, `f16_t`, `f64_t`, and `i8_t` representations, even if the hardware doesn't natively support it.
|
|
125
|
+
Continuing the topic of memory efficiency, we provide a `uint40_t` to allow collection with over 4B+ vectors without allocating 8 bytes for every neighbor reference in the proximity graph.
|
|
127
126
|
|
|
128
|
-
| | FAISS, `f32` | USearch, `f32` | USearch, `f16` | USearch, `
|
|
127
|
+
| | FAISS, `f32` | USearch, `f32` | USearch, `f16` | USearch, `i8` |
|
|
129
128
|
| :----------- | -----------: | -------------: | -------------: | ----------------: |
|
|
130
129
|
| Batch Insert | 16 K/s | 73 K/s | 100 K/s | 104 K/s **+550%** |
|
|
131
130
|
| Batch Search | 82 K/s | 103 K/s | 113 K/s | 134 K/s **+63%** |
|
|
@@ -148,7 +147,7 @@ Continuing the topic of memory-efficiency, we provide a `uint40_t` to allow coll
|
|
|
148
147
|
## Disk-based Indexes
|
|
149
148
|
|
|
150
149
|
With USearch, you can serve indexes from external memory, enabling you to optimize your server choices for indexing speed and serving costs.
|
|
151
|
-
This can result in **20x
|
|
150
|
+
This can result in **20x cost reduction** on AWS and other public clouds.
|
|
152
151
|
|
|
153
152
|
```py
|
|
154
153
|
index.save("index.usearch")
|
|
@@ -162,7 +161,7 @@ other_view.view("index.usearch")
|
|
|
162
161
|
|
|
163
162
|
## Joins
|
|
164
163
|
|
|
165
|
-
One of the big questions these days is how will AI change the world of databases and data
|
|
164
|
+
One of the big questions these days is how will AI change the world of databases and data management.
|
|
166
165
|
Most databases are still struggling to implement high-quality fuzzy search, and the only kind of joins they know are deterministic.
|
|
167
166
|
A `join` is different from searching for every entry, as it requires a one-to-one mapping, banning collisions among separate search results.
|
|
168
167
|
|
|
@@ -171,7 +170,7 @@ A `join` is different from searching for every entry, as it requires a one-to-on
|
|
|
171
170
|
| Exact Join | Fuzzy Join ? | Semantic Join ?? |
|
|
172
171
|
|
|
173
172
|
Using USearch one can implement sub-quadratic complexity approximate, fuzzy, and semantic joins.
|
|
174
|
-
This can come handy in any fuzzy-matching tasks, common to Database Management Software.
|
|
173
|
+
This can come in handy in any fuzzy-matching tasks, common to Database Management Software.
|
|
175
174
|
|
|
176
175
|
```py
|
|
177
176
|
men = Index(...)
|
|
@@ -183,17 +182,17 @@ pairs: dict = men.join(women, max_proposals=0, exact=False)
|
|
|
183
182
|
|
|
184
183
|
## Functionality
|
|
185
184
|
|
|
186
|
-
By now, core functionality is supported across all bindings.
|
|
185
|
+
By now, the core functionality is supported across all bindings.
|
|
187
186
|
Broader functionality is ported per request.
|
|
188
187
|
|
|
189
|
-
| |
|
|
190
|
-
| :---------------------- |
|
|
191
|
-
|
|
|
192
|
-
|
|
|
193
|
-
|
|
|
194
|
-
|
|
|
195
|
-
|
|
|
196
|
-
| 4B+ capacities | ✅
|
|
188
|
+
| | C++ 11 | Python 3 | C 99 | Java | JavaScript | Rust | GoLang | Swift |
|
|
189
|
+
| :---------------------- | :----: | :------: | :---: | :---: | :--------: | :---: | :----: | :---: |
|
|
190
|
+
| Add, search | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
|
|
191
|
+
| Save, load, view | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
|
|
192
|
+
| Join | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
|
|
193
|
+
| User-defined metrics | ✅ | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
|
|
194
|
+
| Variable-length vectors | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
|
|
195
|
+
| 4B+ capacities | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
|
|
197
196
|
|
|
198
197
|
## Application Examples
|
|
199
198
|
|
|
@@ -215,22 +214,22 @@ model = uform.get_model('unum-cloud/uform-vl-multilingual')
|
|
|
215
214
|
index = usearch.index.Index(ndim=256)
|
|
216
215
|
|
|
217
216
|
@server
|
|
218
|
-
def add(
|
|
217
|
+
def add(key: int, photo: pil.Image.Image):
|
|
219
218
|
image = model.preprocess_image(photo)
|
|
220
219
|
vector = model.encode_image(image).detach().numpy()
|
|
221
|
-
index.add(
|
|
220
|
+
index.add(key, vector.flatten(), copy=True)
|
|
222
221
|
|
|
223
222
|
@server
|
|
224
223
|
def search(query: str) -> np.ndarray:
|
|
225
224
|
tokens = model.preprocess_text(query)
|
|
226
225
|
vector = model.encode_text(tokens).detach().numpy()
|
|
227
226
|
matches = index.search(vector.flatten(), 3)
|
|
228
|
-
return matches.
|
|
227
|
+
return matches.keys
|
|
229
228
|
|
|
230
229
|
server.run()
|
|
231
230
|
```
|
|
232
231
|
|
|
233
|
-
We have pre-processed some commonly used datasets,
|
|
232
|
+
We have pre-processed some commonly used datasets, cleaned the images, produced the vectors, and pre-built the index.
|
|
234
233
|
|
|
235
234
|
| Dataset | Modalities | Images | Download |
|
|
236
235
|
| :------------------------------------- | --------------------: | -----: | ------------------------------------: |
|
|
@@ -250,10 +249,10 @@ We have pre-processed some commonly used datasets, cleaning the images, producin
|
|
|
250
249
|
|
|
251
250
|
Comparing molecule graphs and searching for similar structures is expensive and slow.
|
|
252
251
|
It can be seen as a special case of the NP-Complete Subgraph Isomorphism problem.
|
|
253
|
-
Luckily, domain-specific approximate methods
|
|
252
|
+
Luckily, domain-specific approximate methods exist.
|
|
254
253
|
The one commonly used in Chemistry, is to generate structures from [SMILES][smiles], and later hash them into binary fingerprints.
|
|
255
|
-
The
|
|
256
|
-
Below is
|
|
254
|
+
The latter are searchable with bitwise similarity metrics, like the Tanimoto coefficient.
|
|
255
|
+
Below is an example using the RDKit package.
|
|
257
256
|
|
|
258
257
|
```python
|
|
259
258
|
from usearch.index import Index, MetricKind
|
|
@@ -269,27 +268,22 @@ fingerprints = np.vstack([encoder.GetFingerprint(x) for x in molecules])
|
|
|
269
268
|
fingerprints = np.packbits(fingerprints, axis=1)
|
|
270
269
|
|
|
271
270
|
index = Index(ndim=2048, metric=MetricKind.Tanimoto)
|
|
272
|
-
|
|
271
|
+
keys = np.arange(len(molecules))
|
|
273
272
|
|
|
274
|
-
index.add(
|
|
273
|
+
index.add(keys, fingerprints)
|
|
275
274
|
matches = index.search(fingerprints, 10)
|
|
276
275
|
```
|
|
277
276
|
|
|
278
277
|
[smiles]: https://en.wikipedia.org/wiki/Simplified_molecular-input_line-entry_system
|
|
279
278
|
[rdkit-fingerprints]: https://www.rdkit.org/docs/RDKit_Book.html#additional-information-about-the-fingerprints
|
|
280
279
|
|
|
281
|
-
## TODO
|
|
282
|
-
|
|
283
|
-
- JavaScript: Allow calling from "worker threads".
|
|
284
|
-
- Rust: Allow passing a custom thread ID.
|
|
285
|
-
- C# .NET bindings.
|
|
286
280
|
|
|
287
281
|
## Integrations
|
|
288
282
|
|
|
289
283
|
- [x] GPT-Cache.
|
|
290
284
|
- [ ] LangChain.
|
|
291
285
|
- [ ] Microsoft Semantic Kernel.
|
|
292
|
-
- [ ]
|
|
286
|
+
- [ ] ClickHouse.
|
|
293
287
|
|
|
294
288
|
## Citations
|
|
295
289
|
|
package/build.rs
CHANGED
|
@@ -13,7 +13,7 @@ fn main() {
|
|
|
13
13
|
println!("cargo:rerun-if-changed=rust/lib.rs");
|
|
14
14
|
println!("cargo:rerun-if-changed=rust/lib.cpp");
|
|
15
15
|
println!("cargo:rerun-if-changed=rust/lib.hpp");
|
|
16
|
-
println!("cargo:rerun-if-changed=include/
|
|
17
|
-
println!("cargo:rerun-if-changed=include/
|
|
16
|
+
println!("cargo:rerun-if-changed=include/index_plugins.hpp");
|
|
17
|
+
println!("cargo:rerun-if-changed=include/index_dense.hpp");
|
|
18
18
|
println!("cargo:rerun-if-changed=include/usearch/index.hpp");
|
|
19
19
|
}
|
package/c/CMakeLists.txt
ADDED
|
@@ -0,0 +1,48 @@
|
|
|
1
|
+
|
|
2
|
+
|
|
3
|
+
set(USEARCH_PUNNED_INCLUDE_DIRS
|
|
4
|
+
"${CMAKE_CURRENT_SOURCE_DIR}/../include"
|
|
5
|
+
"${CMAKE_CURRENT_SOURCE_DIR}/../fp16/include"
|
|
6
|
+
"${CMAKE_CURRENT_SOURCE_DIR}/../robin-map/include"
|
|
7
|
+
"${CMAKE_CURRENT_SOURCE_DIR}/../simsimd/include"
|
|
8
|
+
"${CMAKE_CURRENT_SOURCE_DIR}/"
|
|
9
|
+
)
|
|
10
|
+
|
|
11
|
+
# This article discusses a better way to allow building either static or shared libraries
|
|
12
|
+
# https://alexreinking.com/blog/building-a-dual-shared-and-static-library-with-cmake.html
|
|
13
|
+
if (${USEARCH_BUILD_STATIC})
|
|
14
|
+
set(CMAKE_CXX_FLAGS " ${CMAKE_CXX_FLAGS} -static-libstdc++")
|
|
15
|
+
add_library(usearch_c STATIC lib.cpp)
|
|
16
|
+
else ()
|
|
17
|
+
add_library(usearch_c SHARED lib.cpp)
|
|
18
|
+
endif()
|
|
19
|
+
|
|
20
|
+
set_target_properties(usearch_c PROPERTIES POSITION_INDEPENDENT_CODE ON)
|
|
21
|
+
set_target_properties(usearch_c PROPERTIES CXX_STANDARD 11)
|
|
22
|
+
|
|
23
|
+
target_include_directories(usearch_c PRIVATE ${USEARCH_PUNNED_INCLUDE_DIRS})
|
|
24
|
+
set_target_properties(usearch_c PROPERTIES RUNTIME_OUTPUT_DIRECTORY ${CMAKE_BINARY_DIR})
|
|
25
|
+
set_target_properties(usearch_c PROPERTIES ARCHIVE_OUTPUT_DIRECTORY ${CMAKE_BINARY_DIR})
|
|
26
|
+
set_target_properties(usearch_c PROPERTIES LIBRARY_OUTPUT_DIRECTORY ${CMAKE_BINARY_DIR})
|
|
27
|
+
|
|
28
|
+
|
|
29
|
+
target_include_directories(usearch_c PRIVATE ${USEARCH_PUNNED_INCLUDE_DIRS})
|
|
30
|
+
|
|
31
|
+
if(${USEARCH_DEBUG_BUILD_ASAN})
|
|
32
|
+
# For ASAN in debug builds
|
|
33
|
+
target_link_libraries(usearch_c PRIVATE gcov)
|
|
34
|
+
endif()
|
|
35
|
+
|
|
36
|
+
if(${USEARCH_USE_SIMSIMD})
|
|
37
|
+
target_compile_definitions(usearch_c PRIVATE USEARCH_USE_SIMSIMD=1)
|
|
38
|
+
endif()
|
|
39
|
+
if (${USEARCH_LOOKUP_LABEL})
|
|
40
|
+
target_compile_definitions(usearch_c PRIVATE USEARCH_LOOKUP_LABEL=1)
|
|
41
|
+
endif()
|
|
42
|
+
|
|
43
|
+
if(${USEARCH_BUILD_TEST})
|
|
44
|
+
add_executable(test_c test.c external_retreival_testutils.c)
|
|
45
|
+
target_link_libraries(test_c usearch_c)
|
|
46
|
+
set_target_properties(test_c PROPERTIES RUNTIME_OUTPUT_DIRECTORY ${CMAKE_BINARY_DIR})
|
|
47
|
+
|
|
48
|
+
endif()
|
package/c/README.md
ADDED
|
@@ -0,0 +1,34 @@
|
|
|
1
|
+
# USearch for C
|
|
2
|
+
|
|
3
|
+
## Installation
|
|
4
|
+
|
|
5
|
+
The simplest form to integrate is to copy the contents of `usearch/c/` into your project.
|
|
6
|
+
To build the library `libusearch_c`, pass enable the `USEARCH_BUILD_CLIB` CMake option:
|
|
7
|
+
|
|
8
|
+
```bash
|
|
9
|
+
cmake -DUSEARCH_BUILD_CLIB=1 -DUSEARCH_BUILD_STATIC=0 -DUSEARCH_BUILD_TEST=0 -DUSEARCH_BUILD_BENCHMARK=0 ..
|
|
10
|
+
```
|
|
11
|
+
|
|
12
|
+
You can choose between a static and dynamic library by setting `USEARCH_BUILD_STATIC`.
|
|
13
|
+
|
|
14
|
+
## Quickstart
|
|
15
|
+
|
|
16
|
+
```c
|
|
17
|
+
usearch_error_t error = NULL;
|
|
18
|
+
usearch_init_options_t opts = create_options(dimensions);
|
|
19
|
+
usearch_index_t index = usearch_init(&opts, &error);
|
|
20
|
+
usearch_reserve(index, vectors_count, &error);
|
|
21
|
+
|
|
22
|
+
float vector[dimensions] = {...};
|
|
23
|
+
usearch_add(index, 42, &vector[0], usearch_scalar_f32_k, &error);
|
|
24
|
+
|
|
25
|
+
ASSERT(!error, error);
|
|
26
|
+
ASSERT(usearch_size(index, &error) == vectors_count, error);
|
|
27
|
+
ASSERT(usearch_capacity(index, &error) == vectors_count, error);
|
|
28
|
+
|
|
29
|
+
usearch_key_t found_keys[10];
|
|
30
|
+
float found_distances[10];
|
|
31
|
+
size_t found_count = usearch_search(index, &vector[0], usearch_scalar_f32_k, 10, &found_keys[0], &found_distances[0], &error);
|
|
32
|
+
|
|
33
|
+
usearch_free(index, &error);
|
|
34
|
+
```
|