usearch 0.21.0 → 0.22.1
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/.github/workflows/prerelease.yml +19 -0
- package/.github/workflows/release.yml +32 -1
- package/.github/workflows/update_version.sh +2 -1
- package/CMakeLists.txt +4 -0
- package/Cargo.toml +1 -1
- package/README.md +117 -626
- package/c/lib.cpp +19 -15
- package/c/usearch.h +26 -23
- package/cmake/emscripten.cmake +8 -0
- package/conanfile.py +1 -1
- package/cpp/README.md +88 -0
- package/cpp/bench.cpp +32 -41
- package/cpp/test.cpp +13 -7
- package/docs/golang/index.rst +6 -0
- package/docs/index.rst +6 -2
- package/docs/javascript/index.rst +1 -1
- package/docs/python/index.rst +1 -1
- package/docs/python/reference.rst +9 -2
- package/docs/rust/index.rst +6 -0
- package/docs/swift/index.rst +6 -0
- package/golang/README.md +28 -0
- package/include/usearch/index.hpp +204 -78
- package/include/usearch/index_punned_dense.hpp +239 -85
- package/java/README.md +22 -0
- package/javascript/README.md +36 -0
- package/javascript/lib.cpp +1 -1
- package/package.json +1 -1
- package/python/README.md +283 -0
- package/python/lib.cpp +61 -11
- package/python/scripts/join.py +7 -3
- package/python/scripts/test.py +28 -243
- package/python/scripts/test_jit.py +244 -0
- package/python/usearch/index.py +97 -25
- package/rust/README.md +67 -0
- package/swift/README.md +20 -0
- package/wasm/CMakeLists.txt +15 -0
- package/wasm/README.md +13 -0
- package/wasm/lib.cpp +5 -0
- package/wasmer.toml +8 -0
- package/wolfram/README.md +13 -0
package/README.md
CHANGED
|
@@ -20,225 +20,61 @@ Vector Search Engine<br/>
|
|
|
20
20
|
<p align="center">
|
|
21
21
|
Euclidean • Angular • Jaccard • Hamming • Haversine • User-Defined Metrics
|
|
22
22
|
<br/>
|
|
23
|
-
<a href="
|
|
24
|
-
<a href="
|
|
25
|
-
<a href="
|
|
26
|
-
<a href="
|
|
27
|
-
<a href="
|
|
28
|
-
<a href="
|
|
29
|
-
<a href="
|
|
30
|
-
<a href="
|
|
31
|
-
<a href="
|
|
23
|
+
<a href="https://unum-cloud.github.io/usearch/cpp">C++11</a> •
|
|
24
|
+
<a href="https://unum-cloud.github.io/usearch/python">Python</a> •
|
|
25
|
+
<a href="https://unum-cloud.github.io/usearch/javascript">JavaScript</a> •
|
|
26
|
+
<a href="https://unum-cloud.github.io/usearch/java">Java</a> •
|
|
27
|
+
<a href="https://unum-cloud.github.io/usearch/rust">Rust</a> •
|
|
28
|
+
<a href="https://unum-cloud.github.io/usearch/c">C99</a> •
|
|
29
|
+
<a href="https://unum-cloud.github.io/usearch/objective-c">Objective-C</a> •
|
|
30
|
+
<a href="https://unum-cloud.github.io/usearch/swift">Swift</a> •
|
|
31
|
+
<a href="https://unum-cloud.github.io/usearch/golang">GoLang</a> •
|
|
32
|
+
<a href="https://unum-cloud.github.io/usearch/wolfram">Wolfram</a>
|
|
32
33
|
<br/>
|
|
33
|
-
Linux • MacOS • Windows • Docker • WebAssembly
|
|
34
|
+
Linux • MacOS • Windows • Docker • WebAssembly
|
|
34
35
|
</p>
|
|
35
36
|
|
|
36
37
|
---
|
|
37
38
|
|
|
38
|
-
-
|
|
39
|
-
-
|
|
40
|
-
-
|
|
41
|
-
-
|
|
42
|
-
-
|
|
43
|
-
-
|
|
44
|
-
-
|
|
45
|
-
-
|
|
46
|
-
-
|
|
47
|
-
-
|
|
48
|
-
-
|
|
49
|
-
- [ ]
|
|
50
|
-
- [
|
|
51
|
-
- [x] USearch + RDKit = [Molecule Search](#ai--vector-search--semantic-search).
|
|
39
|
+
- ✅ Benchmark-topping performance.
|
|
40
|
+
- ✅ Simple and extensible [single C++11 header][usearch-header] implementation.
|
|
41
|
+
- ✅ SIMD-optimized and [user-defined metrics](#user-defined-functions) with JIT-compilation.
|
|
42
|
+
- ✅ Variable dimensionality vectors for unique applications, including GIS and Chess.
|
|
43
|
+
- ✅ Advanced bitwise Tanimoto and Sorensen coefficients ideal for Genomics and Chemistry.
|
|
44
|
+
- ✅ On-the-fly support for [half-precision `f16` and quarter-precision `f8`](#memory-efficiency-downcasting-and-quantization), compatible with any hardware.
|
|
45
|
+
- ✅ [View large indexes from disk](#disk-based-indexes) without loading into RAM.
|
|
46
|
+
- ✅ Space-efficient point-clouds with `uint40_t`, accommodating 4B+ size.
|
|
47
|
+
- ✅ Optimized for concurrent threading, like OpenMP or C++23 executors with bring your threads.
|
|
48
|
+
- ✅ Support for multiple vectors per label.
|
|
49
|
+
- ✅ On-the-fly deletions.
|
|
50
|
+
- ✅ Utilize [USearch and UForm Transformers for Semantic Search](#usearch--ai--multi-modal-semantic-search).
|
|
51
|
+
- ✅ Combine [USearch and RDKit for Molecule Search](#usearch--rdkit--molecular-search).
|
|
52
52
|
|
|
53
53
|
[usearch-header]: https://github.com/unum-cloud/usearch/blob/main/include/usearch/index.hpp
|
|
54
54
|
[obscure-use-cases]: https://ashvardanian.com/posts/abusing-vector-search
|
|
55
55
|
|
|
56
|
-
|
|
56
|
+
## Comparison with FAISS
|
|
57
|
+
|
|
58
|
+
FAISS is a widely recognized standard for high-performance vector search engines.
|
|
59
|
+
USearch and FAISS both employ the same HNSW algorithm, but they differ significantly in their design principles.
|
|
60
|
+
USearch is compact and broadly compatible without sacrificing performance, with a primary focus on user-defined metrics and fewer dependencies.
|
|
57
61
|
|
|
58
62
|
| | FAISS | USearch |
|
|
59
63
|
| :----------------- | :---------------------------- | :--------------------------------- |
|
|
60
|
-
| Implementation | 84 K [SLOC][sloc] in `faiss/` |
|
|
64
|
+
| Implementation | 84 K [SLOC][sloc] in `faiss/` | 3 K [SLOC][sloc] in `usearch/` |
|
|
61
65
|
| Supported metrics | 9 fixed metrics | Any User-Defined metrics |
|
|
62
66
|
| Supported ID types | `uint32_t`, `uint64_t` | `uint32_t`, `uint40_t`, `uint64_t` |
|
|
63
67
|
| Dependencies | BLAS, OpenMP | None |
|
|
64
68
|
| Bindings | SWIG | Native |
|
|
65
69
|
| Acceleration | Learned Quantization | Downcasting |
|
|
66
70
|
|
|
67
|
-
FAISS is the industry standard for a high-performance batteries-included vector search engine.
|
|
68
|
-
Both USearch and FAISS implement the same HNSW algorithm.
|
|
69
|
-
But they differ in a lot of design decisions.
|
|
70
|
-
USearch is designed to be compact and broadly compatible without sacrificing performance.
|
|
71
|
-
|
|
72
|
-
| | FAISS, `f32` | USearch, `f32` | USearch, `f16` | USearch, `f8` |
|
|
73
|
-
| :----------- | -----------: | -------------: | -------------: | ------------: |
|
|
74
|
-
| Batch Insert | 16 K/s | 73 K/s | 100 K/s | **104 K/s** |
|
|
75
|
-
| Batch Search | 82 K/s | 103 K/s | 113 K/s | **134 K/s** |
|
|
76
|
-
| Bulk Insert | 76 K/s | 105 K/s | 115 K/s | **202 K/s** |
|
|
77
|
-
| Bulk Search | 118 K/s | 174 K/s | 173 K/s | **304 K/s** |
|
|
78
|
-
| Recall @1 | 99% | 99.2% | 99.1% | **99.2%** |
|
|
79
|
-
|
|
80
|
-
> Dataset: 1M vectors sample of the Deep1B dataset.
|
|
81
|
-
> Hardware: `c7g.metal` AWS instance with 64 cores and DDR5 memory.
|
|
82
|
-
> HNSW was configured with identical hyper-parameters:
|
|
83
|
-
> connectivity `M=16`,
|
|
84
|
-
> expansion @ construction `efConstruction=128`,
|
|
85
|
-
> and expansion @ search `ef=64`.
|
|
86
|
-
> Batch size is 256.
|
|
87
|
-
> Both libraries were compiled for the target architecture.
|
|
88
|
-
> Jump to the [Performance Tuning][benchmarking] section to read about the effects of those hyper-parameters.
|
|
89
|
-
|
|
90
71
|
[sloc]: https://en.wikipedia.org/wiki/Source_lines_of_code
|
|
91
|
-
[benchmarking]: https://github.com/unum-cloud/usearch/blob/main/docs/benchmarks.md
|
|
92
|
-
|
|
93
|
-
## User-Defined Functions
|
|
94
|
-
|
|
95
|
-
Most vector-search packages focus on just 2 metrics - "Inner Product distance" and "Euclidean distance".
|
|
96
|
-
That only partially exhausts the list of possible metrics.
|
|
97
|
-
A good example would be the rare [Haversine][haversine] distance, used to compute the distance between geo-spatial coordinates, extending Vector Search into the GIS domain.
|
|
98
|
-
Another example would be designing a custom metric for **composite embeddings** concatenated from multiple AI models in real-world applications.
|
|
99
|
-
USearch supports that: [Python](#user-defined-functions-in-python) and [C++](#user-defined-functions-in-c) examples.
|
|
100
|
-
|
|
101
|
-
|
|
102
|
-
|
|
103
|
-
Unlike older approaches indexing high-dimensional spaces, like KD-Trees and Locality Sensitive Hashing, HNSW doesn't require vectors to be identical in length.
|
|
104
|
-
They only have to be comparable.
|
|
105
|
-
So you can apply it in [obscure][obscure] applications, like searching for similar sets or fuzzy text matching.
|
|
106
|
-
|
|
107
|
-
[haversine]: https://ashvardanian.com/posts/abusing-vector-search#geo-spatial-indexing
|
|
108
|
-
[obscure]: https://ashvardanian.com/posts/abusing-vector-search
|
|
109
|
-
|
|
110
|
-
## Memory Efficiency, Downcasting, and Quantization
|
|
111
|
-
|
|
112
|
-
Training a quantization model and dimension-reduction is a common approach to accelerate vector search.
|
|
113
|
-
Those, however, are only sometimes reliable, can significantly affect the statistical properties of your data, and require regular adjustments if your distribution shifts.
|
|
114
|
-
|
|
115
|
-
|
|
116
|
-
|
|
117
|
-
Instead, we have focused on high-precision arithmetic over low-precision downcasted vectors.
|
|
118
|
-
The same index, and `add` and `search` operations will automatically down-cast or up-cast between `f32_t`, `f16_t`, `f64_t`, and `f8_t` representations, even if the hardware doesn't natively support it.
|
|
119
|
-
Continuing the topic of memory-efficiency, we provide a `uint40_t` to allow collection with over 4B+ vectors without allocating 8 bytes for every neighbor reference in the proximity graph.
|
|
120
|
-
|
|
121
|
-
## View Larger Indexes from Disk
|
|
122
|
-
|
|
123
|
-
Modern search systems often suggest using different servers to maximize indexing speed and minimize serving costs.
|
|
124
|
-
Memory-optimized for the first task, and storage-optimized for the second, if the index can be served from external memory, which USearch can.
|
|
125
|
-
|
|
126
|
-
| | To Build | To Serve |
|
|
127
|
-
| :------- | :-------------: | :--------------------: |
|
|
128
|
-
| Instance | u-24tb1.metal | is4gen.8xlarge |
|
|
129
|
-
| Price | ~ $200/h | ~$4.5/h |
|
|
130
|
-
| Memory | 24 TB RAM + EBS | 192 GB RAM + 30 TB SSD |
|
|
131
|
-
|
|
132
|
-
There is a 50x difference between the cost of such instances for identical capacity.
|
|
133
|
-
Of course, the latency of external memory access will be higher, but it is in part compensated with an excellent prefetching mechanism.
|
|
134
|
-
|
|
135
|
-
## Usage
|
|
136
|
-
|
|
137
|
-
There are two usage patters:
|
|
138
|
-
|
|
139
|
-
1. Bare-bones with `usearch/index.hpp`, only available in C++.
|
|
140
|
-
2. Full-fat version with it's own threads, mutexes, type-punning, quantization, that is available both in C++ and is wrapped for higher-level bindings.
|
|
141
|
-
|
|
142
|
-
### C++
|
|
143
|
-
|
|
144
|
-
#### Installation
|
|
145
|
-
|
|
146
|
-
To use in a C++ project simply copy the `include/usearch/index.hpp` header into your project.
|
|
147
|
-
Alternatively fetch it with CMake:
|
|
148
|
-
|
|
149
|
-
```cmake
|
|
150
|
-
FetchContent_Declare(usearch GIT_REPOSITORY https://github.com/unum-cloud/usearch.git)
|
|
151
|
-
FetchContent_MakeAvailable(usearch)
|
|
152
|
-
```
|
|
153
|
-
|
|
154
|
-
#### Quickstart
|
|
155
|
-
|
|
156
|
-
Once included, the low-level C++11 interface is as simple as it gets: `reserve()`, `add()`, `search()`, `size()`, `capacity()`, `save()`, `load()`, `view()`.
|
|
157
|
-
This covers 90% of use-cases.
|
|
158
|
-
|
|
159
|
-
```c++
|
|
160
|
-
using namespace unum::usearch;
|
|
161
|
-
|
|
162
|
-
index_gt<cos_gt<float>> index;
|
|
163
|
-
float vec[3] = {0.1, 0.3, 0.2};
|
|
164
72
|
|
|
165
|
-
|
|
166
|
-
index.add(/* label: */ 42, /* vector: */ {&vec[0], 3});
|
|
167
|
-
auto results = index.search(/* query: */ {&vec[0], 3}, 5 /* neighbors */);
|
|
73
|
+
Base functionality is identical to FAISS, and the interface must be familiar if you have ever investigated Approximate Nearest Neigbors search:
|
|
168
74
|
|
|
169
|
-
|
|
170
|
-
|
|
171
|
-
```
|
|
172
|
-
|
|
173
|
-
The `add` is thread-safe for concurrent index construction.
|
|
174
|
-
|
|
175
|
-
#### Serialization
|
|
176
|
-
|
|
177
|
-
```c++
|
|
178
|
-
index.save("index.usearch");
|
|
179
|
-
index.load("index.usearch"); // Copying from disk
|
|
180
|
-
index.view("index.usearch"); // Memory-mapping from disk
|
|
181
|
-
```
|
|
182
|
-
|
|
183
|
-
#### User-Defined Metrics in C++
|
|
184
|
-
|
|
185
|
-
For advanced users, more compile-time abstractions are available.
|
|
186
|
-
|
|
187
|
-
```cpp
|
|
188
|
-
template <typename metric_at = ip_gt<float>, //
|
|
189
|
-
typename label_at = std::size_t, // `uint32_t`, `uuid_t`...
|
|
190
|
-
typename id_at = std::uint32_t, // `uint40_t`, `uint64_t`...
|
|
191
|
-
typename scalar_at = float, // `double`, `half`, `char`...
|
|
192
|
-
typename allocator_at = std::allocator<char>> //
|
|
193
|
-
class index_gt;
|
|
194
|
-
```
|
|
195
|
-
|
|
196
|
-
You may want to use a custom memory allocator or a rare scalar type, but most often, you would start by defining a custom similarity measure.
|
|
197
|
-
The function object should have the following signature to support different-length vectors.
|
|
198
|
-
|
|
199
|
-
```cpp
|
|
200
|
-
struct custom_metric_t {
|
|
201
|
-
T operator()(T const* a, T const* b, std::size_t a_length, std::size_t b_length) const;
|
|
202
|
-
};
|
|
203
|
-
```
|
|
204
|
-
|
|
205
|
-
The following distances are pre-packaged:
|
|
206
|
-
|
|
207
|
-
- `cos_gt<scalar_t>` for "Cosine" or "Angular" distance.
|
|
208
|
-
- `ip_gt<scalar_t>` for "Inner Product" or "Dot Product" distance.
|
|
209
|
-
- `l2sq_gt<scalar_t>` for the squared "L2" or "Euclidean" distance.
|
|
210
|
-
- `jaccard_gt<scalar_t>` for "Jaccard" distance between two ordered sets of unique elements.
|
|
211
|
-
- `hamming_gt<scalar_t>` for "Hamming" distance, as the number of shared bits in hashes.
|
|
212
|
-
- `tanimoto_gt<scalar_t>` for "Tanimoto" coefficient for bit-strings.
|
|
213
|
-
- `sorensen_gt<scalar_t>` for "Dice-Sorensen" coefficient for bit-strings.
|
|
214
|
-
- `pearson_correlation_gt<scalar_t>` for "Pearson" correlation between probability distributions.
|
|
215
|
-
- `haversine_gt<scalar_t>` for "Haversine" or "Great Circle" distance between coordinates used in GIS applications.
|
|
216
|
-
|
|
217
|
-
#### Multi-Threading
|
|
218
|
-
|
|
219
|
-
Most AI, HPC, or Big Data packages use some form of a thread pool.
|
|
220
|
-
Instead of spawning additional threads within USearch, we focus on the thread safety of `add()` function, simplifying resource management.
|
|
221
|
-
|
|
222
|
-
```cpp
|
|
223
|
-
#pragma omp parallel for
|
|
224
|
-
for (std::size_t i = 0; i < n; ++i)
|
|
225
|
-
native.add(label, span_t{vector, dims}, add_config_t { .thread = omp_get_thread_num() });
|
|
226
|
-
```
|
|
227
|
-
|
|
228
|
-
During initialization, we allocate enough temporary memory for all the cores on the machine.
|
|
229
|
-
On the call, the user can supply the identifier of the current thread, making this library easy to integrate with OpenMP and similar tools.
|
|
230
|
-
|
|
231
|
-
### Python
|
|
232
|
-
|
|
233
|
-
#### Installation
|
|
234
|
-
|
|
235
|
-
```sh
|
|
236
|
-
pip install usearch
|
|
237
|
-
```
|
|
238
|
-
|
|
239
|
-
#### Quickstart
|
|
75
|
+
```py
|
|
76
|
+
$ pip install usearch numpy
|
|
240
77
|
|
|
241
|
-
```python
|
|
242
78
|
import numpy as np
|
|
243
79
|
from usearch.index import Index
|
|
244
80
|
|
|
@@ -246,9 +82,9 @@ index = Index(
|
|
|
246
82
|
ndim=3, # Define the number of dimensions in input vectors
|
|
247
83
|
metric='cos', # Choose 'l2sq', 'haversine' or other metric, default = 'ip'
|
|
248
84
|
dtype='f32', # Quantize to 'f16' or 'f8' if needed, default = 'f32'
|
|
249
|
-
connectivity=16, # How frequent should the connections in the graph be
|
|
250
|
-
expansion_add=128, # Control the recall of indexing
|
|
251
|
-
expansion_search=64, # Control the quality of search
|
|
85
|
+
connectivity=16, # Optional: How frequent should the connections in the graph be
|
|
86
|
+
expansion_add=128, # Optional: Control the recall of indexing
|
|
87
|
+
expansion_search=64, # Optional: Control the quality of search
|
|
252
88
|
)
|
|
253
89
|
|
|
254
90
|
vector = np.array([0.2, 0.6, 0.4])
|
|
@@ -262,428 +98,103 @@ assert distances[0] <= 0.001
|
|
|
262
98
|
assert np.allclose(index[42], vector)
|
|
263
99
|
```
|
|
264
100
|
|
|
265
|
-
|
|
266
|
-
Assuming the presence of Global Interpreter Lock in Python, we spawn threads in the C++ layer on large insertions.
|
|
267
|
-
|
|
268
|
-
#### Serialization
|
|
269
|
-
|
|
270
|
-
```py
|
|
271
|
-
index.save('index.usearch')
|
|
272
|
-
index.load('index.usearch') # Copy the whole index into memory
|
|
273
|
-
index.view('index.usearch') # View from disk without loading in memory
|
|
274
|
-
```
|
|
275
|
-
|
|
276
|
-
If you don't know anything about the index except its path, there are two more endpoints to know:
|
|
277
|
-
|
|
278
|
-
```py
|
|
279
|
-
Index.metadata('index.usearch') -> IndexMetadata
|
|
280
|
-
Index.restore('index.usearch', view=False) -> Index
|
|
281
|
-
```
|
|
282
|
-
|
|
283
|
-
#### Batch Operations
|
|
284
|
-
|
|
285
|
-
Adding or querying a batch of entries is identical to adding a single vector.
|
|
286
|
-
The difference would be in the shape of the tensors.
|
|
287
|
-
|
|
288
|
-
```py
|
|
289
|
-
n = 100
|
|
290
|
-
labels = np.arange(n)
|
|
291
|
-
vectors = np.random.uniform(0, 0.3, (n, index.ndim)).astype(np.float32)
|
|
292
|
-
|
|
293
|
-
index.add(labels, vectors, threads=..., copy=...)
|
|
294
|
-
matches, distances, counts = index.search(vectors, 10, threads=...)
|
|
295
|
-
|
|
296
|
-
assert matches.shape[0] == vectors.shape[0]
|
|
297
|
-
assert counts[0] <= 10
|
|
298
|
-
```
|
|
101
|
+
## User-Defined Functions
|
|
299
102
|
|
|
300
|
-
|
|
301
|
-
|
|
302
|
-
The second controls whether the vector itself will be persisted inside the index.
|
|
303
|
-
If you can preserve the lifetime of the vector somewhere else, you can avoid the copy.
|
|
103
|
+
While most vector search packages concentrate on just a couple of metrics - "Inner Product distance" and "Euclidean distance," USearch extends this list to include any user-defined metrics.
|
|
104
|
+
This flexibility allows you to customize your search for a myriad of applications, from computing geo-spatial coordinates with the rare [Haversine][haversine] distance to creating custom metrics for composite embeddings from multiple AI models.
|
|
304
105
|
|
|
305
|
-
|
|
106
|
+

|
|
306
107
|
|
|
307
|
-
|
|
108
|
+
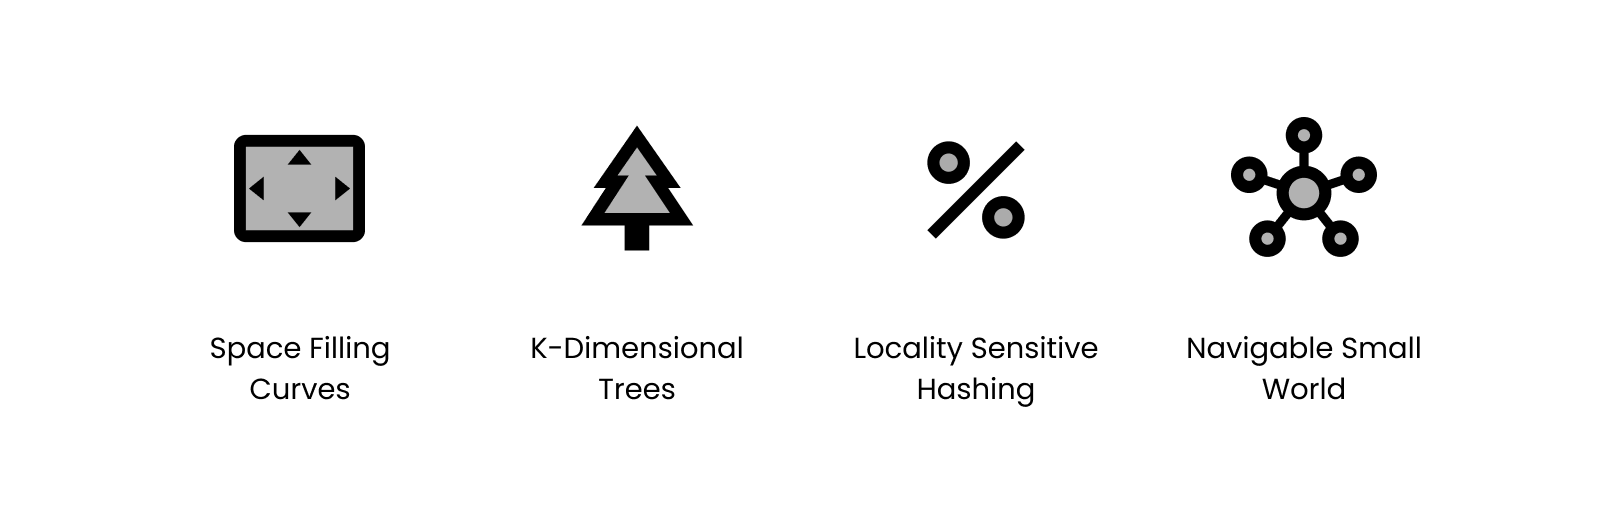
Unlike older approaches indexing high-dimensional spaces, like KD-Trees and Locality Sensitive Hashing, HNSW doesn't require vectors to be identical in length.
|
|
109
|
+
They only have to be comparable.
|
|
110
|
+
So you can apply it in [obscure][obscure] applications, like searching for similar sets or fuzzy text matching, using [GZip][gzip-similarity] as a distance function.
|
|
308
111
|
|
|
309
|
-
|
|
310
|
-
Luckily, with the help of [Numba][numba], we can JIT compile a function with a matching signature and pass it down to the engine.
|
|
112
|
+
> Read more about [JIT and UDF in USearch Python SDK]().
|
|
311
113
|
|
|
312
|
-
|
|
313
|
-
|
|
314
|
-
|
|
315
|
-
ndim = 256
|
|
316
|
-
signature = types.float32(
|
|
317
|
-
types.CPointer(types.float32),
|
|
318
|
-
types.CPointer(types.float32))
|
|
319
|
-
|
|
320
|
-
@cfunc(signature)
|
|
321
|
-
def inner_product(a, b):
|
|
322
|
-
a_array = carray(a, ndim)
|
|
323
|
-
b_array = carray(b, ndim)
|
|
324
|
-
c = 0.0
|
|
325
|
-
for i in range(ndim):
|
|
326
|
-
c += a_array[i] * b_array[i]
|
|
327
|
-
return 1 - c
|
|
328
|
-
|
|
329
|
-
index = Index(ndim=ndim, metric=CompiledMetric(
|
|
330
|
-
pointer=inner_product.address,
|
|
331
|
-
kind=MetricKind.IP,
|
|
332
|
-
signature=MetricSignature.ArrayArray,
|
|
333
|
-
))
|
|
334
|
-
```
|
|
114
|
+
[haversine]: https://ashvardanian.com/posts/abusing-vector-search#geo-spatial-indexing
|
|
115
|
+
[obscure]: https://ashvardanian.com/posts/abusing-vector-search
|
|
116
|
+
[gzip-similarity]: https://twitter.com/LukeGessler/status/1679211291292889100?s=20
|
|
335
117
|
|
|
336
|
-
|
|
118
|
+
## Memory Efficiency, Downcasting, and Quantization
|
|
337
119
|
|
|
338
|
-
|
|
339
|
-
|
|
340
|
-
types.CPointer(types.float32),
|
|
341
|
-
types.CPointer(types.float32),
|
|
342
|
-
types.uint64)
|
|
343
|
-
|
|
344
|
-
@cfunc(signature)
|
|
345
|
-
def inner_product(a, b, ndim):
|
|
346
|
-
a_array = carray(a, ndim)
|
|
347
|
-
b_array = carray(b, ndim)
|
|
348
|
-
c = 0.0
|
|
349
|
-
for i in range(ndim):
|
|
350
|
-
c += a_array[i] * b_array[i]
|
|
351
|
-
return 1 - c
|
|
352
|
-
|
|
353
|
-
index = Index(ndim=ndim, metric=CompiledMetric(
|
|
354
|
-
pointer=inner_product.address,
|
|
355
|
-
kind=MetricKind.IP,
|
|
356
|
-
signature=MetricSignature.ArrayArraySize,
|
|
357
|
-
))
|
|
358
|
-
```
|
|
120
|
+
Training a quantization model and dimension-reduction is a common approach to accelerate vector search.
|
|
121
|
+
Those, however, are only sometimes reliable, can significantly affect the statistical properties of your data, and require regular adjustments if your distribution shifts.
|
|
359
122
|
|
|
360
|
-
|
|
361
|
-
pip install numba
|
|
362
|
-
```
|
|
123
|
+

|
|
363
124
|
|
|
364
|
-
|
|
125
|
+
Instead, we have focused on high-precision arithmetic over low-precision downcasted vectors.
|
|
126
|
+
The same index, and `add` and `search` operations will automatically down-cast or up-cast between `f32_t`, `f16_t`, `f64_t`, and `f8_t` representations, even if the hardware doesn't natively support it.
|
|
127
|
+
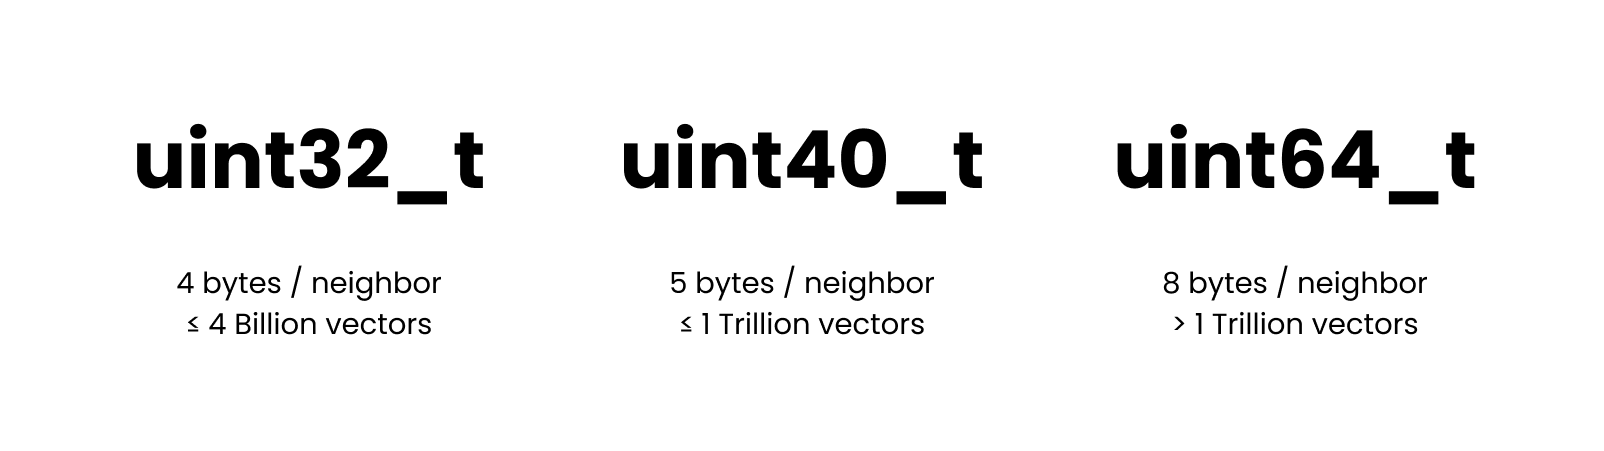
Continuing the topic of memory-efficiency, we provide a `uint40_t` to allow collection with over 4B+ vectors without allocating 8 bytes for every neighbor reference in the proximity graph.
|
|
365
128
|
|
|
366
|
-
|
|
129
|
+
| | FAISS, `f32` | USearch, `f32` | USearch, `f16` | USearch, `f8` |
|
|
130
|
+
| :----------- | -----------: | -------------: | -------------: | ----------------: |
|
|
131
|
+
| Batch Insert | 16 K/s | 73 K/s | 100 K/s | 104 K/s **+550%** |
|
|
132
|
+
| Batch Search | 82 K/s | 103 K/s | 113 K/s | 134 K/s **+63%** |
|
|
133
|
+
| Bulk Insert | 76 K/s | 105 K/s | 115 K/s | 202 K/s **+165%** |
|
|
134
|
+
| Bulk Search | 118 K/s | 174 K/s | 173 K/s | 304 K/s **+157%** |
|
|
135
|
+
| Recall @ 10 | 99% | 99.2% | 99.1% | 99.2% |
|
|
367
136
|
|
|
368
|
-
|
|
369
|
-
|
|
370
|
-
|
|
371
|
-
|
|
372
|
-
|
|
373
|
-
|
|
374
|
-
|
|
375
|
-
|
|
376
|
-
|
|
377
|
-
result += a[i] * b[i];
|
|
378
|
-
return 1 - result;
|
|
379
|
-
}
|
|
380
|
-
""".replace("ndim", str(ndim)))
|
|
381
|
-
|
|
382
|
-
function = cppyy.gbl.inner_product
|
|
383
|
-
index = Index(ndim=ndim, metric=CompiledMetric(
|
|
384
|
-
pointer=cppyy.ll.addressof(function),
|
|
385
|
-
kind=MetricKind.IP,
|
|
386
|
-
signature=MetricSignature.ArrayArraySize,
|
|
387
|
-
))
|
|
388
|
-
```
|
|
137
|
+
> Dataset: 1M vectors sample of the Deep1B dataset.
|
|
138
|
+
> Hardware: `c7g.metal` AWS instance with 64 cores and DDR5 memory.
|
|
139
|
+
> HNSW was configured with identical hyper-parameters:
|
|
140
|
+
> connectivity `M=16`,
|
|
141
|
+
> expansion @ construction `efConstruction=128`,
|
|
142
|
+
> and expansion @ search `ef=64`.
|
|
143
|
+
> Batch size is 256.
|
|
144
|
+
> Both libraries were compiled for the target architecture.
|
|
145
|
+
> Jump to the [Performance Tuning][benchmarking] section to read about the effects of those hyper-parameters.
|
|
389
146
|
|
|
390
|
-
|
|
391
|
-
conda install -c conda-forge cppyy
|
|
392
|
-
```
|
|
147
|
+
[benchmarking]: https://github.com/unum-cloud/usearch/blob/main/docs/benchmarks.md
|
|
393
148
|
|
|
394
|
-
|
|
149
|
+
## Disk-based Indexes
|
|
395
150
|
|
|
396
|
-
|
|
397
|
-
|
|
398
|
-
That is also possible.
|
|
399
|
-
Below is an example of constructing the "Inner Product" distance for 8-dimensional `f32` vectors for x86 using [PeachPy][peachpy].
|
|
151
|
+
With USearch, you can serve indexes from external memory, enabling you to optimize your server choices for indexing speed and serving costs.
|
|
152
|
+
This can result in **20x costs reduction** on AWS and other public clouds.
|
|
400
153
|
|
|
401
154
|
```py
|
|
402
|
-
|
|
403
|
-
Argument,
|
|
404
|
-
ptr,
|
|
405
|
-
float_,
|
|
406
|
-
const_float_,
|
|
407
|
-
)
|
|
408
|
-
from peachpy.x86_64 import (
|
|
409
|
-
abi,
|
|
410
|
-
Function,
|
|
411
|
-
uarch,
|
|
412
|
-
isa,
|
|
413
|
-
GeneralPurposeRegister64,
|
|
414
|
-
LOAD,
|
|
415
|
-
YMMRegister,
|
|
416
|
-
VSUBPS,
|
|
417
|
-
VADDPS,
|
|
418
|
-
VHADDPS,
|
|
419
|
-
VMOVUPS,
|
|
420
|
-
VFMADD231PS,
|
|
421
|
-
VPERM2F128,
|
|
422
|
-
VXORPS,
|
|
423
|
-
RETURN,
|
|
424
|
-
)
|
|
425
|
-
|
|
426
|
-
a = Argument(ptr(const_float_), name="a")
|
|
427
|
-
b = Argument(ptr(const_float_), name="b")
|
|
428
|
-
|
|
429
|
-
with Function(
|
|
430
|
-
"inner_product", (a, b), float_, target=uarch.default + isa.avx2
|
|
431
|
-
) as asm_function:
|
|
432
|
-
|
|
433
|
-
# Request two 64-bit general-purpose registers for addresses
|
|
434
|
-
reg_a, reg_b = GeneralPurposeRegister64(), GeneralPurposeRegister64()
|
|
435
|
-
LOAD.ARGUMENT(reg_a, a)
|
|
436
|
-
LOAD.ARGUMENT(reg_b, b)
|
|
437
|
-
|
|
438
|
-
# Load the vectors
|
|
439
|
-
ymm_a = YMMRegister()
|
|
440
|
-
ymm_b = YMMRegister()
|
|
441
|
-
VMOVUPS(ymm_a, [reg_a])
|
|
442
|
-
VMOVUPS(ymm_b, [reg_b])
|
|
443
|
-
|
|
444
|
-
# Prepare the accumulator
|
|
445
|
-
ymm_c = YMMRegister()
|
|
446
|
-
ymm_one = YMMRegister()
|
|
447
|
-
VXORPS(ymm_c, ymm_c, ymm_c)
|
|
448
|
-
VXORPS(ymm_one, ymm_one, ymm_one)
|
|
449
|
-
|
|
450
|
-
# Accumulate A and B product into C
|
|
451
|
-
VFMADD231PS(ymm_c, ymm_a, ymm_b)
|
|
452
|
-
|
|
453
|
-
# Reduce the contents of a YMM register
|
|
454
|
-
ymm_c_permuted = YMMRegister()
|
|
455
|
-
VPERM2F128(ymm_c_permuted, ymm_c, ymm_c, 1)
|
|
456
|
-
VADDPS(ymm_c, ymm_c, ymm_c_permuted)
|
|
457
|
-
VHADDPS(ymm_c, ymm_c, ymm_c)
|
|
458
|
-
VHADDPS(ymm_c, ymm_c, ymm_c)
|
|
459
|
-
|
|
460
|
-
# Negate the values, to go from "similarity" to "distance"
|
|
461
|
-
VSUBPS(ymm_c, ymm_one, ymm_c)
|
|
462
|
-
|
|
463
|
-
# A common convention is to return floats in XMM registers
|
|
464
|
-
RETURN(ymm_c.as_xmm)
|
|
465
|
-
|
|
466
|
-
python_function = asm_function.finalize(abi.detect()).encode().load()
|
|
467
|
-
metric = CompiledMetric(
|
|
468
|
-
pointer=python_function.loader.code_address,
|
|
469
|
-
kind=MetricKind.IP,
|
|
470
|
-
signature=MetricSignature.ArrayArray,
|
|
471
|
-
)
|
|
472
|
-
index = Index(ndim=ndim, metric=metric)
|
|
473
|
-
```
|
|
474
|
-
|
|
475
|
-
[numba]: https://numba.readthedocs.io/en/stable/reference/jit-compilation.html#c-callbacks
|
|
476
|
-
[cppyy]: https://cppyy.readthedocs.io/en/latest/
|
|
477
|
-
[peachpy]: https://github.com/Maratyszcza/PeachPy
|
|
478
|
-
|
|
479
|
-
#### Tooling
|
|
155
|
+
index.save("index.usearch")
|
|
480
156
|
|
|
481
|
-
|
|
482
|
-
|
|
157
|
+
loaded_copy = index.load("index.usearch")
|
|
158
|
+
view = Index.restore("index.usearch", view=True)
|
|
483
159
|
|
|
484
|
-
|
|
485
|
-
|
|
486
|
-
from usearch.io import load_matrix, save_matrix
|
|
487
|
-
|
|
488
|
-
vectors = load_matrix('deep1B.fbin')
|
|
489
|
-
index = Index(ndim=vectors.shape[1])
|
|
490
|
-
index.add(labels, vectors)
|
|
160
|
+
other_view = Index(ndim=..., metric=CompiledMetric(...))
|
|
161
|
+
other_view.view("index.usearch")
|
|
491
162
|
```
|
|
492
163
|
|
|
493
|
-
|
|
494
|
-
The trivial way is to measure `recall@1` on the entries already present in the index.
|
|
164
|
+
## Joins
|
|
495
165
|
|
|
496
|
-
|
|
497
|
-
|
|
166
|
+
One of the big questions these days is how will AI change the world of databases and data-management?
|
|
167
|
+
Most databases are still struggling to implement high-quality fuzzy search, and the only kind of joins they know are deterministic.
|
|
168
|
+
A `join` is different from searching for every entry, as it requires a one-to-one mapping, banning collisions among separate search results.
|
|
498
169
|
|
|
499
|
-
|
|
500
|
-
|
|
501
|
-
|
|
170
|
+
| Exact Search | Fuzzy Search | Semantic Search ? |
|
|
171
|
+
| :----------: | :----------: | :---------------: |
|
|
172
|
+
| Exact Join | Fuzzy Join ? | Semantic Join ?? |
|
|
502
173
|
|
|
503
|
-
|
|
174
|
+
Using USearch one can implement sub-quadratic complexity approximate, fuzzy, and semantic joins.
|
|
175
|
+
This can come handy in any fuzzy-matching tasks, common to Database Management Software.
|
|
504
176
|
|
|
505
177
|
```py
|
|
506
|
-
|
|
507
|
-
|
|
508
|
-
|
|
509
|
-
matches_approximate = index.search(vectors)
|
|
510
|
-
matches_exact = index.search(vectors, exact=True)
|
|
511
|
-
relevance_scores = relevance(matches_exact, matches_approximate)
|
|
512
|
-
print(dcg(relevance_scores), ndcg(relevance_scores))
|
|
513
|
-
```
|
|
514
|
-
|
|
515
|
-
### JavaScript
|
|
516
|
-
|
|
517
|
-
#### Installation
|
|
518
|
-
|
|
519
|
-
```sh
|
|
520
|
-
npm install usearch
|
|
521
|
-
```
|
|
522
|
-
|
|
523
|
-
#### Quickstart
|
|
524
|
-
|
|
525
|
-
```js
|
|
526
|
-
var index = new usearch.Index({ metric: 'cos', connectivity: 16, dimensions: 3 })
|
|
527
|
-
index.add(42, new Float32Array([0.2, 0.6, 0.4]))
|
|
528
|
-
var results = index.search(new Float32Array([0.2, 0.6, 0.4]), 10)
|
|
529
|
-
|
|
530
|
-
assert.equal(index.size(), 1)
|
|
531
|
-
assert.deepEqual(results.labels, new Uint32Array([42]))
|
|
532
|
-
assert.deepEqual(results.distances, new Float32Array([0]))
|
|
533
|
-
```
|
|
534
|
-
|
|
535
|
-
#### Serialization
|
|
536
|
-
|
|
537
|
-
```js
|
|
538
|
-
index.save('index.usearch')
|
|
539
|
-
index.load('index.usearch')
|
|
540
|
-
index.view('index.usearch')
|
|
178
|
+
men = Index(...)
|
|
179
|
+
women = Index(...)
|
|
180
|
+
pairs: dict = men.join(women, max_proposals=0, exact=False)
|
|
541
181
|
```
|
|
542
182
|
|
|
543
|
-
|
|
544
|
-
|
|
545
|
-
#### Installation
|
|
546
|
-
|
|
547
|
-
```sh
|
|
548
|
-
cargo add usearch
|
|
549
|
-
```
|
|
183
|
+
> Read more in post: [From Dating to Vector Search - "Stable Marriages" on a Planetary Scale 👩❤️👨](https://ashvardanian.com/posts/searching-stable-marriages)
|
|
550
184
|
|
|
551
|
-
|
|
185
|
+
## Functionality
|
|
552
186
|
|
|
553
|
-
|
|
554
|
-
|
|
555
|
-
let options = IndexOptions {
|
|
556
|
-
dimensions: 5,
|
|
557
|
-
metric: MetricKind::IP,
|
|
558
|
-
quantization: ScalarKind::F16,
|
|
559
|
-
connectivity: 0,
|
|
560
|
-
expansion_add: 0,
|
|
561
|
-
expansion_search: 0
|
|
562
|
-
};
|
|
563
|
-
|
|
564
|
-
let index = new_index(&options).unwrap();
|
|
565
|
-
|
|
566
|
-
assert!(index.reserve(10).is_ok());
|
|
567
|
-
assert!(index.capacity() >= 10);
|
|
568
|
-
assert!(index.connectivity() != 0);
|
|
569
|
-
assert_eq!(index.dimensions(), 3);
|
|
570
|
-
assert_eq!(index.size(), 0);
|
|
571
|
-
|
|
572
|
-
let first: [f32; 3] = [0.2, 0.1, 0.2];
|
|
573
|
-
let second: [f32; 3] = [0.2, 0.1, 0.2];
|
|
574
|
-
|
|
575
|
-
assert!(index.add(42, &first).is_ok());
|
|
576
|
-
assert!(index.add(43, &second).is_ok());
|
|
577
|
-
assert_eq!(index.size(), 2);
|
|
578
|
-
|
|
579
|
-
// Read back the tags
|
|
580
|
-
let results = index.search(&first, 10).unwrap();
|
|
581
|
-
assert_eq!(results.count, 2);
|
|
582
|
-
```
|
|
583
|
-
|
|
584
|
-
#### Multi-Threading
|
|
585
|
-
|
|
586
|
-
```rust
|
|
587
|
-
assert!(index.add_in_thread(42, &first, 0).is_ok());
|
|
588
|
-
assert!(index.add_in_thread(43, &second, 0).is_ok());
|
|
589
|
-
let results = index.search_in_thread(&first, 10, 0).unwrap();
|
|
590
|
-
```
|
|
591
|
-
|
|
592
|
-
Being a systems-programming language, Rust has better control over memory management and concurrency but lacks function overloading.
|
|
593
|
-
Aside from the `add` and `search`, USearch Rust binding also provides `add_in_thread` and `search_in_thread`, which let users identify the calling thread to use underlying temporary memory more efficiently.
|
|
594
|
-
|
|
595
|
-
#### Serialization
|
|
596
|
-
|
|
597
|
-
```rust
|
|
598
|
-
assert!(index.save("index.usearch").is_ok());
|
|
599
|
-
assert!(index.load("index.usearch").is_ok());
|
|
600
|
-
assert!(index.view("index.usearch").is_ok());
|
|
601
|
-
```
|
|
602
|
-
|
|
603
|
-
#### Metrics
|
|
604
|
-
|
|
605
|
-
```rust
|
|
606
|
-
assert!(new_l2sq(3, &quant, 0, 0, 0).is_ok());
|
|
607
|
-
assert!(new_cos(3, &quant, 0, 0, 0).is_ok());
|
|
608
|
-
assert!(new_haversine(&quant, 0, 0, 0).is_ok());
|
|
609
|
-
```
|
|
610
|
-
|
|
611
|
-
### Java
|
|
612
|
-
|
|
613
|
-
#### Installation
|
|
614
|
-
|
|
615
|
-
```xml
|
|
616
|
-
<dependency>
|
|
617
|
-
<groupId>cloud.unum</groupId>
|
|
618
|
-
<artifactId>usearch</artifactId>
|
|
619
|
-
<version>0.2.3</version>
|
|
620
|
-
</dependency>
|
|
621
|
-
```
|
|
622
|
-
|
|
623
|
-
Add that snippet to your `pom.xml` and hit `mvn install`.
|
|
624
|
-
|
|
625
|
-
#### Quickstart
|
|
626
|
-
|
|
627
|
-
```java
|
|
628
|
-
Index index = new Index.Config().metric("cos").dimensions(2).build();
|
|
629
|
-
float vec[] = {10, 20};
|
|
630
|
-
index.add(42, vec);
|
|
631
|
-
int[] labels = index.search(vec, 5);
|
|
632
|
-
```
|
|
633
|
-
|
|
634
|
-
### Swift
|
|
635
|
-
|
|
636
|
-
#### Installation
|
|
637
|
-
|
|
638
|
-
```txt
|
|
639
|
-
https://github.com/unum-cloud/usearch
|
|
640
|
-
```
|
|
641
|
-
|
|
642
|
-
#### Quickstart
|
|
643
|
-
|
|
644
|
-
```swift
|
|
645
|
-
let index = Index.l2sq(dimensions: 3, connectivity: 8)
|
|
646
|
-
let vectorA: [Float32] = [0.3, 0.5, 1.2]
|
|
647
|
-
let vectorB: [Float32] = [0.4, 0.2, 1.2]
|
|
648
|
-
index.reserve(2)
|
|
649
|
-
index.add(label: 42, vector: vectorA[...])
|
|
650
|
-
index.add(label: 43, vector: vectorB[...])
|
|
651
|
-
|
|
652
|
-
let results = index.search(vector: vectorA[...], count: 10)
|
|
653
|
-
assert(results.0[0] == 42)
|
|
654
|
-
```
|
|
655
|
-
|
|
656
|
-
### GoLang
|
|
657
|
-
|
|
658
|
-
#### Installation
|
|
659
|
-
|
|
660
|
-
```golang
|
|
661
|
-
import (
|
|
662
|
-
"github.com/unum-cloud/usearch/golang"
|
|
663
|
-
)
|
|
664
|
-
```
|
|
665
|
-
|
|
666
|
-
#### Quickstart
|
|
667
|
-
|
|
668
|
-
```golang
|
|
669
|
-
package main
|
|
670
|
-
|
|
671
|
-
import (
|
|
672
|
-
"fmt"
|
|
673
|
-
"github.com/unum-cloud/usearch/golang"
|
|
674
|
-
)
|
|
675
|
-
|
|
676
|
-
func main() {
|
|
677
|
-
conf := usearch.DefaultConfig(128)
|
|
678
|
-
index := usearch.NewIndex(conf)
|
|
679
|
-
v := make([]float32, 128)
|
|
680
|
-
index.Add(42, v)
|
|
681
|
-
results := index.Search(v, 1)
|
|
682
|
-
}
|
|
683
|
-
```
|
|
684
|
-
|
|
685
|
-
### Wolfram
|
|
187
|
+
By now, core functionality is supported across all bindings.
|
|
188
|
+
Broader functionality is ported per request.
|
|
686
189
|
|
|
190
|
+
| | C++ | Python | Java | JavaScript | Rust | GoLang | Swift |
|
|
191
|
+
| :---------------------- | :---: | :----: | :---: | :--------: | :---: | :----: | :---: |
|
|
192
|
+
| add/search/remove | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
|
|
193
|
+
| save/load/view | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
|
|
194
|
+
| join | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
|
|
195
|
+
| user-defiend metrics | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
|
|
196
|
+
| variable-length vectors | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ |
|
|
197
|
+
| 4B+ capacities | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
|
|
687
198
|
|
|
688
199
|
## Application Examples
|
|
689
200
|
|
|
@@ -722,16 +233,19 @@ server.run()
|
|
|
722
233
|
|
|
723
234
|
We have pre-processed some commonly used datasets, cleaning the images, producing the vectors, and pre-building the index.
|
|
724
235
|
|
|
725
|
-
| Dataset
|
|
726
|
-
|
|
|
727
|
-
| [Unsplash 25K][unsplash-25k-origin]
|
|
728
|
-
| [
|
|
236
|
+
| Dataset | Modalities | Images | Download |
|
|
237
|
+
| :------------------------------------- | --------------------: | -----: | ------------------------------------: |
|
|
238
|
+
| [Unsplash 25K][unsplash-25k-origin] | Images & Descriptions | 25 K | [HuggingFace / Unum][unsplash-25k-hf] |
|
|
239
|
+
| [Conceptual Captions 3M][cc-3m-origin] | Images & Descriptions | 3 M | [HuggingFace / Unum][cc-3m-hf] |
|
|
240
|
+
| [Arxiv 2M][arxiv-2m-origin] | Titles & Abstracts | 2 M | [HuggingFace / Unum][arxiv-2m-hf] |
|
|
729
241
|
|
|
242
|
+
[unsplash-25k-origin]: https://github.com/unsplash/datasets
|
|
243
|
+
[cc-3m-origin]: https://huggingface.co/datasets/conceptual_captions
|
|
244
|
+
[arxiv-2m-origin]: https://www.kaggle.com/datasets/Cornell-University/arxiv
|
|
730
245
|
|
|
731
|
-
[unsplash-25k-
|
|
732
|
-
[cc-3m-
|
|
733
|
-
[
|
|
734
|
-
[cc-3m-hf]: https://unum.cloud
|
|
246
|
+
[unsplash-25k-hf]: https://huggingface.co/datasets/unum-cloud/ann-unsplash-25k
|
|
247
|
+
[cc-3m-hf]: https://huggingface.co/datasets/unum-cloud/ann-cc-3m
|
|
248
|
+
[arxiv-2m-hf]: https://huggingface.co/datasets/unum-cloud/ann-arxiv-2m
|
|
735
249
|
|
|
736
250
|
### USearch + RDKit = Molecular Search
|
|
737
251
|
|
|
@@ -755,32 +269,13 @@ encoder = AllChem.GetRDKitFPGenerator()
|
|
|
755
269
|
fingerprints = np.vstack([encoder.GetFingerprint(x) for x in molecules])
|
|
756
270
|
fingerprints = np.packbits(fingerprints, axis=1)
|
|
757
271
|
|
|
758
|
-
index = Index(ndim=2048, metric=MetricKind.
|
|
272
|
+
index = Index(ndim=2048, metric=MetricKind.Tanimoto)
|
|
759
273
|
labels = np.arange(len(molecules))
|
|
760
274
|
|
|
761
275
|
index.add(labels, fingerprints)
|
|
762
|
-
matches
|
|
276
|
+
matches = index.search(fingerprints, 10)
|
|
763
277
|
```
|
|
764
278
|
|
|
765
|
-
Of if you need a bit of our SIMD superpowers - take some Chemsitry-oriented precompiled metrics from [SimSIMD][simsimd].
|
|
766
|
-
|
|
767
|
-
```python
|
|
768
|
-
import simsimd as sisi
|
|
769
|
-
|
|
770
|
-
index = Index(
|
|
771
|
-
ndim=166, # MACCS fingerprints are 166-dimensional
|
|
772
|
-
metric=CompiledMetric(
|
|
773
|
-
pointer=sisi.to_int(sisi.tanimoto_maccs_neon), # For Arm Neon
|
|
774
|
-
signature=MetricSignature.ArrayArray,
|
|
775
|
-
kind=MetricKind.Tanimoto,
|
|
776
|
-
),
|
|
777
|
-
)
|
|
778
|
-
|
|
779
|
-
index.add(42, np.packbits([1] * 166))
|
|
780
|
-
matches: Matches = index.search(np.packbits([1] * 166))
|
|
781
|
-
```
|
|
782
|
-
|
|
783
|
-
[simsimd]: https://github.com/ashvardanian/simsimd
|
|
784
279
|
[smiles]: https://en.wikipedia.org/wiki/Simplified_molecular-input_line-entry_system
|
|
785
280
|
[rdkit-fingerprints]: https://www.rdkit.org/docs/RDKit_Book.html#additional-information-about-the-fingerprints
|
|
786
281
|
|
|
@@ -793,7 +288,7 @@ matches: Matches = index.search(np.packbits([1] * 166))
|
|
|
793
288
|
## Integrations
|
|
794
289
|
|
|
795
290
|
- [x] GPT-Cache.
|
|
796
|
-
- [ ]
|
|
291
|
+
- [ ] LangChain.
|
|
797
292
|
- [ ] Microsoft Semantic Kernel.
|
|
798
293
|
- [ ] PyTorch.
|
|
799
294
|
|
|
@@ -810,7 +305,3 @@ year = {2022}
|
|
|
810
305
|
month = jun,
|
|
811
306
|
}
|
|
812
307
|
```
|
|
813
|
-
|
|
814
|
-
---
|
|
815
|
-
|
|
816
|
-
Check [that](https://github.com/ashvardanian/image-search) and [other](https://github.com/unum-cloud/examples) examples on our corporate GitHub 🤗
|