toolmenu 0.25.2 → 0.27.1
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.md +170 -683
- package/dist/args.d.ts +14 -2
- package/dist/args.js +44 -1
- package/dist/auth-check.d.ts +27 -0
- package/dist/auth-check.js +177 -0
- package/dist/auth.d.ts +7 -0
- package/dist/auth.js +29 -1
- package/dist/auto.d.ts +8 -0
- package/dist/auto.js +9 -2
- package/dist/breakdown.js +14 -10
- package/dist/cli.js +151 -49
- package/dist/clients.d.ts +13 -2
- package/dist/clients.js +65 -11
- package/dist/config.js +6 -0
- package/dist/diff.d.ts +35 -1
- package/dist/diff.js +57 -12
- package/dist/failures.js +4 -3
- package/dist/help.d.ts +1 -1
- package/dist/help.js +45 -18
- package/dist/history.js +5 -0
- package/dist/html.d.ts +29 -0
- package/dist/html.js +360 -0
- package/dist/index.d.ts +3 -2
- package/dist/index.js +3 -2
- package/dist/init.d.ts +14 -0
- package/dist/init.js +20 -6
- package/dist/junit.d.ts +6 -1
- package/dist/junit.js +12 -3
- package/dist/mcp-env.d.ts +6 -0
- package/dist/mcp-env.js +6 -0
- package/dist/mcp.d.ts +11 -1
- package/dist/mcp.js +123 -22
- package/dist/menu.d.ts +6 -0
- package/dist/menu.js +12 -1
- package/dist/options.d.ts +10 -0
- package/dist/options.js +3 -0
- package/dist/report.d.ts +14 -0
- package/dist/report.js +57 -51
- package/dist/review.d.ts +48 -0
- package/dist/review.js +212 -0
- package/dist/rule-docs.json +49 -4
- package/dist/rules/clients.d.ts +11 -0
- package/dist/rules/clients.js +65 -2
- package/dist/rules/determinism.d.ts +3 -0
- package/dist/rules/determinism.js +44 -7
- package/dist/rules/ids.js +5 -1
- package/dist/rules/index.js +5 -2
- package/dist/rules/output.d.ts +21 -0
- package/dist/rules/output.js +49 -0
- package/dist/rules/search.js +1 -1
- package/dist/rules/spec.d.ts +19 -0
- package/dist/rules/spec.js +86 -1
- package/dist/sanitize.d.ts +42 -0
- package/dist/sanitize.js +142 -0
- package/dist/scan.d.ts +9 -2
- package/dist/scan.js +46 -24
- package/dist/session.d.ts +17 -0
- package/dist/session.js +119 -13
- package/dist/snapshot.js +2 -1
- package/package.json +5 -3
package/README.md
CHANGED
|
@@ -5,7 +5,7 @@
|
|
|
5
5
|
<h1 align="center">toolmenu</h1>
|
|
6
6
|
|
|
7
7
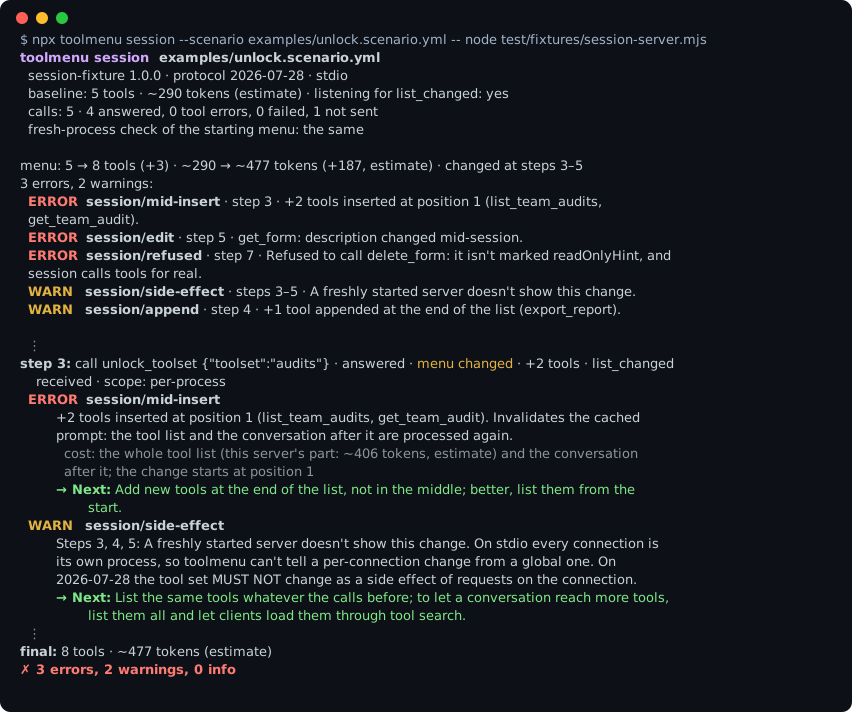
|
<p align="center">
|
|
8
|
-
<b>
|
|
8
|
+
<b>Tests your MCP server the way agents and clients meet it: the menu they read, the calls they make, the results and sign-in they get back, and every release after.</b>
|
|
9
9
|
</p>
|
|
10
10
|
|
|
11
11
|
<p align="center">
|
|
@@ -15,223 +15,108 @@
|
|
|
15
15
|
[](https://github.com/niksa90/toolmenu/blob/main/LICENSE)
|
|
16
16
|
[](https://modelcontextprotocol.io)
|
|
17
17
|
[](https://github.com/niksa90/toolmenu)
|
|
18
|
-
|
|
19
|
-
|
|
20
|
-
|
|
18
|
+
[](https://glama.ai/mcp/servers/niksa90/toolmenu)
|
|
19
|
+
[](https://mcprush.com/to/toolmenu-mcp?ref=badge)
|
|
20
|
+
[](https://mcpservers.org/servers/niksa90/toolmenu)
|
|
21
21
|
|
|
22
|
-
|
|
22
|
+
## License
|
|
23
23
|
|
|
24
|
-
|
|
25
|
-
toolmenu checks that menu the way clients and agents will meet it: across calls,
|
|
26
|
-
connections, clients and releases. No LLM is involved, so the same inputs always give
|
|
27
|
-
the same answer and it fits in CI.
|
|
24
|
+
MIT
|
|
28
25
|
|
|
29
|
-
```sh
|
|
30
|
-
npx toolmenu snapshot -- node dist/server.js # or: npx toolmenu snapshot https://example.com/mcp
|
|
31
|
-
npx toolmenu init -- node dist/server.js # CI: a baseline, a workflow, a comment on every PR
|
|
32
|
-
```
|
|
33
26
|
|
|
34
|
-
|
|
27
|
+
</p>
|
|
35
28
|
|
|
36
|
-
|
|
29
|
+
An MCP server can pass its own tests and still fail in the client. The client's SDK
|
|
30
|
+
rejects a tool list the server's own test client accepted. A default built from the
|
|
31
|
+
clock makes every listing different, so no prompt cache ever matches. A patch release
|
|
32
|
+
makes a parameter required. None of it shows until someone's agent has fewer tools, or
|
|
33
|
+
a bigger bill, and no error to explain it.
|
|
37
34
|
|
|
38
|
-
|
|
39
|
-
|
|
40
|
-
| **A menu that changes mid-session** | `session` calls your tools and watches the list. A tool added mid-conversation can rewrite the whole cached prompt: one unlock cost 40–57K tokens of cache in my logs. |
|
|
41
|
-
| **Breaking releases** | `diff` compares two menus: removed tools, new required parameters, narrowed types, token growth. It also says whether your version bump is big enough. |
|
|
42
|
-
| **The 2026-07-28 protocol** | The tool set must not vary per connection, and results need `resultType`. Elicitation, multi round-trip input and `server/discover` are checked too, as are the 2025 handshakes. |
|
|
43
|
-
| **MCP Apps, Tasks, Server Cards** | It reads `ui://` resources as a host does and checks who may see each tool. It catches tasks sent to clients that can't poll them, and Server Cards that contradict the live server. |
|
|
44
|
-
| **Your client's view** | `--client claude-code \| claude-api-search \| openai` shows what each client loads, cuts, can find and refuses. |
|
|
45
|
-
| **What agents misread** | It flags vague `id`s, IDs no tool returns, instructions buried late in descriptions, and writes without annotations or marked read-only. |
|
|
46
|
-
| **Words routing to the wrong tool** | `routes.yml` pins which tool each keyword must (and must not) reach, the way a keyword or BM25 tool search sees the menu. A description edit that lets `get_audit_trail` win "audit" fails the check, with no model and no eval budget. [More](#snapshot-rules) |
|
|
47
|
-
| **Menus that drift** | It catches defaults built from the clock or a hash order, menus that differ per process, per connection or offline, and listings that depend on who asks. |
|
|
48
|
-
|
|
49
|
-
Every finding says what's wrong, where it is and what toolmenu saw, and ends with a `→ Next:` step.
|
|
50
|
-
It runs on the 22-server [bench](bench/README.md) and on hosted servers (GitHub, Atlassian, Sentry,
|
|
51
|
-
Notion, Supabase, Vercel…). What it has found on real servers is in
|
|
52
|
-
[docs/FINDINGS.md](https://github.com/niksa90/toolmenu/blob/main/docs/FINDINGS.md).
|
|
53
|
-
|
|
54
|
-
> **Status: 0.25.** Spec in [docs/SPEC.md](https://github.com/niksa90/toolmenu/blob/main/docs/SPEC.md),
|
|
55
|
-
> every rule in [docs/RULES.md](docs/RULES.md), changes in [CHANGELOG.md](CHANGELOG.md).
|
|
56
|
-
|
|
57
|
-
<details>
|
|
58
|
-
<summary><b>Why "when it changes" matters</b></summary>
|
|
59
|
-
|
|
60
|
-
The MCP linters I found grade one snapshot of the menu: tool names, descriptions,
|
|
61
|
-
schemas. toolmenu also checks **when** the menu changes:
|
|
62
|
-
|
|
63
|
-
- **Mid-session.** Most clients put the tool list at the start of the prompt, so any
|
|
64
|
-
change to it, even a tool added at the end, means everything after it is processed
|
|
65
|
-
again. More on this, with a benchmark of the setups, in
|
|
66
|
-
[this write-up](https://niksa.me/agent-tools-design-lessons). `session` pins each
|
|
67
|
-
change to the step that caused it, and says where in the list it happened.
|
|
68
|
-
- **Per connection.** 2026-07-28 says the tool set **must not** vary per connection or
|
|
69
|
-
as a side effect of other requests (the 2025 versions allow it). Per-session
|
|
70
|
-
"unlock" designs, like the one I built, are ruled out. `session` tells you whether
|
|
71
|
-
yours is one of them. It also checks the menu clients will actually show: a broken
|
|
72
|
-
`x-mcp-header` or a `$ref` they can't resolve hides a tool or fails every call to
|
|
73
|
-
it. When a tool stops to ask the user something, `session` answers "no" and says
|
|
74
|
-
whether the tool can take it.
|
|
75
|
-
- **Between releases.** `diff` finds breaking changes and token growth, and checks the
|
|
76
|
-
version bump. `history` does it across a package's published releases. It installs
|
|
77
|
-
old versions with today's dependencies, so it records what they serve now
|
|
78
|
-
(FINDINGS F4).
|
|
79
|
-
|
|
80
|
-
Run against the reference server, `@modelcontextprotocol/server-everything`, it
|
|
81
|
-
reports no false findings ([bench/](bench/README.md)).
|
|
82
|
-
|
|
83
|
-
</details>
|
|
84
|
-
|
|
85
|
-
## Start here
|
|
86
|
-
|
|
87
|
-
Needs Node 22 or later. The GitHub Action brings its own if the runner's Node is older,
|
|
88
|
-
for toolmenu only: your server and the job's later steps keep the job's Node.
|
|
89
|
-
Your server can be in any language: toolmenu starts it (stdio) or connects to it (HTTP).
|
|
90
|
-
|
|
91
|
-
One command sets up CI: it snapshots your server into `menu.json` (the baseline) and
|
|
92
|
-
writes `.github/workflows/toolmenu.yml` for your project (Node, Python, Go or Rust).
|
|
93
|
-
Commit both, open a pull request, and toolmenu comments on it.
|
|
35
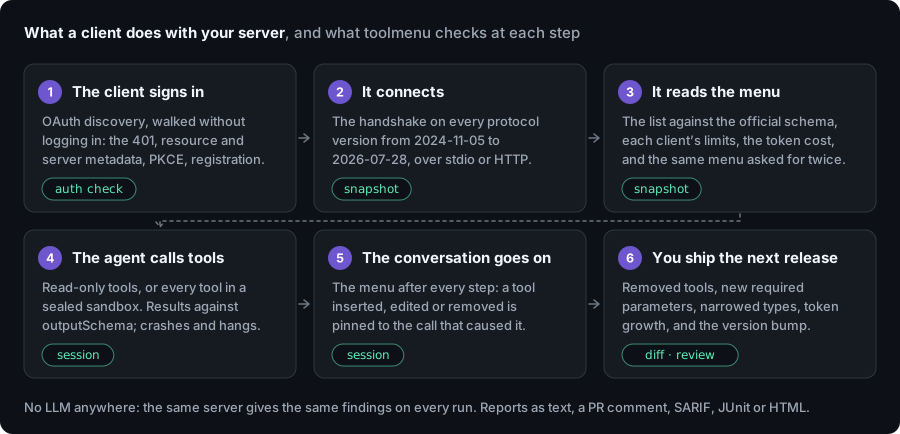
|
+
toolmenu does what a client does, in order, and checks each step against the spec, the
|
|
36
|
+
tool's own schemas and each client's documented limits:
|
|
94
37
|
|
|
95
|
-
|
|
96
|
-
npx toolmenu init -- node dist/server.js # add --with-session to also run session --auto
|
|
97
|
-
```
|
|
38
|
+
|
|
98
39
|
|
|
99
|
-
|
|
100
|
-
|
|
101
|
-
|
|
102
|
-
|
|
103
|
-
Run it anywhere in the repository. `.github/workflows/toolmenu.yml` goes to the git
|
|
104
|
-
root, and the server starts in CI from the folder you ran `init` in, which is also
|
|
105
|
-
where `menu.json` is saved. That's how a monorepo package works: run `init` in
|
|
106
|
-
`packages/server`. Paths to files in the repository are made relative, so they work on
|
|
107
|
-
the runner. `init` lists anything that won't work there (a file outside the
|
|
108
|
-
repository, a `localhost` URL, a virtualenv the runner doesn't have), each with what
|
|
109
|
-
to do.
|
|
110
|
-
|
|
111
|
-
By hand:
|
|
40
|
+
No LLM is involved, so the same server gives the same findings on every run and it fits
|
|
41
|
+
in CI. It doesn't tell you whether an agent picks the right tool; that takes evals with a
|
|
42
|
+
model ([what it can't catch](#what-it-cant-catch)).
|
|
112
43
|
|
|
113
44
|
```sh
|
|
114
|
-
npx toolmenu snapshot -- node dist/server.js
|
|
115
|
-
npx toolmenu
|
|
116
|
-
npx toolmenu session --auto -- node dist/server.js # call read-only tools, watch the menu
|
|
45
|
+
npx toolmenu snapshot -- node dist/server.js # or: npx toolmenu snapshot https://example.com/mcp
|
|
46
|
+
npx toolmenu init -- node dist/server.js # CI: a baseline, a workflow, a comment on every PR
|
|
117
47
|
```
|
|
118
48
|
|
|
119
|
-
|
|
120
|
-
|
|
121
|
-
browser, and `snapshot` and `session` use that login from then on, refreshing it as
|
|
122
|
-
needed:
|
|
49
|
+
Needs Node 22 or later. Your server can be in any language: toolmenu starts it (stdio)
|
|
50
|
+
or connects to it (HTTP).
|
|
123
51
|
|
|
124
|
-
|
|
125
|
-
npx toolmenu auth login https://mcp.example.com/mcp
|
|
126
|
-
npx toolmenu snapshot https://mcp.example.com/mcp
|
|
127
|
-
```
|
|
52
|
+
|
|
128
53
|
|
|
129
|
-
|
|
130
|
-
|
|
131
|
-
|
|
132
|
-
`--client-secret`). Over SSH or in a container, `auth login --no-browser` prints the
|
|
133
|
-
login URL instead of opening it: open it on any device, sign in, and paste back the
|
|
134
|
-
address the browser ends on (a `localhost` page that doesn't load is expected). In
|
|
135
|
-
CI, where nobody can sign in, pass a token as a header.
|
|
136
|
-
Both protocol generations are supported: 2026-07-28 (`server/discover`, stateless)
|
|
137
|
-
and the 2025 `initialize` handshake, through the official TypeScript SDK.
|
|
138
|
-
|
|
139
|
-
Every finding and error says what's wrong, where, what toolmenu saw, and ends in a
|
|
140
|
-
`→ Next:` step. Findings marked `· unsure` are heuristics (names and words): they say
|
|
141
|
-
what was seen, not what it means. `toolmenu explain <rule>` says what a rule checks,
|
|
142
|
-
its default level and how to change it (every rule is in [docs/RULES.md](docs/RULES.md)).
|
|
143
|
-
Every command has its own help: `toolmenu history --help`.
|
|
144
|
-
|
|
145
|
-
Behind a proxy (`HTTPS_PROXY`), stdio servers get the proxy and CA settings
|
|
146
|
-
(`HTTPS_PROXY`, `NO_PROXY`, `NODE_EXTRA_CA_CERTS`, `SSL_CERT_FILE`, `REQUESTS_CA_BUNDLE`…)
|
|
147
|
-
along with the minimal environment, and `NODE_USE_ENV_PROXY=1` so a Node server's
|
|
148
|
-
`fetch` uses the proxy. Without them a server that calls an API can't reach it, and
|
|
149
|
-
fails as if it were broken.
|
|
150
|
-
|
|
151
|
-
### Every server you use: `scan`
|
|
54
|
+
**Contents:** [What it catches](#what-it-catches) · [A finding](#what-a-finding-looks-like) ·
|
|
55
|
+
[In CI](#in-ci-one-pr-comment) · [Commands](#commands) · [Tested on real servers](#tested-on-real-servers) ·
|
|
56
|
+
[What it can't catch](#what-it-cant-catch) · [Docs](#docs)
|
|
152
57
|
|
|
153
|
-
|
|
154
|
-
npx toolmenu scan ~/Library/Application\ Support/Claude/claude_desktop_config.json
|
|
155
|
-
npx toolmenu scan .mcp.json --format markdown
|
|
156
|
-
```
|
|
58
|
+
## What it catches
|
|
157
59
|
|
|
158
|
-
|
|
159
|
-
|
|
160
|
-
text file with one server per line (a URL or a command, optionally `name<TAB>` first),
|
|
161
|
-
four at a time (`--concurrency`), and prints them side by side, then each server's
|
|
162
|
-
findings, like this:
|
|
60
|
+
Each row is something a run on real servers found
|
|
61
|
+
([docs/FINDINGS.md](https://github.com/niksa90/toolmenu/blob/main/docs/FINDINGS.md) has the versions and how to reproduce each).
|
|
163
62
|
|
|
164
|
-
|
|
165
|
-
|
|
166
|
-
|
|
167
|
-
|
|
168
|
-
|
|
169
|
-
|
|
63
|
+
| | What goes wrong | Seen on |
|
|
64
|
+
|---|---|---|
|
|
65
|
+
| **Lists and results a client rejects** | The official SDK client validates `tools/list` and every result. One bad schema and it drops the whole list; an answer that breaks the tool's own `outputSchema` becomes an error | 12 of 1,089 registry servers: 8 lose every tool, 4 lose answers |
|
|
66
|
+
| **A menu that never matches twice** | A default built from the clock, an order from a hash set, a container ID in a description. Every listing or every restart is a new menu, so cached prompts miss | PayPal (`list_transactions` dates), mcp-atlassian, Desktop Commander |
|
|
67
|
+
| **A menu that changes mid-conversation** | Most clients put tools first in the prompt, so a tool added by an "unlock" call means the conversation after it is processed again. 2026-07-28 rules per-connection menus out | One unlock re-processed 40–57K cached tokens in the author's own logs |
|
|
68
|
+
| **Releases that break callers** | Removed tools, new required parameters, narrowed types, a tool that became destructive, with the version bump the change needs | The official filesystem server made `move_file` destructive in a calendar release; Exa removed tools in patch releases |
|
|
69
|
+
| **Sign-in a strict client can't finish** | OAuth discovery that differs from the RFCs: a `resource` that isn't the server's URL, metadata that isn't there, PKCE not advertised | 12 of 79 vendor endpoints that answer 401 name a parent or slash-variant `resource` |
|
|
70
|
+
| **Tools one client can't use** | More tools than the client sends, names its API refuses or rewrites, descriptions cut before the instruction that matters | 6 servers in Docker's catalog list more than VS Code's 128 a request |
|
|
71
|
+
| **Tokens spent on nothing** | Unused `$defs`, the same schema block repeated across tools, growth per release | Notion's server: the same 9 unused `$defs` in all 24 tools, 72% of its menu |
|
|
170
72
|
|
|
171
|
-
|
|
172
|
-
|
|
173
|
-
|
|
174
|
-
makes the exit code 2, because it wasn't checked; one marked `disabled` is listed and
|
|
175
|
-
left alone. URLs are printed without their query, which can hold a key. Nothing is
|
|
176
|
-
written unless `--out-dir` names a folder for each server's menu file.
|
|
73
|
+
It also has heuristics for what agents misread (a parameter called just `id`, writes
|
|
74
|
+
with no annotations, two tools fighting over one word). Those are marked as guesses and
|
|
75
|
+
are never errors. Every rule is in [docs/RULES.md](https://github.com/niksa90/toolmenu/blob/main/docs/RULES.md).
|
|
177
76
|
|
|
178
|
-
##
|
|
77
|
+
## What a finding looks like
|
|
179
78
|
|
|
180
|
-
|
|
181
|
-
|
|
182
|
-
plugin (the server, and skills for checking a change, checking a release, and setting up CI):
|
|
79
|
+
A server whose `unlock_toolset` tool adds two tools to the menu mid-conversation, run
|
|
80
|
+
with `toolmenu session`:
|
|
183
81
|
|
|
184
82
|
```
|
|
185
|
-
|
|
186
|
-
/
|
|
83
|
+
step 3: call unlock_toolset {"toolset":"audits"} · answered · menu changed · +2 tools · list_changed received
|
|
84
|
+
ERROR session/mid-insert
|
|
85
|
+
+2 tools inserted at position 1 (list_team_audits, get_team_audit). Invalidates the cached prompt:
|
|
86
|
+
the tool list and the conversation after it are processed again.
|
|
87
|
+
cost: the whole tool list (this server's part: ~406 tokens, estimate) and the conversation after it
|
|
88
|
+
→ Next: Add new tools at the end of the list, not in the middle; better, list them from the start.
|
|
89
|
+
WARN session/unlock-coverage · unsure
|
|
90
|
+
unlock_toolset looks like it unlocks tools, and the run got through 1 of its 2 toolset values. […]
|
|
91
|
+
not unlocked: "reports"
|
|
92
|
+
→ Next: Unlock every value: session --init puts each one in the starter.
|
|
187
93
|
```
|
|
188
94
|
|
|
189
|
-
|
|
190
|
-
|
|
95
|
+
Every finding has the same parts: a **level** (`ERROR`, `WARN`, `INFO`; `--fail-on`
|
|
96
|
+
decides which fail the run), a **rule id** you can look up (`toolmenu explain
|
|
97
|
+
session/mid-insert`) or turn off in the config, **where** it happened (the step, the
|
|
98
|
+
tool, the parameter path), **what toolmenu saw**, and a **`→ Next:`** step.
|
|
99
|
+
|
|
100
|
+
How much to trust a finding depends on what it rests on, and the rule id's prefix says which:
|
|
191
101
|
|
|
192
|
-
|
|
|
102
|
+
| Rule family | What it rests on |
|
|
193
103
|
|---|---|
|
|
194
|
-
| `
|
|
195
|
-
| `
|
|
196
|
-
| `
|
|
197
|
-
| `
|
|
198
|
-
|
|
199
|
-
Each tool runs the CLI in a child process and returns its text report, so options,
|
|
200
|
-
`toolmenu.config.json` and stored OAuth logins work as they do on the command line.
|
|
201
|
-
Relative paths resolve from the folder `toolmenu mcp` runs in, or a call's `cwd`.
|
|
202
|
-
`snapshot_menu` and `check_session` start the command you give them, as the CLI does;
|
|
203
|
-
clients ask before each tool call unless you allow it. toolmenu's own menu passes its
|
|
204
|
-
checks with no findings, on both protocols and in a session (the test suite checks).
|
|
205
|
-
|
|
206
|
-
## As a library
|
|
207
|
-
|
|
208
|
-
Everything the CLI does is exported from the `toolmenu` package, with types, for test
|
|
209
|
-
suites and scripts of your own:
|
|
210
|
-
|
|
211
|
-
```js
|
|
212
|
-
import { snapshot, diffMenus, loadMenu, session, loadScenario } from 'toolmenu';
|
|
213
|
-
|
|
214
|
-
// The menu and its findings, as `toolmenu snapshot` gives them.
|
|
215
|
-
const { menu, findings } = await snapshot({ kind: 'stdio', command: 'node', args: ['dist/server.js'] });
|
|
216
|
-
// or { kind: 'http', url: 'https://example.com/mcp', headers: { Authorization: `Bearer ${token}` } }
|
|
217
|
-
|
|
218
|
-
// What changed since the committed baseline, and the version bump it needs.
|
|
219
|
-
const diff = diffMenus(await loadMenu('menu.json'), menu);
|
|
220
|
-
console.log(diff.suggestedBump, diff.tokens);
|
|
221
|
-
if (diff.findings.some((f) => f.severity === 'error')) process.exitCode = 1;
|
|
222
|
-
```
|
|
104
|
+
| `spec/`, `apps/`, `lists/schema` | The protocol: the official JSON schema for the server's version (pinned in `schemas/`), a MUST/SHOULD in the spec, or the MCP Apps extension |
|
|
105
|
+
| `diff/` | Two menus compared. A **breaking** change is one where a call that passed validation before now fails it |
|
|
106
|
+
| `session/`, `menu/`, `lists/variance`, `auth/`, `catalog/` | Behaviour toolmenu observed: the menu changing after a step, between two calls, between two processes or connections, or served to a bad credential. The finding names the step or the call |
|
|
107
|
+
| `naming/`, `ids/`, `description/`, `write/`, `search/` | How agents read the menu: names, words, descriptions. Tuned on real servers, but heuristics |
|
|
223
108
|
|
|
224
|
-
|
|
225
|
-
|
|
226
|
-
|
|
227
|
-
|
|
228
|
-
after)` returns each tool's change (`ToolChange[]`) and `runRules` runs the menu rules
|
|
229
|
-
on a menu you built. The `menu.json` format is the `Menu` type (`toolmenu: 1`);
|
|
230
|
-
a later format will bump that number. Library functions don't print or exit: that's
|
|
231
|
-
the CLI's job.
|
|
109
|
+
A finding marked **`· unsure`**, in any family, rests on names and words rather than on
|
|
110
|
+
something toolmenu saw happen (above: "looks like it unlocks tools"). It says what was
|
|
111
|
+
seen, not what it means. No LLM is involved anywhere: the same server gives the same
|
|
112
|
+
findings on every run.
|
|
232
113
|
|
|
233
114
|
## In CI: one PR comment
|
|
234
115
|
|
|
116
|
+
`npx toolmenu init -- <your server command>` snapshots the server into `menu.json` (the
|
|
117
|
+
baseline) and writes this workflow for your project (Node, Python, Go or Rust). Commit
|
|
118
|
+
both. Credentials you pass go into the workflow as `${{ secrets.… }}`, never as text.
|
|
119
|
+
|
|
235
120
|
```yaml
|
|
236
121
|
# .github/workflows/toolmenu.yml
|
|
237
122
|
on: pull_request
|
|
@@ -246,525 +131,127 @@ jobs:
|
|
|
246
131
|
- uses: actions/setup-node@v7
|
|
247
132
|
with: { node-version: 22 }
|
|
248
133
|
- run: npm ci && npm run build
|
|
249
|
-
- uses: niksa90/toolmenu@v0.
|
|
134
|
+
- uses: niksa90/toolmenu@v0.27.1
|
|
250
135
|
with:
|
|
251
136
|
command: node dist/server.js
|
|
252
137
|
baseline: menu.json # your committed snapshot
|
|
253
138
|
scenario: scenario.yml # optional: run a session too
|
|
254
139
|
```
|
|
255
140
|
|
|
256
|
-
|
|
257
|
-
|
|
258
|
-
|
|
259
|
-
("this PR adds ~1,240 tokens to every conversation"), the suggested version bump,
|
|
260
|
-
and anything `session` caught. The same report goes to the job summary.
|
|
261
|
-
|
|
262
|
-
| Input | Default | |
|
|
263
|
-
|---|---|---|
|
|
264
|
-
| `command` or `url` | | How to start the server over stdio, or its Streamable HTTP endpoint |
|
|
265
|
-
| `headers` | | HTTP headers for a `url` server, one `Name: value` per line. Use a secret for keys: `x-api-key: ${{ secrets.MCP_API_KEY }}` |
|
|
266
|
-
| `env` | | Environment variables for a `command` server, one `KEY=value` per line |
|
|
267
|
-
| `baseline` | `menu.json` | The committed snapshot to diff against |
|
|
268
|
-
| `scenario` | | A scenario to run with `session`, or `auto` to build the steps from the menu |
|
|
269
|
-
| `catalog` | `false` | `true` also diffs the operations behind a search tool (`snapshot --catalog`) |
|
|
270
|
-
| `baseline-from` | `snapshot` | `session` diffs every tool the scenario saw (the union menu), for servers whose tools appear after an unlock |
|
|
271
|
-
| `release` | `auto` | Release versions for the bump check. `auto` reads `package.json`, `pyproject.toml` or `Cargo.toml` on the base branch and the head, or compares the tag with the previous one on a tag push. Set `"1.4.0..1.5.0"` yourself, or `off` |
|
|
272
|
-
| `fail-on` | `error` | Fail the job on findings at or above this level |
|
|
273
|
-
| `comment` | `true` | Post and update the PR comment |
|
|
274
|
-
| `sarif` | | A folder to also write the findings to as SARIF, for code scanning (below) |
|
|
275
|
-
| `version` | the Action's own | toolmenu version from npm: by default the one matching the Action tag you pinned (`latest` for the newest). The Action installs toolmenu from npm, so it needs a published version |
|
|
276
|
-
|
|
277
|
-
### In the Security tab: code scanning
|
|
278
|
-
|
|
279
|
-
With `sarif`, findings also go to GitHub code scanning: alerts in the Security tab,
|
|
280
|
-
each on the line of its tool in your `menu.json`, and a code scanning check on the pull
|
|
281
|
-
request. GitHub shows an alert inline in the pull request only when that line changed in
|
|
282
|
-
it, so most stay in the Security tab and the check. Run the workflow on pushes to your
|
|
283
|
-
default branch too, so GitHub has a base to compare a pull request's alerts with. Code scanning is free for public repositories; private ones need GitHub Advanced
|
|
284
|
-
Security.
|
|
285
|
-
|
|
286
|
-
```yaml
|
|
287
|
-
on:
|
|
288
|
-
pull_request:
|
|
289
|
-
push:
|
|
290
|
-
branches: [main] # the base GitHub compares a pull request's alerts with
|
|
291
|
-
permissions:
|
|
292
|
-
contents: read
|
|
293
|
-
pull-requests: write
|
|
294
|
-
security-events: write # to upload SARIF
|
|
295
|
-
steps:
|
|
296
|
-
# … checkout, build, as above
|
|
297
|
-
- uses: niksa90/toolmenu@v0.25.2
|
|
298
|
-
with:
|
|
299
|
-
command: node dist/server.js
|
|
300
|
-
sarif: toolmenu-sarif
|
|
301
|
-
- uses: github/codeql-action/upload-sarif@v4
|
|
302
|
-
if: always() # findings fail the toolmenu step; upload them anyway
|
|
303
|
-
with:
|
|
304
|
-
sarif_file: toolmenu-sarif
|
|
305
|
-
```
|
|
306
|
-
|
|
307
|
-
Outside the Action: `toolmenu snapshot --sarif toolmenu.sarif -- node dist/server.js`
|
|
308
|
-
writes the file beside the usual report (`diff` and `session` take `--sarif` too), or
|
|
309
|
-
`--format sarif` prints it instead.
|
|
310
|
-
|
|
311
|
-
### Other CI systems: JUnit test reports
|
|
312
|
-
|
|
313
|
-
GitLab, Jenkins, Azure DevOps, CircleCI and Buildkite show JUnit XML as test results.
|
|
314
|
-
`--junit <path>` writes the findings of `snapshot`, `diff` or `session` as JUnit beside
|
|
315
|
-
the usual report (`--format junit` prints it instead). New in 0.25.2. Each finding is a test case named
|
|
316
|
-
after its tool, in a class named after its rule (`toolmenu.diff.diff/removed`), so the
|
|
317
|
-
CI system tracks it across runs. Findings at or above `--fail-on` are failures, the rest
|
|
318
|
-
pass with their text, so the test report agrees with the exit code. A clean run is one
|
|
319
|
-
passing case.
|
|
320
|
-
|
|
321
|
-
```yaml
|
|
322
|
-
# .gitlab-ci.yml
|
|
323
|
-
toolmenu:
|
|
324
|
-
image: node:22
|
|
325
|
-
script:
|
|
326
|
-
- npm ci && npm run build
|
|
327
|
-
# Exit 1 means findings: keep going so both reports are written, then fail.
|
|
328
|
-
- npx toolmenu snapshot --out new-menu.json --junit snapshot.xml -- node dist/server.js || code=$?
|
|
329
|
-
- npx toolmenu diff menu.json new-menu.json --junit diff.xml || code=$?
|
|
330
|
-
- exit ${code:-0}
|
|
331
|
-
artifacts:
|
|
332
|
-
when: always
|
|
333
|
-
reports:
|
|
334
|
-
junit: [snapshot.xml, diff.xml]
|
|
335
|
-
```
|
|
336
|
-
|
|
337
|
-
### A badge for your README
|
|
338
|
-
|
|
339
|
-
```sh
|
|
340
|
-
npx toolmenu snapshot --badge toolmenu-badge.json -- node dist/server.js
|
|
341
|
-
```
|
|
342
|
-
|
|
343
|
-
writes a [shields.io endpoint](https://shields.io/badges/endpoint-badge) file (tools,
|
|
344
|
-
tokens, and errors or warnings, in red, yellow or green) and prints the README line
|
|
345
|
-
for it. Commit it with `menu.json`: it changes when the baseline does, so nothing
|
|
346
|
-
has to commit from CI. The badge at the top of this README is toolmenu's own MCP
|
|
347
|
-
server (`toolmenu mcp`), checked by itself.
|
|
348
|
-
|
|
349
|
-
Server behind auth, or PRs from forks and Dependabot? See [docs/github-action.md](https://github.com/niksa90/toolmenu/blob/main/docs/github-action.md).
|
|
350
|
-
Server that unlocks tools on request? Snapshot the full menu for the baseline and run the session on the default one: [servers that unlock tools](https://github.com/niksa90/toolmenu/blob/main/docs/github-action.md#servers-that-unlock-tools).
|
|
351
|
-
PRs without secrets are skipped, and a skipped check still passes; the `skipped` output tells you.
|
|
141
|
+
Every pull request then gets one comment that updates on each push. It leads with a
|
|
142
|
+
verdict (can this menu replace the baseline as it is?), then the breaking changes, the
|
|
143
|
+
token change, the version bump the change needs, and anything `session` caught:
|
|
352
144
|
|
|
353
|
-
|
|
354
|
-
|
|
355
|
-
|
|
356
|
-
after every step, and reports each change with the step that caused it.
|
|
357
|
-
|
|
358
|
-
```yaml
|
|
359
|
-
# scenario.yml
|
|
360
|
-
allow_writes: false # refuse to call tools not marked readOnlyHint
|
|
361
|
-
steps:
|
|
362
|
-
- list
|
|
363
|
-
- call: search_forms
|
|
364
|
-
args: { query: onboarding }
|
|
365
|
-
- call: unlock_toolset
|
|
366
|
-
args: { toolset: audits }
|
|
367
|
-
- wait_for: tools_list_changed # optional; timeout_ms defaults to 5000
|
|
368
|
-
```
|
|
145
|
+
<p align="center">
|
|
146
|
+
<img src="https://raw.githubusercontent.com/niksa90/toolmenu/main/docs/review-comment.png" width="760" alt="toolmenu's review of two real releases of the official filesystem server, as markdown: don't accept as is, 1 breaking change (move_file is now destructive), suggested bump major, +24 tokens">
|
|
147
|
+
</p>
|
|
369
148
|
|
|
370
|
-
|
|
371
|
-
|
|
372
|
-
|
|
373
|
-
name, a description that says it enables or loads tools), the starter unlocks
|
|
374
|
-
**every** value, listing after each, then repeats the first, so the session sees every
|
|
375
|
-
tool behind the unlock. The values come from the parameter's enum or, without one,
|
|
376
|
-
from the server's own read-only listing (`list_toolsets`). Lookups that only describe
|
|
377
|
-
toolsets (`list_toolsets`, `get_toolset_tools`) aren't unlocks, and one not marked
|
|
378
|
-
read-only is suggested, never called. Anything it can't fill in is left as a
|
|
379
|
-
commented-out step. An unlock nothing in the menu names, like joining a room that
|
|
380
|
-
brings more tools, needs a step you add yourself. A scenario is only as good as its
|
|
381
|
-
steps, so the starter is a floor, not a ceiling.
|
|
382
|
-
|
|
383
|
-
On github-mcp-server 1.0.5 with `--dynamic-toolsets` (3 tools at the start, 19
|
|
384
|
-
toolsets), unlocking every toolset reaches 107 tools: all 81 that `--toolsets all`
|
|
385
|
-
serves, and 23 issue and pull-request tools that only the dynamic mode has.
|
|
386
|
-
|
|
387
|
-
| Rule | Default | Catches |
|
|
388
|
-
|---|---|---|
|
|
389
|
-
| `session/mid-insert`, `session/reorder`, `session/remove`, `session/edit` | error | The menu changing mid-session anywhere but the end, with where the change starts and which value changed. Any change to the tool list invalidates the cached prompt: the whole tool list (its size, estimated) and the conversation after it are processed again |
|
|
390
|
-
| `session/append` | warn | Tools added at the end of the list. Still a cache miss for the conversation when your client sends tools at the start of the prompt (Claude's Messages API does); cache-safe only when the client adds new tools after the cached content, as tool search (deferred loading) does |
|
|
391
|
-
| `session/connection-local` | error on 2026-07-28 (HTTP) | A change only this connection sees. 2026-07-28: the tool set MUST NOT vary "per-connection or as a side effect of other requests on the connection" |
|
|
392
|
-
| `session/side-effect` | warn on 2026-07-28 (stdio) | The same, where stdio can't tell per-connection from global |
|
|
393
|
-
| `menu/process-variance`, `menu/connection-variance` | error | Checked before the first step, as in `snapshot` (below) |
|
|
394
|
-
| `session/unannounced` | warn | The menu changed without `notifications/tools/list_changed`, although the server declared `listChanged` |
|
|
395
|
-
| `session/untested` | warn, error if no call got through | Calls that failed before reaching the tool: authentication, something missing on this machine (no Chrome), the network. One finding for the run, not one per step, so an expired CI secret doesn't pass a run that tested nothing |
|
|
396
|
-
| `session/refused`, `session/step-failed` | error | A write the scenario didn't allow, or a call that failed for another reason |
|
|
397
|
-
| `session/tool-error` | warn | A tool that answered with an error for another reason (`isError`): the run tested less than it looks. The same error at several steps is one finding that names them |
|
|
398
|
-
| `session/known-variance` | info | A mid-session change only in values that already vary from one tools/list to the next: same cause as the finding it names, not counted again |
|
|
399
|
-
| `session/assumed-read-only` | info | Tools called on your word (`--assume-read-only`, `assume_read_only`) although the server doesn't mark them readOnlyHint |
|
|
400
|
-
| `session/unlock-coverage` | warn | An unlock whose enum lists its values, called with only some of them: the tools behind the rest were never seen, so a baseline from the session misses them. With `--union-out` or `--auto`, an unlock never called at all too, with why `--auto` skipped it |
|
|
401
|
-
| `session/nothing-called` | warn | `--auto` called no tools (all open-world, missing values, or not read-only): the run only listed the menu |
|
|
402
|
-
| `session/session-lost` | error | The server ended the session after toolmenu opened a second connection with the same credentials (servers with one session per client; 2025-era servers only). The run stops there; rerun with `--processes 1` |
|
|
403
|
-
| `session/handle-error` | warn | 2026-07-28: `--auto` called a read-only tool with a handle that can't exist (`toolmenu-unknown-session`), and it answered with a protocol error instead of a tool error the model can read |
|
|
404
|
-
| `session/error-not-flagged` | warn | A tool answered with an HTTP error from the API behind it (`{"status":401,"object":"error",…}`) as a plain result, not marked `isError`, so a client that reads `isError` takes the call for a success (Notion's server). An auth one also counts toward `session/untested`. Tools that take a URL are left out: their answer is the page's (heuristic) |
|
|
405
|
-
| `session/server-unresponsive` | error | The server stopped answering after a step: even `tools/list` timed out. The run stops there with this one finding, instead of every later step waiting out its timeout (a server that polls a device-code sign-in inside a tool call) |
|
|
406
|
-
| `session/handle-roundtrip` | warn | With `--create-handles`: the tool that creates a session, basket or cart was called, and the tools that take it back refused the handle it had just returned (info when its result had no handle to find) |
|
|
407
|
-
| `session/rate-limited` | error | The server kept refusing requests for being too many (a 429) after toolmenu waited about a minute, or a tool not marked `readOnlyHint` said it was rate-limited (it isn't called again). The run stops there, with the steps it didn't check; give the run its own server instance or raise the limit for it |
|
|
408
|
-
| `session/scope-unchecked` | info | A second server process or connection couldn't start mid-session (a server that holds a file or a port), so whether a change was global wasn't checked. Said once for the run |
|
|
409
|
-
|
|
410
|
-
**No scenario? `session --auto`** builds the steps from the menu: every read-only tool
|
|
411
|
-
whose required arguments the schema itself gives (a `default`, `examples`, an `enum`,
|
|
412
|
-
a type or format), cheapest first, then every value of each read-only unlock (outside
|
|
413
|
-
`--max-calls`, and the first value twice: a second identical unlock should change
|
|
414
|
-
nothing), then the first call again. It never guesses an ID: a tool that needs
|
|
415
|
-
`owner`, `repo` or an issue key is skipped, and the report names the flag that fills
|
|
416
|
-
it: `--value repo_path=/src/app` fills that parameter on every tool that requires it,
|
|
417
|
-
`--value get_issue.issue_key=ABC-1` on one tool, `--values-file values.yml` takes a map
|
|
418
|
-
of either. Servers that don't mark their tools `readOnlyHint` (DeepWiki, every
|
|
419
|
-
2024-11-05 server) get nothing called unless you vouch for them by name:
|
|
420
|
-
`--assume-read-only read_wiki_structure,ask_wiki_question`. Only exact names are
|
|
421
|
-
accepted: a pattern would also cover tools a later release adds. A tool marked or
|
|
422
|
-
named as a write is never called, and the report says which tools ran on your word.
|
|
423
|
-
With `--create-handles` on 2026-07-28, `--auto` also calls the tool that creates a
|
|
424
|
-
session, basket or cart (`start_session`; a write, so only with the flag, and never
|
|
425
|
-
one marked `destructiveHint`; not locks, leases or checkouts) and gives the tools that
|
|
426
|
-
take it back the handle it returned, beside the made-up one.
|
|
427
|
-
`--save-scenario auto.yml` writes the steps, with the skipped tools commented out, for
|
|
428
|
-
you to fill in. Tools marked `openWorldHint: true` (web
|
|
429
|
-
search, fetch, scraping, which can cost API credits) are called only with
|
|
430
|
-
`--open-world`, except unlocks: changing the menu is what a session watches, and an
|
|
431
|
-
unlock spends no search credits, so it runs even on a server that marks every tool
|
|
432
|
-
open-world. A run that ends up calling nothing is `session/nothing-called` (warn),
|
|
433
|
-
with why each tool was left out, not a clean pass. On the 22 servers in `bench/`,
|
|
434
|
-
`--auto` reaches 60 of 262 read-only tools, 84 with `--open-world`.
|
|
435
|
-
|
|
436
|
-
**`session` calls tools for real.** Without `allow_writes: true` it refuses any tool
|
|
437
|
-
not marked `readOnlyHint: true`. `--plan` prints the steps without connecting.
|
|
438
|
-
|
|
439
|
-
## `diff`: compare releases
|
|
149
|
+
That's `toolmenu review --format markdown` on two real releases of the official
|
|
150
|
+
filesystem server. The same findings go to GitHub code scanning (SARIF), to GitLab,
|
|
151
|
+
Jenkins and others as JUnit, or into one offline HTML page:
|
|
440
152
|
|
|
441
|
-
|
|
442
|
-
|
|
443
|
-
|
|
153
|
+
<p align="center">
|
|
154
|
+
<img src="https://raw.githubusercontent.com/niksa90/toolmenu/main/docs/report.png" width="760" alt="toolmenu's HTML report of a session: 3 errors, 2 warnings, the menu after each step with inserted tools marked, and each finding with its next step">
|
|
155
|
+
</p>
|
|
444
156
|
|
|
445
|
-
|
|
446
|
-
|
|
447
|
-
|
|
448
|
-
changes 1 breaking (1 tool) · 0 minor · 3 notice (13 tools)
|
|
449
|
-
version suggested bump: major · not checked (calendar version)
|
|
450
|
-
tokens ~1,640 → ~1,664 (+24, estimate): this release adds ~24 tokens to every conversation that loads the menu
|
|
451
|
-
tools 14 → 14
|
|
452
|
-
|
|
453
|
-
ERROR diff/safety-hint
|
|
454
|
-
`move_file` was marked additive-only and is now destructive (destructiveHint false → true; unset means destructive). Clients that auto-approve additive tools may now ask first.
|
|
455
|
-
→ Next: If the tool still never deletes or overwrites, set destructiveHint: false; if it does now, say so in the release notes.
|
|
456
|
-
INFO diff/annotations
|
|
457
|
-
Annotations changed the same way (openWorldHint (unset) → false) in 13 of 14 tools: read_file, read_text_file, read_media_file, read_multiple_files, write_file, edit_file, … (+7).
|
|
458
|
-
…
|
|
459
|
-
```
|
|
157
|
+
Inputs, servers behind auth, forks and `gate: review` are in
|
|
158
|
+
[docs/github-action.md](https://github.com/niksa90/toolmenu/blob/main/docs/github-action.md); SARIF, JUnit, HTML and the badge in
|
|
159
|
+
[docs/ci.md](https://github.com/niksa90/toolmenu/blob/main/docs/ci.md).
|
|
460
160
|
|
|
461
|
-
|
|
462
|
-
promise nothing about compatibility, so the bump isn't judged, but the breaking change
|
|
463
|
-
is still an error. Changes are classified
|
|
464
|
-
the way OpenAPI breaking-change checkers do it:
|
|
161
|
+
## Commands
|
|
465
162
|
|
|
466
|
-
|
|
|
163
|
+
| Command | What it does | |
|
|
467
164
|
|---|---|---|
|
|
468
|
-
|
|
|
469
|
-
|
|
|
470
|
-
|
|
|
471
|
-
|
|
472
|
-
|
|
473
|
-
|
|
474
|
-
|
|
475
|
-
|
|
476
|
-
|
|
477
|
-
|
|
478
|
-
|
|
479
|
-
|
|
480
|
-
`--
|
|
481
|
-
|
|
482
|
-
|
|
483
|
-
|
|
484
|
-
|
|
485
|
-
|
|
486
|
-
|
|
487
|
-
|
|
488
|
-
|
|
489
|
-
|
|
490
|
-
|
|
491
|
-
|
|
492
|
-
|
|
493
|
-
|
|
494
|
-
|
|
495
|
-
|
|
496
|
-
|
|
497
|
-
|
|
498
|
-
|
|
499
|
-
|
|
500
|
-
|
|
501
|
-
|
|
502
|
-
breaking. Every breaking finding's next step names the version to release when the
|
|
503
|
-
bump is too small.
|
|
504
|
-
|
|
505
|
-
It also reports the token change per tool and suggests a semver bump. To check the
|
|
506
|
-
bump, pass the **release** versions: `--release 1.4.0..1.5.0` (npm, a git tag).
|
|
507
|
-
`diff/version-bump` then warns when the release's bump is smaller. Under 1.0.0 it
|
|
508
|
-
reads versions as npm's caret does (`^0.2.3` accepts any 0.2.x): breaking changes need
|
|
509
|
-
a minor bump, new features a patch, and under 0.1.0 anything goes.
|
|
510
|
-
`diff/version-backwards` warns when the version goes down. Calendar versions and prereleases aren't judged. The version in the snapshot is what the
|
|
511
|
-
server reports (`serverInfo.version`), which is often not the release: the filesystem
|
|
512
|
-
server has said `0.2.0` for 19 releases (FINDINGS F5). It's shown, and only checked
|
|
513
|
-
with `--server-version-is-release`. `diff` also enforces an optional `tokenBudget`
|
|
514
|
-
(`diff/token-budget`). Order changes are only a notice here: between releases, prompt caches rebuild. Order
|
|
515
|
-
matters *within* a session.
|
|
516
|
-
|
|
517
|
-
### Operations behind a search tool (`--catalog`)
|
|
518
|
-
|
|
519
|
-
Big servers increasingly keep most operations out of the menu: a small fixed menu, a
|
|
520
|
-
search tool, and an execute tool (Sentry's `search_sentry_tools` + `execute_sentry_tool`,
|
|
521
|
-
Atlassian's `discover` + `executeRead`). A breaking change to one of those operations
|
|
522
|
-
never shows in the menu. `snapshot --catalog` asks the search tool a fixed set of
|
|
523
|
-
queries and keeps the operations it returns in `menu.json`; `diff` then compares
|
|
524
|
-
operations found in both snapshots with the same rules as tools.
|
|
525
|
-
|
|
526
|
-
```sh
|
|
527
|
-
npx toolmenu snapshot --catalog -- node dist/server.js
|
|
528
|
-
```
|
|
529
|
-
|
|
530
|
-
A search returns only its top matches, so toolmenu crawls the catalog by its own
|
|
531
|
-
words: it starts from the search tool's own example phrases and the nouns in your tool
|
|
532
|
-
names, then searches for every operation it finds or sees mentioned, until 20 queries
|
|
533
|
-
in a row turn up nothing new (at most 200). On Atlassian's hosted server that finds all
|
|
534
|
-
154 operations behind its 21 tools; on Sentry's, 65 behind 9, the same on every run.
|
|
535
|
-
Queries are paced and a rate limit is waited out. An operation not found this time is a
|
|
536
|
-
notice (`diff/catalog-missing`: "not returned by the same queries"), never "removed";
|
|
537
|
-
one found only now is `diff/catalog-added`, and catalogs read with different queries,
|
|
538
|
-
or partly (a query failed), are `diff/catalog-queries`. To steer it, set
|
|
539
|
-
`"catalog": { "queries": [...], "maxQueries": 200, "crawl": true }` in
|
|
540
|
-
`toolmenu.config.json` (FINDINGS F15).
|
|
541
|
-
|
|
542
|
-
A crawl through search is a lower bound, not a proof: an operation that nothing in the
|
|
543
|
-
catalog names, and whose words no query uses, stays unfound. On `@sentry/mcp-server`
|
|
544
|
-
0.42 (stdio) it finds 63 of the 64 operations in the package's catalog; `whoami` comes
|
|
545
|
-
back only when asked for by name. Add queries like that to `catalog.queries`.
|
|
546
|
-
|
|
547
|
-
**Command routers.** Some servers put their operations behind router tools instead:
|
|
548
|
-
one tool per area that takes a `command` and its `parameters`, and lists its commands
|
|
549
|
-
when called with `learn: true` (Azure's MCP server serves 71 such tools in front of
|
|
550
|
-
~410 operations). `--catalog` detects them (a `command` parameter, an arguments
|
|
551
|
-
object, a boolean listing flag, and a description that says "router" or "sub
|
|
552
|
-
commands") and calls each once in its listing mode, never with a command, so nothing
|
|
553
|
-
runs. Routers whose command is required aren't called. Detection missed one? Name
|
|
554
|
-
them: `"catalog": { "routers": ["keyvault", "storage"] }`. A router lists everything
|
|
555
|
-
it has, so unlike a search the catalog is complete except for routers that failed
|
|
556
|
-
(`catalog/failed` says which, and why).
|
|
557
|
-
|
|
558
|
-
## `history`: a package's releases, researched
|
|
559
|
-
|
|
560
|
-
```sh
|
|
561
|
-
npx toolmenu history @modelcontextprotocol/server-filesystem --versions 19 --arg /tmp --csv fs.csv
|
|
562
|
-
```
|
|
563
|
-
|
|
564
|
-
It installs each published version into a temp directory (install scripts off),
|
|
565
|
-
snapshots it, and diffs it against the previous version that worked. For every
|
|
566
|
-
version it records the protocol, the menu, the findings and the **dependency
|
|
567
|
-
versions that actually got installed**: an old version installed today resolves its
|
|
568
|
-
dependencies today, and can serve a different menu than it shipped with.
|
|
569
|
-
|
|
570
|
-
It's best effort: packages that need env vars, arguments or auth are recorded as
|
|
571
|
-
failed, with a reason, never skipped. **It installs and runs third-party code. Run it
|
|
572
|
-
in a container.**
|
|
573
|
-
|
|
574
|
-
## Where the tokens go
|
|
575
|
-
|
|
576
|
-
`snapshot` also shows what the menu's tokens are spent on: the biggest tools (split
|
|
577
|
-
into description and schema), large enums, and waste you can remove:
|
|
578
|
-
|
|
579
|
-
- **Repeated blocks**: the same piece of schema at several places, inside one tool (a
|
|
580
|
-
`$defs` entry could hold it once: "one ~230-token block ×5 in
|
|
581
|
-
content_generateMessageHtml") or across tools (paid once per tool: mongodb-mcp-server
|
|
582
|
-
3.0.4 repeats a ~2,200-token `pipeline` schema in 3 tools). Only the largest repeated
|
|
583
|
-
block is named, not the pieces inside it.
|
|
584
|
-
- **Unused `$defs`**: definitions nothing in the tool refers to. Notion's server 2.5.2
|
|
585
|
-
ships the same 9 in all 24 tools, 72% of its menu.
|
|
586
|
-
|
|
587
|
-
Every tool's estimate is in the menu file, for the ones the summary leaves out:
|
|
588
|
-
`jq -r '.tools[] | "\(.tokens)\t\(.name)"' menu.json | sort -rn`.
|
|
589
|
-
|
|
590
|
-
## `snapshot` rules
|
|
591
|
-
|
|
592
|
-
Every rule comes from a failure I actually hit building 115 tools for one MCP
|
|
593
|
-
server, or from the spec itself. If a rule can't point to one, it doesn't ship.
|
|
594
|
-
|
|
595
|
-
| Rule | Default | Catches |
|
|
165
|
+
| `snapshot` | Connects, lists the menu, checks it (the spec, a second process, your client's limits, token cost) and writes `menu.json` | [docs](https://github.com/niksa90/toolmenu/blob/main/docs/snapshot.md) |
|
|
166
|
+
| `session` | Plays a scenario, or builds one with `--auto`: calls tools, checks every result, and lists the menu after each step. Read-only tools unless you allow writes; `--call-everything` calls every tool, for a server in a sandbox | [docs](https://github.com/niksa90/toolmenu/blob/main/docs/session.md) |
|
|
167
|
+
| `diff` | Compares two menu files: breaking, minor, notice; token change; the semver bump | [docs](https://github.com/niksa90/toolmenu/blob/main/docs/diff.md) |
|
|
168
|
+
| `review` | Should the new menu replace the baseline? One verdict and an exit code | [docs](https://github.com/niksa90/toolmenu/blob/main/docs/diff.md#accepting-a-new-baseline-review) |
|
|
169
|
+
| `auth check` | Walks an HTTP server's OAuth discovery as a spec-following client does, without logging in | [docs](https://github.com/niksa90/toolmenu/blob/main/docs/usage.md#http-servers-and-oauth) |
|
|
170
|
+
| `auth login` | Signs in to a server behind OAuth once, in a browser; `snapshot` and `session` then use that login | [docs](https://github.com/niksa90/toolmenu/blob/main/docs/usage.md#http-servers-and-oauth) |
|
|
171
|
+
| `scan` | `snapshot` on every server in a client config (Claude Desktop, `.mcp.json`, Cursor, VS Code), side by side | [docs](https://github.com/niksa90/toolmenu/blob/main/docs/snapshot.md#every-server-you-use-scan) |
|
|
172
|
+
| `history` | Installs a package's published versions one by one and diffs them. Runs third-party code: use a container | [docs](https://github.com/niksa90/toolmenu/blob/main/docs/diff.md#history-a-packages-releases-researched) |
|
|
173
|
+
| `init` | Writes the baseline and the CI workflow | [above](#in-ci-one-pr-comment) |
|
|
174
|
+
| `mcp` | toolmenu as an MCP server and a Claude Code plugin, so the agent building your server can check it while it works | [docs](https://github.com/niksa90/toolmenu/blob/main/docs/usage.md#for-the-agent-building-your-server-mcp) |
|
|
175
|
+
| `explain <rule>` | What a rule checks, its default level and how to change it | [RULES](https://github.com/niksa90/toolmenu/blob/main/docs/RULES.md) |
|
|
176
|
+
|
|
177
|
+
`--client <name>` checks the menu for one client, from that client's own docs: Claude
|
|
178
|
+
Code, the Claude API, OpenAI, Codex, VS Code (Copilot Chat), Copilot cloud agent and code
|
|
179
|
+
review, Gemini CLI, the Gemini API or Antigravity ([docs](https://github.com/niksa90/toolmenu/blob/main/docs/clients.md)). A client
|
|
180
|
+
that doesn't document a limit doesn't get one: Cursor's and Windsurf's aren't checked.
|
|
181
|
+
|
|
182
|
+
`session` calls tools for real. Without `allow_writes: true` it refuses any tool not
|
|
183
|
+
marked `readOnlyHint: true`, and `--call-everything` is refused over HTTP, because a
|
|
184
|
+
hosted server's tools act on someone's real account.
|
|
185
|
+
|
|
186
|
+
Everything is also exported as a library, with types
|
|
187
|
+
([docs](https://github.com/niksa90/toolmenu/blob/main/docs/usage.md#as-a-library)). All protocol versions from 2024-11-05 to
|
|
188
|
+
2026-07-28 are supported, through the official TypeScript SDK; the table in
|
|
189
|
+
[docs/PROTOCOLS.md](https://github.com/niksa90/toolmenu/blob/main/docs/PROTOCOLS.md) is written by a test that runs each one.
|
|
190
|
+
|
|
191
|
+
## Tested on real servers
|
|
192
|
+
|
|
193
|
+
Rules are checked against public MCP servers before they ship, and a rule that changes
|
|
194
|
+
a finding on one has to say why in the [changelog](CHANGELOG.md). The run on 2026-11-09
|
|
195
|
+
is the baseline for a weekly one ([`bench/scripts/weekly.sh`](bench/scripts/weekly.sh)),
|
|
196
|
+
which compares each week with the last:
|
|
197
|
+
|
|
198
|
+
| Panel | Servers | What ran |
|
|
596
199
|
|---|---|---|
|
|
597
|
-
|
|
|
598
|
-
|
|
|
599
|
-
|
|
|
600
|
-
|
|
|
601
|
-
| `spec/tools-capability` | error | The server doesn't declare the `tools` capability, so clients (the official SDK included) never ask for its tools |
|
|
602
|
-
| `menu/duplicate-name` | error | Two tools with the same name: only one can be called, and some clients reject the list |
|
|
603
|
-
| `naming/route` | error | A `routes.yml` expectation broke: a keyword now matches the wrong tool at least as well as the right one |
|
|
604
|
-
| `description/buried` | warn | Instructions to the agent ("use X instead", "don't retry", "never guess one") past the point where your client cuts descriptions: in Claude Code 16,384 characters for a tool loaded through tool search (its default) and 4,096 for one that loads up front, or your `descriptionLimit`. From a real failure: a client cut at 280 characters, and the line that decided routing was at 1,222 |
|
|
605
|
-
| `description/cut` | info | Descriptions longer than the client sends, with nothing that reads as an instruction past the cut, as one summary that shows where each one is cut. The model gets a prefix that can read as complete |
|
|
606
|
-
| `description/late-instruction` | info | With the default cut: instructions after character 280, which a client that cuts descriptions short would hide, as one summary. Set `descriptionLimit` and `description/buried` checks your real cut instead. (Before 0.13 this was part of `description/cut`; that id's setting still applies.) |
|
|
607
|
-
| `naming/vague-id` | warn | Parameters called just `id` that don't say *which* thing, as one summary with a suggested name |
|
|
608
|
-
| `ids/authored` | info | An ID the agent must supply that no tool appears to return, so the agent may invent it, one finding per kind of ID (heuristic: IDs from a URL or another tool's text output look the same) |
|
|
609
|
-
| `ids/handle-lifetime` | info | 2026-07-28: a tool that creates a handle another tool takes back (`start_session` → `session_id`) doesn't say how long it lasts (heuristic) |
|
|
610
|
-
| `write/unannotated` | warn | Tools named like writes (`delete_`, `send_`…) with no annotations, as one summary grouped by the annotation each name suggests |
|
|
611
|
-
| `naming/shared-word` | info | Nouns that name different things across tools (`list_team_audits` vs `get_audit_trail`), as one summary |
|
|
612
|
-
| `write/read-only-mismatch` | warn | A tool marked `readOnlyHint: true` whose name says it writes (`create_my_account`): clients act on the hint, and `--auto` doesn't call it on the hint alone (heuristic) |
|
|
613
|
-
| `write/no-dry-run` | info | Destructive tools with no dry-run parameter or preview tool, as one summary |
|
|
614
|
-
| `spec/discover` | info | The server only speaks the 2025 protocol, so 2026-07-28 rules are skipped |
|
|
615
|
-
| `spec/deprecated`, `spec/cache-hints` | info | 2026-07-28: deprecated features still advertised; `ttlMs: 0`, or `cacheScope: "public"` on a server that took credentials |
|
|
616
|
-
| `lists/variance` | warn | With `--lists`: `prompts/list`, `resources/list` or `resources/templates/list` differs between two calls, or from a second process or connection (2026-07-28: lists no longer vary per connection) |
|
|
617
|
-
| `lists/schema` | error | With `--lists`: a list result that doesn't match the official schema (2026-07-28 requires `ttlMs` and `cacheScope` on each), or a declared list that fails to answer (warn; info for Method not found, or a setup failure such as missing credentials) |
|
|
618
|
-
| `naming/client-name` | warn | With `--client`: tool names the client's API refuses: `^[a-zA-Z0-9_-]{1,128}$` for the Claude API, `^[a-zA-Z0-9_-]+$` up to 128 for OpenAI's functions. MCP allows names such as `files.read` that neither takes as they are |
|
|
619
|
-
| `menu/auth-variance` | info | With `--as` (or `identities` in the config): the tool set differs by identity, what each adds, lacks or defines differently against the first, and its tokens. Allowed by the spec; a baseline of one identity's menu doesn't cover the others. An identity that can't be listed is said here too |
|
|
620
|
-
| `spec/cache-scope-public` | warn | 2026-07-28, with `--as`: the tool set differs by identity, and `tools/list` says `cacheScope: "public"`, which lets shared caches serve one caller's list to another |
|
|
621
|
-
| `menu/capability-dependent` | info | Tools a server lists only to a client that supports elicitation, or only to one that doesn't. `snapshot` lists as a client with elicitation, so the menu file holds those tools (github-mcp-server 1.14 lists `delete_repository` only to a client that can ask the user to confirm; before 0.22 a baseline missed it), and once more without |
|
|
622
|
-
| `menu/network-dependent` | warn | With `--offline-check` (stdio): the menu listed once more with the network cut off (the proxy variables pointed at a closed port, loopback left alone) differs: inite-visibility serves 3 tools offline and 10 online, so a baseline made with the network doesn't match a machine without it. A server that doesn't start offline is info. A server that ignores the proxy variables still reaches the network where the machine has it directly; then nothing is reported, which isn't a pass |
|
|
623
|
-
| `auth/invalid-accepted` | warn | HTTP with credentials: the menu listed once more with an invalid credential in the same scheme. A server that serves a menu to it, not 401, gives a client whose token expired no reason to log in again; the agent just has fewer tools (Atlassian Rovo served 4 tools to any `Authorization` header). `--processes 1` turns it off |
|
|
624
|
-
|
|
625
|
-
The full list, `diff` and `session` rules included, is [docs/RULES.md](docs/RULES.md).
|
|
626
|
-
|
|
627
|
-
The naming and ID rules are heuristics, tuned on real servers (FINDINGS F7 and
|
|
628
|
-
F10) and a private 115-tool one. They're the extras; the change checks are the point.
|
|
629
|
-
|
|
630
|
-
**Pin routing with `routes.yml`.** Two tools fighting over one word needs a regression
|
|
631
|
-
test, not a rename you'll forget:
|
|
632
|
-
|
|
633
|
-
```yaml
|
|
634
|
-
audit:
|
|
635
|
-
must_match: [list_team_audits]
|
|
636
|
-
must_not_match: [get_audit_trail]
|
|
637
|
-
audit trail:
|
|
638
|
-
must_not_match: [get_store_scores] # on its own: must not match at all
|
|
639
|
-
```
|
|
640
|
-
|
|
641
|
-
Matching is keyword matching, the way a keyword or BM25 tool search sees the menu: a
|
|
642
|
-
tool matches if every word of the route is in its name or description (the exact
|
|
643
|
-
phrase scores higher). It can't read "not", and neither can those searches: a
|
|
644
|
-
disclaimer like "not the audit trail" puts "audit trail" into exactly the tool you
|
|
645
|
-
meant to steer away from, and toolmenu says so.
|
|
646
|
-
|
|
647
|
-
**Config** (optional `toolmenu.config.json`):
|
|
648
|
-
|
|
649
|
-
```json
|
|
650
|
-
{
|
|
651
|
-
"rules": { "naming/shared-word": "off", "ids/authored": "error" },
|
|
652
|
-
"ignore": ["debug_*"],
|
|
653
|
-
"routes": "routes.yml",
|
|
654
|
-
"tokenBudget": 4000,
|
|
655
|
-
"descriptionLimit": "claude-code",
|
|
656
|
-
"fullDescriptions": ["search_capabilities", "lookup_*"],
|
|
657
|
-
"offlineCheck": true
|
|
658
|
-
}
|
|
659
|
-
```
|
|
660
|
-
|
|
661
|
-
`offlineCheck` turns on `--offline-check` for every `snapshot` of a stdio server.
|
|
662
|
-
|
|
663
|
-
`descriptionLimit` is where your client cuts tool descriptions: a number, or a client
|
|
664
|
-
whose cut has been reported: `"claude-code"` (the default: Claude Code's own docs,
|
|
665
|
-
[code.claude.com/docs/en/mcp](https://code.claude.com/docs/en/mcp), read 2026-11-02:
|
|
666
|
-
16,384 characters for a tool loaded through tool search, which is on by default, and
|
|
667
|
-
4,096 for a tool that loads up front, marked `_meta["anthropic/alwaysLoad"]: true`;
|
|
668
|
-
the cut was 2,048 before v2.1.296), `"claude-code-upfront"` (4,096 for every tool:
|
|
669
|
-
Claude Code with tool search off) or
|
|
670
|
-
`"amazon-q"` (10,024, reported in
|
|
671
|
-
[makenotion/notion-mcp-server#145](https://github.com/makenotion/notion-mcp-server/issues/145)).
|
|
672
|
-
Clients that send descriptions in full don't need a setting beyond that. If your own
|
|
673
|
-
client cuts shorter, as mine did at 280, set its number. `fullDescriptions` lists the
|
|
674
|
-
tools it sends uncut, so the description rules skip them.
|
|
200
|
+
| Registry stdio servers (npm), pinned versions | 1,089 | `snapshot`, `session --auto`, and every tool called in a container with no network and no credentials: 15,550 of 16,518 tools |
|
|
201
|
+
| Docker's MCP catalog, at the digests it pins | 237 | The same: 4,117 of 4,237 tools called (41 servers didn't list tools) |
|
|
202
|
+
| Servers vendors publish to run locally (GitHub, AWS Labs, Microsoft, PayPal, Stripe, Notion, HashiCorp, Grafana…) | 98 | The same, with dummy credentials: 2,213 of 2,292 tools called (20 didn't list tools) |
|
|
203
|
+
| Hosted servers: 109 vendor endpoints and a seeded 2,000 from the registry | 2,109 | `snapshot`, a read-only `session --auto` of at most 10 calls, `auth check` on each that answers 401 |
|
|
675
204
|
|
|
676
|
-
|
|
205
|
+
Read those numbers for what they are. Most servers pass most checks: about 1 in 90 of
|
|
206
|
+
the registry's stdio servers fails in the official SDK client. A sealed container with
|
|
207
|
+
made-up input shows whether a tool crashes, hangs or breaks its own schema, not whether
|
|
208
|
+
it does its job: more than half of the calls there came back as a readable tool error,
|
|
209
|
+
the right answer to made-up input or a dummy key. Hosted servers got a few read-only calls each.
|
|
677
210
|
|
|
678
|
-
|
|
679
|
-
|
|
680
|
-
|
|
681
|
-
|
|
211
|
+
The reference server, `@modelcontextprotocol/server-everything`, gets no false finding,
|
|
212
|
+
and a clean fixture server must get none from any command; the test suite fails if one
|
|
213
|
+
appears. What the runs found, including what toolmenu itself got wrong and how it was
|
|
214
|
+
fixed, is in [docs/FINDINGS.md](https://github.com/niksa90/toolmenu/blob/main/docs/FINDINGS.md). The corpora, the scripts and the
|
|
215
|
+
datasets are in [bench/](bench/README.md).
|
|
682
216
|
|
|
683
|
-
|
|
684
|
-
|---|---|---|---|---|
|
|
685
|
-
| `claude-code` | tool names; full definitions for tools marked `_meta["anthropic/alwaysLoad"]` | reads a description up to 4,096 characters | 16,384 through search, 4,096 up front | Claude API's |
|
|
686
|
-
| `claude-api-search` | nothing from tools you defer (keep the 3–5 used most loaded) | name, description, argument names and descriptions; 5 results by default | none documented | `^[a-zA-Z0-9_-]{1,128}$` |
|
|
687
|
-
| `openai` | each deferred function's name and description (its schema loads on demand); a deferred MCP server shows only its own name and description | how many results, and which fields, isn't documented, so `search/findable` doesn't run | none documented | `^[a-zA-Z0-9_-]+$`, up to 128 |
|
|
688
|
-
|
|
689
|
-
The snapshot adds a line such as `as Claude Code: up front ~524 tokens · on demand ~344
|
|
690
|
-
per tool a search loads (largest: update_contacts, ~2,093)`, and `--json` a `client`
|
|
691
|
-
object. With a client that defers tools, `search/findable` runs at any menu size.
|
|
692
|
-
|
|
693
|
-
## What toolmenu can't catch
|
|
217
|
+
## What it can't catch
|
|
694
218
|
|
|
695
219
|
toolmenu sees what the server sends. Plenty of agent failures happen elsewhere:
|
|
696
220
|
|
|
697
|
-
- **
|
|
698
|
-
|
|
699
|
-
|
|
700
|
-
|
|
701
|
-
|
|
702
|
-
|
|
703
|
-
|
|
704
|
-
|
|
705
|
-
- **Whether
|
|
706
|
-
|
|
707
|
-
|
|
708
|
-
|
|
709
|
-
|
|
710
|
-
|
|
711
|
-
|
|
712
|
-
|
|
713
|
-
|
|
714
|
-
|
|
715
|
-
|
|
716
|
-
|
|
717
|
-
|
|
718
|
-
|
|
719
|
-
|
|
720
|
-
|
|
721
|
-
minimal environment otherwise)
|
|
722
|
-
--timeout <ms> per-request timeout (default: 30000)
|
|
723
|
-
--protocol <p> auto (default), legacy (2025 handshake only) or modern
|
|
724
|
-
(2026-07-28 only; an error if the server lacks it)
|
|
725
|
-
--processes <n> server processes or connections to compare (default: 2);
|
|
726
|
-
1 opens no second one, session's scope check included
|
|
727
|
-
--lists <kinds> snapshot: also read and check prompts, resources (comma-separated);
|
|
728
|
-
saved in the menu file beside the tools
|
|
729
|
-
--client <name> snapshot: check the menu for one client, from its own docs:
|
|
730
|
-
claude-code, claude-api-search or openai
|
|
731
|
-
--as <name>:<cred> snapshot: list the menu as this identity too, repeatable:
|
|
732
|
-
"reader:Authorization: Bearer …" (HTTP) or "admin:ROLE=admin"
|
|
733
|
-
(stdio). The first is the menu saved; the others are compared
|
|
734
|
-
--offline-check snapshot (stdio): also list the menu with the network cut off
|
|
735
|
-
--concurrency <n> scan: servers checked at a time (default: 4)
|
|
736
|
-
--out-dir <dir> scan: write each server's menu file there, as <name>.json
|
|
737
|
-
```
|
|
738
|
-
|
|
739
|
-
Exit codes: `0` clean · `1` findings at or above `--fail-on` · `2` couldn't connect
|
|
740
|
-
(for `scan`: a server wasn't checked) or bad usage. `toolmenu <command> --help` lists that command's own options.
|
|
741
|
-
|
|
742
|
-
## Limitations
|
|
743
|
-
|
|
744
|
-
- **Server order isn't final client order.** Clients merge tools from several servers
|
|
745
|
-
and may sort or filter them. A stable server menu is necessary for cache hits, not
|
|
746
|
-
sufficient. toolmenu measures what the server controls.
|
|
747
|
-
- **Token counts are estimates** (`o200k_base`) of what the model reads: each tool's
|
|
748
|
-
name, description and input schema. Output schemas, annotations, icons and `_meta`
|
|
749
|
-
stay with the client and aren't counted. Vendors tokenize, cache and bill
|
|
750
|
-
differently. `diff` recounts both menus with the toolmenu that runs it, so a
|
|
751
|
-
baseline from an older version still compares fairly; a number quoted elsewhere (a
|
|
752
|
-
commit message, a dashboard) should say which toolmenu counted it (0.7.1 changed the
|
|
753
|
-
count for menus with icons by up to 5×, FINDINGS F7).
|
|
754
|
-
- **Heuristic rules say so** in their messages.
|
|
755
|
-
- Not a security scanner or a full conformance suite. Other tools do those well.
|
|
221
|
+
- **Whether the agent picks the right tool.** That needs evals with a model. toolmenu
|
|
222
|
+
stays deterministic on purpose; `routes.yml` pins keyword routing, which is as far as
|
|
223
|
+
it goes.
|
|
224
|
+
- **What the client does with the menu.** Clients merge several servers, sort, filter
|
|
225
|
+
and cut. A stable server menu is necessary for cache hits, not sufficient. The
|
|
226
|
+
`--client` profiles cover what each client documents, and nothing it doesn't.
|
|
227
|
+
- **A feature with no tools.** If the agent reaches for something your menu doesn't
|
|
228
|
+
have, no menu check sees the gap.
|
|
229
|
+
- **Whether a tool does its job.** A call that answers is checked against the schema it
|
|
230
|
+
declares, not against what it should have done.
|
|
231
|
+
- **Security.** It isn't a security scanner or a full conformance suite.
|
|
232
|
+
|
|
233
|
+
Token counts are estimates (`o200k_base`) of what the model reads: each tool's name,
|
|
234
|
+
description and input schema. Vendors tokenize, cache and bill differently.
|
|
235
|
+
|
|
236
|
+
## Docs
|
|
237
|
+
|
|
238
|
+
- [snapshot](https://github.com/niksa90/toolmenu/blob/main/docs/snapshot.md): rules, where the tokens go, `routes.yml`, the config file, `scan`
|
|
239
|
+
- [session](https://github.com/niksa90/toolmenu/blob/main/docs/session.md): scenarios, `--init`, `--auto`, `--call-everything`, every session rule
|
|
240
|
+
- [diff, review, catalogs, history](https://github.com/niksa90/toolmenu/blob/main/docs/diff.md): how changes are classified, the verdicts, operations behind a search tool
|
|
241
|
+
- [clients](https://github.com/niksa90/toolmenu/blob/main/docs/clients.md): what each `--client` profile checks, and its sources
|
|
242
|
+
- [usage](https://github.com/niksa90/toolmenu/blob/main/docs/usage.md): HTTP and OAuth, proxies, the MCP server and plugin, the library, every option
|
|
243
|
+
- [the GitHub Action](https://github.com/niksa90/toolmenu/blob/main/docs/github-action.md) and [other CI output](https://github.com/niksa90/toolmenu/blob/main/docs/ci.md)
|
|
244
|
+
- [RULES](https://github.com/niksa90/toolmenu/blob/main/docs/RULES.md), [PROTOCOLS](https://github.com/niksa90/toolmenu/blob/main/docs/PROTOCOLS.md), [FINDINGS](https://github.com/niksa90/toolmenu/blob/main/docs/FINDINGS.md), [SPEC](https://github.com/niksa90/toolmenu/blob/main/docs/SPEC.md), [CHANGELOG](CHANGELOG.md)
|
|
756
245
|
|
|
757
246
|
## About
|
|
758
247
|
|
|
759
|
-
Built by [Nikša Perović](https://niksa.me) while running a 115-tool MCP server and
|
|
760
|
-
agents trip over its menu.
|
|
761
|
-
|
|
248
|
+
Built by [Nikša Perović](https://niksa.me) while running a 115-tool MCP server and
|
|
249
|
+
watching agents trip over its menu. It started as a check for menus that change at the
|
|
250
|
+
wrong time ([the story, and where it was wrong](https://niksa.me/toolmenu)) and grew
|
|
251
|
+
into a client-side test for the whole server as real servers kept failing in other
|
|
252
|
+
places.
|
|
762
253
|
|
|
763
254
|
Found a false positive, or a failure toolmenu should catch?
|
|
764
255
|
[Open an issue](https://github.com/niksa90/toolmenu/issues) with the menu (a
|
|
765
|
-
`menu.json` is enough) and what you expected.
|
|
766
|
-
[CHANGELOG.md](https://github.com/niksa90/toolmenu/blob/main/CHANGELOG.md).
|
|
256
|
+
`menu.json` is enough) and what you expected.
|
|
767
257
|
|
|
768
|
-
## License
|
|
769
|
-
|
|
770
|
-
MIT
|