toad-eye 2.11.2 → 2.13.0
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.md +16 -2
- package/dist/alerts/grafana.js +1 -1
- package/dist/cli.js +5 -3
- package/dist/core/console-exporter.d.ts +1 -1
- package/dist/core/lifecycle.d.ts +54 -0
- package/dist/core/lifecycle.js +110 -0
- package/dist/core/span-end-processor.d.ts +1 -1
- package/dist/core/spans.js +25 -84
- package/dist/core/tracer.js +2 -2
- package/dist/instrumentations/create.js +49 -76
- package/dist/mcp/middleware.d.ts +2 -4
- package/dist/vercel.d.ts +1 -1
- package/package.json +15 -15
- package/dist/context/error.d.ts +0 -15
- package/dist/context/error.js +0 -17
- package/dist/context/guard.d.ts +0 -8
- package/dist/context/guard.js +0 -41
package/README.md
CHANGED
|
@@ -72,7 +72,21 @@ Open [localhost:3100](http://localhost:3100) (Grafana, admin/admin). 11 dashboar
|
|
|
72
72
|
|
|
73
73
|
> **Requires:** [Docker Desktop](https://docs.docker.com/get-started/get-docker/) (or Docker Engine + Compose plugin)
|
|
74
74
|
|
|
75
|
-
|
|
75
|
+
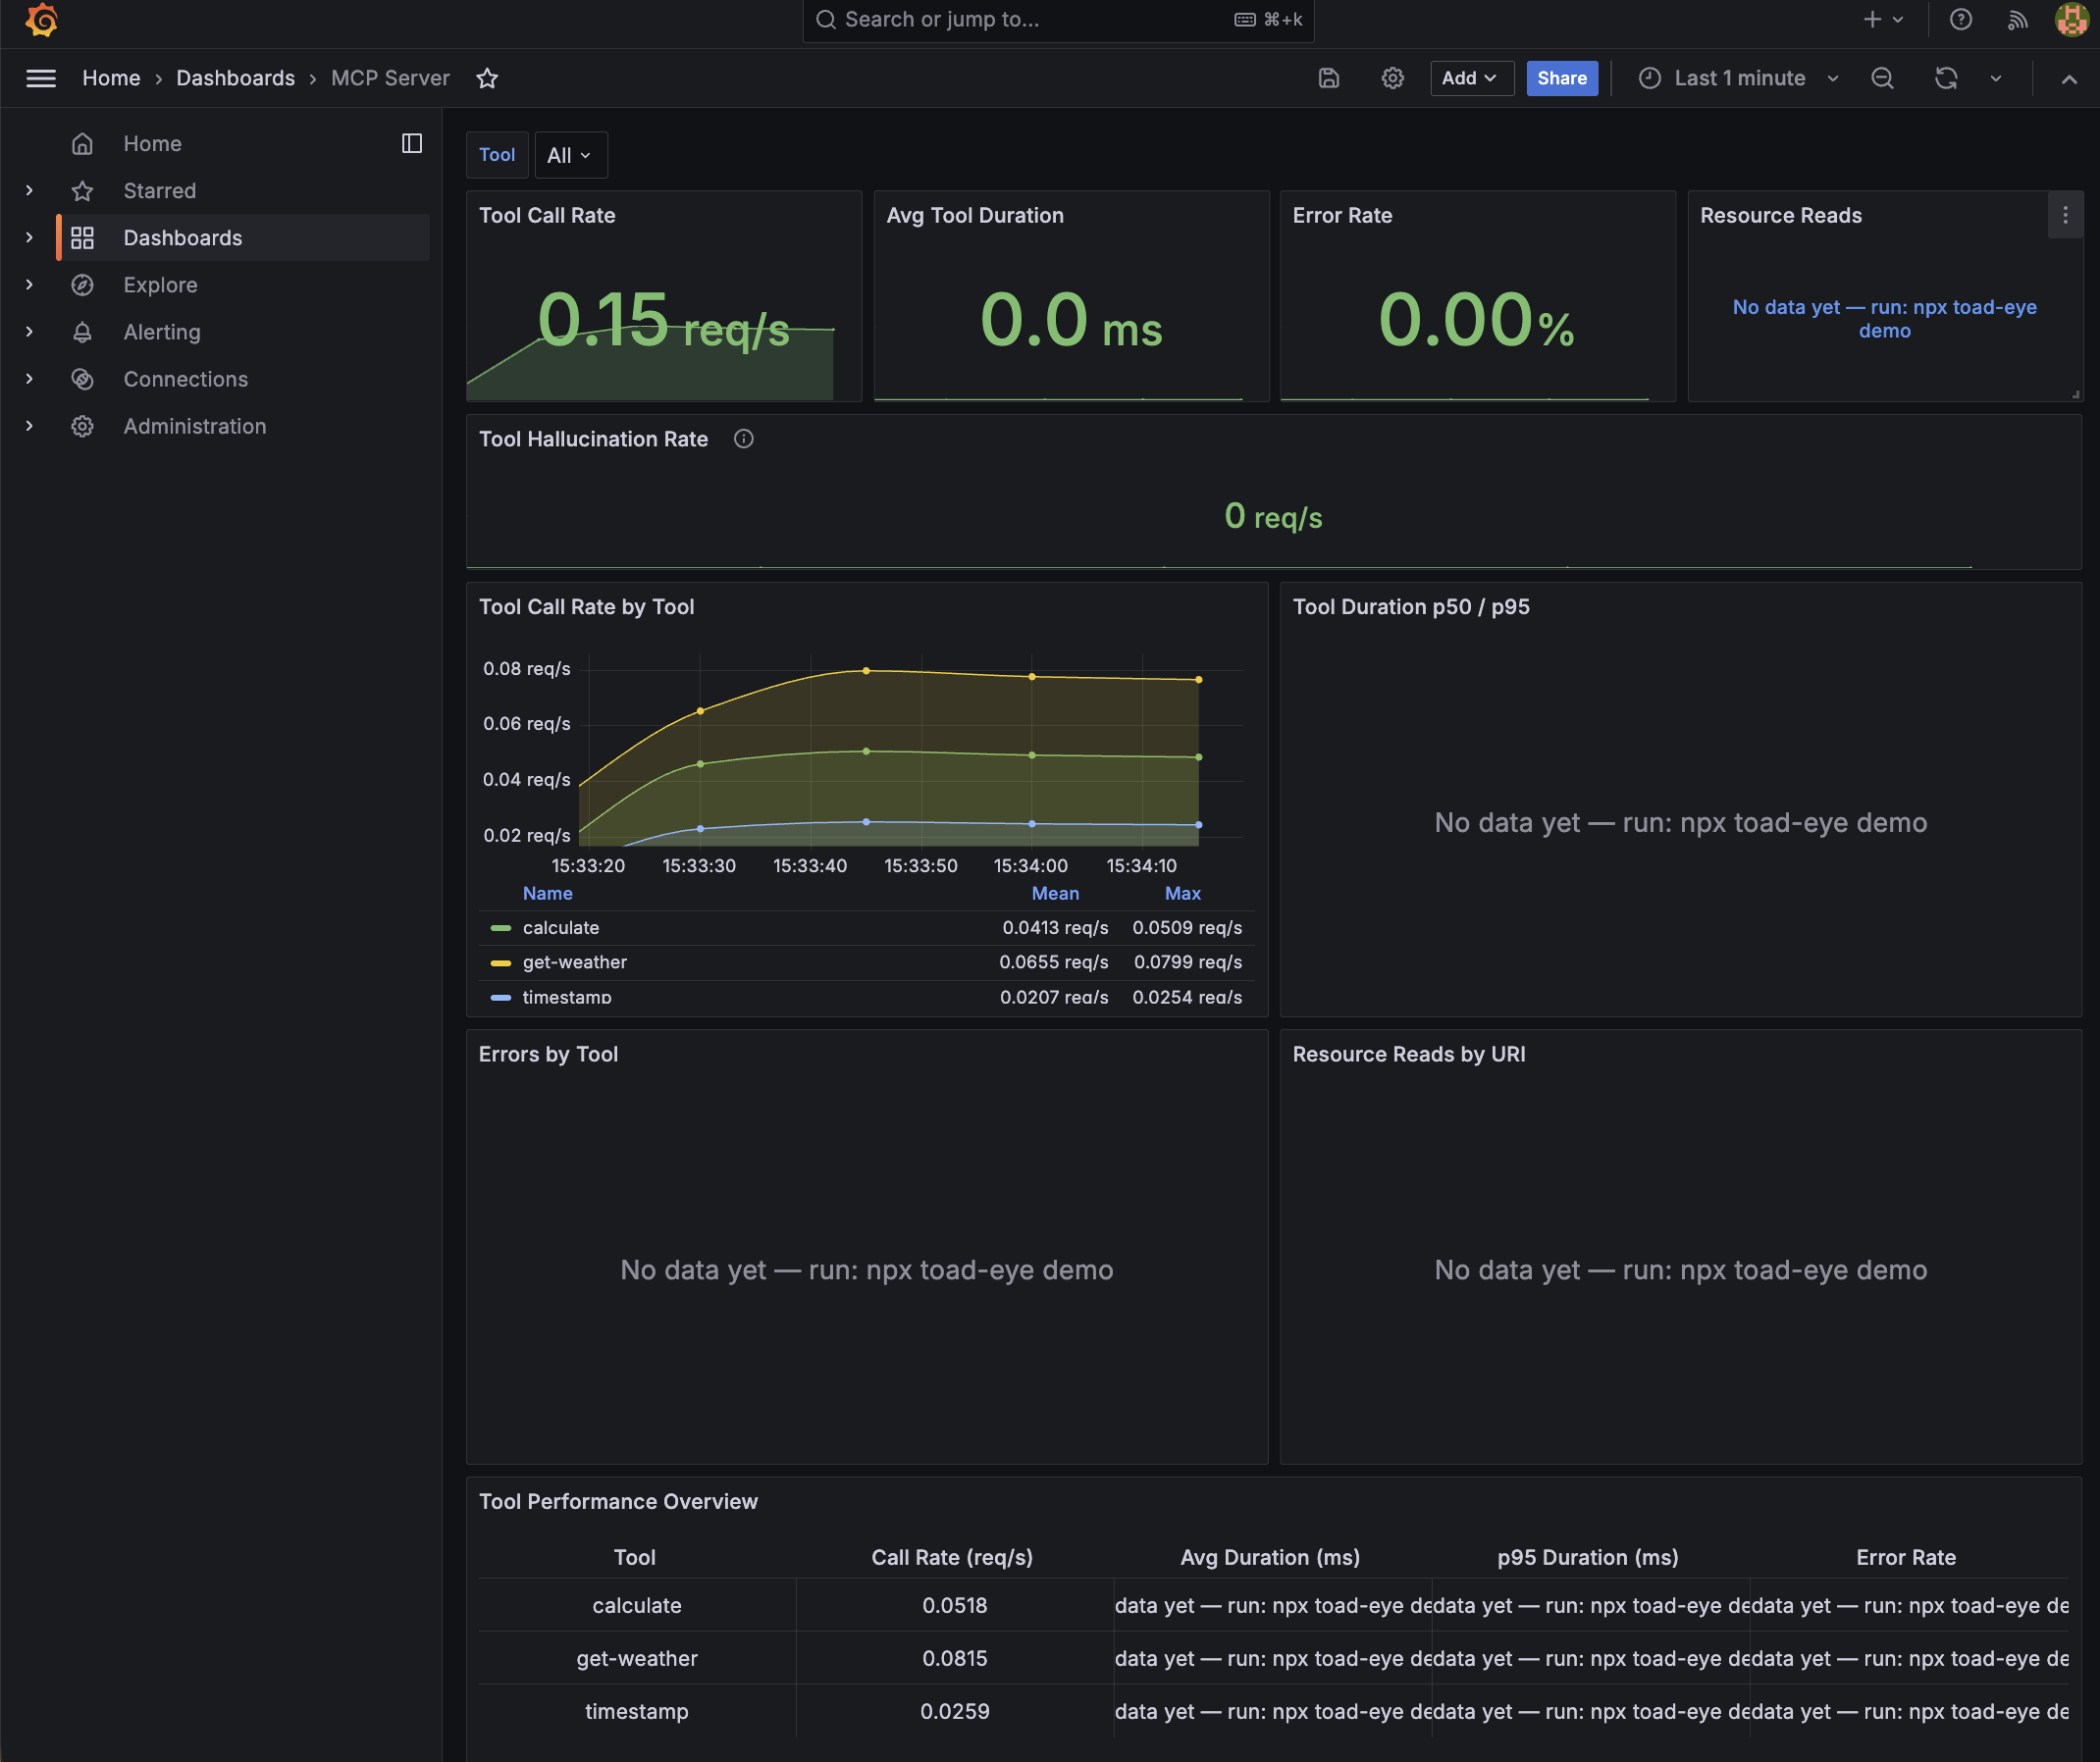
|
|
76
|
+
|
|
77
|
+
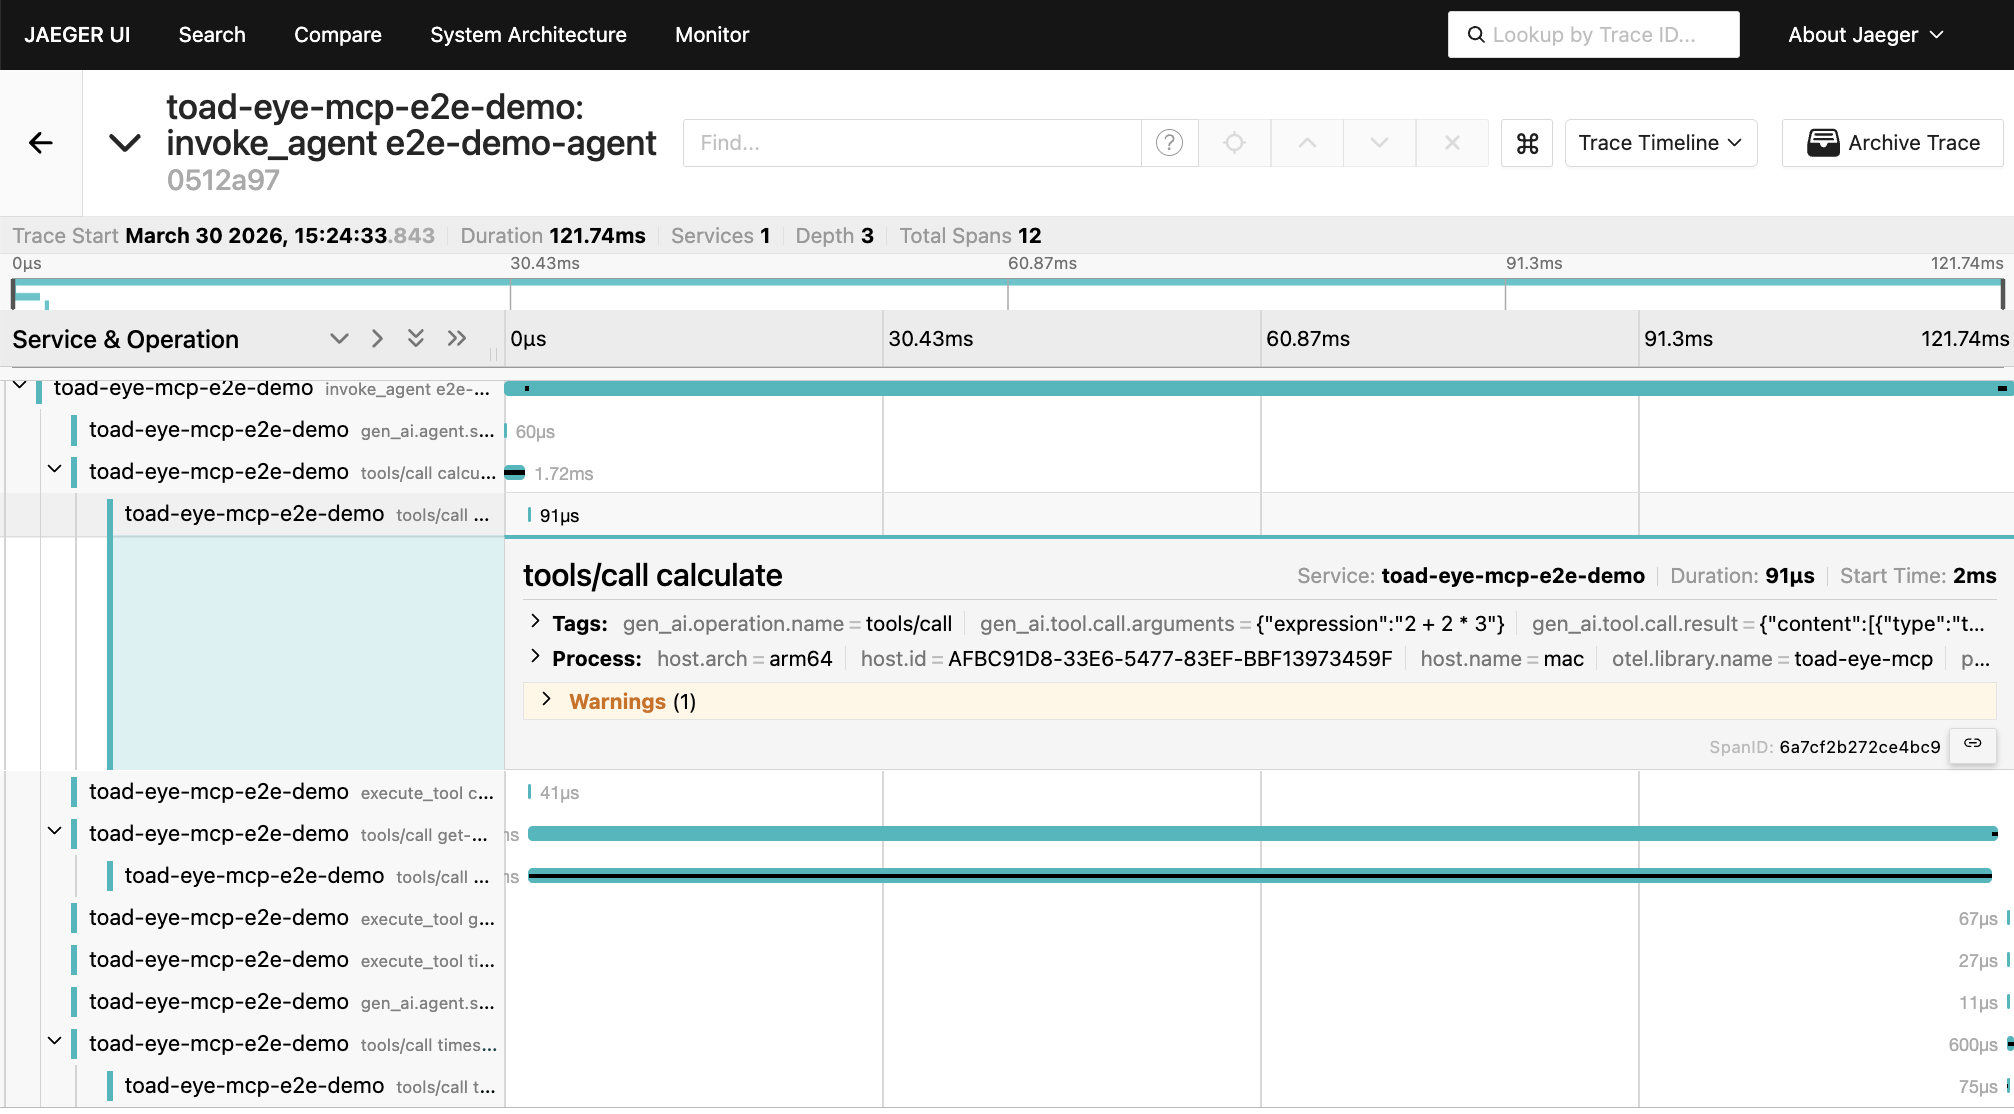
|
|
78
|
+
|
|
79
|
+
## Why toad-eye
|
|
80
|
+
|
|
81
|
+
| Feature | toad-eye | Sentry MCP | Grafana Cloud (OpenLIT) |
|
|
82
|
+
| ---------------------------- | -------- | ---------- | ----------------------- |
|
|
83
|
+
| TypeScript-native | ✅ | ✅ | ❌ (Python) |
|
|
84
|
+
| Self-hosted | ✅ | ❌ | ❌ |
|
|
85
|
+
| MCP E2E tracing | ✅ | ❌ | ❌ |
|
|
86
|
+
| MCP-specific metrics | ✅ | Partial | Partial |
|
|
87
|
+
| Privacy controls | ✅ | ❌ | ❌ |
|
|
88
|
+
| Tool hallucination detection | ✅ | ❌ | ❌ |
|
|
89
|
+
| Budget guards | ✅ | ❌ | ❌ |
|
|
76
90
|
|
|
77
91
|
## What You Get
|
|
78
92
|
|
|
@@ -169,4 +183,4 @@ Full metrics and span attribute reference: [COMPATIBILITY.md](https://github.com
|
|
|
169
183
|
|
|
170
184
|
## Tech Stack
|
|
171
185
|
|
|
172
|
-
TypeScript · OpenTelemetry SDK
|
|
186
|
+
TypeScript · OpenTelemetry SDK 3.x · Hono · Docker Compose (Prometheus, Jaeger, Grafana, OTel Collector) · Vitest (306+ tests)
|
package/dist/alerts/grafana.js
CHANGED
|
@@ -16,7 +16,7 @@ export async function postGrafanaAnnotation(grafanaUrl, alert, apiKey) {
|
|
|
16
16
|
body: JSON.stringify({
|
|
17
17
|
time: Date.now(),
|
|
18
18
|
tags: ["toad-eye", "alert", alert.name],
|
|
19
|
-
text: `🚨 ${alert.name}: ${alert.value.toFixed(4)}
|
|
19
|
+
text: `🚨 ${alert.name}: ${alert.value.toFixed(4)} (threshold: ${alert.threshold})`,
|
|
20
20
|
}),
|
|
21
21
|
});
|
|
22
22
|
if (!res.ok) {
|
package/dist/cli.js
CHANGED
|
@@ -263,7 +263,9 @@ async function demo() {
|
|
|
263
263
|
}
|
|
264
264
|
};
|
|
265
265
|
const run = () => {
|
|
266
|
-
tick()
|
|
266
|
+
tick()
|
|
267
|
+
.catch((err) => console.error("Demo error:", err))
|
|
268
|
+
.then(() => setTimeout(run, DEMO_TICK_INTERVAL_MS));
|
|
267
269
|
};
|
|
268
270
|
run();
|
|
269
271
|
}
|
|
@@ -342,10 +344,10 @@ function runCli() {
|
|
|
342
344
|
status();
|
|
343
345
|
break;
|
|
344
346
|
case "demo":
|
|
345
|
-
demo();
|
|
347
|
+
void demo();
|
|
346
348
|
break;
|
|
347
349
|
case "export-trace":
|
|
348
|
-
exportTraceCommand();
|
|
350
|
+
void exportTraceCommand();
|
|
349
351
|
break;
|
|
350
352
|
case "help":
|
|
351
353
|
case "--help":
|
|
@@ -9,7 +9,7 @@
|
|
|
9
9
|
* 🐸 chat gpt-4o [1.2s] $0.003 ✅
|
|
10
10
|
* 🐸 tools/call broken [12ms] ❌ TypeError
|
|
11
11
|
*/
|
|
12
|
-
import type { SpanExporter, ReadableSpan } from "@opentelemetry/sdk-trace
|
|
12
|
+
import type { SpanExporter, ReadableSpan } from "@opentelemetry/sdk-trace";
|
|
13
13
|
import { type ExportResult } from "@opentelemetry/core";
|
|
14
14
|
export declare class ToadEyeConsoleExporter implements SpanExporter {
|
|
15
15
|
export(spans: ReadableSpan[], resultCallback: (result: ExportResult) => void): void;
|
|
@@ -0,0 +1,54 @@
|
|
|
1
|
+
/**
|
|
2
|
+
* Shared LLM call orchestration — budget, metrics, context guard.
|
|
3
|
+
*
|
|
4
|
+
* Both traceLLMCall() (manual) and createStreamingHandler() (auto)
|
|
5
|
+
* need the same pre/post-call logic. This module provides it as
|
|
6
|
+
* composable functions to eliminate duplication.
|
|
7
|
+
*
|
|
8
|
+
* @internal Not exported from the public API.
|
|
9
|
+
*/
|
|
10
|
+
import type { Span } from "@opentelemetry/api";
|
|
11
|
+
import type { LLMProvider } from "../types/index.js";
|
|
12
|
+
import type { BudgetTracker } from "../budget/index.js";
|
|
13
|
+
export interface BudgetPreCheckResult {
|
|
14
|
+
readonly effectiveProvider: LLMProvider;
|
|
15
|
+
readonly effectiveModel: string;
|
|
16
|
+
readonly estimatedCost: number;
|
|
17
|
+
readonly budget: BudgetTracker | null;
|
|
18
|
+
}
|
|
19
|
+
/**
|
|
20
|
+
* Run budget check before the LLM call.
|
|
21
|
+
* May downgrade provider/model if budget is in downgrade mode.
|
|
22
|
+
* Throws ToadBudgetExceededError if budget is in block mode.
|
|
23
|
+
*/
|
|
24
|
+
export declare function performBudgetPreCheck(provider: LLMProvider, model: string, userId: string | undefined): BudgetPreCheckResult;
|
|
25
|
+
export interface SuccessMetricsInput {
|
|
26
|
+
readonly duration: number;
|
|
27
|
+
readonly provider: string;
|
|
28
|
+
readonly model: string;
|
|
29
|
+
readonly cost: number;
|
|
30
|
+
readonly inputTokens: number;
|
|
31
|
+
readonly outputTokens: number;
|
|
32
|
+
readonly completion: string;
|
|
33
|
+
readonly attrs?: Readonly<Record<string, string>> | undefined;
|
|
34
|
+
}
|
|
35
|
+
/**
|
|
36
|
+
* Record all success-path metrics: request, duration, cost, tokens,
|
|
37
|
+
* empty response detection, latency per token.
|
|
38
|
+
*/
|
|
39
|
+
export declare function recordSuccessMetrics(input: SuccessMetricsInput): void;
|
|
40
|
+
/**
|
|
41
|
+
* Evaluate context window utilization and trigger warnings/blocks.
|
|
42
|
+
* Must be called BEFORE span.end().
|
|
43
|
+
*/
|
|
44
|
+
export declare function evaluateContextGuard(span: Span, model: string, provider: string, inputTokens: number): void;
|
|
45
|
+
/**
|
|
46
|
+
* Record actual cost after the LLM call. Releases the reservation
|
|
47
|
+
* made in performBudgetPreCheck. Warns if budget exceeded.
|
|
48
|
+
*/
|
|
49
|
+
export declare function recordBudgetPostCheck(budget: BudgetTracker | null, cost: number, model: string, userId: string | undefined, estimatedCost: number): void;
|
|
50
|
+
/**
|
|
51
|
+
* Record error-path metrics. Distinguishes budget block errors from
|
|
52
|
+
* generic errors to avoid inflating error rate.
|
|
53
|
+
*/
|
|
54
|
+
export declare function handleErrorMetrics(error: unknown, duration: number, provider: string, model: string, budget: BudgetTracker | null, estimatedCost: number, attrs?: Readonly<Record<string, string>>): void;
|
|
@@ -0,0 +1,110 @@
|
|
|
1
|
+
/**
|
|
2
|
+
* Shared LLM call orchestration — budget, metrics, context guard.
|
|
3
|
+
*
|
|
4
|
+
* Both traceLLMCall() (manual) and createStreamingHandler() (auto)
|
|
5
|
+
* need the same pre/post-call logic. This module provides it as
|
|
6
|
+
* composable functions to eliminate duplication.
|
|
7
|
+
*
|
|
8
|
+
* @internal Not exported from the public API.
|
|
9
|
+
*/
|
|
10
|
+
import { GEN_AI_ATTRS } from "../types/index.js";
|
|
11
|
+
import { calculateCost, getModelPricing } from "./pricing.js";
|
|
12
|
+
import { recordRequest, recordRequestDuration, recordRequestCost, recordTokens, recordResponseEmpty, recordResponseLatencyPerToken, recordContextUtilization, recordContextBlocked, recordBudgetExceeded, recordBudgetDowngraded, recordBudgetBlocked, recordError, } from "./metrics.js";
|
|
13
|
+
import { getConfig, getBudgetTracker } from "./tracer.js";
|
|
14
|
+
import { ToadBudgetExceededError } from "../budget/index.js";
|
|
15
|
+
/**
|
|
16
|
+
* Run budget check before the LLM call.
|
|
17
|
+
* May downgrade provider/model if budget is in downgrade mode.
|
|
18
|
+
* Throws ToadBudgetExceededError if budget is in block mode.
|
|
19
|
+
*/
|
|
20
|
+
export function performBudgetPreCheck(provider, model, userId) {
|
|
21
|
+
const budget = getBudgetTracker();
|
|
22
|
+
const estimatedCost = budget ? calculateCost(model, 500, 200) : 0;
|
|
23
|
+
let effectiveProvider = provider;
|
|
24
|
+
let effectiveModel = model;
|
|
25
|
+
if (budget) {
|
|
26
|
+
const override = budget.checkBefore(provider, model, userId, estimatedCost);
|
|
27
|
+
if (override) {
|
|
28
|
+
effectiveProvider = override.provider;
|
|
29
|
+
effectiveModel = override.model;
|
|
30
|
+
recordBudgetDowngraded(override.budget);
|
|
31
|
+
}
|
|
32
|
+
}
|
|
33
|
+
return { effectiveProvider, effectiveModel, estimatedCost, budget };
|
|
34
|
+
}
|
|
35
|
+
/**
|
|
36
|
+
* Record all success-path metrics: request, duration, cost, tokens,
|
|
37
|
+
* empty response detection, latency per token.
|
|
38
|
+
*/
|
|
39
|
+
export function recordSuccessMetrics(input) {
|
|
40
|
+
const { duration, provider, model, cost, inputTokens, outputTokens, completion, attrs, } = input;
|
|
41
|
+
recordRequest(provider, model, attrs);
|
|
42
|
+
recordRequestDuration(duration, provider, model, attrs);
|
|
43
|
+
recordRequestCost(cost, provider, model, attrs);
|
|
44
|
+
recordTokens(inputTokens + outputTokens, provider, model, attrs);
|
|
45
|
+
if (completion.trim() === "") {
|
|
46
|
+
recordResponseEmpty(provider, model, attrs);
|
|
47
|
+
}
|
|
48
|
+
if (outputTokens > 0) {
|
|
49
|
+
recordResponseLatencyPerToken(duration / outputTokens, provider, model, attrs);
|
|
50
|
+
}
|
|
51
|
+
}
|
|
52
|
+
// ── Context guard ─────────────────────────────────────────────────
|
|
53
|
+
/**
|
|
54
|
+
* Evaluate context window utilization and trigger warnings/blocks.
|
|
55
|
+
* Must be called BEFORE span.end().
|
|
56
|
+
*/
|
|
57
|
+
export function evaluateContextGuard(span, model, provider, inputTokens) {
|
|
58
|
+
const pricing = getModelPricing(model);
|
|
59
|
+
if (!pricing?.maxContextTokens || inputTokens <= 0)
|
|
60
|
+
return;
|
|
61
|
+
const utilization = inputTokens / pricing.maxContextTokens;
|
|
62
|
+
span.setAttribute(GEN_AI_ATTRS.CONTEXT_UTILIZATION, utilization);
|
|
63
|
+
recordContextUtilization(utilization, provider, model);
|
|
64
|
+
const guard = getConfig()?.contextGuard;
|
|
65
|
+
if (!guard)
|
|
66
|
+
return;
|
|
67
|
+
if (guard.alertAt !== undefined && utilization >= guard.alertAt) {
|
|
68
|
+
recordContextBlocked(model);
|
|
69
|
+
span.addEvent("gen_ai.context.limit_exceeded", {
|
|
70
|
+
"gen_ai.toad_eye.context_utilization": utilization,
|
|
71
|
+
"gen_ai.toad_eye.context.threshold": guard.alertAt,
|
|
72
|
+
});
|
|
73
|
+
console.warn(`toad-eye: context window ${(utilization * 100).toFixed(0)}% full for ${model} — exceeds alertAt threshold ${(guard.alertAt * 100).toFixed(0)}%. Compress context before next call.`);
|
|
74
|
+
}
|
|
75
|
+
else if (guard.warnAt !== undefined && utilization >= guard.warnAt) {
|
|
76
|
+
console.warn(`toad-eye: context window ${(utilization * 100).toFixed(0)}% full for ${model} (${inputTokens}/${pricing.maxContextTokens} tokens)`);
|
|
77
|
+
}
|
|
78
|
+
}
|
|
79
|
+
// ── Budget post-check ─────────────────────────────────────────────
|
|
80
|
+
/**
|
|
81
|
+
* Record actual cost after the LLM call. Releases the reservation
|
|
82
|
+
* made in performBudgetPreCheck. Warns if budget exceeded.
|
|
83
|
+
*/
|
|
84
|
+
export function recordBudgetPostCheck(budget, cost, model, userId, estimatedCost) {
|
|
85
|
+
if (!budget)
|
|
86
|
+
return;
|
|
87
|
+
const exceeded = budget.recordCost(cost, model, userId, estimatedCost);
|
|
88
|
+
if (exceeded) {
|
|
89
|
+
recordBudgetExceeded(exceeded.budget);
|
|
90
|
+
console.warn(`toad-eye: ${exceeded.budget} budget exceeded — limit $${exceeded.limit}, current $${exceeded.current.toFixed(2)}`);
|
|
91
|
+
}
|
|
92
|
+
}
|
|
93
|
+
// ── Error metrics ─────────────────────────────────────────────────
|
|
94
|
+
/**
|
|
95
|
+
* Record error-path metrics. Distinguishes budget block errors from
|
|
96
|
+
* generic errors to avoid inflating error rate.
|
|
97
|
+
*/
|
|
98
|
+
export function handleErrorMetrics(error, duration, provider, model, budget, estimatedCost, attrs) {
|
|
99
|
+
recordRequest(provider, model, attrs);
|
|
100
|
+
recordRequestDuration(duration, provider, model, attrs);
|
|
101
|
+
if (budget) {
|
|
102
|
+
budget.releaseReservation(estimatedCost);
|
|
103
|
+
}
|
|
104
|
+
if (error instanceof ToadBudgetExceededError) {
|
|
105
|
+
recordBudgetBlocked(error.budget);
|
|
106
|
+
}
|
|
107
|
+
else {
|
|
108
|
+
recordError(provider, model, attrs);
|
|
109
|
+
}
|
|
110
|
+
}
|
|
@@ -4,7 +4,7 @@
|
|
|
4
4
|
* Extracts LLM/MCP-relevant attributes from ReadableSpan into a clean
|
|
5
5
|
* SpanEndData object — user never touches OTel SDK internals.
|
|
6
6
|
*/
|
|
7
|
-
import type { SpanProcessor, ReadableSpan } from "@opentelemetry/sdk-trace
|
|
7
|
+
import type { SpanProcessor, ReadableSpan } from "@opentelemetry/sdk-trace";
|
|
8
8
|
/** Structured span data passed to the onSpanEnd callback. */
|
|
9
9
|
export interface SpanEndData {
|
|
10
10
|
readonly traceId: string;
|
package/dist/core/spans.js
CHANGED
|
@@ -1,10 +1,10 @@
|
|
|
1
1
|
import { createHash } from "node:crypto";
|
|
2
2
|
import { trace, SpanStatusCode } from "@opentelemetry/api";
|
|
3
3
|
import { GEN_AI_ATTRS, INSTRUMENTATION_NAME } from "../types/index.js";
|
|
4
|
-
import {
|
|
5
|
-
import { getConfig
|
|
6
|
-
import { calculateCost
|
|
7
|
-
import {
|
|
4
|
+
import { recordThinkingRatio } from "./metrics.js";
|
|
5
|
+
import { getConfig } from "./tracer.js";
|
|
6
|
+
import { calculateCost } from "./pricing.js";
|
|
7
|
+
import { performBudgetPreCheck, recordSuccessMetrics, evaluateContextGuard, recordBudgetPostCheck, handleErrorMetrics, } from "./lifecycle.js";
|
|
8
8
|
const tracer = trace.getTracer(INSTRUMENTATION_NAME);
|
|
9
9
|
let saltWarningEmitted = false;
|
|
10
10
|
// Track the last config ref so saltWarningEmitted resets across re-inits without circular imports
|
|
@@ -109,10 +109,6 @@ function setBaseAttributes(span, input) {
|
|
|
109
109
|
...attrs,
|
|
110
110
|
});
|
|
111
111
|
}
|
|
112
|
-
function recordBaseMetrics(duration, provider, model, attrs) {
|
|
113
|
-
recordRequest(provider, model, attrs);
|
|
114
|
-
recordRequestDuration(duration, provider, model, attrs);
|
|
115
|
-
}
|
|
116
112
|
function setSuccessAttributes(span, input, output, resolvedCost) {
|
|
117
113
|
const completion = processContent(output.completion);
|
|
118
114
|
span.setAttributes({
|
|
@@ -164,25 +160,15 @@ export async function traceLLMCall(input, fn) {
|
|
|
164
160
|
if (!getConfig()) {
|
|
165
161
|
console.warn("toad-eye: traceLLMCall called before initObservability() — no telemetry will be recorded.");
|
|
166
162
|
}
|
|
167
|
-
const
|
|
168
|
-
|
|
169
|
-
|
|
170
|
-
|
|
171
|
-
|
|
172
|
-
|
|
173
|
-
|
|
174
|
-
const userId = input.attributes?.[GEN_AI_ATTRS.USER_ID];
|
|
175
|
-
const override = budget.checkBefore(input.provider, input.model, userId, estimatedCost);
|
|
176
|
-
if (override) {
|
|
177
|
-
// Downgrade mode — use modified provider/model
|
|
178
|
-
effectiveInput = {
|
|
179
|
-
...input,
|
|
180
|
-
provider: override.provider,
|
|
181
|
-
model: override.model,
|
|
182
|
-
};
|
|
183
|
-
recordBudgetDowngraded(override.budget);
|
|
163
|
+
const userId = input.attributes?.[GEN_AI_ATTRS.USER_ID];
|
|
164
|
+
const { effectiveProvider, effectiveModel, estimatedCost, budget } = performBudgetPreCheck(input.provider, input.model, userId);
|
|
165
|
+
const effectiveInput = effectiveProvider !== input.provider || effectiveModel !== input.model
|
|
166
|
+
? {
|
|
167
|
+
...input,
|
|
168
|
+
provider: effectiveProvider,
|
|
169
|
+
model: effectiveModel,
|
|
184
170
|
}
|
|
185
|
-
|
|
171
|
+
: input;
|
|
186
172
|
const op = effectiveInput.operationName ?? "chat";
|
|
187
173
|
return tracer.startActiveSpan(`${op} ${effectiveInput.model}`, async (span) => {
|
|
188
174
|
const start = performance.now();
|
|
@@ -194,70 +180,25 @@ export async function traceLLMCall(input, fn) {
|
|
|
194
180
|
const resolvedCost = output.cost ??
|
|
195
181
|
calculateCost(effectiveInput.model, output.inputTokens, output.outputTokens);
|
|
196
182
|
setSuccessAttributes(span, effectiveInput, output, resolvedCost);
|
|
197
|
-
|
|
198
|
-
|
|
199
|
-
|
|
200
|
-
|
|
201
|
-
|
|
202
|
-
|
|
203
|
-
|
|
204
|
-
|
|
205
|
-
|
|
206
|
-
}
|
|
207
|
-
|
|
208
|
-
|
|
209
|
-
if (pricing?.maxContextTokens && output.inputTokens > 0) {
|
|
210
|
-
const utilization = output.inputTokens / pricing.maxContextTokens;
|
|
211
|
-
span.setAttribute(GEN_AI_ATTRS.CONTEXT_UTILIZATION, utilization);
|
|
212
|
-
recordContextUtilization(utilization, effectiveInput.provider, effectiveInput.model);
|
|
213
|
-
// Context guard — post-call warning when approaching limit.
|
|
214
|
-
// This warns about the CURRENT call's context usage so agents
|
|
215
|
-
// can compress context before the NEXT call.
|
|
216
|
-
const guard = getConfig()?.contextGuard;
|
|
217
|
-
if (guard) {
|
|
218
|
-
if (guard.alertAt !== undefined && utilization >= guard.alertAt) {
|
|
219
|
-
recordContextBlocked(effectiveInput.model);
|
|
220
|
-
span.addEvent("gen_ai.context.limit_exceeded", {
|
|
221
|
-
"gen_ai.toad_eye.context_utilization": utilization,
|
|
222
|
-
"gen_ai.toad_eye.context.threshold": guard.alertAt,
|
|
223
|
-
});
|
|
224
|
-
console.warn(`toad-eye: context window ${(utilization * 100).toFixed(0)}% full for ${effectiveInput.model} — exceeds alertAt threshold ${(guard.alertAt * 100).toFixed(0)}%. Compress context before next call.`);
|
|
225
|
-
}
|
|
226
|
-
else if (guard.warnAt !== undefined &&
|
|
227
|
-
utilization >= guard.warnAt) {
|
|
228
|
-
console.warn(`toad-eye: context window ${(utilization * 100).toFixed(0)}% full for ${effectiveInput.model} (${output.inputTokens}/${pricing.maxContextTokens} tokens)`);
|
|
229
|
-
}
|
|
230
|
-
}
|
|
231
|
-
}
|
|
232
|
-
// Budget recording AFTER the call — releases the cost reservation
|
|
233
|
-
if (budget) {
|
|
234
|
-
const userId = effectiveInput.attributes?.[GEN_AI_ATTRS.USER_ID];
|
|
235
|
-
const exceeded = budget.recordCost(resolvedCost, effectiveInput.model, userId, estimatedCost);
|
|
236
|
-
if (exceeded) {
|
|
237
|
-
recordBudgetExceeded(exceeded.budget);
|
|
238
|
-
console.warn(`toad-eye: ${exceeded.budget} budget exceeded — limit $${exceeded.limit}, current $${exceeded.current.toFixed(2)}`);
|
|
239
|
-
}
|
|
240
|
-
}
|
|
183
|
+
recordSuccessMetrics({
|
|
184
|
+
duration,
|
|
185
|
+
provider: effectiveInput.provider,
|
|
186
|
+
model: effectiveInput.model,
|
|
187
|
+
cost: resolvedCost,
|
|
188
|
+
inputTokens: output.inputTokens,
|
|
189
|
+
outputTokens: output.outputTokens,
|
|
190
|
+
completion: output.completion,
|
|
191
|
+
attrs,
|
|
192
|
+
});
|
|
193
|
+
evaluateContextGuard(span, effectiveInput.model, effectiveInput.provider, output.inputTokens);
|
|
194
|
+
recordBudgetPostCheck(budget, resolvedCost, effectiveInput.model, effectiveInput.attributes?.[GEN_AI_ATTRS.USER_ID], estimatedCost);
|
|
241
195
|
return output;
|
|
242
196
|
}
|
|
243
197
|
catch (error) {
|
|
244
198
|
const duration = performance.now() - start;
|
|
245
199
|
const message = error instanceof Error ? error.message : String(error);
|
|
246
|
-
const attrs = resolveAttributes(effectiveInput);
|
|
247
200
|
setErrorAttributes(span, message);
|
|
248
|
-
|
|
249
|
-
// Release cost reservation on any error (no cost was incurred)
|
|
250
|
-
if (budget) {
|
|
251
|
-
budget.releaseReservation(estimatedCost);
|
|
252
|
-
}
|
|
253
|
-
if (error instanceof ToadBudgetExceededError) {
|
|
254
|
-
// Budget blocks are intentional guardrails, not errors — record
|
|
255
|
-
// only the budget-specific metric to avoid inflating error rate
|
|
256
|
-
recordBudgetBlocked(error.budget);
|
|
257
|
-
}
|
|
258
|
-
else {
|
|
259
|
-
recordError(effectiveInput.provider, effectiveInput.model, attrs);
|
|
260
|
-
}
|
|
201
|
+
handleErrorMetrics(error, duration, effectiveInput.provider, effectiveInput.model, budget, estimatedCost, resolveAttributes(effectiveInput));
|
|
261
202
|
throw error;
|
|
262
203
|
}
|
|
263
204
|
finally {
|
package/dist/core/tracer.js
CHANGED
|
@@ -3,7 +3,7 @@ import { resourceFromAttributes } from "@opentelemetry/resources";
|
|
|
3
3
|
import { OTLPTraceExporter } from "@opentelemetry/exporter-trace-otlp-http";
|
|
4
4
|
import { OTLPMetricExporter } from "@opentelemetry/exporter-metrics-otlp-http";
|
|
5
5
|
import { PeriodicExportingMetricReader } from "@opentelemetry/sdk-metrics";
|
|
6
|
-
import { TraceIdRatioBasedSampler, ParentBasedSampler, BatchSpanProcessor, } from "@opentelemetry/sdk-trace
|
|
6
|
+
import { TraceIdRatioBasedSampler, ParentBasedSampler, BatchSpanProcessor, } from "@opentelemetry/sdk-trace";
|
|
7
7
|
import { ATTR_SERVICE_NAME } from "@opentelemetry/semantic-conventions";
|
|
8
8
|
import { initMetrics, resetMetrics } from "./metrics.js";
|
|
9
9
|
import { resetCustomPricing } from "./pricing.js";
|
|
@@ -96,7 +96,7 @@ export function initObservability(config) {
|
|
|
96
96
|
const needsCustomProcessors = config.instrument?.includes("ai") || config.onSpanEnd !== undefined;
|
|
97
97
|
const spanProcessors = needsCustomProcessors
|
|
98
98
|
? [
|
|
99
|
-
new BatchSpanProcessor(traceExporter),
|
|
99
|
+
new BatchSpanProcessor({ exporter: traceExporter }),
|
|
100
100
|
...(config.instrument?.includes("ai")
|
|
101
101
|
? [new ToadEyeAISpanProcessor()]
|
|
102
102
|
: []),
|
|
@@ -1,9 +1,10 @@
|
|
|
1
1
|
import { createRequire } from "node:module";
|
|
2
2
|
import { trace, context, diag, SpanStatusCode, } from "@opentelemetry/api";
|
|
3
3
|
import { traceLLMCall, processContent } from "../core/spans.js";
|
|
4
|
-
import { calculateCost
|
|
5
|
-
import {
|
|
6
|
-
import { getConfig
|
|
4
|
+
import { calculateCost } from "../core/pricing.js";
|
|
5
|
+
import { recordTimeToFirstToken, recordError } from "../core/metrics.js";
|
|
6
|
+
import { getConfig } from "../core/tracer.js";
|
|
7
|
+
import { performBudgetPreCheck, recordSuccessMetrics, evaluateContextGuard, recordBudgetPostCheck, handleErrorMetrics, } from "../core/lifecycle.js";
|
|
7
8
|
import { GEN_AI_ATTRS, INSTRUMENTATION_NAME } from "../types/index.js";
|
|
8
9
|
const require = createRequire(import.meta.url);
|
|
9
10
|
function isModuleInstalled(moduleName) {
|
|
@@ -75,35 +76,27 @@ original, patch, providerName) {
|
|
|
75
76
|
b["stream_options"] = { include_usage: true };
|
|
76
77
|
}
|
|
77
78
|
}
|
|
78
|
-
// Pass thisArg so extractRequest can access instance properties (e.g., Gemini model name)
|
|
79
79
|
const req = patch.extractRequest(body, thisArg);
|
|
80
80
|
const start = performance.now();
|
|
81
|
-
// Budget check BEFORE the LLM call — mirrors traceLLMCall behavior
|
|
82
|
-
const budget = getBudgetTracker();
|
|
83
81
|
const config = getConfig();
|
|
84
82
|
const userId = config?.attributes?.[GEN_AI_ATTRS.USER_ID];
|
|
85
|
-
const estimatedCost
|
|
86
|
-
let effectiveProvider = providerName;
|
|
87
|
-
let effectiveModel = req.model;
|
|
88
|
-
if (budget) {
|
|
89
|
-
const override = budget.checkBefore(providerName, req.model, userId, estimatedCost);
|
|
90
|
-
if (override) {
|
|
91
|
-
effectiveProvider = override.provider;
|
|
92
|
-
effectiveModel = override.model;
|
|
93
|
-
recordBudgetDowngraded(override.budget);
|
|
94
|
-
}
|
|
95
|
-
}
|
|
83
|
+
const { effectiveProvider, effectiveModel, estimatedCost, budget } = performBudgetPreCheck(providerName, req.model, userId);
|
|
96
84
|
const op = patch.operationName ?? "chat";
|
|
97
85
|
const span = tracer.startSpan(`${op} ${effectiveModel}`);
|
|
98
86
|
const ctx = trace.setSpan(context.active(), span);
|
|
99
87
|
const sessionId = config?.sessionExtractor?.() ?? config?.sessionId;
|
|
100
88
|
let ttftMs = 0;
|
|
89
|
+
const processedPrompt = processContent(req.prompt);
|
|
101
90
|
span.setAttributes({
|
|
102
91
|
[GEN_AI_ATTRS.PROVIDER]: effectiveProvider,
|
|
103
92
|
[GEN_AI_ATTRS.REQUEST_MODEL]: effectiveModel,
|
|
104
93
|
[GEN_AI_ATTRS.TEMPERATURE]: req.temperature ?? 1.0,
|
|
105
94
|
[GEN_AI_ATTRS.OPERATION]: op,
|
|
106
95
|
...(sessionId !== undefined && { [GEN_AI_ATTRS.SESSION_ID]: sessionId }),
|
|
96
|
+
...(processedPrompt !== undefined && {
|
|
97
|
+
[GEN_AI_ATTRS.PROMPT]: processedPrompt,
|
|
98
|
+
}),
|
|
99
|
+
...config?.attributes,
|
|
107
100
|
});
|
|
108
101
|
let response;
|
|
109
102
|
try {
|
|
@@ -112,18 +105,20 @@ original, patch, providerName) {
|
|
|
112
105
|
catch (err) {
|
|
113
106
|
const duration = performance.now() - start;
|
|
114
107
|
const message = err instanceof Error ? err.message : String(err);
|
|
115
|
-
|
|
116
|
-
if (budget)
|
|
117
|
-
budget.releaseReservation(estimatedCost);
|
|
108
|
+
const sanitized = processContent(message);
|
|
118
109
|
span.setAttributes({
|
|
110
|
+
[GEN_AI_ATTRS.INPUT_TOKENS]: 0,
|
|
111
|
+
[GEN_AI_ATTRS.OUTPUT_TOKENS]: 0,
|
|
112
|
+
[GEN_AI_ATTRS.COST]: 0,
|
|
119
113
|
[GEN_AI_ATTRS.STATUS]: "error",
|
|
120
|
-
[GEN_AI_ATTRS.ERROR]:
|
|
114
|
+
...(sanitized !== undefined && { [GEN_AI_ATTRS.ERROR]: sanitized }),
|
|
115
|
+
});
|
|
116
|
+
span.setStatus({
|
|
117
|
+
code: SpanStatusCode.ERROR,
|
|
118
|
+
message: sanitized ?? message,
|
|
121
119
|
});
|
|
122
|
-
span.setStatus({ code: SpanStatusCode.ERROR, message });
|
|
123
120
|
span.end();
|
|
124
|
-
|
|
125
|
-
recordRequestDuration(duration, effectiveProvider, effectiveModel);
|
|
126
|
-
recordError(effectiveProvider, effectiveModel);
|
|
121
|
+
handleErrorMetrics(err, duration, effectiveProvider, effectiveModel, budget, estimatedCost, config?.attributes);
|
|
127
122
|
throw err;
|
|
128
123
|
}
|
|
129
124
|
// Some SDKs (Gemini) return { stream: AsyncIterable } instead of a direct AsyncIterable
|
|
@@ -179,42 +174,23 @@ original, patch, providerName) {
|
|
|
179
174
|
else {
|
|
180
175
|
span.setStatus({ code: SpanStatusCode.OK });
|
|
181
176
|
}
|
|
182
|
-
|
|
183
|
-
|
|
184
|
-
|
|
185
|
-
|
|
186
|
-
|
|
187
|
-
|
|
188
|
-
|
|
189
|
-
|
|
190
|
-
|
|
191
|
-
|
|
192
|
-
|
|
193
|
-
|
|
194
|
-
|
|
195
|
-
|
|
196
|
-
if (pricing?.maxContextTokens && acc.inputTokens > 0) {
|
|
197
|
-
const utilization = acc.inputTokens / pricing.maxContextTokens;
|
|
198
|
-
span.setAttribute(GEN_AI_ATTRS.CONTEXT_UTILIZATION, utilization);
|
|
199
|
-
recordContextUtilization(utilization, effectiveProvider, effectiveModel);
|
|
200
|
-
// Context guard — post-stream warning
|
|
201
|
-
const guard = config?.contextGuard;
|
|
202
|
-
if (guard) {
|
|
203
|
-
if (guard.alertAt !== undefined && utilization >= guard.alertAt) {
|
|
204
|
-
recordContextBlocked(effectiveModel);
|
|
205
|
-
span.addEvent("gen_ai.context.limit_exceeded", {
|
|
206
|
-
"gen_ai.toad_eye.context_utilization": utilization,
|
|
207
|
-
"gen_ai.toad_eye.context.threshold": guard.alertAt,
|
|
208
|
-
});
|
|
209
|
-
console.warn(`toad-eye: context window ${(utilization * 100).toFixed(0)}% full for ${effectiveModel} — exceeds alertAt threshold ${(guard.alertAt * 100).toFixed(0)}%. Compress context before next call.`);
|
|
210
|
-
}
|
|
211
|
-
else if (guard.warnAt !== undefined &&
|
|
212
|
-
utilization >= guard.warnAt) {
|
|
213
|
-
console.warn(`toad-eye: context window ${(utilization * 100).toFixed(0)}% full for ${effectiveModel} (${acc.inputTokens}/${pricing.maxContextTokens} tokens)`);
|
|
214
|
-
}
|
|
215
|
-
}
|
|
177
|
+
const attrs = config?.attributes;
|
|
178
|
+
recordSuccessMetrics({
|
|
179
|
+
duration,
|
|
180
|
+
provider: effectiveProvider,
|
|
181
|
+
model: effectiveModel,
|
|
182
|
+
cost,
|
|
183
|
+
inputTokens: acc.inputTokens,
|
|
184
|
+
outputTokens: acc.outputTokens,
|
|
185
|
+
completion: acc.completion,
|
|
186
|
+
attrs,
|
|
187
|
+
});
|
|
188
|
+
// SAFETY finish reason is an error for metrics
|
|
189
|
+
if (acc.finishReason === "SAFETY") {
|
|
190
|
+
recordError(effectiveProvider, effectiveModel, attrs);
|
|
216
191
|
}
|
|
217
|
-
|
|
192
|
+
evaluateContextGuard(span, effectiveModel, effectiveProvider, acc.inputTokens);
|
|
193
|
+
// Prefill/decode latency split (streaming-specific)
|
|
218
194
|
if (ttftMs > 0) {
|
|
219
195
|
const decodeMs = duration - ttftMs;
|
|
220
196
|
span.setAttribute("gen_ai.toad_eye.latency.decode_ms", decodeMs);
|
|
@@ -222,29 +198,26 @@ original, patch, providerName) {
|
|
|
222
198
|
span.setAttribute("gen_ai.toad_eye.throughput.tokens_per_second", acc.outputTokens / (decodeMs / 1000));
|
|
223
199
|
}
|
|
224
200
|
}
|
|
225
|
-
|
|
226
|
-
|
|
227
|
-
|
|
228
|
-
if (exceeded) {
|
|
229
|
-
recordBudgetExceeded(exceeded.budget);
|
|
230
|
-
console.warn(`toad-eye: ${exceeded.budget} budget exceeded — limit $${exceeded.limit}, current $${exceeded.current.toFixed(2)}`);
|
|
231
|
-
}
|
|
232
|
-
}
|
|
201
|
+
recordBudgetPostCheck(budget, cost, effectiveModel, userId, estimatedCost);
|
|
202
|
+
// span.end() AFTER all span writes including budget post-check
|
|
203
|
+
span.end();
|
|
233
204
|
}, (err) => {
|
|
234
205
|
const duration = performance.now() - start;
|
|
235
206
|
const message = err instanceof Error ? err.message : String(err);
|
|
236
|
-
|
|
237
|
-
if (budget)
|
|
238
|
-
budget.releaseReservation(estimatedCost);
|
|
207
|
+
const sanitized = processContent(message);
|
|
239
208
|
span.setAttributes({
|
|
209
|
+
[GEN_AI_ATTRS.INPUT_TOKENS]: 0,
|
|
210
|
+
[GEN_AI_ATTRS.OUTPUT_TOKENS]: 0,
|
|
211
|
+
[GEN_AI_ATTRS.COST]: 0,
|
|
240
212
|
[GEN_AI_ATTRS.STATUS]: "error",
|
|
241
|
-
[GEN_AI_ATTRS.ERROR]:
|
|
213
|
+
...(sanitized !== undefined && { [GEN_AI_ATTRS.ERROR]: sanitized }),
|
|
214
|
+
});
|
|
215
|
+
span.setStatus({
|
|
216
|
+
code: SpanStatusCode.ERROR,
|
|
217
|
+
message: sanitized ?? message,
|
|
242
218
|
});
|
|
243
|
-
span.setStatus({ code: SpanStatusCode.ERROR, message });
|
|
244
219
|
span.end();
|
|
245
|
-
|
|
246
|
-
recordRequestDuration(duration, effectiveProvider, effectiveModel);
|
|
247
|
-
recordError(effectiveProvider, effectiveModel);
|
|
220
|
+
handleErrorMetrics(err, duration, effectiveProvider, effectiveModel, budget, estimatedCost, config?.attributes);
|
|
248
221
|
}));
|
|
249
222
|
// Proxy preserves the original object shape (getters, private fields, methods)
|
|
250
223
|
// while intercepting only the async iterator for instrumentation
|
package/dist/mcp/middleware.d.ts
CHANGED
|
@@ -9,10 +9,8 @@
|
|
|
9
9
|
* and strict TypeScript. Wrapping the public API is the stable path.
|
|
10
10
|
*/
|
|
11
11
|
import type { ToadMcpOptions } from "./types.js";
|
|
12
|
-
|
|
13
|
-
|
|
14
|
-
(): void;
|
|
15
|
-
}
|
|
12
|
+
/** Call when the MCP server is shutting down to decrement the active session counter. */
|
|
13
|
+
export type ToadEyeMiddlewareDispose = () => void;
|
|
16
14
|
export declare function toadEyeMiddleware(server: any, options?: ToadMcpOptions): ToadEyeMiddlewareDispose;
|
|
17
15
|
/**
|
|
18
16
|
* Trace a sampling/createMessage call (server → client LLM request).
|
package/dist/vercel.d.ts
CHANGED
|
@@ -20,7 +20,7 @@
|
|
|
20
20
|
* });
|
|
21
21
|
* ```
|
|
22
22
|
*/
|
|
23
|
-
import type { SpanProcessor, ReadableSpan } from "@opentelemetry/sdk-trace
|
|
23
|
+
import type { SpanProcessor, ReadableSpan } from "@opentelemetry/sdk-trace";
|
|
24
24
|
/**
|
|
25
25
|
* OTel SpanProcessor that enriches Vercel AI SDK spans with toad-eye
|
|
26
26
|
* cost attributes and records metrics.
|
package/package.json
CHANGED
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
{
|
|
2
2
|
"name": "toad-eye",
|
|
3
|
-
"version": "2.
|
|
3
|
+
"version": "2.13.0",
|
|
4
4
|
"description": "Observability for MCP servers and LLM applications — traces, metrics, dashboards. One-line instrumentation for OpenAI, Anthropic, Gemini, and MCP. Self-hosted with Grafana + Prometheus + Jaeger.",
|
|
5
5
|
"type": "module",
|
|
6
6
|
"main": "dist/index.js",
|
|
@@ -87,23 +87,23 @@
|
|
|
87
87
|
],
|
|
88
88
|
"license": "ISC",
|
|
89
89
|
"dependencies": {
|
|
90
|
-
"@opentelemetry/api": "^1.
|
|
91
|
-
"@opentelemetry/
|
|
92
|
-
"@opentelemetry/exporter-
|
|
93
|
-
"@opentelemetry/
|
|
94
|
-
"@opentelemetry/
|
|
95
|
-
"@opentelemetry/sdk-
|
|
96
|
-
"@opentelemetry/sdk-
|
|
97
|
-
"@opentelemetry/sdk-trace
|
|
98
|
-
"@opentelemetry/semantic-conventions": "^1.
|
|
99
|
-
"yaml": "^2.
|
|
90
|
+
"@opentelemetry/api": "^1.10.0",
|
|
91
|
+
"@opentelemetry/core": "^3.1.0",
|
|
92
|
+
"@opentelemetry/exporter-metrics-otlp-http": "^0.301.0",
|
|
93
|
+
"@opentelemetry/exporter-trace-otlp-http": "^0.301.0",
|
|
94
|
+
"@opentelemetry/resources": "^3.1.0",
|
|
95
|
+
"@opentelemetry/sdk-metrics": "^3.1.0",
|
|
96
|
+
"@opentelemetry/sdk-node": "^0.301.0",
|
|
97
|
+
"@opentelemetry/sdk-trace": "^3.1.0",
|
|
98
|
+
"@opentelemetry/semantic-conventions": "^1.44.0",
|
|
99
|
+
"yaml": "^2.9.1"
|
|
100
100
|
},
|
|
101
101
|
"peerDependencies": {
|
|
102
102
|
"@anthropic-ai/sdk": ">=0.30.0",
|
|
103
103
|
"@google/generative-ai": ">=0.20.0",
|
|
104
|
+
"@modelcontextprotocol/sdk": ">=1.0.0",
|
|
104
105
|
"nodemailer": ">=8.0.0",
|
|
105
|
-
"openai": ">=4.0.0"
|
|
106
|
-
"@modelcontextprotocol/sdk": ">=1.0.0"
|
|
106
|
+
"openai": ">=4.0.0"
|
|
107
107
|
},
|
|
108
108
|
"peerDependenciesMeta": {
|
|
109
109
|
"openai": {
|
|
@@ -123,7 +123,7 @@
|
|
|
123
123
|
}
|
|
124
124
|
},
|
|
125
125
|
"devDependencies": {
|
|
126
|
-
"@types/nodemailer": "^
|
|
127
|
-
"vitest": "^
|
|
126
|
+
"@types/nodemailer": "^8.0.2",
|
|
127
|
+
"vitest": "^5.1.0"
|
|
128
128
|
}
|
|
129
129
|
}
|
package/dist/context/error.d.ts
DELETED
|
@@ -1,15 +0,0 @@
|
|
|
1
|
-
/** Thrown when context guard blockAt threshold is exceeded. */
|
|
2
|
-
export declare class ToadContextExceededError extends Error {
|
|
3
|
-
readonly utilization: number;
|
|
4
|
-
readonly threshold: number;
|
|
5
|
-
readonly model: string;
|
|
6
|
-
readonly maxContextTokens: number;
|
|
7
|
-
readonly inputTokens: number;
|
|
8
|
-
constructor(info: {
|
|
9
|
-
utilization: number;
|
|
10
|
-
threshold: number;
|
|
11
|
-
model: string;
|
|
12
|
-
maxContextTokens: number;
|
|
13
|
-
inputTokens: number;
|
|
14
|
-
});
|
|
15
|
-
}
|
package/dist/context/error.js
DELETED
|
@@ -1,17 +0,0 @@
|
|
|
1
|
-
/** Thrown when context guard blockAt threshold is exceeded. */
|
|
2
|
-
export class ToadContextExceededError extends Error {
|
|
3
|
-
utilization;
|
|
4
|
-
threshold;
|
|
5
|
-
model;
|
|
6
|
-
maxContextTokens;
|
|
7
|
-
inputTokens;
|
|
8
|
-
constructor(info) {
|
|
9
|
-
super(`toad-eye: context window ${(info.utilization * 100).toFixed(0)}% full (${info.inputTokens}/${info.maxContextTokens} tokens) for model ${info.model} — blocked at ${(info.threshold * 100).toFixed(0)}%`);
|
|
10
|
-
this.name = "ToadContextExceededError";
|
|
11
|
-
this.utilization = info.utilization;
|
|
12
|
-
this.threshold = info.threshold;
|
|
13
|
-
this.model = info.model;
|
|
14
|
-
this.maxContextTokens = info.maxContextTokens;
|
|
15
|
-
this.inputTokens = info.inputTokens;
|
|
16
|
-
}
|
|
17
|
-
}
|
package/dist/context/guard.d.ts
DELETED
|
@@ -1,8 +0,0 @@
|
|
|
1
|
-
export declare function resetContextGuardState(): void;
|
|
2
|
-
/**
|
|
3
|
-
* Check context utilization before an LLM call.
|
|
4
|
-
* - If utilization > blockAt → throw ToadContextExceededError
|
|
5
|
-
* - If utilization > warnAt → console.warn (once per model per session)
|
|
6
|
-
* - If model unknown or no guard configured → skip silently
|
|
7
|
-
*/
|
|
8
|
-
export declare function checkContextGuard(model: string, inputTokens: number): void;
|
package/dist/context/guard.js
DELETED
|
@@ -1,41 +0,0 @@
|
|
|
1
|
-
import { getModelPricing } from "../core/pricing.js";
|
|
2
|
-
import { getConfig } from "../core/tracer.js";
|
|
3
|
-
import { ToadContextExceededError } from "./error.js";
|
|
4
|
-
let warnedModels = new Set();
|
|
5
|
-
export function resetContextGuardState() {
|
|
6
|
-
warnedModels = new Set();
|
|
7
|
-
}
|
|
8
|
-
/**
|
|
9
|
-
* Check context utilization before an LLM call.
|
|
10
|
-
* - If utilization > blockAt → throw ToadContextExceededError
|
|
11
|
-
* - If utilization > warnAt → console.warn (once per model per session)
|
|
12
|
-
* - If model unknown or no guard configured → skip silently
|
|
13
|
-
*/
|
|
14
|
-
export function checkContextGuard(model, inputTokens) {
|
|
15
|
-
if (inputTokens <= 0)
|
|
16
|
-
return;
|
|
17
|
-
const config = getConfig();
|
|
18
|
-
const guard = config?.contextGuard;
|
|
19
|
-
if (!guard)
|
|
20
|
-
return;
|
|
21
|
-
const pricing = getModelPricing(model);
|
|
22
|
-
if (!pricing?.maxContextTokens)
|
|
23
|
-
return;
|
|
24
|
-
const utilization = inputTokens / pricing.maxContextTokens;
|
|
25
|
-
if (guard.blockAt !== undefined && utilization >= guard.blockAt) {
|
|
26
|
-
throw new ToadContextExceededError({
|
|
27
|
-
utilization,
|
|
28
|
-
threshold: guard.blockAt,
|
|
29
|
-
model,
|
|
30
|
-
maxContextTokens: pricing.maxContextTokens,
|
|
31
|
-
inputTokens,
|
|
32
|
-
});
|
|
33
|
-
}
|
|
34
|
-
if (guard.warnAt !== undefined && utilization >= guard.warnAt) {
|
|
35
|
-
const key = `${model}:${Math.floor(utilization * 10)}`;
|
|
36
|
-
if (!warnedModels.has(key)) {
|
|
37
|
-
warnedModels.add(key);
|
|
38
|
-
console.warn(`toad-eye: context window ${(utilization * 100).toFixed(0)}% full for ${model} (${inputTokens}/${pricing.maxContextTokens} tokens)`);
|
|
39
|
-
}
|
|
40
|
-
}
|
|
41
|
-
}
|