seo-crawl-audit 0.10.3 → 0.12.0
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.md +32 -7
- package/bundle/cli.js +82 -53
- package/bundle/mcp.js +49 -19
- package/bundle/server.js +71 -41
- package/package.json +3 -3
package/README.md
CHANGED
|
@@ -8,7 +8,7 @@ needs no account or API key. Page HTML is processed in memory; normalized
|
|
|
8
8
|
results stay in local JSON, checkpoint, CSV, and self-contained HTML files.
|
|
9
9
|
|
|
10
10
|
[Open the interactive example report](https://melnixdev.github.io/seo-crawl-audit/)
|
|
11
|
-
or [view its source file](examples/quotes-toscrape-report.html).
|
|
11
|
+
or [view its source file](https://github.com/MelnixDev/seo-crawl-audit/blob/main/examples/quotes-toscrape-report.html).
|
|
12
12
|
|
|
13
13
|
## Report preview
|
|
14
14
|
|
|
@@ -21,7 +21,9 @@ without a server.
|
|
|
21
21
|
|
|
22
22
|
|
|
23
23
|
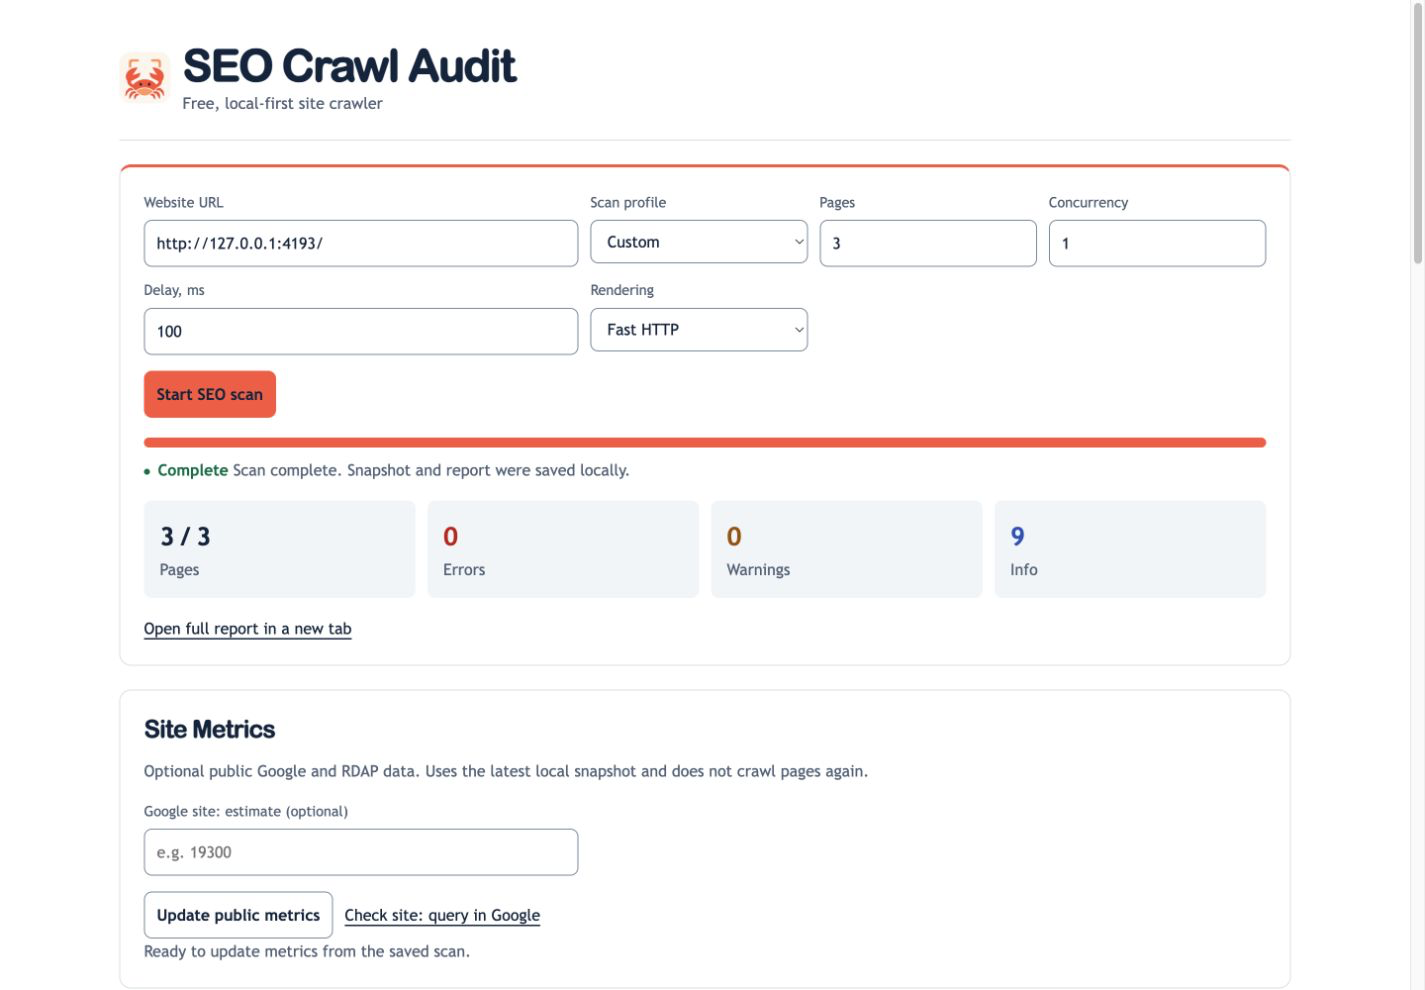
Run `seo-audit serve` to start scans from a loopback-only browser interface,
|
|
24
|
-
follow progress, and open the generated local report.
|
|
24
|
+
follow progress, and open the generated local report. Choose Quick (100),
|
|
25
|
+
Standard (1,000), Full sitemap, or a Custom page limit. Full sitemap first shows
|
|
26
|
+
the discovered URL count and requires explicit confirmation above 5,000 URLs.
|
|
25
27
|
|
|
26
28
|
### Overview and local history
|
|
27
29
|
|
|
@@ -162,14 +164,17 @@ and public RDAP data are updated through a separate Site Metrics action after a
|
|
|
162
164
|
scan, without crawling the pages again; every estimate is labelled and kept
|
|
163
165
|
separate from authoritative Search Console data.
|
|
164
166
|
[Read the Site Metrics guide](https://github.com/MelnixDev/seo-crawl-audit/blob/main/docs/site-metrics.md).
|
|
167
|
+
[Read the large-scan and resume guide](https://github.com/MelnixDev/seo-crawl-audit/blob/main/docs/large-scans.md).
|
|
165
168
|
|
|
166
|
-
|
|
169
|
+
Agents can use the local STDIO MCP server and a portable project skill:
|
|
167
170
|
|
|
168
171
|
```bash
|
|
169
172
|
npx seo-crawl-audit agent-init --platform all
|
|
170
173
|
```
|
|
171
174
|
|
|
172
|
-
|
|
175
|
+
This prepares project-scoped integrations for Codex, Claude Code, and OpenCode
|
|
176
|
+
without replacing existing configuration files. [Read the agent integration
|
|
177
|
+
guide](https://github.com/MelnixDev/seo-crawl-audit/blob/main/docs/agent-integration.md).
|
|
173
178
|
|
|
174
179
|
Protected preview or staging site credentials can be supplied through a named
|
|
175
180
|
JSON environment variable. [Read the authenticated scans guide](https://github.com/MelnixDev/seo-crawl-audit/blob/main/docs/authenticated-scans.md).
|
|
@@ -287,6 +292,9 @@ When a sitemap is found in an interactive terminal, the menu offers the first
|
|
|
287
292
|
100 pages, every sitemap URL, groups of 100 with confirmation, or a custom
|
|
288
293
|
number. `--pages` and `--all` skip the menu. If no sitemap is found, press Enter
|
|
289
294
|
to continue through same-origin internal links, or enter the full sitemap URL.
|
|
295
|
+
With `--json`, progress is written to stderr so stdout remains valid JSON for
|
|
296
|
+
scripts and CI. The CLI shows the planning phase, robots/sitemap status, crawl
|
|
297
|
+
phase, retries, and a live page progress bar while it runs.
|
|
290
298
|
|
|
291
299
|
### `seo-audit check [url]`
|
|
292
300
|
|
|
@@ -404,7 +412,7 @@ seo-audit history \
|
|
|
404
412
|
## Configuration
|
|
405
413
|
|
|
406
414
|
The repository includes [`seo-audit.config.json`](seo-audit.config.json) and a
|
|
407
|
-
[JSON Schema](packages/core/config.schema.json). CLI flags take precedence over
|
|
415
|
+
[JSON Schema](https://github.com/MelnixDev/seo-crawl-audit/blob/main/packages/core/config.schema.json). CLI flags take precedence over
|
|
408
416
|
the config file, which takes precedence over the saved baseline, followed by
|
|
409
417
|
safe defaults.
|
|
410
418
|
|
|
@@ -484,6 +492,10 @@ compatible command resumes without requesting saved pages again. The checkpoint
|
|
|
484
492
|
is removed after completion and retained after interruption. Successful pages
|
|
485
493
|
are reused; transient failures and HTTP 5xx results are refreshed. Only an
|
|
486
494
|
unfinished final NDJSON record is recoverable—earlier corruption is reported.
|
|
495
|
+
For large runs, the NDJSON journal stays on disk until the final snapshot and
|
|
496
|
+
report are written successfully. Checkpoint inspection is streamed instead of
|
|
497
|
+
loading the entire journal as text. The supported local UI and MCP ceiling is
|
|
498
|
+
50,000 pages; use a responsible delay and scan only sites you may crawl.
|
|
487
499
|
|
|
488
500
|
Every completed scan and check also saves a full SnapshotV2 beside the selected
|
|
489
501
|
baseline under `.seo-audit/history/`. Use `--history-dir` to move it or
|
|
@@ -506,6 +518,10 @@ It includes:
|
|
|
506
518
|
- summary cards and partial-scan state;
|
|
507
519
|
- current and lifecycle tabs;
|
|
508
520
|
- severity, rule, inferred template, owner, and URL/text filters;
|
|
521
|
+
- a Pages / Сторінки explorer with status, observed indexability, metadata,
|
|
522
|
+
depth, transfer size, links, page-level issue counts, and on-demand details;
|
|
523
|
+
- page search, status/indexability/issue filters, deterministic sorting,
|
|
524
|
+
pagination, and filtered page CSV export;
|
|
509
525
|
- evidence, before/after values, remediation, and fingerprint;
|
|
510
526
|
- engine and rule-set versions;
|
|
511
527
|
- client-side CSV export;
|
|
@@ -513,6 +529,15 @@ It includes:
|
|
|
513
529
|
- optional local agency name, logo, and primary color;
|
|
514
530
|
- clear clean-report and no-filter-match states.
|
|
515
531
|
|
|
532
|
+
Reports render only the current paginated issue rows, debounce text search, and
|
|
533
|
+
build CSV only when requested. Reports above 25,000 issues show a performance
|
|
534
|
+
notice while remaining self-contained.
|
|
535
|
+
|
|
536
|
+
Page Explorer uses only the current snapshot and makes no network requests.
|
|
537
|
+
Its indexability labels describe crawler-observed restrictions; they do not
|
|
538
|
+
claim that a search engine has indexed a URL. Reports made from legacy minimal
|
|
539
|
+
page data keep working and show unavailable details as `—`.
|
|
540
|
+
|
|
516
541
|
Template grouping turns repeated findings such as `/products/red-shoe` and
|
|
517
542
|
`/products/blue-shirt` into `/products/:slug`. Numeric IDs, UUIDs, dates, and
|
|
518
543
|
hashes have stable placeholders. Grouping changes only presentation: rule IDs,
|
|
@@ -587,8 +612,8 @@ const result = await scan(plan, {
|
|
|
587
612
|
const issues = audit(result.snapshot);
|
|
588
613
|
```
|
|
589
614
|
|
|
590
|
-
[Read the typed public API guide](docs/public-api.md) and the
|
|
591
|
-
[architecture notes](docs/architecture.md).
|
|
615
|
+
[Read the typed public API guide](https://github.com/MelnixDev/seo-crawl-audit/blob/main/docs/public-api.md) and the
|
|
616
|
+
[architecture notes](https://github.com/MelnixDev/seo-crawl-audit/blob/main/docs/architecture.md).
|
|
592
617
|
|
|
593
618
|
## Responsible crawling and safe defaults
|
|
594
619
|
|