seo-crawl-audit 0.1.2 → 0.7.2
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.md +335 -228
- package/bin/seo-audit.js +18 -3
- package/bundle/cli.js +154 -0
- package/package.json +10 -8
- package/examples/quotes-toscrape-report.html +0 -423
- package/src/audit.js +0 -125
- package/src/baseline.js +0 -65
- package/src/checkpoint.js +0 -90
- package/src/cli.js +0 -850
- package/src/compare.js +0 -205
- package/src/crawler.js +0 -306
- package/src/html-report.js +0 -474
- package/src/html.js +0 -105
- package/src/report.js +0 -43
- package/src/request-gate.js +0 -27
- package/src/robots.js +0 -80
- package/src/sitemap.js +0 -212
- package/src/target.js +0 -35
- package/src/urls.js +0 -45
package/README.md
CHANGED
|
@@ -1,48 +1,101 @@
|
|
|
1
1
|
# SEO Crawl Audit
|
|
2
2
|
|
|
3
|
-
|
|
4
|
-
|
|
5
|
-
|
|
6
|
-
|
|
7
|
-
account
|
|
8
|
-
|
|
9
|
-
|
|
10
|
-
|
|
11
|
-
|
|
12
|
-
|
|
13
|
-
|
|
14
|
-
|
|
15
|
-
|
|
16
|
-
|
|
17
|
-
|
|
18
|
-
|
|
19
|
-
|
|
20
|
-
|
|
21
|
-
|
|
3
|
+
Free, open-source, local-first SEO crawler and regression audit tool.
|
|
4
|
+
|
|
5
|
+
`seo-audit` crawls server-rendered pages, saves a versioned JSON snapshot,
|
|
6
|
+
finds concrete SEO problems, and detects regressions after a deployment. It
|
|
7
|
+
needs no account or API key. Page HTML is processed in memory; normalized
|
|
8
|
+
results stay in local JSON, checkpoint, CSV, and self-contained HTML files.
|
|
9
|
+
|
|
10
|
+
[Open the interactive example report](https://melnixdev.github.io/seo-crawl-audit/)
|
|
11
|
+
or [view its source file](examples/quotes-toscrape-report.html).
|
|
12
|
+
|
|
13
|
+
## Report preview
|
|
14
|
+
|
|
15
|
+
The report is a self-contained HTML file: open it locally, share it as an
|
|
16
|
+
artifact, or publish the same file on GitHub Pages. Charts and filters work
|
|
17
|
+
without a server.
|
|
18
|
+
|
|
19
|
+
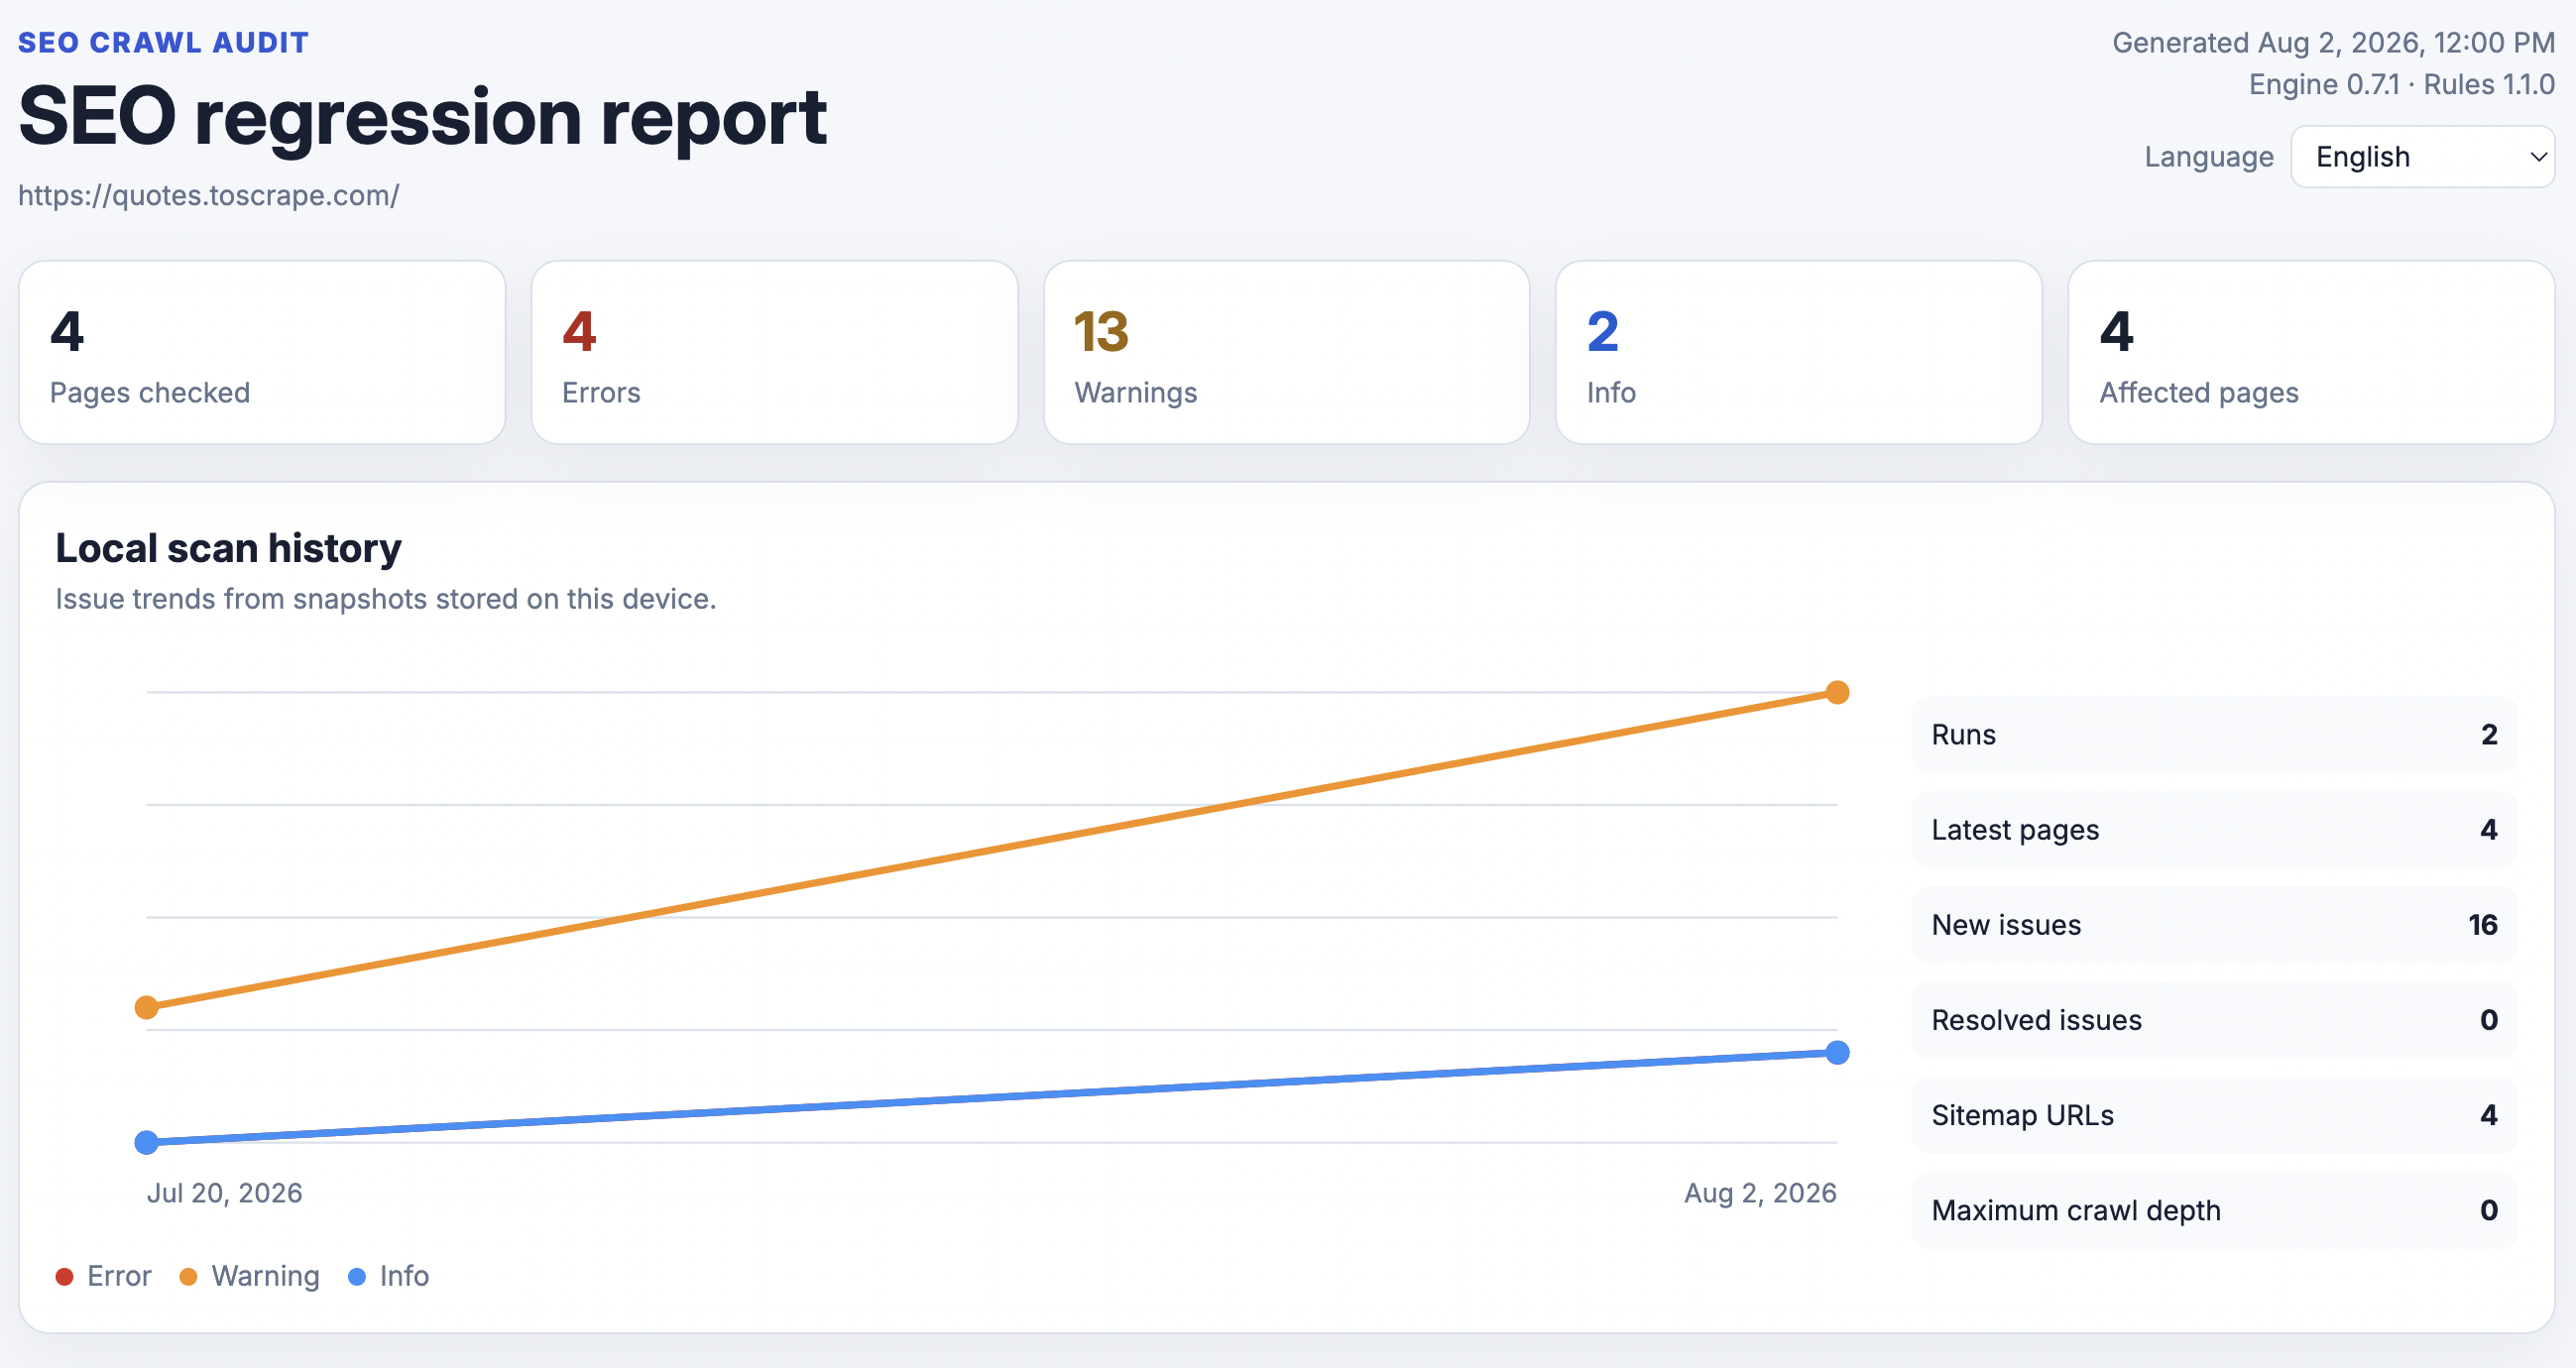
### Overview and local history
|
|
20
|
+
|
|
21
|
+
|
|
22
|
+
|
|
23
|
+
The overview keeps scan coverage, issue counts, and locally stored trends in
|
|
24
|
+
one place.
|
|
25
|
+
|
|
26
|
+
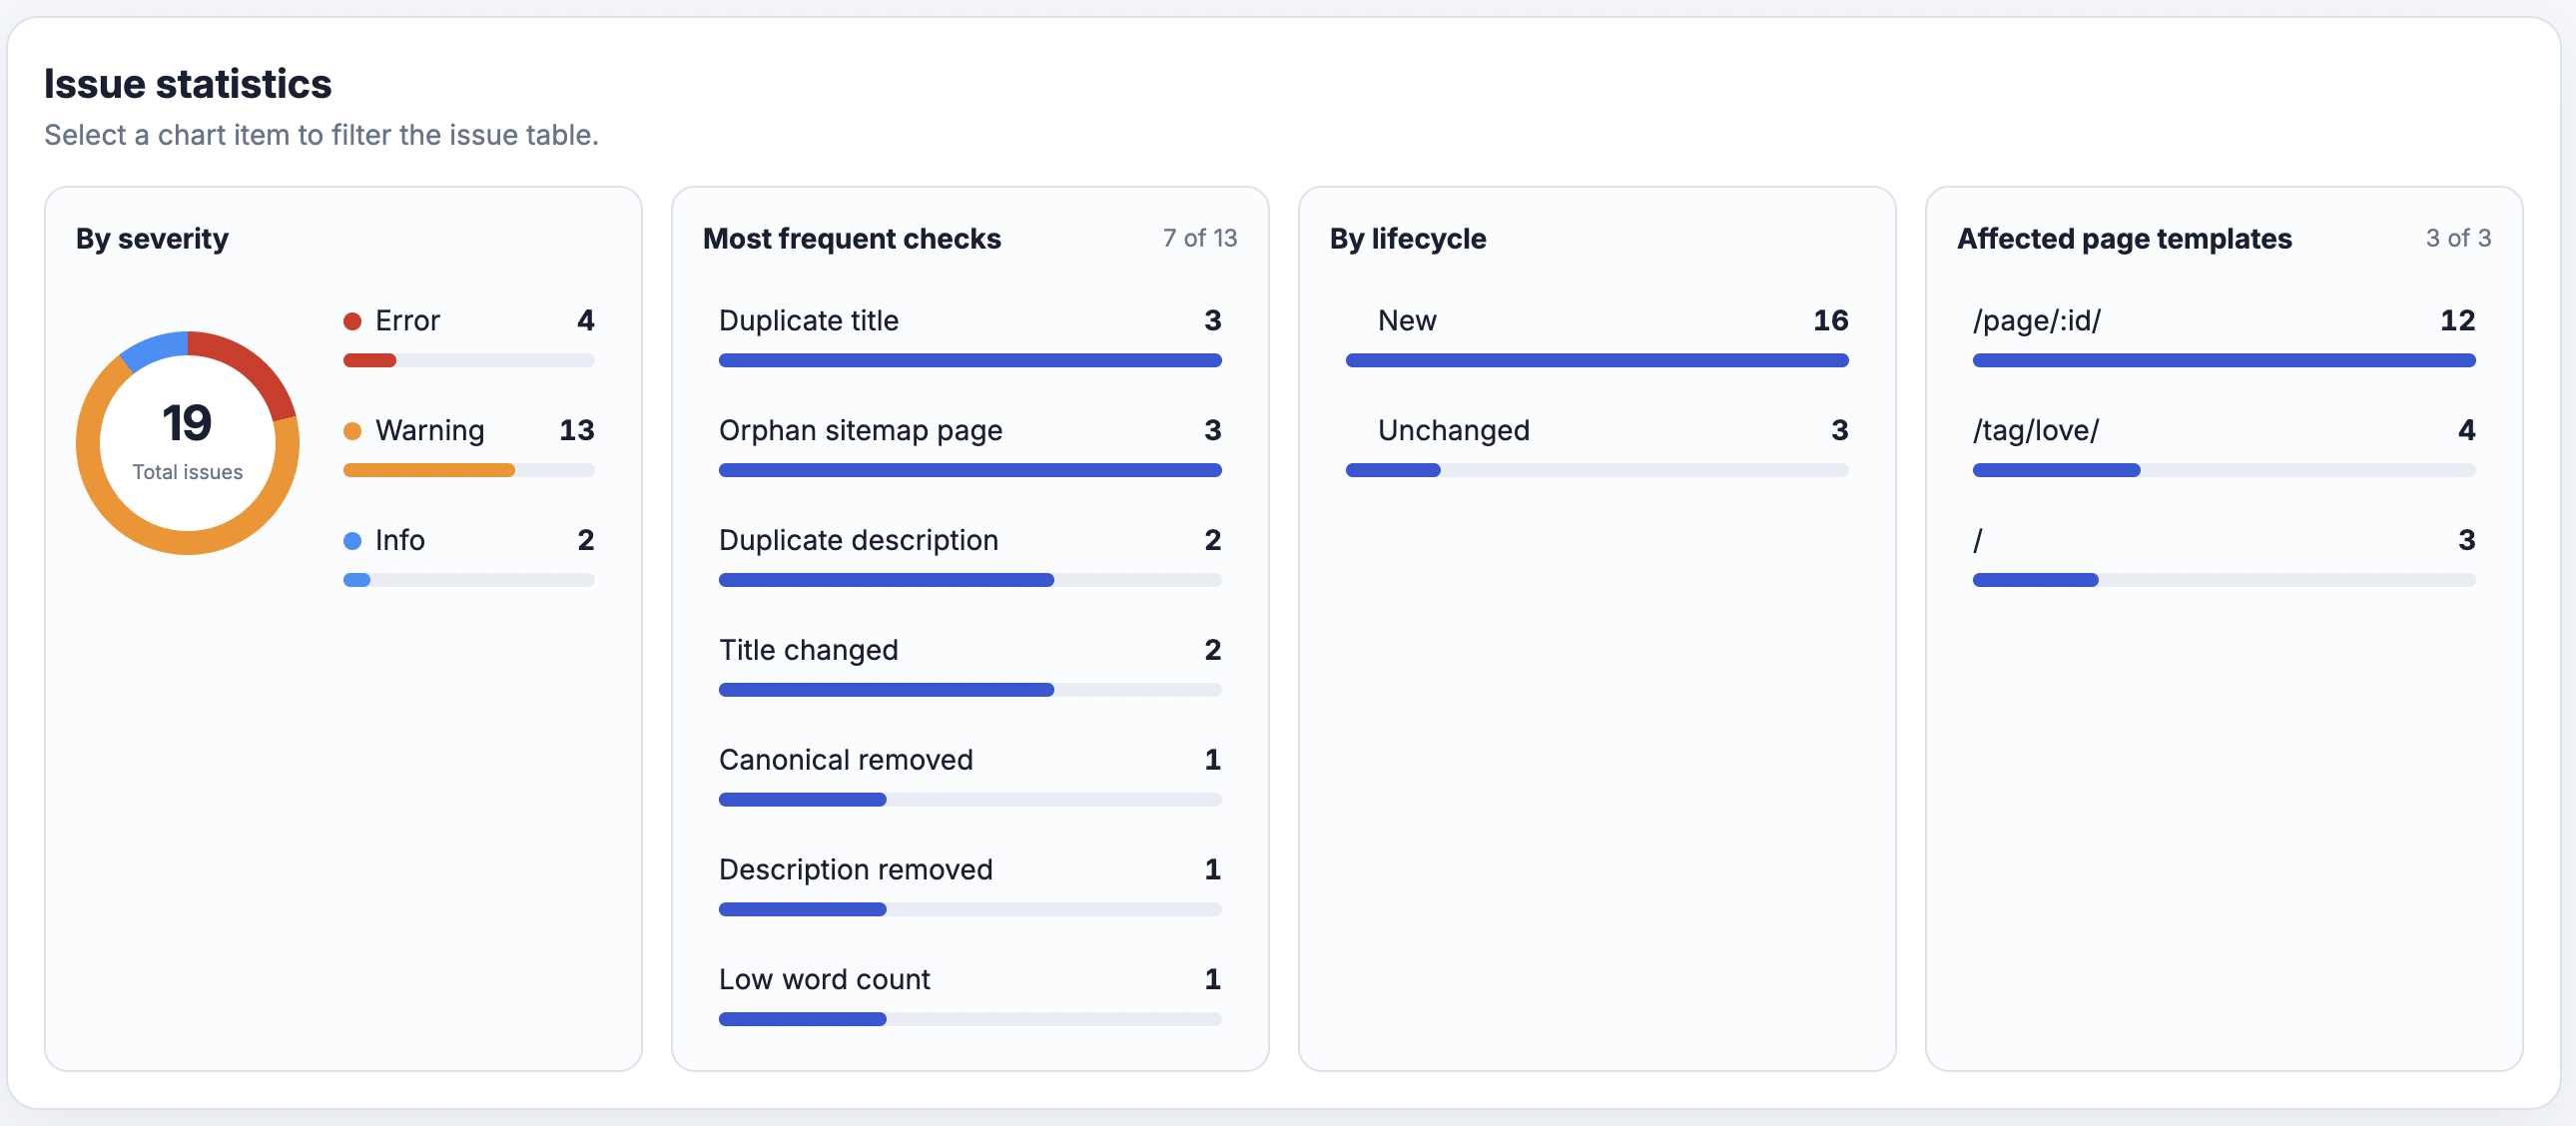
### Interactive issue analytics
|
|
27
|
+
|
|
28
|
+
|
|
29
|
+
|
|
30
|
+
Select a severity, rule, lifecycle state, or page template to filter the issue
|
|
31
|
+
table immediately.
|
|
32
|
+
|
|
33
|
+
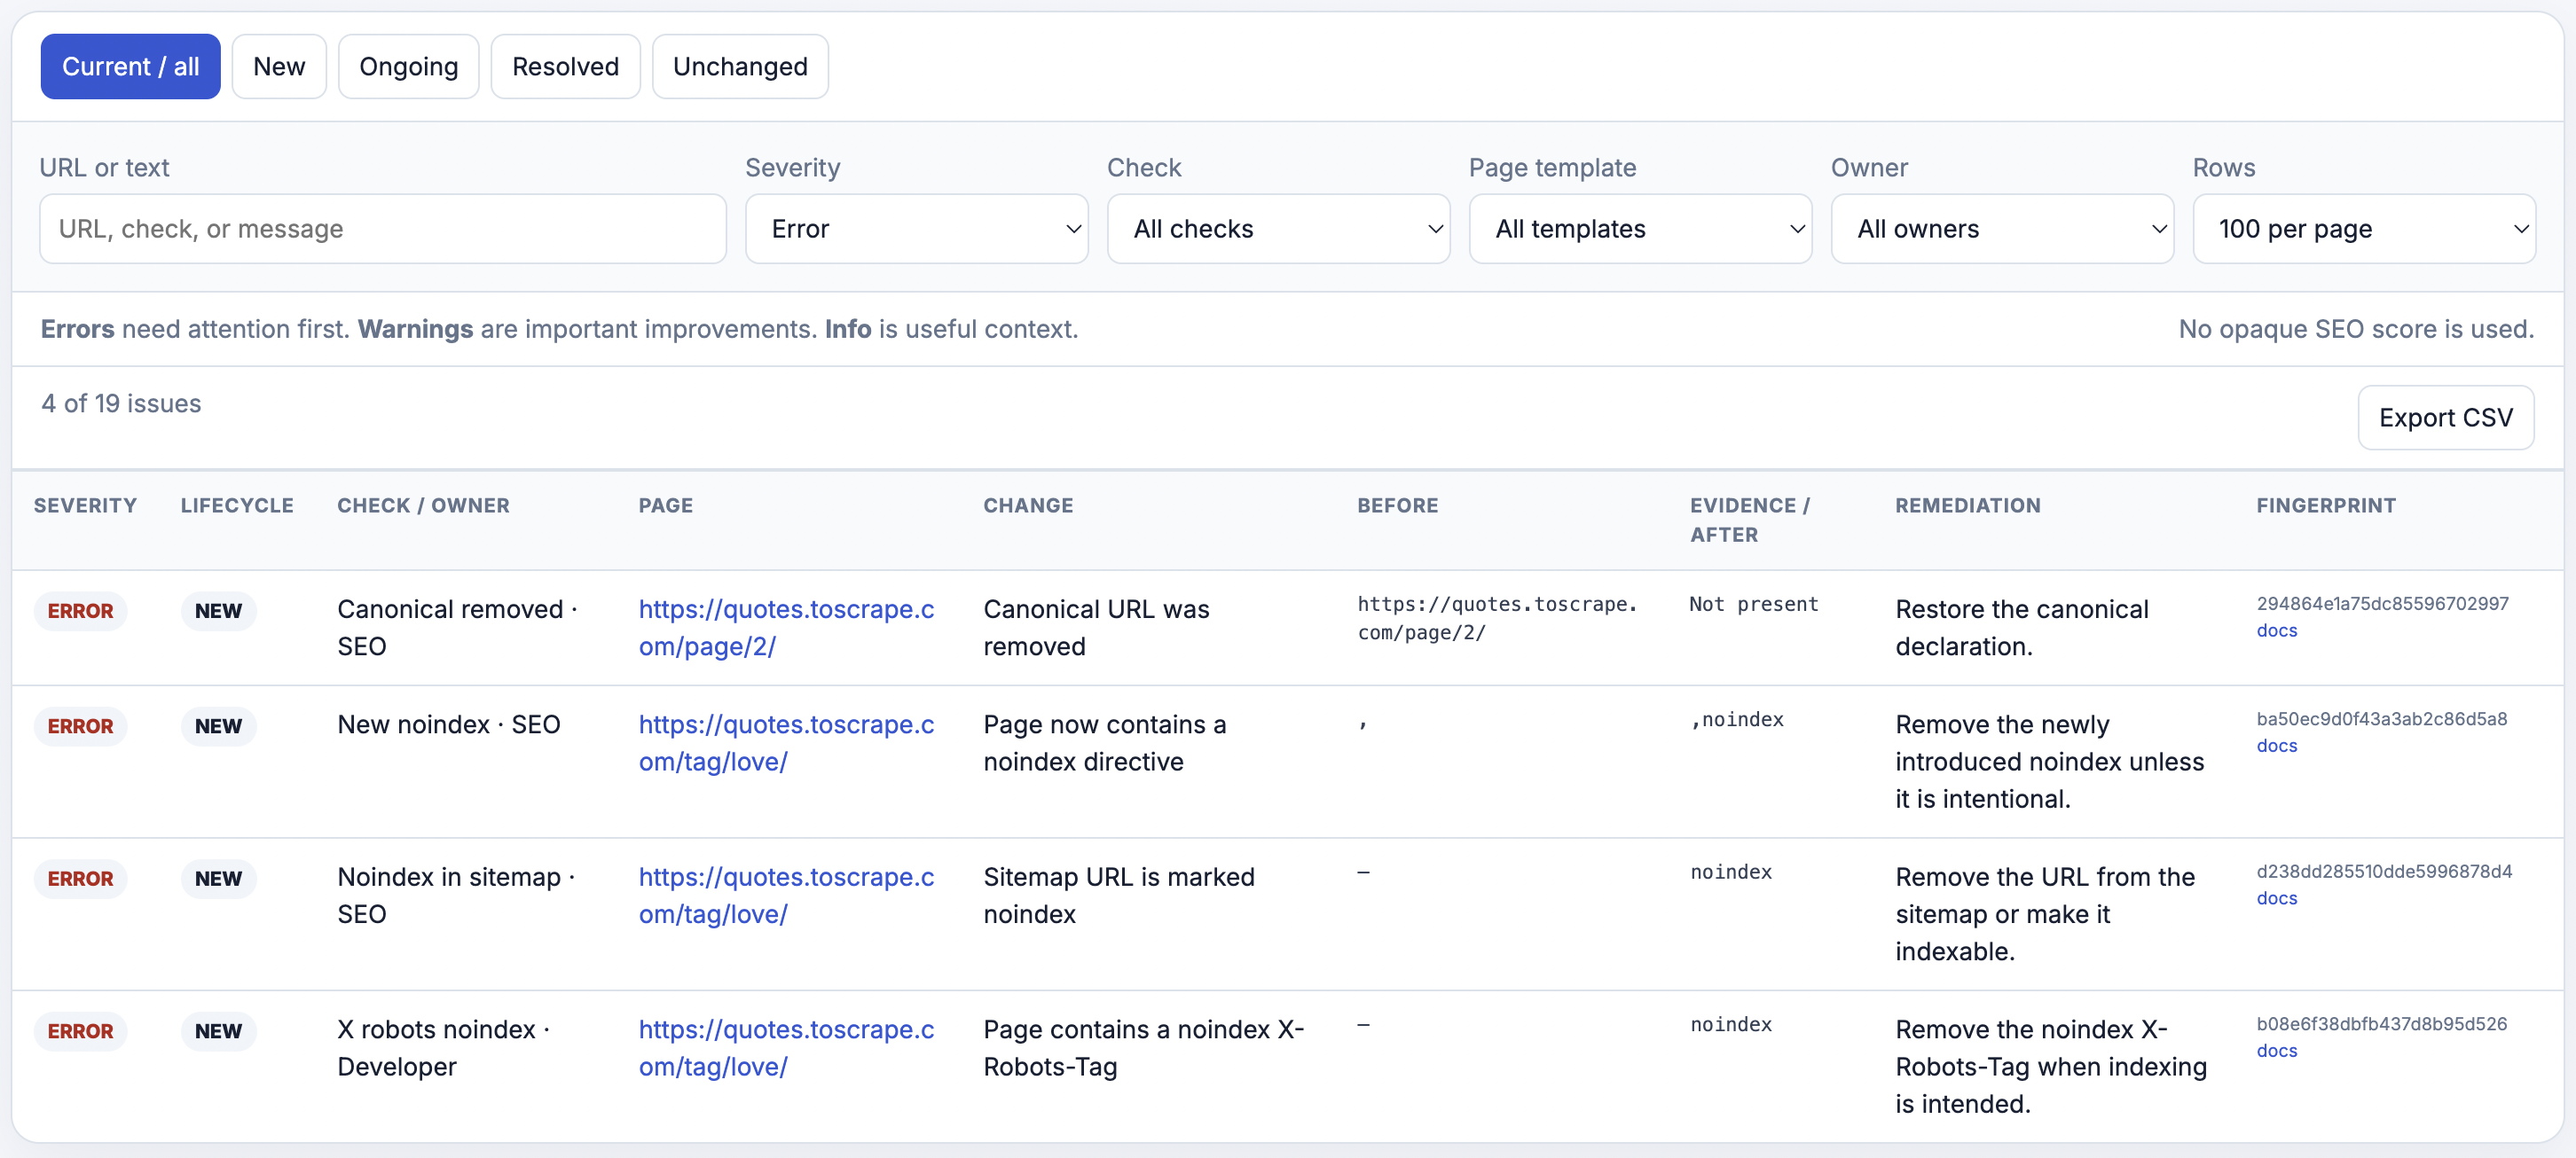
### Filtered issue table
|
|
34
|
+
|
|
35
|
+
|
|
36
|
+
|
|
37
|
+
Chart selections and report filters narrow the table to the findings that need
|
|
38
|
+
attention, with evidence and remediation kept alongside each issue.
|
|
39
|
+
|
|
40
|
+
## Highlights
|
|
41
|
+
|
|
42
|
+
- automatic `robots.txt`, sitemap, sitemap-index, and gzip sitemap support;
|
|
43
|
+
- bounded concurrency with a per-origin request delay;
|
|
44
|
+
- retries for timeouts, `429`, and temporary `5xx`, including `Retry-After`;
|
|
45
|
+
- redirect-chain and redirect-loop detection;
|
|
46
|
+
- 40+ explicit audit and regression rules with stable fingerprints;
|
|
47
|
+
- SnapshotV2 with automatic baseline v1 migration;
|
|
48
|
+
- `new`, `ongoing`, `resolved`, and `unchanged` issue lifecycle;
|
|
49
|
+
- resumable scans and a useful report even after interruption;
|
|
50
|
+
- local SnapshotV2 history with issue, page-count, sitemap, and crawl-depth
|
|
51
|
+
trends—without a hosted account;
|
|
52
|
+
- English/Ukrainian report localization, filters, CSV export, print layout,
|
|
53
|
+
and local report branding;
|
|
54
|
+
- interactive issue statistics for severity, frequent checks, ownership, and
|
|
55
|
+
regression lifecycle, with chart-to-table filtering;
|
|
56
|
+
- a production-versus-preview release guard with safe environment-based
|
|
57
|
+
authentication for private deployments;
|
|
58
|
+
- configuration, suppressions with expiry, severity overrides, and budgets;
|
|
59
|
+
- a self-contained GitHub Action that runs inside the GitHub runner;
|
|
60
|
+
- typed engine API with injectable `fetch`, checkpoints, events, logger, and
|
|
61
|
+
`AbortSignal`.
|
|
62
|
+
|
|
63
|
+
The project intentionally does not calculate an opaque overall SEO score.
|
|
64
|
+
Every finding names the affected URL, rule, risk, evidence, owner, and suggested
|
|
65
|
+
remediation.
|
|
22
66
|
|
|
23
67
|
## Requirements and installation
|
|
24
68
|
|
|
25
69
|
Node.js 20.19 or newer is required.
|
|
26
70
|
|
|
71
|
+
Run without installing:
|
|
72
|
+
|
|
27
73
|
```bash
|
|
28
|
-
|
|
29
|
-
cd seo-crawl-audit
|
|
30
|
-
npm install
|
|
31
|
-
npm link
|
|
74
|
+
npx seo-crawl-audit https://example.com/
|
|
32
75
|
```
|
|
33
76
|
|
|
34
|
-
|
|
77
|
+
Or install the CLI globally:
|
|
35
78
|
|
|
36
79
|
```bash
|
|
80
|
+
npm install --global seo-crawl-audit
|
|
37
81
|
seo-audit --version
|
|
38
|
-
seo-audit --help
|
|
39
82
|
```
|
|
40
83
|
|
|
41
|
-
|
|
84
|
+
For repository development:
|
|
85
|
+
|
|
86
|
+
```bash
|
|
87
|
+
git clone https://github.com/MelnixDev/seo-crawl-audit.git
|
|
88
|
+
cd seo-crawl-audit
|
|
89
|
+
npm install
|
|
90
|
+
npm run build
|
|
91
|
+
npm link --workspace seo-crawl-audit
|
|
92
|
+
```
|
|
93
|
+
|
|
94
|
+
## Five-minute example
|
|
42
95
|
|
|
43
96
|
[Quotes to Scrape](https://quotes.toscrape.com/) is a public educational site
|
|
44
|
-
made for crawler practice. It is unrelated to this project and keeps the
|
|
45
|
-
small
|
|
97
|
+
made for crawler practice. It is unrelated to this project and keeps the
|
|
98
|
+
example small.
|
|
46
99
|
|
|
47
100
|
```bash
|
|
48
101
|
seo-audit scan https://quotes.toscrape.com/ \
|
|
@@ -52,15 +105,7 @@ seo-audit scan https://quotes.toscrape.com/ \
|
|
|
52
105
|
--report quotes-report.html
|
|
53
106
|
```
|
|
54
107
|
|
|
55
|
-
|
|
56
|
-
HTML report. In the current demo scan, the tool finds missing descriptions and
|
|
57
|
-
canonical URLs while the pages themselves remain reachable.
|
|
58
|
-
|
|
59
|
-
[View the included example report](examples/quotes-toscrape-report.html). GitHub
|
|
60
|
-
may show the HTML source; download the file and open it in any browser to use
|
|
61
|
-
the filters.
|
|
62
|
-
|
|
63
|
-
Run a fresh comparison later:
|
|
108
|
+
Run a comparison later:
|
|
64
109
|
|
|
65
110
|
```bash
|
|
66
111
|
seo-audit check https://quotes.toscrape.com/ \
|
|
@@ -73,7 +118,7 @@ seo-audit check https://quotes.toscrape.com/ \
|
|
|
73
118
|
|
|
74
119
|
### `seo-audit <url>`
|
|
75
120
|
|
|
76
|
-
|
|
121
|
+
Shortcut for `seo-audit scan <url>`.
|
|
77
122
|
|
|
78
123
|
```bash
|
|
79
124
|
seo-audit https://example.com/
|
|
@@ -81,7 +126,8 @@ seo-audit https://example.com/
|
|
|
81
126
|
|
|
82
127
|
### `seo-audit scan <url>`
|
|
83
128
|
|
|
84
|
-
Crawls a site, audits its current
|
|
129
|
+
Crawls a site, audits its current state, saves SnapshotV2, and optionally writes
|
|
130
|
+
an HTML report.
|
|
85
131
|
|
|
86
132
|
```bash
|
|
87
133
|
seo-audit scan https://example.com/
|
|
@@ -89,25 +135,14 @@ seo-audit scan https://example.com/ --pages 250
|
|
|
89
135
|
seo-audit scan https://example.com/ --all
|
|
90
136
|
```
|
|
91
137
|
|
|
92
|
-
|
|
93
|
-
|
|
94
|
-
|
|
95
|
-
|
|
96
|
-
3. tries `/sitemap.xml` and `/sitemap_index.xml` when needed;
|
|
97
|
-
4. shows an interactive scan-size menu when a sitemap is found;
|
|
98
|
-
5. saves the baseline to `.seo-audit.json`;
|
|
99
|
-
6. creates `seo-audit-report.html` in an interactive terminal.
|
|
100
|
-
|
|
101
|
-
The menu offers the first 100 pages, the whole sitemap, batches of 100 with
|
|
102
|
-
confirmation, or any positive number entered by the user. `--pages` and `--all`
|
|
103
|
-
skip that menu.
|
|
104
|
-
|
|
105
|
-
If no sitemap is found, the interactive command asks for its full URL. Pressing
|
|
106
|
-
Enter instead starts a same-origin internal-link crawl.
|
|
138
|
+
When a sitemap is found in an interactive terminal, the menu offers the first
|
|
139
|
+
100 pages, every sitemap URL, groups of 100 with confirmation, or a custom
|
|
140
|
+
number. `--pages` and `--all` skip the menu. If no sitemap is found, press Enter
|
|
141
|
+
to continue through same-origin internal links, or enter the full sitemap URL.
|
|
107
142
|
|
|
108
143
|
### `seo-audit check [url]`
|
|
109
144
|
|
|
110
|
-
Crawls
|
|
145
|
+
Crawls again and compares the result with a saved baseline.
|
|
111
146
|
|
|
112
147
|
```bash
|
|
113
148
|
seo-audit check
|
|
@@ -115,258 +150,330 @@ seo-audit check https://preview.example.com/
|
|
|
115
150
|
seo-audit check --baseline production-seo.json --strict
|
|
116
151
|
```
|
|
117
152
|
|
|
118
|
-
|
|
119
|
-
|
|
120
|
-
|
|
153
|
+
Without `url`, the saved site URL is used. A different origin supports
|
|
154
|
+
production-to-preview comparison while keeping paths comparable. New
|
|
155
|
+
error-level findings return exit code `1`; `--strict` also blocks on warnings.
|
|
156
|
+
If `scan` receives SIGINT or SIGTERM, it flushes completed pages, writes the
|
|
157
|
+
partial snapshot/report, keeps the checkpoint, and exits with code `130`.
|
|
121
158
|
|
|
122
|
-
|
|
123
|
-
`--strict` is enabled.
|
|
159
|
+
### `seo-audit compare`
|
|
124
160
|
|
|
125
|
-
|
|
126
|
-
|
|
127
|
-
Builds a new HTML audit report from an existing baseline without crawling or
|
|
128
|
-
making network requests.
|
|
161
|
+
Scans production, requests the same paths from a preview deployment, and
|
|
162
|
+
reports only SEO regressions introduced by the preview:
|
|
129
163
|
|
|
130
164
|
```bash
|
|
131
|
-
seo-audit
|
|
132
|
-
|
|
133
|
-
|
|
165
|
+
seo-audit compare \
|
|
166
|
+
--production https://example.com/ \
|
|
167
|
+
--preview https://preview-123.example.dev/ \
|
|
168
|
+
--pages 100 \
|
|
169
|
+
--report preview-seo-report.html
|
|
134
170
|
```
|
|
135
171
|
|
|
136
|
-
|
|
137
|
-
|
|
138
|
-
|
|
139
|
-
## HTML report
|
|
140
|
-
|
|
141
|
-
The report is one portable HTML file with no external scripts, fonts, tracking,
|
|
142
|
-
or uploaded data. It contains:
|
|
143
|
-
|
|
144
|
-
- summary cards for checked and affected pages;
|
|
145
|
-
- error, warning, and informational issue counts;
|
|
146
|
-
- free-text search across URL, rule, message, before, and after values;
|
|
147
|
-
- severity and rule filters;
|
|
148
|
-
- paginated results with 100, 250, or 500 rows per page;
|
|
149
|
-
- direct links to affected pages;
|
|
150
|
-
- before/after values for regression checks.
|
|
151
|
-
|
|
152
|
-
During an interactive `scan`, the report is created immediately and refreshed
|
|
153
|
-
after the first completed request batch, then periodically as the scan grows.
|
|
154
|
-
Writes are atomic, so interruption should not leave a half-written HTML file.
|
|
155
|
-
A partial report clearly says that it contains saved results and shows
|
|
156
|
-
`checked / target` page counts.
|
|
157
|
-
|
|
158
|
-
Interactive `scan` and `check` commands create the default report automatically.
|
|
159
|
-
For scripts or CI, request one explicitly:
|
|
172
|
+
For a protected deployment, put request headers in an environment variable as
|
|
173
|
+
a JSON object and pass only its name on the command line:
|
|
160
174
|
|
|
161
175
|
```bash
|
|
162
|
-
|
|
163
|
-
seo-audit
|
|
176
|
+
export SEO_AUDIT_PREVIEW_HEADERS='{"Authorization":"Bearer …"}'
|
|
177
|
+
seo-audit compare \
|
|
178
|
+
--production https://example.com/ \
|
|
179
|
+
--preview https://preview-123.example.dev/ \
|
|
180
|
+
--preview-headers-env SEO_AUDIT_PREVIEW_HEADERS
|
|
164
181
|
```
|
|
165
182
|
|
|
166
|
-
|
|
167
|
-
|
|
168
|
-
|
|
169
|
-
|
|
170
|
-
`scan` stores completed page results in an append-only checkpoint beside the
|
|
171
|
-
baseline. For the default `.seo-audit.json` output, its name is:
|
|
183
|
+
Header values are used only by the injected request adapter. They are never
|
|
184
|
+
written to snapshots, reports, checkpoints, or JSON output. Errors block the
|
|
185
|
+
release with exit code `1`; `--strict` also blocks on warnings.
|
|
172
186
|
|
|
173
|
-
|
|
174
|
-
.seo-audit.checkpoint.ndjson
|
|
175
|
-
```
|
|
187
|
+
### `seo-audit report [baseline]`
|
|
176
188
|
|
|
177
|
-
|
|
178
|
-
page HTML. Each completed request batch is appended immediately. If the process
|
|
179
|
-
is stopped, run the same compatible scan command again:
|
|
189
|
+
Regenerates HTML from a saved snapshot without network requests.
|
|
180
190
|
|
|
181
191
|
```bash
|
|
182
|
-
seo-audit
|
|
192
|
+
seo-audit report
|
|
193
|
+
seo-audit report quotes-baseline.json --report quotes-report.html
|
|
183
194
|
```
|
|
184
195
|
|
|
185
|
-
|
|
186
|
-
is reused only when the start URL, sitemap, query-string policy, and robots
|
|
187
|
-
policy match. An incompatible checkpoint is replaced automatically.
|
|
196
|
+
### `seo-audit history [url]`
|
|
188
197
|
|
|
189
|
-
|
|
190
|
-
when a stepped scan is stopped before its target or when the process is
|
|
191
|
-
interrupted. Checkpoint files are excluded by the included `.gitignore`.
|
|
192
|
-
|
|
193
|
-
To deliberately make every request without reading or writing a checkpoint:
|
|
198
|
+
Lists locally saved runs and creates an HTML report with issue trends:
|
|
194
199
|
|
|
195
200
|
```bash
|
|
196
|
-
seo-audit https://example.com/
|
|
201
|
+
seo-audit history https://example.com/
|
|
202
|
+
seo-audit history --history-dir ./audit-history --report history.html
|
|
197
203
|
```
|
|
198
204
|
|
|
199
|
-
|
|
200
|
-
observe the current response from every baseline URL.
|
|
201
|
-
|
|
202
|
-
## What is checked
|
|
205
|
+
Compare any two saved runs without crawling:
|
|
203
206
|
|
|
204
|
-
|
|
205
|
-
|
|
206
|
-
-
|
|
207
|
-
-
|
|
208
|
-
-
|
|
209
|
-
|
|
210
|
-
- missing meta descriptions;
|
|
211
|
-
- missing canonical URLs;
|
|
212
|
-
- missing or multiple H1 headings;
|
|
213
|
-
- `noindex` directives.
|
|
214
|
-
|
|
215
|
-
The regression check detects:
|
|
216
|
-
|
|
217
|
-
- a previously working page becoming unavailable;
|
|
218
|
-
- a new `noindex` directive;
|
|
219
|
-
- a page becoming blocked by `robots.txt`;
|
|
220
|
-
- a removed or changed title;
|
|
221
|
-
- a removed meta description;
|
|
222
|
-
- a removed or changed canonical URL;
|
|
223
|
-
- a removed H1 heading;
|
|
224
|
-
- a changed redirect destination;
|
|
225
|
-
- a changed `robots.txt`.
|
|
226
|
-
|
|
227
|
-
Errors represent changes or conditions likely to block indexing or make a page
|
|
228
|
-
unusable. Warnings identify important metadata problems. Informational findings
|
|
229
|
-
are worth reviewing but do not fail a normal check.
|
|
207
|
+
```bash
|
|
208
|
+
seo-audit history \
|
|
209
|
+
--from .seo-audit/history/older.snapshot.json \
|
|
210
|
+
--to .seo-audit/history/newer.snapshot.json \
|
|
211
|
+
--report selected-runs.html
|
|
212
|
+
```
|
|
230
213
|
|
|
231
214
|
## Options
|
|
232
215
|
|
|
233
216
|
```text
|
|
234
217
|
--baseline <file> Baseline input for check (default: .seo-audit.json)
|
|
235
|
-
--
|
|
218
|
+
--config <file> Config file (default: seo-audit.config.json)
|
|
219
|
+
--output <file> Snapshot output for scan (default: .seo-audit.json)
|
|
236
220
|
--report <file> HTML report output (default: seo-audit-report.html)
|
|
237
221
|
--no-report Disable automatic HTML report generation
|
|
238
|
-
--no-cache Disable
|
|
222
|
+
--no-cache Disable checkpoint caching and resume
|
|
239
223
|
--pages <number> Scan an exact number of pages
|
|
240
224
|
--all Scan every URL found in the sitemap
|
|
241
225
|
--max-pages <number> Deprecated alias for --pages
|
|
242
226
|
--concurrency <number> Concurrent requests (default: 5)
|
|
243
|
-
--delay <ms> Delay between
|
|
227
|
+
--delay <ms> Delay between starts per origin (default: 100)
|
|
244
228
|
--timeout <ms> Per-request timeout (default: 10000)
|
|
245
229
|
--sitemap <url> Use a specific sitemap or sitemap index
|
|
246
230
|
--no-sitemap Skip sitemap discovery and crawl internal links
|
|
247
231
|
--include-query Treat query-string URLs as separate pages
|
|
248
232
|
--ignore-robots Ignore robots.txt disallow rules
|
|
249
233
|
--strict Fail check on warnings as well as errors
|
|
250
|
-
--
|
|
251
|
-
--
|
|
234
|
+
--production <url> Production URL for compare
|
|
235
|
+
--preview <url> Preview deployment URL for compare
|
|
236
|
+
--production-headers-env <name>
|
|
237
|
+
Read production headers from a JSON environment variable
|
|
238
|
+
--preview-headers-env <name>
|
|
239
|
+
Read preview headers from a JSON environment variable
|
|
240
|
+
--history-dir <path> Local snapshot history directory
|
|
241
|
+
--no-history Do not save this scan to local history
|
|
242
|
+
--from <snapshot> Older snapshot for an explicit history comparison
|
|
243
|
+
--to <snapshot> Newer snapshot for an explicit history comparison
|
|
244
|
+
--json Print machine-readable output
|
|
245
|
+
--help Show help
|
|
252
246
|
--version Show the installed version
|
|
253
247
|
```
|
|
254
248
|
|
|
255
|
-
|
|
256
|
-
|
|
257
|
-
|
|
258
|
-
|
|
259
|
-
|
|
260
|
-
|
|
261
|
-
|
|
262
|
-
|
|
263
|
-
|
|
264
|
-
|
|
265
|
-
|
|
266
|
-
|
|
267
|
-
|
|
268
|
-
|
|
269
|
-
|
|
270
|
-
|
|
271
|
-
|
|
272
|
-
|
|
273
|
-
|
|
274
|
-
|
|
275
|
-
|
|
276
|
-
|
|
277
|
-
|
|
278
|
-
|
|
279
|
-
|
|
280
|
-
|
|
281
|
-
|
|
282
|
-
|
|
283
|
-
|
|
284
|
-
|
|
285
|
-
|
|
286
|
-
|
|
287
|
-
|
|
288
|
-
|
|
289
|
-
|
|
290
|
-
|
|
291
|
-
|
|
292
|
-
|
|
293
|
-
|
|
249
|
+
## Configuration
|
|
250
|
+
|
|
251
|
+
The repository includes [`seo-audit.config.json`](seo-audit.config.json) and a
|
|
252
|
+
[JSON Schema](packages/core/config.schema.json). CLI flags take precedence over
|
|
253
|
+
the config file, which takes precedence over the saved baseline, followed by
|
|
254
|
+
safe defaults.
|
|
255
|
+
|
|
256
|
+
```json
|
|
257
|
+
{
|
|
258
|
+
"$schema": "./packages/core/config.schema.json",
|
|
259
|
+
"url": "https://example.com/",
|
|
260
|
+
"sitemap": "auto",
|
|
261
|
+
"maxPages": 100,
|
|
262
|
+
"concurrency": 5,
|
|
263
|
+
"delay": 100,
|
|
264
|
+
"timeout": 10000,
|
|
265
|
+
"respectRobots": true,
|
|
266
|
+
"includeQuery": false,
|
|
267
|
+
"enabledRules": null,
|
|
268
|
+
"severityOverrides": {
|
|
269
|
+
"low-word-count": "info"
|
|
270
|
+
},
|
|
271
|
+
"suppressions": [
|
|
272
|
+
{
|
|
273
|
+
"rule": "missing-description",
|
|
274
|
+
"urlPattern": "/legal/**",
|
|
275
|
+
"reason": "Description intentionally omitted",
|
|
276
|
+
"expiresAt": "2027-01-01"
|
|
277
|
+
}
|
|
278
|
+
],
|
|
279
|
+
"regressionBudgets": {
|
|
280
|
+
"error": 0,
|
|
281
|
+
"warning": 3
|
|
282
|
+
},
|
|
283
|
+
"report": {
|
|
284
|
+
"agencyName": "Example Agency",
|
|
285
|
+
"logo": "https://example.com/logo.png",
|
|
286
|
+
"primaryColor": "#3157d5"
|
|
287
|
+
}
|
|
288
|
+
}
|
|
294
289
|
```
|
|
295
290
|
|
|
296
|
-
|
|
291
|
+
Expired suppressions stop matching automatically, so the issue appears again.
|
|
292
|
+
`urlPattern` accepts `*` within one path segment and `**` across segments.
|
|
297
293
|
|
|
298
|
-
##
|
|
294
|
+
## What is checked
|
|
299
295
|
|
|
300
|
-
|
|
301
|
-
|
|
296
|
+
The rule registry covers access and HTTP failures, meta and header `noindex`,
|
|
297
|
+
robots blocking, canonical validity and targets, redirects, sitemap consistency,
|
|
298
|
+
titles, descriptions, headings, internal links, orphan pages, hreflang,
|
|
299
|
+
structured data syntax, language declarations, exact duplicate content, social
|
|
300
|
+
metadata, image alt attributes, and low word count.
|
|
301
|
+
|
|
302
|
+
Regression-only checks cover newly introduced indexing blocks, status changes,
|
|
303
|
+
metadata removal or edits, redirect changes, robots changes, and sharp sitemap
|
|
304
|
+
URL loss.
|
|
305
|
+
|
|
306
|
+
[Read the rule-by-rule documentation](https://github.com/MelnixDev/seo-crawl-audit/blob/main/docs/rules.md) ·
|
|
307
|
+
[Українська версія довідника правил](https://github.com/MelnixDev/seo-crawl-audit/blob/main/docs/rules.uk.md).
|
|
308
|
+
|
|
309
|
+
## Snapshots, lifecycle, and checkpoints
|
|
310
|
+
|
|
311
|
+
SnapshotV2 records schema, engine and rule-set versions, generated time, config
|
|
312
|
+
hash, robots and sitemap state, normalized page data, link-graph summary, and
|
|
313
|
+
crawl statistics. Baseline schema v1 is upgraded automatically when read.
|
|
314
|
+
|
|
315
|
+
Issues use a stable 24-character fingerprint. A comparison separates:
|
|
316
|
+
|
|
317
|
+
- `newIssues` — absent from the previous snapshot;
|
|
318
|
+
- `ongoingIssues` — same issue identity with changed evidence;
|
|
319
|
+
- `resolvedIssues` — present before but absent now;
|
|
320
|
+
- `unchangedIssues` — same identity and evidence.
|
|
321
|
+
|
|
322
|
+
`DiffResult.complete` is `false` for partial or truncated comparisons. Findings
|
|
323
|
+
on checked pages are still reported, while unchecked pages are not falsely
|
|
324
|
+
classified as missing or resolved.
|
|
325
|
+
|
|
326
|
+
During `scan`, completed normalized page results are appended to
|
|
327
|
+
`.seo-audit.checkpoint.ndjson`. Full HTML is not cached. Running the same
|
|
328
|
+
compatible command resumes without requesting saved pages again. The checkpoint
|
|
329
|
+
is removed after completion and retained after interruption. Successful pages
|
|
330
|
+
are reused; transient failures and HTTP 5xx results are refreshed. Only an
|
|
331
|
+
unfinished final NDJSON record is recoverable—earlier corruption is reported.
|
|
332
|
+
|
|
333
|
+
Every completed scan and check also saves a full SnapshotV2 beside the selected
|
|
334
|
+
baseline under `.seo-audit/history/`. Use `--history-dir` to move it or
|
|
335
|
+
`--no-history` for an ephemeral run. History is read directly from disk; no URL,
|
|
336
|
+
snapshot, or metric is uploaded. The HTML trend view shows errors, warnings,
|
|
337
|
+
informational findings, new/resolved issues, page count, sitemap count, and
|
|
338
|
+
maximum crawl depth.
|
|
339
|
+
|
|
340
|
+
## HTML and CSV report
|
|
341
|
+
|
|
342
|
+
The portable HTML file contains no external script, font, or tracking request.
|
|
343
|
+
It includes:
|
|
344
|
+
|
|
345
|
+
- an `English / Українська` language selector that translates the complete
|
|
346
|
+
interface, rule names, findings, remediation, lifecycle labels, and CSV;
|
|
347
|
+
- dependency-free interactive charts for severity, most frequent checks,
|
|
348
|
+
inferred page templates, and owner or regression-lifecycle distribution;
|
|
349
|
+
selecting a chart item filters
|
|
350
|
+
the issue table and selecting it again clears that filter;
|
|
351
|
+
- summary cards and partial-scan state;
|
|
352
|
+
- current and lifecycle tabs;
|
|
353
|
+
- severity, rule, inferred template, owner, and URL/text filters;
|
|
354
|
+
- evidence, before/after values, remediation, and fingerprint;
|
|
355
|
+
- engine and rule-set versions;
|
|
356
|
+
- client-side CSV export;
|
|
357
|
+
- print-friendly PDF layout;
|
|
358
|
+
- optional local agency name, logo, and primary color;
|
|
359
|
+
- clear clean-report and no-filter-match states.
|
|
360
|
+
|
|
361
|
+
Template grouping turns repeated findings such as `/products/red-shoe` and
|
|
362
|
+
`/products/blue-shirt` into `/products/:slug`. Numeric IDs, UUIDs, dates, and
|
|
363
|
+
hashes have stable placeholders. Grouping changes only presentation: rule IDs,
|
|
364
|
+
evidence, snapshots, and issue fingerprints remain unchanged.
|
|
365
|
+
|
|
366
|
+
Writes are atomic. Interactive scans refresh a partial report while results are
|
|
367
|
+
being checkpointed, so interruption does not discard already completed work.
|
|
368
|
+
|
|
369
|
+
## GitHub Action
|
|
370
|
+
|
|
371
|
+
The Action crawls entirely inside the GitHub runner. It produces exit status,
|
|
372
|
+
JSON summary, HTML report, job summary, and annotations for error-level
|
|
373
|
+
regressions.
|
|
302
374
|
|
|
303
375
|
```yaml
|
|
304
376
|
name: SEO regression check
|
|
305
|
-
|
|
306
|
-
on:
|
|
307
|
-
pull_request:
|
|
377
|
+
on: [pull_request]
|
|
308
378
|
|
|
309
379
|
jobs:
|
|
310
380
|
seo:
|
|
311
381
|
runs-on: ubuntu-latest
|
|
312
382
|
steps:
|
|
313
383
|
- uses: actions/checkout@v4
|
|
314
|
-
- uses:
|
|
384
|
+
- uses: MelnixDev/seo-crawl-audit@v0
|
|
385
|
+
id: seo
|
|
315
386
|
with:
|
|
316
|
-
|
|
317
|
-
|
|
318
|
-
|
|
387
|
+
url: https://preview.example.com/
|
|
388
|
+
baseline: .seo-audit.json
|
|
389
|
+
config: seo-audit.config.json
|
|
390
|
+
fail-on: error
|
|
391
|
+
report: seo-audit-report.html
|
|
392
|
+
- uses: actions/upload-artifact@v4
|
|
393
|
+
with:
|
|
394
|
+
name: seo-crawl-audit-report
|
|
395
|
+
path: |
|
|
396
|
+
${{ steps.seo.outputs.report }}
|
|
397
|
+
${{ steps.seo.outputs.summary }}
|
|
319
398
|
```
|
|
320
399
|
|
|
321
|
-
|
|
322
|
-
when a human-readable CI report is useful.
|
|
400
|
+
[Read all Action inputs and outputs](docs/github-action.md).
|
|
323
401
|
|
|
324
|
-
##
|
|
402
|
+
## Core API and repository structure
|
|
325
403
|
|
|
326
|
-
The
|
|
327
|
-
starts requests at least 100 milliseconds apart, limits concurrency to five
|
|
328
|
-
in-flight requests, and applies a ten-second timeout. The same request gate is
|
|
329
|
-
used for `robots.txt`, sitemap discovery, sitemap files, and HTML pages.
|
|
404
|
+
The npm workspace separates reusable concerns:
|
|
330
405
|
|
|
331
|
-
|
|
406
|
+
```text
|
|
407
|
+
packages/core @seo-crawl-audit/core — scan, audit, diff, snapshots, reports
|
|
408
|
+
packages/cli seo-crawl-audit — terminal UX and npm executable
|
|
409
|
+
packages/action @seo-crawl-audit/action — GitHub runner entry point
|
|
410
|
+
```
|
|
332
411
|
|
|
333
|
-
|
|
334
|
-
seo-audit
|
|
412
|
+
`@seo-crawl-audit/core` is currently an internal workspace package and is not
|
|
413
|
+
published separately on npm. Install `seo-crawl-audit` for the supported,
|
|
414
|
+
self-contained CLI. The imports below document the repository API used by the
|
|
415
|
+
CLI and Action and are intended for contributors working in this workspace.
|
|
416
|
+
|
|
417
|
+
```ts
|
|
418
|
+
import { audit, planScan, scan } from "@seo-crawl-audit/core";
|
|
419
|
+
import { createFileCheckpointStore } from "@seo-crawl-audit/core/node";
|
|
420
|
+
|
|
421
|
+
const plan = await planScan({ url: "https://example.com/", maxPages: 100 });
|
|
422
|
+
const result = await scan(plan, {
|
|
423
|
+
signal: controller.signal,
|
|
424
|
+
checkpointStore: createFileCheckpointStore(".seo-audit.checkpoint.ndjson"),
|
|
425
|
+
onEvent(event) {
|
|
426
|
+
if (event.type === "progress") console.log(event.completed, event.total);
|
|
427
|
+
},
|
|
428
|
+
});
|
|
429
|
+
|
|
430
|
+
const issues = audit(result.snapshot);
|
|
335
431
|
```
|
|
336
432
|
|
|
337
|
-
|
|
338
|
-
|
|
339
|
-
|
|
433
|
+
[Read the typed public API guide](docs/public-api.md) and the
|
|
434
|
+
[architecture notes](docs/architecture.md).
|
|
435
|
+
|
|
436
|
+
## Responsible crawling and safe defaults
|
|
437
|
+
|
|
438
|
+
- delay: `100 ms` between request starts per origin;
|
|
439
|
+
- concurrency: `5`;
|
|
440
|
+
- timeout: `10 s`;
|
|
441
|
+
- `robots.txt` respected;
|
|
442
|
+
- same-origin page discovery;
|
|
443
|
+
- query strings excluded;
|
|
444
|
+
- HTML limited to `5 MiB` and robots to `512 KiB`;
|
|
445
|
+
- retries are bounded and use exponential backoff with jitter;
|
|
446
|
+
- `Retry-After` is honored up to 30 seconds;
|
|
447
|
+
- redirects are limited to 10.
|
|
448
|
+
|
|
449
|
+
Use a longer delay for a small site or a server you do not control:
|
|
340
450
|
|
|
341
451
|
```bash
|
|
342
|
-
seo-audit
|
|
452
|
+
seo-audit https://example.com/ --delay 500
|
|
343
453
|
```
|
|
344
454
|
|
|
345
|
-
|
|
346
|
-
so it is not a polite default for a public website. Increase concurrency or
|
|
347
|
-
reduce the delay only on sites you are allowed to test.
|
|
455
|
+
Use `--delay 0` only for local or explicitly controlled fixtures.
|
|
348
456
|
|
|
349
457
|
## Current scope
|
|
350
458
|
|
|
351
|
-
- server-rendered HTML
|
|
352
|
-
- same-origin
|
|
353
|
-
- sitemap and
|
|
354
|
-
-
|
|
355
|
-
-
|
|
356
|
-
-
|
|
357
|
-
- `robots.txt` responses are limited to 512 KiB;
|
|
358
|
-
- authenticated pages are not supported.
|
|
459
|
+
- server-rendered HTML; JavaScript rendering is not included;
|
|
460
|
+
- same-origin crawl discovery;
|
|
461
|
+
- sitemap and internal-link seeding;
|
|
462
|
+
- non-HTML responses are recorded but not parsed for page metadata;
|
|
463
|
+
- authenticated pages are not supported;
|
|
464
|
+
- results are normalized and ordered for reproducible output.
|
|
359
465
|
|
|
360
466
|
## Development
|
|
361
467
|
|
|
362
468
|
```bash
|
|
469
|
+
npm run build
|
|
363
470
|
npm test
|
|
364
471
|
npm run check
|
|
365
472
|
```
|
|
366
473
|
|
|
367
|
-
|
|
368
|
-
|
|
369
|
-
and
|
|
474
|
+
CI covers Node.js 20, 22, and 24. Tests use local HTTP fixtures for robots,
|
|
475
|
+
sitemaps, gzip, retries, redirects, cancellation, checkpoint resume, migration,
|
|
476
|
+
rules, lifecycle, HTML escaping, npm packaging, and the GitHub Action.
|
|
370
477
|
|
|
371
478
|
## License
|
|
372
479
|
|