sage-mem 2.9.0 → 2.10.2
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.en.md +59 -11
- package/README.md +59 -11
- package/lib/assembly/tools-mount.js +5 -2
- package/lib/autodream/audit.js +58 -1
- package/lib/autodream/prompt.js +30 -2
- package/lib/autodream/report.js +136 -1
- package/lib/autodream/size-tools.js +222 -0
- package/lib/autodream/tools.js +28 -2
- package/lib/autodream/util.js +3 -1
- package/lib/client.js +401 -66
- package/lib/memory/scan.js +6 -1
- package/lib/memory/size-policy.js +218 -0
- package/lib/memory/trim-archive.js +251 -0
- package/lib/memory/trim-plan.js +331 -0
- package/lib/memory/write-protocol.js +31 -2
- package/lib/shared/codes.js +13 -0
- package/lib/shared/limits.js +47 -0
- package/lib/tools/memory-tools.js +215 -6
- package/lib/typert.host.js +14 -0
- package/package.json +1 -1
- package/skills/sage-mem/SKILL.md +37 -2
package/README.en.md
CHANGED
|
@@ -12,7 +12,7 @@
|
|
|
12
12
|
|
|
13
13
|
**Cross-session memory for DeepSeek Harness — plain markdown files, no database, no worker.**
|
|
14
14
|
|
|
15
|
-
**Current release: `2.
|
|
15
|
+
**Current release: `2.10.2`** — the npm badge above is the dynamic source of truth. **Contract baseline: `1.0.0`** — the first stable release, whose public commitments, the capability boundaries and the list of things it explicitly cannot do are frozen in the
|
|
16
16
|
[frozen contract](https://github.com/gezi-wen/sage-mem/blob/main/docs/1.0.0-contract.md).
|
|
17
17
|
|
|
18
18
|
If it is useful to you, a Star is the most direct feedback.
|
|
@@ -27,6 +27,7 @@ If it is useful to you, a Star is the most direct feedback.
|
|
|
27
27
|
- [Memory File Format](#memory-file-format)
|
|
28
28
|
- [Retrieval and Injection](#retrieval-and-injection)
|
|
29
29
|
- [Write Safety](#write-safety)
|
|
30
|
+
- [Size Governance: What to Do When a Memory Grows Too Big](#size-governance-what-to-do-when-a-memory-grows-too-big)
|
|
30
31
|
- [Autodream](#autodream)
|
|
31
32
|
- [Migrating from Claude Code](#migrating-from-claude-code)
|
|
32
33
|
- [Configuration Reference](#configuration-reference)
|
|
@@ -71,10 +72,10 @@ Most memory schemes take the "SQLite + a long-running worker" route: once memori
|
|
|
71
72
|
|---|---|
|
|
72
73
|
| **File-based storage** | One `.md` per memory: frontmatter holds metadata, the body holds content. No database, no hidden format |
|
|
73
74
|
| **Automatic injection** | Every new question rescans the memory directory and re-picks the most relevant few for that question, injecting them into context before the model speaks — no file reading needed |
|
|
74
|
-
| **The model can look things up too** |
|
|
75
|
+
| **The model can look things up too** | Three tools are also given to the model (`search_memory` / `read_memory`, plus the disk-writing `trim_memory`), so it can go through memories on its own, read the original text by line, and cut a stale section out into the archive |
|
|
75
76
|
| **Writes are not overwritten** | While you are editing and the model is changing things at the same time, the later write does not silently clobber the earlier one; the conflict is left as a pending record for you to decide which side to keep |
|
|
76
77
|
| **Zero extra services** | No worker, no SQLite, no port, no long-running process, and no extra API key or cloud service (the only runtime dependency is the ordinary npm library `zod`) |
|
|
77
|
-
| **Anti-bloat** | Rules guide the model in judging "is this worth storing": nothing without substance is stored, nothing derivable by reading the code / git is stored |
|
|
78
|
+
| **Anti-bloat** | Rules guide the model in judging "is this worth storing": nothing without substance is stored, nothing derivable by reading the code / git is stored; the ones that did grow are flagged and dealt with along the 16 KB / 40 KB lines (see [size governance](#size-governance-what-to-do-when-a-memory-grows-too-big)) |
|
|
78
79
|
| **Tidyable** | The optional "autodream" reads your memories through once: merges duplicates, fixes the index and broken links, and creates a rollback point before changing anything |
|
|
79
80
|
| **Migration from Claude Code** | The persona (`CLAUDE.md` → `AGENTS.md`) is copied as-is; memories just need organizing into `.md` files under four types (see [the next section](#migrating-from-claude-code)) |
|
|
80
81
|
| **Ships its own usage guide** | The package carries a skill (`skills/sage-mem/`): what a memory looks like, the four types, what not to store, the frontmatter pitfalls, how retrieval actually works, how to audit and fix a broken index. Installing the plugin is enough — the agent gets the instructions, no manual setup |
|
|
@@ -191,7 +192,7 @@ Since 1.9.0 the memory-management surface follows the harness language (**Settin
|
|
|
191
192
|
|
|
192
193
|
|
|
193
194
|
|
|
194
|
-
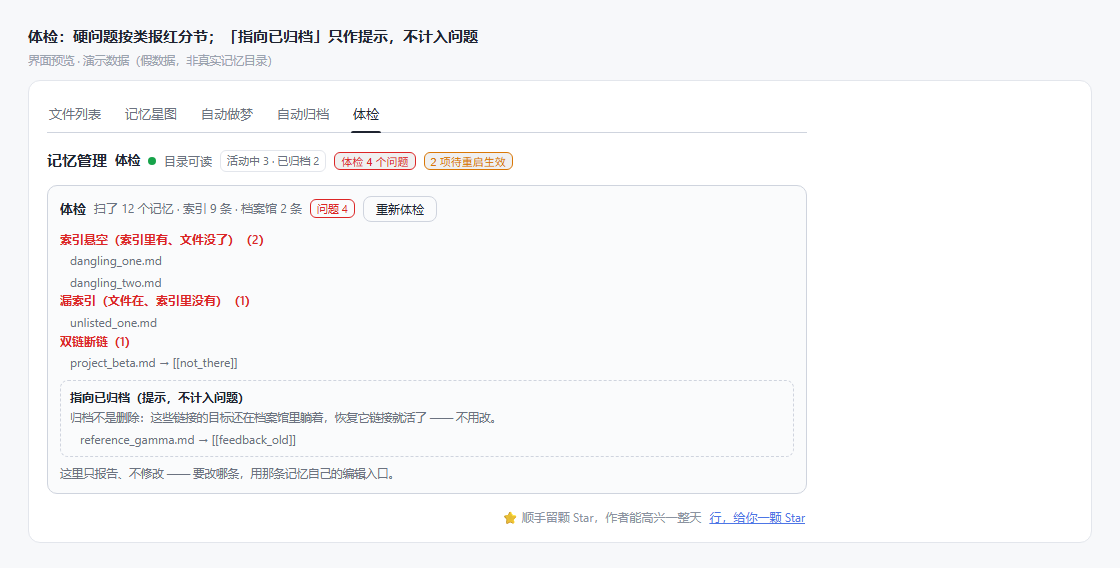
*Health — one screen answers "is anything wrong with this library": the **conflict queue on top** (a finite list that needs your decision: which of two contradictory statements is void) and the **audit below** (dangling index entries, missing index entries, broken links and the rest, reported in red by category). "Points to an archived memory" is only a hint — it does not count as a problem, and there is **no one-click fix**: which one to change is your call. The audit only reports and never modifies. When there is really something to deal with, the badge gets a **「复制修复提示词」(copy fix prompt)** button next to it (2.6.0): it turns what this screen needs into one prompt in your clipboard — **the audit problems and the pending conflicts are written as two separate sections** (fix these / only advise on those), so you can paste it to the agent and let it work. A receipt appears at the bottom afterwards — it closes itself in 10 seconds, closes as soon as you switch tabs, and you can dismiss it by hand.*
|
|
195
|
+
*Health — one screen answers "is anything wrong with this library": the **conflict queue on top** (a finite list that needs your decision: which of two contradictory statements is void) and the **audit below** (dangling index entries, missing index entries, broken links and the rest, reported in red by category). "Points to an archived memory" is only a hint — it does not count as a problem, and there is **no one-click fix**: which one to change is your call. The audit only reports and never modifies. Since 2.10.1 it has two size categories: **over-size memories** (40 KB or more counts as a problem; 16–40 KB is only a hint — 2.10.2 raised both lines from 8/16 KB) and an **over-long index** (report only, see [size governance](#size-governance-what-to-do-when-a-memory-grows-too-big)). When there is really something to deal with, the badge gets a **「复制修复提示词」(copy fix prompt)** button next to it (2.6.0): it turns what this screen needs into one prompt in your clipboard — **the audit problems and the pending conflicts are written as two separate sections** (fix these / only advise on those), so you can paste it to the agent and let it work. A receipt appears at the bottom afterwards — it closes itself in 10 seconds, closes as soon as you switch tabs, and you can dismiss it by hand.*
|
|
195
196
|
|
|
196
197
|
*Lab (2.9.0, sits after Health) — only switches that change **which memories are picked**, all off by default. Today it holds one: **MMR de-duplication**. When one topic takes every injection slot, it subtracts each candidate's similarity to what is already picked before choosing. It only changes **which items are picked** (never the score, never a file, never a pinned baseline memory) and returns candidates as-is when they fit the slots. Why it is off by default: in the offline comparison it never fired (the IDF gate already keeps candidates under 10), and in a stress run with the gate disabled duplication fell only 4.5% while wrong picks rose 24% — it knows "different", not "irrelevant". Read the three notes on that page before turning it on; **if memories seem to go missing, switch it off and restart**.
|
|
197
198
|
|
|
@@ -213,7 +214,7 @@ Since 1.9.0 the memory-management surface follows the harness language (**Settin
|
|
|
213
214
|
|
|
214
215
|
|
|
215
216
|
|
|
216
|
-
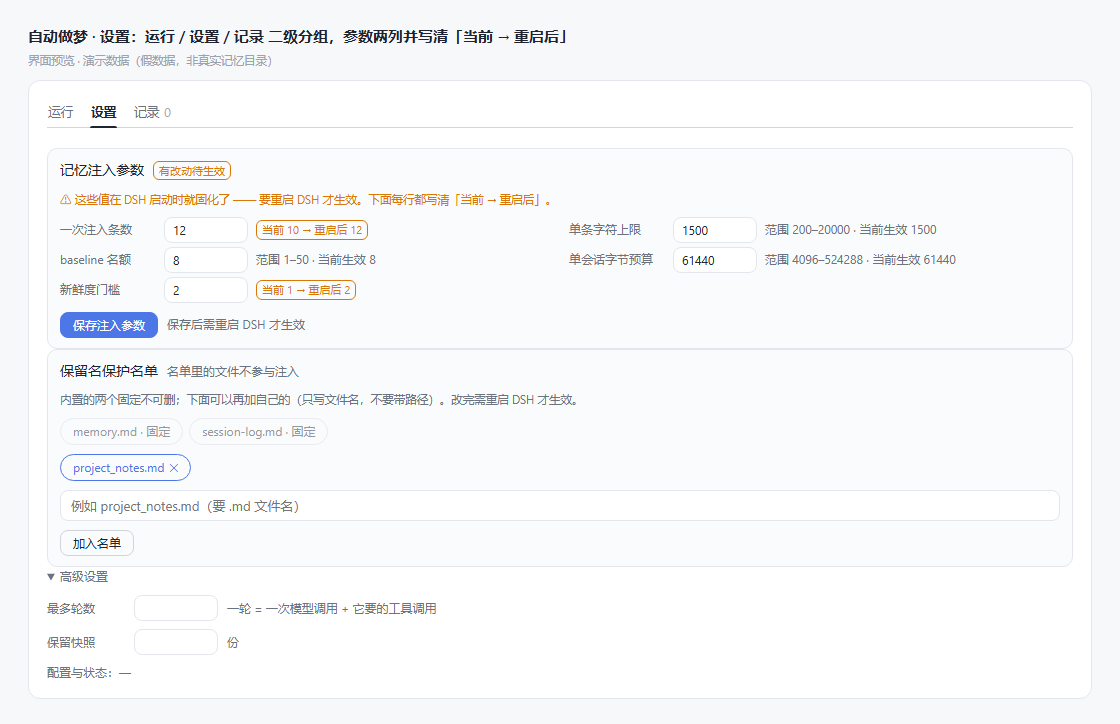
*Autodream · settings — run / settings / history as secondary groups; the five injection parameters laid out in two columns, with both 「当前生效」(currently in effect) and 「重启后」(after restart) written out
|
|
217
|
+
*Autodream · settings — run / settings / history as secondary groups; the five injection parameters laid out in two columns, with both 「当前生效」(currently in effect) and 「重启后」(after restart) written out. Since 2.10.1 this page ends with a **「不参与整理的文件」(files excluded from tidying)** block: you check names from the files that actually exist in the memory directory (no more typing them by hand), and a checked file is never trimmed or compressed by size governance — it is not counted as over the line either; the two built-in names (index / session log) cannot be unchecked, and **a save takes effect only after restarting DSH**.*
|
|
217
218
|
|
|
218
219
|
|
|
219
220
|
|
|
@@ -283,16 +284,17 @@ The comparison on the offline evaluation set (before and after the threshold): *
|
|
|
283
284
|
|
|
284
285
|
**Intent detection never suppresses repetition on three kinds of explicit request**: "we settled on A last time, right?" (verification), "we are not using A any more" (correction), "why did we not pick A before" (asking for the basis) must be given the original text; if it cannot be judged, it does not judge, and it does not guess.
|
|
285
286
|
|
|
286
|
-
### The Model Can Browse Memories Too:
|
|
287
|
+
### The Model Can Browse Memories Too: Three Tools
|
|
287
288
|
|
|
288
|
-
The trigger right for retrieval is split in two: half with the plugin (automatic injection — it guesses what you want to see), half with the model (the
|
|
289
|
+
The trigger right for retrieval is split in two: half with the plugin (automatic injection — it guesses what you want to see), half with the model (the three tools below — it looks things up on its own, and tidies them too).
|
|
289
290
|
|
|
290
291
|
| Tool | Purpose |
|
|
291
292
|
|---|---|
|
|
292
293
|
| `search_memory(query, scope?, limit?, cursor?)` | Compares summaries first, then searches bodies by paragraph; returns candidates, matching passages, line numbers, and **coverage information** (how many files were scanned, how many paragraphs were filtered out for insufficient relevance, whether there is a next page) |
|
|
293
294
|
| `read_memory(name, startLine?, startByte?, maxBytes?, revision?)` | Reads the body by line, paginated. Pass the `revision` you last read, and if the content has been changed by someone it returns `revision_changed`, **and does not return the content** — otherwise you would read the wrong thing with stale line numbers |
|
|
295
|
+
| `trim_memory(file, heading?, startLine?, endLine?, reason)` | Cuts one stale section out of a memory and archives it to `archive/`, leaving a single pointer line at the original spot. **It writes to disk**, it is **not safe to run concurrently** (two cuts at once would step on each other's revision, so the host queues them), and it **only cuts, never deletes**; `MEMORY.md` / `session-log.md` / protected names are refused, and both the cut segment and the remaining body need ≥ 1 KB |
|
|
294
296
|
|
|
295
|
-
|
|
297
|
+
The first two tools go through **the same** safe read path (file name checks → symlink and reserved-name identity checks → size gate); no separate entrance that bypasses the gate was opened for the tools. `trim_memory` goes through the **single** cut-and-archive write order (lock table → name gate → snapshot → recompute → write the archived file first → revision-guarded write of the main file, see [size governance](#size-governance-what-to-do-when-a-memory-grows-too-big)) — there is no second implementation of it either. They register through the tool service the host provides — that is **not a hard dependency**: when the host does not provide that service, the plugin works as normal, only the status card switches to a "read the memory directory directly" wording.
|
|
296
298
|
|
|
297
299
|
### Relaying the Baton on Long Tasks: Task Checkpoints
|
|
298
300
|
|
|
@@ -346,6 +348,47 @@ The reason is: when a stale memory is cited as fact, the act of "citing" itself
|
|
|
346
348
|
|
|
347
349
|
If the memory directory cannot be read, or permissions are wrong → **it degrades to no injection and writes a log**; it does not fail silently. Broken frontmatter is **handled leniently**: fields that cannot be parsed fall back to defaults (`type` missing is recorded as `reference`), and the file itself is still readable — one wrong line does not make a whole memory disappear.
|
|
348
350
|
|
|
351
|
+
## Size Governance: What to Do When a Memory Grows Too Big
|
|
352
|
+
|
|
353
|
+
Memories are files, and files only ever grow — so "too big" needs a way out, and it cannot rely on anyone remembering to take it.
|
|
354
|
+
|
|
355
|
+
**First, a correction to something the previous version got wrong.** The 2.10.1 notes said injection only reads the first 1500 characters, so whatever is written past that cap is, for your future self, as good as absent. That holds in exactly two cases: `baseline` memories (they never go through paragraph replacement, so they are still read from the start and still cut off at the single-item character limit), and an injection that only hits the summary and never the body. Otherwise the body is injected **in 600-character blocks**, selected by relevance — the relevant passage of a large file is still picked, so **size does not affect what gets matched** (the mechanism is in [Retrieval and Injection](#retrieval-and-injection)).
|
|
356
|
+
|
|
357
|
+
What size does affect is three other things:
|
|
358
|
+
|
|
359
|
+
- **Reading the full text means putting all of it into the context.** `read_memory` has no paging, so a large file arrives in one piece.
|
|
360
|
+
- **Autodream costs more.** The more over-line entries a run has to read through, the more time and tokens that run spends.
|
|
361
|
+
- **Editing gets riskier.** The longer the file, the greater the chance a trim or a compression changes the wrong place or drops a fact that is still in force.
|
|
362
|
+
|
|
363
|
+
And one more thing that is not a cost but is in itself a signal: **the longer a memory is, the more likely it is an un-tidied pile.**
|
|
364
|
+
|
|
365
|
+
So the point of the lines is not "letting the tail into the context" — the relevant part of the tail gets in anyway. The point is those three costs, and that signal. 2.10.2 raising them to 16 KB / 40 KB uses the same reasoning: at 8 KB, an ordinary long memory trips the warning on nearly every write, and that is not a hint, it is noise.
|
|
366
|
+
|
|
367
|
+
**Three lines** (defined in exactly one place, `lib/shared/limits.js`; the UI, the audit and the tools all read that one copy):
|
|
368
|
+
|
|
369
|
+
| Quantity | Value | Who acts on it |
|
|
370
|
+
|---|---|---|
|
|
371
|
+
| Warning line | **16 KB** per memory | one line in the write log, one `ℹ` line in the `read_memory` receipt, listed as a hint by the audit |
|
|
372
|
+
| Force line | **40 KB** per memory | counts as an audit problem; autodream has to deal with it in that run |
|
|
373
|
+
| Index line | `MEMORY.md` **240 characters** per line / **24 KB** whole file | **report only**: the index should be slimmed, but which entry to drop is your decision |
|
|
374
|
+
|
|
375
|
+
**Two remedies, both leaving a trail**:
|
|
376
|
+
|
|
377
|
+
- **Segment archiving** (split when it splits) — move one stale section into `archive/<original>-<slice>-<date>.md` and leave **one pointer line with keywords at the original spot** in the main file ("this old content was archived to archive/…"). The archive is not part of retrieval, so those keywords are the only lead back to the details — write them so they can be searched for. The archived file's frontmatter carries `archived_at` / `archived_reason` / `archived_from` / `archived_slice`, so half a year later it still tells you why it was cut and from where. The cut segment and the remaining body each need ≥ 1 KB.
|
|
378
|
+
- **Compression** (compress when it does not split) — shorten in place: conclusion first, de-duplicate, drop what has been overturned. The frontmatter gains `compressed_at` / `compressed_reason` / `compressed_from_bytes` automatically (the autodream path has the host add them; when you compress through the file tools yourself there is no interception point, so write that line by hand).
|
|
379
|
+
|
|
380
|
+
**Three hard rules**:
|
|
381
|
+
|
|
382
|
+
1. **The index and the session log are out of scope.** `MEMORY.md` is report-only; `session-log.md` is a reserved name served by the "raw read/write" path (4 MB cap), and no size rule nags an append-only log.
|
|
383
|
+
2. **The protection list is not touched.** Files checked under 「自动整理 → 设置 → 不参与整理的文件」(Automation → Settings → files excluded from tidying) are skipped by both autodream and `trim_memory`, and **are not counted as over the line either**. The list reuses the existing `reserved` names: once a file is on it, the memory tools refuse to write it (that is what "protected" has always meant), so edit it with the file tools.
|
|
384
|
+
3. **Nothing is ever deleted.** Archiving is the strongest thing this feature can do: a cut only moves, and when writing the main file fails the archived copy is renamed for safekeeping (`archive/.retired-*`) — still not deleted.
|
|
385
|
+
|
|
386
|
+
**Three entry points, one set of rules**: the main agent's `trim_memory` (writes to disk, not concurrency-safe, cut-only-never-delete); autodream's "stage 3.5 — size governance" plus `archive_segment` (unattended; it checks afterwards whether the number of force-line entries actually went down and says so if it did not); and on the human side, the two new audit categories under Health plus the protection block above.
|
|
387
|
+
|
|
388
|
+
**Explicitly not done**: physical compression (gz/zip — archived files stay `.md`, readable and recoverable), automatic deletion, trimming `session-log.md`, a switchable "not searchable", and making these thresholds a setting.
|
|
389
|
+
|
|
390
|
+
⚠️ **Two known boundaries**: ① when the main agent compresses with the file tools, the plugin has **no interception point** — compression trails are added automatically only on the autodream path, and the audit cannot verify a hand-written one; ② **cutting the same section twice on the same day reports a name clash (`exists`)** — archive names carry the date, so pick another heading or use compression instead.
|
|
391
|
+
|
|
349
392
|
## Autodream
|
|
350
393
|
|
|
351
394
|
The optional memory-consolidation feature (identifier `autodream`): it reads through the memory directory once — merging duplicates, deleting the overturned, fixing the index and broken links, converting relative dates into absolute dates — so that the next session can find its bearings quickly.
|
|
@@ -445,6 +488,8 @@ Value semantics: **out-of-range values are clamped to the boundary, illegal valu
|
|
|
445
488
|
|
|
446
489
|
The panel can change the five caps above (written to `<state directory>/settings.json`, precedence **settings page > environment variable > built-in default**), as well as reserved names (file names that are protected and that the settings page may not write or delete, written to `<state directory>/reserved.json`). **Some items take effect only after restarting DSH**, and the panel writes out both the value in effect now and the value after restart.
|
|
447
490
|
|
|
491
|
+
Since 2.10.1 the reserved names have a second role — **files excluded from tidying** (Automation → Settings): you check names from the files that actually exist in the memory directory, and a checked file is never trimmed or compressed by size governance and **is not counted as over the line either**. The two built-in names (index / session log) cannot be unchecked; **a save takes effect only after restarting DSH** (the list is read into memory when DSH starts).
|
|
492
|
+
|
|
448
493
|
### Files in the State Directory
|
|
449
494
|
|
|
450
495
|
| File | Purpose |
|
|
@@ -492,7 +537,7 @@ sage-mem does three things only, all of them on your own machine:
|
|
|
492
537
|
| What it does | Concrete scope |
|
|
493
538
|
|---|---|
|
|
494
539
|
| **Reading memories** | reads only the top-level `*.md` under `SAGE_MEM_DIR` (default `~/.sage-mem/memory`), 512 KB per file |
|
|
495
|
-
| **Writing memories** | writes to the same directory through the model's file tools or the settings page; reserved names such as `MEMORY.md` and `session-log.md` are protected and the settings page cannot touch them |
|
|
540
|
+
| **Writing memories** | writes to the same directory through the model's file tools or the settings page; reserved names such as `MEMORY.md` and `session-log.md` are protected and the settings page cannot touch them. Since 2.10.1 there is one more kind of write: segment archiving moves a stale section into `archive/` and leaves a single pointer line in the main file (**move only, never delete**) |
|
|
496
541
|
| **Injection** | hands the selected memories to the model as context (at most 10 relevant + 8 `baseline`, 60 KB cumulative per session — ⚠️ this cap is **soft**, see [Retrieval and Injection](#retrieval-and-injection)) |
|
|
497
542
|
|
|
498
543
|
**What it does not do**: it opens no port, starts no long-running process, and needs no API key; it **does not capture every event** (whether to store is judged by the model according to rules; it is not "everything you say gets recorded").
|
|
@@ -564,8 +609,8 @@ Module boundaries (since 1.2.0):
|
|
|
564
609
|
- `lib/index.js` — the **composition root** plus the three gateways. The typert manifest pins `sourceLocation` to this file, so the gateway classes stay here (moving them would be a contract drift)
|
|
565
610
|
- `lib/recall/` — the injection chain: selection (`select`) / rendering and budget (`compose`) / text (`text`) / session state (`state`)
|
|
566
611
|
- `lib/assembly/` — the four mounts: autodream / retrieval tools / observation / write gate
|
|
567
|
-
- `lib/memory/` — pure memory-layer functions and file operations; `lib/autodream/` — the autodream engine
|
|
568
|
-
- `lib/shared/` — zero-dependency cross-layer rules: file-name rule / local timestamps / the
|
|
612
|
+
- `lib/memory/` — pure memory-layer functions and file operations. Size governance is three separate things inside it: `memory/size-policy` (the **pure verdict**: three tiers + advice + that one sentence of plain language), `memory/trim-plan` (the **pure split**: turning a selection into "archived file + remaining body + pointer", with six invariants), and `memory/trim-archive` (the **single** place that writes a cut: exclusive write of the archived file first, then a revision-guarded write of the main file, and if that fails the archived copy is retired to `.retired-*` rather than deleted); `lib/autodream/` — the autodream engine, where `autodream/size-tools` is the thin model-facing adapter (it only forwards `archive_segment` to `trim-archive` and never re-implements the disk order)
|
|
613
|
+
- `lib/shared/` — zero-dependency cross-layer rules: file-name rule / local timestamps / the size lines (the 512 KB hard ceiling plus the three governance lines: 16 KB, 40 KB, and the index's 240 characters / 24 KB. **Exactly one copy each**; `test/duplication-test.mjs` turns red otherwise)
|
|
569
614
|
- UI side: `client/*.js` is split per screen (`05-shared.js` holds the cross-screen primitives and type tables); `npm run build:client` concatenates them into `lib/client.js`
|
|
570
615
|
- Dependency direction: `memory` never imports `autodream`, `recall` depends only on `memory`, `assembly` never imports the composition root (`test/structure-test.mjs` turns red if that changes)
|
|
571
616
|
|
|
@@ -609,6 +654,9 @@ No. Serialized writes guarantee only **in-process** ordering; there is no file l
|
|
|
609
654
|
**Can I do without autodream?**
|
|
610
655
|
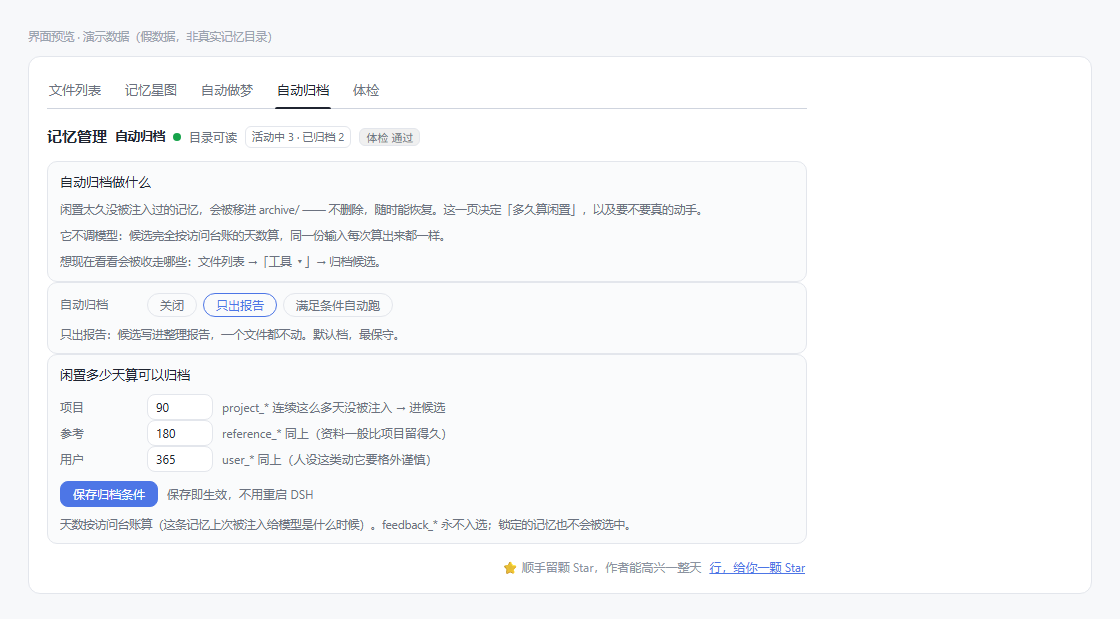
Yes, it is off by default. It and archiving are two different things: archiving is a deterministic rule (by idle days), calls no model and costs nothing.
|
|
611
656
|
|
|
657
|
+
**What do I do when a memory file keeps growing?**
|
|
658
|
+
Start with the **over-size memories** section under Health: 40 KB or more must be dealt with, 16–40 KB is only a hint. There are exactly two remedies — if it splits, **archive a segment** (the stale section moves into `archive/` and the main file keeps one pointer line with the reason at the original spot, recoverable at any time); if it does not split, **compress** it (conclusion first, de-duplicate, drop what has been overturned). The model has `trim_memory` to cut directly, and autodream handles anything over 40 KB on every run. If you do not want certain files touched, check them under 「自动整理 → 设置 → 不参与整理的文件」(Automation → Settings → files excluded from tidying). The index `MEMORY.md` is report-only and never rewritten automatically; `session-log.md` is out of scope. Details in [size governance](#size-governance-what-to-do-when-a-memory-grows-too-big).
|
|
659
|
+
|
|
612
660
|
**The plugin market says "the registry's latest is older than the installed version, updating would downgrade"?**
|
|
613
661
|
That is a **stale `/latest` cache on the download-region mirror**, not a mis-published package: the mirror's full metadata (the document pnpm reads) already has the new version, while the `/<pkg>/latest` shortcut still serves an old one. Retry after a minute or two; if it persists, temporarily switch the market's download region to "Global" (the origin registry, registry.npmjs.org), update, then switch back. To check what is actually published: `npm view sage-mem dist-tags`.
|
|
614
662
|
|
package/README.md
CHANGED
|
@@ -14,7 +14,7 @@
|
|
|
14
14
|
|
|
15
15
|
> File-based cross-session memory for DeepSeek Harness — every memory is a plain markdown file you can open, edit and delete. No database, no worker, no port.
|
|
16
16
|
|
|
17
|
-
**当前发布版本:`2.
|
|
17
|
+
**当前发布版本:`2.10.2`** —— 顶部 npm 徽章是动态权威。**契约基线:`1.0.0`** —— 第一个稳定版,公开承诺、能力边界与「明确做不到」的清单冻结在
|
|
18
18
|
[契约冻结](https://github.com/gezi-wen/sage-mem/blob/main/docs/1.0.0-contract.md)。
|
|
19
19
|
|
|
20
20
|
如果它对你有用,给个 Star 是最直接的反馈。
|
|
@@ -29,6 +29,7 @@
|
|
|
29
29
|
- [记忆文件格式](#记忆文件格式)
|
|
30
30
|
- [检索与注入](#检索与注入)
|
|
31
31
|
- [写入安全](#写入安全)
|
|
32
|
+
- [体积治理:超线了怎么办](#体积治理超线了怎么办)
|
|
32
33
|
- [自动做梦](#自动做梦)
|
|
33
34
|
- [从 Claude Code 迁移](#从-claude-code-迁移)
|
|
34
35
|
- [配置参考](#配置参考)
|
|
@@ -73,10 +74,10 @@ sage-mem 补上这一层,做法是:**把该记住的事写成一张张卡片
|
|
|
73
74
|
|---|---|
|
|
74
75
|
| **文件式存储** | 每条记忆一个 `.md`:frontmatter 存元数据,正文存内容。无数据库、无隐藏格式 |
|
|
75
76
|
| **自动注入** | 每条新问题都会重新扫一遍记忆目录,按这条问题挑出最相关的几条,在模型开口之前拼进上下文 —— 不用模型自己去翻文件 |
|
|
76
|
-
| **模型也能自己查** |
|
|
77
|
+
| **模型也能自己查** | 另给模型三个工具(`search_memory` / `read_memory`,以及会写盘的 `trim_memory`),它可以主动翻记忆、按行读原文、把已经过时的一节裁去归档 |
|
|
77
78
|
| **写入不被覆盖** | 你正在编辑、模型同时在改的时候,后写的不会静默盖掉先写的;冲突留成待处理记录,由你决定保留哪边 |
|
|
78
79
|
| **零额外服务** | 无 worker、无 SQLite、无端口、无常驻进程,不需要额外的 API key 或云服务(运行时唯一的依赖是普通 npm 库 `zod`) |
|
|
79
|
-
| **防膨胀** | 靠规则引导模型判断「值不值得存」:无实质内容的不存,靠读代码 / git
|
|
80
|
+
| **防膨胀** | 靠规则引导模型判断「值不值得存」:无实质内容的不存,靠读代码 / git 能推出来的不存;已经长大的那几条按 16 KB / 40 KB 两条线提醒与处置(见[体积治理](#体积治理超线了怎么办)) |
|
|
80
81
|
| **可整理** | 可选的「自动做梦」把记忆通读一遍:合并重复、修索引与断链,改动前先建回滚点 |
|
|
81
82
|
| **从 Claude Code 迁移** | 人格(`CLAUDE.md` → `AGENTS.md`)照搬;记忆按四类整理成 `.md` 即可(见[下一节](#从-claude-code-迁移)) |
|
|
82
83
|
| **自带使用指南** | 包内携带一份技能(`skills/sage-mem/`):记忆长什么样、四类怎么分、什么不该存、frontmatter 的坑、检索怎么工作、索引坏了怎么修。装上插件就够了 —— Agent 拿到说明书,不需要手工配置 |
|
|
@@ -191,7 +192,7 @@ SAGE_MEM_DIR=/path/to/your/memory
|
|
|
191
192
|
|
|
192
193
|

|
|
193
194
|
|
|
194
|
-
*库健康 —— 一屏回答「这个库有没有事」:**冲突队列在上**(要你裁决的有限队列:两条说法互斥,选哪一方作废),**体检在下**(索引悬空、漏索引、双链断链等结构问题按类报红)。「指向已归档」只作提示、不计入问题;也**不提供一键修补** ——
|
|
195
|
+
*库健康 —— 一屏回答「这个库有没有事」:**冲突队列在上**(要你裁决的有限队列:两条说法互斥,选哪一方作废),**体检在下**(索引悬空、漏索引、双链断链等结构问题按类报红)。「指向已归档」只作提示、不计入问题;也**不提供一键修补** —— 改哪条由你决定。体检只报告、不修改。2.10.1 起体检多两类体积审计:**超线体积**(单条 ≥ 40 KB 计入问题、16–40 KB 只列提示;这两条线 2.10.2 从 8/16 KB 抬上来)与**索引过长**(只报不改,见[体积治理](#体积治理超线了怎么办))。真有事要处理时,徽标后面会多一颗**「复制修复提示词」**(2.6.0):把这一屏要处理的事整理成一段提示词放进剪贴板 —— **体检问题与待裁决冲突分两段写**(前者照清单修、后者只给建议),粘给智能体就能照着办;复制成功后下方弹一条提示,10 秒自收、换页签即收、也能自己关掉。*
|
|
195
196
|
|
|
196
197
|
*实验性(2.9.0,排在库健康之后)—— 只给「会改变选出哪些记忆」的开关,默认全关。当前只有一项 **MMR 去重**:注入名额被同一件事的多份记忆占满时,先扣掉候选与已选中那些的相似度再挑。它**只改挑哪几条**(不改打分、不改文件、不碰锁定的 baseline 记忆),候选不够名额时原样返回。为什么默认关:离线对照里它一次都没触发(证据门已把候选压到 10 条以内),而关掉证据门的压力测试中重复度只降 4.5%、误注入却涨了 24% —— 它只知道「不像」,不知道「不相关」。打开前请读那一页的三条声明;**若觉得记忆变少了,关掉它、重启即可恢复**。*
|
|
197
198
|
|
|
@@ -213,7 +214,7 @@ SAGE_MEM_DIR=/path/to/your/memory
|
|
|
213
214
|
|
|
214
215
|

|
|
215
216
|
|
|
216
|
-
*自动做梦 · 设置 —— 运行 / 设置 / 记录
|
|
217
|
+
*自动做梦 · 设置 —— 运行 / 设置 / 记录 二级分组;五个注入参数两列排开,并写清「当前生效」与「重启后」。2.10.1 起这一页下方多一块**「不参与整理的文件」**:从记忆目录里现成的文件名里勾(不再手打),勾上的文件在体积治理时既不裁剪也不压缩、也不计入超线;索引与流水两个内置名不可取消,**保存后需重启 DSH 才生效**。*
|
|
217
218
|
|
|
218
219
|

|
|
219
220
|
|
|
@@ -283,16 +284,17 @@ baselinePriority: 10 # 可选:多条 baseline 之间谁先注入(越大越
|
|
|
283
284
|
|
|
284
285
|
**意图识别绝不在三类显式请求上抑制重复**:「上次决定用 A 对吧」(核实)、「不用 A 了」(更正)、「之前为什么没选 A」(问依据)必须给原文;判不出来就不判,不猜。
|
|
285
286
|
|
|
286
|
-
###
|
|
287
|
+
### 模型也能自己翻:三个工具
|
|
287
288
|
|
|
288
|
-
|
|
289
|
+
检索的触发权分两半:一半在插件(自动注入,它猜你想看什么),一半在模型(下面这三个工具,它主动查、也主动整理)。
|
|
289
290
|
|
|
290
291
|
| 工具 | 用途 |
|
|
291
292
|
|---|---|
|
|
292
293
|
| `search_memory(query, scope?, limit?, cursor?)` | 先比摘要、再按段落查正文;返回候选、命中片段、行号,以及**覆盖情况**(扫了几份、几段因相关性不够被滤掉、有没有下一页) |
|
|
293
294
|
| `read_memory(name, startLine?, startByte?, maxBytes?, revision?)` | 按行分页读正文。带上你上次读到的 `revision`,内容被人改过时会回 `revision_changed`,**并且不返回内容** —— 否则你会拿着过期行号读错东西 |
|
|
295
|
+
| `trim_memory(file, heading?, startLine?, endLine?, reason)` | 把一段旧内容裁下来归档到 `archive/`,主文件原位置只留一行指针。**会写盘**、**不可并发**(两个裁段并行会互相踩 revision,宿主据此排队)、**只裁不删**;`MEMORY.md` / `session-log.md` / 保护名单一律拒绝,被裁段与剩余正文各需 ≥ 1 KB |
|
|
294
296
|
|
|
295
|
-
|
|
297
|
+
前两个工具走的是**同一条**安全读路径(文件名检查 → 符号链接与保留名身份检查 → 体积闸门),没有为工具另开一条绕过闸门的入口;`trim_memory` 走的是**唯一**的裁段写序(锁表 → 名字闸 → 快照 → 重算 → 先写归档件 → revision 守卫改主文件,见[体积治理](#体积治理超线了怎么办)),同样没有第二份实现。它们通过宿主提供的工具服务注册 —— **不是硬依赖**:宿主不提供这个服务时,插件照常工作,只是状态卡换一套「直接读记忆目录」的说法。
|
|
296
298
|
|
|
297
299
|
### 长任务的接力棒:任务检查点
|
|
298
300
|
|
|
@@ -346,6 +348,47 @@ sage-mem 给记忆目录的写入加了**版本守卫**:写入前记下当前
|
|
|
346
348
|
|
|
347
349
|
记忆目录读不到、权限错 → **降级为不注入并写日志**,不会静默失效。frontmatter 坏掉则**宽容处理**:解析不出来的字段回落默认(`type` 缺失按 `reference` 记),文件本身照样能被读到 —— 不会因为一行写错就让整条记忆消失。
|
|
348
350
|
|
|
351
|
+
## 体积治理:超线了怎么办
|
|
352
|
+
|
|
353
|
+
记忆是文件,而文件只会越写越长 —— 「太大了」因此必须有出口,而且不能指望谁记得住。
|
|
354
|
+
|
|
355
|
+
**先把上一版写错的一句话改对。** 2.10.1 的说明里写着「注入只读前 1500 字,所以超过上限之后写进去的内容,对未来的你等于不存在」。这句话只在两种情况下成立:`baseline` 记忆(它不吃段落替换,仍从开头读、受单条字数上限截断),以及某次注入只命中摘要、没命中正文的时候。其余情况下正文是**按 600 字一块选段**注入的 —— 一条大文件里相关的那段照样会被选中,**体积不影响命中**(机制见[检索与注入](#检索与注入))。
|
|
356
|
+
|
|
357
|
+
体积真正影响的是另外三笔:
|
|
358
|
+
|
|
359
|
+
- **读全文就是整份进上下文。** `read_memory` 没有分页,一条大文件读一次就是整份。
|
|
360
|
+
- **自动做梦更贵。** 一趟要通读的超线条目越多,那趟花的时间与 token 越多。
|
|
361
|
+
- **编辑更容易出错。** 越长的文件,裁段与压缩时改错地方、碰掉还在生效的事实的风险越大。
|
|
362
|
+
|
|
363
|
+
还有一条不算成本,但它本身就是信号:**越长,越可能是没整理过的堆积。**
|
|
364
|
+
|
|
365
|
+
所以线的意义不是「让尾部能进上下文」—— 尾部的相关内容本来就能进。线的意义是上面这三笔成本,和这个信号。2.10.2 把线抬到 16 KB / 40 KB 也是同一个理由:8 KB 时一条正常的长条目几乎每次写入都在提醒,那种提醒不叫提示,叫噪音。
|
|
366
|
+
|
|
367
|
+
**三条线**(唯一定义处 `lib/shared/limits.js`,界面、审计、工具读的是同一份):
|
|
368
|
+
|
|
369
|
+
| 量 | 值 | 谁在管 |
|
|
370
|
+
|---|---|---|
|
|
371
|
+
| 提醒线 | 单条 **16 KB** | 写入日志里一行提醒、`read_memory` 回执里一行 `ℹ`、体检里列为提示 |
|
|
372
|
+
| 强制线 | 单条 **40 KB** | 计入体检问题;自动做梦这一趟必须处置 |
|
|
373
|
+
| 索引线 | `MEMORY.md` 单行 **240 字符** / 整份 **24 KB** | **只报不改**:它该瘦身,但删哪个条目由你决定 |
|
|
374
|
+
|
|
375
|
+
**两条处置,都必须留痕**:
|
|
376
|
+
|
|
377
|
+
- **裁段归档**(能拆就拆)—— 把一节旧内容搬进 `archive/<原名>-<片段>-<日期>.md`,**主文件在原位置留一行带关键词的指针**(「这段旧内容已归档到 archive/…」)。归档区不在检索面里,这行关键词是你以后找回细节的唯一线索,所以要写得出搜得到的话。归档件的 frontmatter 带 `archived_at` / `archived_reason` / `archived_from` / `archived_slice`,半年后仍看得出「为什么裁、从哪裁的」。被裁段与剩余正文各需 ≥ 1 KB。
|
|
378
|
+
- **压缩**(拆不开就压)—— 就地改短:结论前置、去重、删掉被推翻的。frontmatter 自动补 `compressed_at` / `compressed_reason` / `compressed_from_bytes`(自动做梦那条路由宿主补;你用文件工具自己压时没有拦截点,得手写一笔)。
|
|
379
|
+
|
|
380
|
+
**三条铁律**:
|
|
381
|
+
|
|
382
|
+
1. **索引与流水不在范围。** `MEMORY.md` 只报不改;`session-log.md` 是保留名,走「原样读写」那条路(上限 4 MB),体积规则不催一条追加型流水。
|
|
383
|
+
2. **保护名单不动。** 「自动整理 → 设置 → 不参与整理的文件」里勾上的文件,自动做梦与 `trim_memory` 都跳过,**也不计入超线**。名单复用的就是既有的 `reserved`:勾进去之后 memory 工具会拒写它(「受保护」一直就是这个意思),要改请用文件工具。
|
|
384
|
+
3. **永不删除。** 归档是这里能造成的最强后果:裁段只移不删,改主文件失败时归档件会被改名保命(`archive/.retired-*`),照样不删。
|
|
385
|
+
|
|
386
|
+
**三个入口,口径同一份**:主智能体的 `trim_memory`(会写盘、不可并发、只裁不删);自动做梦的「阶段 3.5 体积治理」+ `archive_segment`(无人值守,跑完核对强制线条数有没有下降,没降就写明「这趟没做完」);人这边是「库健康」的两类审计,加上上面那块保护名单勾选。
|
|
387
|
+
|
|
388
|
+
**明确不做**:物理压缩(gz/zip,归档件保持 `.md` 可读可捞回)、自动删除、给 `session-log.md` 裁剪、可开关的「不进检索」、把阈值做成设置项。
|
|
389
|
+
|
|
390
|
+
⚠️ **两条已知边界**:① 主智能体用文件工具压缩时插件**没有拦截点**,压缩留痕只有自动做梦那条路是自动补的,审计验不了手写那条;② **同一段在同一天裁第二次会报重名(`exists`)** —— 归档名带日期,换个标题再裁,或者干脆改用压缩。
|
|
391
|
+
|
|
349
392
|
## 自动做梦
|
|
350
393
|
|
|
351
394
|
可选的记忆整理功能(标识 `autodream`):把记忆目录通读一遍 —— 合并重复的、删掉被推翻的、修索引与断链、把相对日期换成绝对日期,让下一次会话能快速对上位置。
|
|
@@ -445,6 +488,8 @@ sage-mem 给记忆目录的写入加了**版本守卫**:写入前记下当前
|
|
|
445
488
|
|
|
446
489
|
面板可改上面五个上限(写入 `<状态目录>/settings.json`,优先级 **设置页 > 环境变量 > 内置默认**),以及保留名(受保护、设置页不许写删的文件名,写入 `<状态目录>/reserved.json`)。**部分项要重启 DSH 才生效**,面板上会写清「当前生效 / 重启后」。
|
|
447
490
|
|
|
491
|
+
2.10.1 起,保留名有了第二个身份 ——「**不参与整理的文件**」(自动整理 → 设置):从记忆目录里现成的文件名里勾选,勾上的文件在体积治理时既不裁剪、也不压缩、**也不计入超线**。索引与流水两个内置名不可取消;**保存后需重启 DSH 才生效**(名单在 DSH 启动时读进内存)。
|
|
492
|
+
|
|
448
493
|
### 状态目录里的文件
|
|
449
494
|
|
|
450
495
|
| 文件 | 用途 |
|
|
@@ -492,7 +537,7 @@ sage-mem 只做三件事,全都在你本机:
|
|
|
492
537
|
| 它做什么 | 具体范围 |
|
|
493
538
|
|---|---|
|
|
494
539
|
| **读记忆** | 只读 `SAGE_MEM_DIR`(默认 `~/.sage-mem/memory`)下的顶层 `*.md`,单文件上限 512 KB |
|
|
495
|
-
| **写记忆** | 经模型的文件工具或设置页写同一个目录;`MEMORY.md`、`session-log.md`
|
|
540
|
+
| **写记忆** | 经模型的文件工具或设置页写同一个目录;`MEMORY.md`、`session-log.md` 等保留名受保护,设置页碰不到。2.10.1 起多一种写:裁段归档把一段旧内容移进 `archive/`,主文件只留一行指针(**只移不删**) |
|
|
496
541
|
| **注入** | 把选中的记忆作为上下文交给模型(最多 10 条相关 + 8 条 `baseline`,单场会话累计 60 KB —— ⚠️ 这个上限是**软的**,见[检索与注入](#检索与注入)) |
|
|
497
542
|
|
|
498
543
|
**它不做什么**:不开端口、不起常驻进程、不需要任何 API key;**不做事件全捕获**(存不存由模型按规则判断,不是「你说了什么都记」)。
|
|
@@ -566,8 +611,8 @@ memory/ 目录(markdown 文件,4 类)
|
|
|
566
611
|
- `lib/index.js` —— **组合根** + 三个 Gateway。typert manifest 的 `sourceLocation` 钉在这个文件上,所以 Gateway 类不搬走(搬 = 契约漂移)
|
|
567
612
|
- `lib/recall/` —— 注入链:选材(`select`)/ 渲染与预算(`compose`)/ 文本(`text`)/ 会话状态(`state`)
|
|
568
613
|
- `lib/assembly/` —— 四块挂载:autodream / 检索工具 / 观测 / 写入门
|
|
569
|
-
- `lib/memory/` ——
|
|
570
|
-
- `lib/shared/` —— 跨层零依赖的小判据:文件名规则 / 本地时间戳 /
|
|
614
|
+
- `lib/memory/` —— 记忆层的纯函数与文件操作。体积治理在其中是三件分开的东西:`memory/size-policy`(**纯判据**:三档 + 建议 + 那一句人话)、`memory/trim-plan`(**纯切分**:选段翻译成「归档件 + 剩余正文 + 指针」,六条不变量)、`memory/trim-archive`(**唯一**的裁段写盘处:先排他写归档件、再 revision 守卫改主文件、失败把归档件退役成 `.retired-*` 而不删);`lib/autodream/` —— 自动做梦引擎,其中 `autodream/size-tools` 是模型面的薄适配(只把 `archive_segment` 转调 `trim-archive`,自己不拼写盘逻辑)
|
|
615
|
+
- `lib/shared/` —— 跨层零依赖的小判据:文件名规则 / 本地时间戳 / 体积线(512 KB 硬顶,加上体积治理的三条线:16 KB、40 KB、索引 240 字符与 24 KB。**只许一份**,`test/duplication-test.mjs` 会红)
|
|
571
616
|
- 界面侧:`client/*.js` 按屏分片(`05-shared.js` 放跨屏小基元与类型词表),`npm run build:client` 拼成 `lib/client.js`
|
|
572
617
|
- 依赖方向:`memory` 不认识 `autodream`,`recall` 只依赖 `memory`,`assembly` 不反向依赖组合根(`test/structure-test.mjs` 会红)
|
|
573
618
|
|
|
@@ -612,6 +657,9 @@ npm test # 全部断言(含三条守卫)
|
|
|
612
657
|
**能不用自动做梦吗?**
|
|
613
658
|
能,它默认就是关闭的。它和归档是两件事:归档是确定性规则(按闲置天数),不调模型、不花钱。
|
|
614
659
|
|
|
660
|
+
**记忆文件越写越大怎么办?**
|
|
661
|
+
先看「库健康」里的**超线体积**一节:单条 ≥ 40 KB 必须处置,16–40 KB 只提示。处置只有两条路 —— 拆得开就**裁段归档**(旧的一节搬进 `archive/`,主文件原位置留一行带缘由的指针,随时捞得回),拆不开就**压缩**(结论前置、去重、删掉被推翻的)。模型手上有 `trim_memory` 可以直接裁,自动做梦每趟也会自己处理超过 40 KB 的条目。不想让某几个文件被碰,就在「自动整理 → 设置 → 不参与整理的文件」里勾上。索引 `MEMORY.md` 只报告、不自动改;`session-log.md` 不参与。详见[体积治理](#体积治理超线了怎么办)。
|
|
662
|
+
|
|
615
663
|
**插件市场报「registry 上的最新版比已装还旧,更新会降级」?**
|
|
616
664
|
那是**下载地区镜像的 `/latest` 缓存滞后**,不是包发错了:镜像的全量元数据(pnpm 读的那份)已经是新版,但 `/<包>/latest` 这个快捷入口还缓存着旧值。先等一两分钟重试;仍然不行就把插件市场的「下载地区」临时切到「全球」(直连 registry.npmjs.org)更新,完成后再切回。核对实际发布版本:`npm view sage-mem dist-tags`。
|
|
617
665
|
|
|
@@ -1,5 +1,5 @@
|
|
|
1
1
|
/**
|
|
2
|
-
* 检索工具(`search_memory` / `read_memory`)的挂载(1.2.0 从构造函数原样搬出)。
|
|
2
|
+
* 检索工具(`search_memory` / `read_memory` / `trim_memory`)的挂载(1.2.0 从构造函数原样搬出)。
|
|
3
3
|
*
|
|
4
4
|
* 工具是否注册成功。拿不到宿主的 `tools` 服务时为 false —— 状态卡据此换文案:
|
|
5
5
|
* 有工具就教它「用 search_memory 搜」,没有就退回「直接读记忆目录」。
|
|
@@ -27,9 +27,12 @@ export function mountMemoryTools(ctx) {
|
|
|
27
27
|
if (typeof ctx.inject === 'function') {
|
|
28
28
|
ctx.inject(['tools'], (inner) => {
|
|
29
29
|
try {
|
|
30
|
-
const { searchMemory, readMemory } = createMemoryTools(ctx)
|
|
30
|
+
const { searchMemory, readMemory, trimMemory } = createMemoryTools(ctx)
|
|
31
31
|
inner.tools.register(searchMemory)
|
|
32
32
|
inner.tools.register(readMemory)
|
|
33
|
+
// 2.10.1:体积治理的模型入口。与检索工具同一个注册窗口 —— 缺它不会让注入链降级,
|
|
34
|
+
// 只是模型少一条「把过大记忆裁小」的路(审计与做梦那边仍会照常提示)。
|
|
35
|
+
inner.tools.register(trimMemory)
|
|
33
36
|
state.ready = true
|
|
34
37
|
} catch (err) {
|
|
35
38
|
// 注册失败 ≠ 注入失败。出声一次,然后什么也不做。
|
package/lib/autodream/audit.js
CHANGED
|
@@ -28,6 +28,8 @@ import { readdir, readFile } from 'node:fs/promises'
|
|
|
28
28
|
import { join } from 'node:path'
|
|
29
29
|
import { hasFrontmatter, parseFrontmatter } from '../memory/frontmatter.js'
|
|
30
30
|
import { isIndexName, resolveIndexNames } from '../memory/index-file.js'
|
|
31
|
+
import { isNonEntry, isReserved } from '../memory/naming.js'
|
|
32
|
+
import { classifySize, indexFindings, sizeText } from '../memory/size-policy.js'
|
|
31
33
|
import { parseValidityTime } from '../memory/validity.js'
|
|
32
34
|
import { SESSION_LOG_KEY, isPlainMdName } from '../shared/md-name.js'
|
|
33
35
|
import { ARCHIVE_DIR_NAME, inspectMemoryEntry } from '../memory/scan.js'
|
|
@@ -415,6 +417,38 @@ export async function auditMemoryDir(dir, opts = {}) {
|
|
|
415
417
|
}
|
|
416
418
|
}
|
|
417
419
|
|
|
420
|
+
/**
|
|
421
|
+
* 体积治理(2.10.1)—— 超线条目与超长索引。
|
|
422
|
+
*
|
|
423
|
+
* 两条判据上的硬约束,都是「不加就会催人去干坏事」的那种:
|
|
424
|
+
* · **保护名单与非条目一律跳过**(`isReserved` / `isNonEntry`):它们本来就不许改,
|
|
425
|
+
* 把它们算成「超线待处置」等于让人去动 `MEMORY.md` / `session-log.md` / 自己声明的单副本;
|
|
426
|
+
* · **只有强制线(≥40 KB)进 problems**(见下面 `problems` 汇总):16 KB 只是提醒线,
|
|
427
|
+
* 掺进去会让 `problems` 这个唯一健康数字变成「永远大于 0」的噪音 —— 与 validityHints
|
|
428
|
+
* 同一条理由(issue #8 的教训)。
|
|
429
|
+
* 索引单列:它压根不许改(本版只报不改),进 problems 只会挂一盏关不掉的红灯。
|
|
430
|
+
*/
|
|
431
|
+
const oversize = []
|
|
432
|
+
for (const f of entries) {
|
|
433
|
+
// 读不动的已经单列 `unreadable`:这里再报一次等于同一件事记两笔。
|
|
434
|
+
if (!contents.has(f)) continue
|
|
435
|
+
if (isReserved(f) || isNonEntry(f)) continue
|
|
436
|
+
const verdict = classifySize({ bytes: Buffer.byteLength(contents.get(f), 'utf8'), kind: 'entry' })
|
|
437
|
+
if (verdict.level === 'warn' || verdict.level === 'force') {
|
|
438
|
+
oversize.push({ file: f, bytes: verdict.bytes, level: verdict.level })
|
|
439
|
+
}
|
|
440
|
+
}
|
|
441
|
+
const indexOversize = []
|
|
442
|
+
if (indexText) {
|
|
443
|
+
const findings = indexFindings(indexText)
|
|
444
|
+
// ok 不进清单:健康的索引不该在报告里占一行。
|
|
445
|
+
if (findings.level !== 'ok') {
|
|
446
|
+
indexOversize.push({ file: indexFile, bytes: findings.bytes, longLines: findings.longLines.length })
|
|
447
|
+
}
|
|
448
|
+
}
|
|
449
|
+
/** 强制线以上的条数 —— 这是体积这一项对 `problems` 的唯一贡献。 */
|
|
450
|
+
const oversizeForced = oversize.filter((o) => o.level === 'force').length
|
|
451
|
+
|
|
418
452
|
const problems =
|
|
419
453
|
dangling.length +
|
|
420
454
|
unlisted.length +
|
|
@@ -425,7 +459,8 @@ export async function auditMemoryDir(dir, opts = {}) {
|
|
|
425
459
|
hashHazards.length +
|
|
426
460
|
noFrontmatter.length +
|
|
427
461
|
unreadable.length +
|
|
428
|
-
strays.length
|
|
462
|
+
strays.length +
|
|
463
|
+
oversizeForced
|
|
429
464
|
|
|
430
465
|
return {
|
|
431
466
|
dir,
|
|
@@ -450,6 +485,11 @@ export async function auditMemoryDir(dir, opts = {}) {
|
|
|
450
485
|
noFrontmatter: noFrontmatter.map((file) => ({ file })),
|
|
451
486
|
unreadable: unreadable.map((file) => ({ file })),
|
|
452
487
|
strays: strays.map((file) => ({ file })),
|
|
488
|
+
// 2.10.1 体积治理:warn / force 都列(面板与模型都要看见「该处置了」),
|
|
489
|
+
// 但只有 force 计入 problems —— 见上面那段。
|
|
490
|
+
oversize,
|
|
491
|
+
// 索引超长:**只报不改**(MEMORY.md 在保护名单里),因此永不进 problems。
|
|
492
|
+
indexOversize,
|
|
453
493
|
problems,
|
|
454
494
|
}
|
|
455
495
|
}
|
|
@@ -472,6 +512,23 @@ export function formatAudit(report, limit = 12) {
|
|
|
472
512
|
}
|
|
473
513
|
section('索引悬空', report.dangling, (r) => r.file)
|
|
474
514
|
section('漏索引', report.unlisted, (r) => r.file)
|
|
515
|
+
/**
|
|
516
|
+
* 体积两节(2.10.1)。标题里直接写「怎么办」,因为这两类是**模型能立刻动手**的:
|
|
517
|
+
* 说「体积过大」它只会如实转述,说「能拆就 archive_segment、拆不开就压缩」它才会去做。
|
|
518
|
+
*
|
|
519
|
+
* ⚠️ 两节而不是三节:这一段每次审计都会进模型上下文,拆得越细 token 越贵。
|
|
520
|
+
* 强制线与提醒线合在一节里用**行内标签**区分,但**排序时 force 在前** ——
|
|
521
|
+
* `limit` 截断时被砍掉的必须是「还能再等一等」的那些,不是「本趟必须处置」的那些。
|
|
522
|
+
* 索引单列一节:它压根不许改(本版只报不改),混进超线清单会让人去动 `MEMORY.md`。
|
|
523
|
+
*/
|
|
524
|
+
const overs = report.oversize ?? []
|
|
525
|
+
const oversizeRows = [...overs.filter((r) => r.level === 'force'), ...overs.filter((r) => r.level !== 'force')]
|
|
526
|
+
section('超线体积(≥40 KB 必须处置:能拆一节就 archive_segment,拆不开就 write_memory 压缩;16 KB 起只提醒)', oversizeRows, (r) =>
|
|
527
|
+
`${r.file} ${sizeText(r.bytes)} · ${r.level === 'force' ? '必须处置' : '提醒'}`,
|
|
528
|
+
)
|
|
529
|
+
section('索引过长(只报不改:MEMORY.md 在保护名单里)', report.indexOversize ?? [], (r) =>
|
|
530
|
+
`${r.file} ${sizeText(r.bytes)} · ${r.longLines} 行超过单行上限`,
|
|
531
|
+
)
|
|
475
532
|
// 多个大小写变体各自都可能是「用户以为的那份索引」:两边都列出来,让他删掉多余的。
|
|
476
533
|
section('索引大小写冲突(同一目录存在多个变体,请只保留一个)', report.indexConflicts ?? [], (r) => r.file)
|
|
477
534
|
section('type 与前缀不一致', report.typeMismatch, (r) => `${r.file} type=${r.type} 前缀=${r.prefix}`)
|
package/lib/autodream/prompt.js
CHANGED
|
@@ -1,8 +1,11 @@
|
|
|
1
1
|
/**
|
|
2
2
|
* sage-mem autodream — 提示词。
|
|
3
3
|
*
|
|
4
|
-
* 四阶段结构:定位 → 收集 → 整合 →
|
|
4
|
+
* 四阶段结构:定位 → 收集 → 整合 → 修剪与索引。2.10.1 在「整合」与「修剪」之间插了
|
|
5
|
+
* **阶段 3.5 体积治理**(超 40 KB 的条目必须裁段归档或压缩,2.10.2 起线从 16 KB 抬到 40 KB),
|
|
6
|
+
* 所以实际是五节。
|
|
5
7
|
*
|
|
8
|
+
* 两个非显然的取舍:
|
|
6
9
|
* 1. **写记忆的规范必须随 prompt 自带。** autodream 是一次独立调用,带不上外部的
|
|
7
10
|
* 技能文档。所以四类前缀、`type` 一致性、YAML 两个静默陷阱、受保护文件名这些
|
|
8
11
|
* **必须**出现在 prompt 里,否则模型会照着「看起来像」的方式写坏。
|
|
@@ -26,7 +29,7 @@ export function buildAutodreamSystemPrompt(opts) {
|
|
|
26
29
|
const { apply, withSessions } = opts
|
|
27
30
|
const reserved = Array.isArray(opts.reservedFiles) ? opts.reservedFiles.filter(Boolean) : []
|
|
28
31
|
const reservedNote = reserved.length
|
|
29
|
-
? `-
|
|
32
|
+
? `- **保护名单:不许改、也不计入超线**(使用者指定):${reserved.map((f) => `\`${f}\``).join('、')} —— 这些多半是手写单副本、人工维护的重要记忆,一个字都不要动;它们的体积再大也不算「待处置」,不要因为「太大」去动它们`
|
|
30
33
|
: '- 有些记忆是使用者手写单副本、人工维护的;本次没有额外指定保护名单,遇到明显「成篇手写、结构不像流水」的记忆请保守处理'
|
|
31
34
|
const modeLine = apply
|
|
32
35
|
? '本次是**改写模式**:你有写工具,可以直接改记忆文件。运行前已经把整个 memory 目录快照了一份(这就是回滚点),改坏能整体退回去——但这只保证「可恢复」,不保证「改得对」。宁可少改,不要乱动。\n\n**每一次写入都请写清 `reason`。** 这一趟是无人值守跑的,人只能靠这份缘由判断你改得对不对。写清「为什么改这条、改成了什么」,不要写「整理优化」这种没有信息量的话。缺了**不会被拒绝**——改动照样生效——但整理声明里会把那条标成「未自述」,用宿主能追溯到的信息顶替。\n\n**遇到两条说法互斥的记忆(同一件事两种说法),用 `report_contradiction` 报出来,不要自己删改其中任何一条。** 裁决由人做:报出来之后这两条暂时都不进正文,人会在面板上选哪条作废。自己删改等于替人决定「哪条历史不该存在」。'
|
|
@@ -85,6 +88,21 @@ export function buildAutodreamUserPrompt(opts) {
|
|
|
85
88
|
- 两条记忆互相矛盾时,用 \`report_contradiction\` 报出来(不要自己删改其中任何一条)`
|
|
86
89
|
: `- 给出 \`MEMORY.md\` 该增删哪些行的**具体清单**(逐字给出要改成的那行文本)`
|
|
87
90
|
|
|
91
|
+
/**
|
|
92
|
+
* 阶段 3.5(2.10.1 体积治理)。两条路都要写出来,而且**必须带工具名与判据**:
|
|
93
|
+
* 只说「处置一下超大的记忆」,模型会回一句「有几条偏大」就过去了;写清「能拆就 archive_segment、
|
|
94
|
+
* 拆不开就 write_memory 压缩」,它才知道自己手上真有这两把刀。
|
|
95
|
+
*
|
|
96
|
+
* 两种模式分叉同样必须:「只出报告」那一趟**没有写工具**,让它「去压缩」只会让它编一段
|
|
97
|
+
* 假动作写进报告里(与阶段 4 的分叉同一条理由)。
|
|
98
|
+
*/
|
|
99
|
+
const stage3_5 = apply
|
|
100
|
+
? `- **能拆出一个完整小节** → \`archive_segment\`:旧段进 \`archive/\`(可人工捞回),主文件原位置自动留一行指针
|
|
101
|
+
- **拆不开** → \`write_memory\` 就地压缩:结论前置、去重、删掉已被推翻的说法;压缩后宿主会自动补压缩留痕,缘由用你自己的 \`reason\`
|
|
102
|
+
- 动手前先跑 \`audit_memory\` —— 它会直接列出超过 40 KB 的条目,别自己拿眼睛估体积`
|
|
103
|
+
: `- 逐条列出超过 40 KB 的文件,并给**能照着动手**的处置:裁哪一节(写出小节标题或行区间),或压成哪几句要点
|
|
104
|
+
- 不要只写「建议压缩」—— 那句话在下一趟里等于什么都没说`
|
|
105
|
+
|
|
88
106
|
return `# Autodream:一次记忆整理
|
|
89
107
|
|
|
90
108
|
今天:${stampDate(now)}
|
|
@@ -114,6 +132,16 @@ export function buildAutodreamUserPrompt(opts) {
|
|
|
114
132
|
|
|
115
133
|
${apply ? '你有写工具,直接落盘。**每次 `write_memory` / `archive_memory` 都必须带 `reason`**(一句话:为什么动这条、动成了什么)。这一趟的每次改动都会被记进「整理声明」,人要照着它核对。' : '你没有写工具,把每条改动写成「文件 → 具体改成什么 → 为什么」的形式。'}
|
|
116
134
|
|
|
135
|
+
## 阶段 3.5 — 体积治理
|
|
136
|
+
|
|
137
|
+
体积线:单条 **16 KB 提醒、40 KB 强制**。**超过 40 KB 的条目本趟必须处置**,二选一:
|
|
138
|
+
|
|
139
|
+
${stage3_5}
|
|
140
|
+
|
|
141
|
+
- \`MEMORY.md\`、\`session-log.md\`、保护名单里的文件**不算**(它们不许动,也不计入超线)
|
|
142
|
+
- 裁段**必须带 \`reason\`**:一句话说清这段为什么该进档案馆。工具会自动在主文件原位置留一行指针,**不需要**你自己摘索引(文件还在顶层,摘了反而错)
|
|
143
|
+
- 若确实一条都没处置,回报里**说明为什么**(例如「都超线了但拆不开、压缩也压不下去」),不要沉默
|
|
144
|
+
|
|
117
145
|
## 阶段 4 — 修剪与索引
|
|
118
146
|
|
|
119
147
|
${stage4}
|