remem-mcp 0.7.0 → 0.7.6
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.md +84 -262
- package/dist/{chunk-TGLOMFIE.js → chunk-2RKMX6EE.js} +49 -8
- package/dist/chunk-2RKMX6EE.js.map +1 -0
- package/dist/{chunk-OYUNKUZK.js → chunk-L7YZBBIB.js} +1085 -34
- package/dist/chunk-L7YZBBIB.js.map +1 -0
- package/dist/{chunk-ZXI67YIV.js → chunk-MPEN2X43.js} +120 -4
- package/dist/chunk-MPEN2X43.js.map +1 -0
- package/dist/{engine-3JUSB3RK.js → engine-LAY25SCA.js} +4 -2
- package/dist/index.js +781 -294
- package/dist/index.js.map +1 -1
- package/dist/{resolver-YIFWRNMS.js → resolver-UHU4MBQX.js} +50 -15
- package/dist/resolver-UHU4MBQX.js.map +1 -0
- package/dist/sdk.js +3 -3
- package/dist/{server-SUKPVQWL.js → server-MYSF7R5Y.js} +4 -3
- package/dist/server-MYSF7R5Y.js.map +1 -0
- package/dist/storage/schema.sql +76 -5
- package/package.json +1 -1
- package/scripts/verify-codegraph-stats.mjs +122 -0
- package/skills/remem-mcp/SKILL.md +14 -4
- package/dist/chunk-OYUNKUZK.js.map +0 -1
- package/dist/chunk-TGLOMFIE.js.map +0 -1
- package/dist/chunk-ZXI67YIV.js.map +0 -1
- package/dist/resolver-YIFWRNMS.js.map +0 -1
- package/dist/server-SUKPVQWL.js.map +0 -1
- /package/dist/{engine-3JUSB3RK.js.map → engine-LAY25SCA.js.map} +0 -0
package/README.md
CHANGED
|
@@ -5,25 +5,11 @@
|
|
|
5
5
|
[](https://opensource.org/licenses/MIT)
|
|
6
6
|
[](https://github.com/tinhien11/remem-mcp)
|
|
7
7
|
|
|
8
|
-
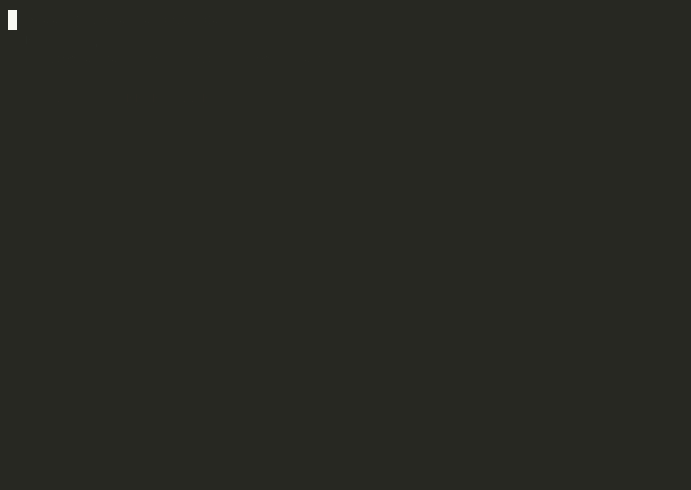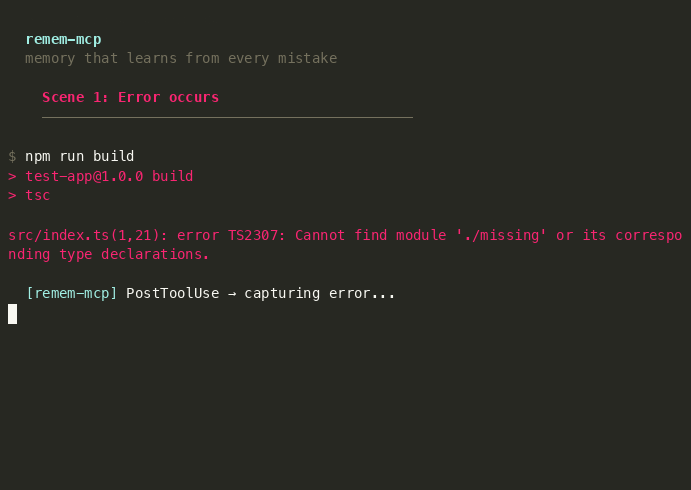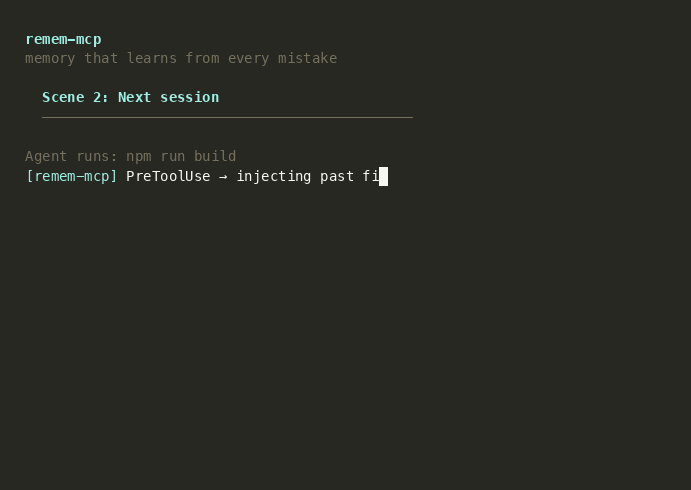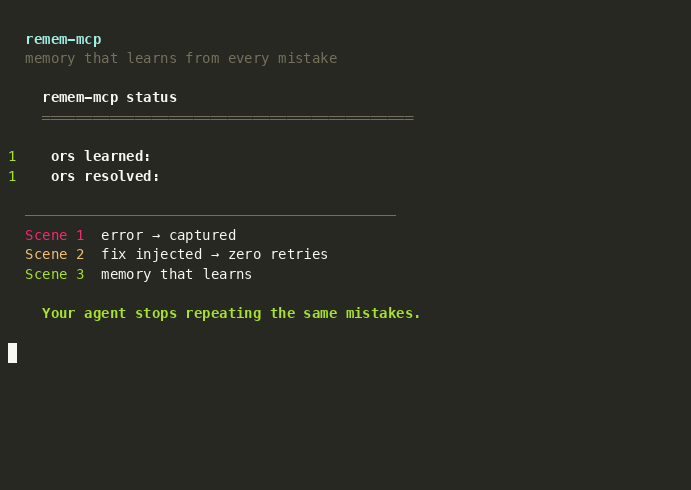
> Your coding agent stops repeating the same mistakes
|
|
8
|
+
> Your coding agent stops repeating the same mistakes.
|
|
9
9
|
|
|
10
|
-
Local memory that survives context compaction
|
|
10
|
+
Local-first memory that survives context compaction. Learns from every error, injects fixes before the next attempt, and syncs to your git repo so your whole team shares it.
|
|
11
11
|
|
|
12
|
-
**
|
|
13
|
-
|
|
14
|
-
<video src="https://raw.githubusercontent.com/tinhien11/remem-mcp/main/docs/screenshots/demo-learning-loop.mp4" controls muted width="100%"></video>
|
|
15
|
-
|
|
16
|
-
|
|
17
|
-
|
|
18
|
-
### See it in action
|
|
19
|
-
|
|
20
|
-
| Error learning loop | CodeGraph search | Web viewer |
|
|
21
|
-
|---|---|---|
|
|
22
|
-
|  | 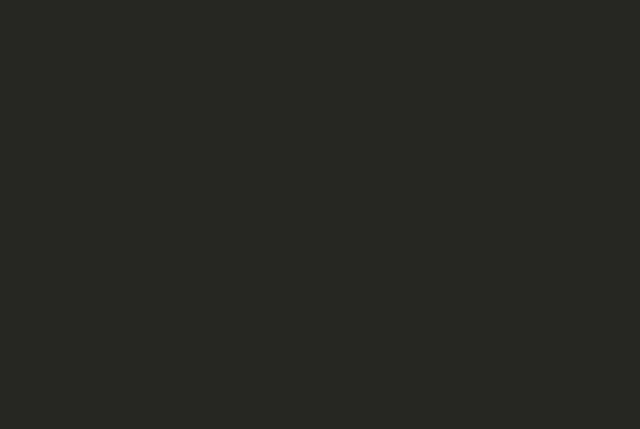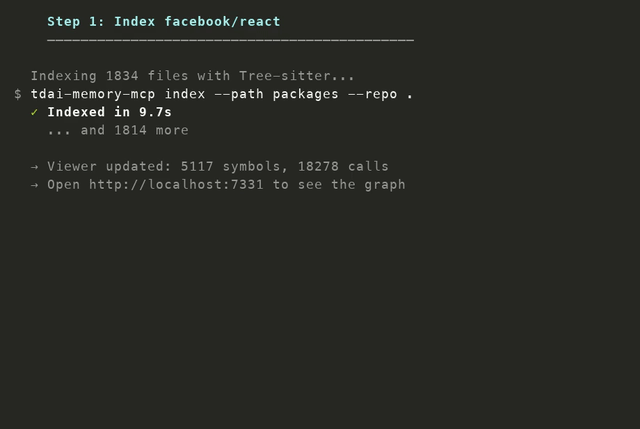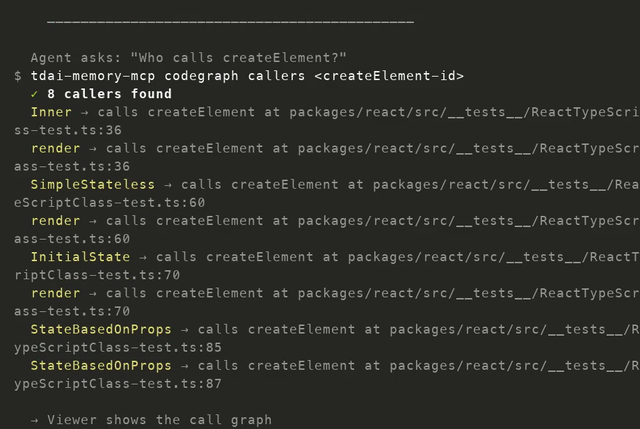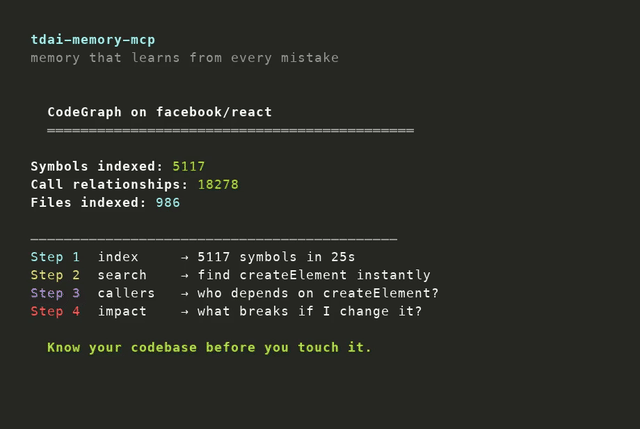 | 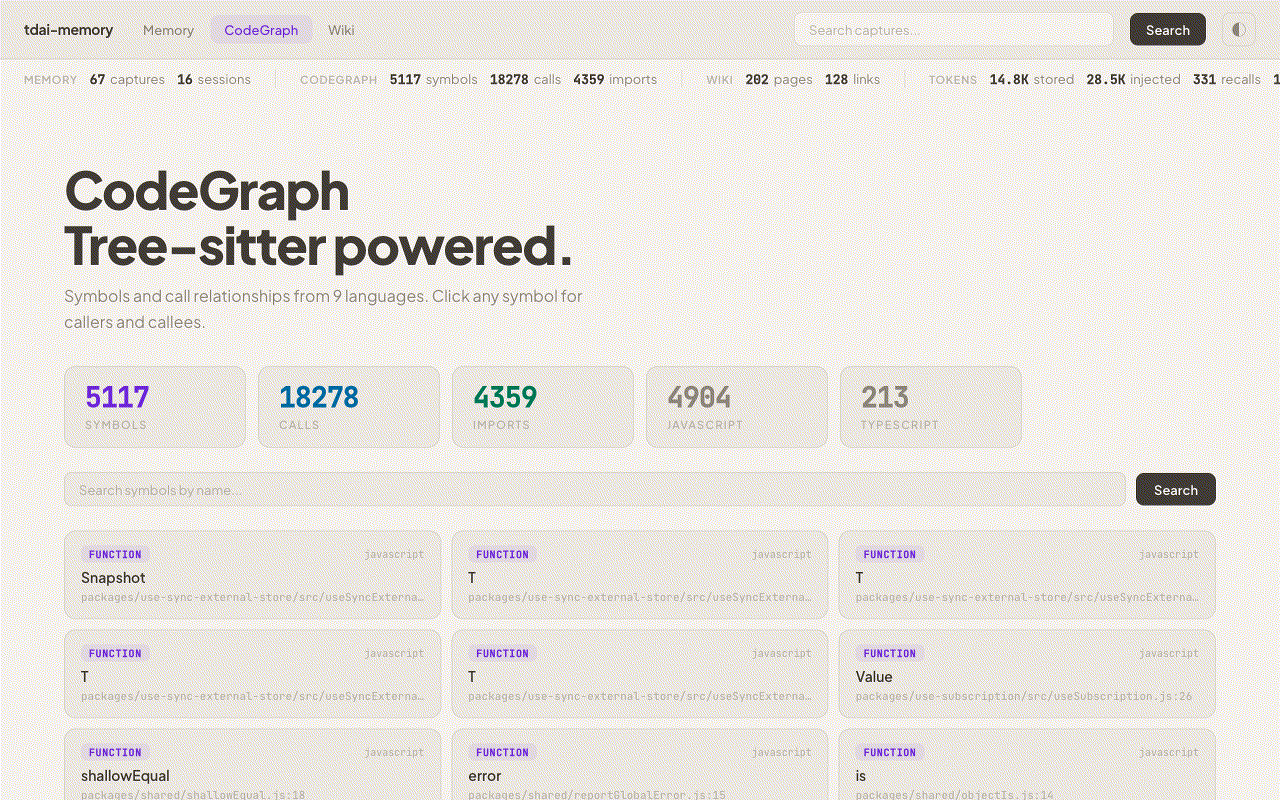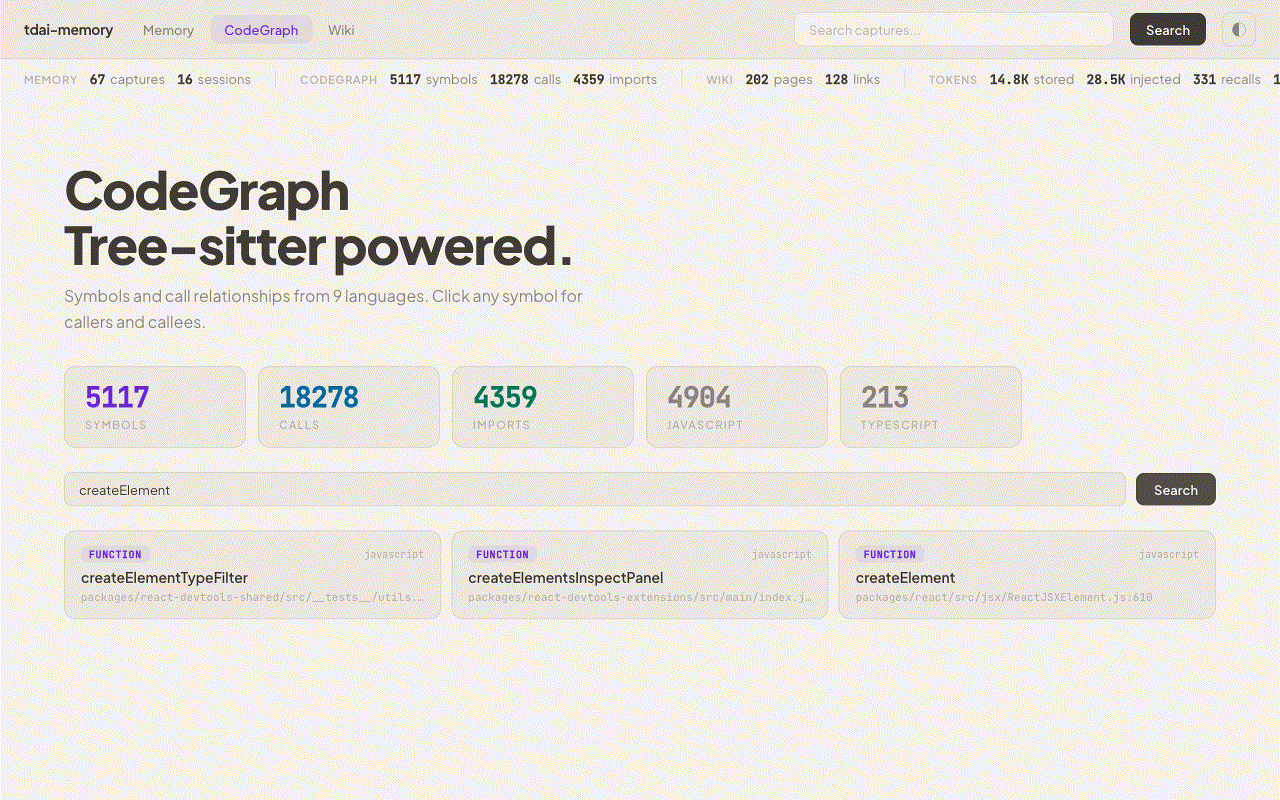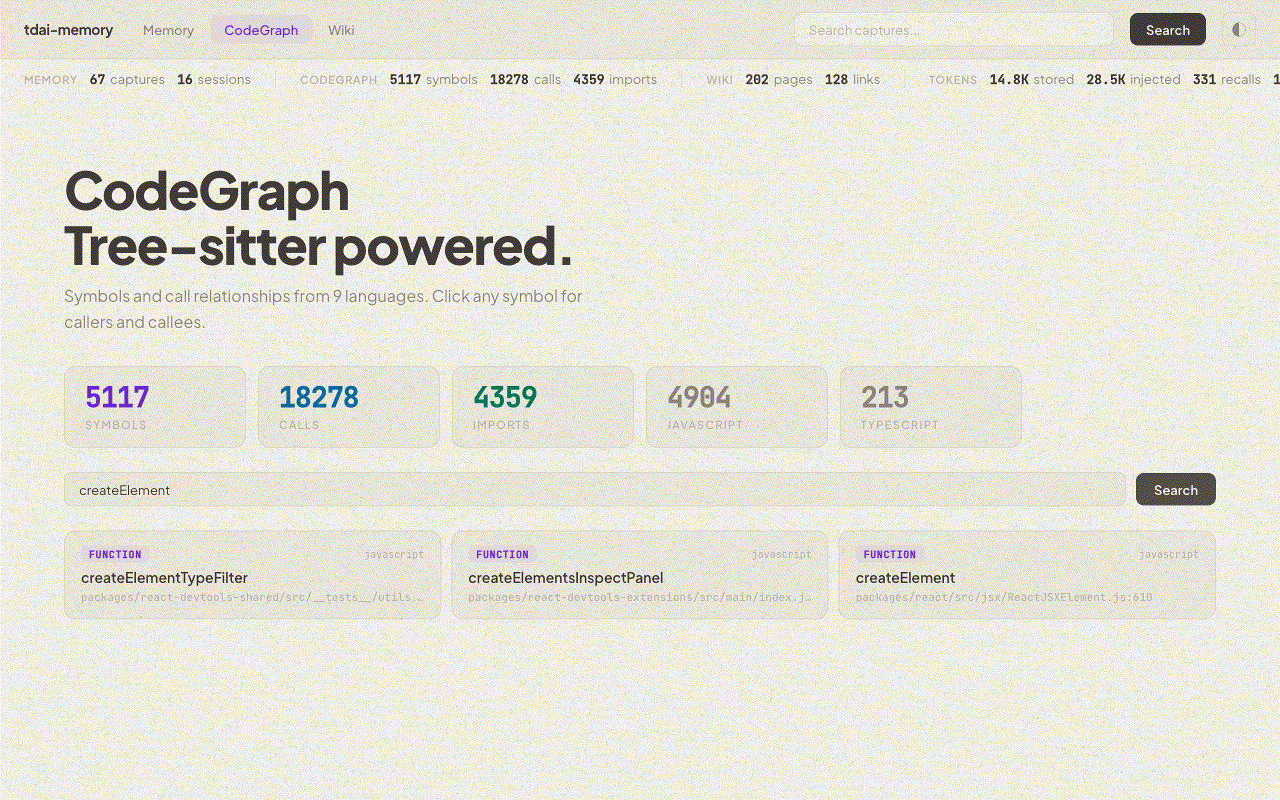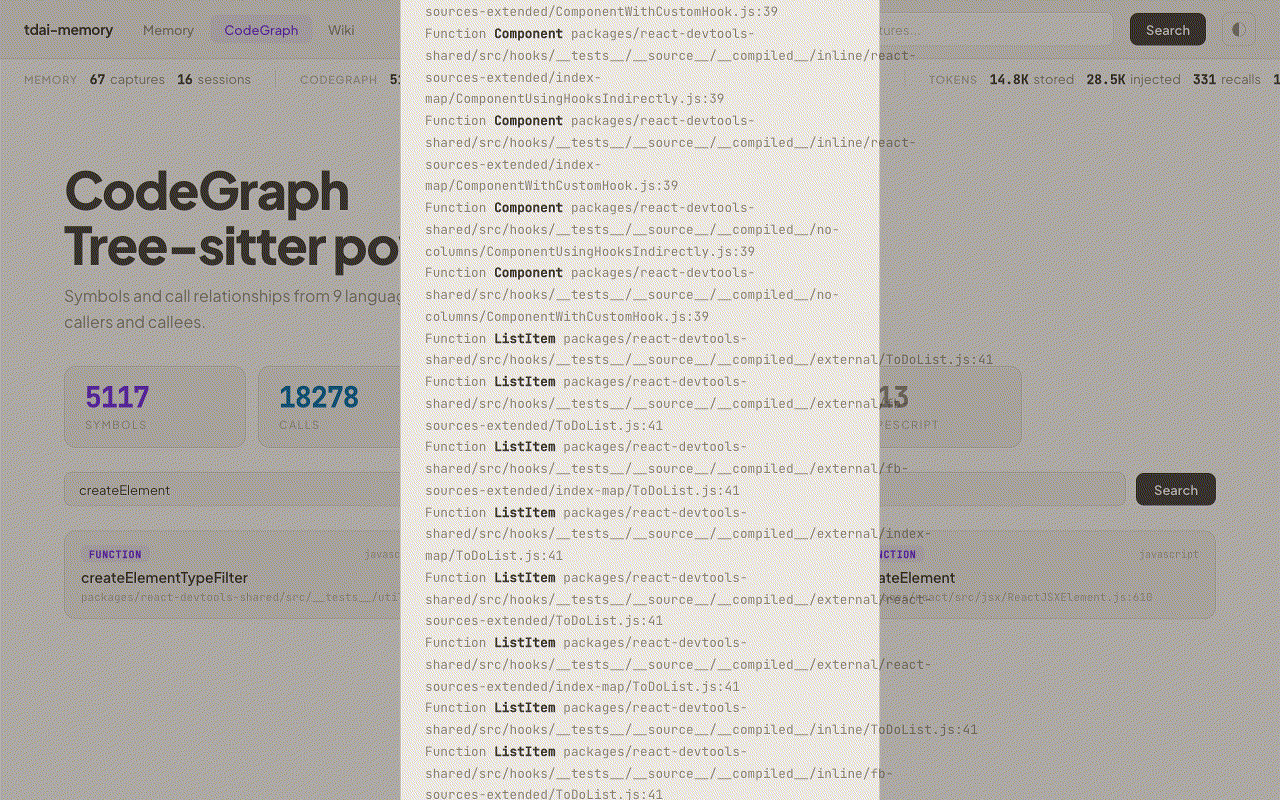 |
|
|
23
|
-
|
|
24
|
-
| Viewer: overview | CodeGraph: callers | CodeGraph: search |
|
|
25
|
-
|---|---|---|
|
|
26
|
-
| 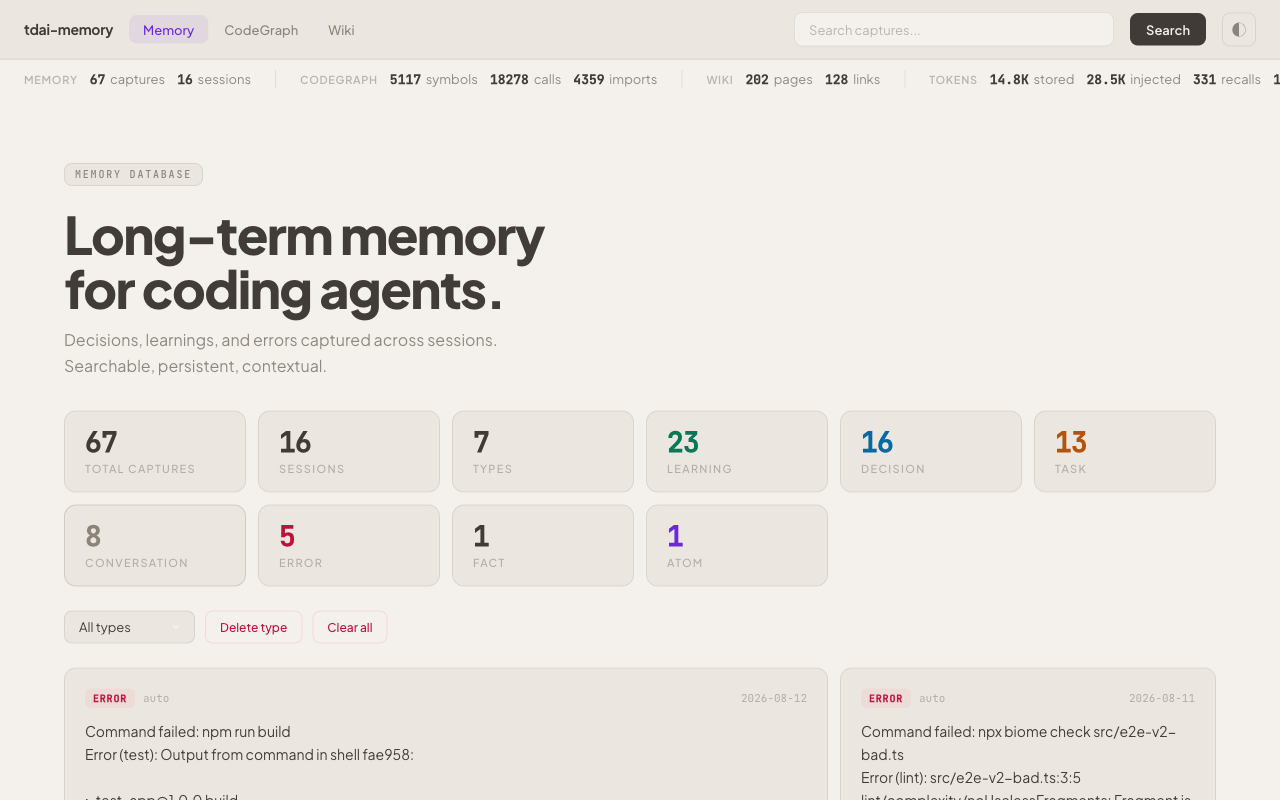 |  | 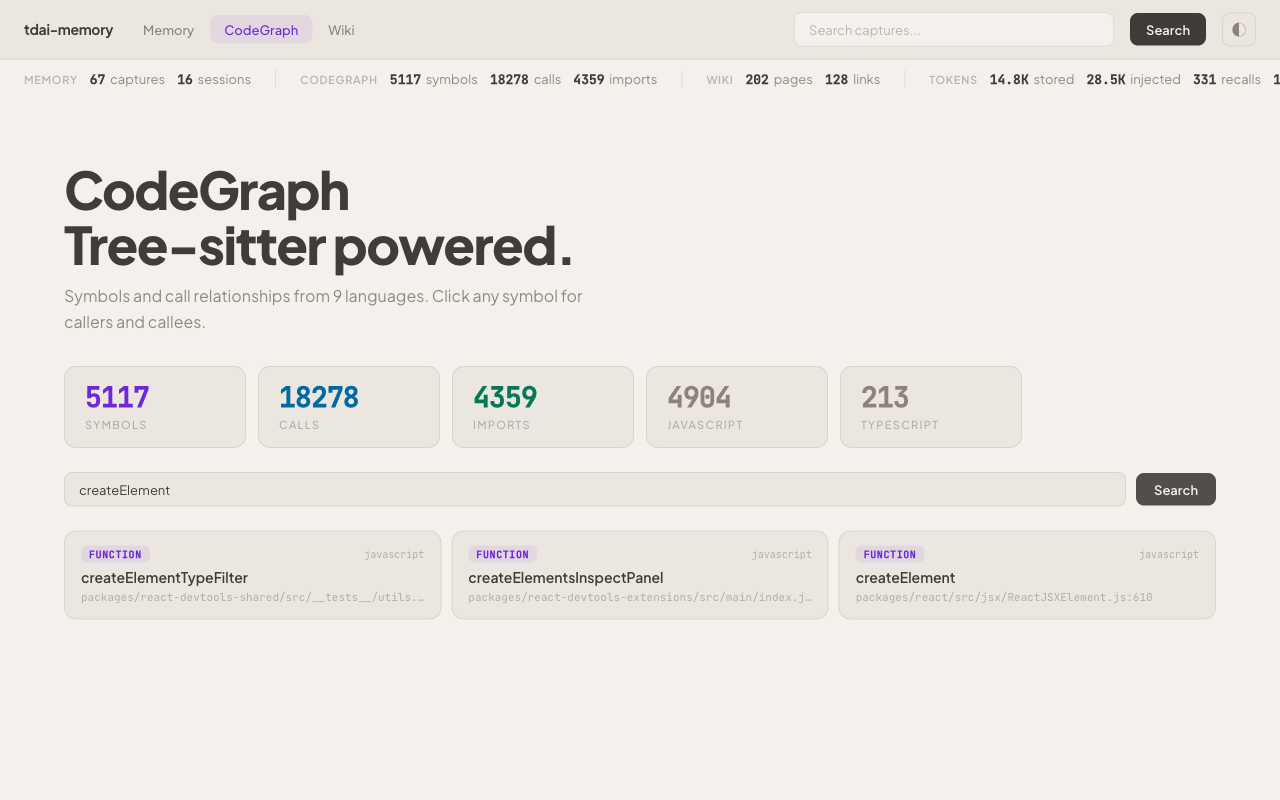 |
|
|
12
|
+
**No API key. No cloud. No database server. Just a SQLite file.**
|
|
27
13
|
|
|
28
14
|
---
|
|
29
15
|
|
|
@@ -33,242 +19,106 @@ Local memory that survives context compaction — learns from every error, injec
|
|
|
33
19
|
npx remem-mcp setup
|
|
34
20
|
```
|
|
35
21
|
|
|
36
|
-
|
|
37
|
-
|
|
38
|
-
```bash
|
|
39
|
-
npx remem-mcp demo # Live demo: real build, real errors, real hooks
|
|
40
|
-
npx remem-mcp demo-codegraph # Live CodeGraph demo on facebook/react
|
|
41
|
-
npx remem-mcp status # One dashboard: everything at a glance
|
|
42
|
-
```
|
|
43
|
-
|
|
44
|
-
The demo creates a real TypeScript project, runs real `npm run build`, captures real TS2307 errors, and shows the full learning loop — capture → inject → fix → zero retries. No hardcoded strings.
|
|
22
|
+
Auto-detects ZCode, Claude Code, Cursor, Devin, Codex. Registers MCP server + hooks.
|
|
45
23
|
|
|
46
24
|
---
|
|
47
25
|
|
|
48
|
-
## Quick start
|
|
49
|
-
|
|
50
|
-
**Nothing.** Just use your agent normally. No commands, no setup, no init.
|
|
26
|
+
## Quick start
|
|
51
27
|
|
|
52
|
-
|
|
53
|
-
|
|
54
|
-
|
|
55
|
-
- **Session end** → worker auto-extracts facts, consolidates summaries, updates persona
|
|
28
|
+
1. Restart your agent (quit and reopen)
|
|
29
|
+
2. Ask: "what do you remember?"
|
|
30
|
+
3. If agent recalls past context = memory working
|
|
56
31
|
|
|
57
|
-
|
|
58
|
-
|
|
59
|
-
|
|
32
|
+
In your agent, you can say:
|
|
33
|
+
- "index the code in src" → CodeGraph indexes symbols
|
|
34
|
+
- "find who calls function X" → caller analysis
|
|
35
|
+
- "what do you remember?" → recall past context
|
|
60
36
|
|
|
61
37
|
---
|
|
62
38
|
|
|
63
|
-
## What
|
|
64
|
-
|
|
65
|
-
```
|
|
66
|
-
┌─────────────────────────────────────────────────┐
|
|
67
|
-
│ AI Agent │
|
|
68
|
-
│ (Claude Code / Devin / Cursor) │
|
|
69
|
-
└────────┬──────────────────────────┬──────────────┘
|
|
70
|
-
│ MCP tools (45) │ Hooks (auto)
|
|
71
|
-
▼ ▼
|
|
72
|
-
┌──────────────────┐ ┌────────────────────┐
|
|
73
|
-
│ recall() │ │ SessionStart │──▶ inject L2/L3 + skills + canvas
|
|
74
|
-
│ capture() │ │ UserPromptSubmit │──▶ inject BM25 match
|
|
75
|
-
│ codegraph_* │ │ PreToolUse │──▶ inject canvas + skills + errors
|
|
76
|
-
│ wiki_* │ │ PostToolUse │──▶ offload to refs + canvas node
|
|
77
|
-
│ canvas_get │ │ Stop │──▶ spawn worker + skill extraction
|
|
78
|
-
│ ref_read │ │ PostCompact │──▶ save checkpoint
|
|
79
|
-
│ skill_* │ │ │
|
|
80
|
-
│ proxy (HTTP) │ │ │
|
|
81
|
-
└────────┬─────────┘ └─────────┬──────────┘
|
|
82
|
-
│ │
|
|
83
|
-
▼ ▼
|
|
84
|
-
┌─────────────────────────────────────────────────┐
|
|
85
|
-
│ SQLite (memory.db) │
|
|
86
|
-
│ │
|
|
87
|
-
│ L0 captures ──▶ L1 atoms ──▶ L2 scenarios ──▶ L3 persona
|
|
88
|
-
│ (raw) (facts) (summaries) (preferences)
|
|
89
|
-
│ │
|
|
90
|
-
│ CodeGraph: symbols + calls + imports │
|
|
91
|
-
│ Wiki: markdown docs + ADRs │
|
|
92
|
-
│ Canvas: Mermaid nodes + edges + refs │
|
|
93
|
-
│ Skills: trigger conditions + steps + validation │
|
|
94
|
-
└───────────────────────────────────────────────────┘
|
|
95
|
-
```
|
|
96
|
-
|
|
97
|
-
### Memory pipeline (L0 → L3)
|
|
39
|
+
## What happens automatically
|
|
98
40
|
|
|
99
|
-
|
|
100
|
-
|
|
101
|
-
|
|
102
|
-
|
|
41
|
+
| When | What |
|
|
42
|
+
|---|---|
|
|
43
|
+
| Session start | Past errors, decisions, and persona injected into agent context |
|
|
44
|
+
| Each prompt | Matching memory injected into agent context |
|
|
45
|
+
| Failed commands | Auto-captured as error memories |
|
|
46
|
+
| Context compaction | Memory re-injected after compaction |
|
|
47
|
+
| Session end | Worker auto-extracts facts, consolidates summaries, updates persona |
|
|
103
48
|
|
|
104
|
-
|
|
105
|
-
|
|
106
|
-
### CodeGraph
|
|
107
|
-
|
|
108
|
-
Structural code indexing via tree-sitter (9 languages: TS/JS/Python/Go/Rust/Java/C/C++/C#).
|
|
109
|
-
|
|
110
|
-
- **6-strategy call resolution**: import-map (0.95) → same-module (0.90) → unique-name (0.75) → suffix (0.55) → fuzzy (0.35)
|
|
111
|
-
- **Call types**: direct (`foo()`), method (`obj.method()`), JSX (`<Component/>`)
|
|
112
|
-
- **Stdlib filter**: skips `fmt.Printf`, `console.log`, `print()` — reduces noise
|
|
113
|
-
- **Tools**: `codegraph_search`, `codegraph_callers`, `codegraph_callees`, `codegraph_impact`, `codegraph_detect_changes`
|
|
49
|
+
You don't run any commands. The agent calls `recall()` before answering and `capture()` after work — the skill tells it to.
|
|
114
50
|
|
|
115
51
|
---
|
|
116
52
|
|
|
117
|
-
##
|
|
118
|
-
|
|
119
|
-
| | remem-mcp | Mem0 | Claude MEMORY.md | Mneme | TencentDB |
|
|
120
|
-
|---|---|---|---|---|---|
|
|
121
|
-
| **Survives compaction** | Yes — PreCompact hook saves checkpoint, re-injects after | Yes — cloud store | No — 200-line cap, silent truncation | Yes — PreCompact hook | Yes |
|
|
122
|
-
| **Learns from errors** | Yes — auto-captures, injects fixes | No | No | No | No |
|
|
123
|
-
| **Symbolic short-term memory** | Yes — Mermaid canvas, 92% token reduction | No | No | No | Yes — 61% on WideSearch |
|
|
124
|
-
| **Memory proxy** | Yes — OpenAI + Anthropic, zero-code | No | No | No | Yes |
|
|
125
|
-
| **Skill auto-extraction** | Yes — rule-based, no LLM needed | No | No | No | Yes — LLM-based |
|
|
126
|
-
| **Semantic search** | Hybrid BM25 + sqlite-vec | Vector only | No — LLM filename picker, max 5 files | Vector + graph | Hybrid |
|
|
127
|
-
| **Setup** | 1 command | API key + cloud | Built-in | Build from source (Rust) | Docker |
|
|
128
|
-
| **Data location** | Local SQLite | Cloud | Local markdown | Local SQLite | SQLite |
|
|
129
|
-
| **Team sharing** | Git-native (commit, diff, merge) | Cloud sync | Copy-paste | Manual | Cloud |
|
|
130
|
-
| **API key** | No | Yes | No | No | No |
|
|
131
|
-
| **Cost** | Free | $19–249/mo | Free | Free | Free |
|
|
132
|
-
|
|
133
|
-
---
|
|
134
|
-
|
|
135
|
-
## Per-agent install
|
|
136
|
-
|
|
137
|
-
<details>
|
|
138
|
-
<summary>Claude Code</summary>
|
|
139
|
-
|
|
140
|
-
```bash
|
|
141
|
-
claude mcp add remem-mcp --scope user -- npx -y remem-mcp
|
|
142
|
-
npx remem-mcp install-hooks
|
|
143
|
-
```
|
|
144
|
-
</details>
|
|
145
|
-
|
|
146
|
-
<details>
|
|
147
|
-
<summary>Cursor</summary>
|
|
148
|
-
|
|
149
|
-
[](cursor://anysphere.cursor-deeplink/mcp/install?name=remem-mcp&config=eyJjb21tYW5kIjoibnB4IiwiYXJncyI6WyIteSIsInJlbWVtLW1jcCJdfQ==)
|
|
53
|
+
## How it works
|
|
150
54
|
|
|
151
|
-
Or add to `~/.cursor/mcp.json`:
|
|
152
|
-
```json
|
|
153
|
-
{
|
|
154
|
-
"mcpServers": {
|
|
155
|
-
"remem-mcp": { "command": "npx", "args": ["-y", "remem-mcp"] }
|
|
156
|
-
}
|
|
157
|
-
}
|
|
158
55
|
```
|
|
159
|
-
|
|
160
|
-
|
|
161
|
-
|
|
162
|
-
|
|
163
|
-
|
|
164
|
-
|
|
165
|
-
|
|
166
|
-
|
|
56
|
+
AI Agent (ZCode / Claude Code / Devin / Cursor / Codex)
|
|
57
|
+
│
|
|
58
|
+
├── MCP tools ──▶ recall, capture, codegraph_*, wiki_*, feedback
|
|
59
|
+
│
|
|
60
|
+
└── Hooks ──▶ SessionStart, UserPromptSubmit,
|
|
61
|
+
PostToolUse, PostCompaction, SessionEnd
|
|
62
|
+
│
|
|
63
|
+
▼
|
|
64
|
+
SQLite (memory.db)
|
|
65
|
+
|
|
66
|
+
L0 captures → L1 atoms → L2 scenarios → L3 persona
|
|
67
|
+
(raw) (facts) (summaries) (preferences)
|
|
68
|
+
|
|
69
|
+
CodeGraph: symbols + calls + imports (tree-sitter, 9 languages)
|
|
70
|
+
Memory links: Hebbian co-retrieval (frequently co-retrieved = stronger)
|
|
167
71
|
```
|
|
168
|
-
</details>
|
|
169
72
|
|
|
170
|
-
|
|
171
|
-
<summary>Codex CLI</summary>
|
|
172
|
-
|
|
173
|
-
Add to `~/.codex/config.toml`:
|
|
174
|
-
```toml
|
|
175
|
-
[mcp_servers.remem-mcp]
|
|
176
|
-
command = "npx"
|
|
177
|
-
args = ["-y", "remem-mcp"]
|
|
178
|
-
|
|
179
|
-
[mcp_servers.remem-mcp.env]
|
|
180
|
-
REMEM_GLOBAL_SESSION_KEY = "global"
|
|
181
|
-
```
|
|
182
|
-
|
|
183
|
-
Then run `npx remem-mcp install-hooks`.
|
|
184
|
-
> MCP tools require `sandbox_mode = "danger-full-access"`.
|
|
185
|
-
</details>
|
|
73
|
+
**No LLM API key needed** — rule-based extraction + keyword grouping.
|
|
186
74
|
|
|
187
75
|
---
|
|
188
76
|
|
|
189
|
-
##
|
|
190
|
-
|
|
191
|
-
Memory lives in a local SQLite database — outside the agent's context window. When the agent compacts or starts a new session, memory is re-injected automatically. No more re-explaining what you already told it yesterday.
|
|
192
|
-
|
|
193
|
-
**PreCompact hook**: when the agent is about to compact context, remem-mcp saves a checkpoint (decisions made, approaches tried, what's verified working) to the DB. After compaction, the agent recalls it — so the compact doesn't destroy your session's learnings.
|
|
194
|
-
|
|
195
|
-
Two layers: **automatic** (runs via hooks, zero tool calls) and **on-demand** (you call when you need deeper context).
|
|
196
|
-
|
|
197
|
-
### Automatic — three learning loops + compaction survival + symbolic memory
|
|
198
|
-
|
|
199
|
-
All run via lifecycle hooks. The agent doesn't need to call any tool.
|
|
200
|
-
|
|
201
|
-
1. **Error learning** — command fails → capture → inject fix before next attempt → succeed → upvote.
|
|
202
|
-
|
|
203
|
-
2. **Decision learning** — `npm install`, `git commit`, config → auto-capture → inject past decisions before similar commands.
|
|
204
|
-
|
|
205
|
-
3. **Pattern learning** — Write/Edit → auto-capture code patterns → inject same-language patterns before editing.
|
|
206
|
-
|
|
207
|
-
4. **Compaction survival** — PreCompact hook fires before context compaction → saves checkpoint → agent recalls after compact. Memory survives.
|
|
208
|
-
|
|
209
|
-
5. **Symbolic short-term memory** (F1) — PostToolUse offloads verbose tool output to `refs/*.md` files and appends a node to a Mermaid canvas. PreToolUse injects the canvas (compact graph, ~100 tokens for 5 steps) so the agent reasons over symbols, not raw logs. Drill down via `ref_read(node_id)`. **92% token reduction** vs. raw tool logs. Enable with `REMEM_FLOW=full`.
|
|
210
|
-
|
|
211
|
-
6. **Skill auto-extraction** (F3) — Stop hook detects step-by-step task captures (numbered lists, bullet lists, "Step N:" patterns) and auto-creates a reusable Skill with trigger conditions, steps, and validation rules. Skills are injected into PreToolUse when trigger conditions match the current command. Archived skills are always injected. Enable with `REMEM_FLOW=full`.
|
|
212
|
-
|
|
213
|
-
### Memory Proxy — zero-code LLM integration (F2)
|
|
77
|
+
## CodeGraph
|
|
214
78
|
|
|
215
|
-
|
|
79
|
+
Structural code indexing via tree-sitter. The agent uses `codegraph_search` instead of grep to find symbols.
|
|
216
80
|
|
|
217
81
|
```bash
|
|
218
|
-
remem-mcp
|
|
82
|
+
npx remem-mcp index --path src # index a directory
|
|
83
|
+
npx remem-mcp search-code --query "parseTar" # find symbols
|
|
84
|
+
npx remem-mcp callers <id> # who calls this?
|
|
85
|
+
npx remem-mcp impact <id> # blast radius
|
|
219
86
|
```
|
|
220
87
|
|
|
221
|
-
|
|
88
|
+
9 languages: TS/JS/Python/Go/Rust/Java/C/C++/C#. 6-strategy call resolution (import-map → same-module → unique-name → suffix → fuzzy). Stdlib calls filtered out.
|
|
222
89
|
|
|
223
|
-
|
|
224
|
-
|
|
225
|
-
|
|
226
|
-
|
|
227
|
-
|
|
90
|
+
| Repo | Files | Symbols | Calls | Time |
|
|
91
|
+
|---|---|---|---|---|
|
|
92
|
+
| remem-mcp | 79 | 301 | 6,456 | 3s |
|
|
93
|
+
| AZR Go | 455 | 3,417 | 41,603 | 111s |
|
|
94
|
+
| Orca TS | 3,000 | 7,632 | 78,981 | 705s |
|
|
228
95
|
|
|
229
|
-
|
|
230
|
-
# Search symbols (auto-indexes src/ on first call)
|
|
231
|
-
npx remem-mcp search-code --query "parseTar"
|
|
232
|
-
# → parseTar at src/parse.ts:22
|
|
233
|
-
|
|
234
|
-
# List symbols in a file
|
|
235
|
-
npx remem-mcp list-code src/reporters/fancy.ts
|
|
236
|
-
# → Class L49-135 FancyReporter
|
|
237
|
-
# → Method L86-134 formatLogObj
|
|
238
|
-
|
|
239
|
-
# Trace callers / callees / impact (use symbol ID from search)
|
|
240
|
-
npx remem-mcp callers 01KZXPPHF93TS4HV8FWCSSK36A
|
|
241
|
-
npx remem-mcp impact 01KZXPPHF93TS4HV8FWCSSK36A
|
|
242
|
-
|
|
243
|
-
# Manual re-index (only needed after major changes)
|
|
244
|
-
npx remem-mcp index --path src --repo .
|
|
245
|
-
|
|
246
|
-
# Wiki + viewer
|
|
247
|
-
npx remem-mcp wiki ingest --path docs # Index markdown docs + ADRs
|
|
248
|
-
npx remem-mcp wiki outdated # Find outdated wiki pages
|
|
249
|
-
npx remem-mcp viewer # Web UI at localhost:7331
|
|
250
|
-
```
|
|
96
|
+
---
|
|
251
97
|
|
|
252
|
-
|
|
253
|
-
- **Wiki** — markdown docs, ADRs, outdated detection.
|
|
254
|
-
- **Search** — hybrid BM25 + sqlite-vec vector search with RRF fusion. `explain_recall` shows scores.
|
|
98
|
+
## Why it's different
|
|
255
99
|
|
|
256
|
-
|
|
100
|
+
| | remem-mcp | Mem0 | Claude MEMORY.md | Mneme |
|
|
101
|
+
|---|---|---|---|---|
|
|
102
|
+
| **Survives compaction** | Yes | Yes — cloud | No — 200-line cap | Yes |
|
|
103
|
+
| **Learns from errors** | Yes — auto | No | No | No |
|
|
104
|
+
| **Search** | Hybrid BM25 + vector + entities | Vector only | No | Vector + graph |
|
|
105
|
+
| **Memory links** | Hebbian co-retrieval | No | No | Graph |
|
|
106
|
+
| **Decay/forget** | Yes | No | No | No |
|
|
107
|
+
| **CodeGraph** | Yes — 6-strategy call resolution | No | No | No |
|
|
108
|
+
| **Token offload** | Yes — Mermaid canvas | No | No | No |
|
|
109
|
+
| **Setup** | 1 command | API key + cloud | Built-in | Build from source |
|
|
110
|
+
| **Cost** | Free | $19–249/mo | Free | Free |
|
|
257
111
|
|
|
258
112
|
---
|
|
259
113
|
|
|
260
|
-
##
|
|
114
|
+
## Useful commands
|
|
261
115
|
|
|
262
116
|
```bash
|
|
263
|
-
npx remem-mcp status #
|
|
264
|
-
npx remem-mcp viewer #
|
|
265
|
-
npx remem-mcp errors #
|
|
266
|
-
npx remem-mcp
|
|
267
|
-
npx remem-mcp
|
|
268
|
-
npx remem-mcp recent [N] # Recent captures
|
|
269
|
-
npx remem-mcp proxy # Start Memory Proxy (HTTP, :8765)
|
|
270
|
-
npx remem-mcp skill-extract # Batch extract skills from task captures
|
|
271
|
-
npx remem-mcp help all # Full list of 40+ subcommands
|
|
117
|
+
npx remem-mcp status # health + hooks + DB + CodeGraph
|
|
118
|
+
npx remem-mcp viewer # web UI at localhost:7331
|
|
119
|
+
npx remem-mcp errors # error dashboard
|
|
120
|
+
npx remem-mcp recent [N] # recent captures
|
|
121
|
+
npx remem-mcp help all # full list of 40+ subcommands
|
|
272
122
|
```
|
|
273
123
|
|
|
274
124
|
---
|
|
@@ -280,60 +130,32 @@ All settings have defaults. Config file is optional: `~/.config/remem-mcp/config
|
|
|
280
130
|
| Setting | Env var | Default |
|
|
281
131
|
|---|---|---|
|
|
282
132
|
| DB path | `REMEM_DB_PATH` | `~/.local/share/remem-mcp/memory.db` |
|
|
283
|
-
| **Unified flow** (F1+F3) | `REMEM_FLOW` | _(unset, set to `full`)_ |
|
|
284
|
-
| **Symbolic memory** (F1) | `REMEM_OFFLOAD_ENABLED` | `false` (set to `true`) |
|
|
285
|
-
| **Pipeline** (F1/F3) | `REMEM_PIPELINE` | `noop` (`mermaid`, `skill`, `llm-mermaid`) |
|
|
286
|
-
| **Proxy port** (F2) | `REMEM_PROXY_PORT` | `8765` |
|
|
287
|
-
| **Proxy upstream** (F2) | `REMEM_UPSTREAM_URL` | `https://api.openai.com` |
|
|
288
|
-
| **Proxy API key** (F2) | `REMEM_UPSTREAM_API_KEY` | _(from OPENAI_API_KEY)_ |
|
|
289
133
|
| Cross-project memory | `REMEM_GLOBAL_SESSION_KEY` | _(unset)_ |
|
|
290
|
-
|
|
|
291
|
-
| Auto-global classification | `auto_global=true` on capture | _(off)_ |
|
|
134
|
+
| Unified flow (F1+F2+F3) | `REMEM_FLOW` | _(unset, set to `full`)_ |
|
|
292
135
|
| Suppress hook feedback | `REMEM_QUIET` | _(unset, set to `1`)_ |
|
|
293
|
-
| Retro window (days) | `REMEM_RETRO_DAYS` | `7` |
|
|
294
|
-
| Core-only mode (disable advanced tools) | `REMEM_CORE_ONLY` | _(unset, set to `1`)_ |
|
|
295
|
-
| LLM API key (pipeline) | `REMEM_LLM_API_KEY` | _(unset)_ |
|
|
296
136
|
|
|
297
|
-
**
|
|
137
|
+
**Global memory policy** — set `REMEM_GLOBAL_SESSION_KEY` to *read* cross-project memory automatically. Captures stay project-local unless the user explicitly asks to save globally; then use `session_key: "global"`. Do not auto-classify ordinary captures into global.
|
|
298
138
|
|
|
299
|
-
|
|
139
|
+
**Team sharing** — `npx remem-mcp sync-export` writes `.remem-mcp/memory-export.jsonl`. Commit it to git. Team members get the same memory on `git pull`.
|
|
300
140
|
|
|
301
|
-
|
|
302
|
-
|
|
303
|
-
|
|
304
|
-
|
|
305
|
-
|
|
306
|
-
const memory = new Memory();
|
|
307
|
-
await memory.capture("We chose SQLite for storage.", "decision", ["arch"]);
|
|
308
|
-
const results = await memory.recall("storage decision");
|
|
141
|
+
**Per-repo capture exclusions** — Drop a `.remem.toml` in any project root:
|
|
142
|
+
```toml
|
|
143
|
+
[capture]
|
|
144
|
+
ignore_paths = ["node_modules", "dist", ".git", "*.min.js"]
|
|
309
145
|
```
|
|
310
146
|
|
|
311
147
|
---
|
|
312
148
|
|
|
313
149
|
## Benchmark
|
|
314
150
|
|
|
315
|
-
remem-mcp
|
|
316
|
-
|
|
317
|
-
|
|
318
|
-
|
|
319
|
-
|
|
|
320
|
-
|
|
321
|
-
| **AMB Layer 1** (basic recall) | **100** | — | — | — |
|
|
322
|
-
| **AMB Layer 2** (multi-session) | **100** | — | — | — |
|
|
323
|
-
| **AMB Layer 3** (scale + distractors) | **100** | — | — | — |
|
|
324
|
-
| **LoCoMo** (long conversation QA) | **95** | — | 92.5 | — |
|
|
325
|
-
| **PersonaMem** (personalization) | **100** | 76 | — | 48 |
|
|
326
|
-
| **LongMemEval** (long-term memory, ICR 2025) | **96** | — | 94.4 | — |
|
|
327
|
-
|
|
328
|
-
- **PersonaMem** — [bowen-upenn/PersonaMem](https://github.com/bowen-upenn/PersonaMem) (588 questions, 20 personas, multiple-choice QA). TencentDB reports 76% with memory enabled, 48% without. remem-mcp scores **100%** using a search-recall proxy (no LLM API key needed).
|
|
329
|
-
- **LoCoMo** — long conversation multi-hop QA (19 sessions, 400+ turns). Mem0 reports 92.5%. remem-mcp scores **95%** with keyword + semantic-similarity scoring.
|
|
330
|
-
- **AMB** — Agent Memory Benchmark (L1: 56 recall tests, L2: 5 multi-session scenarios, L3: 1K+ memories with distractors). remem-mcp scores **100/100/100** using the official AMB CLI.
|
|
331
|
-
- **LongMemEval** — [xiaowu0162/LongMemEval](https://github.com/xiaowu0162/LongMemEval) (ICLR 2025, 500 questions, 5 memory abilities: temporal reasoning, multi-session, knowledge update, single-session recall, abstention). Mem0 reports 94.4%. remem-mcp scores **96%** on the oracle variant.
|
|
332
|
-
|
|
333
|
-
Run the benchmarks:
|
|
151
|
+
| Benchmark | remem-mcp | Mem0 | Without memory |
|
|
152
|
+
|---|---|---|---|
|
|
153
|
+
| **AMB** (L1/L2/L3) | **100/100/100** | — | — |
|
|
154
|
+
| **LoCoMo** (long conversation QA) | **95** | 92.5 | — |
|
|
155
|
+
| **PersonaMem** (personalization) | **100** | — | 48 |
|
|
156
|
+
| **LongMemEval** (ICLR 2025) | **96** | 94.4 | — |
|
|
334
157
|
|
|
335
158
|
```bash
|
|
336
|
-
bash scripts/bench-all.sh # Full: AMB + LoCoMo + PersonaMem (~5 min)
|
|
337
159
|
bash scripts/bench-all.sh --quick # AMB only (~2 min)
|
|
338
160
|
```
|
|
339
161
|
|
|
@@ -341,11 +163,11 @@ bash scripts/bench-all.sh --quick # AMB only (~2 min)
|
|
|
341
163
|
|
|
342
164
|
## Architecture
|
|
343
165
|
|
|
344
|
-
See [ARCHITECTURE.md](./ARCHITECTURE.md) for full system diagrams, schema, and performance
|
|
166
|
+
See [ARCHITECTURE.md](./ARCHITECTURE.md) for full system diagrams, schema, and performance details.
|
|
345
167
|
|
|
346
168
|
## Credits
|
|
347
169
|
|
|
348
|
-
Core based on [TencentDB Agent Memory](https://github.com/TencentCloud/TencentDB-Agent-Memory) (MIT, Tencent 2026).
|
|
170
|
+
Core based on [TencentDB Agent Memory](https://github.com/TencentCloud/TencentDB-Agent-Memory) (MIT, Tencent 2026). CodeGraph call resolution adapted from Codebase-Memory (arXiv:2603.27277). Recall boost adapted from [ai-memory](https://github.com/akitaonrails/ai-memory) by Akita On Rails. Contextual retrieval from [Anthropic](https://www.anthropic.com/news/contextual-retrieval) (2024).
|
|
349
171
|
|
|
350
172
|
## License
|
|
351
173
|
|
|
@@ -1,12 +1,12 @@
|
|
|
1
1
|
import {
|
|
2
2
|
init_engine
|
|
3
|
-
} from "./chunk-
|
|
3
|
+
} from "./chunk-MPEN2X43.js";
|
|
4
4
|
import {
|
|
5
5
|
LocalEmbedder,
|
|
6
6
|
SQLiteBackend,
|
|
7
7
|
init_local,
|
|
8
8
|
stripQueryProperNouns
|
|
9
|
-
} from "./chunk-
|
|
9
|
+
} from "./chunk-L7YZBBIB.js";
|
|
10
10
|
import {
|
|
11
11
|
generateId,
|
|
12
12
|
init_ulid
|
|
@@ -473,11 +473,13 @@ var Memory = class {
|
|
|
473
473
|
type,
|
|
474
474
|
content: redactedContent,
|
|
475
475
|
tags,
|
|
476
|
-
createdAt: Date.now()
|
|
476
|
+
createdAt: Date.now(),
|
|
477
|
+
metadata: opts?.metadata
|
|
477
478
|
};
|
|
478
479
|
await this.storage.put(entry);
|
|
479
480
|
try {
|
|
480
|
-
const
|
|
481
|
+
const contextualContent = this.buildContextualPreamble(type, tags) + redactedContent;
|
|
482
|
+
const embedding = await this.embedder.embed(contextualContent);
|
|
481
483
|
await this.storage.putVector(id, embedding);
|
|
482
484
|
} catch {
|
|
483
485
|
}
|
|
@@ -530,6 +532,7 @@ var Memory = class {
|
|
|
530
532
|
const limit = Math.min(opts?.limit ?? 20, 100);
|
|
531
533
|
const mode = opts?.mode ?? "hybrid";
|
|
532
534
|
const sessionKey = opts?.sessionKey ?? this.sessionKey;
|
|
535
|
+
const explain = opts?.explain ?? false;
|
|
533
536
|
let queryEmbedding = null;
|
|
534
537
|
if (mode === "hybrid" || mode === "vector") {
|
|
535
538
|
const stripped = stripQueryProperNouns(query);
|
|
@@ -543,7 +546,8 @@ var Memory = class {
|
|
|
543
546
|
limit: projectLimit,
|
|
544
547
|
offset: 0,
|
|
545
548
|
mode,
|
|
546
|
-
filters: opts?.filters
|
|
549
|
+
filters: opts?.filters,
|
|
550
|
+
explain
|
|
547
551
|
});
|
|
548
552
|
let globalResults = [];
|
|
549
553
|
try {
|
|
@@ -552,7 +556,8 @@ var Memory = class {
|
|
|
552
556
|
limit: reservedGlobal,
|
|
553
557
|
offset: 0,
|
|
554
558
|
mode,
|
|
555
|
-
filters: opts?.filters
|
|
559
|
+
filters: opts?.filters,
|
|
560
|
+
explain
|
|
556
561
|
});
|
|
557
562
|
} catch {
|
|
558
563
|
}
|
|
@@ -567,17 +572,53 @@ var Memory = class {
|
|
|
567
572
|
limit,
|
|
568
573
|
offset: 0,
|
|
569
574
|
mode,
|
|
570
|
-
filters: opts?.filters
|
|
575
|
+
filters: opts?.filters,
|
|
576
|
+
explain
|
|
571
577
|
});
|
|
572
578
|
}
|
|
573
579
|
/** Compute the embedding vector for a piece of text using the configured embedder. */
|
|
574
580
|
async embed(text) {
|
|
575
581
|
return this.embedder.embed(text);
|
|
576
582
|
}
|
|
583
|
+
/**
|
|
584
|
+
* v13: Build a contextual preamble for embedding (Anthropic contextual retrieval technique).
|
|
585
|
+
* Prepends type + tags to give the vector model more context about what the capture is.
|
|
586
|
+
* The raw content stays pristine for FTS5 lexical search.
|
|
587
|
+
*/
|
|
588
|
+
buildContextualPreamble(type, tags) {
|
|
589
|
+
const parts = [];
|
|
590
|
+
if (type && type !== "conversation") {
|
|
591
|
+
parts.push(`[${type}]`);
|
|
592
|
+
}
|
|
593
|
+
if (tags && tags.length > 0) {
|
|
594
|
+
parts.push(`tags: ${tags.join(", ")}`);
|
|
595
|
+
}
|
|
596
|
+
return parts.length > 0 ? parts.join(" ") + ". " : "";
|
|
597
|
+
}
|
|
577
598
|
/** Delete a capture by ID. */
|
|
578
599
|
async forget(id) {
|
|
579
600
|
return this.storage.delete(id);
|
|
580
601
|
}
|
|
602
|
+
/** Get a capture by ID. Returns null if not found or deleted. */
|
|
603
|
+
async get(id) {
|
|
604
|
+
return this.storage.get(id);
|
|
605
|
+
}
|
|
606
|
+
/** Run forget sweep to evict low-salience and TTL-expired captures. */
|
|
607
|
+
async forgetSweep(opts) {
|
|
608
|
+
return this.storage.forgetSweep(opts ?? {});
|
|
609
|
+
}
|
|
610
|
+
/** Record feedback for a capture (v12). Adjusts salience multiplier. */
|
|
611
|
+
async feedback(captureId, signal, reason) {
|
|
612
|
+
this.storage.recordFeedback(captureId, signal, reason, "sdk");
|
|
613
|
+
}
|
|
614
|
+
/** Get feedback signals for a capture (v12). */
|
|
615
|
+
async getFeedback(captureId) {
|
|
616
|
+
return this.storage.getFeedback(captureId);
|
|
617
|
+
}
|
|
618
|
+
/** Query mutation log (v12). */
|
|
619
|
+
async queryAudit(opts) {
|
|
620
|
+
return this.storage.queryAudit(opts);
|
|
621
|
+
}
|
|
581
622
|
/** Update an existing capture's content, tags, type, or trust state. */
|
|
582
623
|
async update(id, opts) {
|
|
583
624
|
const existing = await this.storage.get(id);
|
|
@@ -816,4 +857,4 @@ export {
|
|
|
816
857
|
classifyGlobalContent,
|
|
817
858
|
Memory
|
|
818
859
|
};
|
|
819
|
-
//# sourceMappingURL=chunk-
|
|
860
|
+
//# sourceMappingURL=chunk-2RKMX6EE.js.map
|