playwright-e2e-mcp 0.1.4 → 0.2.0
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.md +208 -54
- package/dist/http.d.ts +1 -1
- package/dist/http.js +1 -1
- package/dist/prompts.d.ts +6 -0
- package/dist/prompts.js +39 -0
- package/dist/prompts.js.map +1 -0
- package/dist/server.d.ts +4 -3
- package/dist/server.js +63 -5
- package/dist/server.js.map +1 -1
- package/dist/tools/analyze-history.d.ts +48 -0
- package/dist/tools/analyze-history.js +132 -0
- package/dist/tools/analyze-history.js.map +1 -0
- package/dist/tools/compare-visual-state.d.ts +89 -17
- package/dist/tools/compare-visual-state.js +10 -3
- package/dist/tools/compare-visual-state.js.map +1 -1
- package/dist/tools/diagnose-flaky.js +5 -2
- package/dist/tools/diagnose-flaky.js.map +1 -1
- package/dist/tools/generate-e2e-test.d.ts +11 -0
- package/dist/tools/generate-e2e-test.js +50 -3
- package/dist/tools/generate-e2e-test.js.map +1 -1
- package/dist/tools/get-failure.d.ts +6 -1
- package/dist/tools/get-failure.js +17 -11
- package/dist/tools/get-failure.js.map +1 -1
- package/dist/tools/get-run-status.d.ts +28 -0
- package/dist/tools/get-run-status.js +75 -0
- package/dist/tools/get-run-status.js.map +1 -0
- package/dist/tools/inspect-page.d.ts +102 -14
- package/dist/tools/inspect-page.js +50 -10
- package/dist/tools/inspect-page.js.map +1 -1
- package/dist/tools/probe-script.d.ts +20 -0
- package/dist/tools/probe-script.js +641 -0
- package/dist/tools/probe-script.js.map +1 -0
- package/dist/tools/run-test.d.ts +5 -1
- package/dist/tools/run-test.js +30 -3
- package/dist/tools/run-test.js.map +1 -1
- package/dist/tools/shared.d.ts +117 -3
- package/dist/tools/shared.js +154 -285
- package/dist/tools/shared.js.map +1 -1
- package/dist/tools/suggest-fix.d.ts +89 -0
- package/dist/tools/suggest-fix.js +437 -0
- package/dist/tools/suggest-fix.js.map +1 -0
- package/dist/tools/validate-selector.d.ts +83 -6
- package/dist/tools/validate-selector.js +71 -32
- package/dist/tools/validate-selector.js.map +1 -1
- package/dist/types/index.d.ts +40 -0
- package/dist/utils/locator-expr.d.ts +38 -0
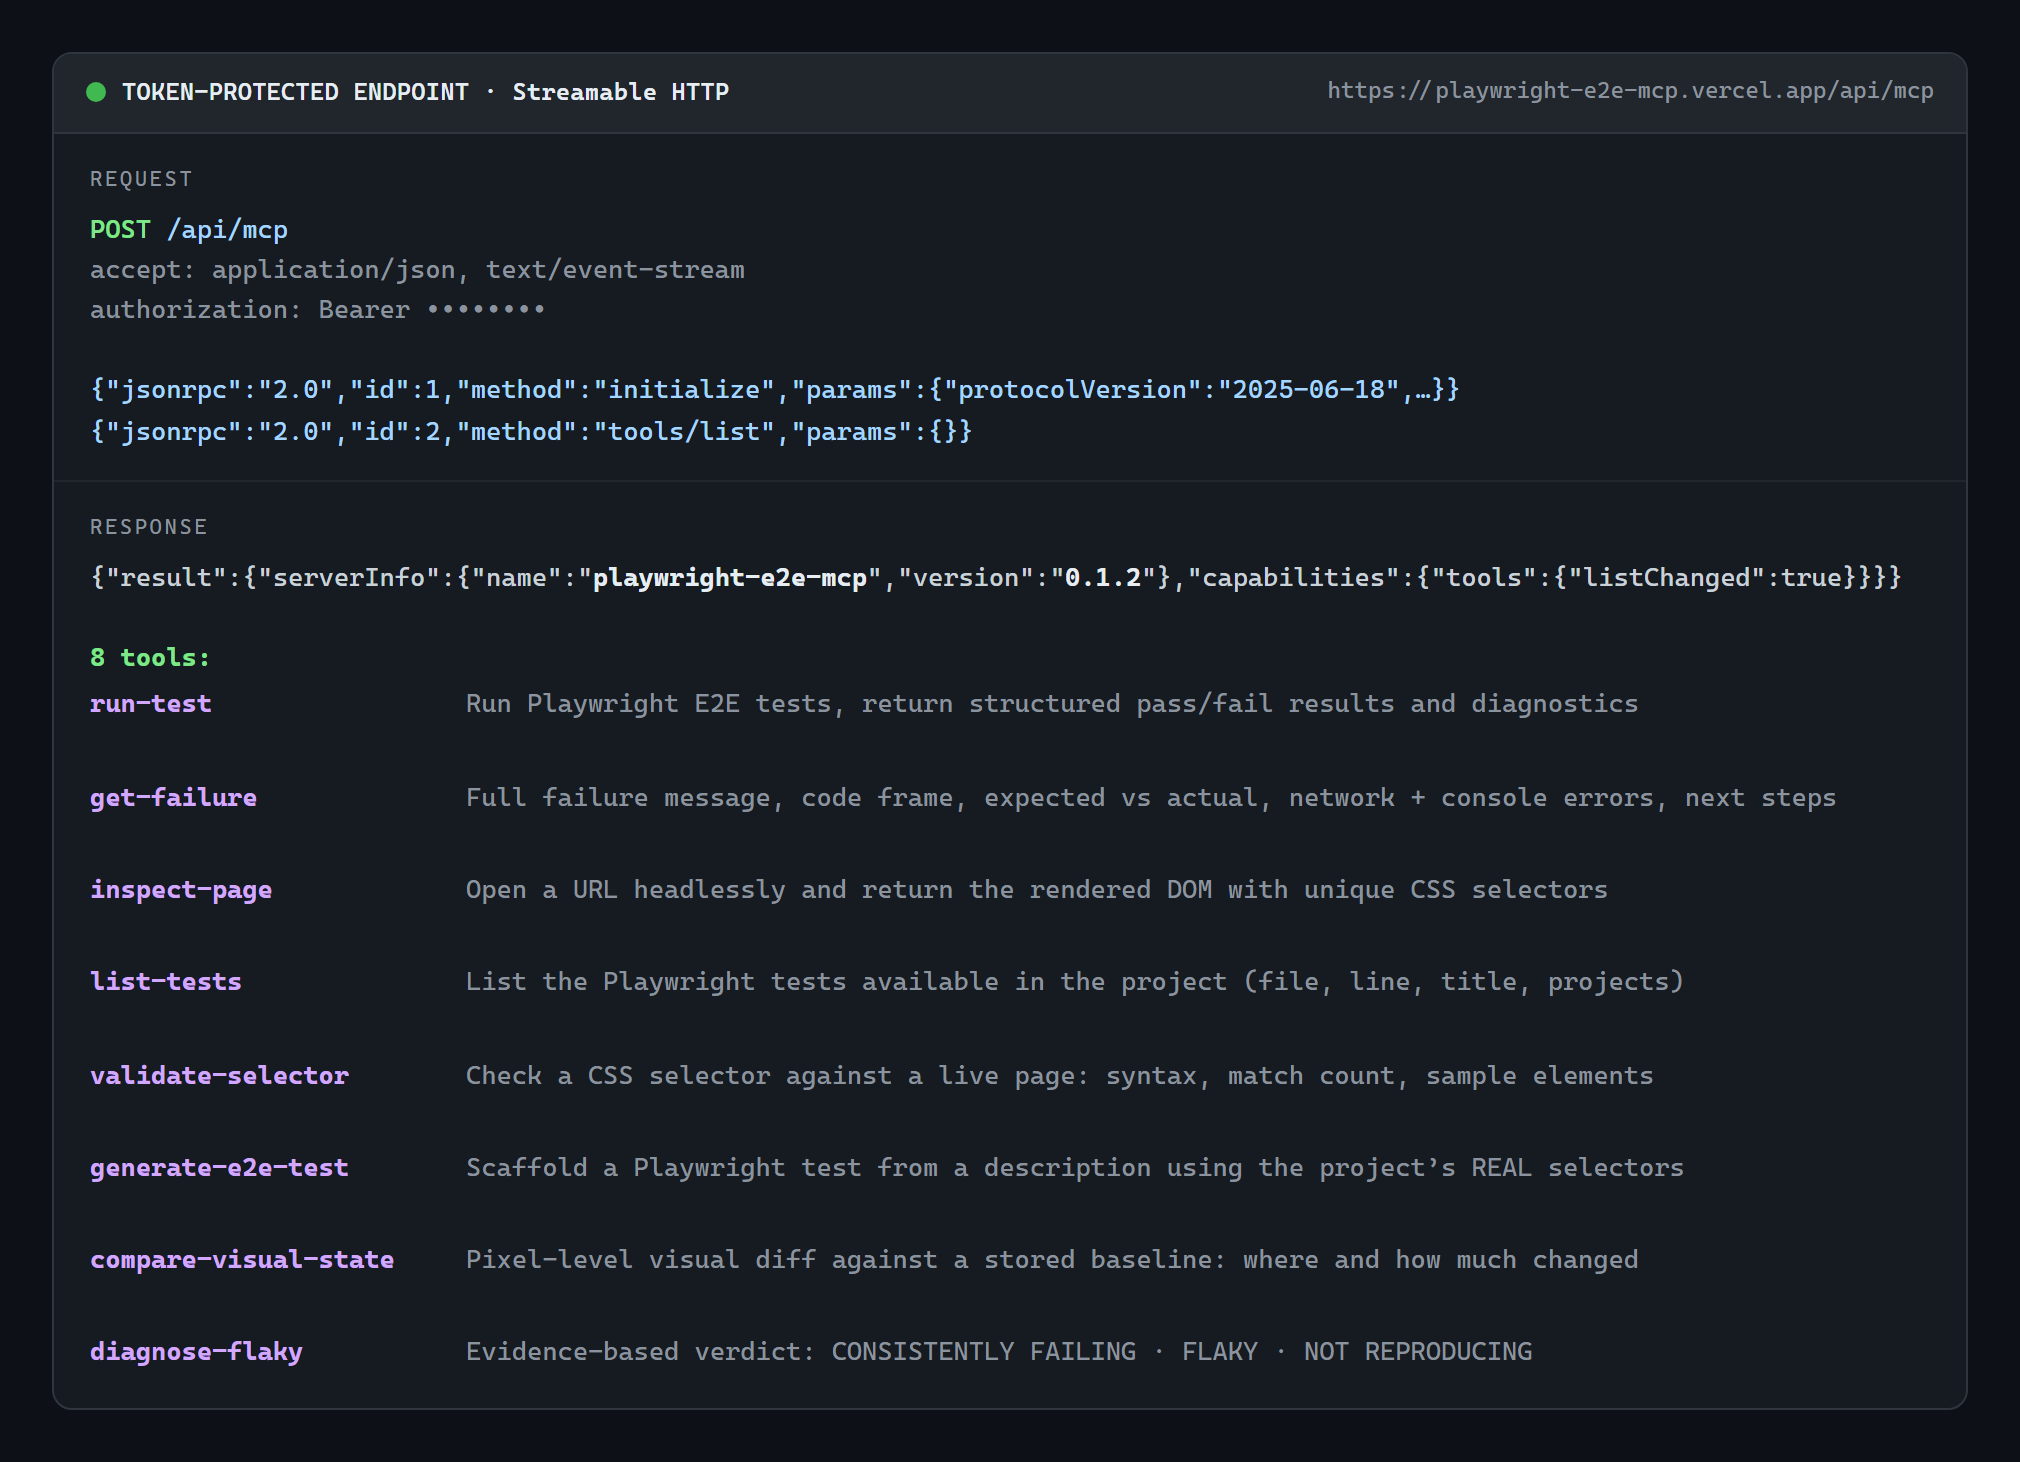
- package/dist/utils/locator-expr.js +280 -0
- package/dist/utils/locator-expr.js.map +1 -0
- package/dist/utils/playwright-runner.d.ts +9 -1
- package/dist/utils/playwright-runner.js +60 -4
- package/dist/utils/playwright-runner.js.map +1 -1
- package/dist/utils/report-parser.d.ts +3 -1
- package/dist/utils/report-parser.js +22 -0
- package/dist/utils/report-parser.js.map +1 -1
- package/dist/utils/run-history.d.ts +103 -0
- package/dist/utils/run-history.js +219 -0
- package/dist/utils/run-history.js.map +1 -0
- package/dist/utils/run-registry.d.ts +34 -0
- package/dist/utils/run-registry.js +86 -0
- package/dist/utils/run-registry.js.map +1 -0
- package/dist/utils/trace-reader.d.ts +23 -2
- package/dist/utils/trace-reader.js +86 -15
- package/dist/utils/trace-reader.js.map +1 -1
- package/package.json +2 -2
package/README.md
CHANGED
|
@@ -1,21 +1,46 @@
|
|
|
1
1
|
# playwright-e2e-mcp
|
|
2
2
|
|
|
3
3
|
[](https://github.com/trajectiq-ai/E2E/actions/workflows/ci.yml) [](https://github.com/trajectiq-ai/E2E/releases) [](https://registry.modelcontextprotocol.io/)
|
|
4
|
+
[](https://m8ven.ai/mcp/trajectiq-ai/e2e?s=readme)
|
|
4
5
|
|
|
5
|
-
An [MCP](https://modelcontextprotocol.io) server that
|
|
6
|
+
An [MCP](https://modelcontextprotocol.io) server that **diagnoses and fixes failing Playwright
|
|
7
|
+
tests**. It is the layer that sits next to a browser-driving MCP: Playwright MCP gives an agent
|
|
8
|
+
hands in the browser; this server gives it a test runner, a failure analyst and a verified fixer.
|
|
6
9
|
|
|
7
10
|
```
|
|
8
|
-
run-test ──▶ get-failure ──▶
|
|
9
|
-
|
|
10
|
-
|
|
11
|
+
run-test ──▶ get-failure ──▶ suggest-fix (apply + re-run) ──▶ green
|
|
12
|
+
│ │ └─ refuses when the element is really gone (app bug)
|
|
13
|
+
│ └─ DOM at failure, failed requests, console errors
|
|
14
|
+
└─ background runs, progress ──▶ analyze-history (flaky / broken / regressed)
|
|
11
15
|
```
|
|
12
16
|
|
|
13
|
-
|
|
14
|
-
|
|
15
|
-
|
|
16
|
-
|
|
17
|
-
|
|
18
|
-
|
|
17
|
+
What it does that a browser-driving MCP or a raw `npx playwright test` does not:
|
|
18
|
+
|
|
19
|
+
- **Structured runs.** Stats plus each failure's `file:line`, kind (assertion, timeout,
|
|
20
|
+
dead dev server, syntax error, crash, full disk…) and a concrete fix hint. Long suites run
|
|
21
|
+
in the background with live progress.
|
|
22
|
+
- **Diagnosis from the trace.** The DOM at the moment of failure, the failed action, the
|
|
23
|
+
4xx/5xx requests and console errors, read from Playwright's own trace.
|
|
24
|
+
- **Fixes that are proven, not guessed.** `suggest-fix` matches a broken locator against the
|
|
25
|
+
DOM at failure, swaps in a Playwright locator proven unique on the page
|
|
26
|
+
(`getByRole('button', { name: 'Proceed to checkout' })`), re-runs the test and reverts the
|
|
27
|
+
edit if it is still red. When nothing on the page plausibly matches, it says the element is
|
|
28
|
+
missing and does not patch the test to hide a real bug.
|
|
29
|
+
- **Flakiness across runs.** Every run is recorded locally; `analyze-history` separates
|
|
30
|
+
tests that flip (flaky) from ones that started failing (regressed) or always fail (broken),
|
|
31
|
+
and groups failures that share one cause.
|
|
32
|
+
- **Pages behind a login.** Every page tool accepts a Playwright `storageState`, extra
|
|
33
|
+
headers, and click/fill steps to reach a modal or a later step.
|
|
34
|
+
- **Small on the wire.** In the [benchmark](bench/RESULTS.md), diagnosing and fixing one
|
|
35
|
+
drifted locator cost about 5,300 tokens here against about 7,400 with Playwright MCP plus a
|
|
36
|
+
shell, and the fix was applied and verified without the agent editing anything.
|
|
37
|
+
|
|
38
|
+
### What it does not do
|
|
39
|
+
|
|
40
|
+
It does not drive an exploratory browsing session step by step, and it does not replace
|
|
41
|
+
Playwright's own Test Agents (planner, generator, healer) inside VS Code. Use Playwright MCP
|
|
42
|
+
for interactive browsing and this server for running, diagnosing and fixing the suite; they
|
|
43
|
+
work side by side in the same client.
|
|
19
44
|
|
|
20
45
|
## Demo
|
|
21
46
|
|
|
@@ -23,7 +48,7 @@ with unique CSS selectors, and validate the replacement selector before re-runni
|
|
|
23
48
|
`https://playwright-e2e-mcp.vercel.app/api/mcp` returns for a client that sends the
|
|
24
49
|
bearer token (without one, only `list-tests` and `get-failure` are listed):
|
|
25
50
|
|
|
26
|
-
|
|
27
52
|
|
|
28
53
|
**A real test run** — `run-test` served over stdio by `npx -y playwright-e2e-mcp`
|
|
29
54
|
against the bundled `examples/sample-test.spec.ts` (actual output, unedited):
|
|
@@ -42,10 +67,17 @@ and every other MCP client — pick whichever route fits:
|
|
|
42
67
|
| --- | --- |
|
|
43
68
|
| **npm (canonical, fastest)** | `npx -y playwright-e2e-mcp` |
|
|
44
69
|
| **MCP Registry** (registry-aware clients discover it automatically) | `io.github.trajectiq-ai/E2E` — [listing](https://registry.modelcontextprotocol.io/) |
|
|
45
|
-
| **Any client, no npm account needed** | `npx -y github:trajectiq-ai/E2E#v0.
|
|
70
|
+
| **Any client, no npm account needed** | `npx -y github:trajectiq-ai/E2E#v0.2.0` (pin a release tag) |
|
|
46
71
|
| **Claude Desktop, zero Node setup** | double-click the [`.mcpb` extension](https://github.com/trajectiq-ai/E2E/releases) |
|
|
47
72
|
| **Remote-only clients (ChatGPT connectors)** | `https://playwright-e2e-mcp.vercel.app/api/mcp` |
|
|
48
73
|
|
|
74
|
+
One line for the common clients:
|
|
75
|
+
|
|
76
|
+
```bash
|
|
77
|
+
claude mcp add playwright-e2e -- npx -y playwright-e2e-mcp
|
|
78
|
+
code --add-mcp '{"name":"playwright-e2e","command":"npx","args":["-y","playwright-e2e-mcp"]}'
|
|
79
|
+
```
|
|
80
|
+
|
|
49
81
|
Details and per-client config: [Installation](#installation) ·
|
|
50
82
|
[MCP client configuration](#mcp-client-configuration).
|
|
51
83
|
|
|
@@ -55,14 +87,35 @@ Details and per-client config: [Installation](#installation) ·
|
|
|
55
87
|
|
|
56
88
|
| Tool | Purpose |
|
|
57
89
|
| --- | --- |
|
|
58
|
-
| `run-test` | Run Playwright tests and return stats, failures, diagnostics and hints |
|
|
59
|
-
| `get-
|
|
60
|
-
| `
|
|
90
|
+
| `run-test` | Run Playwright tests and return stats, failures, diagnostics and hints; reports progress, and `background: true` returns a run id for long suites |
|
|
91
|
+
| `get-run-status` | Progress or final result of a background run; can wait for it or cancel it |
|
|
92
|
+
| `get-failure` | Deep analysis of one failure: stack, expected/actual, **DOM snapshot at failure (from the Playwright trace)**, failed requests, console errors, next steps |
|
|
93
|
+
| `suggest-fix` | Patch a failure: a drifted locator is replaced with one **proven unique** on the DOM at failure, changed copy gets the new expected text; `apply: true` writes it, re-runs the test and reverts if still red |
|
|
94
|
+
| `inspect-page` | Open a URL headlessly (optionally signed in, after steps) and return elements with **verified Playwright locators**, CSS selectors, visibility, text and console output |
|
|
61
95
|
| `list-tests` | List available tests (`file`, `line`, full title, projects) with filtering |
|
|
62
|
-
| `validate-selector` | Check a CSS selector against a live page: validity, match count,
|
|
63
|
-
| `generate-e2e-test` | Scaffold a Playwright test from a description using the project's **real** selectors
|
|
96
|
+
| `validate-selector` | Check a CSS selector, Playwright selector or **locator expression** against a live page: validity, match count, and a sturdier verified locator for each match |
|
|
97
|
+
| `generate-e2e-test` | Scaffold a Playwright test from a description using the project's **real** selectors and verified locators from the live page |
|
|
64
98
|
| `compare-visual-state` | Visual regression: screenshot before/after a change and report *what* moved and how colors shifted |
|
|
65
99
|
| `diagnose-flaky` | Run a failing test 2–10 times **with retries disabled** and return an evidence verdict: `CONSISTENTLY FAILING`, `FLAKY` or `NOT REPRODUCING` |
|
|
100
|
+
| `analyze-history` | Rank flaky, regressed and broken tests from the local run history, group failures by cause, or show one test's timeline |
|
|
101
|
+
|
|
102
|
+
Two **prompts** package the main workflows for clients that show them as slash commands:
|
|
103
|
+
`fix-failing-test` (optional `test`) and `triage-flaky-tests`.
|
|
104
|
+
|
|
105
|
+
### Page state: signed-in pages, headers and steps
|
|
106
|
+
|
|
107
|
+
`inspect-page`, `validate-selector` and `compare-visual-state` accept the same page-state
|
|
108
|
+
arguments (`suggest-fix` accepts `storageState` and `headers` for a live `url`):
|
|
109
|
+
|
|
110
|
+
| Argument | Type | Description |
|
|
111
|
+
| --- | --- | --- |
|
|
112
|
+
| `storageState` | string | Path inside the project to a Playwright storageState JSON (cookies + localStorage), e.g. `playwright/.auth/user.json` from your setup project. Defaults to `PW_MCP_STORAGE_STATE` |
|
|
113
|
+
| `headers` | object | Extra HTTP headers for every request, e.g. `{ "Authorization": "Bearer …" }` |
|
|
114
|
+
| `actions` | array | Up to 20 steps run after load: `{ "type": "click" \| "dblclick" \| "hover" \| "fill" \| "press" \| "check" \| "uncheck" \| "select" \| "wait" \| "goto", "locator"?, "value"?, "url"?, "ms"? }`. Locators use Playwright syntax, e.g. `getByRole('button', { name: 'Open settings' })` |
|
|
115
|
+
| `viewport` | object | `{ "width": 390, "height": 844 }` (default 1280×720) |
|
|
116
|
+
|
|
117
|
+
A failing step reports which one failed and how many ran. When the page lands on a login
|
|
118
|
+
screen, the response says so and suggests `storageState`.
|
|
66
119
|
|
|
67
120
|
### `run-test`
|
|
68
121
|
|
|
@@ -80,6 +133,11 @@ Details and per-client config: [Installation](#installation) ·
|
|
|
80
133
|
| `retryOnFailure` | boolean | Auto-retry failures **once** before reporting them (default `true`; ignored when `retries` is set) |
|
|
81
134
|
| `lastFailed` | boolean | Only re-run tests that failed in the previous run (Playwright `--last-failed`) — the fast fix → re-run loop |
|
|
82
135
|
| `args` | string[] | Extra Playwright flags from an allowlist (`--repeat-each=N`, `--max-failures=N`, `--update-snapshots`, `--shard=1/3`, `--trace=on`, …); values go after `=` and are checked, and flags that take a path, such as `--config` or `--output`, are rejected |
|
|
136
|
+
| `background` | boolean | Return a run id at once; poll `get-run-status` for progress and the result |
|
|
137
|
+
|
|
138
|
+
Progress: clients that send a progress token get a notification as each test finishes
|
|
139
|
+
(`3/12 tests done, 1 failed`). Every run is appended to the local history used by
|
|
140
|
+
`analyze-history`.
|
|
83
141
|
|
|
84
142
|
Flakiness handling: by default the server injects `--retries=1` (unless the config
|
|
85
143
|
already sets `retries`), so a test that passes on the retry is reported as **flaky**,
|
|
@@ -130,16 +188,25 @@ numbered next steps (re-run this single test by `file:line`, headed/debug mode,
|
|
|
130
188
|
| Argument | Type | Description |
|
|
131
189
|
| --- | --- | --- |
|
|
132
190
|
| `url` | string | Full http(s) URL to open (required) |
|
|
191
|
+
| `view` | `elements` \| `locators` | `locators` returns a compact map of interactive elements with verified locators (cheapest); `elements` (default) the DOM inventory |
|
|
133
192
|
| `projectRoot` | string | Project whose Playwright launches the browser |
|
|
134
|
-
| `selector` | string | Inspect matches of this
|
|
193
|
+
| `selector` | string | Inspect matches of this selector instead of the whole DOM |
|
|
135
194
|
| `waitFor` | string | Wait for a selector (CSS or `text=…`) before inspecting |
|
|
136
195
|
| `waitUntil` | `load` \| `domcontentloaded` \| `networkidle` | Navigation wait condition |
|
|
137
196
|
| `includeHtml` | boolean | Include the rendered HTML (capped) |
|
|
138
197
|
| `maxHtmlChars` | number | HTML cap, default `20000` |
|
|
139
198
|
| `timeoutMs` | number | Overall limit, default `45000` |
|
|
199
|
+
| `storageState` / `headers` / `actions` / `viewport` | — | [Page state](#page-state-signed-in-pages-headers-and-steps) |
|
|
140
200
|
|
|
141
|
-
|
|
142
|
-
|
|
201
|
+
Each element comes with Playwright locators that were **checked on the page** to resolve to
|
|
202
|
+
exactly that element, best first (role + accessible name, test id, label, placeholder, text,
|
|
203
|
+
then CSS), plus its unique CSS selector, visibility, box and text. Console messages are
|
|
204
|
+
captured, errors first. A locator map looks like:
|
|
205
|
+
|
|
206
|
+
```markdown
|
|
207
|
+
1. `getByRole('button', { name: 'Proceed to checkout' })` — button "Proceed to checkout" · also `getByTestId('checkout-btn')`
|
|
208
|
+
2. `getByLabel('Search')` — searchbox "Search"
|
|
209
|
+
```
|
|
143
210
|
|
|
144
211
|
### `list-tests`
|
|
145
212
|
|
|
@@ -159,14 +226,19 @@ Uses `playwright test --list` when Playwright works, and **falls back to a sourc
|
|
|
159
226
|
| Argument | Type | Description |
|
|
160
227
|
| --- | --- | --- |
|
|
161
228
|
| `url` | string | Live page to test against (required) |
|
|
162
|
-
| `selector` | string | CSS selector
|
|
229
|
+
| `selector` | string | CSS, a Playwright selector (`text=`, `role=`, `>>`) or a locator expression such as `getByRole('button', { name: 'Save' }).first()` (required) |
|
|
163
230
|
| `projectRoot` | string | Project whose Playwright launches the browser |
|
|
164
231
|
| `timeoutMs` | number | Overall limit, default `45000` |
|
|
232
|
+
| `storageState` / `headers` / `actions` / `viewport` | — | [Page state](#page-state-signed-in-pages-headers-and-steps) |
|
|
165
233
|
|
|
166
|
-
|
|
167
|
-
|
|
168
|
-
|
|
169
|
-
|
|
234
|
+
Locator expressions are parsed into a whitelisted call chain (`getByRole`, `getByText`,
|
|
235
|
+
`getByLabel`, `getByPlaceholder`, `getByAltText`, `getByTitle`, `getByTestId`, `locator`,
|
|
236
|
+
`first`, `last`, `nth`, `filter`) and are never evaluated as code.
|
|
237
|
+
|
|
238
|
+
Verdicts: `✅ VALID — N matches` with a sample of matches and a **unique locator** for each,
|
|
239
|
+
a strict-mode warning when more than one element matches, a hint when a CSS selector is
|
|
240
|
+
brittle (`:nth-child`, long descendant chains, XPath), `✅ VALID — 0 matches` with debugging
|
|
241
|
+
advice, or `❌ INVALID` with the parse error.
|
|
170
242
|
|
|
171
243
|
### `generate-e2e-test`
|
|
172
244
|
|
|
@@ -184,7 +256,8 @@ Reads the agent's recent changes (`git status`, falling back to `git diff HEAD~1
|
|
|
184
256
|
then recent mtimes), extracts the locators those files actually declare
|
|
185
257
|
(`data-testid`, `getByRole`, `aria-label`, `placeholder`, `id`, `name`, element text),
|
|
186
258
|
ranks verified-live selectors first, writes a spec built from them, and reports each
|
|
187
|
-
selector with its source `file:line`.
|
|
259
|
+
selector with its source `file:line`. When the source has no usable selectors, it uses the
|
|
260
|
+
verified locators from the live page that best match the description.
|
|
188
261
|
|
|
189
262
|
### `compare-visual-state`
|
|
190
263
|
|
|
@@ -198,6 +271,7 @@ selector with its source `file:line`.
|
|
|
198
271
|
| `tolerance` | number | Percent of pixels that may differ (default `0.1`) |
|
|
199
272
|
| `pixelThreshold` | number | Per-pixel channel delta considered different (default `60`) |
|
|
200
273
|
| `waitUntil` / `waitFor` / `timeoutMs` | — | As with `inspect-page` |
|
|
274
|
+
| `storageState` / `headers` / `actions` / `viewport` | — | [Page state](#page-state-signed-in-pages-headers-and-steps) |
|
|
201
275
|
|
|
202
276
|
The first call saves a baseline under `.pw-mcp/visual/` (add that to `.gitignore`, or
|
|
203
277
|
commit it for CI comparisons). Later calls report changed-pixel counts, **merged
|
|
@@ -227,6 +301,60 @@ failure), the count of **distinct normalized error signatures**, and one of:
|
|
|
227
301
|
|
|
228
302
|
The last run is stored, so `get-failure` can analyze it immediately afterwards.
|
|
229
303
|
|
|
304
|
+
### `suggest-fix`
|
|
305
|
+
|
|
306
|
+
| Argument | Type | Description |
|
|
307
|
+
| --- | --- | --- |
|
|
308
|
+
| `index` | number | 1-based failure index from the last run (default `1`) |
|
|
309
|
+
| `apply` | boolean | Write the fix into the spec (default `false`: return the diff only) |
|
|
310
|
+
| `verify` | boolean | After applying, re-run the test and revert the file if it still fails (default `true`) |
|
|
311
|
+
| `allowExpectationUpdate` | boolean | Allow applying a changed expected text/value (default `false`, since it can hide a real regression) |
|
|
312
|
+
| `url` | string | Heal against this live page instead of the DOM snapshot in the failure trace |
|
|
313
|
+
| `storageState` / `headers` | — | For `url`, as in [Page state](#page-state-signed-in-pages-headers-and-steps) |
|
|
314
|
+
| `config` / `timeoutMs` / `projectRoot` | — | As with `run-test` |
|
|
315
|
+
|
|
316
|
+
Two kinds of fix:
|
|
317
|
+
|
|
318
|
+
- **Locator drift.** The broken locator is read from the error, its words are matched
|
|
319
|
+
(with synonyms such as *btn → button*, *checkout → proceed to checkout*) against every
|
|
320
|
+
element in the DOM at failure, and the best match's verified-unique locator replaces it.
|
|
321
|
+
Confidence is `high` when the match is clear, `medium` otherwise.
|
|
322
|
+
- **Changed copy.** For `toHaveText`, `toContainText`, `toHaveValue`, `toHaveTitle`,
|
|
323
|
+
`toHaveURL` and `toHaveAttribute`, it proposes the value the page actually showed. It is
|
|
324
|
+
only applied with `allowExpectationUpdate: true`.
|
|
325
|
+
|
|
326
|
+
The response is a unified diff. With `apply: true` the file is written only if it has not
|
|
327
|
+
changed since the failure, the single test is re-run (same project, no retries), and the
|
|
328
|
+
edit is reverted when it is still red. If nothing on the page shares the locator's
|
|
329
|
+
distinctive words, it refuses and reports that the element is most likely **missing**.
|
|
330
|
+
|
|
331
|
+
### `get-run-status`
|
|
332
|
+
|
|
333
|
+
| Argument | Type | Description |
|
|
334
|
+
| --- | --- | --- |
|
|
335
|
+
| `runId` | string | Run id from `run-test` with `background: true` (default: the most recent run) |
|
|
336
|
+
| `waitSeconds` | number | Wait up to this long (max 55) for the run to finish |
|
|
337
|
+
| `cancel` | boolean | Stop the run and kill its browsers |
|
|
338
|
+
|
|
339
|
+
While running it reports tests done / total and failures so far; once finished it returns
|
|
340
|
+
the full `run-test` result, which also becomes the last run for `get-failure` and
|
|
341
|
+
`suggest-fix`. The 20 most recent runs are kept in memory.
|
|
342
|
+
|
|
343
|
+
### `analyze-history`
|
|
344
|
+
|
|
345
|
+
| Argument | Type | Description |
|
|
346
|
+
| --- | --- | --- |
|
|
347
|
+
| `view` | `flaky` \| `patterns` \| `test` | `flaky` (default) ranks unstable tests; `patterns` groups failures by kind and normalized error; `test` shows one test's timeline |
|
|
348
|
+
| `test` | string | Substring of a test's file or title (filters every view) |
|
|
349
|
+
| `lastRuns` | number | How many recent runs to analyze (default `30`) |
|
|
350
|
+
| `limit` | number | Max rows (default `15`) |
|
|
351
|
+
|
|
352
|
+
Every `run-test`, `diagnose-flaky` and `suggest-fix` run appends a line to
|
|
353
|
+
`<project>/.playwright-e2e-mcp/history.jsonl` (the folder carries its own `.gitignore`;
|
|
354
|
+
nothing leaves the machine; `PW_MCP_HISTORY=0` turns it off). The flaky view separates
|
|
355
|
+
tests that flip between pass and fail, tests that started failing and stayed red
|
|
356
|
+
(regressed), and tests that failed every run (broken), each with a `PFFP~` timeline.
|
|
357
|
+
|
|
230
358
|
---
|
|
231
359
|
|
|
232
360
|
## Installation
|
|
@@ -242,8 +370,8 @@ builds `dist/` automatically on install). Pin a release tag: an unpinned
|
|
|
242
370
|
`github:trajectiq-ai/E2E` runs whatever is on the default branch at that moment.
|
|
243
371
|
|
|
244
372
|
```bash
|
|
245
|
-
npx -y github:trajectiq-ai/E2E#v0.
|
|
246
|
-
npm install -D github:trajectiq-ai/E2E#v0.
|
|
373
|
+
npx -y github:trajectiq-ai/E2E#v0.2.0
|
|
374
|
+
npm install -D github:trajectiq-ai/E2E#v0.2.0 @playwright/test # or as a project dependency
|
|
247
375
|
npx playwright install chromium
|
|
248
376
|
```
|
|
249
377
|
|
|
@@ -251,7 +379,7 @@ Or grab the packaged tarball from the repo's **GitHub Releases** page and instal
|
|
|
251
379
|
it locally:
|
|
252
380
|
|
|
253
381
|
```bash
|
|
254
|
-
npm install -D https://github.com/trajectiq-ai/E2E/releases/download/v0.
|
|
382
|
+
npm install -D https://github.com/trajectiq-ai/E2E/releases/download/v0.2.0/playwright-e2e-mcp-0.2.0.tgz
|
|
255
383
|
```
|
|
256
384
|
|
|
257
385
|
Listed in the **official [MCP Registry](https://registry.modelcontextprotocol.io/)** as
|
|
@@ -267,7 +395,7 @@ Listed in the **official [MCP Registry](https://registry.modelcontextprotocol.io
|
|
|
267
395
|
"mcpServers": {
|
|
268
396
|
"playwright-e2e": {
|
|
269
397
|
"command": "npx",
|
|
270
|
-
"args": ["-y", "github:trajectiq-ai/E2E#v0.
|
|
398
|
+
"args": ["-y", "github:trajectiq-ai/E2E#v0.2.0"],
|
|
271
399
|
"env": { "PW_MCP_PROJECT_ROOT": "/absolute/path/to/your/project" }
|
|
272
400
|
}
|
|
273
401
|
}
|
|
@@ -281,8 +409,8 @@ when the client launches it somewhere else (e.g. your home directory).
|
|
|
281
409
|
**Codex / VS Code / Copilot CLIs:**
|
|
282
410
|
|
|
283
411
|
```bash
|
|
284
|
-
codex mcp add playwright-e2e -- npx -y github:trajectiq-ai/E2E#v0.
|
|
285
|
-
code --add-mcp '{"name":"playwright-e2e","command":"npx","args":["-y","github:trajectiq-ai/E2E#v0.
|
|
412
|
+
codex mcp add playwright-e2e -- npx -y github:trajectiq-ai/E2E#v0.2.0
|
|
413
|
+
code --add-mcp '{"name":"playwright-e2e","command":"npx","args":["-y","github:trajectiq-ai/E2E#v0.2.0"]}'
|
|
286
414
|
```
|
|
287
415
|
|
|
288
416
|
Codex's defaults fight this server: the first launch clones the repo and runs
|
|
@@ -293,7 +421,7 @@ Codex's defaults fight this server: the first launch clones the repo and runs
|
|
|
293
421
|
```toml
|
|
294
422
|
[mcp_servers.playwright-e2e]
|
|
295
423
|
command = "npx"
|
|
296
|
-
args = ["-y", "github:trajectiq-ai/E2E#v0.
|
|
424
|
+
args = ["-y", "github:trajectiq-ai/E2E#v0.2.0"]
|
|
297
425
|
startup_timeout_sec = 60
|
|
298
426
|
tool_timeout_sec = 600
|
|
299
427
|
```
|
|
@@ -308,7 +436,7 @@ into `PW_MCP_PROJECT_ROOT`, so the tools point at a real project from the first
|
|
|
308
436
|
**Claude Code:**
|
|
309
437
|
|
|
310
438
|
```bash
|
|
311
|
-
claude mcp add playwright-e2e -- npx -y github:trajectiq-ai/E2E#v0.
|
|
439
|
+
claude mcp add playwright-e2e -- npx -y github:trajectiq-ai/E2E#v0.2.0
|
|
312
440
|
```
|
|
313
441
|
|
|
314
442
|
**Gemini CLI / Qwen Code:** paste the `mcpServers` block above into
|
|
@@ -364,7 +492,7 @@ has `PW_MCP_HTTP_TOKEN` set, so a request without `Authorization: Bearer <token>
|
|
|
364
492
|
bridge (below).
|
|
365
493
|
|
|
366
494
|
**Open vs. token-protected.** With `PW_MCP_HTTP_TOKEN` set (at least 16
|
|
367
|
-
characters; use a random value)
|
|
495
|
+
characters; use a random value) every tool is served to clients that send
|
|
368
496
|
`Authorization: Bearer <token>`, and every other request gets `401`. Without that
|
|
369
497
|
variable anyone who reaches the URL can call the bridge, so it degrades to
|
|
370
498
|
`list-tests` and `get-failure` in restricted mode: `list-tests` scans sources
|
|
@@ -422,6 +550,8 @@ every push, so there is no token to manage and no CLI step — watch the
|
|
|
422
550
|
| Environment variable | Default | Purpose |
|
|
423
551
|
| --- | --- | --- |
|
|
424
552
|
| `PW_MCP_PROJECT_ROOT` | server cwd | Default project root for every tool |
|
|
553
|
+
| `PW_MCP_STORAGE_STATE` | — | Default `storageState` file (inside the project) for the page tools |
|
|
554
|
+
| `PW_MCP_HISTORY` | on | `0` stops recording runs to `.playwright-e2e-mcp/history.jsonl` |
|
|
425
555
|
| `PW_MCP_ALLOWED_ROOTS` | — | Extra directories a caller may pass as `projectRoot` (`:`-separated, `;` on Windows). Anything outside these and the default root is rejected |
|
|
426
556
|
| `PW_MCP_HTTP_TOKEN` | — | HTTP bridge only: bearer token (16+ characters) that unlocks all tools (see above) |
|
|
427
557
|
| `PW_MCP_ALLOWED_HOSTS` | localhost + Vercel hostnames when there is no token | HTTP bridge only: comma-separated `Host` allowlist; `*` accepts any |
|
|
@@ -442,22 +572,40 @@ object (`time`, `level`, `message` plus context):
|
|
|
442
572
|
|
|
443
573
|
## Typical workflow
|
|
444
574
|
|
|
445
|
-
1. `
|
|
446
|
-
|
|
447
|
-
2. `
|
|
448
|
-
|
|
449
|
-
|
|
450
|
-
|
|
451
|
-
|
|
452
|
-
|
|
453
|
-
|
|
454
|
-
to
|
|
455
|
-
|
|
456
|
-
to
|
|
457
|
-
|
|
458
|
-
|
|
459
|
-
|
|
460
|
-
|
|
575
|
+
1. `run-test` `{ "testFiles": ["tests/checkout.spec.ts"] }`, or `{ "background": true }`
|
|
576
|
+
for a long suite and `get-run-status` `{ "waitSeconds": 30 }` until it finishes.
|
|
577
|
+
2. `get-failure` `{ "index": 1 }` to read the code frame, expected/actual, **the DOM
|
|
578
|
+
snapshot at failure**, the failed network requests and the page's console errors.
|
|
579
|
+
3. `suggest-fix` `{ "index": 1 }` for a locator or copy change: review the diff, then
|
|
580
|
+
`{ "index": 1, "apply": true }` to write it and verify with a re-run. If it reports the
|
|
581
|
+
element is missing, fix the app, not the test.
|
|
582
|
+
4. For anything it cannot patch: `inspect-page` `{ "url": "…", "view": "locators" }`
|
|
583
|
+
(add `storageState` or `actions` to reach the right screen), then `validate-selector`
|
|
584
|
+
to prove the new locator before editing.
|
|
585
|
+
5. If a failure looks intermittent: `diagnose-flaky` `{ "runs": 3 }` for fresh evidence,
|
|
586
|
+
and `analyze-history` to see how the test behaved across earlier runs.
|
|
587
|
+
6. After changing CSS or components: `compare-visual-state` `{ "url": "…", "name": "checkout" }`.
|
|
588
|
+
7. Re-run **only what failed** with `run-test` `{ "lastFailed": true }` until green.
|
|
589
|
+
|
|
590
|
+
To write a new test, start with `generate-e2e-test` `{ "description": "checkout with a saved card" }`.
|
|
591
|
+
|
|
592
|
+
## Benchmark
|
|
593
|
+
|
|
594
|
+
[`bench/token-benchmark.mjs`](bench/token-benchmark.mjs) breaks a checkout button's test id
|
|
595
|
+
on a storefront page and fixes it two ways: with this server (`run-test` → `suggest-fix` →
|
|
596
|
+
apply) and with Playwright MCP plus a shell (`playwright test`, `browser_navigate` +
|
|
597
|
+
`browser_snapshot`, edit, re-run). Latest result ([full output](bench/RESULTS.md)):
|
|
598
|
+
|
|
599
|
+
| Step | playwright-e2e-mcp | Playwright MCP + shell |
|
|
600
|
+
| --- | ---: | ---: |
|
|
601
|
+
| Tool definitions (sent with every request) | 4,565 | 4,726 |
|
|
602
|
+
| Run the failing test | 246 | 325 |
|
|
603
|
+
| Find the element / propose the fix | 260 | 2,286 |
|
|
604
|
+
| Apply + verify (re-run) | 257 | 34 |
|
|
605
|
+
| **Total for one fix** | 5,328 | 7,371 |
|
|
606
|
+
|
|
607
|
+
Tokens are characters ÷ 4. The Playwright MCP route is a lower bound: it assumes the agent
|
|
608
|
+
picks the right locator from the snapshot on the first try, which the server does for it here.
|
|
461
609
|
|
|
462
610
|
## Edge cases handled
|
|
463
611
|
|
|
@@ -518,10 +666,12 @@ object (`time`, `level`, `message` plus context):
|
|
|
518
666
|
src/
|
|
519
667
|
├── index.ts # bin entry point (--version/--help, main-module guard)
|
|
520
668
|
├── server.ts # McpServer setup, tool registration, shutdown handling
|
|
521
|
-
├── tools/ # the
|
|
669
|
+
├── tools/ # the eleven tools, the probe script + shared plumbing
|
|
670
|
+
├── prompts.ts # fix-failing-test, triage-flaky-tests
|
|
522
671
|
├── utils/ # playwright-runner, report-parser, project-detector, path-utils,
|
|
523
672
|
│ # logger, trace-reader (trace.zip → DOM/network/console),
|
|
524
|
-
│ # image-diff (PNG codec + pixel diff), change-analyzer
|
|
673
|
+
│ # image-diff (PNG codec + pixel diff), change-analyzer,
|
|
674
|
+
│ # locator-expr, run-history, run-registry
|
|
525
675
|
└── types/ # shared interfaces and the ErrorKind taxonomy
|
|
526
676
|
```
|
|
527
677
|
|
|
@@ -557,7 +707,10 @@ server over stdio against a live fixture app and a Playwright project under
|
|
|
557
707
|
`e2e/fixture/`, then drives it exactly like an MCP client and asserts ~40 behaviours
|
|
558
708
|
that only appear end-to-end:
|
|
559
709
|
|
|
560
|
-
- initialize handshake,
|
|
710
|
+
- initialize handshake, 11 tools, 2 prompts, spec tool annotations and object input schemas,
|
|
711
|
+
- verified locators, locator validation, signed-in pages (`storageState`) and page steps,
|
|
712
|
+
- background runs with progress, run history views, and `suggest-fix` healing a drifted
|
|
713
|
+
locator and verifying it with a re-run (and refusing when the element is missing),
|
|
561
714
|
- live DOM inspection, CSS selector validation (matches, zero matches, engine
|
|
562
715
|
syntax, parse errors), dead-server detection,
|
|
563
716
|
- visual regression: baseline → unchanged compare → `blue → red` diff detection,
|
|
@@ -588,3 +741,4 @@ pipeline in one shot.
|
|
|
588
741
|
## License
|
|
589
742
|
|
|
590
743
|
MIT
|
|
744
|
+
[](https://m8ven.ai/mcp/trajectiq-ai-e2e-fzfqvz?s=readme)
|
package/dist/http.d.ts
CHANGED
|
@@ -10,7 +10,7 @@
|
|
|
10
10
|
* verified locally before it is deployed.
|
|
11
11
|
*
|
|
12
12
|
* The stdio transport in server.ts is untouched; this is an additional way to
|
|
13
|
-
* reach the same
|
|
13
|
+
* reach the same eleven tools.
|
|
14
14
|
*/
|
|
15
15
|
import type { IncomingMessage, ServerResponse } from 'node:http';
|
|
16
16
|
import type { McpHttpHandler } from '@modelcontextprotocol/server';
|
package/dist/http.js
CHANGED
|
@@ -10,7 +10,7 @@
|
|
|
10
10
|
* verified locally before it is deployed.
|
|
11
11
|
*
|
|
12
12
|
* The stdio transport in server.ts is untouched; this is an additional way to
|
|
13
|
-
* reach the same
|
|
13
|
+
* reach the same eleven tools.
|
|
14
14
|
*/
|
|
15
15
|
import { createHash, timingSafeEqual } from 'node:crypto';
|
|
16
16
|
import { createMcpHandler, hostHeaderValidationResponse } from '@modelcontextprotocol/server';
|
|
@@ -0,0 +1,6 @@
|
|
|
1
|
+
/**
|
|
2
|
+
* MCP prompts: the workflows this server is built for, exposed so clients
|
|
3
|
+
* can offer them as slash commands (/fix-failing-test, /triage-flaky-tests).
|
|
4
|
+
*/
|
|
5
|
+
import type { McpServer } from '@modelcontextprotocol/server';
|
|
6
|
+
export declare function registerPrompts(server: McpServer): void;
|
package/dist/prompts.js
ADDED
|
@@ -0,0 +1,39 @@
|
|
|
1
|
+
/**
|
|
2
|
+
* MCP prompts: the workflows this server is built for, exposed so clients
|
|
3
|
+
* can offer them as slash commands (/fix-failing-test, /triage-flaky-tests).
|
|
4
|
+
*/
|
|
5
|
+
import { z } from 'zod';
|
|
6
|
+
function userText(text) {
|
|
7
|
+
return { messages: [{ role: 'user', content: { type: 'text', text } }] };
|
|
8
|
+
}
|
|
9
|
+
export function registerPrompts(server) {
|
|
10
|
+
server.registerPrompt('fix-failing-test', {
|
|
11
|
+
title: 'Fix a failing E2E test',
|
|
12
|
+
description: 'Run the tests, diagnose the first failure, apply a verified fix or explain the real bug.',
|
|
13
|
+
argsSchema: z.object({
|
|
14
|
+
test: z.string().optional().describe('Test file or file:line to focus on (default: the whole suite)'),
|
|
15
|
+
}),
|
|
16
|
+
}, ({ test }) => userText([
|
|
17
|
+
`Fix the failing Playwright test${test ? ` ${test}` : 's in this project'} using the playwright-e2e-mcp tools:`,
|
|
18
|
+
'',
|
|
19
|
+
`1. Call run-test${test ? ` with testFiles: ["${test}"]` : ''} (use background: true and get-run-status for a long suite).`,
|
|
20
|
+
'2. For each failure, call get-failure to read the error, the DOM at failure, failed requests and console errors.',
|
|
21
|
+
'3. If the failure is a broken locator or changed copy, call suggest-fix; review the diff and confidence, then call it again with apply: true (it re-runs the test and reverts if it still fails).',
|
|
22
|
+
'4. If suggest-fix finds no confident replacement, the element is likely missing: treat it as an app bug, explain the evidence (failed requests, console errors), and do not weaken the test.',
|
|
23
|
+
'5. If the test passes on retry or the verdict is unclear, call diagnose-flaky before changing anything.',
|
|
24
|
+
'6. Finish with run-test lastFailed: true and report what changed and why.',
|
|
25
|
+
].join('\n')));
|
|
26
|
+
server.registerPrompt('triage-flaky-tests', {
|
|
27
|
+
title: 'Triage flaky tests',
|
|
28
|
+
description: 'Rank unstable tests from the local run history and diagnose the worst one.',
|
|
29
|
+
}, () => userText([
|
|
30
|
+
'Triage flaky Playwright tests with the playwright-e2e-mcp tools:',
|
|
31
|
+
'',
|
|
32
|
+
'1. Call analyze-history (view: "flaky") to rank unstable tests; if there is little history, run run-test with args: ["--repeat-each=5"] first.',
|
|
33
|
+
'2. Call analyze-history with view: "patterns" to see failures that share one cause.',
|
|
34
|
+
'3. For the top flaky test, call diagnose-flaky with runs: 5 for fresh evidence.',
|
|
35
|
+
'4. Read the failing attempt with get-failure and propose a stabilizing change (await, web-first assertion, waiting on the right response), not a longer timeout.',
|
|
36
|
+
'5. Summarize: which tests are flaky, which are simply broken, and the shared causes.',
|
|
37
|
+
].join('\n')));
|
|
38
|
+
}
|
|
39
|
+
//# sourceMappingURL=prompts.js.map
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
{"version":3,"file":"prompts.js","sourceRoot":"","sources":["../src/prompts.ts"],"names":[],"mappings":"AAAA;;;GAGG;AAEH,OAAO,EAAE,CAAC,EAAE,MAAM,KAAK,CAAC;AAGxB,SAAS,QAAQ,CAAC,IAAY;IAC5B,OAAO,EAAE,QAAQ,EAAE,CAAC,EAAE,IAAI,EAAE,MAAe,EAAE,OAAO,EAAE,EAAE,IAAI,EAAE,MAAe,EAAE,IAAI,EAAE,EAAE,CAAC,EAAE,CAAC;AAC7F,CAAC;AAED,MAAM,UAAU,eAAe,CAAC,MAAiB;IAC/C,MAAM,CAAC,cAAc,CACnB,kBAAkB,EAClB;QACE,KAAK,EAAE,wBAAwB;QAC/B,WAAW,EAAE,0FAA0F;QACvG,UAAU,EAAE,CAAC,CAAC,MAAM,CAAC;YACnB,IAAI,EAAE,CAAC,CAAC,MAAM,EAAE,CAAC,QAAQ,EAAE,CAAC,QAAQ,CAAC,+DAA+D,CAAC;SACtG,CAAC;KACH,EACD,CAAC,EAAE,IAAI,EAAE,EAAE,EAAE,CACX,QAAQ,CACN;QACE,kCAAkC,IAAI,CAAC,CAAC,CAAC,IAAI,IAAI,EAAE,CAAC,CAAC,CAAC,mBAAmB,sCAAsC;QAC/G,EAAE;QACF,mBAAmB,IAAI,CAAC,CAAC,CAAC,sBAAsB,IAAI,IAAI,CAAC,CAAC,CAAC,EAAE,8DAA8D;QAC3H,kHAAkH;QAClH,mMAAmM;QACnM,8LAA8L;QAC9L,yGAAyG;QACzG,2EAA2E;KAC5E,CAAC,IAAI,CAAC,IAAI,CAAC,CACb,CACJ,CAAC;IAEF,MAAM,CAAC,cAAc,CACnB,oBAAoB,EACpB;QACE,KAAK,EAAE,oBAAoB;QAC3B,WAAW,EAAE,4EAA4E;KAC1F,EACD,GAAG,EAAE,CACH,QAAQ,CACN;QACE,kEAAkE;QAClE,EAAE;QACF,gJAAgJ;QAChJ,qFAAqF;QACrF,iFAAiF;QACjF,kKAAkK;QAClK,sFAAsF;KACvF,CAAC,IAAI,CAAC,IAAI,CAAC,CACb,CACJ,CAAC;AACJ,CAAC"}
|
package/dist/server.d.ts
CHANGED
|
@@ -1,7 +1,8 @@
|
|
|
1
1
|
/**
|
|
2
|
-
* MCP server setup: creates the McpServer instance, registers the
|
|
3
|
-
* tools (with spec tool annotations)
|
|
4
|
-
*
|
|
2
|
+
* MCP server setup: creates the McpServer instance, registers the eleven
|
|
3
|
+
* tools (with spec tool annotations) and the workflow prompts, and wires
|
|
4
|
+
* each invocation to a ToolContext (per-tool logger, abort signal, progress
|
|
5
|
+
* reporter, shared store, default project root).
|
|
5
6
|
*
|
|
6
7
|
* Logs go to stderr only — stdout belongs to the MCP protocol.
|
|
7
8
|
*/
|