pi-warden 0.64.1 → 0.73.0
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/CHANGELOG.md +132 -0
- package/README.md +49 -93
- package/dist/adaptive.d.ts +133 -0
- package/dist/adaptive.js +275 -0
- package/dist/atomic.d.ts +10 -0
- package/dist/atomic.js +51 -0
- package/dist/config.d.ts +49 -7
- package/dist/config.js +53 -28
- package/dist/evidence.d.ts +93 -0
- package/dist/evidence.js +409 -0
- package/dist/extension.d.ts +12 -1
- package/dist/extension.js +561 -80
- package/dist/extension.js.bak +668 -102
- package/dist/guard.d.ts +2 -1
- package/dist/guard.js +4 -4
- package/dist/holds.d.ts +1 -1
- package/dist/holds.js +3 -2
- package/dist/host-compat.d.ts +2 -0
- package/dist/host-compat.js +132 -0
- package/dist/host-dirs.d.ts +10 -0
- package/dist/host-dirs.js +21 -0
- package/dist/index-cmd.d.ts +6 -5
- package/dist/index-cmd.js +16 -24
- package/dist/index.d.ts +19 -3
- package/dist/index.js +9 -1
- package/dist/init.js +31 -3
- package/dist/learning.d.ts +12 -11
- package/dist/learning.js +60 -38
- package/dist/loops.d.ts +12 -1
- package/dist/loops.js +18 -7
- package/dist/panel.d.ts +4 -1
- package/dist/panel.js +11 -6
- package/dist/prefs.d.ts +9 -1
- package/dist/prefs.js +18 -7
- package/dist/rules-audit.d.ts +208 -0
- package/dist/rules-audit.js +417 -0
- package/dist/rules-calibrate.d.ts +196 -0
- package/dist/rules-calibrate.js +474 -0
- package/dist/rules-lint.d.ts +86 -0
- package/dist/rules-lint.js +196 -0
- package/dist/rules-log.d.ts +103 -0
- package/dist/rules-log.js +196 -0
- package/dist/rules-report.d.ts +55 -0
- package/dist/rules-report.js +88 -0
- package/dist/rules.d.ts +95 -6
- package/dist/rules.js +248 -65
- package/dist/shape.d.ts +1 -1
- package/dist/shape.js +14 -3
- package/dist/stuck.d.ts +34 -11
- package/dist/stuck.js +20 -8
- package/dist/trace.d.ts +1 -1
- package/dist/turn-rules.d.ts +86 -0
- package/dist/turn-rules.js +232 -0
- package/dist/waste.d.ts +98 -0
- package/dist/waste.js +582 -0
- package/dist/widget-render.d.ts +23 -0
- package/dist/widget-render.js +82 -0
- package/dist/widget.d.ts +5 -22
- package/dist/widget.js +3 -80
- package/package.json +7 -3
package/CHANGELOG.md
CHANGED
|
@@ -8,6 +8,138 @@ How to keep this current: add the entry in the same pull request as the change,
|
|
|
8
8
|
|
|
9
9
|
<!-- Empty. Next release starts here. -->
|
|
10
10
|
|
|
11
|
+
## 0.73.0
|
|
12
|
+
|
|
13
|
+
### Fixed
|
|
14
|
+
|
|
15
|
+
- pi-warden runs on oh-my-pi and other hosts that load Pi extensions through a compatibility layer. `src/host-compat.ts` maps the host API onto the Pi contract: `before_agent_start` gets `systemPromptOptions` with the active skills, and an `appendSystemPrompt` becomes the host's `systemPrompt` array. An input the extension handles is also marked `handled`. `agent_settled` runs after pi-warden's `agent_end` handlers have been dispatched and the host becomes idle. If background work is cancelled without another `agent_end`, the adapter waits for that work to drain. Command contexts get `getSystemPromptOptions()`. On upstream Pi the API is not changed.
|
|
16
|
+
- Data paths follow the host: the user config, the `/warden index` directory, and `holds.db` use the host's agent directory (`~/.pi/agent` on Pi, `~/.omp/agent` on oh-my-pi), and the project file uses the host's config directory (`.pi/pi-warden.json` or `.omp/pi-warden.json`).
|
|
17
|
+
- On a host whose overlay handle cannot release focus, Escape closes the trace and config panels.
|
|
18
|
+
- `import { defaultConfig } from "pi-warden"` works again without the optional `@earendil-works/pi-coding-agent` peer and now also without the optional `@earendil-works/pi-tui` peer: the library entry has no runtime import of either. Host directories come from the new injectable `HostDirs` parameter on every path function (`defaultHostDirs()` reads `PI_CODING_AGENT_DIR` and falls back to `~/.pi/agent`; existing callers keep working unchanged), and `src/extension.ts` builds them once from the host and passes them to every call. The entry's only pi-tui code — the rendered status stack — moved to `src/widget-render.ts`, which the entry does not re-export.
|
|
19
|
+
- On a host whose agent directory is not the Pi default (oh-my-pi), an interactive session shows a one-time notice when `~/.pi/agent/pi-warden` exists and the notice has not been shown on this host: it names the target and legacy folders and a command that moves the fresh data aside and copies the legacy data in its place, and records a marker beside the data folder so it shows once. Headless sessions show nothing.
|
|
20
|
+
|
|
21
|
+
### Docs
|
|
22
|
+
|
|
23
|
+
- `docs/configuration.md`, `docs/data-handling.md`, `docs/commands.md`, and `docs/faq.md` say that paths follow the host. `docs/configuration.md` and `docs/data-handling.md` add a one-time migration note for existing oh-my-pi users: close all Pi and oh-my-pi sessions, then run `{ [ ! -e "$HOME/.omp/agent/pi-warden" ] || mv "$HOME/.omp/agent/pi-warden" "$HOME/.omp/agent/pi-warden.before-migration"; } && cp -R "$HOME/.pi/agent/pi-warden" "$HOME/.omp/agent/pi-warden"` and copy each project's `.pi/pi-warden.json` to `.omp/pi-warden.json` (keep the original). oh-my-pi shows this notice once per machine.
|
|
24
|
+
|
|
25
|
+
## 0.72.0
|
|
26
|
+
|
|
27
|
+
### Added
|
|
28
|
+
|
|
29
|
+
- A project rule may cite where its wording came from with a `source: <file>:<line>` header beside `paths:`, for example `source: AGENTS.md:65`. `/warden rules` shows it, and when the rule fires the steer names it: `"<rule>" (from AGENTS.md line 65) ...`. A bad value is ignored and `/warden rules` reports the line.
|
|
30
|
+
- `/warden init` compiles an existing `AGENTS.md` or `CLAUDE.md` into small rules. The prompt hands the agent the instruction file's lines with line numbers and asks for one rule per instruction that can be judged from one changed file, each with a `source:` header and a `paths:` header when the instruction concerns certain files, wording close to the source, and a concrete violation pattern. Instructions that need other files, repository history, or the task, and anything a linter or type checker enforces, are left out of the file and listed in the reply with the reason. The reply suggests `/warden rules check` when the user has a key; the check is never run automatically. When `pi-warden.md` already exists the prompt is unchanged.
|
|
31
|
+
- `/warden rules audit [paths...] [--max N] [--yes]` judges existing files against the project rules as if each had just been written: one Jev request per file, at most four at a time, over the source files under the given paths (default: the project) that git does not ignore and at least one rule applies to, capped at `--max` (default 50) with the number left out reported. A confirm dialog names the file count and what leaves the machine before anything is sent; a headless run needs `--yes`. The output is a table by rule (files judged, files flagged, mean score) and the flagged files with their rule scores, worst first, plus a Markdown copy at `.pi-warden/rules-audit.md`. Nothing is recorded in the rules log. With no key or no consent it says so and sends nothing.
|
|
32
|
+
- `/warden bench [--runs N]` (default 10) measures what a rules check costs on this machine: the fixed built-in sample file judged N times against the active rules, reporting p50 and p95 latency, requests, mean input tokens per check, and estimated cost per check and per 100 edits. No confirmation is needed — the sample is built in and no project content is sent — and with no key or no consent it says so and sends nothing.
|
|
33
|
+
- `/warden rules calibrate [--commits N] [--max N] [--yes]` replays the changed files of the last N non-merge commits (default 20) through the project rules and reports, per rule, how often it applied and fired, the mean score, and the flags `fires on everything` and `undecided`, worst first, then the rules no file in the sample reached; a rule with no fire in the sample reports `no violation in sample` and is not flagged, because replayed commits are mostly compliant code. Each changed file is one `edit` request (the removed lines as `oldText`, the added lines as `newText`, the file after the commit as context), capped at `--max` (default 40); binary, generated, gitignored, `rules.exclude`, and `rules.skip` files are skipped, and a rule fires at its own `threshold:` cutoff. The scores go to the local rules log with `source: "calibrate"`, which `/warden report` counts apart from live verdicts. Nothing is sent before a confirm dialog showing the request count and the redacted diffs; a headless run needs the explicit `--yes`.
|
|
34
|
+
- `/warden rules tune` sends the session's agent one prompt with the rules the latest calibrate flagged `fires on everything` or `undecided`, or that `/warden rules check` (this session) flagged: each rule's current text and why it was flagged, and the ask for a rewrite that is concrete and judgeable from one changed file. The agent edits `pi-warden.md` with its own tools. With nothing flagged it says so and sends nothing.
|
|
35
|
+
- A project rule may carry `when: turn` beside `paths:`, `threshold:`, and `severity:` (default `edit`). A `when: turn` rule is judged once at the end of each agent run against the whole diff the run made and the user's task for that run, in one request, instead of on every edit — the home for rules one edit cannot answer, such as a change that adds more than the task asked for, a new abstraction with a single use, or logic duplicated across files. Turn rules are never asked about a single edit. The header lines parse in any order and at most once; a bad value is ignored and `/warden rules` reports the line.
|
|
36
|
+
- The end-of-run pass also judges files that shell commands changed in ways the per-edit guard cannot see (`sed -i`, `patch`, `git apply`, a generator's output redirected to a file, a subagent's writes): each changed file that no `write`, `edit`, or literal shell write already judged during the run is judged once, with its diff as the edit and the same per-edit question. The baseline is a read-only snapshot of the working tree taken in the background at run start (a temporary index file; the working tree, the real index, and the stash list are never touched), diffed at run end and including new untracked files git does not ignore. Every git call is asynchronous, so no hook blocks while git hashes the tree; the run end waits for a snapshot still running. The diff is capped at `rules.maxChars` per file and in total with the cut named. The unseen-change requests are capped at five files per run — the same cap as the files one shell command writes — with the first files in diff order judged and the rest named in the trace. Findings are one steer at the end of the run through the done-check's delivery, at most once per run and within the per-run steer budget; nothing holds. With no `when: turn` rules and no change the per-edit guard missed, no request is made and nothing is said.
|
|
37
|
+
|
|
38
|
+
### Tests
|
|
39
|
+
|
|
40
|
+
- Offline coverage for the history replay: hunk extraction from `git log -p`, the skip rules (binary, generated, ignored, `rules.exclude`, `rules.skip`), the request cap, the confirm and `--yes` paths, the report flags and their order at the `/warden report` thresholds, the `source: "calibrate"` log records, and the tune prompt (with no prompt when nothing is flagged), on temporary git repositories with a fake judge.
|
|
41
|
+
|
|
42
|
+
- Rules replay (`scripts/rules-replay.mjs`, `npm run eval:replay`): replays the `write` and `edit` calls of past Pi sessions in a project against that project's current rules, one request per judged call, and writes a review sheet (every flagged call plus a fixed-seed sample of unflagged calls) outside the repository beside aggregate counts. `--score` turns labelled sheets into precision on the flagged items and the estimated miss rate from the unflagged sample. The first run on this repository's own sessions is in `eval/reports/2026-09-27-rules-replay/`, unlabelled pending an independent reviewer. Offline tests cover the session replay and the output boundaries.
|
|
43
|
+
|
|
44
|
+
### Docs
|
|
45
|
+
|
|
46
|
+
- `docs/commands.md`, `docs/guards.md`, and `docs/data-handling.md` cover the two commands and what the replay sends.
|
|
47
|
+
|
|
48
|
+
## 0.71.0
|
|
49
|
+
|
|
50
|
+
### Added
|
|
51
|
+
|
|
52
|
+
- A project rule may set its own cutoff and severity in header lines at the top of its body, beside `paths:`: `threshold: 0.8` (a number from 0 to 1) and `severity: high|normal|low` (default `normal`). A rule with a `threshold:` fires at its own cutoff instead of `rules.threshold`; severity only orders findings (high, normal, low, then score), in the steer and in the trace. A bad value is ignored and `/warden rules` reports the line.
|
|
53
|
+
- `rules.softThreshold` (default `0`, off): a score from this value up to a rule's cutoff becomes a soft "please double-check" finding. Soft findings never hold, get one short separate sentence in the same steer (`Also check whether "<rule>" applies here (0.62).`), count against the steer budget like any other steer, and are recorded in the rules log with `soft: true`. When only soft findings exist the steer is that sentence alone.
|
|
54
|
+
|
|
55
|
+
### Tests
|
|
56
|
+
|
|
57
|
+
- Rules bench (`eval/rules-bench/`): 161 labelled cases (107 tune, 54 holdout) and eight new cases: six add a new violation of a rule the file already breaks and two touch only a line next to an old violation. Three fixture rules carry header lines (`severity:` on two, `threshold: 0.9` on the boolean-name rule). The scorer reads those headers and reports each rule at its own cutoff and the soft tier under it. The run is in `eval/reports/2026-09-27-rules-tiers/`, with case `r15-04` recorded as a still-open miss.
|
|
58
|
+
|
|
59
|
+
### Docs
|
|
60
|
+
|
|
61
|
+
- `docs/guards.md` → Calibration records the rules-tier measurement, and `docs/configuration.md` documents `rules.softThreshold`.
|
|
62
|
+
|
|
63
|
+
## 0.70.2
|
|
64
|
+
|
|
65
|
+
### Fixed
|
|
66
|
+
|
|
67
|
+
- Two store writes in one process no longer race. Every write to a loops, prefs, user-config, steer-stats, or rules-log file now goes to a temporary file unique to the process and the write before the rename, and the read-modify-write changes to the loops and prefs files run one after another, so a `warden_loops` or `warden_remember` call can no longer fail with `ENOENT` or silently lose the other call's change. A second Pi process writing the same file is still not guarded.
|
|
68
|
+
|
|
69
|
+
## 0.70.1
|
|
70
|
+
|
|
71
|
+
### Tests
|
|
72
|
+
|
|
73
|
+
- Rules bench (`eval/rules-bench/`, `npm run eval:rules`): 17 fixture rules and 153 labelled cases (four violations, three compliant near-misses and two cases where the rule does not apply for each rule), split into a fixed `tune` set (102) and a fixed `holdout` set (51), one request per case. `--split` selects the set, `--budget` caps requests, `--concurrency` sets parallel requests, `--dry-run` lists the plan and sends nothing, and `--rescore DIR` re-scores saved answers without spending. The scorer reports recall, false-alarm rate, precision and counts at cutoffs 0.3 to 0.9, AUC per rule, the rules whose clean cases sit in the 0.3 to 0.5 band, and the two-tier view (raise at 0.7 against a 0.5 to 0.7 double-check). Cases where a path-scoped rule is not asked at all are counted apart from the metrics. The first run is in `eval/reports/2026-09-26-rules-bench/`. The guard is unchanged.
|
|
74
|
+
|
|
75
|
+
## 0.70.0
|
|
76
|
+
|
|
77
|
+
### Added
|
|
78
|
+
|
|
79
|
+
- `/warden rules check` asks Jev which of the active rules the rules guard cannot judge well, and prints one line per rule that needs attention with the reason, its score, and one suggestion (`move it to your linter`, `split it so the changed file alone shows the violation`), then `N fine, M need attention`. Two questions per rule: whether it can be judged from one changed file's content alone (`from_change_alone`, `needs_other_files`, `needs_task_or_history`, `too_vague`) and whether a standard linter, formatter, or type checker could enforce it exactly (cutoff 0.70, measured in `docs/guards.md` → Calibration). Rule names, text, and `paths:` scopes are sent redacted, with no file content and no task text; with no key or no consent it says so and sends nothing, and plain `/warden rules` stays local. Advice only: no rule is changed, disabled, or skipped, and the guard's questions, thresholds, and defaults are untouched.
|
|
80
|
+
|
|
81
|
+
## 0.69.0
|
|
82
|
+
|
|
83
|
+
### Added
|
|
84
|
+
|
|
85
|
+
- `/warden report [--days N]` reads a local rules verdict log and reports, per rule, how often it was judged, fired, was cleared after a fire, and its mean violation score, with a flag for `never fires`, `fires on everything`, or `undecided`, then the rules in the current set with no records. Default 30 days; local only, nothing is sent. Each judgment from the rules guard is now recorded (time, session id, project-relative path, tool, rule id and name, outcome, P(violation), the threshold, whether it was a finding, and whether it cleared an earlier finding), keyed by a hash of the project path under `~/.pi/agent/pi-warden/rules/`; the file keeps the newest 5,000 records and a write failure is silent to the agent and shown once in the trace.
|
|
86
|
+
|
|
87
|
+
### Docs
|
|
88
|
+
|
|
89
|
+
- README rewritten shorter: badges, one headline claim, a table of what the agent does and what pi-warden does, and the measured numbers in one list.
|
|
90
|
+
|
|
91
|
+
## 0.68.0
|
|
92
|
+
|
|
93
|
+
### Added
|
|
94
|
+
|
|
95
|
+
- `/warden rules` prints the active parsed rule ids, path scopes and source files, plus the dropped count and `rules.exclude` patterns, so the local rule set can be inspected without sending anything to Jev. With `rules.enabled: false` the output leads with `Rules guard is off (rules.enabled: false). These would apply:` and the same details follow. A fallback document judged as one aggregate rule reports its condensed size only.
|
|
96
|
+
|
|
97
|
+
## 0.67.0
|
|
98
|
+
|
|
99
|
+
### Added
|
|
100
|
+
|
|
101
|
+
- **Stuck evidence.** The stuck guard now sends the judge a compact structured `evidence` section next to today's fields. Per run: the failing test, error, location, summary and exit code, parsed generically from the run's own output (TAP/node test, jest, vitest, pytest, tsc, eslint, cargo, go, a `make test` script, Playwright), the run number of the earlier run that failed the same way after durations, clock times, temp paths, line:column positions and ordering are normalised, and a 300-character head plus 300-character tail fallback when no parser knows the output. Per `edit`/`write`: the path and a diff of the change capped at 600 characters. A digest gives the failed runs, the distinct failures, the runs that repeat an earlier command, the edits between the first and last failed run, and the information-gathering calls after the first failure. Every string is redacted, the whole object is capped at 4 KB, and the oldest runs are dropped first. The measurement behind it is in `eval/reports/2026-09-26-stuck-evidence/`: on the same 40 stuck bench cases, accuracy 0.725 → 1.000, right where the old state was wrong on 11 cases and wrong where it was right on none (sign test p = 0.001), no latency change at p50. Edit diffs (capped, redacted) now leave the machine for stuck checks; `docs/data-handling.md` lists them.
|
|
102
|
+
- Config `stuck.evidence` (default `true`, valid in the user and the project file). `false` sends the output tails only, as before. The guard's questions, thresholds and when it fires are unchanged.
|
|
103
|
+
|
|
104
|
+
### Tests
|
|
105
|
+
|
|
106
|
+
- Judge bench: the stuck arms are now the shipped guard itself. Arm A is `buildStuckRequest` with `stuck.evidence` on (the default), arm C is the same builder with it off, and arm B keeps A and enlarges the raw slices, so a run compares the shipped state against its predecessor on the same cases. The generic parser and the failure signature moved out of `eval/judge-bench/` into `src/evidence.ts`, so the bench exercises the shipped code; the bench's own parser module is gone.
|
|
107
|
+
- New tests: the request without evidence equals the state sent before the change, one sample of each runner format names its failing test, an unknown output falls back to head and tail, noise-only differences (line numbers, times, temp paths, ordering) are one failure while a changed failure is two, a credential in an output or in a diff never reaches the state, the 4 KB cap holds and drops the oldest runs first then the oldest edits, and `stuck.evidence` is read from the user file and the project file.
|
|
108
|
+
|
|
109
|
+
## 0.66.1
|
|
110
|
+
|
|
111
|
+
### Tests
|
|
112
|
+
|
|
113
|
+
- Judge bench (`eval/judge-bench/`, `npm run eval:judge`): 80 labelled cases for the stuck and done guards (40 each, half positive), each sent to the real judge in three request states: A, the state the guards build today; B, the same shape with larger raw output slices; C, today's fields plus a compact `evidence` object from a generic failure parser (failing tests, errors, locations, edit diffs, file types, checks after the last edit). 36 traces come from real runs of node test, tsc, cargo, go, sbcl and scripts in throwaway projects; the rest are written in the runners' own formats. Scoring uses the guards' own thresholds and gate. `--dry-run` lists the plan and sends nothing; `--budget` caps requests. Guard behaviour does not change.
|
|
114
|
+
- First judge bench run (`eval/reports/2026-09-26-judge-bench/`, 720 requests, 3 repeats): on stuck, the structured state is right where today's state is wrong on 11 cases and never the reverse (sign test p = 0.001; accuracy 0.725 → 0.992), mostly progressing windows that today's state calls stuck; its digest is close to the label rule, so this is an upper bound. On done, no arm beats today's state beyond noise, because the five not-done cases with a passing check after the last edit never reach the judge. Larger raw slices change one verdict. Latency p50 is 245–257 ms in every arm.
|
|
115
|
+
|
|
116
|
+
## 0.66.0
|
|
117
|
+
|
|
118
|
+
### Added
|
|
119
|
+
|
|
120
|
+
- Call-waste notes. Each tool call re-reads the whole conversation, so four patterns that spend calls for nothing now earn one advisory sentence each, attached to the tool result that triggers them: a second `sleep` poll inside 10 calls, a third ranged read of one file whose ranges are adjacent or overlapping, a third search of one file with the same or an overlapping pattern, and a check re-run with a different output filter after an earlier run was cut by a pipe and showed no failure. The note is text added to a result the model is about to read, so it costs no request; it never holds, blocks, or warns, never spends `steerBudget`, and is not adapted by `steers`. One note per detector per 20 calls. On the first run of a session one tip is appended to the system prompt when `waste.tip` is on: read files in large ranges or whole, run a check once without a pipe and search its output, and wait with one blocking command instead of repeated sleeps. New config section `waste`: `enabled` (default `true`), `tip` (default `false`, opt-in), `every` (20), and one switch per detector (`sleep`, `paging`, `search`, `recheck`, all default `true`). Every note is recorded in the trace as the `waste` guard with its detector. Thresholds come from an offline measurement over the tool calls of 1175 existing sessions; the weak-model bench that ran the guard on and off is under `eval/reports/2026-09-26-waste-nudges/`.
|
|
121
|
+
|
|
122
|
+
### Changed
|
|
123
|
+
|
|
124
|
+
- The session tip is opt-in: `waste.tip` defaults to `false`. The five-repeat A/B on the weak suite (`eval/reports/2026-09-26-waste-tip-5x/`, 80 runs) put the tip's arm 0.5% apart on tokens and 0.6% apart on turns from the control, with a paired sign test over the task medians at p = 1.0 for tokens and for turns, with and without the long task, so the prompt tax is not paid by default. The four call-waste notes stay on by default and are unaffected; `waste.enabled` still gates both.
|
|
125
|
+
|
|
126
|
+
### Tests
|
|
127
|
+
|
|
128
|
+
- The same two cells re-run at five repeats on the weak suite (`eval/reports/2026-09-26-waste-tip-5x/`, 80 runs) do not confirm the two-repeat numbers: tokens −0.5%, turns +0.6%, tool calls −10%, no detector note fired in either cell, tip delivered in all 40 waste-on runs, success 33 against 30 of 40 and harm 2 against 4. A paired sign test over the task medians gives p = 1.00 for tokens and for turns, with and without the long task, so the −43% tokens and −26% turns of the batch above were small-sample spread rather than a guard effect. One waste-on run was killed at the runner's 12-minute timeout; dropping it does not change the verdict.
|
|
129
|
+
|
|
130
|
+
## 0.65.1
|
|
131
|
+
|
|
132
|
+
### Fixed
|
|
133
|
+
|
|
134
|
+
- The rules guard no longer blames an edit for code that the edit kept. Each edit's request now carries `after`, the lines of `before` with the edit applied, and each rule question asks whether the change introduces a violation, judged on `after`, instead of judging `newText` alone with `before` as context only. In the weak-model bench, three of the four rules steers that were noise flagged a missing `@returns` for an edit to a function body or an added import, with the JSDoc still directly above the function. An edit that drops a required `@returns` is still flagged.
|
|
135
|
+
- A rules steer names the rule and the written file only; it no longer names the rules file (`from pi-warden.md`). After a false rules steer in the bench, one weak model spent 6 calls reading pi-warden's own config and hold log.
|
|
136
|
+
|
|
137
|
+
## 0.65.0
|
|
138
|
+
|
|
139
|
+
### Added
|
|
140
|
+
|
|
141
|
+
- Adaptive steers per model. pi-warden counts, per model and per steer kind (`intent-mismatch`, `off-task`, `rules`, `slop`, `stuck`, `conscience`, and the other advisory notes), the steers it sent, the ones the agent followed (a course change in its next two messages), and the ones it disputed ("as I said", "false positive"). After 30 or more steers, a kind followed under 20% of the time or disputed over 40% becomes trace-only for that model; 1 in 5 is still sent, and every further 30 steers the probes decide whether it is sent again. Holds, confirm, deny, security masking, the credential notice on masked output, and the done-check are never trace-only, and per-call judgments never change. The counts stay in `steer-stats.json` in pi-warden's data folder. `/warden status` lists the trace-only kinds per model with their rates; `/warden unmute <kind> [model]` resets a pair. New config section `steers`: `adaptive` (default `true`), `minSteers` (30), `minFollowed` (0.2), `maxDisputed` (0.4), `recheckEvery` (30), `probeEvery` (5). A replay of 937 recorded sessions would make `intent-mismatch` trace-only for three models (6 to 11% followed) and nothing else.
|
|
142
|
+
|
|
11
143
|
## 0.64.1
|
|
12
144
|
|
|
13
145
|
### Fixed
|
package/README.md
CHANGED
|
@@ -1,16 +1,28 @@
|
|
|
1
|
-
|
|
1
|
+
<div align="center">
|
|
2
2
|
|
|
3
|
-
|
|
3
|
+
# pi-warden
|
|
4
4
|
|
|
5
|
-
|
|
5
|
+
**Your coding agent says "done". It didn't run the tests.**<br>
|
|
6
|
+
**pi-warden catches it, and the agent fixes it without you.**
|
|
6
7
|
|
|
7
|
-
|
|
8
|
+
[](https://www.npmjs.com/package/pi-warden)
|
|
9
|
+
[](https://www.npmjs.com/package/pi-warden)
|
|
10
|
+
[](https://github.com/DevMortimer/pi-warden/stargazers)
|
|
11
|
+
[](LICENSE)
|
|
12
|
+
[](https://github.com/earendil-works/pi)
|
|
13
|
+
[](https://typesafe.ai)
|
|
8
14
|
|
|
9
|
-
|
|
15
|
+
</div>
|
|
10
16
|
|
|
11
17
|
|
|
12
18
|
|
|
13
|
-
<
|
|
19
|
+
<div align="center">
|
|
20
|
+
|
|
21
|
+
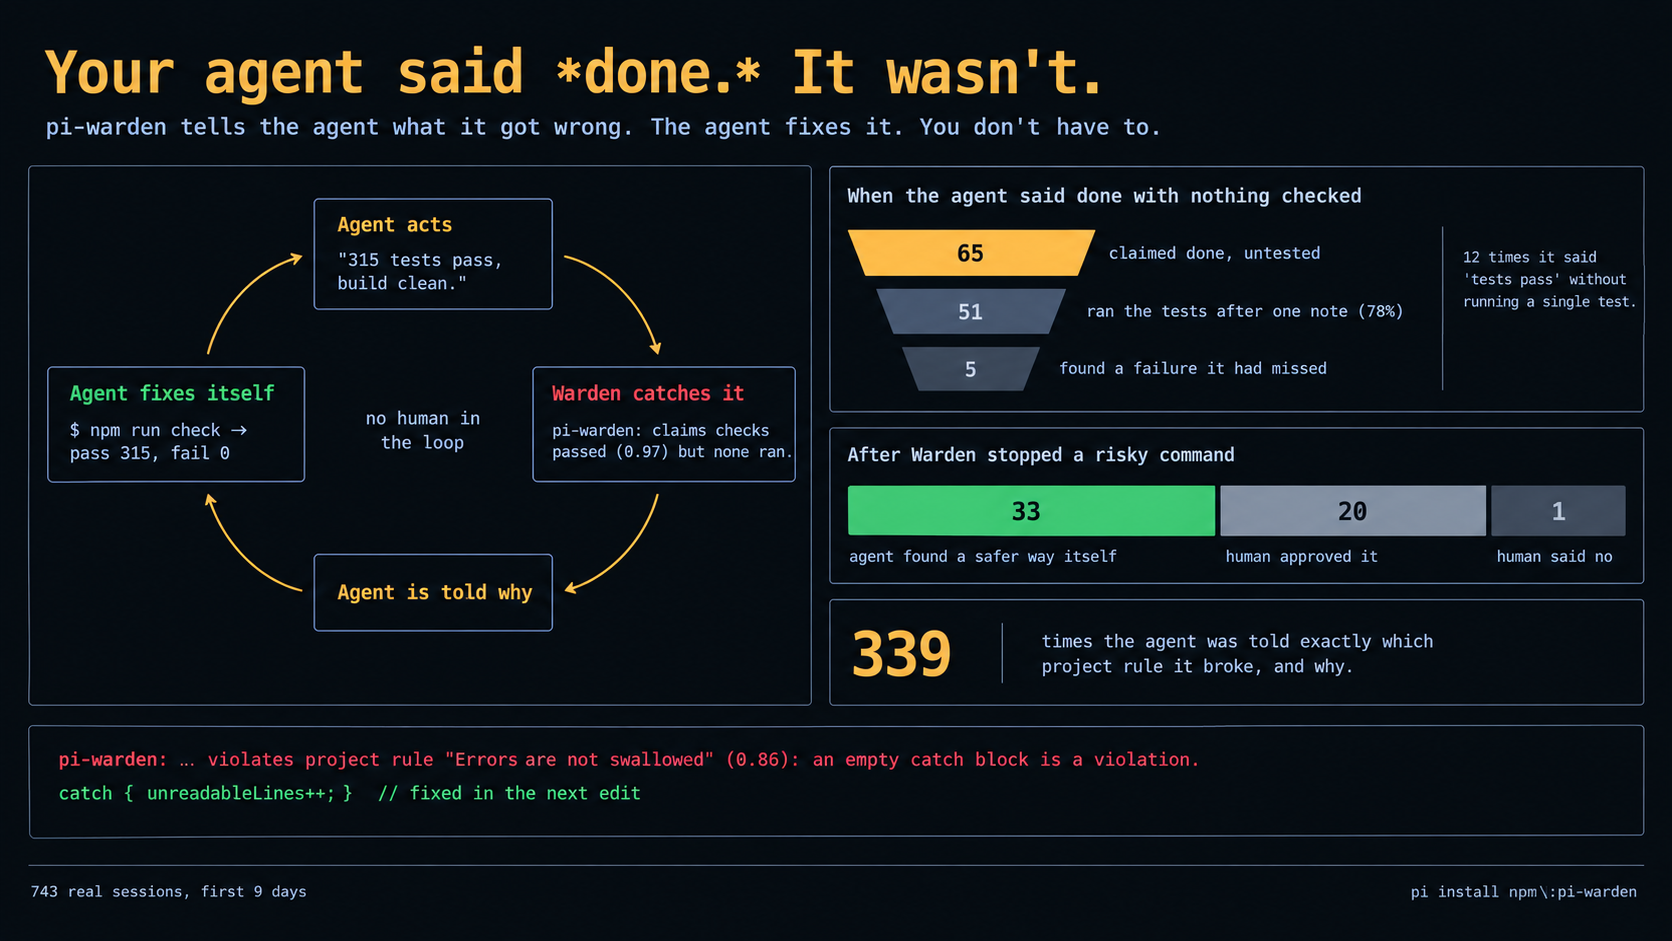
**759 sessions · 220 risky actions stopped before they ran · 76% of fake "done"s turned into real test runs**
|
|
22
|
+
|
|
23
|
+
<sub>Nine days of the maintainer's real use across all their projects, not just this one, 2026-09-16 to 2026-09-24. Method and noise: [field report](eval/reports/2026-09-24-field-usage/).</sub>
|
|
24
|
+
|
|
25
|
+
</div>
|
|
14
26
|
|
|
15
27
|
## Install
|
|
16
28
|
|
|
@@ -18,115 +30,59 @@ Instead of interrupting you for every problem, Warden usually feeds the issue ba
|
|
|
18
30
|
pi install npm:pi-warden
|
|
19
31
|
```
|
|
20
32
|
|
|
21
|
-
|
|
22
|
-
2. `/warden init` to write a starter `pi-warden.md`. The rules guard enforces what you put there.
|
|
23
|
-
3. `/warden index` (recommended) so the conscience knows your skills and tools from their real descriptions.
|
|
24
|
-
4. `/warden test` to see one synthetic verdict, then work as usual. The status line shows verdicts; `ctrl+shift+w` opens the trace sidebar.
|
|
25
|
-
|
|
26
|
-
The conscience is beta and off by default. Turn it on with `conscience.enabled: true` in the user config.
|
|
27
|
-
|
|
28
|
-
Works without any key (offline guards: pattern list, runaway stop, sensitive-path notes, credential warnings). Requires Pi 0.85+, Node 22.19+.
|
|
29
|
-
|
|
30
|
-
## What Warden catches
|
|
31
|
-
|
|
32
|
-
| Guard | Watches | Does |
|
|
33
|
-
| --- | --- | --- |
|
|
34
|
-
| **Action** | `bash`, `write`, `edit` before run | Holds irreversible calls, records trace-only off-task findings |
|
|
35
|
-
| **Rules** | every `write` and `edit` | Judges against project Markdown rules, quotes the broken rule |
|
|
36
|
-
| **Slop** | code and replies | Names stubs, restating comments, dead code, hedging |
|
|
37
|
-
| **Stuck** | tool results | Repeated failures using the same strategy |
|
|
38
|
-
| **Done-check** | final message | "Done" claims with no test/build/lint behind them, or UI changes nobody looked at |
|
|
39
|
-
| **Security** | code and output | Hardcoded secrets, injection risks |
|
|
40
|
-
| **Runaway** | reply stream | Stops replies that begin repeating themselves |
|
|
41
|
-
| **Subagent triage** | async child reports | Keeps noisy background work from waking the parent |
|
|
42
|
-
| **Conscience** (beta, off) | each operator prompt | Recommends a skill or tool from the capability index before the agent acts; enable with `conscience.enabled: true` |
|
|
43
|
-
|
|
44
|
-
## How intervention works
|
|
45
|
-
|
|
46
|
-
|
|
33
|
+
Then `/warden enable` (paste a [TypeSafe](https://console.typesafe.ai) key) and `/warden init` (writes a starter `pi-warden.md`). That's it. No key? The offline guards still run.
|
|
47
34
|
|
|
48
|
-
|
|
49
|
-
2. **Known-dangerous pattern? Catch it locally.** Force push, `git reset --hard`, recursive `rm`, SQL `DROP` held instantly. An agent deleting temp-directory scratch it created in the same session is not held (macOS and Windows).
|
|
50
|
-
3. **Needs judgment?** Warden evaluates the action in context.
|
|
51
|
-
4. **Steer or hold.** Most issues go back to the agent so it can correct itself. Irreversible actions can be stopped before they run.
|
|
35
|
+
## It steers. It doesn't nag.
|
|
52
36
|
|
|
53
|
-
|
|
37
|
+
Most guardrails stop and ask you. pi-warden tells **the agent** what it got wrong, and the agent corrects itself. You are pulled in only when something can't be undone: **3 holds per 1,000 calls. The other 997 just run.**
|
|
54
38
|
|
|
55
|
-
|
|
39
|
+
| Your agent… | pi-warden… |
|
|
40
|
+
| --- | --- |
|
|
41
|
+
| says "done" with no test, build, or lint behind it | sends it back to prove it |
|
|
42
|
+
| breaks a rule in your `pi-warden.md` or `AGENTS.md` | quotes the exact rule it broke |
|
|
43
|
+
| is about to `git push --force`, `reset --hard`, `rm -rf`, `DROP` | holds it before it runs |
|
|
44
|
+
| retries the same failing fix for the third time | asks for a new hypothesis |
|
|
45
|
+
| writes stubs, restating comments, hardcoded secrets | names them on the spot |
|
|
46
|
+
| floods its context with a 40k-line log | keeps the lines that matter, stores the rest |
|
|
47
|
+
| starts repeating itself forever | stops the reply |
|
|
56
48
|
|
|
57
|
-
|
|
58
|
-
- **Custom policies**: command, path, and arming rules for your own workflow.
|
|
59
|
-
- **Context saver** trims oversized tool output while keeping the full result retrievable.
|
|
60
|
-
- **Multiple judgment backends**: TypeSafe by default, with OpenRouter support.
|
|
61
|
-
- **Honest about being off**: when judgments cannot run (no consent, no key, a rejected key, budget spent) Warden says so once, with the fix. A failing backend is paused after repeated errors instead of costing a timeout per action.
|
|
62
|
-
- **Full traceability**: inspect what Warden saw, decided, and told the agent.
|
|
63
|
-
- **Desktop alerts** for events that need you.
|
|
49
|
+
[Every guard, with its thresholds and calibration →](docs/guards.md)
|
|
64
50
|
|
|
65
|
-
##
|
|
66
|
-
|
|
67
|
-
Put `pi-warden.md` at the project root. Each heading is one rule:
|
|
51
|
+
## Rules no linter can check
|
|
68
52
|
|
|
69
53
|
```markdown
|
|
70
|
-
#
|
|
71
|
-
|
|
54
|
+
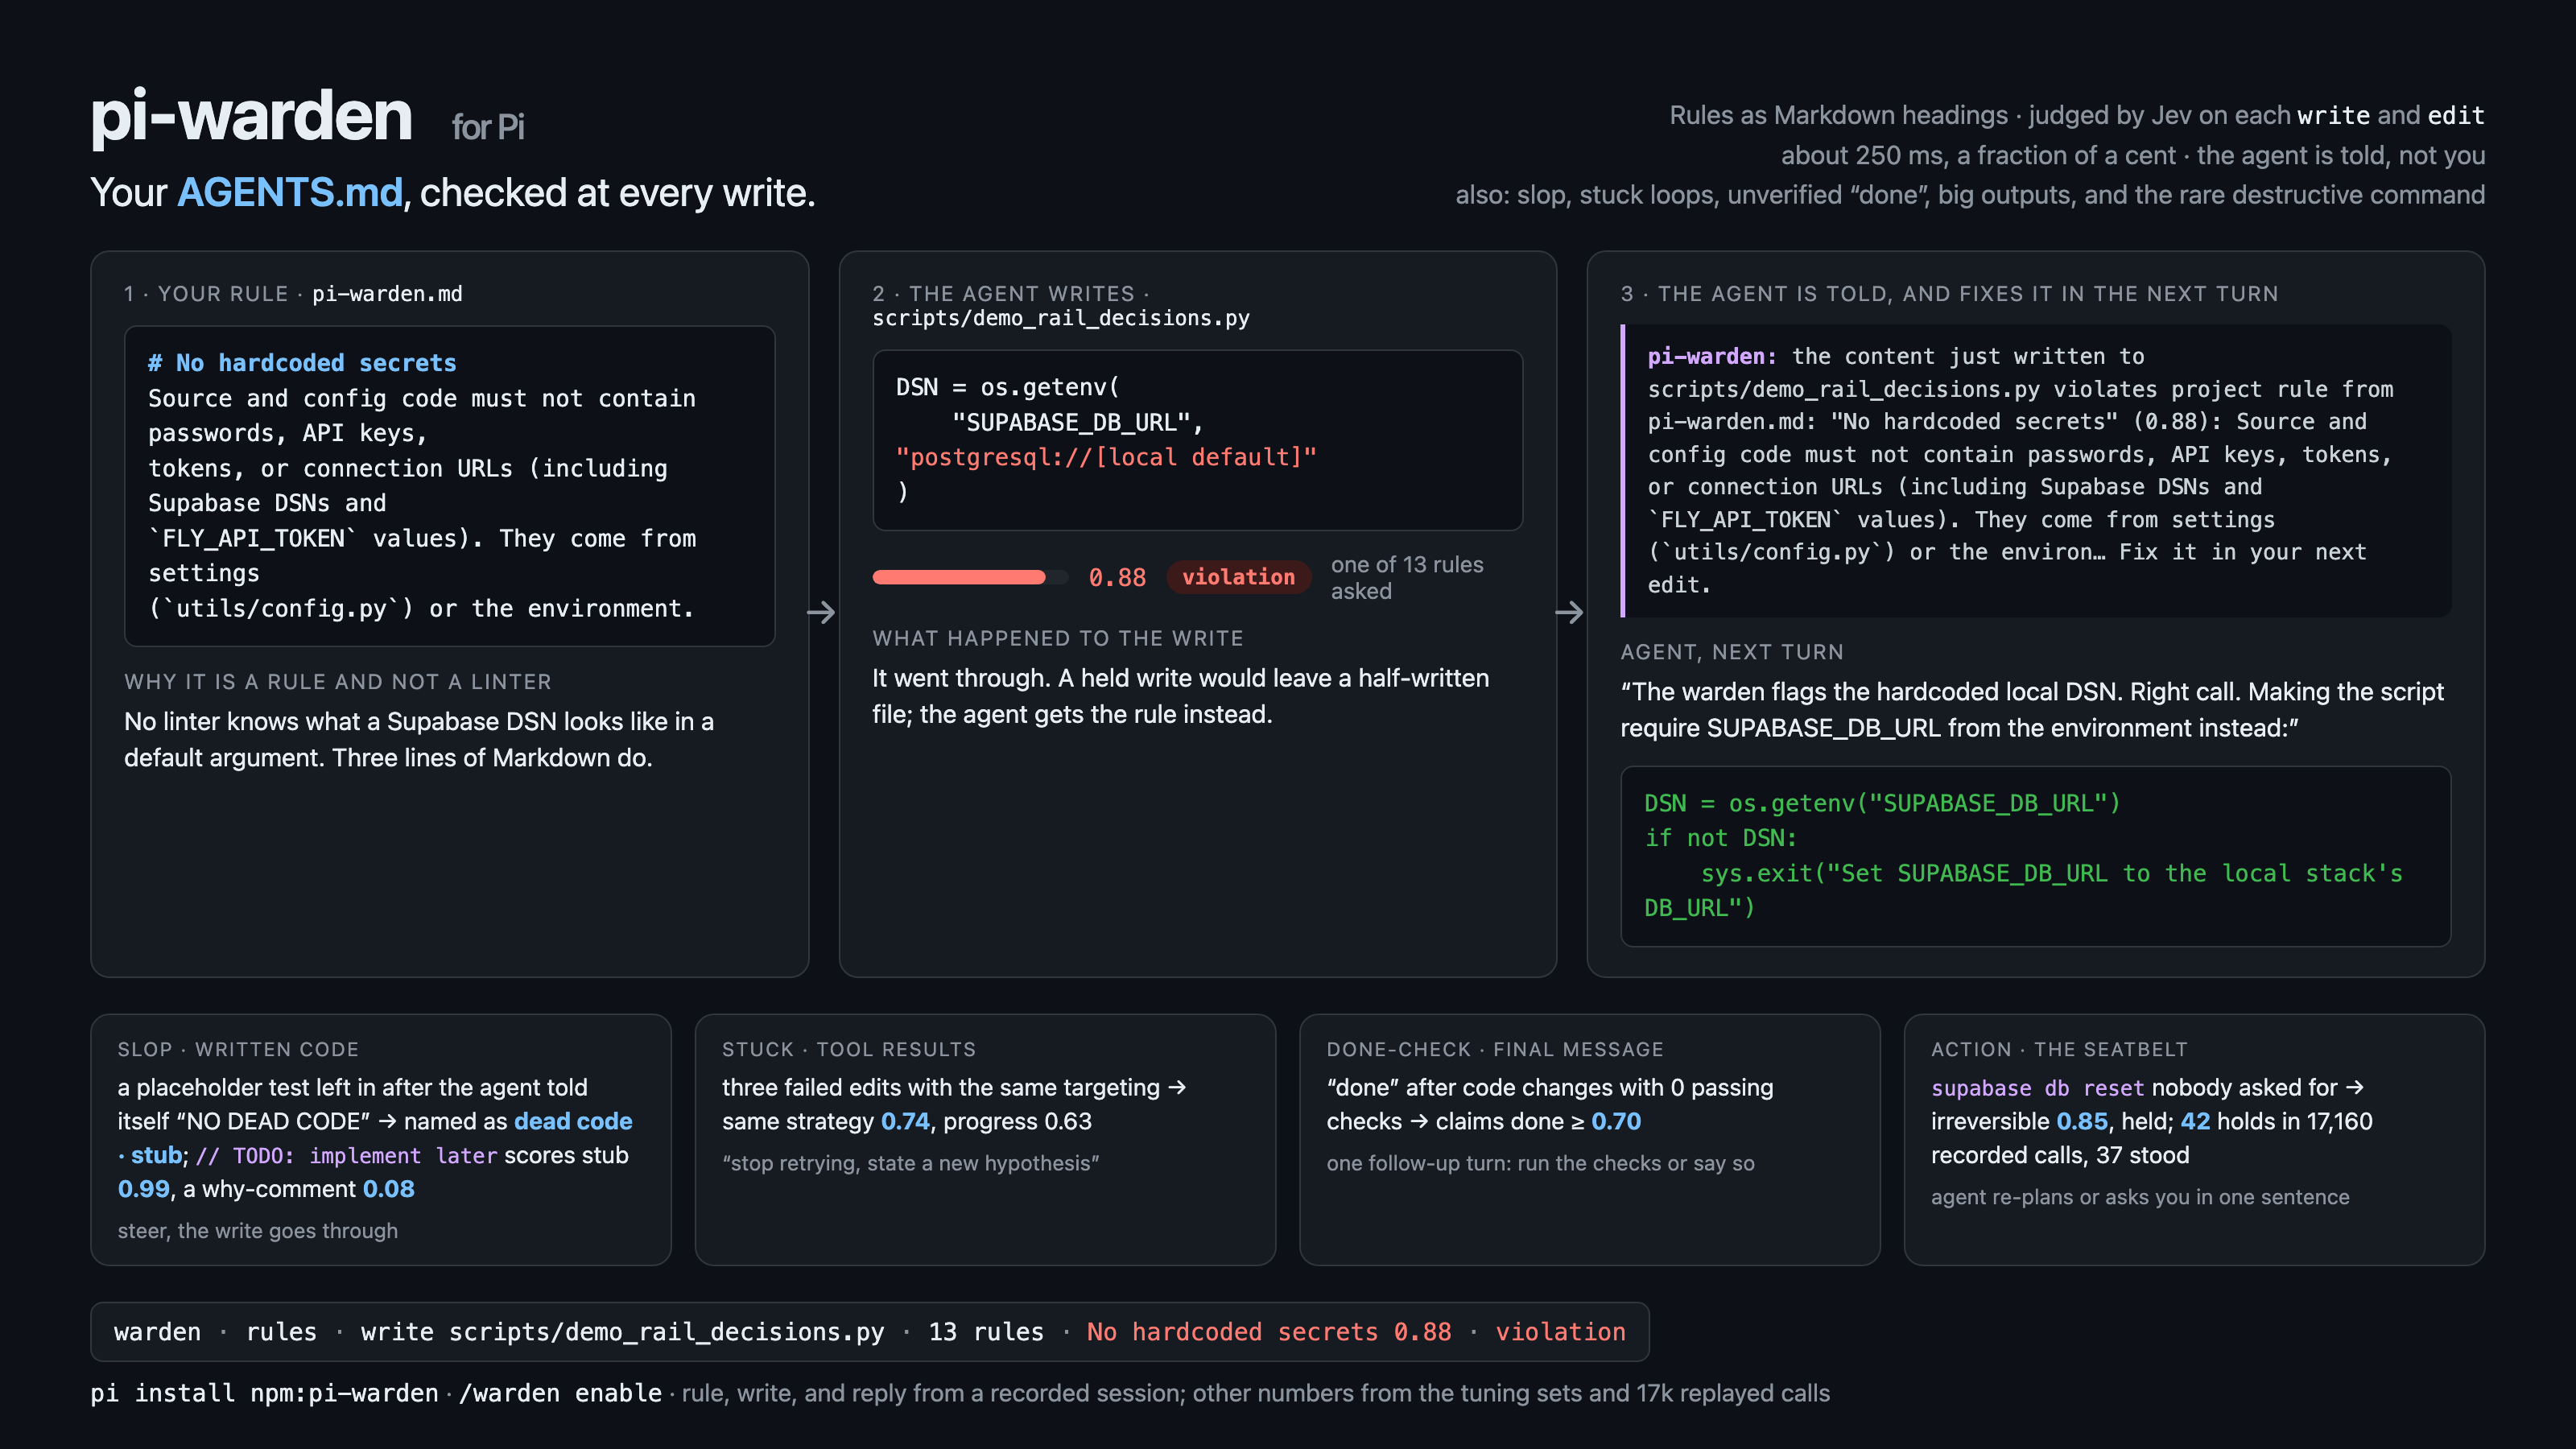
# A TODO names a ticket
|
|
55
|
+
A bare `TODO` or `FIXME` without a ticket reference is a violation.
|
|
72
56
|
|
|
73
|
-
#
|
|
74
|
-
paths: src/**/*.ts
|
|
75
|
-
|
|
57
|
+
# Errors never reach the user raw
|
|
58
|
+
paths: src/api/**/*.ts
|
|
59
|
+
Catch errors at the handler and return a message a user can act on.
|
|
76
60
|
```
|
|
77
61
|
|
|
78
|
-
|
|
79
|
-
|
|
80
|
-
## Does it actually help?
|
|
81
|
-
|
|
82
|
-
### In daily use
|
|
83
|
-
|
|
84
|
-
Four days of the maintainer's own work, 397 sessions ([report](eval/reports/2026-09-24-field-usage/), [raw numbers](eval/reports/2026-09-24-field-usage/usage.json), `scripts/field-usage.mjs` to run it on your own logs):
|
|
85
|
-
|
|
86
|
-
- **Done-check:** 47 nudges; in 35 the agent then ran a test or build.
|
|
87
|
-
- **Holds:** 143 of 19,695 actions. Of the 44 with a recorded outcome, the agent took a safer route 33 times.
|
|
88
|
-
- **Rules:** 195 corrections naming a project rule, including a process wait with no timeout and a home path in a public test fixture.
|
|
89
|
-
- **Context:** about 123,000 tokens of oversized output trimmed in the traced sessions, and no agent needed the full output back.
|
|
90
|
-
|
|
91
|
-
The report also lists what was noise that week (scratch deletes, credential notices on source code, two over-broad rules) and what changed because of it.
|
|
62
|
+
Each `#` heading is one rule. Every write and edit is judged against it in about a quarter of a second by [Jev](https://typesafe.ai), a model that returns a probability, not prose. No `pi-warden.md`? Your `AGENTS.md`, `CLAUDE.md`, or `README.md` is used instead.
|
|
92
63
|
|
|
93
|
-
|
|
64
|
+
## Receipts
|
|
94
65
|
|
|
95
|
-
|
|
66
|
+
- **Rules:** in 150 paired agent runs, the agent without pi-warden broke the tested rule **6 times**. With it: **0**.
|
|
67
|
+
- **Done-check:** after a nudge, the agent ran a check **57 of 75** times, and sometimes found a failure it had missed.
|
|
68
|
+
- **Holds:** when the agent was stopped, it found a safer way **40 of 65** times; you approved 24.
|
|
69
|
+
- **Stability:** 13,952 guard cases over 109 overnight cycles, no score drift.
|
|
96
70
|
|
|
97
|
-
|
|
98
|
-
|
|
99
|
-
These are project-maintained benchmarks, not universal claims. Raw reports and reproducible eval tooling are in the repo.
|
|
100
|
-
|
|
101
|
-
### Does it get in the way? Measured, not promised.
|
|
102
|
-
|
|
103
|
-
**3 holds per 1,000 calls. The other 997 run.** Across 315 recorded sessions and 18,075 guarded calls, the action hold fired 48 times, each for an action that is hard to undo. On the maintainer's machine, 452 allowed calls have run since outcome tracking began and not one was regretted afterward. When a hold was wrong, one retry cleared it: 2 of 13 labeled holds stood, the other 11 cleared on retry. The 27 calls the maintainer later regretted in the replay were ordinary edits and commits, not the kind a pre-call hold can see coming; those belong to the rules guard, the done-check, and the regret label, which are measured too. Snapshot numbers: `scripts/hold-stats.mjs` refreshes them, and the full replay is in [`eval/reports/2026-09-21-calibration-0.33.3/`](eval/reports/2026-09-21-calibration-0.33.3/).
|
|
104
|
-
|
|
105
|
-
[See the evals ->](eval/reports/)
|
|
71
|
+
Every number has a script and a raw report in [`eval/reports/`](eval/reports/). They are the maintainer's measurements, not a universal promise, and the reports list what was noise.
|
|
106
72
|
|
|
107
73
|
## Privacy
|
|
108
74
|
|
|
109
|
-
|
|
75
|
+
Secrets and unshown paths are stripped before anything leaves your machine. [Exactly what is sent →](docs/data-handling.md)
|
|
110
76
|
|
|
111
|
-
##
|
|
77
|
+
## Docs
|
|
112
78
|
|
|
113
|
-
|
|
114
|
-
- [docs/configuration.md](docs/configuration.md): all config keys, defaults, status line templates
|
|
115
|
-
- [docs/commands.md](docs/commands.md): command reference
|
|
116
|
-
- [docs/faq.md](docs/faq.md): cost, permissions, headless CI, project overrides
|
|
117
|
-
- [docs/data-handling.md](docs/data-handling.md): what leaves the machine, what stays
|
|
118
|
-
- [docs/examples.md](docs/examples.md): real session examples
|
|
119
|
-
- [examples/](examples/): starter rules file, both config files
|
|
79
|
+
[Guards](docs/guards.md) · [Configuration](docs/configuration.md) · [Commands](docs/commands.md) · [FAQ](docs/faq.md) · [Data handling](docs/data-handling.md) · [Examples](docs/examples.md)
|
|
120
80
|
|
|
121
81
|
## Development
|
|
122
82
|
|
|
123
83
|
```bash
|
|
124
84
|
npm install
|
|
125
|
-
npm run check
|
|
126
|
-
npm run test:live # live tests (costs real judgments)
|
|
127
|
-
npm run eval:ab # A/B benchmark (costs real tokens)
|
|
85
|
+
npm run check # typecheck + offline tests + build
|
|
128
86
|
```
|
|
129
87
|
|
|
130
|
-
|
|
131
|
-
|
|
132
|
-
MIT
|
|
88
|
+
MIT licensed.
|
|
@@ -0,0 +1,133 @@
|
|
|
1
|
+
import type { HostDirs } from "./host-dirs.js";
|
|
2
|
+
import type { SteersConfig } from "./config.js";
|
|
3
|
+
/**
|
|
4
|
+
* Per-model steer adaptation. A steer kind that a model follows rarely or disputes often becomes trace-only for that
|
|
5
|
+
* model: on recorded sessions intent-mismatch notices were followed 8% of the time, the done-check 77%, and strong
|
|
6
|
+
* models dispute noise ("as I said …"). Holds and per-call judgments never change; only whether a note is sent.
|
|
7
|
+
*/
|
|
8
|
+
/** One kind of note to the agent. Finer than the steer guard: the `action` guard sends several unrelated notes. */
|
|
9
|
+
export type SteerKind = "intent-mismatch" | "off-task" | "should-proceed" | "warn-headless" | "large-output" | "slop" | "rules" | "sensitive-path" | "security-write" | "stuck" | "repeat" | "done" | "prose" | "conscience" | "loops" | "runaway" | "subagent" | "hold" | "confirm" | "deny" | "masking" | "credential-notice";
|
|
10
|
+
export declare const STEER_KINDS: readonly SteerKind[];
|
|
11
|
+
/**
|
|
12
|
+
* Never trace-only, whatever a model does with them: holds, confirm and deny verdicts, security masking, the credential
|
|
13
|
+
* notice on masked output, and the done-check. Runaway recovery and subagent wakes start a turn of their own; muting
|
|
14
|
+
* them would change what the run does, not only what the agent is told.
|
|
15
|
+
*/
|
|
16
|
+
export declare const NEVER_MUTED: ReadonlySet<SteerKind>;
|
|
17
|
+
interface Counts {
|
|
18
|
+
sent: number;
|
|
19
|
+
followed: number;
|
|
20
|
+
disputed: number;
|
|
21
|
+
}
|
|
22
|
+
export interface PairState extends Counts {
|
|
23
|
+
muted: boolean;
|
|
24
|
+
/** Steers asked for since the pair became trace-only or was last re-checked. */
|
|
25
|
+
asked: number;
|
|
26
|
+
/** Outcomes of the probe steers sent since then. */
|
|
27
|
+
probe: Counts;
|
|
28
|
+
}
|
|
29
|
+
export interface MutedPair {
|
|
30
|
+
model: string;
|
|
31
|
+
kind: SteerKind;
|
|
32
|
+
sent: number;
|
|
33
|
+
followed: number;
|
|
34
|
+
disputed: number;
|
|
35
|
+
}
|
|
36
|
+
/** Where the counts live: next to the user config, in pi-warden's data folder. `PI_WARDEN_STEER_STATS` overrides it. */
|
|
37
|
+
export declare function steerStatsPath(dirs?: HostDirs): string;
|
|
38
|
+
export declare const DEFAULT_STEERS: SteersConfig;
|
|
39
|
+
/** True when the counts put the pair under the follow floor or over the dispute ceiling. */
|
|
40
|
+
export declare function failing(kind: SteerKind, counts: Counts, config: SteersConfig): boolean;
|
|
41
|
+
export type SteerDecision = "send" | "probe" | "trace-only";
|
|
42
|
+
/** The counts per (model, kind) pair, read once and written after every change. */
|
|
43
|
+
export declare class SteerStats {
|
|
44
|
+
private readonly path;
|
|
45
|
+
private data;
|
|
46
|
+
constructor(path?: string);
|
|
47
|
+
private load;
|
|
48
|
+
private save;
|
|
49
|
+
pair(model: string, kind: SteerKind): PairState | undefined;
|
|
50
|
+
private ensure;
|
|
51
|
+
/**
|
|
52
|
+
* Called before a steer of this kind goes out. A trace-only pair still sends the first of every `probeEvery` steers;
|
|
53
|
+
* after `recheckEvery` steers the probes decide: rates within the thresholds end trace-only, and the probe counts
|
|
54
|
+
* become the pair's new counts, so a fresh `minSteers` must pass before it can be muted again.
|
|
55
|
+
*/
|
|
56
|
+
request(model: string, kind: SteerKind, config: SteersConfig): SteerDecision;
|
|
57
|
+
/**
|
|
58
|
+
* The outcome of one sent steer. Crossing the thresholds at `minSteers` or later makes the pair trace-only. Kinds in
|
|
59
|
+
* NEVER_MUTED are counted, for the status, and never muted.
|
|
60
|
+
*/
|
|
61
|
+
observe(model: string, kind: SteerKind, outcome: {
|
|
62
|
+
followed: boolean;
|
|
63
|
+
disputed: boolean;
|
|
64
|
+
}, config: SteersConfig): void;
|
|
65
|
+
/** Drops the pair's counts; its steers are sent again. True when there was something to reset. */
|
|
66
|
+
unmute(model: string, kind: SteerKind): boolean;
|
|
67
|
+
/** Every trace-only pair, per model. */
|
|
68
|
+
muted(): MutedPair[];
|
|
69
|
+
/** Models with a pair of this kind, for `/warden unmute` without a model. */
|
|
70
|
+
modelsWith(kind: SteerKind): string[];
|
|
71
|
+
}
|
|
72
|
+
export declare function formatMuted(pairs: readonly MutedPair[], config: SteersConfig): string;
|
|
73
|
+
/** One assistant message after the steer: its text and its tool calls. */
|
|
74
|
+
export interface AssistantView {
|
|
75
|
+
text: string;
|
|
76
|
+
calls: Array<{
|
|
77
|
+
name: string;
|
|
78
|
+
input: Record<string, unknown>;
|
|
79
|
+
}>;
|
|
80
|
+
}
|
|
81
|
+
/** What the steer was about, for the follow check. */
|
|
82
|
+
export interface SteerSubject {
|
|
83
|
+
/** The file the note named (rules, slop, security). */
|
|
84
|
+
path?: string;
|
|
85
|
+
/** The call the note was about (stuck, repeat): a different next call is a course change. */
|
|
86
|
+
call?: {
|
|
87
|
+
name: string;
|
|
88
|
+
input: Record<string, unknown>;
|
|
89
|
+
};
|
|
90
|
+
/** The tool or skill the conscience named. */
|
|
91
|
+
capability?: {
|
|
92
|
+
kind: "tool" | "skill";
|
|
93
|
+
id: string;
|
|
94
|
+
};
|
|
95
|
+
}
|
|
96
|
+
/** Agent replies that argue with a note instead of acting on it. The same pattern the field replays used. */
|
|
97
|
+
export declare const DISPUTE: RegExp;
|
|
98
|
+
/**
|
|
99
|
+
* Whether the next assistant messages (at most two) changed course after a steer of this kind, and whether they
|
|
100
|
+
* disputed it. A port of the heuristic the field replays used; it is a proxy and does not prove the note caused the change.
|
|
101
|
+
*/
|
|
102
|
+
export declare function steerOutcome(kind: SteerKind, subject: SteerSubject, views: readonly AssistantView[]): {
|
|
103
|
+
followed: boolean;
|
|
104
|
+
disputed: boolean;
|
|
105
|
+
};
|
|
106
|
+
/**
|
|
107
|
+
* Sent steers waiting for the agent's next two messages. A steer queued for the next turn waits past the next user
|
|
108
|
+
* message; any other steer that meets a user message first is settled on what it saw, or dropped when it saw nothing.
|
|
109
|
+
*/
|
|
110
|
+
export declare class SteerWatch {
|
|
111
|
+
private pending;
|
|
112
|
+
add(model: string, kinds: readonly SteerKind[], subject?: SteerSubject, options?: {
|
|
113
|
+
nextTurn?: boolean;
|
|
114
|
+
}): void;
|
|
115
|
+
/** Feeds one assistant message; returns the steers it settled. */
|
|
116
|
+
assistant(view: AssistantView): Array<{
|
|
117
|
+
model: string;
|
|
118
|
+
kind: SteerKind;
|
|
119
|
+
followed: boolean;
|
|
120
|
+
disputed: boolean;
|
|
121
|
+
}>;
|
|
122
|
+
/** A user message arrived. */
|
|
123
|
+
user(): Array<{
|
|
124
|
+
model: string;
|
|
125
|
+
kind: SteerKind;
|
|
126
|
+
followed: boolean;
|
|
127
|
+
disputed: boolean;
|
|
128
|
+
}>;
|
|
129
|
+
clear(): void;
|
|
130
|
+
}
|
|
131
|
+
/** The text and tool calls of an assistant message as Pi stores it. */
|
|
132
|
+
export declare function assistantView(content: unknown): AssistantView;
|
|
133
|
+
export {};
|