pi-magi-theme 0.3.1 → 0.3.2
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.md +22 -2
- package/extensions/magi/index.ts +97 -14
- package/package.json +4 -3
package/README.md
CHANGED
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
# pi-magi-theme
|
|
2
2
|
|
|
3
|
-
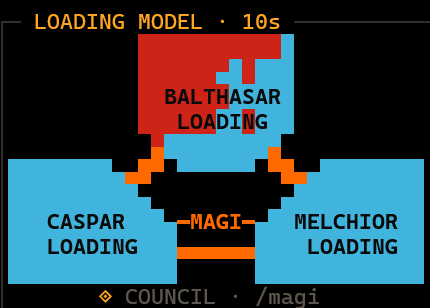
A three-mind council theme + extension for [pi](https://pi.dev): a MAGI SYSTEM header, the three MAGI as their control screen in a fixed side panel, live llama-swap telemetry, and `/magi`, a council of three models that votes on your engineering questions and reviews your pending changes.
|
|
3
|
+
A three-mind council theme + extension for [pi](https://pi.dev): a MAGI SYSTEM header, the three MAGI as their control screen in a fixed side panel, live llama-swap and [NInfer](https://github.com/b-iurea/ninfer-v100) telemetry, and `/magi`, a council of three models that votes on your engineering questions and reviews your pending changes.
|
|
4
4
|
|
|
5
5
|
Fan-art theme inspired by Neon Genesis Evangelion: the MAGI and their screen belong to their creators, all rights reserved to khara, Inc. This project is not affiliated with them. The rest of the symbolism (the Tree of Life, the sephirot, the seven seals) is public domain.
|
|
6
6
|
|
|
@@ -8,6 +8,13 @@ Fan-art theme inspired by Neon Genesis Evangelion: the MAGI and their screen bel
|
|
|
8
8
|
|
|
9
9
|
|
|
10
10
|
|
|
11
|
+
## What's new in 0.3.2
|
|
12
|
+
|
|
13
|
+
- **NInfer support.** List your `ninfer-serve` servers in `magi.json` (`"ninfer": { "urls": [...] }`) and their models appear in pi as `ninfer/<id>`, with no `models.json` entry: context window, thinking levels and image input come from what the server publishes. See [NInfer](#ninfer).
|
|
14
|
+
- **NINFER panel section.** With a `ninfer` model the side panel shows GPU, VRAM, RAM, energy, cost and the last request's speed and cache hits, read from the server's `/metrics`, and whether the server is up from `/health`.
|
|
15
|
+
- **Thinking budget on NInfer.** The learned budget (`/magi budget`) is sent as `thinking_budget_tokens`, which NInfer honours like llama-server.
|
|
16
|
+
- Requires a ninfer-serve with capabilities and `/metrics` ([b-iurea/ninfer-v100](https://github.com/b-iurea/ninfer-v100), branch `v3-artifact-support`); an older one still works, with text input and the Qwen low/medium/xhigh levels assumed, and no panel stats.
|
|
17
|
+
|
|
11
18
|
## Install
|
|
12
19
|
|
|
13
20
|
```bash
|
|
@@ -152,7 +159,8 @@ Each nature is a lens, not a specialty, so the council answers any question, not
|
|
|
152
159
|
- `ui.kwhPrice` and `ui.currency` (`EUR` or `USD`): the COST row multiplies the GPU energy by this price, showing the running total of every session with the current one in brackets;
|
|
153
160
|
- `totalWh`: written by the theme, GPU energy summed over every session (delete the key to reset the COST total);
|
|
154
161
|
- `hygiene` and `thinkingBudget` are set with `/magi hygiene` and `/magi budget` (`hygiene.minPruneChars` by hand only); `thinkingBudget.message` sends the closing message with every request (default `true`); `thinkingBudget.learned` is written by the theme (recent thinking lengths per model and phase);
|
|
155
|
-
- `loads`: written by the theme, how long each llama-swap model took to load last time (paces the angel attack; 60s when unknown)
|
|
162
|
+
- `loads`: written by the theme, how long each llama-swap model took to load last time (paces the angel attack; 60s when unknown);
|
|
163
|
+
- `ninfer`: `{ "urls": ["http://host:8080"], "apiKey": "…" }`, see [NInfer](#ninfer).
|
|
156
164
|
|
|
157
165
|
## Release
|
|
158
166
|
|
|
@@ -164,6 +172,18 @@ npm version patch && git push --follow-tags
|
|
|
164
172
|
|
|
165
173
|
No token: npmjs is configured to trust this repository's `publish.yml` (npm trusted publishing, OIDC), which also signs the provenance.
|
|
166
174
|
|
|
175
|
+
## NInfer
|
|
176
|
+
|
|
177
|
+
[NInfer](https://github.com/b-iurea/ninfer-v100) `ninfer-serve` loads one model per process. List the servers in `magi.json` (`apiKey` only if they run with `--api-key`):
|
|
178
|
+
|
|
179
|
+
```json
|
|
180
|
+
"ninfer": { "urls": ["http://192.168.2.220:8080"] }
|
|
181
|
+
```
|
|
182
|
+
|
|
183
|
+
At startup MAGI reads each server's `/v1/models` and registers its model under the `ninfer` provider (`/model ninfer/<id>`): the context window from `max_model_len`, the thinking levels from `meta.ninfer.reasoning.levels` (sent as `reasoning_effort`, `off` sends `none`) and image input from `architecture.input_modalities` (on when the server runs with `--vision`). A server that is down or still loading is skipped until the next pi start. Add `ninfer/*` to `enabledModels` if you use that filter.
|
|
184
|
+
|
|
185
|
+
With a `ninfer` session model the side panel shows a NINFER section like the llama-swap one: GPU, VRAM, RAM, energy and cost from `/metrics`, the last request's speed and cache hits, ready or offline from `/health`. The thinking budget is sent as `thinking_budget_tokens`. MECHA SELECT, `/magi status`, the prefix prewarm and the live seals need llama-swap.
|
|
186
|
+
|
|
167
187
|
## llama-swap
|
|
168
188
|
|
|
169
189
|
**Thinking levels.** [pi-llama-swap](https://www.npmjs.com/package/@danielmeneses/pi-llama-swap) registers every model with reasoning off, so `/thinking` only offers `off`. At session start MAGI reads the reasoning levels llama-swap publishes in `/v1/models` (`meta.llamaswap.reasoning.levels`) and re-registers those models with thinking on: `/thinking` then offers exactly those levels, sent as `chat_template_kwargs` (`enable_thinking`, `reasoning_effort`). Aliases (e.g. the Instruct twin of a Thinking model) stay off, and image input follows `architecture.input_modalities`. A new or renamed model works without a `modelOverrides` entry in `models.json`; entries you keep there still apply on top (e.g. `samplingParams`). The starting level is pi's usual one for a model switch: the level saved for that model (`Ctrl+S` in `/thinking`), else `defaultThinkingLevel`.
|
package/extensions/magi/index.ts
CHANGED
|
@@ -719,8 +719,9 @@ interface GpuStat {
|
|
|
719
719
|
|
|
720
720
|
type SwapState = "off" | "checking" | "loading" | "ready" | "asleep" | "error";
|
|
721
721
|
|
|
722
|
-
/** Live state of the
|
|
722
|
+
/** Live state of the server behind the session model: llama-swap, or a ninfer-serve (one resident model, no loading). */
|
|
723
723
|
const swap = {
|
|
724
|
+
kind: "" as "" | "llama-swap" | "ninfer",
|
|
724
725
|
base: "", // e.g. http://host:9292
|
|
725
726
|
headers: {} as Record<string, string>,
|
|
726
727
|
modelId: "", // the id pi uses (may be an alias)
|
|
@@ -755,17 +756,22 @@ function swapGet(path: string, timeoutMs = 5000): Promise<Response> {
|
|
|
755
756
|
return fetch(swap.base + path, { headers: swap.headers, signal: AbortSignal.timeout(timeoutMs) });
|
|
756
757
|
}
|
|
757
758
|
|
|
758
|
-
/** Parses
|
|
759
|
+
/** Parses the Prometheus /metrics of llama-swap (llamaswap_*) or ninfer-serve (ninfer_*, same names) into GPU and RAM stats. */
|
|
759
760
|
function parseSwapMetrics(text: string): void {
|
|
760
761
|
const gpus = new Map<string, GpuStat>();
|
|
761
762
|
for (const line of text.split("\n")) {
|
|
762
|
-
const m = /^
|
|
763
|
+
const m = /^(?:llamaswap|ninfer)_([a-z_]+)(?:\{([^}]*)\})?\s+(\S+)$/.exec(line);
|
|
763
764
|
if (!m) continue;
|
|
764
765
|
const key = m[1]!;
|
|
765
766
|
const labels = m[2] ?? "";
|
|
766
767
|
const value = Number(m[3]);
|
|
767
768
|
if (key === "memory_used_bytes") swap.ramUsed = value;
|
|
768
769
|
else if (key === "memory_total_bytes") swap.ramTotal = value;
|
|
770
|
+
// ninfer-serve has no request history: the last completed request comes with the metrics
|
|
771
|
+
else if (key === "last_tokens_per_second" && value > 0) swap.srvTps = value;
|
|
772
|
+
else if (key === "last_prompt_per_second" && value > 0) swap.srvPps = value;
|
|
773
|
+
else if (key === "last_cache_tokens") swap.cacheTokens = value;
|
|
774
|
+
else if (key === "last_prompt_tokens") swap.inputTokens = Math.max(0, value - swap.cacheTokens); // llama-swap's input_tokens exclude the cache
|
|
769
775
|
if (!key.startsWith("gpu_")) continue;
|
|
770
776
|
const id = /id="([^"]*)"/.exec(labels)?.[1] ?? "0";
|
|
771
777
|
const gpu = gpus.get(id) ?? { name: /name="([^"]*)"/.exec(labels)?.[1] ?? "GPU", util: 0, memUsed: 0, memTotal: 0, temp: 0, power: 0 };
|
|
@@ -834,6 +840,7 @@ async function refreshSwapMetrics(): Promise<void> {
|
|
|
834
840
|
|
|
835
841
|
/** Notices when llama-swap unloaded the session model (e.g. its ttl expired) so the panel can say so. */
|
|
836
842
|
async function refreshSwapRunning(): Promise<void> {
|
|
843
|
+
if (swap.kind === "ninfer") return refreshNinferHealth();
|
|
837
844
|
if (!swap.base || swap.state !== "ready") return;
|
|
838
845
|
try {
|
|
839
846
|
const { running } = (await (await swapGet("/running")).json()) as { running?: { model: string }[] };
|
|
@@ -843,8 +850,21 @@ async function refreshSwapRunning(): Promise<void> {
|
|
|
843
850
|
}
|
|
844
851
|
}
|
|
845
852
|
|
|
853
|
+
/** ninfer-serve keeps its model resident: it is ready while /health answers 200. */
|
|
854
|
+
async function refreshNinferHealth(): Promise<void> {
|
|
855
|
+
try {
|
|
856
|
+
const res = await swapGet("/health", 3000);
|
|
857
|
+
if (res.ok) {
|
|
858
|
+
if (swap.state !== "ready") setSwapState("ready");
|
|
859
|
+
} else setSwapState("error", `health HTTP ${res.status}`);
|
|
860
|
+
} catch (err) {
|
|
861
|
+
setSwapState("error", err instanceof Error ? err.message : String(err));
|
|
862
|
+
}
|
|
863
|
+
}
|
|
864
|
+
|
|
846
865
|
/** Server-side token metrics of the most recent request: a single row from /api/metrics/activity. */
|
|
847
866
|
async function refreshSwapActivity(): Promise<void> {
|
|
867
|
+
if (swap.kind === "ninfer") return refreshSwapMetrics(); // the last request comes with /metrics
|
|
848
868
|
if (!swap.base) return;
|
|
849
869
|
try {
|
|
850
870
|
const { data } = (await (await swapGet("/api/metrics/activity?limit=1")).json()) as { data?: any[] };
|
|
@@ -870,7 +890,8 @@ const LIVE_STALE_MS = 2_000;
|
|
|
870
890
|
* ponytail: with several slots it takes the fullest busy one, assuming it is this session's request.
|
|
871
891
|
*/
|
|
872
892
|
async function refreshLiveContext(): Promise<void> {
|
|
873
|
-
|
|
893
|
+
// ponytail: ninfer-serve has no /slots, its seals follow pi's estimate
|
|
894
|
+
if (swap.kind !== "llama-swap" || swap.state !== "ready") return;
|
|
874
895
|
try {
|
|
875
896
|
const slots = (await (await swapGet(`/upstream/${encodeURIComponent(swap.realId)}/slots`, 1_500)).json()) as any[];
|
|
876
897
|
const busy = slots.filter((s) => s.is_processing && s.n_prompt_tokens > 0);
|
|
@@ -957,6 +978,60 @@ async function enableSwapReasoning(pi: ExtensionAPI, ctx: ExtensionContext): Pro
|
|
|
957
978
|
}
|
|
958
979
|
}
|
|
959
980
|
|
|
981
|
+
/**
|
|
982
|
+
* ninfer-serve (NInfer) servers listed in magi.json "ninfer": each loads one model and lists it in /v1/models
|
|
983
|
+
* (owned_by "ninfer", max_model_len). They are registered as provider "ninfer", one model per server.
|
|
984
|
+
* Thinking goes as top-level reasoning_effort (NInfer rejects unknown chat_template_kwargs), "none" turns it off;
|
|
985
|
+
* the levels and image input come from what the server publishes (meta.ninfer.reasoning.levels, architecture.input_modalities).
|
|
986
|
+
*/
|
|
987
|
+
async function discoverNinfer(pi: ExtensionAPI, cfg: MagiConfig["ninfer"]): Promise<void> {
|
|
988
|
+
if (!cfg?.urls?.length) return;
|
|
989
|
+
const headers: Record<string, string> = cfg.apiKey ? { Authorization: `Bearer ${cfg.apiKey}` } : {};
|
|
990
|
+
const lists = await Promise.all(
|
|
991
|
+
cfg.urls.map(async (url) => {
|
|
992
|
+
const baseUrl = url.replace(/\/(v1\/?)?$/, "") + "/v1";
|
|
993
|
+
try {
|
|
994
|
+
const { data } = (await (await fetch(`${baseUrl}/models`, { headers, signal: AbortSignal.timeout(3000) })).json()) as { data?: any[] };
|
|
995
|
+
return (data ?? [])
|
|
996
|
+
.filter((m) => m.owned_by === "ninfer")
|
|
997
|
+
.map((m) => {
|
|
998
|
+
// an older ninfer-serve publishes no capabilities: assume the Qwen effort template, text only
|
|
999
|
+
const levels: string[] = m.meta?.ninfer?.reasoning?.levels ?? ["low", "medium", "xhigh"];
|
|
1000
|
+
return {
|
|
1001
|
+
id: m.id,
|
|
1002
|
+
name: m.id,
|
|
1003
|
+
baseUrl,
|
|
1004
|
+
reasoning: levels.length > 0,
|
|
1005
|
+
input: m.architecture?.input_modalities?.includes("image") ? ["text", "image"] : ["text"],
|
|
1006
|
+
cost: { input: 0, output: 0, cacheRead: 0, cacheWrite: 0 },
|
|
1007
|
+
contextWindow: m.max_model_len,
|
|
1008
|
+
maxTokens: Math.min(32768, m.max_model_len),
|
|
1009
|
+
thinkingLevelMap: { off: "none", ...Object.fromEntries(PI_THINKING_LEVELS.map((l) => [l, levels.includes(l) ? l : null])) },
|
|
1010
|
+
};
|
|
1011
|
+
});
|
|
1012
|
+
} catch {
|
|
1013
|
+
return []; // server down or still loading: its model is simply not offered
|
|
1014
|
+
}
|
|
1015
|
+
}),
|
|
1016
|
+
);
|
|
1017
|
+
const models = lists.flat();
|
|
1018
|
+
if (!models.length) return;
|
|
1019
|
+
pi.registerProvider("ninfer", {
|
|
1020
|
+
api: "openai-completions",
|
|
1021
|
+
baseUrl: models[0]!.baseUrl,
|
|
1022
|
+
apiKey: cfg.apiKey || "ninfer", // a placeholder keeps the models listed when the server has no --api-key
|
|
1023
|
+
compat: {
|
|
1024
|
+
supportsDeveloperRole: false,
|
|
1025
|
+
supportsReasoningEffort: true,
|
|
1026
|
+
supportsUsageInStreaming: true,
|
|
1027
|
+
supportsStore: false,
|
|
1028
|
+
supportsStrictMode: false,
|
|
1029
|
+
maxTokensField: "max_tokens",
|
|
1030
|
+
},
|
|
1031
|
+
models,
|
|
1032
|
+
} as any);
|
|
1033
|
+
}
|
|
1034
|
+
|
|
960
1035
|
/** Models llama-swap keeps in memory: real id → "ready" | "starting" | … (empty when the server is unreachable). */
|
|
961
1036
|
async function swapRunning(): Promise<Map<string, string>> {
|
|
962
1037
|
try {
|
|
@@ -967,13 +1042,15 @@ async function swapRunning(): Promise<Map<string, string>> {
|
|
|
967
1042
|
}
|
|
968
1043
|
}
|
|
969
1044
|
|
|
970
|
-
/** Points the
|
|
1045
|
+
/** Points the monitor at the llama-swap or ninfer-serve behind `model`, without loading anything; false for other providers. */
|
|
971
1046
|
async function connectSwap(ctx: ExtensionContext, model: Model<any> | undefined): Promise<boolean> {
|
|
972
|
-
if (!model || model.provider !== "llama-swap" || !model.baseUrl) {
|
|
1047
|
+
if (!model || (model.provider !== "llama-swap" && model.provider !== "ninfer") || !model.baseUrl) {
|
|
973
1048
|
swap.base = "";
|
|
1049
|
+
swap.kind = "";
|
|
974
1050
|
setSwapState("off");
|
|
975
1051
|
return false;
|
|
976
1052
|
}
|
|
1053
|
+
swap.kind = model.provider;
|
|
977
1054
|
const id = model.id;
|
|
978
1055
|
swap.modelId = id;
|
|
979
1056
|
swap.realId = id;
|
|
@@ -986,6 +1063,7 @@ async function connectSwap(ctx: ExtensionContext, model: Model<any> | undefined)
|
|
|
986
1063
|
};
|
|
987
1064
|
void refreshSwapMetrics();
|
|
988
1065
|
void refreshSwapActivity();
|
|
1066
|
+
if (swap.kind === "ninfer") return true; // one model, no aliases
|
|
989
1067
|
const aliases = await swapAliases();
|
|
990
1068
|
if (swap.modelId !== id) return true;
|
|
991
1069
|
swap.realId = aliases.get(id) ?? id;
|
|
@@ -995,6 +1073,7 @@ async function connectSwap(ctx: ExtensionContext, model: Model<any> | undefined)
|
|
|
995
1073
|
/** Shows whether the session model is already in VRAM or asleep, without loading it: typing wakes it. */
|
|
996
1074
|
async function probeModel(ctx: ExtensionContext, model: Model<any> | undefined = ctx.model): Promise<void> {
|
|
997
1075
|
if (!(await connectSwap(ctx, model))) return;
|
|
1076
|
+
if (swap.kind === "ninfer") return refreshNinferHealth();
|
|
998
1077
|
const state = (await swapRunning()).get(swap.realId);
|
|
999
1078
|
if (swap.modelId === model!.id) setSwapState(state === "ready" ? "ready" : "asleep");
|
|
1000
1079
|
}
|
|
@@ -1005,6 +1084,7 @@ async function probeModel(ctx: ExtensionContext, model: Model<any> | undefined =
|
|
|
1005
1084
|
*/
|
|
1006
1085
|
async function preloadModel(ctx: ExtensionContext, model: Model<any> | undefined = ctx.model): Promise<void> {
|
|
1007
1086
|
if (!(await connectSwap(ctx, model))) return;
|
|
1087
|
+
if (swap.kind === "ninfer") return refreshNinferHealth(); // nothing to load: ninfer-serve starts with its model resident
|
|
1008
1088
|
const id = model!.id;
|
|
1009
1089
|
swap.expectedLoadMs = loadMagiConfig().loads?.[swap.realId] ?? LOAD_DEFAULT_MS;
|
|
1010
1090
|
|
|
@@ -1055,7 +1135,7 @@ function loadPrefixStore(): Record<string, any> {
|
|
|
1055
1135
|
|
|
1056
1136
|
/** Keeps the shared part of pi's real llama-swap request; written only when it changes (new tools, another thinking level…). */
|
|
1057
1137
|
function rememberPrefix(cwd: string, payload: any): void {
|
|
1058
|
-
if (
|
|
1138
|
+
if (swap.kind !== "llama-swap" || payload?.model !== swap.modelId || payload.messages?.[0]?.role !== "system") return;
|
|
1059
1139
|
const { stream, stream_options, max_tokens, max_completion_tokens, messages, ...options } = payload;
|
|
1060
1140
|
const body = { ...options, messages: [messages[0]] };
|
|
1061
1141
|
const json = JSON.stringify(body);
|
|
@@ -1437,7 +1517,7 @@ class MagiPanel implements Component {
|
|
|
1437
1517
|
private swapRows(inner: number, compact: boolean): string[] {
|
|
1438
1518
|
if (!swap.base) return [];
|
|
1439
1519
|
const th = this.theme;
|
|
1440
|
-
const out = [this.sep(inner, "LLAMA-SWAP")];
|
|
1520
|
+
const out = [this.sep(inner, swap.kind === "ninfer" ? "NINFER" : "LLAMA-SWAP")];
|
|
1441
1521
|
const st =
|
|
1442
1522
|
swap.state === "ready"
|
|
1443
1523
|
? th.fg("success", "IN VRAM")
|
|
@@ -1584,6 +1664,7 @@ type MagiConfig = Partial<Record<MagiUnit, MagiUnitConfig>> & {
|
|
|
1584
1664
|
loads?: Record<string, number>; // real model id → ms its last load took
|
|
1585
1665
|
totalWh?: number; // GPU energy summed over every session, for the COST row
|
|
1586
1666
|
hygiene?: Partial<HygieneOptions> & { enabled?: boolean }; // context pruning for local models, see local-models.ts
|
|
1667
|
+
ninfer?: { urls?: string[]; apiKey?: string }; // ninfer-serve servers to register as provider "ninfer"
|
|
1587
1668
|
thinkingBudget?: {
|
|
1588
1669
|
mode?: BudgetMode; // auto (learned per model) · fixed · off, set with /magi budget
|
|
1589
1670
|
planning?: number; // fixed budgets
|
|
@@ -2132,7 +2213,9 @@ function windowTitle(cwd: string, done = false): string {
|
|
|
2132
2213
|
return `${done ? "✓ " : ""}π - Magi - ${dir}`;
|
|
2133
2214
|
}
|
|
2134
2215
|
|
|
2135
|
-
export default function (pi: ExtensionAPI) {
|
|
2216
|
+
export default async function (pi: ExtensionAPI) {
|
|
2217
|
+
// before startup, like pi-llama-swap: --model and the saved session model must already find it
|
|
2218
|
+
await discoverNinfer(pi, loadMagiConfig().ninfer);
|
|
2136
2219
|
let chrome = true;
|
|
2137
2220
|
let panelEnabled = true;
|
|
2138
2221
|
let tuiRef: TUI | undefined;
|
|
@@ -2345,7 +2428,7 @@ export default function (pi: ExtensionAPI) {
|
|
|
2345
2428
|
applyChrome(ctx);
|
|
2346
2429
|
// nothing is loaded at startup: a new session picks its MECHA unit, a resumed one shows whether its model is in VRAM
|
|
2347
2430
|
const fresh = event.reason === "new" || (event.reason === "startup" && !ctx.sessionManager.getBranch().some((e) => e.type === "message"));
|
|
2348
|
-
void probeModel(ctx).then(() => (fresh && chrome && swap.
|
|
2431
|
+
void probeModel(ctx).then(() => (fresh && chrome && swap.kind === "llama-swap" ? pickModel(ctx) : undefined));
|
|
2349
2432
|
// GPU stats every 3s while something happens, every 30s when idle
|
|
2350
2433
|
metricsTimer ??= setInterval(() => {
|
|
2351
2434
|
const now = Date.now();
|
|
@@ -2647,7 +2730,7 @@ export default function (pi: ExtensionAPI) {
|
|
|
2647
2730
|
if (UI_ARGS.test(arg)) return manageUi(arg, ctx);
|
|
2648
2731
|
if (arg === "config") return configureMagi(ctx);
|
|
2649
2732
|
if (arg === "mecha") {
|
|
2650
|
-
if (ctx.mode !== "tui" ||
|
|
2733
|
+
if (ctx.mode !== "tui" || swap.kind !== "llama-swap") return ctx.ui.notify("MECHA SELECT needs the TUI and a llama-swap model", "error");
|
|
2651
2734
|
liveCtx = ctx;
|
|
2652
2735
|
return pickModel(ctx);
|
|
2653
2736
|
}
|
|
@@ -2745,7 +2828,7 @@ export default function (pi: ExtensionAPI) {
|
|
|
2745
2828
|
? "Thinking budget off: llama-server decides. /magi budget auto"
|
|
2746
2829
|
: `Thinking budget ${budgetMode.toUpperCase()} · ${model || "no model"}: ${phase("planning")} · ${phase("acting")}` +
|
|
2747
2830
|
` · closing message ${budgetMessage ? "on" : "off"}` +
|
|
2748
|
-
(swap.base ? "" : " · applies to llama-swap models only") +
|
|
2831
|
+
(swap.base ? "" : " · applies to llama-swap and ninfer models only") +
|
|
2749
2832
|
(budgetIgnored.has(model) ? " · ⚠ llama-server thinks past it: it was started with its own --reasoning-budget (or is too old), which wins" : ""),
|
|
2750
2833
|
"info",
|
|
2751
2834
|
);
|
|
@@ -2790,8 +2873,8 @@ export default function (pi: ExtensionAPI) {
|
|
|
2790
2873
|
return;
|
|
2791
2874
|
}
|
|
2792
2875
|
if (arg === "status") {
|
|
2793
|
-
if (
|
|
2794
|
-
ctx.ui.notify("/magi status needs a llama-swap session model", "warning");
|
|
2876
|
+
if (swap.kind !== "llama-swap") {
|
|
2877
|
+
ctx.ui.notify("/magi status needs a llama-swap session model (ninfer-serve keeps no request history)", "warning");
|
|
2795
2878
|
return;
|
|
2796
2879
|
}
|
|
2797
2880
|
let report: { data?: ActivityRow[]; total?: number };
|
package/package.json
CHANGED
|
@@ -1,7 +1,7 @@
|
|
|
1
1
|
{
|
|
2
2
|
"name": "pi-magi-theme",
|
|
3
|
-
"version": "0.3.
|
|
4
|
-
"description": "MAGI SYSTEM theme + extension for pi (Evangelion fan art): MAGI control screen panel, three-model /magi council, MECHA SELECT model picker, angel-attack loading, seven-seal context gauge, llama-swap telemetry",
|
|
3
|
+
"version": "0.3.2",
|
|
4
|
+
"description": "MAGI SYSTEM theme + extension for pi (Evangelion fan art): MAGI control screen panel, three-model /magi council, MECHA SELECT model picker, angel-attack loading, seven-seal context gauge, llama-swap and NInfer telemetry",
|
|
5
5
|
"keywords": [
|
|
6
6
|
"pi-package",
|
|
7
7
|
"pi-extension",
|
|
@@ -9,7 +9,8 @@
|
|
|
9
9
|
"pi",
|
|
10
10
|
"magi",
|
|
11
11
|
"evangelion",
|
|
12
|
-
"llama-swap"
|
|
12
|
+
"llama-swap",
|
|
13
|
+
"ninfer"
|
|
13
14
|
],
|
|
14
15
|
"author": "b-iurea",
|
|
15
16
|
"license": "MIT",
|