pi-context-guard-jev 0.2.0 → 0.3.2
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.md +111 -409
- package/docs/CACHE.md +5 -1
- package/docs/DESIGN.md +60 -24
- package/docs/REFERENCE.md +164 -0
- package/docs/RESULTS.md +146 -0
- package/docs/TESTING.md +29 -10
- package/package.json +2 -2
- package/src/checkpoint.ts +39 -16
- package/src/config.ts +8 -1
- package/src/images.ts +89 -0
- package/src/index.ts +87 -34
- package/src/items.ts +13 -14
- package/src/process.ts +45 -0
- package/src/recall.ts +44 -11
- package/src/render.ts +2 -0
- package/src/run.ts +71 -11
- package/src/size.ts +114 -0
- package/src/stats.ts +50 -18
- package/src/types.ts +2 -0
package/README.md
CHANGED
|
@@ -1,374 +1,38 @@
|
|
|
1
1
|
# pi-context-guard-jev
|
|
2
2
|
|
|
3
|
-
|
|
4
|
-
|
|
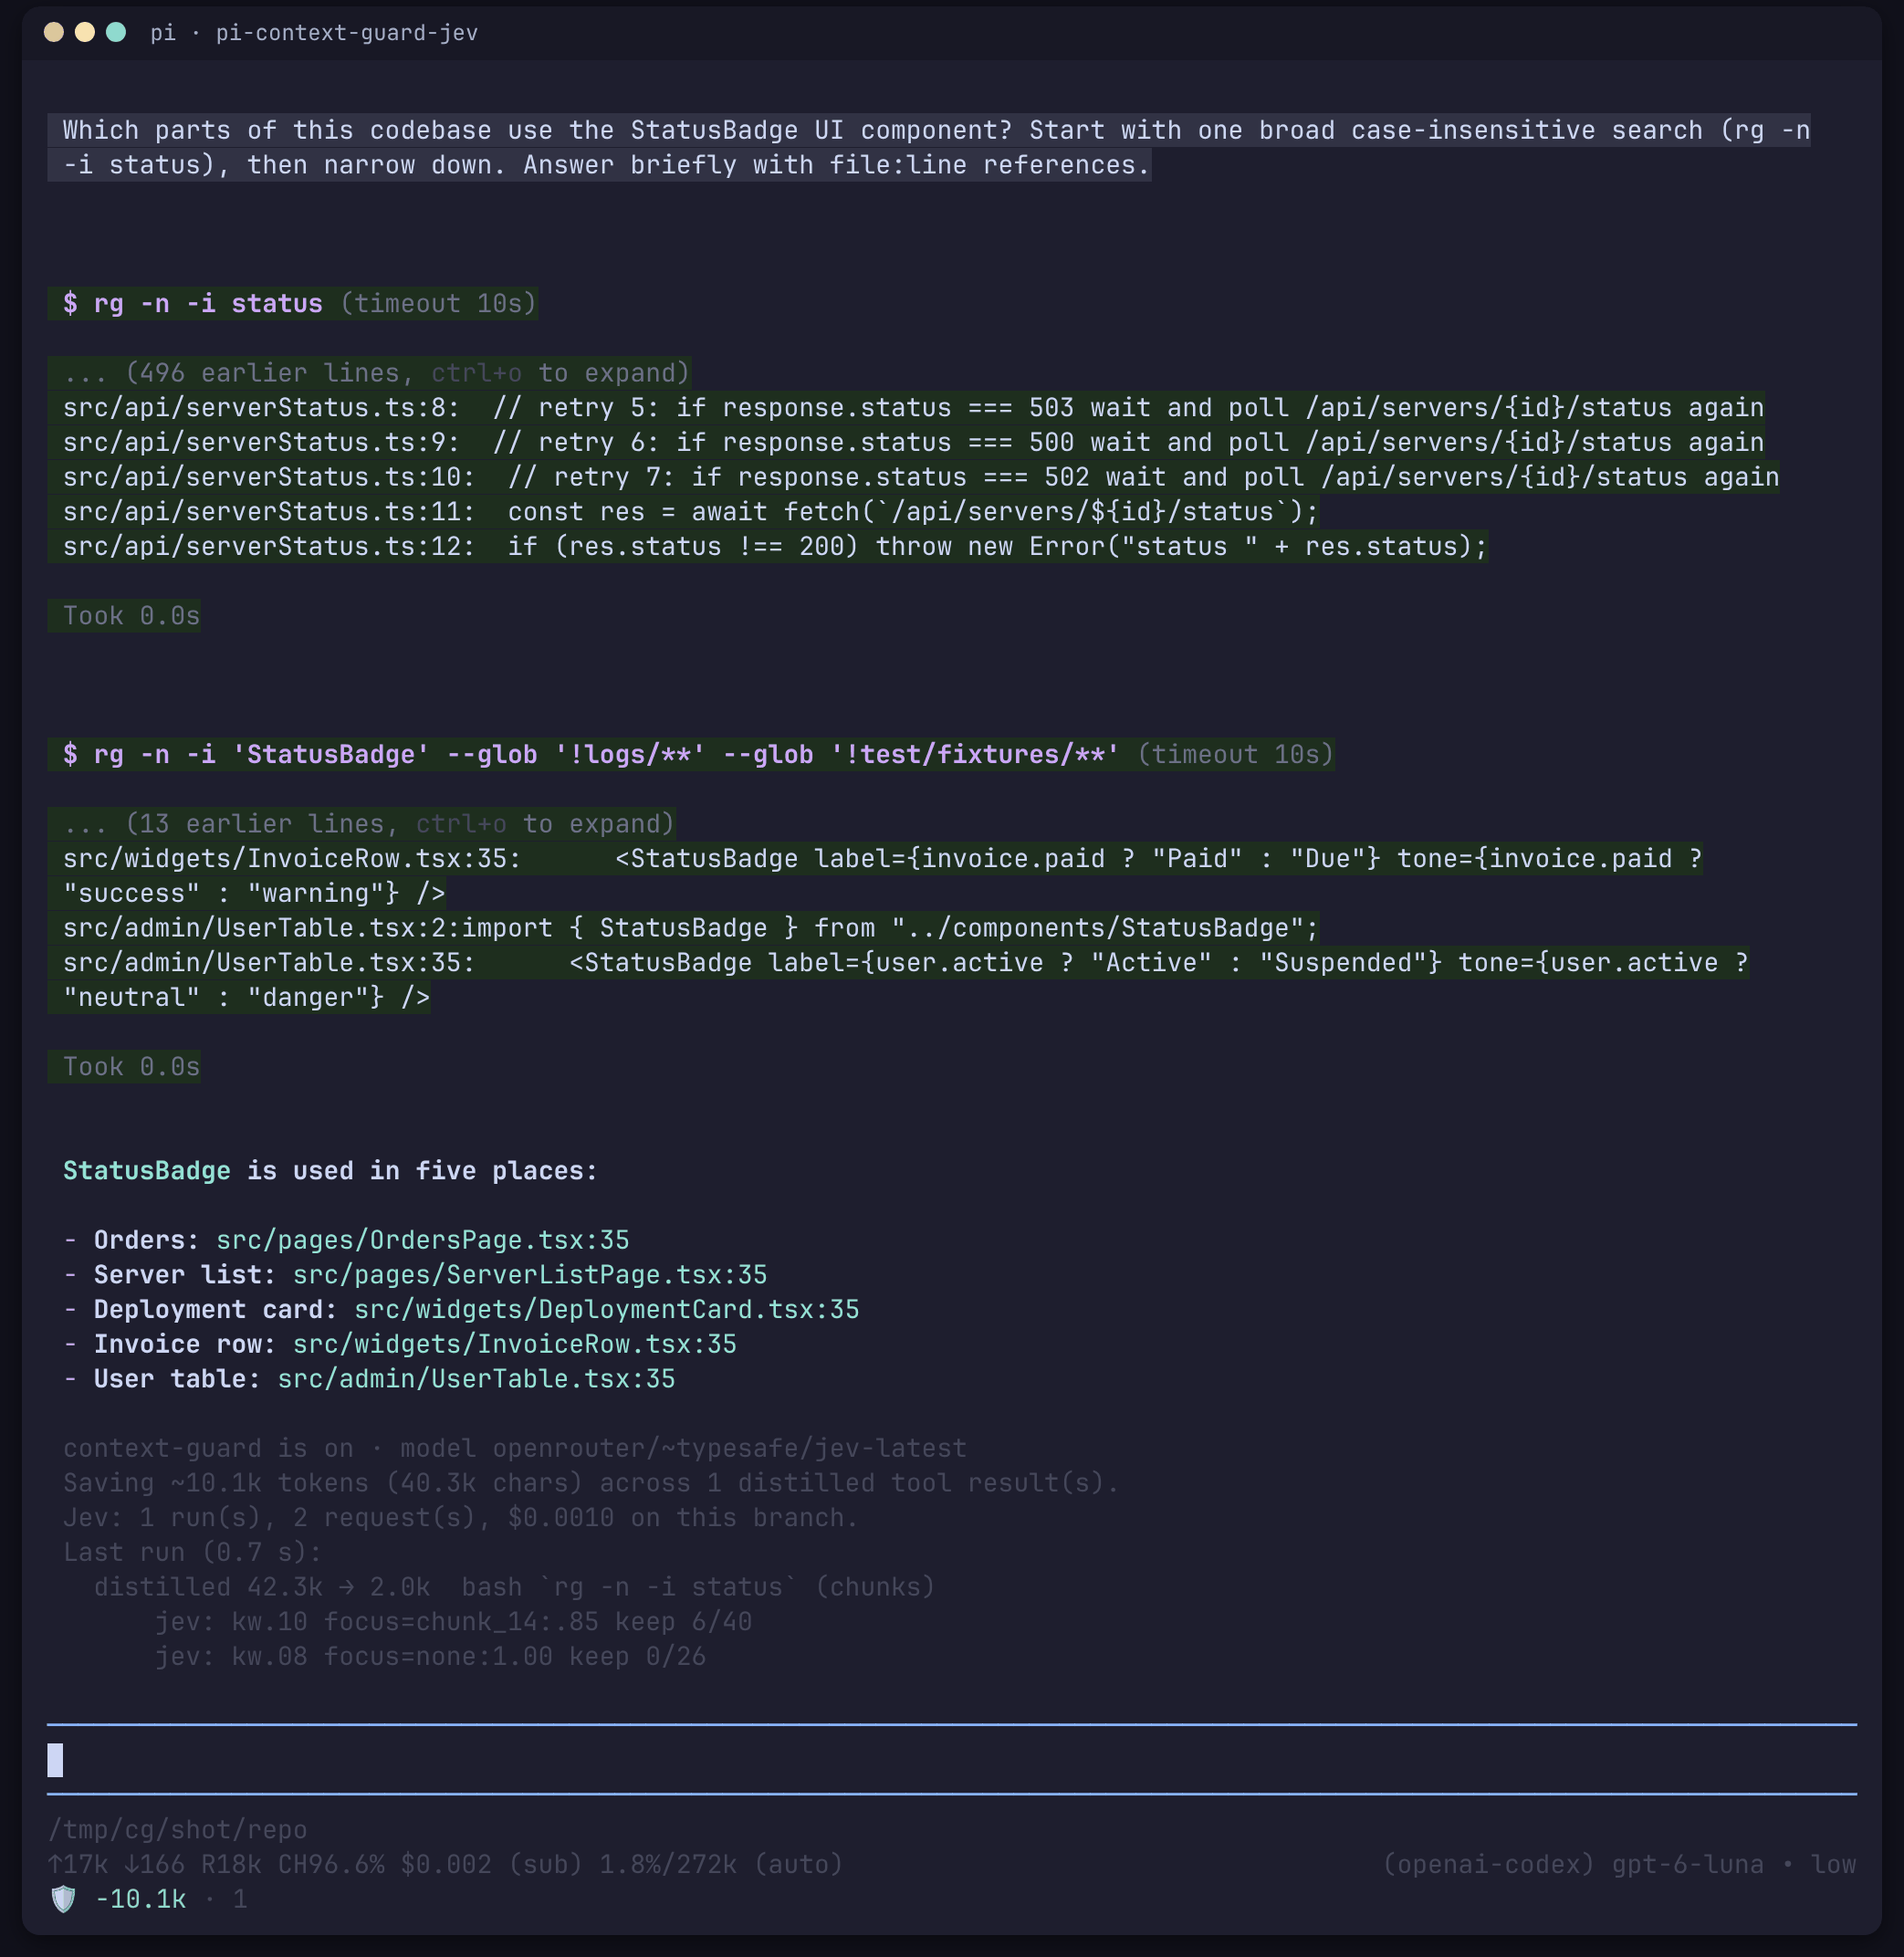
3
|
+
A [Pi](https://github.com/earendil-works/pi) extension that removes tool output your agent no longer needs
|
|
4
|
+
from its context. The Jev classifier decides which lines to keep. Kept lines are copied verbatim, and the
|
|
5
|
+
model can `recall` anything that was removed.
|
|
5
6
|
|
|
6
|
-
, the next request carried
|
|
26
|
-
**9.2k instead of 35.3k tokens** after reading a 164 KB file, **11.5k instead of 34.3k** after a code
|
|
27
|
-
search, and **5.7k instead of 7.5k** after a failing test run. In an autonomous 30-request bug-fixing
|
|
28
|
-
run, the context peaked at **45k instead of 68–88k tokens** ([Long autonomous runs](#long-autonomous-runs)).
|
|
29
|
-
Every follow-up and every task still succeeded.
|
|
30
|
-
- **Verbatim, never rewritten.** Jev is a classifier: it answers yes/no and multiple-choice questions and
|
|
31
|
-
does not write text. Kept lines are copied byte for byte, and each removed stretch becomes one line that
|
|
32
|
-
says what was there (`[… 79 lines omitted: matches in dist/core/tools/grep.js, …]`). Small outputs and
|
|
33
|
-
earlier exchanges that are no longer needed are removed whole and leave a one-line note. Unlike a
|
|
34
|
-
summary, nothing the model sees afterwards is paraphrased or invented.
|
|
35
|
-
- **Nothing is lost.** The original stays in the session file. The model can `recall` it (whole, by
|
|
36
|
-
regex, or by line range), including a whole omitted exchange, and `/tree` back to before the edit
|
|
37
|
-
restores it.
|
|
38
|
-
- **Judged against the work, not by size.** Truncation and size limits can't tell a needed line from
|
|
39
|
-
noise. Jev sees the task, the agent's progress or final answer, and the earlier conversation, and decides
|
|
40
|
-
per chunk, per small output and per earlier exchange, so what the ongoing task needs survives. A failed
|
|
41
|
-
command the agent already got past, or a file read made stale by a later edit, goes.
|
|
42
|
-
- **Works during long autonomous runs and in subagents.** Besides the end of each run, it checkpoints
|
|
43
|
-
during long runs, once old output has piled up, so a 2-hour run or a long worker doesn't carry
|
|
44
|
-
everything until it ends.
|
|
45
|
-
- **Cheap, and careful with the prompt cache.** Jev costs $0.0003–0.007 and 0.6–2 s per pass (measured).
|
|
46
|
-
Edits are batched and made only when the smaller context pays for the prompt-cache rewrite they cause.
|
|
47
|
-
On Anthropic, cache breakpoints keep everything before the first edit readable from cache. Tested with
|
|
48
|
-
Claude Sonnet 5.5 and GPT-6 Luna.
|
|
49
|
-
- **You can see what it does.** The footer shows `🛡 −10.1k · 1`. `/guard` lists every decision with Jev's
|
|
50
|
-
probabilities, and `/guard off` turns it off for good.
|
|
51
|
-
|
|
52
|
-
**Trade-offs:**
|
|
53
|
-
- **It sends data to a third party.** Tool output and conversation excerpts go to OpenRouter and TypeSafe
|
|
54
|
-
([Privacy](#privacy)).
|
|
55
|
-
- **It can cost a little more in short sessions.** The first request after an edit rewrites part of the
|
|
56
|
-
prompt cache, so the first gain is context room; the bill shrinks only in longer sessions
|
|
57
|
-
([Examples](#examples-measured)).
|
|
58
|
-
- **Follow-ups may need `recall`.** A question that goes back to something removed makes the model recall
|
|
59
|
-
it or search again.
|
|
60
|
-
|
|
61
|
-
## How it works
|
|
62
|
-
|
|
63
|
-
1. **A run finishes.** When Pi is about to settle a completed run (`agent_before_settle`), the extension
|
|
64
|
-
looks at the tool outputs of that run (everything after the last user message) and at earlier
|
|
65
|
-
exchanges (steps 6 and 7). Long runs also get checkpoints before they end
|
|
66
|
-
([Long autonomous runs](#long-autonomous-runs)).
|
|
67
|
-
2. **It picks large outputs.** These are text-only tool results of at least 4,000 characters, including
|
|
68
|
-
the output of failed commands. They are skipped if they add up to less than 8,000 characters.
|
|
69
|
-
3. **It chunks each output.** grep-style output is grouped by file. Other output is cut into windows of
|
|
70
|
-
roughly 0.8–4k characters, with breaks at blank lines where possible.
|
|
71
|
-
4. **It sends one Jev request per segment** (up to 32,000 characters and 40 chunks). Each request asks three
|
|
72
|
-
kinds of question about the user's question and the final answer, and, when there is one, the earlier
|
|
73
|
-
conversation of the session (so output that the ongoing work still needs is kept even if this run's
|
|
74
|
-
question was about something else):
|
|
75
|
-
- `keep_whole`: is all of this output still needed?
|
|
76
|
-
- `focus`: does the answer use most of it, none of it, or a few chunks (and if so, which one matters most)?
|
|
77
|
-
- one yes/no question per chunk: is this chunk needed?
|
|
78
|
-
5. **It writes a `context_edit` per result.** The edit keeps the needed chunks verbatim, replaces each run of
|
|
79
|
-
removed chunks with an omission line, and starts with a header that tells the model how to
|
|
80
|
-
`recall` the full output. If the kept part would still be more than 60% of the original, the result is
|
|
81
|
-
left as it is.
|
|
82
|
-
6. **Small outputs** (400 characters up to the 4,000-character limit) are judged as whole items, many per
|
|
83
|
-
Jev request: "will the agent still need this output?" An output that is not needed becomes
|
|
84
|
-
`[context-guard] Omitted the output of bash `…` (1.2k chars): judged no longer needed. Full output: recall(…).`
|
|
85
|
-
7. **Old exchanges** (a user prompt and everything up to the next prompt: replies, tool calls and results,
|
|
86
|
-
custom messages) from earlier, finished runs are judged against the current work, several per request:
|
|
87
|
-
"is this earlier exchange still relevant?" The last 2 exchanges before the current prompt are never
|
|
88
|
-
touched. An unrelated exchange keeps a one-line note on its prompt
|
|
89
|
-
(`[context-guard] Omitted an earlier exchange judged unrelated to the current work: "…" (N messages, ~Mk tokens). Full exchange: recall(…).`)
|
|
90
|
-
and every other entry of it is omitted (`replacement: null`), so tool calls and their results always go
|
|
91
|
-
together. Exchanges with images, with entries another extension changed, or under 2,000 characters
|
|
92
|
-
are not judged. An omission early in the session makes the next request rewrite the prompt cache
|
|
93
|
-
from there, so at run end it happens only when it pays off over as many later requests as the session
|
|
94
|
-
has had so far and saves at least 8,000 characters (`exchangeBreakEven`); otherwise the exchanges
|
|
95
|
-
wait, and are judged again at later run ends until their total pays off. All three kinds are judged
|
|
96
|
-
in parallel, at most `concurrency` (6) Jev requests at a time.
|
|
97
|
-
|
|
98
|
-
During long runs, **mid-run checkpoints** do the same for older items before the run ends (next
|
|
99
|
-
section).
|
|
100
|
-
|
|
101
|
-
Errors, timeouts and unclear answers always mean *keep*. For the full algorithm, see
|
|
102
|
-
[docs/DESIGN.md](docs/DESIGN.md).
|
|
103
|
-
|
|
104
|
-
## Long autonomous runs
|
|
105
|
-
|
|
106
|
-
Run-end distillation helps the *next* prompt. A 30–120 minute autonomous run (the main agent or a long
|
|
107
|
-
worker) would still carry every tool output until it ends, and Pi compacts only near the window
|
|
108
|
-
minus 16k tokens. So, while a run is going, the extension also checkpoints:
|
|
109
|
-
|
|
110
|
-
1. **At a turn boundary** (`turn_end`; Pi applies the edit to the very next request, before its compaction
|
|
111
|
-
check), large and small outputs of the current run that are at least `midRunMinAgeTurns` (4) turns old
|
|
112
|
-
and not judged before are eligible, and so are old exchanges not judged during this run. The final turn
|
|
113
|
-
of a run is left to run-end distillation.
|
|
114
|
-
2. **In batches:** a checkpoint runs only when the eligible items add up to `midRunBatchChars` (60,000)
|
|
115
|
-
characters, so edits, and the cache rewrites they cause, are rare.
|
|
116
|
-
3. **Only when it pays:** an edit makes the next request rewrite the prompt cache once (OpenAI Codex: the
|
|
117
|
-
whole context; Anthropic: everything after the latest cache entry it can still read, at worst after the
|
|
118
|
-
question). The break-even rule
|
|
119
|
-
(`midRunBreakEven`) skips a checkpoint unless the expected saving over the rest of the run covers that.
|
|
120
|
-
Old exchanges come early in the context, so they move the rewrite back to the start; if the batch with
|
|
121
|
-
them does not pay off, the checkpoint runs on the tool outputs alone, and the exchanges wait for run end.
|
|
122
|
-
4. **Jev gets a checkpoint question:** no final answer exists yet, so it sees the task, the agent's latest
|
|
123
|
-
notes, the tool calls made since this output, and whether the output was superseded (the file was
|
|
124
|
-
edited afterwards, or the same command ran again). It answers whether the agent will still need each
|
|
125
|
-
chunk to finish. Each output is judged mid-run at most once; run-end distillation judges the rest,
|
|
126
|
-
including outputs kept at a checkpoint, with the final answer.
|
|
127
|
-
5. **On Anthropic** the previous question stays pinned, and the first request after a checkpoint also gets
|
|
128
|
-
a breakpoint at the latest cache entry this process wrote before the first edited output, so the
|
|
129
|
-
unchanged part of the run is still read from cache.
|
|
130
|
-
|
|
131
|
-
**Measured** (Pi 1.0.3, e2e scenario `long`: "fix all failing tests" in a generated project with 10 bugs,
|
|
132
|
-
the full suite after every fix; single runs, not a benchmark; costs are what Pi reports at list price):
|
|
133
|
-
|
|
134
|
-
| Main model | Configuration | Requests | Peak context | Main-model cost | Checkpoints (Jev) | Suite green |
|
|
135
|
-
|---|---|---|---|---|---|---|
|
|
136
|
-
| GPT-6 Luna | guard off | 32 / 37 | 68.4k / 87.7k | $0.020 / $0.030 | – | yes / yes |
|
|
137
|
-
| GPT-6 Luna | `midRun: false` (run end only) | 26 | 86.3k | $0.022 | – (run end $0.006) | yes |
|
|
138
|
-
| GPT-6 Luna | default | 29 | **45.0k** | $0.021 | 2 at requests 16 and 24, 0.8 s each, removed 62k and 60k chars ($0.006 with run end) | yes |
|
|
139
|
-
| GPT-6 Luna | `smallResultMinChars: 0` (large outputs only) | 31 | 72.4k | $0.024 | 1 at request 19, 1.0 s, removed 154k chars ($0.007 with run end) | yes |
|
|
140
|
-
| Claude Sonnet 5.5 | guard off | 14 | 89.8k | $0.41 | – | yes |
|
|
141
|
-
| Claude Sonnet 5.5 | `smallResultMinChars: 0` | 8 | 65.7k | $0.24 | none: too short to pay off (run end $0.003) | yes |
|
|
142
|
-
| Claude Sonnet 5.5 | forced: `midRunBreakEven: false`, `midRunMinAgeTurns: 2`, `midRunBatchChars: 20000`, `smallResultMinChars: 0` | 12 | 43.3k | $0.34 | 3 ($0.0032 with run end) | yes |
|
|
143
|
-
|
|
144
|
-
Context per request (every 5th request), GPT-6 Luna:
|
|
145
|
-
|
|
146
|
-
| Request | 1 | 6 | 11 | 16 | 21 | 26 | 31 | 36 |
|
|
147
|
-
|---|---|---|---|---|---|---|---|---|
|
|
148
|
-
| guard off (37 requests) | 3.0k | 14.6k | 29.3k | 41.4k | 52.1k | 62.5k | 73.3k | 83.4k |
|
|
149
|
-
| default (29 requests) | 3.2k | 17.0k | 35.3k | 41.0k | 39.3k | 28.9k | – | – |
|
|
150
|
-
|
|
151
|
-
At the default run's first checkpoint, Jev distilled four superseded test logs (for example 30,164 → 8,163)
|
|
152
|
-
and replaced 4 of 7 small reads of files the agent had already edited with one-line notes (for example
|
|
153
|
-
3,386 → 145); the next request carried 20.1k instead of 41.0k tokens. No run needed `recall`.
|
|
154
|
-
|
|
155
|
-
**Trade-offs:**
|
|
156
|
-
- **OpenAI Codex reads nothing from cache after any edit** (2,560 or 0 tokens on the next request, after
|
|
157
|
-
every checkpoint measured, wherever the edit was). Each checkpoint re-sends the context uncached once and
|
|
158
|
-
pays back after about 8–10 later requests. In these 26–37-request runs the main-model cost came out
|
|
159
|
-
about the same with and without checkpoints, plus about $0.005 of Jev per run; the gain is a smaller
|
|
160
|
-
context.
|
|
161
|
-
- **On Anthropic a checkpoint rewrites the cache after the latest entry the next request can read** (at worst after the question; writing costs 12.5× the read price).
|
|
162
|
-
In the forced run, the requests after the three checkpoints read 5.8k / 16.7k / 16.7k tokens and wrote
|
|
163
|
-
10.9k / 22.8k / 20.0k. After the first checkpoint of a run only the system prompt and question can be
|
|
164
|
-
read, because the run's first output is usually the first one edited. Claude solved the task in 8–14
|
|
165
|
-
requests, too few for a checkpoint to pay off, so with the default break-even rule it never
|
|
166
|
-
checkpointed; forced checkpoints in such short runs cost more than they saved. Checkpoints are meant
|
|
167
|
-
for runs that go on for dozens of requests.
|
|
168
|
-
- **Latency mid-run:** a checkpoint pauses the run for the Jev requests (0.5–2.2 s measured, at most
|
|
169
|
-
`timeoutMs`).
|
|
170
|
-
- Details: [docs/CACHE.md](docs/CACHE.md#mid-run-checkpoints), [docs/DESIGN.md](docs/DESIGN.md#mid-run-checkpoints),
|
|
171
|
-
wording probe in [docs/JEV.md](docs/JEV.md#checkpoint-wording).
|
|
7
|
+
|
|
172
8
|
|
|
173
9
|
## Install
|
|
174
10
|
|
|
175
11
|
```bash
|
|
176
12
|
pi install npm:pi-context-guard-jev
|
|
177
|
-
# or from GitHub
|
|
178
|
-
pi install git:github.com/alandarev/pi-context-guard-jev
|
|
179
|
-
# or, for development, load it for one session from a checkout
|
|
180
|
-
pi -e ./src/index.ts
|
|
181
13
|
```
|
|
182
14
|
|
|
183
|
-
|
|
184
|
-
|
|
185
|
-
- Pi ≥ 1.0.3
|
|
186
|
-
- An OpenRouter credential (`OPENROUTER_API_KEY` or `/login`) for the default classifier,
|
|
187
|
-
`openrouter/~typesafe/jev-latest`. Any classifier model in Pi's catalog can be set with the `model`
|
|
188
|
-
setting, but only the default has been tested.
|
|
15
|
+
Requires Pi ≥ 1.0.3 and an OpenRouter credential (`OPENROUTER_API_KEY` or `/login`). Once it is ready, the
|
|
16
|
+
footer shows `🛡 0 saved`.
|
|
189
17
|
|
|
190
|
-
|
|
18
|
+
## What it removes
|
|
191
19
|
|
|
192
|
-
|
|
193
|
-
|
|
194
|
-
**This extension sends data to a third party, and it is on by default.** After every run that qualifies,
|
|
195
|
-
each Jev request sends the following to OpenRouter, which forwards it to TypeSafe:
|
|
196
|
-
|
|
197
|
-
- the user's question (up to 4,000 characters),
|
|
198
|
-
- the final answer (up to 6,000 characters),
|
|
199
|
-
- the assistant's notes written during the run (up to 2,000 characters),
|
|
200
|
-
- excerpts of the earlier conversation in this session: the latest compaction or branch summary (up to
|
|
201
|
-
2,000 characters), the first prompt (up to 1,000), and the last 3 earlier exchanges, each one prompt (up to
|
|
202
|
-
800) and the last assistant text after it (up to 1,200). Tool calls and tool outputs of earlier runs are not
|
|
203
|
-
included in this part. Set `historyExchanges` to `0` to send none of it,
|
|
204
|
-
- the tool name and arguments,
|
|
205
|
-
- the full text of the large tool output being judged, and of small outputs (from 400 characters; up to
|
|
206
|
-
4,000 characters each). This can include source code, logs or anything else the tools returned,
|
|
207
|
-
- excerpts of old exchanges being judged: each prompt (up to 600 characters), the last assistant text (up to
|
|
208
|
-
800), the tool calls as short labels (tool name and the command or path, up to 80 characters each) and the
|
|
209
|
-
size. Set `pruneExchanges` to `false` to send none of it.
|
|
210
|
-
|
|
211
|
-
Never sent: tool outputs below `smallResultMinChars` (400 characters), results of excluded tools (`edit`,
|
|
212
|
-
`write`), outputs with images, old exchanges with images or with entries another extension changed,
|
|
213
|
-
exchanges below 2,000 characters, and the last `keepRecentExchanges` (2) exchanges before the current
|
|
214
|
-
prompt. Large outputs are sent only when the run's large outputs add up to `minRunChars` (8,000); small
|
|
215
|
-
outputs and old exchanges are sent at every run end and every mid-run checkpoint that has any.
|
|
216
|
-
|
|
217
|
-
`/guard off` turns the extension off and saves that choice in the settings file, so it stays off in later
|
|
218
|
-
sessions. See OpenRouter's data policy:
|
|
219
|
-
<https://openrouter.ai/docs/guides/privacy/data-collection>.
|
|
220
|
-
|
|
221
|
-
## Status bar
|
|
222
|
-
|
|
223
|
-
| Text | Meaning |
|
|
224
|
-
|---|---|
|
|
225
|
-
| `🛡 0 saved` | On and ready; nothing is distilled on this branch yet |
|
|
226
|
-
| `🛡 distilling…` | Jev is judging the outputs of the run that just finished, or of a mid-run checkpoint |
|
|
227
|
-
| `🛡 −4.2k · 1` | ≈ tokens kept out of context · items: about 4.2k tokens are currently kept out of context, by 1 distilled or omitted tool output or old exchange |
|
|
228
|
-
| `🛡 guard off` | Turned off with `/guard off` or `"enabled": false` |
|
|
229
|
-
| `🛡 no openrouter key` | No credential for the classifier's provider (the provider name is filled in) |
|
|
230
|
-
| `🛡 Jev model not found` | The configured `model` is not in Pi's classifier catalog |
|
|
231
|
-
|
|
232
|
-
The token figure is Pi's usual estimate, characters ÷ 4. It counts what is kept out of the model's context
|
|
233
|
-
**on the current branch right now**: original length minus replacement length, for every distilled output
|
|
234
|
-
and omitted exchange that is still in the context. It goes down after `/tree` to a point before an edit, and after compaction
|
|
235
|
-
removes distilled results. It is not a measured token count and not a cumulative total.
|
|
236
|
-
|
|
237
|
-
## `/guard` command
|
|
238
|
-
|
|
239
|
-
| Command | Effect |
|
|
240
|
-
|---|---|
|
|
241
|
-
| `/guard` or `/guard status` | Shows whether the guard is on, the model, the savings on this branch (distilled outputs and omitted exchanges), Jev runs and mid-run checkpoints, requests and cost, whether checkpoints and exchange pruning are on, and the last run's or checkpoint's result for each item (large, small, exchange), including Jev traces such as `kw.15 focus=chunk_4:.52 keep 9/29` or `p.06` |
|
|
242
|
-
| `/guard on` / `/guard off` | Turns the guard on or off and saves `enabled` to the settings file |
|
|
243
|
-
| `/guard reload` | Re-reads the settings file and shows any warnings again |
|
|
244
|
-
|
|
245
|
-
Settings are read at session start and on `/guard reload`.
|
|
246
|
-
|
|
247
|
-
## `recall` tool
|
|
248
|
-
|
|
249
|
-
Every distilled output and omitted exchange starts with `[context-guard]` and ends with
|
|
250
|
-
`recall({"entryId":"…"})`. For an omitted exchange, recall returns the whole exchange as a transcript
|
|
251
|
-
(prompt, replies, tool calls and results, custom messages). The model can call:
|
|
252
|
-
|
|
253
|
-
| Parameter | Meaning |
|
|
254
|
-
|---|---|
|
|
255
|
-
| `entryId` (required) | The entry id from the header |
|
|
256
|
-
| `pattern` | JavaScript regex (≤ 500 chars, 1 s limit); returns only matching lines, prefixed with their line numbers |
|
|
257
|
-
| `offset` | First line to return, 1-based. When `pattern` is set, this counts matching lines. |
|
|
258
|
-
| `limit` | Most lines to return |
|
|
259
|
-
|
|
260
|
-
Like Pi's `read` tool, the output is capped at 2,000 lines and 50 KB, and a note says how to continue.
|
|
261
|
-
|
|
262
|
-
## Configuration
|
|
263
|
-
|
|
264
|
-
The settings file is `~/.pi/agent/context-guard.json` (inside Pi's agent directory), or the path in
|
|
265
|
-
`PI_CONTEXT_GUARD_CONFIG`. Every key is optional. Values that are missing, the wrong type or out of range
|
|
266
|
-
fall back to the default.
|
|
267
|
-
|
|
268
|
-
| Key | Default | Meaning |
|
|
20
|
+
| Item | Rule | The model then sees |
|
|
269
21
|
|---|---|---|
|
|
270
|
-
|
|
|
271
|
-
|
|
|
272
|
-
|
|
|
273
|
-
|
|
|
274
|
-
| `keepWholeThreshold` | `0.7` | Keep a segment untouched if P(`keep_whole`) is at least this |
|
|
275
|
-
| `focusWholeThreshold` | `0.6` | Keep a segment untouched if `focus` picks "whole" with at least this probability |
|
|
276
|
-
| `chunkKeepThreshold` | `0.6` | Keep a chunk if P(chunk needed) is at least this |
|
|
277
|
-
| `noneThreshold` | `0.5` | Remove a segment entirely if `focus` picks "none" with at least this probability and no chunk passes |
|
|
278
|
-
| `maxKeepRatio` | `0.6` | Skip the edit if the kept chunks are more than this fraction of the original |
|
|
279
|
-
| `keepCitedFiles` | `false` | Also keep grep chunks for files that the final answer names (see DESIGN.md for why it is off) |
|
|
280
|
-
| `timeoutMs` | `8000` | Total time budget for all Jev requests of one run; unfinished parts are kept |
|
|
281
|
-
| `concurrency` | `6` | Jev requests in parallel |
|
|
282
|
-
| `maxSegmentChars` | `32000` | Most characters of one output per Jev request (keeps the worst-case request under Jev's 32k-token context, see docs/JEV.md) |
|
|
283
|
-
| `maxChunksPerSegment` | `40` | Most chunks per Jev request |
|
|
284
|
-
| `excludeTools` | `["edit", "write"]` | Tools whose results are never distilled |
|
|
285
|
-
| `distillErrors` | `true` | Also distill error results, such as the log of a failing test or build; Jev is told the call failed, and that its details are usually no longer needed once the agent got past it |
|
|
286
|
-
| `historyExchanges` | `3` | Earlier exchanges (prompt + last assistant text) sent to Jev so it judges relevance against the ongoing work; `0` sends no earlier conversation at all (integer 0–10) |
|
|
287
|
-
| `pinAnthropicCache` | `true` | Anthropic cache breakpoints: at the previous user question on every request, and on the first request after context edits a read point (at a cache entry this process wrote) and a write anchor ([docs/CACHE.md](docs/CACHE.md)) |
|
|
288
|
-
| `midRun` | `true` | Mid-run checkpoints during long runs ([Long autonomous runs](#long-autonomous-runs)) |
|
|
289
|
-
| `midRunMinAgeTurns` | `4` | Judge an output mid-run only once it is at least this many turns old (integer 1–100) |
|
|
290
|
-
| `midRunBatchChars` | `60000` | Run a checkpoint only when the not-yet-judged eligible outputs add up to this many characters |
|
|
291
|
-
| `midRunBatchCharsOpenAI` | `60000` | The same, for `openai-codex` models |
|
|
292
|
-
| `midRunChunkKeepThreshold` | `0.6` | Keep a chunk at a checkpoint if P(still needed) is at least this (probe in docs/JEV.md) |
|
|
293
|
-
| `midRunBreakEven` | `true` | Skip a checkpoint unless its one-time prompt-cache rewrite is likely to pay off; `false` checkpoints purely for context room |
|
|
294
|
-
| `smallResultMinChars` | `400` | Tool results from this size up to `minResultChars` are judged as whole items; `0` turns this off |
|
|
295
|
-
| `smallKeepThreshold` | `0.45` | Keep a small output if P(still needed) is at least this (probe in docs/JEV.md) |
|
|
296
|
-
| `pruneExchanges` | `true` | Judge old exchanges and omit the unrelated ones |
|
|
297
|
-
| `keepRecentExchanges` | `2` | The last this many exchanges before the current prompt are never omitted |
|
|
298
|
-
| `exchangeOmitThreshold` | `0.2` | Omit an exchange only if P(still relevant) is below this (probe in docs/JEV.md) |
|
|
299
|
-
| `exchangeBreakEven` | `true` | At run end, omit unrelated exchanges only when the cache rewrite they cause pays off; deferred ones are judged again at later run ends and omitted once their total pays off. `false` always omits them |
|
|
300
|
-
| `exchangeMinSavingChars` | `8000` | A run end omits exchanges only if they save at least this many characters together (when they cost a cache rewrite) |
|
|
301
|
-
|
|
302
|
-
Example:
|
|
22
|
+
| Large tool output (≥ 4k chars) | Jev keeps the chunks the work still needs | The kept lines, verbatim, and one line per removed stretch |
|
|
23
|
+
| Small tool output (400–4k chars) | Jev: is it still needed? | A one-line note |
|
|
24
|
+
| Earlier exchange about another task | Jev: is it still relevant? | A one-line note on its prompt |
|
|
25
|
+
| Image in a tool result | After 3 turns (no Jev call) | The result's text and a one-line note |
|
|
303
26
|
|
|
304
|
-
|
|
305
|
-
|
|
306
|
-
|
|
27
|
+
The extension runs when a run finishes. In long runs it also runs mid-run, once enough old output has piled
|
|
28
|
+
up. An edit makes the next request rewrite part of the prompt cache, so mid-run edits and edits to earlier
|
|
29
|
+
exchanges wait until the smaller context pays for that. It leaves alone images you send, results of `edit`
|
|
30
|
+
and `write`, and the last two exchanges before your current prompt.
|
|
31
|
+
|
|
32
|
+
## Example
|
|
307
33
|
|
|
308
|
-
|
|
309
|
-
|
|
310
|
-
- messages of the current run other than tool results, and the last `keepRecentExchanges` exchanges before
|
|
311
|
-
the current prompt
|
|
312
|
-
- compaction and branch summaries, exchanges that did not finish (the last reply has tool calls), and
|
|
313
|
-
messages Pi cannot edit (system messages, `!` shell executions), which stay in place inside an omitted
|
|
314
|
-
exchange
|
|
315
|
-
- tool results that contain images
|
|
316
|
-
- error results, if `distillErrors` is `false`
|
|
317
|
-
- results of excluded tools (`edit`, `write` by default)
|
|
318
|
-
- results shorter than `smallResultMinChars` (400), and large results of runs below `minRunChars`
|
|
319
|
-
- aborted or failed runs
|
|
320
|
-
- results that are already distilled, or that another extension already edited
|
|
321
|
-
- single lines too long for one Jev request (kept as they are)
|
|
322
|
-
- tool outputs of earlier runs one by one: earlier runs are only touched as whole exchanges
|
|
323
|
-
|
|
324
|
-
## Limitations
|
|
325
|
-
|
|
326
|
-
- **Lossy by design.** Relevance is judged against the run's question and answer and the earlier
|
|
327
|
-
conversation (the ongoing task), so a follow-up that goes somewhere new may need something that was
|
|
328
|
-
removed. The header and omission lines say what is missing, and `recall` returns it. An earlier task
|
|
329
|
-
that comes back after several unrelated ones may have been omitted as a whole exchange.
|
|
330
|
-
- **Latency.** Settling waits for Jev. This adds about 0.5–1.2 s after each qualifying run (measured), and
|
|
331
|
-
never more than `timeoutMs` (8 s). A mid-run checkpoint pauses the run the same way.
|
|
332
|
-
- **Cost.** Each qualifying run costs a few Jev requests, measured at under $0.001 per run. The first prompt
|
|
333
|
-
after an edit also has a one-time partial prompt-cache miss ([docs/CACHE.md](docs/CACHE.md)).
|
|
334
|
-
- **Steering.** A message sent during a run starts a new span. Tool results from before it are never
|
|
335
|
-
distilled.
|
|
336
|
-
|
|
337
|
-
## Examples (measured)
|
|
338
|
-
|
|
339
|
-
Real runs on public code with Pi 1.0.3: each example ran once with the guard on and once with it off
|
|
340
|
-
(`--no-guard`), from the same prompts. These are single runs, not a benchmark: the main model takes a
|
|
341
|
-
different path each time. Reproduce with `node test/e2e/examples.mjs` ([docs/TESTING.md](docs/TESTING.md)).
|
|
342
|
-
Examples A–C judge large outputs only (their numbers match `smallResultMinChars: 0`); example D shows the
|
|
343
|
-
default configuration and `exchangeBreakEven: false`.
|
|
344
|
-
|
|
345
|
-
**A. Searching a real codebase.** In a copy of the published Pi package (`dist/` without source maps and
|
|
346
|
-
the minified bundle, plus `docs/`), the agent was asked where Pi decides to auto-compact, starting with
|
|
347
|
-
`rg -n -i compact dist docs`. Pi's bash tool returned the last 50 KB of that search. Jev kept the matches
|
|
348
|
-
in the compaction module, the settings and the decision points in `agent-session.js`, and dropped matches
|
|
349
|
-
in the grep tool, HTML export templates, the SDK and so on. Then the agent was asked "which of those
|
|
350
|
-
settings can a user change, and what are their defaults?".
|
|
351
|
-
- Claude Sonnet 5.5: 50,413 → 16,210 chars (141 of 431 lines kept). The first turn-2 request carried
|
|
352
|
-
**15.5k tokens instead of 28.2k**. The answer was correct (`enabled` true, `reserveTokens` 16384,
|
|
353
|
-
`keepRecentTokens` 20000), without `recall`.
|
|
354
|
-
- GPT-6 Luna: 51,216 → 13,023 chars (107 of 385 lines), and a 5.4k read of `compaction.js` → 1.8k; two
|
|
355
|
-
smaller outputs were left whole. Turn 2 carried **11.5k tokens instead of 34.3k** and was correct, without
|
|
356
|
-
`recall`.
|
|
357
|
-
|
|
358
|
-
**C. Reading a 164 KB source file.** The agent read `dist/core/agent-session.js` (3,535 lines) in
|
|
359
|
-
seven 500-line pieces and explained how a prompt reaches the model. Jev kept 45–164 lines of each of the first
|
|
360
|
-
four pieces and removed the last three completely (each became a one-line stub). The follow-up asked for a
|
|
361
|
-
detail the explanation never mentioned: the exact error thrown when a prompt arrives during compaction.
|
|
362
|
-
That line was among the kept ones, so the agent quoted it exactly without `recall`. The turn-2 request
|
|
363
|
-
carried **9.2k tokens instead of 35.3k**.
|
|
364
|
-
|
|
365
|
-
**B. A failing test run.** In a copy of this repository with one injected off-by-one bug, the agent ran
|
|
366
|
-
the unit tests (a 15.8k-character log, 3 failures among 116 tests) and reported the cause. Jev kept the
|
|
367
|
-
3 failures with their assertion messages and the failing-test summary, and dropped the passing tests:
|
|
368
|
-
15.8k → 8.6k chars. Turn 2 ("now fix it") carried **5.7k tokens instead of 7.5k**, and both runs fixed
|
|
369
|
-
the bug. Failing commands are distilled because `distillErrors` is on by default.
|
|
370
|
-
|
|
371
|
-
What the model sees after distilling (example A, Claude; the first lines of the real replacement):
|
|
34
|
+
The agent ran `rg -n -i compact dist docs` (50 KB) to find where Pi decides to auto-compact. After the
|
|
35
|
+
run, the output that later requests carry starts like this:
|
|
372
36
|
|
|
373
37
|
```text
|
|
374
38
|
[context-guard] Distilled the output of bash `rg -n -i compact dist docs`: kept 141 of 431 lines (15.1k of 50.4k chars); the rest was judged not needed for the answer. Full output: recall({"entryId":"1704787f"}).
|
|
@@ -380,58 +44,96 @@ dist/core/compaction/compaction.d.ts:54:/** Estimate projected context without t
|
|
|
380
44
|
dist/core/compaction/compaction.d.ts:57: * Check if compaction should trigger based on context usage.
|
|
381
45
|
dist/core/compaction/compaction.d.ts:59:export declare function shouldCompact(contextTokens: number, contextWindow: number, settings: CompactionSettings): boolean;
|
|
382
46
|
[… 44 lines omitted: matches in dist/core/compaction/compaction.d.ts, dist/core/compaction/branch-summarization.d.ts, dist/core/compaction/index.d.ts, dist/core/session-manager.d.ts, dist/core/cache-stats.js and 2 more …]
|
|
47
|
+
…
|
|
383
48
|
```
|
|
384
49
|
|
|
385
|
-
|
|
386
|
-
|
|
387
|
-
|
|
388
|
-
|
|
389
|
-
|
|
390
|
-
|
|
391
|
-
|
|
392
|
-
|
|
393
|
-
|
|
394
|
-
|
|
395
|
-
|
|
396
|
-
|
|
397
|
-
|
|
398
|
-
|
|
399
|
-
|
|
400
|
-
|
|
401
|
-
|
|
402
|
-
|
|
|
403
|
-
|
|
|
404
|
-
|
|
|
405
|
-
|
|
406
|
-
|
|
407
|
-
|
|
408
|
-
|
|
409
|
-
|
|
410
|
-
|
|
411
|
-
|
|
412
|
-
|
|
413
|
-
|
|
414
|
-
|
|
415
|
-
|
|
416
|
-
|
|
417
|
-
|
|
418
|
-
|
|
419
|
-
|
|
420
|
-
|
|
421
|
-
|
|
422
|
-
|
|
423
|
-
|
|
424
|
-
|
|
425
|
-
|
|
426
|
-
|
|
427
|
-
|
|
428
|
-
|
|
429
|
-
|
|
430
|
-
|
|
431
|
-
|
|
432
|
-
|
|
433
|
-
|
|
434
|
-
|
|
435
|
-
|
|
436
|
-
|
|
437
|
-
|
|
50
|
+
With the matches it kept, the model then answered which compaction settings a user can change and their
|
|
51
|
+
defaults correctly, without `recall`.
|
|
52
|
+
|
|
53
|
+
Small outputs, old exchanges and images leave one line each:
|
|
54
|
+
|
|
55
|
+
```text
|
|
56
|
+
[context-guard] Omitted the output of bash `npm test` (1.2k chars): judged no longer needed. Full output: recall({"entryId":"…"}).
|
|
57
|
+
[context-guard] Omitted an earlier exchange judged unrelated to the current work: "which API clients retry on 503?" (6 messages, ~2.2k tokens). Full exchange: recall({"entryId":"…"}).
|
|
58
|
+
[context-guard] Removed 1 image from this output (1280×960; ~1.6k tokens), 4 turns old. recall({"entryId":"…"}) shows it again.
|
|
59
|
+
```
|
|
60
|
+
|
|
61
|
+
## Results
|
|
62
|
+
|
|
63
|
+
Context size of the next request, with the guard on and off:
|
|
64
|
+
|
|
65
|
+
| Task | Model | On | Off |
|
|
66
|
+
|---|---|---|---|
|
|
67
|
+
| Code search (50 KB `rg`), then a follow-up question | Claude Sonnet 5.5 | 15.5k | 28.2k |
|
|
68
|
+
| The same | GPT-6 Luna | 11.5k | 34.3k |
|
|
69
|
+
| Reading a 164 KB file, then a question about a detail | GPT-6 Luna | 9.2k | 35.3k |
|
|
70
|
+
| Failing test log, then "now fix it" | GPT-6 Luna | 5.7k | 7.5k |
|
|
71
|
+
| Autonomous run fixing 10 bugs (peak over the run) | GPT-6 Luna | 45k | 68–88k |
|
|
72
|
+
| Six screenshots, then a question about one of them | Claude Sonnet 5.5 | 9.4k | ~14.1k |
|
|
73
|
+
|
|
74
|
+
Every follow-up was answered correctly, and every task was finished. The screenshot row's "off" value is
|
|
75
|
+
the request before the images were removed. Jev costs $0.0003–0.007 and takes 0.6–2 s per pass. These are
|
|
76
|
+
single runs, not a benchmark. Details: [docs/RESULTS.md](docs/RESULTS.md).
|
|
77
|
+
|
|
78
|
+
## Use
|
|
79
|
+
|
|
80
|
+
It works on its own; there is nothing to call.
|
|
81
|
+
|
|
82
|
+
- **Footer:** `🛡 −4.2k · 3` means about 4.2k tokens are kept out of context right now, by 3 edits. After a
|
|
83
|
+
compaction, `🛡 0 · Σ−79k` shows the total saved in the session.
|
|
84
|
+
- **`/guard`:** shows every decision of the last pass, with Jev's probabilities. `/guard off` and
|
|
85
|
+
`/guard on` are saved for later sessions. `/guard reload` re-reads the settings.
|
|
86
|
+
- **`recall`:** the model calls it when it needs something removed: the whole original, lines that match a
|
|
87
|
+
regex, or a line range. You can also ask for it ("recall the full test log").
|
|
88
|
+
- **Undo:** use `/tree` to go back to before an edit; the original is still in the session file.
|
|
89
|
+
|
|
90
|
+
## Configure
|
|
91
|
+
|
|
92
|
+
Optional. Put the settings in `~/.pi/agent/context-guard.json`:
|
|
93
|
+
|
|
94
|
+
```json
|
|
95
|
+
{
|
|
96
|
+
"excludeTools": ["edit", "write", "bash"],
|
|
97
|
+
"imageKeepTurns": 5,
|
|
98
|
+
"historyExchanges": 0
|
|
99
|
+
}
|
|
100
|
+
```
|
|
101
|
+
|
|
102
|
+
| Key | Default | Meaning |
|
|
103
|
+
|---|---|---|
|
|
104
|
+
| `enabled` | `true` | Master switch (`/guard on` and `/guard off` write it) |
|
|
105
|
+
| `excludeTools` | `["edit", "write"]` | Tools whose output is never touched |
|
|
106
|
+
| `imageKeepTurns` | `3` | Remove images from tool results after this many turns; `0` turns this off |
|
|
107
|
+
| `pruneExchanges` | `true` | Omit earlier exchanges about other tasks |
|
|
108
|
+
| `midRun` | `true` | Also run during long runs, not only at the end |
|
|
109
|
+
| `historyExchanges` | `3` | Earlier exchanges sent to Jev as context; `0` sends none |
|
|
110
|
+
| `model` | `openrouter/~typesafe/jev-latest` | Classifier model |
|
|
111
|
+
|
|
112
|
+
All settings: [docs/REFERENCE.md](docs/REFERENCE.md#configuration).
|
|
113
|
+
|
|
114
|
+
## Privacy
|
|
115
|
+
|
|
116
|
+
Jev runs on OpenRouter and TypeSafe. Each pass sends them your prompt, the agent's answer or progress
|
|
117
|
+
notes, short excerpts of earlier messages, and the text of the tool outputs being judged. That text can
|
|
118
|
+
include source code and logs. Images, `edit` and `write` results, and outputs under 400 chars are never
|
|
119
|
+
sent. Turn the extension off with `/guard off`. The full list of what is sent:
|
|
120
|
+
[docs/REFERENCE.md](docs/REFERENCE.md#data-sent-to-jev).
|
|
121
|
+
|
|
122
|
+
## Trade-offs
|
|
123
|
+
|
|
124
|
+
- **The first request after an edit costs more.** The prompt cache has to be rewritten from the edit
|
|
125
|
+
onward. In short sessions you gain context room, not a lower bill.
|
|
126
|
+
- **Lossy by design.** A follow-up that goes somewhere new may need `recall` (the model sees what was
|
|
127
|
+
removed and how to get it back).
|
|
128
|
+
- **It adds 0.5–2 s** after a run, or mid-run while a checkpoint runs (at most 8 s).
|
|
129
|
+
|
|
130
|
+
## More
|
|
131
|
+
|
|
132
|
+
- [docs/REFERENCE.md](docs/REFERENCE.md): every setting, status, command and `recall` parameter
|
|
133
|
+
- [docs/RESULTS.md](docs/RESULTS.md): measured runs, including where it does not help
|
|
134
|
+
- [docs/DESIGN.md](docs/DESIGN.md): how it works
|
|
135
|
+
- [docs/CACHE.md](docs/CACHE.md): prompt-cache costs on Anthropic and OpenAI
|
|
136
|
+
- [docs/JEV.md](docs/JEV.md): the Jev questions and threshold choices
|
|
137
|
+
- [docs/TESTING.md](docs/TESTING.md): unit and live tests
|
|
138
|
+
|
|
139
|
+
MIT license.
|
package/docs/CACHE.md
CHANGED
|
@@ -214,7 +214,11 @@ So checkpoints pay for themselves only when the run goes on for roughly 8–30 m
|
|
|
214
214
|
Anthropic: factor 16, rewrite = context after the read point the next request would get, or after the
|
|
215
215
|
question when no logged entry is trusted, or the whole context with pinning off; other providers: factor
|
|
216
216
|
16, rewrite = context from the first eligible output), assuming the run goes on
|
|
217
|
-
about as long as it has run so far.
|
|
217
|
+
about as long as it has run so far. Context size is measured in text characters (`src/size.ts`): an image
|
|
218
|
+
counts as 4 characters per token (Pi's chars ÷ 4; Anthropic: width × height / 750 tokens), not its base64 length, and a
|
|
219
|
+
thinking signature counts at half its length. Counting the base64 once blocked every checkpoint in a long
|
|
220
|
+
Claude run with screenshots (rewrite estimated at 2–22M characters for a 150–370k-token context).
|
|
221
|
+
In the measured Claude runs (8–14 requests) it never allowed a
|
|
218
222
|
checkpoint; in the GPT runs (26–37 requests) it allowed one or two. Turn it off to checkpoint purely for
|
|
219
223
|
context room.
|
|
220
224
|
|