pi-better-web-search 0.1.8 → 0.1.11
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/CHANGELOG.md +30 -0
- package/README.md +50 -29
- package/docs/README.zh-CN.md +35 -21
- package/docs/architecture.md +25 -17
- package/docs/providers.md +23 -8
- package/docs/publishing.md +6 -6
- package/docs/testing.md +1 -1
- package/lib/candidates.ts +48 -31
- package/lib/format.ts +9 -2
- package/lib/health.ts +15 -3
- package/lib/providers/deepseek.ts +13 -32
- package/lib/providers/http.ts +56 -6
- package/lib/providers/ollama.ts +5 -2
- package/lib/providers/openai.ts +9 -1
- package/lib/providers/types.ts +20 -0
- package/lib/search.ts +88 -17
- package/package.json +3 -3
package/CHANGELOG.md
CHANGED
|
@@ -1,5 +1,35 @@
|
|
|
1
1
|
# Changelog
|
|
2
2
|
|
|
3
|
+
## 0.1.11
|
|
4
|
+
|
|
5
|
+
- Increase the default timeout to 120 seconds per search and URL fetch attempt
|
|
6
|
+
for all providers. Provider errors still trigger fallback immediately, and
|
|
7
|
+
`PI_BETTER_WEB_SEARCH_TIMEOUT_MS` can override the default.
|
|
8
|
+
|
|
9
|
+
## 0.1.10
|
|
10
|
+
|
|
11
|
+
- Verify against Pi 1.5.2 and document support for the OpenAI ChatGPT OAuth
|
|
12
|
+
login as well as OpenAI API keys and legacy Codex OAuth.
|
|
13
|
+
- Use the lowest model-supported reasoning effort for OpenAI Responses search,
|
|
14
|
+
independently of the conversation's thinking level, as in pi-web-search.
|
|
15
|
+
- Document that Pi virtual models are not directly supported.
|
|
16
|
+
|
|
17
|
+
## 0.1.9
|
|
18
|
+
|
|
19
|
+
- Preserve provider diversity and apply cooldowns before limiting actual search
|
|
20
|
+
and fetch attempts, so skipped siblings cannot crowd out healthy providers.
|
|
21
|
+
- Reject DeepSeek search queries over 128 Unicode characters with a generic,
|
|
22
|
+
actionable `Search query is too long` error instead of silently shortening
|
|
23
|
+
them or trying a fallback.
|
|
24
|
+
- Distinguish model-access 403 errors from provider-wide failures, and track
|
|
25
|
+
URL-fetch transport failures while preserving partial successes.
|
|
26
|
+
- Count concurrent failures during one cooldown as a single outage; increase
|
|
27
|
+
backoff only when a subsequent attempt after expiry also fails.
|
|
28
|
+
- Bound HTTP error bodies, individual attempt messages, and model-facing error
|
|
29
|
+
text. Fix Claude version parsing when a date follows the major version.
|
|
30
|
+
- Clarify that brand ranking only covers supported APIs, and test OpenCode Go
|
|
31
|
+
against the actual pi model catalog rather than a fabricated API assignment.
|
|
32
|
+
|
|
3
33
|
## 0.1.8
|
|
4
34
|
|
|
5
35
|
- Shorten overlong DeepSeek search queries at a word boundary before sending
|
package/README.md
CHANGED
|
@@ -10,13 +10,16 @@ and returns provider data as-is.
|
|
|
10
10
|
[](https://github.com/zhexusun10/pi-better-web-search/actions/workflows/ci.yml)
|
|
11
11
|
[](https://www.npmjs.com/package/pi-better-web-search)
|
|
12
12
|
[](LICENSE)
|
|
13
|
-
[![Pi 1.
|
|
13
|
+
[](https://pi.dev)
|
|
14
14
|
[](https://nodejs.org)
|
|
15
15
|
|
|
16
16
|
[简体中文](docs/README.zh-CN.md) · [Architecture](docs/architecture.md) · [Providers](docs/providers.md) · [Testing](docs/testing.md) · [Source](extensions/index.ts)
|
|
17
17
|
|
|
18
18
|
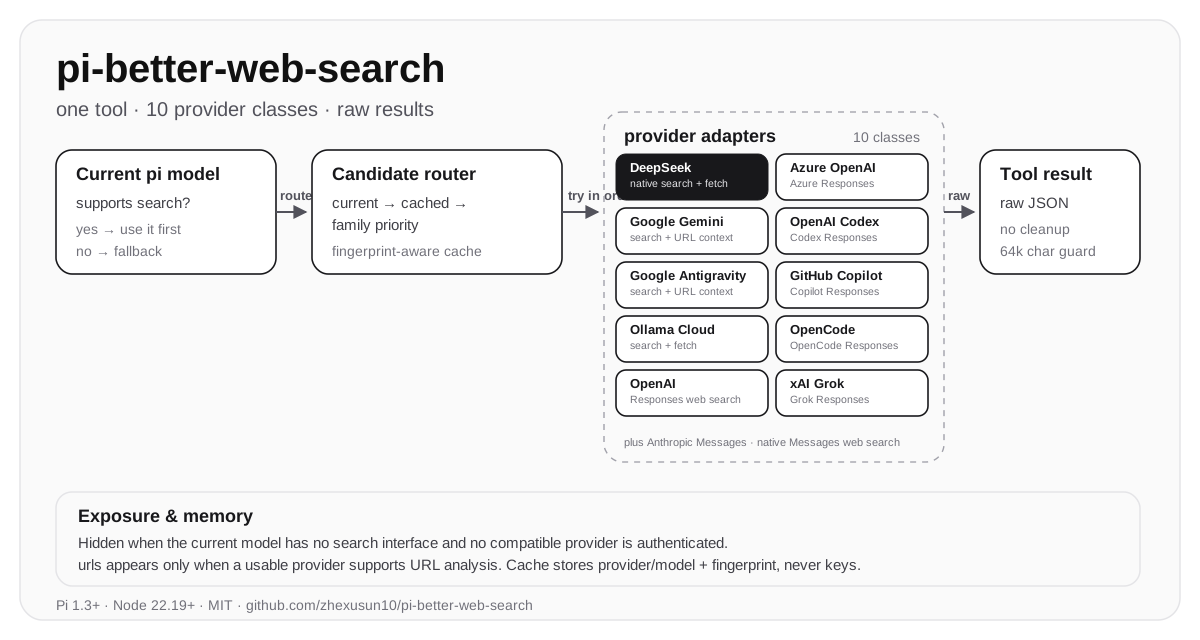
|
|
19
19
|
|
|
20
|
+
> The npm registry may lag GitHub releases. If the version you want is not yet
|
|
21
|
+
> published to npm, install the tagged GitHub release below instead.
|
|
22
|
+
|
|
20
23
|
```bash
|
|
21
24
|
pi install npm:pi-better-web-search
|
|
22
25
|
```
|
|
@@ -26,14 +29,14 @@ Then start a new pi process, or run `/reload` in an existing session.
|
|
|
26
29
|
GitHub and local installations also work:
|
|
27
30
|
|
|
28
31
|
```bash
|
|
29
|
-
pi install git:github.com/zhexusun10/pi-better-web-search
|
|
32
|
+
pi install git:github.com/zhexusun10/pi-better-web-search@v0.1.11
|
|
30
33
|
pi install ./path/to/pi-better-web-search
|
|
31
34
|
```
|
|
32
35
|
|
|
33
36
|
> Do not load this package together with `pi-web-search`. Both register a tool
|
|
34
37
|
> named `web_search`, and the second registration replaces the first.
|
|
35
38
|
|
|
36
|
-
Requirements: **pi 1.3+** and **Node.js 22.19+**.
|
|
39
|
+
Requirements: **pi 1.3+** and **Node.js 22.19+**. Tested with **pi 1.5.2**.
|
|
37
40
|
|
|
38
41
|
## What it fixes
|
|
39
42
|
|
|
@@ -79,11 +82,11 @@ The runtime schema is logically:
|
|
|
79
82
|
}
|
|
80
83
|
```
|
|
81
84
|
|
|
82
|
-
- `query` searches the web.
|
|
83
|
-
|
|
84
|
-
|
|
85
|
-
|
|
86
|
-
the
|
|
85
|
+
- `query` searches the web. Outer whitespace is trimmed; search operators are
|
|
86
|
+
otherwise passed through unchanged. If DeepSeek is selected and the query
|
|
87
|
+
exceeds 128 Unicode characters, the tool returns an error with the actual
|
|
88
|
+
length and limit, asking the model to shorten the query and retry. It does not
|
|
89
|
+
send the query or silently truncate it. Other providers may accept longer queries.
|
|
87
90
|
- `urls` analyzes the listed pages. URLs can be used **alone** or together with
|
|
88
91
|
`query`. A query plus URLs performs a search and then analyzes the URLs.
|
|
89
92
|
- At most **20** URLs may be supplied.
|
|
@@ -117,6 +120,12 @@ invalid URLs alongside valid work are reported in the `fetched` entries.
|
|
|
117
120
|
| 10 | **xAI (Grok)** | Yes | No | Grok dialect Responses API (`web_search_call.action.sources`) |
|
|
118
121
|
| * | **Anthropic Messages** | Yes | No | Messages API `web_search_20260209` tool & Claude Code OAuth |
|
|
119
122
|
|
|
123
|
+
OpenAI search supports both Pi's **OpenAI (ChatGPT subscription) / Sign in with
|
|
124
|
+
ChatGPT** OAuth login and an OpenAI API key, as well as the separate legacy
|
|
125
|
+
**OpenAI Codex** OAuth login. Model and web search availability still depend
|
|
126
|
+
on the account and service. Pi virtual models (`pi-virtual`) are not directly
|
|
127
|
+
supported; automatic fallback can still use an authenticated concrete model.
|
|
128
|
+
|
|
120
129
|
URL analysis is only exposed when at least one usable interface supports it.
|
|
121
130
|
For example, a current OpenAI model with only OpenAI credentials gets a
|
|
122
131
|
query-only schema, while the same session with DeepSeek, Ollama Cloud, or Google
|
|
@@ -152,14 +161,16 @@ For a search:
|
|
|
152
161
|
their capability tier as a tiebreaker: OpenAI tiers are
|
|
153
162
|
`luna → terra → sol → astra` and Claude tiers are
|
|
154
163
|
`haiku → sonnet → opus → fable`. Ties are deterministic.
|
|
155
|
-
5. Alternate
|
|
156
|
-
|
|
157
|
-
|
|
158
|
-
|
|
159
|
-
provider; a model-specific failure keeps trying sibling models.
|
|
164
|
+
5. Alternate providers are considered before additional models of an already
|
|
165
|
+
represented provider; siblings are then tried round-robin across families.
|
|
166
|
+
A provider-wide failure skips that provider, while a model-specific failure
|
|
167
|
+
(including a model-specific 403) can fall back to a sibling.
|
|
160
168
|
|
|
161
|
-
|
|
162
|
-
URL fetching.
|
|
169
|
+
The search limit is 12 actual attempts; skipped candidates do not consume it.
|
|
170
|
+
URL fetching follows the same idea with a separate limit of 6 actual attempts.
|
|
171
|
+
Model ranking applies only to supported APIs: for example, the built-in
|
|
172
|
+
`opencode-go` DeepSeek models use `openai-completions`, which this extension
|
|
173
|
+
cannot search through and does not reinterpret as Responses.
|
|
163
174
|
|
|
164
175
|
The current model is normally tried first when it supports search, unless its
|
|
165
176
|
provider or model is in a failure cooldown. The cache does not replace a
|
|
@@ -167,20 +178,27 @@ supported current model; it mainly lets an unsupported current model use a
|
|
|
167
178
|
remembered compatible provider immediately on later calls.
|
|
168
179
|
|
|
169
180
|
If a provider errors, the extension records the attempt and moves to the next
|
|
170
|
-
interface.
|
|
171
|
-
|
|
172
|
-
|
|
181
|
+
interface. An overlong query rejected by DeepSeek instead returns immediately
|
|
182
|
+
without trying another provider or updating its health state. Aborts stop
|
|
183
|
+
immediately. Each search or URL fetch attempt times out after 120 seconds by
|
|
184
|
+
default; explicit provider errors trigger fallback immediately without waiting
|
|
185
|
+
for the timeout. Set `PI_BETTER_WEB_SEARCH_TIMEOUT_MS` to override the per-attempt
|
|
186
|
+
timeout. If every attempt fails, the tool returns an error whose message contains
|
|
187
|
+
the provider errors.
|
|
173
188
|
Provider/model routing remains in `details.attempts`. For a URL-only call, the
|
|
174
|
-
error also reports the per-URL failures.
|
|
189
|
+
error also reports the per-URL failures. Provider error bodies and model-facing
|
|
190
|
+
error text are bounded to prevent an oversized error from filling the context.
|
|
175
191
|
|
|
176
192
|
Provider-wide failures (auth, balance, network, timeout, malformed request) and
|
|
177
193
|
model-specific failures are remembered for the life of the extension process.
|
|
178
194
|
On later calls the failed provider or model is moved behind healthy candidates
|
|
179
195
|
for search and fetch independently. The cooldown starts at 60 seconds, doubles
|
|
180
|
-
|
|
181
|
-
|
|
182
|
-
|
|
183
|
-
|
|
196
|
+
when a subsequent attempt after expiry fails, and is capped at 10 minutes.
|
|
197
|
+
Concurrent failures during the same cooldown do not extend it; a successful
|
|
198
|
+
search or a fetch with at least one successful URL and no provider transport
|
|
199
|
+
error clears it. Set
|
|
200
|
+
`PI_BETTER_WEB_SEARCH_FAILURE_COOLDOWN_MS=0` to disable this behavior. Calls
|
|
201
|
+
already in flight may still try the same candidate at the same time.
|
|
184
202
|
|
|
185
203
|
### Cache fingerprint invalidation
|
|
186
204
|
|
|
@@ -266,7 +284,7 @@ this:
|
|
|
266
284
|
- Redirects are not resolved and sources are not derived.
|
|
267
285
|
- Unknown provider fields are preserved when the result fits the size guard.
|
|
268
286
|
|
|
269
|
-
A final output-size guard limits
|
|
287
|
+
A final output-size guard limits model-facing results and errors to **96,000
|
|
270
288
|
Unicode code points** by default. Normal-sized results retain their original
|
|
271
289
|
fields and formatting. If indentation alone exceeds the limit, compact JSON is
|
|
272
290
|
returned without dropping data or setting the truncation flag.
|
|
@@ -282,7 +300,7 @@ links or bare domains in unrecognized fields cannot always be identified. Other
|
|
|
282
300
|
entries omitted; results are not re-ranked or summarized.
|
|
283
301
|
|
|
284
302
|
The JSON portion remains valid, followed by a single `[truncated]` line. No
|
|
285
|
-
truncation metadata or per-string markers are added to the
|
|
303
|
+
output-size truncation metadata or per-string markers are added to the JSON.
|
|
286
304
|
Because of the trailing line, the complete text is not itself valid JSON.
|
|
287
305
|
`details.truncated` is also set to `true` when data is actually removed.
|
|
288
306
|
|
|
@@ -331,8 +349,11 @@ Content-Type: application/json
|
|
|
331
349
|
```
|
|
332
350
|
|
|
333
351
|
Search uses `query`, `count: 10`, and `need_content: true`. DeepSeek limits
|
|
334
|
-
`query` to 128 Unicode characters
|
|
335
|
-
|
|
352
|
+
`query` to 128 Unicode characters. Longer queries return an error before any
|
|
353
|
+
DeepSeek request is sent; the model should shorten the query and retry. For
|
|
354
|
+
example: `Search query is too long (129 Unicode characters). The maximum is
|
|
355
|
+
128 Unicode characters. Shorten the query and retry.` The raw `results` array
|
|
356
|
+
is returned unchanged,
|
|
336
357
|
including `rerank_score`, `title`, `url`,
|
|
337
358
|
`snippet`, `summary`, `content`, `site_name`, `site_icon`, `date`, `authority`,
|
|
338
359
|
and any unknown fields.
|
|
@@ -364,7 +385,7 @@ See [SECURITY.md](SECURITY.md) for reporting vulnerabilities.
|
|
|
364
385
|
|
|
365
386
|
## Verified
|
|
366
387
|
|
|
367
|
-
- **
|
|
388
|
+
- **Unit and integration tests** covering exposure, schema variants,
|
|
368
389
|
provider request shapes, SSE parsing, raw-result preservation, fallback,
|
|
369
390
|
cache invalidation, URL handling, truncation, and abort behavior.
|
|
370
391
|
- **Real DeepSeek Search/Fetch run** with a real API key: 10 raw search results,
|
|
@@ -406,7 +427,7 @@ npm run build
|
|
|
406
427
|
```
|
|
407
428
|
|
|
408
429
|
`npm run build` runs the checks and tests, verifies the npm file list, and packs
|
|
409
|
-
`dist/pi-better-web-search-0.1.
|
|
430
|
+
`dist/pi-better-web-search-0.1.9.tgz`. Nothing is published automatically.
|
|
410
431
|
|
|
411
432
|
The test suite uses plain `.mjs` files that import the `.ts` sources directly.
|
|
412
433
|
It mocks `globalThis.fetch`, uses a temporary cache file, and exercises
|
package/docs/README.zh-CN.md
CHANGED
|
@@ -10,6 +10,9 @@
|
|
|
10
10
|
|
|
11
11
|

|
|
12
12
|
|
|
13
|
+
> npm 版本可能落后于 GitHub Release。如果所需版本尚未发布到 npm,可使用
|
|
14
|
+
> 下方指定标签的 GitHub 安装方式。
|
|
15
|
+
|
|
13
16
|
```bash
|
|
14
17
|
pi install npm:pi-better-web-search
|
|
15
18
|
```
|
|
@@ -19,14 +22,14 @@ pi install npm:pi-better-web-search
|
|
|
19
22
|
也可以从 GitHub 或本地安装:
|
|
20
23
|
|
|
21
24
|
```bash
|
|
22
|
-
pi install git:github.com/zhexusun10/pi-better-web-search
|
|
25
|
+
pi install git:github.com/zhexusun10/pi-better-web-search@v0.1.11
|
|
23
26
|
pi install ./path/to/pi-better-web-search
|
|
24
27
|
```
|
|
25
28
|
|
|
26
29
|
> 不要和 `pi-web-search` 同时加载。两者都注册 `web_search`,后注册的会覆盖
|
|
27
30
|
> 先注册的。
|
|
28
31
|
|
|
29
|
-
要求:**pi 1.3+**,**Node.js 22.19
|
|
32
|
+
要求:**pi 1.3+**,**Node.js 22.19+**。已通过 **pi 1.5.2** 依赖测试。
|
|
30
33
|
|
|
31
34
|
## 它解决什么问题
|
|
32
35
|
|
|
@@ -65,9 +68,9 @@ pi install ./path/to/pi-better-web-search
|
|
|
65
68
|
}
|
|
66
69
|
```
|
|
67
70
|
|
|
68
|
-
- `query`
|
|
69
|
-
|
|
70
|
-
|
|
71
|
+
- `query` 搜索网页,只去掉首尾空白,搜索语法其余部分原样保留。如果选中
|
|
72
|
+
DeepSeek 且 query 超过 128 个 Unicode 字符,工具会直接返回实际长度和上限,
|
|
73
|
+
提示模型缩短后重试;不会发送请求或静默截断。其他 provider 可以接受更长的查询。
|
|
71
74
|
- `urls` 分析指定页面。可以**单独使用**,也可以和 `query` 一起使用。两者同时
|
|
72
75
|
提供时,先搜索,再分析 URL。
|
|
73
76
|
- 最多 **20** 个 URL。
|
|
@@ -98,6 +101,11 @@ provider 都失败时,工具返回错误(`isError: true`),不会静默
|
|
|
98
101
|
| 10 | **xAI (Grok)** | 是 | 否 | 原生 Grok 方言 Responses API(`web_search_call.action.sources`) |
|
|
99
102
|
| * | **Anthropic Messages** | 是 | 否 | Messages API `web_search_20260209` 工具及 Claude Code OAuth 凭据 |
|
|
100
103
|
|
|
104
|
+
OpenAI 搜索支持 Pi 的 **OpenAI(ChatGPT 订阅)/ Sign in with ChatGPT**
|
|
105
|
+
OAuth 登录、OpenAI API Key,以及独立的旧版 **OpenAI Codex** OAuth 登录。
|
|
106
|
+
模型和搜索工具能否使用仍取决于账号及服务。Pi 虚拟模型(`pi-virtual`)
|
|
107
|
+
暂不直接支持,但可自动回退到其他已认证的具体模型。
|
|
108
|
+
|
|
101
109
|
只有至少一个可用接口支持 URL 分析时,`urls` 才会暴露。例如:当前模型是
|
|
102
110
|
OpenAI 且只有 OpenAI 凭据时,schema 只有 `query`;同一会话只要还有
|
|
103
111
|
DeepSeek、Google Gemini、Antigravity 或 Ollama Cloud 凭据,就会出现 `urls`。
|
|
@@ -126,25 +134,31 @@ Provider 识别顺序:
|
|
|
126
134
|
内版本号从新到旧;GPT 和 Claude 仍按版本优先,版本相同时才按能力等级排序
|
|
127
135
|
(便宜的等级优先,未知等级排最后):OpenAI 为 `luna → terra → sol → astra`,
|
|
128
136
|
Claude 为 `haiku → sonnet → opus → fable`。
|
|
129
|
-
5.
|
|
130
|
-
provider
|
|
131
|
-
|
|
132
|
-
会跳过该 provider 的其余模型;模型级失败则继续尝试同 provider 的其他模型。
|
|
137
|
+
5. 优先尝试尚未覆盖的 provider,再按 family 的 round-robin 尝试各 provider
|
|
138
|
+
的备用模型。provider 级失败会跳过该 provider;模型级失败(包括模型权限 403)
|
|
139
|
+
则可继续尝试同 provider 的其他模型。
|
|
133
140
|
|
|
134
|
-
|
|
141
|
+
搜索最多发起 12 次实际尝试;URL 抓取采用同样的思路,最多发起 6 次。跳过的候选
|
|
142
|
+
不占用次数。排序只适用于支持的 API:例如内置的 `opencode-go` DeepSeek 模型
|
|
143
|
+
使用 `openai-completions`,本扩展不会将它们当作 Responses 搜索接口。
|
|
135
144
|
|
|
136
145
|
当前模型支持搜索时通常优先当前模型,除非该 provider 或该模型正处于失败冷却期。
|
|
137
146
|
缓存不会覆盖它。缓存主要用于当前模型不支持搜索时,让下一次调用直接使用之前成功
|
|
138
147
|
的兼容 provider。
|
|
139
148
|
|
|
140
|
-
Provider 报错时记录 attempt
|
|
141
|
-
|
|
149
|
+
Provider 报错时记录 attempt 并继续下一个接口。DeepSeek 查询超长则直接返回错误,
|
|
150
|
+
不继续尝试其他 provider,也不记录为 provider 健康故障。取消会立即停止。搜索和 URL
|
|
151
|
+
抓取的每次尝试默认超时 120 秒;provider 直接报错时立即 fallback,不等待超时。
|
|
152
|
+
`PI_BETTER_WEB_SEARCH_TIMEOUT_MS` 可覆盖默认值。所有尝试都失败时,
|
|
142
153
|
工具返回错误,消息中包含 provider 返回的错误;provider/model 路由信息保留在
|
|
143
|
-
`details.attempts` 中。URL-only 调用还会报告每个 URL 的失败原因。
|
|
154
|
+
`details.attempts` 中。URL-only 调用还会报告每个 URL 的失败原因。provider 错误
|
|
155
|
+
响应体与发给模型的错误文本都有大小限制,避免错误内容占满上下文。
|
|
144
156
|
|
|
145
157
|
Provider 级失败(鉴权、余额、网络、超时、请求头异常)和单个模型失败都会在扩展进程内
|
|
146
158
|
记住。后续调用会把失败的 provider 或模型排到健康候选之后,搜索和 URL 抓取分别记录。
|
|
147
|
-
冷却时间从 60
|
|
159
|
+
冷却时间从 60 秒开始,冷却结束后的再次尝试失败时翻倍,最多 10 分钟;同一冷却期内
|
|
160
|
+
的并发失败不会延长时间。搜索成功,或至少一个 URL 抓取成功且没有 provider
|
|
161
|
+
网络错误时,清除对应冷却。设置
|
|
148
162
|
`PI_BETTER_WEB_SEARCH_FAILURE_COOLDOWN_MS=0` 可禁用。已经在途的并发调用仍可能同时
|
|
149
163
|
尝试同一个候选。
|
|
150
164
|
|
|
@@ -226,7 +240,7 @@ Provider 数据放在 JSON 外层中返回,不做清理。示例:
|
|
|
226
240
|
- 不解析 redirect,不派生 sources。
|
|
227
241
|
- 未超出大小限制时,provider 的未知字段也会保留。
|
|
228
242
|
|
|
229
|
-
|
|
243
|
+
最终大小保护默认限制结果及错误文本不超过 **96,000 个 Unicode code point**。
|
|
230
244
|
未超限时保留原始字段及格式;如果只是缩进导致超限,会先压缩 JSON,
|
|
231
245
|
不丢失数据,也不标记为截断。
|
|
232
246
|
|
|
@@ -239,8 +253,8 @@ Provider 数据放在 JSON 外层中返回,不做清理。示例:
|
|
|
239
253
|
其他长字符串可能被缩短,字段或数组末尾的条目可能被省略;
|
|
240
254
|
不对结果重排或总结。
|
|
241
255
|
|
|
242
|
-
JSON 部分仍然合法,末尾仅追加一行 `[truncated]
|
|
243
|
-
|
|
256
|
+
成功结果的 JSON 部分仍然合法,末尾仅追加一行 `[truncated]`。输出大小截断不会在
|
|
257
|
+
JSON 中添加元数据,也不会逐个标记字符串。由于末尾追加了这一行,
|
|
244
258
|
整个文本不再是合法 JSON。确实丢失数据时,`details.truncated` 也会设为
|
|
245
259
|
`true`。
|
|
246
260
|
|
|
@@ -278,8 +292,8 @@ Content-Type: application/json
|
|
|
278
292
|
```
|
|
279
293
|
|
|
280
294
|
搜索使用 `query`、`count: 10`、`need_content: true`。DeepSeek 的 `query` 上限为
|
|
281
|
-
128 个 Unicode
|
|
282
|
-
数组原样返回,包括 `rerank_score`、`title`、`url`、`snippet`、`summary`、`content`、
|
|
295
|
+
128 个 Unicode 字符,超长时会在发送请求前直接返回错误,提示缩短后重试。
|
|
296
|
+
原始 `results` 数组原样返回,包括 `rerank_score`、`title`、`url`、`snippet`、`summary`、`content`、
|
|
283
297
|
`site_name`、`site_icon`、`date`、`authority` 和未知字段。
|
|
284
298
|
|
|
285
299
|
Fetch 发送 `{ "url": "..." }`,原样保存 `{ title, content }`。URL 最长 8192
|
|
@@ -304,7 +318,7 @@ provider;`403`/`404` 作为单个 URL 的错误上报,orchestrator 只重试
|
|
|
304
318
|
|
|
305
319
|
## 已验证
|
|
306
320
|
|
|
307
|
-
-
|
|
321
|
+
- **单元/集成测试**:暴露规则、schema 变体、provider 请求形状、SSE 解析、
|
|
308
322
|
原始结果保留、fallback、缓存失效、URL 处理、截断和取消。
|
|
309
323
|
- **真实 DeepSeek Search/Fetch**:使用真实 API key,返回 10 条原始搜索结果、
|
|
310
324
|
summary/content、合法 fetch 页面,以及文档中的 404/非法 URL 错误。
|
|
@@ -339,7 +353,7 @@ npm run build
|
|
|
339
353
|
```
|
|
340
354
|
|
|
341
355
|
`npm run build` 会运行检查、测试、包内容验证,并生成
|
|
342
|
-
`dist/pi-better-web-search-0.1.
|
|
356
|
+
`dist/pi-better-web-search-0.1.9.tgz`。不会自动发布。
|
|
343
357
|
|
|
344
358
|
测试是 `.mjs` 文件,直接导入 `.ts` 源码,mock `globalThis.fetch`,使用临时缓存
|
|
345
359
|
目录。详见 [测试](testing.md) 和 [发布](publishing.md)。
|
package/docs/architecture.md
CHANGED
|
@@ -73,13 +73,14 @@ Search candidates:
|
|
|
73
73
|
2. The remembered search provider when the cache fingerprint is current.
|
|
74
74
|
3. One candidate per remaining family in this order:
|
|
75
75
|
**DeepSeek → Ollama → Google → OpenAI → xAI → Anthropic**.
|
|
76
|
-
4.
|
|
77
|
-
|
|
78
|
-
|
|
79
|
-
sibling model
|
|
76
|
+
4. Prefer previously unrepresented provider ids, then try remaining sibling
|
|
77
|
+
models round-robin across families. Provider-wide failures skip that
|
|
78
|
+
provider; model-specific failures, including model-access 403s, can use a
|
|
79
|
+
sibling model. The cap is 12 actual search attempts, not skipped candidates.
|
|
80
80
|
|
|
81
81
|
Fetch candidates use the same shape but include only adapters with
|
|
82
|
-
`supportsUrls` and a `fetch` implementation. The fetch cap is 6 attempts.
|
|
82
|
+
`supportsUrls` and a `fetch` implementation. The fetch cap is 6 actual attempts.
|
|
83
|
+
Cooldowns are applied to the full discovery set before either cap.
|
|
83
84
|
|
|
84
85
|
Within a family, models are ordered by brand first: DeepSeek, OpenAI, Claude,
|
|
85
86
|
Gemini/Gemma, then other gateway brands. Brands without named tiers use variant
|
|
@@ -87,14 +88,19 @@ order `flash → base → pro`, then version number, newest first. GPT and Claud
|
|
|
87
88
|
use version number first, newest first, with capability tier as a tiebreaker:
|
|
88
89
|
OpenAI uses `luna → terra → sol → astra` and Claude uses
|
|
89
90
|
`haiku → sonnet → opus → fable`. Ties fall back to the deterministic
|
|
90
|
-
`provider/id@baseUrl` order.
|
|
91
|
+
`provider/id@baseUrl` order. Ranking only applies to models whose API is already
|
|
92
|
+
supported. For example, built-in `opencode-go` DeepSeek models use
|
|
93
|
+
`openai-completions` and are not eligible for Responses search.
|
|
91
94
|
A provider id is only retried with another model when the first failure was
|
|
92
95
|
model-specific; provider-wide failures (auth, balance, network, timeout,
|
|
93
96
|
malformed request) skip the rest of that provider. Provider failures and
|
|
94
97
|
model-specific failures are remembered per phase (search/fetch) for the life of
|
|
95
98
|
the process. On later calls the failed provider or model is moved behind healthy
|
|
96
|
-
candidates for a 60-second to 10-minute exponential cooldown
|
|
97
|
-
|
|
99
|
+
candidates for a 60-second to 10-minute exponential cooldown. Concurrent
|
|
100
|
+
failures during an active cooldown count as one outage; a failed probe after
|
|
101
|
+
expiry increases the cooldown. A successful search or fetch with at least one
|
|
102
|
+
successful URL and no provider transport error clears it. Calls already in
|
|
103
|
+
flight are not cancelled or reordered.
|
|
98
104
|
|
|
99
105
|
The current model is preferred when it supports search and neither its provider
|
|
100
106
|
nor that model is cooling down. The cache is a fallback, not an override. When
|
|
@@ -133,9 +139,10 @@ be used. A cached provider that is no longer available is ignored.
|
|
|
133
139
|
|
|
134
140
|
## Input validation
|
|
135
141
|
|
|
136
|
-
- `query` is trimmed
|
|
137
|
-
|
|
138
|
-
|
|
142
|
+
- `query` is trimmed. When DeepSeek is selected, queries over 128 Unicode
|
|
143
|
+
characters produce an actionable error before any DeepSeek request; no
|
|
144
|
+
automatic truncation, fallback, or health cooldown occurs. Other providers
|
|
145
|
+
are not subject to this limit.
|
|
139
146
|
- `urls` is an array of at most 20 strings.
|
|
140
147
|
- Each URL must be HTTP/HTTPS, have a host, omit username/password, and be at
|
|
141
148
|
most 8192 characters.
|
|
@@ -169,10 +176,11 @@ The result is a JSON wrapper:
|
|
|
169
176
|
}
|
|
170
177
|
```
|
|
171
178
|
|
|
172
|
-
Fields inside `search` and `fetched[].data` are provider data. The extension
|
|
173
|
-
not deduplicate,
|
|
174
|
-
|
|
175
|
-
|
|
179
|
+
Fields inside `search` and `fetched[].data` are provider data. The extension
|
|
180
|
+
does not deduplicate,
|
|
181
|
+
normalize, filter, re-rank, summarize, insert citation markers, or append source
|
|
182
|
+
sections. The final guard keeps model-facing results and errors within 96,000
|
|
183
|
+
Unicode code points by default (`PI_BETTER_WEB_SEARCH_MAX_CHARS`).
|
|
176
184
|
It preserves ordinary formatted JSON, or uses compact JSON if that alone fits.
|
|
177
185
|
Otherwise it budgets sibling fields and array entries independently. Recognized
|
|
178
186
|
link and identity fields stay whole; entries or branches that cannot fit them
|
|
@@ -182,8 +190,8 @@ rather than partially emitted. Unknown relative links or bare domains may not be
|
|
|
182
190
|
identifiable. Other strings can be shortened, and fields or trailing array entries
|
|
183
191
|
omitted. The JSON portion
|
|
184
192
|
stays valid, followed by one `[truncated]` line; the complete text is therefore
|
|
185
|
-
not valid JSON. No truncation metadata is injected into the
|
|
186
|
-
|
|
193
|
+
not valid JSON. No output-size truncation metadata is injected into the JSON;
|
|
194
|
+
`details.truncated` marks output-size data loss. When truncation is needed with a limit of 11–13 characters,
|
|
187
195
|
only the marker is returned; below 11, a minimal JSON value is returned instead.
|
|
188
196
|
This is a character guard, not a token or model-context limit; it does not
|
|
189
197
|
provide pagination or retain the complete provider payload for later use.
|
package/docs/providers.md
CHANGED
|
@@ -20,8 +20,13 @@ stream parsing, and error behavior:
|
|
|
20
20
|
| * | **Anthropic Messages** | api `anthropic-messages` | Yes | No | Messages API `web_search_20260209` tool & OAuth |
|
|
21
21
|
|
|
22
22
|
A model whose API is `openai-completions` is not search-capable unless it is
|
|
23
|
-
served by DeepSeek or Ollama Cloud.
|
|
24
|
-
|
|
23
|
+
served by the native DeepSeek provider or Ollama Cloud. In particular, the
|
|
24
|
+
built-in `opencode-go` DeepSeek models use `openai-completions`; brand ranking
|
|
25
|
+
does not make them Responses-compatible or expose them as search candidates.
|
|
26
|
+
A local Ollama daemon is not supported; Ollama Cloud uses the hosted REST API.
|
|
27
|
+
Pi virtual models (`pi-virtual`) are not directly supported: their routed
|
|
28
|
+
concrete model is not known to this extension. The normal fallback can still
|
|
29
|
+
select another authenticated concrete model.
|
|
25
30
|
|
|
26
31
|
## DeepSeek
|
|
27
32
|
|
|
@@ -54,10 +59,11 @@ POST https://api.deepseek.com/v1/tools/search
|
|
|
54
59
|
}
|
|
55
60
|
```
|
|
56
61
|
|
|
57
|
-
- `query` is 1–128 Unicode characters, not all whitespace.
|
|
58
|
-
|
|
59
|
-
|
|
60
|
-
|
|
62
|
+
- `query` is 1–128 Unicode characters, not all whitespace. Longer queries
|
|
63
|
+
return a model-facing error with the actual length and the 128-character
|
|
64
|
+
limit; the model should shorten the query and retry. No DeepSeek request is
|
|
65
|
+
sent, no automatic truncation or fallback occurs, and no failure cooldown is
|
|
66
|
+
recorded.
|
|
61
67
|
- `count` is within the documented 1–50 range; this package uses 10.
|
|
62
68
|
- `need_content` is `true`, so `content` can contain the page body. The output
|
|
63
69
|
character guard protects the model context.
|
|
@@ -147,9 +153,18 @@ Supported APIs:
|
|
|
147
153
|
- `azure-openai-responses`
|
|
148
154
|
- `openai-codex-responses`
|
|
149
155
|
|
|
156
|
+
The `openai` provider uses the Responses API with either pi's **Sign in with
|
|
157
|
+
ChatGPT** OAuth credentials or an OpenAI API key (`OPENAI_API_KEY` or pi's
|
|
158
|
+
registry). Pi resolves and refreshes OAuth credentials; the resulting access
|
|
159
|
+
token is sent as a Bearer token. `openai-codex` uses a separate legacy ChatGPT
|
|
160
|
+
OAuth flow and Codex endpoint. Search availability depends on the account,
|
|
161
|
+
subscription, model and OpenAI service.
|
|
162
|
+
|
|
150
163
|
The request uses `tools: [{ "type": "web_search" }]`, `stream: true`, and
|
|
151
|
-
`store: false`.
|
|
152
|
-
|
|
164
|
+
`store: false`. For reasoning models, the request uses the lowest effort
|
|
165
|
+
supported by the model metadata, independently of the conversation's thinking
|
|
166
|
+
level; native xAI does not send this setting. Endpoint resolution appends
|
|
167
|
+
`/responses`, or `/codex/responses` for Codex models. Codex requests add the account id header,
|
|
153
168
|
`originator: codex_cli_rs`, instructions, low verbosity, required tool choice,
|
|
154
169
|
and parallel tool calls.
|
|
155
170
|
|
package/docs/publishing.md
CHANGED
|
@@ -30,7 +30,7 @@ local `pi-web-search` reference checkout, `.env` files, and `DESIGN.md`.
|
|
|
30
30
|
npm run build
|
|
31
31
|
```
|
|
32
32
|
|
|
33
|
-
This produces `dist/pi-better-web-search-0.1.
|
|
33
|
+
This produces `dist/pi-better-web-search-0.1.11.tgz`. The tarball is not
|
|
34
34
|
committed.
|
|
35
35
|
|
|
36
36
|
## Publish
|
|
@@ -42,7 +42,7 @@ npm publish --access public
|
|
|
42
42
|
Alternatively, publish the verified tarball directly:
|
|
43
43
|
|
|
44
44
|
```bash
|
|
45
|
-
npm publish dist/pi-better-web-search-0.1.
|
|
45
|
+
npm publish dist/pi-better-web-search-0.1.11.tgz --access public
|
|
46
46
|
```
|
|
47
47
|
|
|
48
48
|
`prepublishOnly` reruns the checks, tests, and package verification. npm may
|
|
@@ -51,10 +51,10 @@ require browser or OTP authentication.
|
|
|
51
51
|
## Tag and release
|
|
52
52
|
|
|
53
53
|
```bash
|
|
54
|
-
git tag -a v0.1.
|
|
55
|
-
git push origin v0.1.
|
|
56
|
-
gh release create v0.1.
|
|
57
|
-
--title "v0.1.
|
|
54
|
+
git tag -a v0.1.11 -m "v0.1.11"
|
|
55
|
+
git push origin v0.1.11
|
|
56
|
+
gh release create v0.1.11 dist/pi-better-web-search-0.1.11.tgz \
|
|
57
|
+
--title "v0.1.11" \
|
|
58
58
|
--notes-file /path/to/release-notes.md
|
|
59
59
|
```
|
|
60
60
|
|
package/docs/testing.md
CHANGED
|
@@ -17,7 +17,7 @@ npm run verify:package
|
|
|
17
17
|
tarball contains runtime sources, docs, assets, and metadata, while excluding
|
|
18
18
|
tests, scripts, CI files, the local reference checkout, and `DESIGN.md`.
|
|
19
19
|
- `npm run build` runs the checks, tests, package verification, and packs
|
|
20
|
-
`dist/pi-better-web-search-0.1.
|
|
20
|
+
`dist/pi-better-web-search-0.1.9.tgz`.
|
|
21
21
|
|
|
22
22
|
Tests import the TypeScript sources directly. The suite mocks `globalThis.fetch`
|
|
23
23
|
and uses temporary cache directories. Coverage includes:
|
package/lib/candidates.ts
CHANGED
|
@@ -78,10 +78,10 @@ function modelTier(candidate: Candidate): number {
|
|
|
78
78
|
}
|
|
79
79
|
|
|
80
80
|
/**
|
|
81
|
-
* Brand order
|
|
82
|
-
*
|
|
83
|
-
*
|
|
84
|
-
*
|
|
81
|
+
* Brand order among models that already support an adapter in the same family.
|
|
82
|
+
* A custom Responses gateway may expose several brands; OpenAI and Claude keep
|
|
83
|
+
* their named-tier ordering while other brands use flash / base / pro ordering.
|
|
84
|
+
* This ranking does not make an unsupported model API search-capable.
|
|
85
85
|
*/
|
|
86
86
|
function modelBrandRank(id: string): number {
|
|
87
87
|
const normalized = id.toLowerCase();
|
|
@@ -117,10 +117,14 @@ function versionTuple(id: string, family: ProviderFamily): number[] {
|
|
|
117
117
|
if (family === "openai") {
|
|
118
118
|
match = normalized.match(/^(?:gpt|o)[-_ ]?(\d+(?:\.\d+)*)/);
|
|
119
119
|
} else if (family === "anthropic") {
|
|
120
|
-
|
|
121
|
-
|
|
122
|
-
match = normalized.match(/^claude-(\d+)(?:-(\d+))?/)
|
|
123
|
-
|
|
120
|
+
// A date can immediately follow a major version, e.g.
|
|
121
|
+
// claude-sonnet-4-20250514. Do not interpret it as a minor version.
|
|
122
|
+
match = normalized.match(/^claude-(?:haiku|sonnet|opus|fable)-(\d+)(?:-(\d+))?/)
|
|
123
|
+
?? normalized.match(/^claude-(\d+)(?:-(\d+))?/);
|
|
124
|
+
if (match) {
|
|
125
|
+
const minor = match[2];
|
|
126
|
+
return [Number(match[1]), minor && minor.length < 8 ? Number(minor) : 0];
|
|
127
|
+
}
|
|
124
128
|
} else if (family === "google") {
|
|
125
129
|
match = normalized.match(/^(?:gemini|gemma)[-_]?(\d+(?:\.\d+)*)/);
|
|
126
130
|
if (!match) return [];
|
|
@@ -319,8 +323,8 @@ function buildCandidates(
|
|
|
319
323
|
}
|
|
320
324
|
|
|
321
325
|
if (!resolution.fresh && cached && isUsable(cached)) {
|
|
322
|
-
//
|
|
323
|
-
//
|
|
326
|
+
// Do not promote a cached sibling ahead of other providers. Siblings from
|
|
327
|
+
// the same provider remain eligible in the later fallback pass.
|
|
324
328
|
const sameProviderSelected = selected.some(
|
|
325
329
|
(candidate) => candidate.model.provider === cached.model.provider,
|
|
326
330
|
);
|
|
@@ -341,14 +345,10 @@ function buildCandidates(
|
|
|
341
345
|
}
|
|
342
346
|
}
|
|
343
347
|
|
|
344
|
-
//
|
|
345
|
-
//
|
|
346
|
-
//
|
|
347
|
-
//
|
|
348
|
-
// families so every family gets a second chance before any family gets a
|
|
349
|
-
// third, keeping the broad cross-provider coverage that the one-per-family
|
|
350
|
-
// pass provides. A provider-wide runtime failure still skips the rest of that
|
|
351
|
-
// provider id; only model-specific failures reach these siblings.
|
|
348
|
+
// Prefer an interface from each provider before trying sibling models. A
|
|
349
|
+
// single provider may expose many highly ranked models in one family, but a
|
|
350
|
+
// provider-wide failure would make all of them unusable at once. Keep the
|
|
351
|
+
// family round-robin within each pass, then include every remaining sibling.
|
|
352
352
|
const queues = new Map<ProviderFamily, Candidate[]>();
|
|
353
353
|
for (const family of PROVIDER_FAMILIES) {
|
|
354
354
|
const queue = usableFamilyCandidates(resolution, family, isUsable).filter(
|
|
@@ -356,33 +356,50 @@ function buildCandidates(
|
|
|
356
356
|
);
|
|
357
357
|
if (queue.length > 0) queues.set(family, queue);
|
|
358
358
|
}
|
|
359
|
-
|
|
360
|
-
|
|
361
|
-
|
|
362
|
-
progressed
|
|
363
|
-
|
|
364
|
-
|
|
365
|
-
|
|
366
|
-
|
|
367
|
-
|
|
359
|
+
const representedProviders = new Set(selected.map((candidate) => candidate.model.provider));
|
|
360
|
+
for (const distinctProvidersOnly of [true, false]) {
|
|
361
|
+
let progressed = true;
|
|
362
|
+
while (selected.length < cap && progressed) {
|
|
363
|
+
progressed = false;
|
|
364
|
+
for (const family of PROVIDER_FAMILIES) {
|
|
365
|
+
if (selected.length >= cap) break;
|
|
366
|
+
const queue = queues.get(family);
|
|
367
|
+
if (!queue) continue;
|
|
368
|
+
const index = distinctProvidersOnly
|
|
369
|
+
? queue.findIndex((candidate) => !representedProviders.has(candidate.model.provider))
|
|
370
|
+
: 0;
|
|
371
|
+
if (index < 0 || index >= queue.length) continue;
|
|
372
|
+
const [next] = queue.splice(index, 1);
|
|
373
|
+
if (addUnique(selected, next, seen, cap)) {
|
|
374
|
+
representedProviders.add(next.model.provider);
|
|
375
|
+
progressed = true;
|
|
376
|
+
}
|
|
377
|
+
}
|
|
368
378
|
}
|
|
369
379
|
}
|
|
370
380
|
|
|
371
381
|
return selected;
|
|
372
382
|
}
|
|
373
383
|
|
|
374
|
-
|
|
384
|
+
/** The orchestrator can request all candidates and cap actual attempts instead. */
|
|
385
|
+
export function getSearchCandidates(
|
|
386
|
+
resolution: ResolutionContext,
|
|
387
|
+
cap = SEARCH_ATTEMPT_CAP,
|
|
388
|
+
): Candidate[] {
|
|
375
389
|
const cached = resolution.fresh
|
|
376
390
|
? undefined
|
|
377
391
|
: resolveRef(resolution, resolution.cache.search, supportsSearch);
|
|
378
|
-
return buildCandidates(resolution, supportsSearch, cached,
|
|
392
|
+
return buildCandidates(resolution, supportsSearch, cached, cap);
|
|
379
393
|
}
|
|
380
394
|
|
|
381
|
-
export function getFetchCandidates(
|
|
395
|
+
export function getFetchCandidates(
|
|
396
|
+
resolution: ResolutionContext,
|
|
397
|
+
cap = FETCH_ATTEMPT_CAP,
|
|
398
|
+
): Candidate[] {
|
|
382
399
|
const cached = resolution.fresh
|
|
383
400
|
? undefined
|
|
384
401
|
: resolveRef(resolution, resolution.cache.fetch, supportsUrls);
|
|
385
|
-
return buildCandidates(resolution, supportsUrls, cached,
|
|
402
|
+
return buildCandidates(resolution, supportsUrls, cached, cap);
|
|
386
403
|
}
|
|
387
404
|
|
|
388
405
|
export function hasExposedCandidate(resolution: ResolutionContext): boolean {
|
package/lib/format.ts
CHANGED
|
@@ -70,10 +70,17 @@ export function formatSuccess(
|
|
|
70
70
|
export function formatError(
|
|
71
71
|
message: string,
|
|
72
72
|
details: WebSearchDetails,
|
|
73
|
+
prefix = "Failed: ",
|
|
73
74
|
): AgentToolResult<WebSearchDetails> {
|
|
75
|
+
const full = `${prefix}${message}`;
|
|
76
|
+
const limited = truncateText(full, MAX_OUTPUT_CHARS);
|
|
77
|
+
const marker = "[truncated]";
|
|
78
|
+
const text = limited.truncated && MAX_OUTPUT_CHARS >= marker.length
|
|
79
|
+
? `${truncateText(full, MAX_OUTPUT_CHARS - marker.length).text}${marker}`
|
|
80
|
+
: limited.text;
|
|
74
81
|
return {
|
|
75
|
-
content: [{ type: "text", text
|
|
76
|
-
details,
|
|
82
|
+
content: [{ type: "text", text }],
|
|
83
|
+
details: limited.truncated ? { ...details, truncated: true } : details,
|
|
77
84
|
isError: true,
|
|
78
85
|
};
|
|
79
86
|
}
|
package/lib/health.ts
CHANGED
|
@@ -43,10 +43,18 @@ function recordFailure(
|
|
|
43
43
|
provider: string,
|
|
44
44
|
message: string,
|
|
45
45
|
now: number,
|
|
46
|
+
attemptStartedAt: number,
|
|
46
47
|
): void {
|
|
47
48
|
const previous = failures.get(key);
|
|
48
|
-
const consecutiveFailures = (previous?.consecutiveFailures ?? 0) + 1;
|
|
49
49
|
const base = failureCooldownMs();
|
|
50
|
+
if (base === 0) {
|
|
51
|
+
failures.delete(key);
|
|
52
|
+
return;
|
|
53
|
+
}
|
|
54
|
+
// In-flight calls, or last-resort attempts started before expiry, are not a
|
|
55
|
+
// new probe even when they finish after the previous cooldown has expired.
|
|
56
|
+
if (previous && (previous.retryAt > now || attemptStartedAt < previous.retryAt)) return;
|
|
57
|
+
const consecutiveFailures = (previous?.consecutiveFailures ?? 0) + 1;
|
|
50
58
|
const exponent = Math.min(consecutiveFailures - 1, 10);
|
|
51
59
|
const cooldown = Math.min(base * 2 ** exponent, MAX_FAILURE_COOLDOWN_MS);
|
|
52
60
|
failures.set(key, {
|
|
@@ -63,8 +71,9 @@ export function recordProviderFailure(
|
|
|
63
71
|
provider: string,
|
|
64
72
|
message: string,
|
|
65
73
|
now = Date.now(),
|
|
74
|
+
attemptStartedAt = now,
|
|
66
75
|
): void {
|
|
67
|
-
recordFailure(providerFailureKey(phase, provider), phase, provider, message, now);
|
|
76
|
+
recordFailure(providerFailureKey(phase, provider), phase, provider, message, now, attemptStartedAt);
|
|
68
77
|
}
|
|
69
78
|
|
|
70
79
|
/** Remember a single model failure without cooling down its whole provider. */
|
|
@@ -74,8 +83,9 @@ export function recordModelFailure(
|
|
|
74
83
|
model: string,
|
|
75
84
|
message: string,
|
|
76
85
|
now = Date.now(),
|
|
86
|
+
attemptStartedAt = now,
|
|
77
87
|
): void {
|
|
78
|
-
recordFailure(modelFailureKey(phase, provider, model), phase, provider, message, now);
|
|
88
|
+
recordFailure(modelFailureKey(phase, provider, model), phase, provider, message, now, attemptStartedAt);
|
|
79
89
|
}
|
|
80
90
|
|
|
81
91
|
export function clearProviderFailure(phase: ProviderPhase, provider: string): void {
|
|
@@ -91,6 +101,7 @@ export function isProviderCoolingDown(
|
|
|
91
101
|
provider: string,
|
|
92
102
|
now = Date.now(),
|
|
93
103
|
): boolean {
|
|
104
|
+
if (failureCooldownMs() === 0) return false;
|
|
94
105
|
const failure = failures.get(providerFailureKey(phase, provider));
|
|
95
106
|
return !!failure && failure.retryAt > now;
|
|
96
107
|
}
|
|
@@ -101,6 +112,7 @@ export function isModelCoolingDown(
|
|
|
101
112
|
model: string,
|
|
102
113
|
now = Date.now(),
|
|
103
114
|
): boolean {
|
|
115
|
+
if (failureCooldownMs() === 0) return false;
|
|
104
116
|
const failure = failures.get(modelFailureKey(phase, provider, model));
|
|
105
117
|
return !!failure && failure.retryAt > now;
|
|
106
118
|
}
|
|
@@ -12,6 +12,7 @@ import {
|
|
|
12
12
|
readJson,
|
|
13
13
|
responseError,
|
|
14
14
|
} from "./http.ts";
|
|
15
|
+
import { QueryLengthError } from "./types.ts";
|
|
15
16
|
import type {
|
|
16
17
|
ProviderAdapter,
|
|
17
18
|
ProviderFetchEntry,
|
|
@@ -58,35 +59,14 @@ function rethrowAbort(error: unknown, signal: AbortSignal | undefined): void {
|
|
|
58
59
|
throw error;
|
|
59
60
|
}
|
|
60
61
|
|
|
61
|
-
function validateQuery(query: string):
|
|
62
|
-
const length = typeof query === "string" ? Array.from(query).length : 0;
|
|
62
|
+
function validateQuery(query: string): void {
|
|
63
63
|
if (typeof query !== "string" || query.trim().length === 0) {
|
|
64
|
-
|
|
64
|
+
throw new Error(`Invalid query: a non-whitespace query of 1-${DEEPSEEK_MAX_QUERY_LENGTH} Unicode characters is required`);
|
|
65
65
|
}
|
|
66
|
-
|
|
67
|
-
|
|
66
|
+
const length = Array.from(query).length;
|
|
67
|
+
if (length > DEEPSEEK_MAX_QUERY_LENGTH) {
|
|
68
|
+
throw new QueryLengthError("DeepSeek", length, DEEPSEEK_MAX_QUERY_LENGTH);
|
|
68
69
|
}
|
|
69
|
-
return undefined;
|
|
70
|
-
}
|
|
71
|
-
|
|
72
|
-
/**
|
|
73
|
-
* DeepSeek rejects queries longer than 128 Unicode characters. Agent-generated
|
|
74
|
-
* search queries routinely exceed that limit, especially when several parallel
|
|
75
|
-
* calls are issued. Shorten only the provider-bound copy, preferring a word
|
|
76
|
-
* boundary so the tail is not cut in the middle of a term. The original query
|
|
77
|
-
* remains in the model-facing output.
|
|
78
|
-
*/
|
|
79
|
-
export function clampDeepSeekQuery(query: string): string {
|
|
80
|
-
const characters = Array.from(query);
|
|
81
|
-
if (characters.length <= DEEPSEEK_MAX_QUERY_LENGTH) return query;
|
|
82
|
-
|
|
83
|
-
const head = characters.slice(0, DEEPSEEK_MAX_QUERY_LENGTH).join("");
|
|
84
|
-
const boundary = head.search(/\s+\S*$/u);
|
|
85
|
-
// Keep the hard cut when word-trimming would discard too much of the query.
|
|
86
|
-
if (boundary >= Math.floor(DEEPSEEK_MAX_QUERY_LENGTH / 2)) {
|
|
87
|
-
return head.slice(0, boundary).trimEnd();
|
|
88
|
-
}
|
|
89
|
-
return head.trimEnd();
|
|
90
70
|
}
|
|
91
71
|
|
|
92
72
|
function validateFetchUrl(url: string): string | undefined {
|
|
@@ -167,9 +147,7 @@ export const deepseekAdapter: ProviderAdapter = {
|
|
|
167
147
|
): Promise<ProviderSearchResult> {
|
|
168
148
|
checkAbort(signal);
|
|
169
149
|
|
|
170
|
-
|
|
171
|
-
const queryError = validateQuery(effectiveQuery);
|
|
172
|
-
if (queryError) throw new Error(queryError);
|
|
150
|
+
validateQuery(query);
|
|
173
151
|
|
|
174
152
|
const target = await resolveDeepSeekTarget(ctx, model);
|
|
175
153
|
checkAbort(signal);
|
|
@@ -178,7 +156,7 @@ export const deepseekAdapter: ProviderAdapter = {
|
|
|
178
156
|
method: "POST",
|
|
179
157
|
headers: target.headers,
|
|
180
158
|
body: JSON.stringify({
|
|
181
|
-
query
|
|
159
|
+
query,
|
|
182
160
|
count: DEEPSEEK_SEARCH_COUNT,
|
|
183
161
|
need_content: DEEPSEEK_NEED_CONTENT,
|
|
184
162
|
}),
|
|
@@ -227,8 +205,11 @@ export const deepseekAdapter: ProviderAdapter = {
|
|
|
227
205
|
});
|
|
228
206
|
} catch (error) {
|
|
229
207
|
rethrowAbort(error, signal);
|
|
230
|
-
|
|
231
|
-
|
|
208
|
+
const providerError = errorMessage(error);
|
|
209
|
+
entries.push({ url, error: providerError });
|
|
210
|
+
// This request reaches the provider endpoint, so a transport failure is
|
|
211
|
+
// not specific to the target URL. Preserve earlier successes and stop.
|
|
212
|
+
return { entries, providerError };
|
|
232
213
|
}
|
|
233
214
|
checkAbort(signal);
|
|
234
215
|
|
package/lib/providers/http.ts
CHANGED
|
@@ -1,12 +1,57 @@
|
|
|
1
1
|
export class HttpError extends Error {
|
|
2
2
|
readonly status: number;
|
|
3
3
|
readonly body?: string;
|
|
4
|
+
readonly code?: string;
|
|
4
5
|
|
|
5
|
-
constructor(status: number, message: string, body?: string) {
|
|
6
|
+
constructor(status: number, message: string, body?: string, code?: string) {
|
|
6
7
|
super(message);
|
|
7
8
|
this.name = "HttpError";
|
|
8
9
|
this.status = status;
|
|
9
10
|
this.body = body;
|
|
11
|
+
this.code = code;
|
|
12
|
+
}
|
|
13
|
+
}
|
|
14
|
+
|
|
15
|
+
/** Bound untrusted HTTP error bodies before storing or forwarding them. */
|
|
16
|
+
export const MAX_ERROR_BODY_BYTES = 64 * 1024;
|
|
17
|
+
|
|
18
|
+
async function readErrorBody(response: Response): Promise<string> {
|
|
19
|
+
if (!response.body) return "";
|
|
20
|
+
const reader = response.body.getReader();
|
|
21
|
+
const decoder = new TextDecoder();
|
|
22
|
+
let text = "";
|
|
23
|
+
let bytes = 0;
|
|
24
|
+
let done = false;
|
|
25
|
+
let truncated = false;
|
|
26
|
+
try {
|
|
27
|
+
while (true) {
|
|
28
|
+
const chunk = await reader.read();
|
|
29
|
+
if (chunk.done) {
|
|
30
|
+
done = true;
|
|
31
|
+
break;
|
|
32
|
+
}
|
|
33
|
+
const remaining = MAX_ERROR_BODY_BYTES - bytes;
|
|
34
|
+
const part = chunk.value.subarray(0, remaining);
|
|
35
|
+
bytes += part.byteLength;
|
|
36
|
+
text += decoder.decode(part, { stream: true });
|
|
37
|
+
// Stop reading even if this chunk exactly fills the budget; the stream
|
|
38
|
+
// might be unbounded and waiting for another chunk could hang the call.
|
|
39
|
+
if (bytes >= MAX_ERROR_BODY_BYTES) {
|
|
40
|
+
truncated = true;
|
|
41
|
+
break;
|
|
42
|
+
}
|
|
43
|
+
}
|
|
44
|
+
text += decoder.decode();
|
|
45
|
+
return truncated ? `${text}\n[truncated]` : text;
|
|
46
|
+
} finally {
|
|
47
|
+
if (!done) {
|
|
48
|
+
try {
|
|
49
|
+
await reader.cancel();
|
|
50
|
+
} catch {
|
|
51
|
+
// An interrupted response may already be closed.
|
|
52
|
+
}
|
|
53
|
+
}
|
|
54
|
+
reader.releaseLock();
|
|
10
55
|
}
|
|
11
56
|
}
|
|
12
57
|
|
|
@@ -24,22 +69,26 @@ export async function readJson<T = unknown>(response: Response): Promise<T> {
|
|
|
24
69
|
}
|
|
25
70
|
|
|
26
71
|
export async function responseError(response: Response, label: string): Promise<HttpError> {
|
|
27
|
-
const body = await response
|
|
72
|
+
const body = await readErrorBody(response).catch(() => "");
|
|
28
73
|
let detail = body.trim();
|
|
74
|
+
let code: string | undefined;
|
|
29
75
|
|
|
30
76
|
if (detail) {
|
|
31
77
|
try {
|
|
32
78
|
const parsed = JSON.parse(body) as {
|
|
33
|
-
error?: { message?: unknown } | string;
|
|
79
|
+
error?: { message?: unknown; code?: unknown } | string;
|
|
34
80
|
message?: unknown;
|
|
81
|
+
code?: unknown;
|
|
35
82
|
};
|
|
36
|
-
const
|
|
37
|
-
const message =
|
|
83
|
+
const nestedError = typeof parsed.error === "object" && parsed.error !== null ? parsed.error : undefined;
|
|
84
|
+
const message = nestedError?.message ?? (typeof parsed.error === "string" ? parsed.error : parsed.message);
|
|
85
|
+
const errorCode = nestedError?.code ?? parsed.code;
|
|
86
|
+
if (typeof errorCode === "string") code = errorCode;
|
|
38
87
|
if (typeof message === "string" && message.trim()) {
|
|
39
88
|
detail = message.trim();
|
|
40
89
|
}
|
|
41
90
|
} catch {
|
|
42
|
-
// Keep the raw response body when it is not JSON.
|
|
91
|
+
// Keep the bounded raw response body when it is not complete JSON.
|
|
43
92
|
}
|
|
44
93
|
}
|
|
45
94
|
|
|
@@ -48,6 +97,7 @@ export async function responseError(response: Response, label: string): Promise<
|
|
|
48
97
|
response.status,
|
|
49
98
|
`${label} API error (${response.status}${statusText}): ${detail || "no response body"}`,
|
|
50
99
|
body || undefined,
|
|
100
|
+
code,
|
|
51
101
|
);
|
|
52
102
|
}
|
|
53
103
|
|
package/lib/providers/ollama.ts
CHANGED
|
@@ -163,8 +163,11 @@ export const ollamaAdapter: ProviderAdapter = {
|
|
|
163
163
|
});
|
|
164
164
|
} catch (error) {
|
|
165
165
|
rethrowAbort(error, signal);
|
|
166
|
-
|
|
167
|
-
|
|
166
|
+
const providerError = errorMessage(error);
|
|
167
|
+
entries.push({ url, error: providerError });
|
|
168
|
+
// Transport failures reach the provider endpoint, not the target URL.
|
|
169
|
+
// Preserve earlier successes but do not repeat a broken connection.
|
|
170
|
+
return { entries, providerError };
|
|
168
171
|
}
|
|
169
172
|
checkAbort(signal);
|
|
170
173
|
|
package/lib/providers/openai.ts
CHANGED
|
@@ -1,5 +1,5 @@
|
|
|
1
1
|
import type { ExtensionContext } from "@earendil-works/pi-coding-agent";
|
|
2
|
-
import type
|
|
2
|
+
import { clampThinkingLevel, type Api, type Model } from "@earendil-works/pi-ai";
|
|
3
3
|
import {
|
|
4
4
|
buildRequestHeaders,
|
|
5
5
|
getHeader,
|
|
@@ -152,6 +152,14 @@ async function searchResponses(
|
|
|
152
152
|
stream: true,
|
|
153
153
|
store: false,
|
|
154
154
|
};
|
|
155
|
+
// Search is independent of the conversation's thinking setting. Use the
|
|
156
|
+
// lowest supported effort to avoid unnecessary latency and token usage.
|
|
157
|
+
// Native xAI does not accept the same reasoning controls.
|
|
158
|
+
if (family !== "xai" && model.reasoning) {
|
|
159
|
+
const level = clampThinkingLevel(model, "off");
|
|
160
|
+
const mapped = model.thinkingLevelMap?.[level];
|
|
161
|
+
if (mapped !== null) body.reasoning = { effort: mapped ?? (level === "off" ? "none" : level) };
|
|
162
|
+
}
|
|
155
163
|
if (isCodex) {
|
|
156
164
|
body.instructions = "Answer the user's request using web search when needed.";
|
|
157
165
|
body.text = { verbosity: "low" };
|
package/lib/providers/types.ts
CHANGED
|
@@ -4,6 +4,24 @@ import type { Api, Model } from "@earendil-works/pi-ai";
|
|
|
4
4
|
export const PROVIDER_FAMILIES = ["deepseek", "ollama", "google", "openai", "xai", "anthropic"] as const;
|
|
5
5
|
export type ProviderFamily = (typeof PROVIDER_FAMILIES)[number];
|
|
6
6
|
|
|
7
|
+
/** A request validation error that the model can fix and retry. */
|
|
8
|
+
export class QueryLengthError extends Error {
|
|
9
|
+
readonly provider: string;
|
|
10
|
+
readonly actualLength: number;
|
|
11
|
+
readonly maxLength: number;
|
|
12
|
+
|
|
13
|
+
constructor(provider: string, actualLength: number, maxLength: number) {
|
|
14
|
+
super(
|
|
15
|
+
`Search query is too long (${actualLength} Unicode characters). `
|
|
16
|
+
+ `The maximum is ${maxLength} Unicode characters. Shorten the query and retry.`,
|
|
17
|
+
);
|
|
18
|
+
this.name = "QueryLengthError";
|
|
19
|
+
this.provider = provider;
|
|
20
|
+
this.actualLength = actualLength;
|
|
21
|
+
this.maxLength = maxLength;
|
|
22
|
+
}
|
|
23
|
+
}
|
|
24
|
+
|
|
7
25
|
export interface ProviderSearchResult {
|
|
8
26
|
answer?: string;
|
|
9
27
|
results?: unknown;
|
|
@@ -21,6 +39,8 @@ export interface ProviderFetchEntry {
|
|
|
21
39
|
|
|
22
40
|
export interface ProviderFetchResult {
|
|
23
41
|
entries: ProviderFetchEntry[];
|
|
42
|
+
/** A transport failure reaching the provider, not a failure of a target URL. */
|
|
43
|
+
providerError?: string;
|
|
24
44
|
}
|
|
25
45
|
|
|
26
46
|
export interface ProviderAdapter {
|
package/lib/search.ts
CHANGED
|
@@ -4,6 +4,8 @@ import type {
|
|
|
4
4
|
ExtensionContext,
|
|
5
5
|
} from "@earendil-works/pi-coding-agent";
|
|
6
6
|
import {
|
|
7
|
+
FETCH_ATTEMPT_CAP,
|
|
8
|
+
SEARCH_ATTEMPT_CAP,
|
|
7
9
|
getFetchCandidates,
|
|
8
10
|
getSearchCandidates,
|
|
9
11
|
resolveResolutionContext,
|
|
@@ -14,6 +16,7 @@ import { writeCache, type PreferenceCache, type ProviderRef } from "./cache.ts";
|
|
|
14
16
|
import {
|
|
15
17
|
formatError,
|
|
16
18
|
formatSuccess,
|
|
19
|
+
truncateText,
|
|
17
20
|
type WebSearchAttempt,
|
|
18
21
|
type WebSearchDetails,
|
|
19
22
|
type WebSearchOutput,
|
|
@@ -25,9 +28,10 @@ import {
|
|
|
25
28
|
recordModelFailure,
|
|
26
29
|
recordProviderFailure,
|
|
27
30
|
} from "./health.ts";
|
|
31
|
+
import { QueryLengthError } from "./providers/types.ts";
|
|
28
32
|
import { MAX_URLS } from "./schema.ts";
|
|
29
33
|
|
|
30
|
-
export const DEFAULT_ATTEMPT_TIMEOUT_MS =
|
|
34
|
+
export const DEFAULT_ATTEMPT_TIMEOUT_MS = 120_000;
|
|
31
35
|
|
|
32
36
|
export interface UrlValidationError {
|
|
33
37
|
url: string;
|
|
@@ -50,12 +54,22 @@ interface FetchState {
|
|
|
50
54
|
error?: string;
|
|
51
55
|
}
|
|
52
56
|
|
|
57
|
+
const MAX_ERROR_DETAIL_CHARS = 8_192;
|
|
58
|
+
|
|
53
59
|
function errorMessage(error: unknown): string {
|
|
54
60
|
if (error instanceof Error) return error.message;
|
|
55
61
|
if (typeof error === "string") return error;
|
|
56
62
|
return String(error);
|
|
57
63
|
}
|
|
58
64
|
|
|
65
|
+
function limitErrorMessage(message: string): string {
|
|
66
|
+
const marker = "[truncated]";
|
|
67
|
+
const limited = truncateText(message, MAX_ERROR_DETAIL_CHARS);
|
|
68
|
+
return limited.truncated
|
|
69
|
+
? `${truncateText(message, MAX_ERROR_DETAIL_CHARS - marker.length).text}${marker}`
|
|
70
|
+
: message;
|
|
71
|
+
}
|
|
72
|
+
|
|
59
73
|
function summarizeUrlErrors(errors: UrlValidationError[]): string {
|
|
60
74
|
return errors.map((entry) => `${entry.url}: ${entry.error}`).join("; ");
|
|
61
75
|
}
|
|
@@ -203,7 +217,28 @@ const PROVIDER_WIDE_FAILURE_PATTERNS: readonly RegExp[] = [
|
|
|
203
217
|
/\bbytestring\b/i,
|
|
204
218
|
];
|
|
205
219
|
|
|
206
|
-
|
|
220
|
+
const MODEL_PERMISSION_PATTERNS: readonly RegExp[] = [
|
|
221
|
+
/\bmodel[_ -](?:not[_ -](?:found|allowed|available|supported)|access[_ -]denied)\b/i,
|
|
222
|
+
/\bmodels?\b[^\n]{0,200}\b(?:not (?:found|allowed|available|accessible|enabled|supported)|does not exist|access denied|permission denied)\b/i,
|
|
223
|
+
/\b(?:do(?:es)? not have|don't have|no|lack(?:s)?|denied|not (?:allowed|authorized|permitted))\b[^\n]{0,160}\b(?:access|permission|use)\b[^\n]{0,160}\bmodels?\b/i,
|
|
224
|
+
/\b(?:access|permission)\b[^\n]{0,160}\b(?:denied|not (?:granted|allowed|permitted))\b[^\n]{0,160}\bmodels?\b/i,
|
|
225
|
+
/\b(?:access|permission)\b[^\n]{0,160}\bmodels?\b[^\n]{0,160}\b(?:denied|not (?:granted|allowed|permitted))\b/i,
|
|
226
|
+
];
|
|
227
|
+
|
|
228
|
+
export function isProviderWideFailure(message: string, error?: unknown): boolean {
|
|
229
|
+
const details = typeof error === "object" && error !== null
|
|
230
|
+
? error as { status?: unknown; code?: unknown }
|
|
231
|
+
: undefined;
|
|
232
|
+
const isForbidden = details?.status === 403 || details?.status === "403"
|
|
233
|
+
|| /(?:\(|HTTP\s+|status(?:\s+code)?\s*)403\b|\bforbidden\b/i.test(message);
|
|
234
|
+
const code = typeof details?.code === "string" ? details.code : "";
|
|
235
|
+
if (isForbidden && MODEL_PERMISSION_PATTERNS.some((pattern) => pattern.test(`${code} ${message}`))) {
|
|
236
|
+
return false;
|
|
237
|
+
}
|
|
238
|
+
const status = typeof details?.status === "number" || typeof details?.status === "string"
|
|
239
|
+
? Number(details.status)
|
|
240
|
+
: NaN;
|
|
241
|
+
if (status === 401 || status === 403 || status === 429 || (status >= 500 && status < 600)) return true;
|
|
207
242
|
return PROVIDER_WIDE_FAILURE_PATTERNS.some((pattern) => pattern.test(message));
|
|
208
243
|
}
|
|
209
244
|
|
|
@@ -256,17 +291,20 @@ async function runSearch(
|
|
|
256
291
|
onUpdate: AgentToolUpdateCallback | undefined,
|
|
257
292
|
attempts: WebSearchAttempt[],
|
|
258
293
|
): Promise<SearchSuccess | undefined> {
|
|
259
|
-
const candidates = getSearchCandidates(resolution);
|
|
294
|
+
const candidates = getSearchCandidates(resolution, Infinity);
|
|
260
295
|
if (candidates.length === 0) return undefined;
|
|
261
296
|
|
|
262
|
-
//
|
|
263
|
-
//
|
|
264
|
-
// whole attempt budget on one interface.
|
|
297
|
+
// Skipped candidates do not consume the budget. Consider the full discovery
|
|
298
|
+
// set when applying cooldowns so a healthy provider beyond the cap is usable.
|
|
265
299
|
const failedProviders = new Set<string>();
|
|
300
|
+
let attemptCount = 0;
|
|
266
301
|
|
|
267
302
|
for (const candidate of prioritizeCandidates("search", candidates)) {
|
|
268
303
|
if (externalSignal?.aborted) throw abortReason(externalSignal);
|
|
269
304
|
if (failedProviders.has(candidate.model.provider)) continue;
|
|
305
|
+
if (attemptCount >= SEARCH_ATTEMPT_CAP) break;
|
|
306
|
+
attemptCount += 1;
|
|
307
|
+
const attemptStartedAt = Date.now();
|
|
270
308
|
|
|
271
309
|
const timeout = timeoutMs();
|
|
272
310
|
const signal = attemptSignal(externalSignal, timeout);
|
|
@@ -283,22 +321,29 @@ async function runSearch(
|
|
|
283
321
|
return { candidate, result: result ?? {} };
|
|
284
322
|
} catch (error) {
|
|
285
323
|
if (externalSignal?.aborted) throw abortReason(externalSignal);
|
|
286
|
-
|
|
324
|
+
// Input validation is actionable by the model and must not poison health
|
|
325
|
+
// or silently fall through to another provider.
|
|
326
|
+
if (error instanceof QueryLengthError) throw error;
|
|
327
|
+
const rawMessage = errorMessage(error);
|
|
328
|
+
const providerWide = isProviderWideFailure(rawMessage, error);
|
|
329
|
+
const message = limitErrorMessage(rawMessage);
|
|
287
330
|
attempts.push({
|
|
288
331
|
phase: "search",
|
|
289
332
|
provider: candidate.model.provider,
|
|
290
333
|
model: candidate.model.id,
|
|
291
334
|
message,
|
|
292
335
|
});
|
|
293
|
-
if (
|
|
336
|
+
if (providerWide) {
|
|
294
337
|
failedProviders.add(candidate.model.provider);
|
|
295
|
-
recordProviderFailure("search", candidate.model.provider, message);
|
|
338
|
+
recordProviderFailure("search", candidate.model.provider, message, Date.now(), attemptStartedAt);
|
|
296
339
|
} else {
|
|
297
340
|
recordModelFailure(
|
|
298
341
|
"search",
|
|
299
342
|
candidate.model.provider,
|
|
300
343
|
candidate.model.id,
|
|
301
344
|
message,
|
|
345
|
+
Date.now(),
|
|
346
|
+
attemptStartedAt,
|
|
302
347
|
);
|
|
303
348
|
}
|
|
304
349
|
}
|
|
@@ -331,7 +376,7 @@ function assignFetchEntries(
|
|
|
331
376
|
if (index === undefined) continue;
|
|
332
377
|
|
|
333
378
|
if (entry.error || entry.data === undefined) {
|
|
334
|
-
states[index].error = entry.error || "Provider did not return data for this URL";
|
|
379
|
+
states[index].error = limitErrorMessage(entry.error || "Provider did not return data for this URL");
|
|
335
380
|
continue;
|
|
336
381
|
}
|
|
337
382
|
|
|
@@ -369,11 +414,15 @@ async function runFetch(
|
|
|
369
414
|
// As with search, a provider-wide failure is not retried with another model
|
|
370
415
|
// from the same provider id.
|
|
371
416
|
const failedProviders = new Set<string>();
|
|
417
|
+
let attemptCount = 0;
|
|
372
418
|
|
|
373
419
|
for (const candidate of prioritizeCandidates("fetch", candidates)) {
|
|
374
420
|
if (remaining.length === 0) break;
|
|
375
421
|
if (externalSignal?.aborted) throw abortReason(externalSignal);
|
|
376
422
|
if (failedProviders.has(candidate.model.provider)) continue;
|
|
423
|
+
if (attemptCount >= FETCH_ATTEMPT_CAP) break;
|
|
424
|
+
attemptCount += 1;
|
|
425
|
+
const attemptStartedAt = Date.now();
|
|
377
426
|
|
|
378
427
|
const timeout = timeoutMs();
|
|
379
428
|
const signal = attemptSignal(externalSignal, timeout);
|
|
@@ -400,8 +449,21 @@ async function runFetch(
|
|
|
400
449
|
|
|
401
450
|
const assigned = assignFetchEntries(states, remaining, result?.entries ?? [], candidate);
|
|
402
451
|
remaining = assigned.remaining;
|
|
403
|
-
|
|
404
|
-
|
|
452
|
+
if (result?.providerError) {
|
|
453
|
+
const message = limitErrorMessage(result.providerError);
|
|
454
|
+
attempts.push({
|
|
455
|
+
phase: "fetch",
|
|
456
|
+
provider: candidate.model.provider,
|
|
457
|
+
model: candidate.model.id,
|
|
458
|
+
message,
|
|
459
|
+
});
|
|
460
|
+
failedProviders.add(candidate.model.provider);
|
|
461
|
+
recordProviderFailure("fetch", candidate.model.provider, message, Date.now(), attemptStartedAt);
|
|
462
|
+
for (const index of remaining) states[index].error ||= message;
|
|
463
|
+
} else if (assigned.successful > 0) {
|
|
464
|
+
clearProviderFailure("fetch", candidate.model.provider);
|
|
465
|
+
clearModelFailure("fetch", candidate.model.provider, candidate.model.id);
|
|
466
|
+
}
|
|
405
467
|
|
|
406
468
|
if (assigned.successful > 0) {
|
|
407
469
|
// Replace only on a strictly larger success count, so the first
|
|
@@ -413,22 +475,26 @@ async function runFetch(
|
|
|
413
475
|
}
|
|
414
476
|
} catch (error) {
|
|
415
477
|
if (externalSignal?.aborted) throw abortReason(externalSignal);
|
|
416
|
-
const
|
|
478
|
+
const rawMessage = errorMessage(error);
|
|
479
|
+
const providerWide = isProviderWideFailure(rawMessage, error);
|
|
480
|
+
const message = limitErrorMessage(rawMessage);
|
|
417
481
|
attempts.push({
|
|
418
482
|
phase: "fetch",
|
|
419
483
|
provider: candidate.model.provider,
|
|
420
484
|
model: candidate.model.id,
|
|
421
485
|
message,
|
|
422
486
|
});
|
|
423
|
-
if (
|
|
487
|
+
if (providerWide) {
|
|
424
488
|
failedProviders.add(candidate.model.provider);
|
|
425
|
-
recordProviderFailure("fetch", candidate.model.provider, message);
|
|
489
|
+
recordProviderFailure("fetch", candidate.model.provider, message, Date.now(), attemptStartedAt);
|
|
426
490
|
} else {
|
|
427
491
|
recordModelFailure(
|
|
428
492
|
"fetch",
|
|
429
493
|
candidate.model.provider,
|
|
430
494
|
candidate.model.id,
|
|
431
495
|
message,
|
|
496
|
+
Date.now(),
|
|
497
|
+
attemptStartedAt,
|
|
432
498
|
);
|
|
433
499
|
}
|
|
434
500
|
for (const index of remaining) {
|
|
@@ -495,7 +561,12 @@ export async function runWebSearch(
|
|
|
495
561
|
return formatError(message, { attempts, error: message });
|
|
496
562
|
}
|
|
497
563
|
|
|
498
|
-
|
|
564
|
+
try {
|
|
565
|
+
searchSuccess = await runSearch(resolution, query, signal, onUpdate, attempts);
|
|
566
|
+
} catch (error) {
|
|
567
|
+
if (!(error instanceof QueryLengthError)) throw error;
|
|
568
|
+
return formatError(error.message, { attempts, error: error.message }, "");
|
|
569
|
+
}
|
|
499
570
|
if (!searchSuccess) {
|
|
500
571
|
const providerErrors = attemptMessages(attempts, "search");
|
|
501
572
|
const message = providerErrors || "This tool is not available in this conversation.";
|
|
@@ -503,7 +574,7 @@ export async function runWebSearch(
|
|
|
503
574
|
}
|
|
504
575
|
}
|
|
505
576
|
|
|
506
|
-
const fetchCandidates = validFetchRequested ? getFetchCandidates(resolution) : [];
|
|
577
|
+
const fetchCandidates = validFetchRequested ? getFetchCandidates(resolution, Infinity) : [];
|
|
507
578
|
if (validFetchRequested && fetchCandidates.length === 0) {
|
|
508
579
|
const message = "URL fetch is not available in this conversation.";
|
|
509
580
|
// The search half succeeded; remember it even though the URL half did not.
|
package/package.json
CHANGED
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
{
|
|
2
2
|
"name": "pi-better-web-search",
|
|
3
|
-
"version": "0.1.
|
|
3
|
+
"version": "0.1.11",
|
|
4
4
|
"description": "A better provider-native web_search tool for pi: raw results, automatic provider fallback, URL analysis, and native DeepSeek Search/Fetch.",
|
|
5
5
|
"type": "module",
|
|
6
6
|
"license": "MIT",
|
|
@@ -58,8 +58,8 @@
|
|
|
58
58
|
"typebox": "*"
|
|
59
59
|
},
|
|
60
60
|
"devDependencies": {
|
|
61
|
-
"@earendil-works/pi-ai": "1.
|
|
62
|
-
"@earendil-works/pi-coding-agent": "1.
|
|
61
|
+
"@earendil-works/pi-ai": "1.5.2",
|
|
62
|
+
"@earendil-works/pi-coding-agent": "1.5.2",
|
|
63
63
|
"@types/node": "22.19.19",
|
|
64
64
|
"typebox": "1.3.27",
|
|
65
65
|
"typescript": "5.9.3"
|