parseman 0.3.0 → 0.4.0
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.md +53 -29
- package/package.json +2 -1
package/README.md
CHANGED
|
@@ -6,8 +6,6 @@
|
|
|
6
6
|
|
|
7
7
|
Write parsers in TypeScript — fast enough to run as-is, and blazing fast when the bundler macro kicks in. Same code either way; no grammar files, no generated output to check in. Drop the plugin in tests or anywhere a bundler isn't around and everything still works.
|
|
8
8
|
|
|
9
|
-
_Note: Not necessarily production-ready! I still have test cases and sample parsers I want to build to more rigorously test the API and performance._
|
|
10
|
-
|
|
11
9
|
## Benchmarks
|
|
12
10
|
|
|
13
11
|
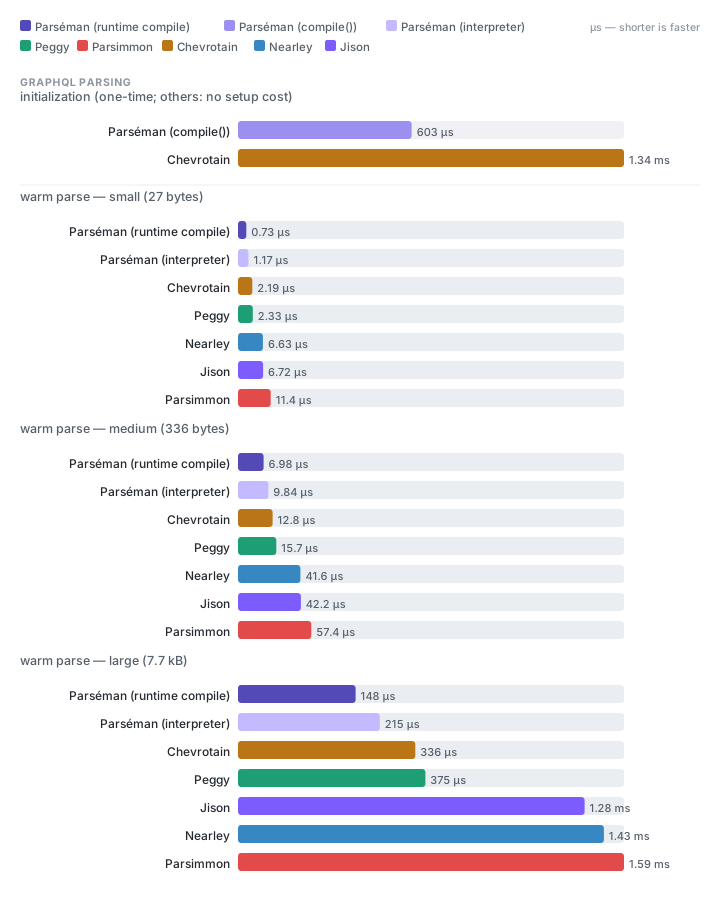
Measured on Apple M2 Pro. Bars show µs per parse — shorter is faster.
|
|
@@ -18,9 +16,9 @@ Measured on Apple M2 Pro. Bars show µs per parse — shorter is faster.
|
|
|
18
16
|
|
|
19
17
|
|
|
20
18
|
|
|
21
|
-
Parséman has three modes — **interpreter** (zero setup, works anywhere), **macro build** (compiled by the bundler plugin at build time, zero runtime cost), and **`.compile()`** (optional runtime JIT). Most production use lands on one of the first two. The initialization section only shows parsers with a nonzero setup cost: `.compile()` costs
|
|
19
|
+
Parséman has three modes — **interpreter** (zero setup, works anywhere), **macro build** (compiled by the bundler plugin at build time, zero runtime cost), and **`.compile()`** (optional runtime JIT). Most production use lands on one of the first two. The initialization section only shows parsers with a nonzero setup cost: `.compile()` costs 75–650 µs depending on grammar size; Chevrotain always costs 840–1,400 µs. Parsers not listed there start for free.
|
|
22
20
|
|
|
23
|
-
On JSON,
|
|
21
|
+
On JSON, CSV, and GraphQL, Parséman macro beats Peggy at every fixture size in the charts above. For CST-building grammars (`node()` rules with trivia capture), the interpreter runs ~2× faster than Chevrotain on the JSON CST fixture while building an equivalent tree.
|
|
24
22
|
|
|
25
23
|
---
|
|
26
24
|
|
|
@@ -118,30 +116,44 @@ Combinator trees — `literal`, `regex`, `sequence`, `choice`, `many`, `oneOrMor
|
|
|
118
116
|
|
|
119
117
|
## Combinators
|
|
120
118
|
|
|
119
|
+
**Terminology:** In this README, **combinator** means any building block that matches input (`literal`, `choice`, `sequence`, …). The `parser()` **function** is different — it wraps a root combinator with document-level options (trivia, line tracking) and gives you `.parse(input)`. Same word family, two roles: combinators compose the grammar; `parser()` configures how you run it.
|
|
120
|
+
|
|
121
|
+
A combinator reads from the input at the current position and succeeds or fails (returning a value on success). Composing combinators with `sequence`, `choice`, `many`, etc. is how you express parsing decisions.
|
|
122
|
+
|
|
123
|
+
`makeWord`, `rules`, and `parser` are **helpers**: definition-time factories or wrappers that *produce* combinators. They never match input themselves.
|
|
124
|
+
|
|
121
125
|
| Combinator | Description |
|
|
122
126
|
|---|---|
|
|
123
127
|
| `literal(s, opts?)` | Exact string match. `opts.caseInsensitive` for locale-aware comparison. |
|
|
124
128
|
| `word(s, boundary?)` | Single keyword with automatic word-boundary guard. |
|
|
125
|
-
| `
|
|
129
|
+
| `keywords(words, opts?)` | Match one of many keywords (longest-first), with optional boundary and case folding. |
|
|
126
130
|
| `regex(pattern)` | Match a regex at the current position. Patterns are optimized via `regexp-tree`. |
|
|
127
|
-
| `sequence(...
|
|
128
|
-
| `choice(...
|
|
129
|
-
| `many(
|
|
130
|
-
| `oneOrMore(
|
|
131
|
-
| `optional(
|
|
132
|
-
| `sepBy(
|
|
133
|
-
| `transform(
|
|
131
|
+
| `sequence(...combinators)` | Match all in order; returns a tuple `[v1, v2, ...]`. Skips trivia between terms when trivia is set. |
|
|
132
|
+
| `choice(...combinators)` | Ordered alternatives (PEG — first match wins). Disjoint first chars → O(1) dispatch. |
|
|
133
|
+
| `many(combinator)` | Zero or more; compiles to a `while` loop. |
|
|
134
|
+
| `oneOrMore(combinator)` | One or more; fails if nothing matches. |
|
|
135
|
+
| `optional(combinator)` | Zero or one; returns `null` on no match. |
|
|
136
|
+
| `sepBy(combinator, sep)` | Zero or more combinator matches separated by `sep`. |
|
|
137
|
+
| `transform(combinator, fn)` | Map the result: `fn(value, span) → newValue`. |
|
|
134
138
|
| `skip(main, skipped)` | Match `main` then `skipped`; return `main`'s value. |
|
|
135
|
-
| `
|
|
136
|
-
| `node(type, parser, build)` | CST/AST rule: captures `parser`'s terminals into `children`/`rawChildren` and trivia offsets into a flat `triviaLog`, then calls `build(children, rawChildren, span, triviaLog)`. |
|
|
139
|
+
| `node(type, combinator, build)` | CST/AST rule: captures the combinator's terminals into `children`/`rawChildren` and trivia offsets into a flat `triviaLog`, then calls `build(children, rawChildren, span, triviaLog)`. |
|
|
137
140
|
| `ref<T>()` | Low-level forward declaration slot (use `rules()` in most cases). |
|
|
138
|
-
| `not(
|
|
141
|
+
| `not(combinator)` | Negative lookahead — succeeds (consuming nothing) when the combinator fails. |
|
|
139
142
|
| `guard(predicate)` | Succeeds only when `predicate(ctx)` returns true; used for context-sensitive rules. |
|
|
140
|
-
| `withCtx(extra,
|
|
141
|
-
| `recover(
|
|
143
|
+
| `withCtx(extra, combinator)` | Merge `extra` into the user context for the duration of the combinator. |
|
|
144
|
+
| `recover(combinator, sentinel)` | On failure, skip input until `sentinel` matches; returns a `CSTError` node. |
|
|
142
145
|
| `scanTo(sentinel, opts?)` | Scan forward until `sentinel` matches (sentinel not consumed). Pass `opts.skip` to treat certain patterns as opaque blobs that may contain the sentinel character. Pass `opts.orEOF: true` to succeed at end-of-input. |
|
|
143
146
|
| `balanced(open, close, opts?)` | Match a single balanced delimited region — e.g. `(…)` or `[…]` — including the delimiters. Primarily used as an element of `scanTo`'s `opts.skip` list. |
|
|
144
147
|
|
|
148
|
+
### Helpers (produce combinators at definition time)
|
|
149
|
+
|
|
150
|
+
| Helper | Description |
|
|
151
|
+
|---|---|
|
|
152
|
+
| `trivia(combinator)` | Label a combinator as skippable filler (whitespace, comments). Does not skip by itself — pass the result to `parser({ trivia })` to turn on auto-skipping between tokens. |
|
|
153
|
+
| `makeWord(boundary?)` | Returns `(str) => Combinator` with a fixed word-boundary class. Not a combinator — see [keyword disambiguation](#ordered-choice-and-keyword-disambiguation). |
|
|
154
|
+
| `rules(factory)` | Named, mutually-recursive rule bundle. See [Named and recursive rules](#named-and-recursive-rules). |
|
|
155
|
+
| `parser({ trivia }, combinator)` | Wrap a root combinator with document-level trivia skipping. See [Whitespace and comment skipping](#whitespace-and-comment-skipping). |
|
|
156
|
+
|
|
145
157
|
---
|
|
146
158
|
|
|
147
159
|
## Performance: collapse opaque shapes into one regex
|
|
@@ -169,14 +181,17 @@ Two takeaways:
|
|
|
169
181
|
|
|
170
182
|
## Whitespace and comment skipping
|
|
171
183
|
|
|
172
|
-
|
|
184
|
+
Skipping filler between tokens is a two-step setup:
|
|
185
|
+
|
|
186
|
+
1. **Define** what counts as filler — usually `regex(/\s+/)`, comments, or both — and wrap it with `trivia()`. This only sets a metadata flag (`isTrivia`); it does not change when the parser runs.
|
|
187
|
+
2. **Activate** skipping by passing that combinator to `parser({ trivia }, combinator)`. That installs it on the parse context so `sequence`, `sepBy`, `choice`, etc. consume matching filler automatically between terms.
|
|
173
188
|
|
|
174
189
|
```ts
|
|
175
190
|
import { parser, regex, trivia, sepBy, literal } from 'parseman'
|
|
176
191
|
|
|
177
|
-
const ws = trivia(regex(/\s*/))
|
|
192
|
+
const ws = trivia(regex(/\s*/)) // "this pattern is filler" — not skipped yet
|
|
178
193
|
const word = regex(/[a-z]+/)
|
|
179
|
-
const list = parser({ trivia: ws }, sepBy(word, literal(',')))
|
|
194
|
+
const list = parser({ trivia: ws }, sepBy(word, literal(','))) // skipping on
|
|
180
195
|
|
|
181
196
|
list.parse('foo , bar , baz')
|
|
182
197
|
// { ok: true, value: ['foo', 'bar', 'baz'], ... }
|
|
@@ -196,19 +211,28 @@ const ws = trivia(many(choice(regex(/\s+/), lineComment, blockComment)
|
|
|
196
211
|
|
|
197
212
|
`choice()` uses PEG ordered-choice semantics: first match wins. **Order matters.**
|
|
198
213
|
|
|
199
|
-
For keywords — where `if` should not match the prefix of `ifdef` — use `word()
|
|
214
|
+
For keywords — where `if` should not match the prefix of `ifdef` — use the `word` combinator. Pass a custom **boundary** (the character class that must *not* follow the match) per call, or use `makeWord` to bake one boundary into a small factory:
|
|
200
215
|
|
|
201
216
|
```ts
|
|
202
|
-
|
|
217
|
+
import { word, makeWord, choice, regex } from 'parseman'
|
|
218
|
+
|
|
219
|
+
word('true') // combinator — default boundary
|
|
220
|
+
word('color', 'A-Za-z0-9_-') // combinator — one-off custom boundary
|
|
221
|
+
|
|
222
|
+
// Helper — returns a function that produces combinators (not a combinator itself)
|
|
223
|
+
const kw = makeWord()
|
|
224
|
+
const cssKw = makeWord('A-Za-z0-9_-')
|
|
203
225
|
|
|
204
226
|
const token = choice(
|
|
205
|
-
kw('if'),
|
|
227
|
+
kw('if'), // each call yields a combinator
|
|
206
228
|
kw('else'),
|
|
207
|
-
|
|
208
|
-
regex(/[a-zA-Z_]\w*/),
|
|
229
|
+
cssKw('color'),
|
|
230
|
+
regex(/[a-zA-Z_]\w*/), // ident fallback
|
|
209
231
|
)
|
|
210
232
|
```
|
|
211
233
|
|
|
234
|
+
`makeWord` is optional — `(s) => word(s, 'A-Za-z0-9_-')` is equivalent.
|
|
235
|
+
|
|
212
236
|
Or build the boundary guard by hand with `not()`:
|
|
213
237
|
|
|
214
238
|
```ts
|
|
@@ -290,7 +314,7 @@ value.define(choice(object, array, str, num, bool, nil))
|
|
|
290
314
|
|
|
291
315
|
## Grammars that build an AST
|
|
292
316
|
|
|
293
|
-
For grammars that produce a typed CST/AST, support incremental re-parsing, or care about trivia, wrap each rule in `node(type,
|
|
317
|
+
For grammars that produce a typed CST/AST, support incremental re-parsing, or care about trivia, wrap each rule in `node(type, combinator, build)`. parseman captures the rule's terminals into `children` / `rawChildren` and records trivia as flat `[start, end, insertIdx, …]` triples in `triviaLog`, then hands all four to `build(children, rawChildren, span, triviaLog)`. **Capture is the library's job:** you don't wrap terminals to recover their spans, and you don't reconstruct trivia — it's collected as the parser runs, in both the interpreter and the compiled build. Use `buildTriviaIndex(tree, input)` to turn `triviaLog` into a before/after lookup table.
|
|
294
318
|
|
|
295
319
|
```ts
|
|
296
320
|
import { rules, parser, node, regex, literal, sequence, many, trivia } from 'parseman'
|
|
@@ -316,7 +340,7 @@ Expr.parse('1 + 2 + 3', 0, { trackLines: false })
|
|
|
316
340
|
- **`rawChildren`** — structural children only (same items as `children`, without trivia tokens).
|
|
317
341
|
- **`triviaLog`** — flat `[start, end, insertIdx, …]` triples for whitespace/comments consumed between terms. `insertIdx` is the `rawChildren` index before which the trivia was consumed. Pass the tree to `buildTriviaIndex(tree, input)` for a `before`/`after` map of trivia tokens — useful for whitespace-sensitive syntax (e.g. CSS `div p` vs `div.p`).
|
|
318
342
|
|
|
319
|
-
Each rule returned from the factory is independently callable — `Expr`, `Num` above are the **rule registry** incremental re-parsing needs. Wrap a rule's inner
|
|
343
|
+
Each rule returned from the factory is independently callable — `Expr`, `Num` above are the **rule registry** incremental re-parsing needs. Wrap a rule's inner combinator in `parser({ trivia }, combinator)` so trivia-skipping is baked in regardless of which rule you start from; the macro compiles the wrapper (and all capture) away to flat JS.
|
|
320
344
|
|
|
321
345
|
> `transform(p, fn)` is still the tool for plain value-mapping (no children/trivia). `node()` is for CST/AST rules — it adds the capture `transform` doesn't. Both compile under the macro.
|
|
322
346
|
|
|
@@ -383,7 +407,7 @@ export const { Expr } = rules<{ Expr: Combinator<Node> }>(g => {
|
|
|
383
407
|
|
|
384
408
|
`withCtx` and `guard` implement context-sensitive rules without mutating shared state, and they compose into `rules()` like any other combinator.
|
|
385
409
|
|
|
386
|
-
`withCtx(extra,
|
|
410
|
+
`withCtx(extra, combinator)` merges `extra` into the user context for the duration of the combinator. `guard(predicate)` succeeds only when `predicate(ctx)` returns true, gating a rule behind runtime context.
|
|
387
411
|
|
|
388
412
|
```ts
|
|
389
413
|
import { rules, withCtx, guard, many, sequence, choice, literal, regex, trivia, parser } from 'parseman'
|
|
@@ -406,7 +430,7 @@ export const { Program } = rules<{ Program: Combinator<unknown> }>(g => {
|
|
|
406
430
|
|
|
407
431
|
## Error recovery
|
|
408
432
|
|
|
409
|
-
`recover(
|
|
433
|
+
`recover(combinator, sentinel)` wraps a combinator so that on failure it skips forward until `sentinel` matches, then returns a `CSTError` node instead of bailing on the whole parse. Error recovery is never pretty, but at least you can keep going.
|
|
410
434
|
|
|
411
435
|
```ts
|
|
412
436
|
import { recover, scanTo, balanced, literal } from 'parseman'
|
package/package.json
CHANGED
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
{
|
|
2
2
|
"name": "parseman",
|
|
3
|
-
"version": "0.
|
|
3
|
+
"version": "0.4.0",
|
|
4
4
|
"description": "Parser combinators that compile to optimized JavaScript — use as a library or as a build-time macro",
|
|
5
5
|
"type": "module",
|
|
6
6
|
"author": "Matthew Dean <matthew-dean@users.noreply.github.com>",
|
|
@@ -35,6 +35,7 @@
|
|
|
35
35
|
"test:watch": "vitest",
|
|
36
36
|
"typecheck": "tsc",
|
|
37
37
|
"bench": "node --import tsx/esm bench/run.ts",
|
|
38
|
+
"build:chevrotain-bench": "node --import tsx/esm scripts/build-chevrotain-bench.mjs",
|
|
38
39
|
"bench:compile-grammars": "peggy --format es -o bench/json-parser.js bench/json.pegjs && peggy --format es -o bench/csv-parser.js bench/csv.pegjs && peggy --format es -o bench/graphqlite-parser.js bench/graphqlite.pegjs"
|
|
39
40
|
},
|
|
40
41
|
"keywords": [
|