parseman 0.1.7 → 0.2.0
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.md +27 -31
- package/package.json +5 -3
package/README.md
CHANGED
|
@@ -6,6 +6,8 @@
|
|
|
6
6
|
|
|
7
7
|
Write parsers in TypeScript — fast enough to run as-is, and blazing fast when the bundler macro kicks in. Same code either way; no grammar files, no generated output to check in. Drop the plugin in tests or anywhere a bundler isn't around and everything still works.
|
|
8
8
|
|
|
9
|
+
_Note: Not necessarily production-ready! I still have test cases and sample parsers I want to build to more rigorously test the API and performance._
|
|
10
|
+
|
|
9
11
|
## Benchmarks
|
|
10
12
|
|
|
11
13
|
Measured on Apple M2 Pro. Bars show µs per parse — shorter is faster.
|
|
@@ -14,7 +16,9 @@ Measured on Apple M2 Pro. Bars show µs per parse — shorter is faster.
|
|
|
14
16
|
|
|
15
17
|

|
|
16
18
|
|
|
17
|
-
|
|
19
|
+
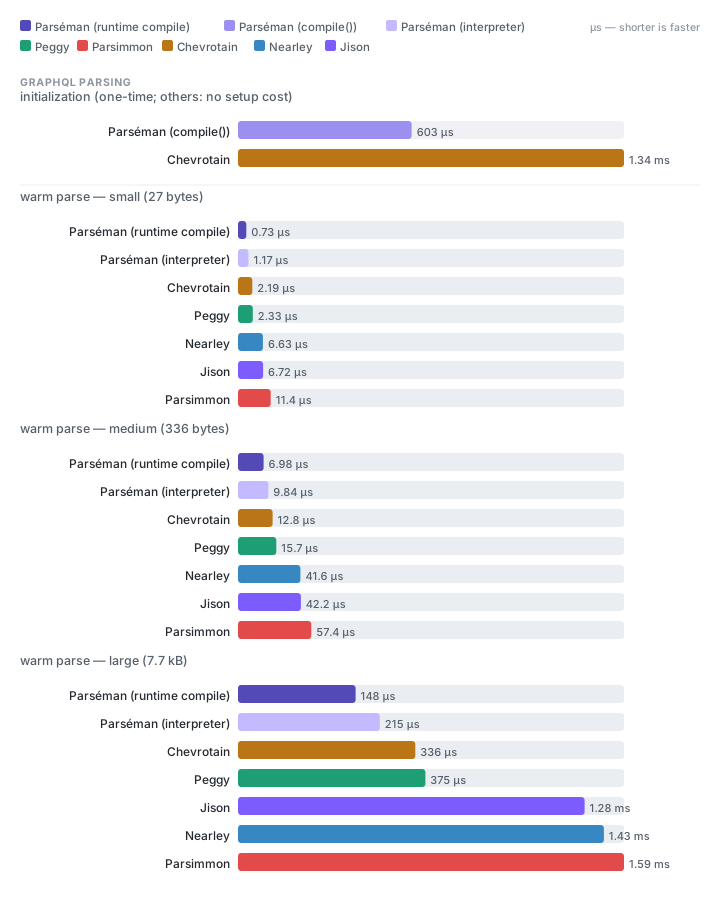
|
|
20
|
+
|
|
21
|
+
On JSON, Parséman compiled matches Peggy at small and medium sizes; Peggy pulls ahead by ~10% at 12 kB — it's been doing this a while. On CSV and GraphQL, where the grammar is non-recursive or fully inlineable, Parséman compiled is the clear winner. The `w/ .compile()` bar shows total time including the one-time compile step; the dark overlay shows parse-only time (same compiled code as the macro build).
|
|
18
22
|
|
|
19
23
|
---
|
|
20
24
|
|
|
@@ -124,8 +128,8 @@ Pure combinator trees — `literal`, `regex`, `sequence`, `choice`, `many`, `one
|
|
|
124
128
|
| `sepBy(parser, sep)` | Zero or more `parser` separated by `sep`. |
|
|
125
129
|
| `transform(parser, fn)` | Map the result: `fn(value, span) → newValue`. |
|
|
126
130
|
| `skip(main, skipped)` | Match `main` then `skipped`; return `main`'s value. |
|
|
127
|
-
| `
|
|
128
|
-
| `ref<T>()` | Low-level forward declaration slot (use `
|
|
131
|
+
| `rules(factory)` | Named grammar rules — no forward declarations needed, handles mutual recursion. |
|
|
132
|
+
| `ref<T>()` | Low-level forward declaration slot (use `rules()` in most cases). |
|
|
129
133
|
| `not(parser)` | Negative lookahead — succeeds (consuming nothing) when `parser` fails. |
|
|
130
134
|
| `guard(predicate)` | Succeeds only when `predicate(ctx)` returns true; used for context-sensitive rules. |
|
|
131
135
|
| `withCtx(extra, parser)` | Merge `extra` into the user context for the duration of `parser`. |
|
|
@@ -137,16 +141,16 @@ Pure combinator trees — `literal`, `regex`, `sequence`, `choice`, `many`, `one
|
|
|
137
141
|
|
|
138
142
|
## Whitespace and comment skipping
|
|
139
143
|
|
|
140
|
-
|
|
144
|
+
Wrap your root combinator with `parser()` to declare trivia — whitespace and comments to skip between tokens. This bakes the setting into the combinator tree so all modes (interpreter, `compile()`, macro build) behave identically:
|
|
141
145
|
|
|
142
146
|
```ts
|
|
143
|
-
import { regex, sepBy, literal
|
|
147
|
+
import { parser, regex, trivia, sepBy, literal } from 'parseman'
|
|
144
148
|
|
|
145
|
-
const ws = regex(/\s*/)
|
|
149
|
+
const ws = trivia(regex(/\s*/))
|
|
146
150
|
const word = regex(/[a-z]+/)
|
|
147
|
-
const list = sepBy(word, literal(','))
|
|
151
|
+
const list = parser({ trivia: ws }, sepBy(word, literal(',')))
|
|
148
152
|
|
|
149
|
-
parse(
|
|
153
|
+
list.parse('foo , bar , baz')
|
|
150
154
|
// { ok: true, value: ['foo', 'bar', 'baz'], ... }
|
|
151
155
|
```
|
|
152
156
|
|
|
@@ -155,15 +159,7 @@ Multiple trivia types — whitespace and comments — combine with `choice()` an
|
|
|
155
159
|
```ts
|
|
156
160
|
const lineComment = sequence(literal('//'), regex(/[^\n]*/))
|
|
157
161
|
const blockComment = sequence(literal('/*'), scanTo(literal('*/'), []))
|
|
158
|
-
const
|
|
159
|
-
```
|
|
160
|
-
|
|
161
|
-
Use `grammar(opts, root)` instead of the `parse()` trivia option when you want trivia only for a subtree within a larger parse:
|
|
162
|
-
|
|
163
|
-
```ts
|
|
164
|
-
import { grammar } from 'parseman'
|
|
165
|
-
|
|
166
|
-
const jsonValue = grammar({ trivia: ws }, choice(object, array, str, num, bool, nil))
|
|
162
|
+
const ws = trivia(many(choice(regex(/\s+/), lineComment, blockComment)))
|
|
167
163
|
```
|
|
168
164
|
|
|
169
165
|
---
|
|
@@ -196,20 +192,20 @@ const op = choice(literal('instanceof'), literal('in'), literal('if'))
|
|
|
196
192
|
|
|
197
193
|
---
|
|
198
194
|
|
|
199
|
-
##
|
|
195
|
+
## Named and recursive rules
|
|
200
196
|
|
|
201
|
-
Use `
|
|
197
|
+
Use `rules()` when your combinators need to reference each other by name. Pass a factory that receives all rule names as ready-to-use references and returns the definitions:
|
|
202
198
|
|
|
203
199
|
```ts
|
|
204
|
-
import { parser, choice, sequence, literal, sepBy, transform, regex } from 'parseman'
|
|
200
|
+
import { rules, parser, choice, sequence, literal, sepBy, transform, trivia, regex } from 'parseman'
|
|
205
201
|
import type { Combinator } from 'parseman'
|
|
206
202
|
|
|
207
203
|
type JSON = null | boolean | number | string | JSON[] | Record<string, JSON>
|
|
208
204
|
|
|
209
|
-
const ws = regex(/[ \t\n\r]*/)
|
|
205
|
+
const ws = trivia(regex(/[ \t\n\r]*/))
|
|
210
206
|
|
|
211
|
-
const { value } =
|
|
212
|
-
const comma =
|
|
207
|
+
const { value } = rules<{ value: Combinator<JSON> }>(g => {
|
|
208
|
+
const comma = literal(',')
|
|
213
209
|
|
|
214
210
|
const array = transform(
|
|
215
211
|
sequence(literal('['), sepBy(g.value, comma), literal(']')),
|
|
@@ -225,26 +221,26 @@ const { value } = parser<{ value: Combinator<JSON> }>(g => {
|
|
|
225
221
|
)
|
|
226
222
|
|
|
227
223
|
return {
|
|
228
|
-
value:
|
|
229
|
-
{ trivia: ws },
|
|
230
|
-
choice(object, array, jsonString, jsonNumber, jsonBool, jsonNull)
|
|
231
|
-
) as Combinator<JSON>,
|
|
224
|
+
value: choice(object, array, jsonString, jsonNumber, jsonBool, jsonNull) as Combinator<JSON>,
|
|
232
225
|
}
|
|
233
226
|
})
|
|
227
|
+
|
|
228
|
+
export const jsonParser = parser({ trivia: ws }, value)
|
|
229
|
+
jsonParser.parse('{ "a": 1 }')
|
|
234
230
|
```
|
|
235
231
|
|
|
236
|
-
`g.value` is a
|
|
232
|
+
`g.value` is a reference that works anywhere inside the factory regardless of order. Local helpers (`comma`, `pair`, `object`) that don't need to be cross-referenced can be plain `const`. Only put a rule in the returned object if other rules need to reach it as `g.xxx`.
|
|
237
233
|
|
|
238
|
-
> **Macro
|
|
234
|
+
> **Macro and `rules()`:** The plugin fully compiles `rules()` factories, including recursive ones. It emits mutually recursive named functions (`_pf0` etc.) so the cycle is broken. Add `with { type: 'macro' }` to your import and the entire grammar — recursive rules included — is inlined at build time.
|
|
239
235
|
|
|
240
236
|
### `ref<T>()` — low-level forward declaration
|
|
241
237
|
|
|
242
|
-
`
|
|
238
|
+
`rules()` handles forward references automatically. `ref<T>()` is the lower-level primitive it uses internally, exposed for cases where you need a single forward slot outside of a `rules()` call:
|
|
243
239
|
|
|
244
240
|
```ts
|
|
245
241
|
const value = ref<JSON>()
|
|
246
242
|
// ... build parsers that use value ...
|
|
247
|
-
value.define(
|
|
243
|
+
value.define(choice(object, array, str, num, bool, nil))
|
|
248
244
|
```
|
|
249
245
|
|
|
250
246
|
---
|
package/package.json
CHANGED
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
{
|
|
2
2
|
"name": "parseman",
|
|
3
|
-
"version": "0.
|
|
3
|
+
"version": "0.2.0",
|
|
4
4
|
"description": "Parser combinators that compile to optimized JavaScript — use as a library or as a build-time macro",
|
|
5
5
|
"type": "module",
|
|
6
6
|
"author": "Matthew Dean <matthew-dean@users.noreply.github.com>",
|
|
@@ -34,7 +34,8 @@
|
|
|
34
34
|
"test": "vitest run",
|
|
35
35
|
"test:watch": "vitest",
|
|
36
36
|
"typecheck": "tsc",
|
|
37
|
-
"bench": "node --import tsx/esm bench/run.ts"
|
|
37
|
+
"bench": "node --import tsx/esm bench/run.ts",
|
|
38
|
+
"bench:compile-grammars": "peggy --format es -o bench/json-parser.js bench/json.pegjs && peggy --format es -o bench/csv-parser.js bench/csv.pegjs && peggy --format es -o bench/graphqlite-parser.js bench/graphqlite.pegjs"
|
|
38
39
|
},
|
|
39
40
|
"keywords": [
|
|
40
41
|
"parser",
|
|
@@ -56,7 +57,8 @@
|
|
|
56
57
|
"tsx": "~4.22.4",
|
|
57
58
|
"typescript": "7.0.1-rc",
|
|
58
59
|
"vite": "~8.0.16",
|
|
59
|
-
"vitest": "~4.1.9"
|
|
60
|
+
"vitest": "~4.1.9",
|
|
61
|
+
"xregexp": "~5.1.2"
|
|
60
62
|
},
|
|
61
63
|
"dependencies": {
|
|
62
64
|
"magic-string": "~0.30.21",
|