llmxray 0.5.0 → 0.6.0
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.ar.md +305 -302
- package/README.fr.md +301 -298
- package/README.md +301 -298
- package/README.sr.md +301 -298
- package/README.zh-CN.md +301 -298
- package/dist/assets/{AITrainingPage-BGxiNftI.js → AITrainingPage-E06gN8gf.js} +1 -1
- package/dist/assets/{AnalyticsPage-Ct-sjfwM.js → AnalyticsPage-DE1P_0ls.js} +1 -1
- package/dist/assets/BenchmarkPage-aPSp8X68.js +31 -0
- package/dist/assets/CacheLabPage-DK6ysPiC.js +3 -0
- package/dist/assets/{ComparisonPage-BnJNpxsl.js → ComparisonPage-B-TTYJzF.js} +1 -1
- package/dist/assets/{CostDashboardPage-B4NDxJsX.js → CostDashboardPage-uaU9LjEe.js} +1 -1
- package/dist/assets/{DashboardPage-BGQp7-l9.js → DashboardPage-i7XFboZS.js} +1 -1
- package/dist/assets/{EmbeddingsPage-VBfXkb7Z.js → EmbeddingsPage-BIj9zAA3.js} +1 -1
- package/dist/assets/{FimPlaygroundPage-DLoI_Bvm.js → FimPlaygroundPage-BQLvqvU_.js} +1 -1
- package/dist/assets/{GoogleCallbackPage-Cs3tBy_I.js → GoogleCallbackPage-eAe26FFg.js} +1 -1
- package/dist/assets/{JsonTreeNode-BSiw1fzq.js → JsonTreeNode-CWxvNXOX.js} +1 -1
- package/dist/assets/{ModelCapabilityIcons.vue_vue_type_script_setup_true_lang-BEGN0dLS.js → ModelCapabilityIcons.vue_vue_type_script_setup_true_lang-B5ZTvJWj.js} +1 -1
- package/dist/assets/ProtocolObservatoryPage--sesoYfn.js +2 -0
- package/dist/assets/{RAGPage-CnnZW7un.js → RAGPage-CEwQVaIo.js} +1 -1
- package/dist/assets/SessionPage-BZ6kBsHI.js +15 -0
- package/dist/assets/SettingsPage-CnF1KHWK.js +1 -0
- package/dist/assets/{StatusBadge.vue_vue_type_script_setup_true_lang-DO0LFtqz.js → StatusBadge.vue_vue_type_script_setup_true_lang-BGo19Xph.js} +1 -1
- package/dist/assets/{StorageGauge.vue_vue_type_style_index_0_lang-BvYHZigP.js → StorageGauge.vue_vue_type_style_index_0_lang-CUFDMHxV.js} +1 -1
- package/dist/assets/{SystemPage-BEGyNOxu.js → SystemPage-B6rcHN5S.js} +2 -2
- package/dist/assets/{TabBar.vue_vue_type_script_setup_true_lang-BwHA1qGL.js → TabBar.vue_vue_type_script_setup_true_lang-C0hGnp0C.js} +1 -1
- package/dist/assets/{TokenStreamDisplay.vue_vue_type_script_setup_true_lang-DyRMkTKm.js → TokenStreamDisplay.vue_vue_type_script_setup_true_lang-CW2jbXwZ.js} +1 -1
- package/dist/assets/{ToolWorkshopPage-CNhpkdiG.js → ToolWorkshopPage-DmrV0xap.js} +1 -1
- package/dist/assets/{agent-store-Ak5tH3gE.js → agent-store--SqycFe6.js} +1 -1
- package/dist/assets/{canvas-ai-db-Bw1M5Zgc.js → canvas-ai-db-Da1vIVOq.js} +1 -1
- package/dist/assets/{download-DgBo5doZ.js → download-CUsL7GrM.js} +1 -1
- package/dist/assets/format-CKxSMkvr.js +1 -0
- package/dist/assets/{generate-service-D1KjeWIo.js → generate-service-BZdEHgFU.js} +1 -1
- package/dist/assets/{google-auth-store-Db6JKC8L.js → google-auth-store-DXrzgrLv.js} +1 -1
- package/dist/assets/{index-BM7fRtY0.js → index-BPkqt5Qe.js} +1 -1
- package/dist/assets/{index-aU4tMz4Z.css → index-C78FkuPP.css} +1 -1
- package/dist/assets/{index-YmhR__TY.js → index-C8P_C63i.js} +1 -1
- package/dist/assets/{index-S2vqeDf7.js → index-YRiA3BUj.js} +12 -12
- package/dist/assets/{info-47X0r1B2.js → info-DH8FG2G3.js} +1 -1
- package/dist/assets/{metrics-store-DzujlkfW.js → metrics-store-BCparPrV.js} +1 -1
- package/dist/assets/{papaparse.min-D0aQsTQw.js → papaparse.min-Dopi_5A-.js} +1 -1
- package/dist/assets/{pencil-B-eZ2Kq9.js → pencil-gkZEyblB.js} +1 -1
- package/dist/assets/{play-DT41vD7M.js → play-HRQny-4Y.js} +1 -1
- package/dist/assets/{rag-store-gqowRN8t.js → rag-store-D0yMVMjG.js} +3 -3
- package/dist/assets/{session-store-BO1u_qJQ.js → session-store-2bGNgO7a.js} +1 -1
- package/dist/assets/{share-2-IBretU3M.js → share-2-c3XzX2pt.js} +1 -1
- package/dist/assets/{square-CbKkOlNA.js → square-CqZgk1mI.js} +1 -1
- package/dist/assets/{storage-store-GsT1cPEh.js → storage-store-BLDOaasz.js} +1 -1
- package/dist/assets/stream-handler-BGYCTeOR.js +4 -0
- package/dist/assets/{tool-workshop-store-BLoF0Gob.js → tool-workshop-store-DBnJxusu.js} +1 -1
- package/dist/assets/{toolcall-store-BEFdRqL-.js → toolcall-store-CJSLkRLe.js} +1 -1
- package/dist/assets/{trash-2-BdlHNMOp.js → trash-2-DU091nIw.js} +1 -1
- package/dist/index.html +2 -2
- package/package.json +9 -1
- package/dist/assets/BenchmarkPage-q41YsHY8.js +0 -31
- package/dist/assets/ProtocolObservatoryPage-CgunJ_Wi.js +0 -2
- package/dist/assets/SessionPage-NE_x02_4.js +0 -15
- package/dist/assets/SettingsPage-DTpQIrlG.js +0 -1
- package/dist/assets/format-BqVZ9rwM.js +0 -1
- package/dist/assets/stream-handler-B5y5PItW.js +0 -4
package/README.md
CHANGED
|
@@ -1,298 +1,301 @@
|
|
|
1
|
-
<p align="center">
|
|
2
|
-
<img src="https://raw.githubusercontent.com/LogneBudo/llmxray/master/public/favicon.svg" alt="LLMxRay" width="80" />
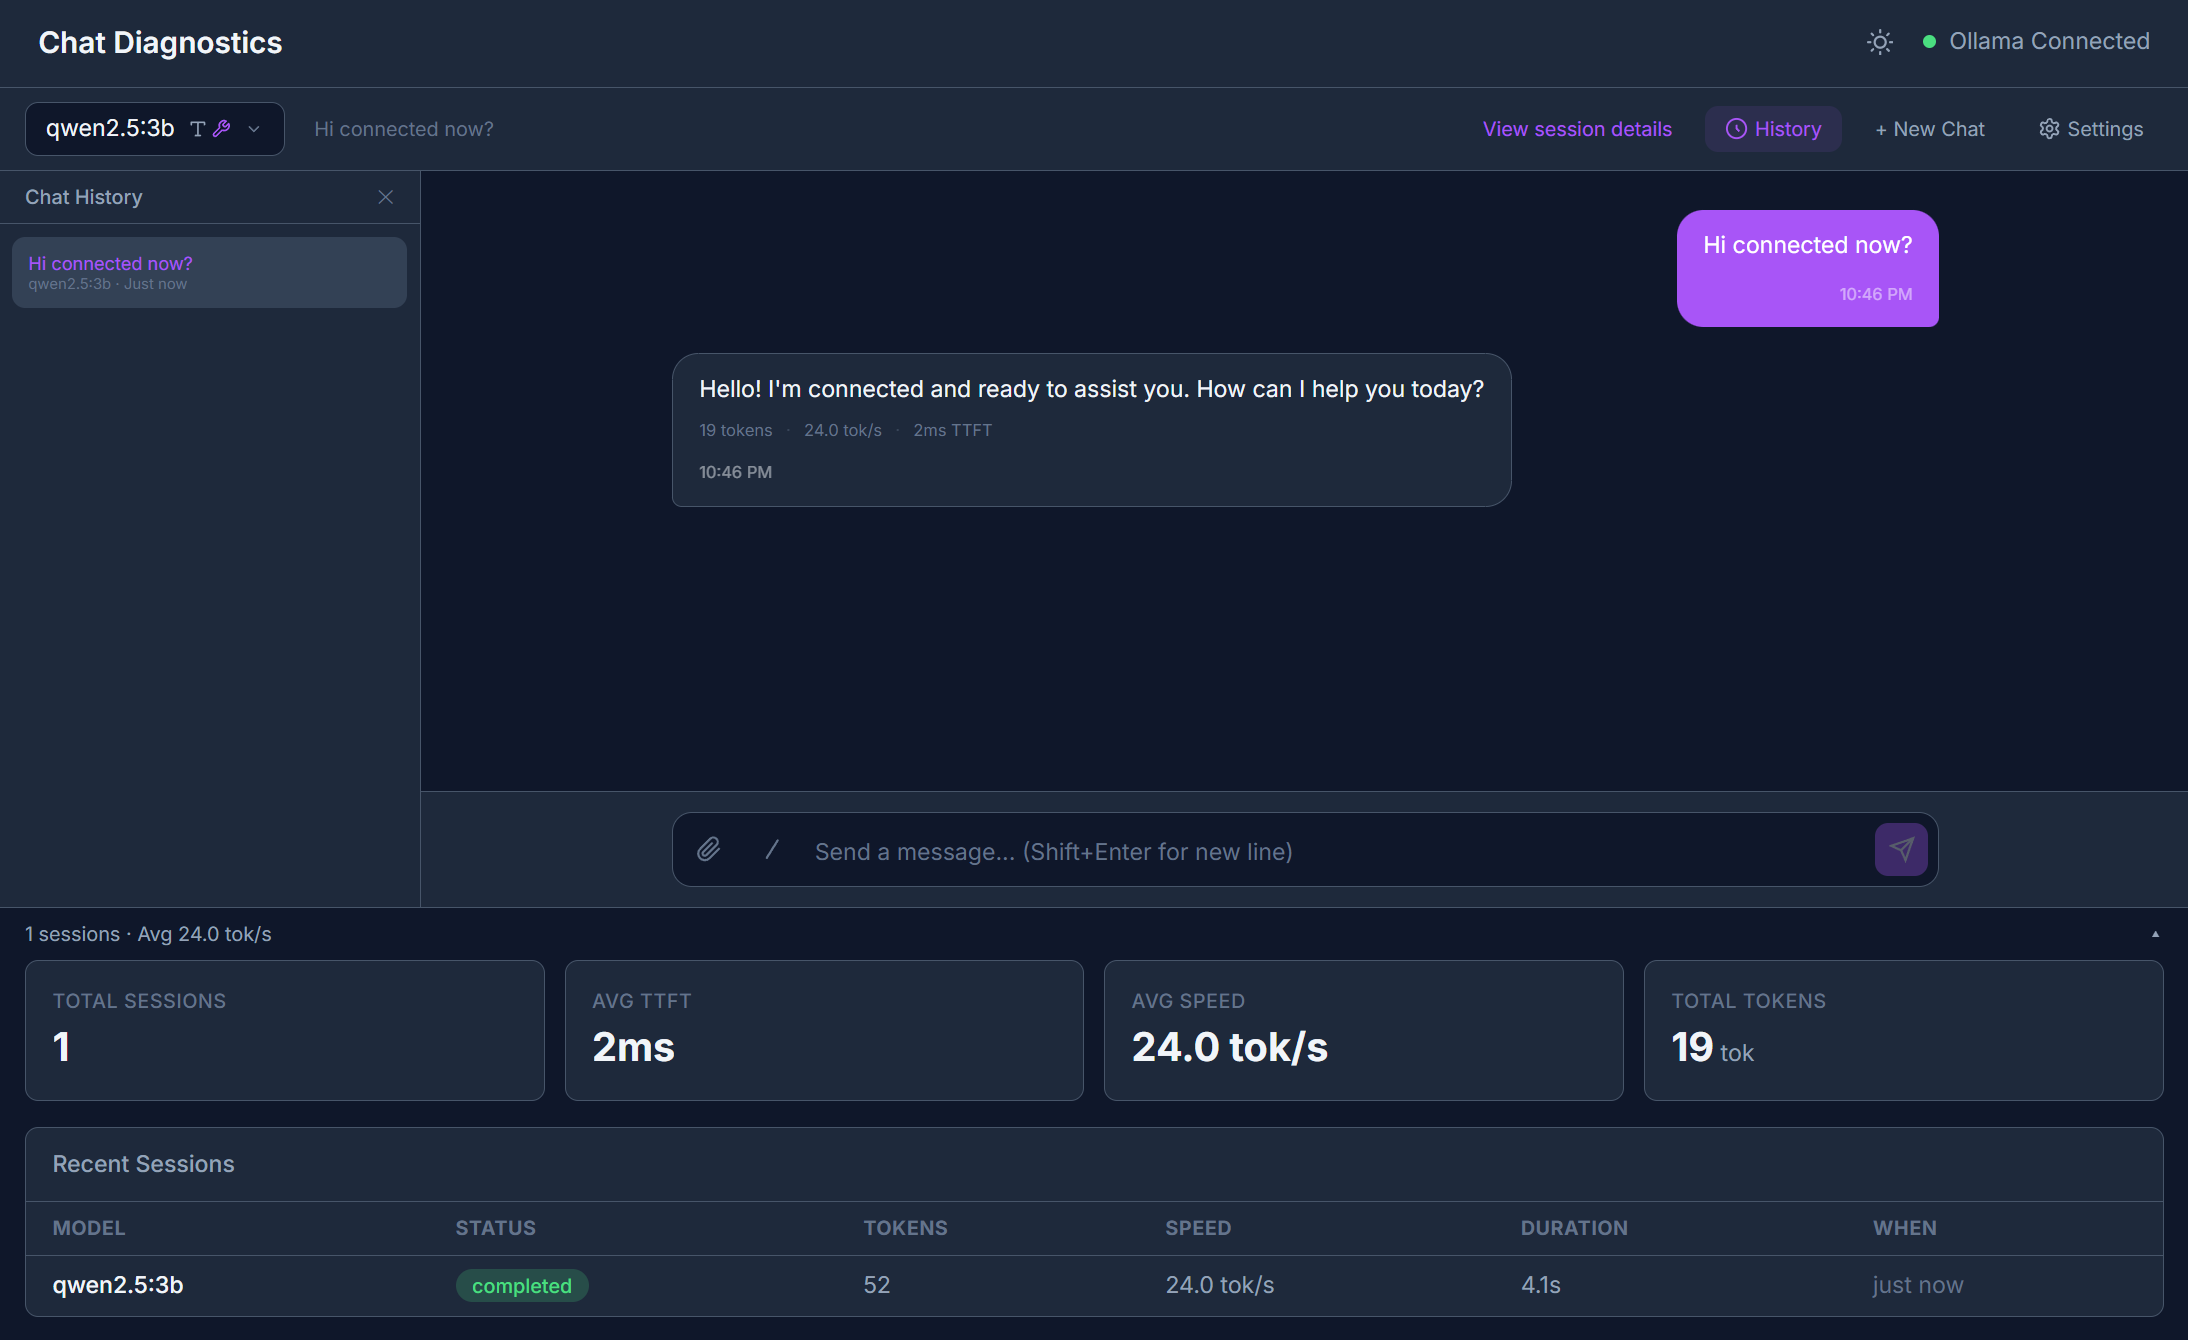
|
|
3
|
-
</p>
|
|
4
|
-
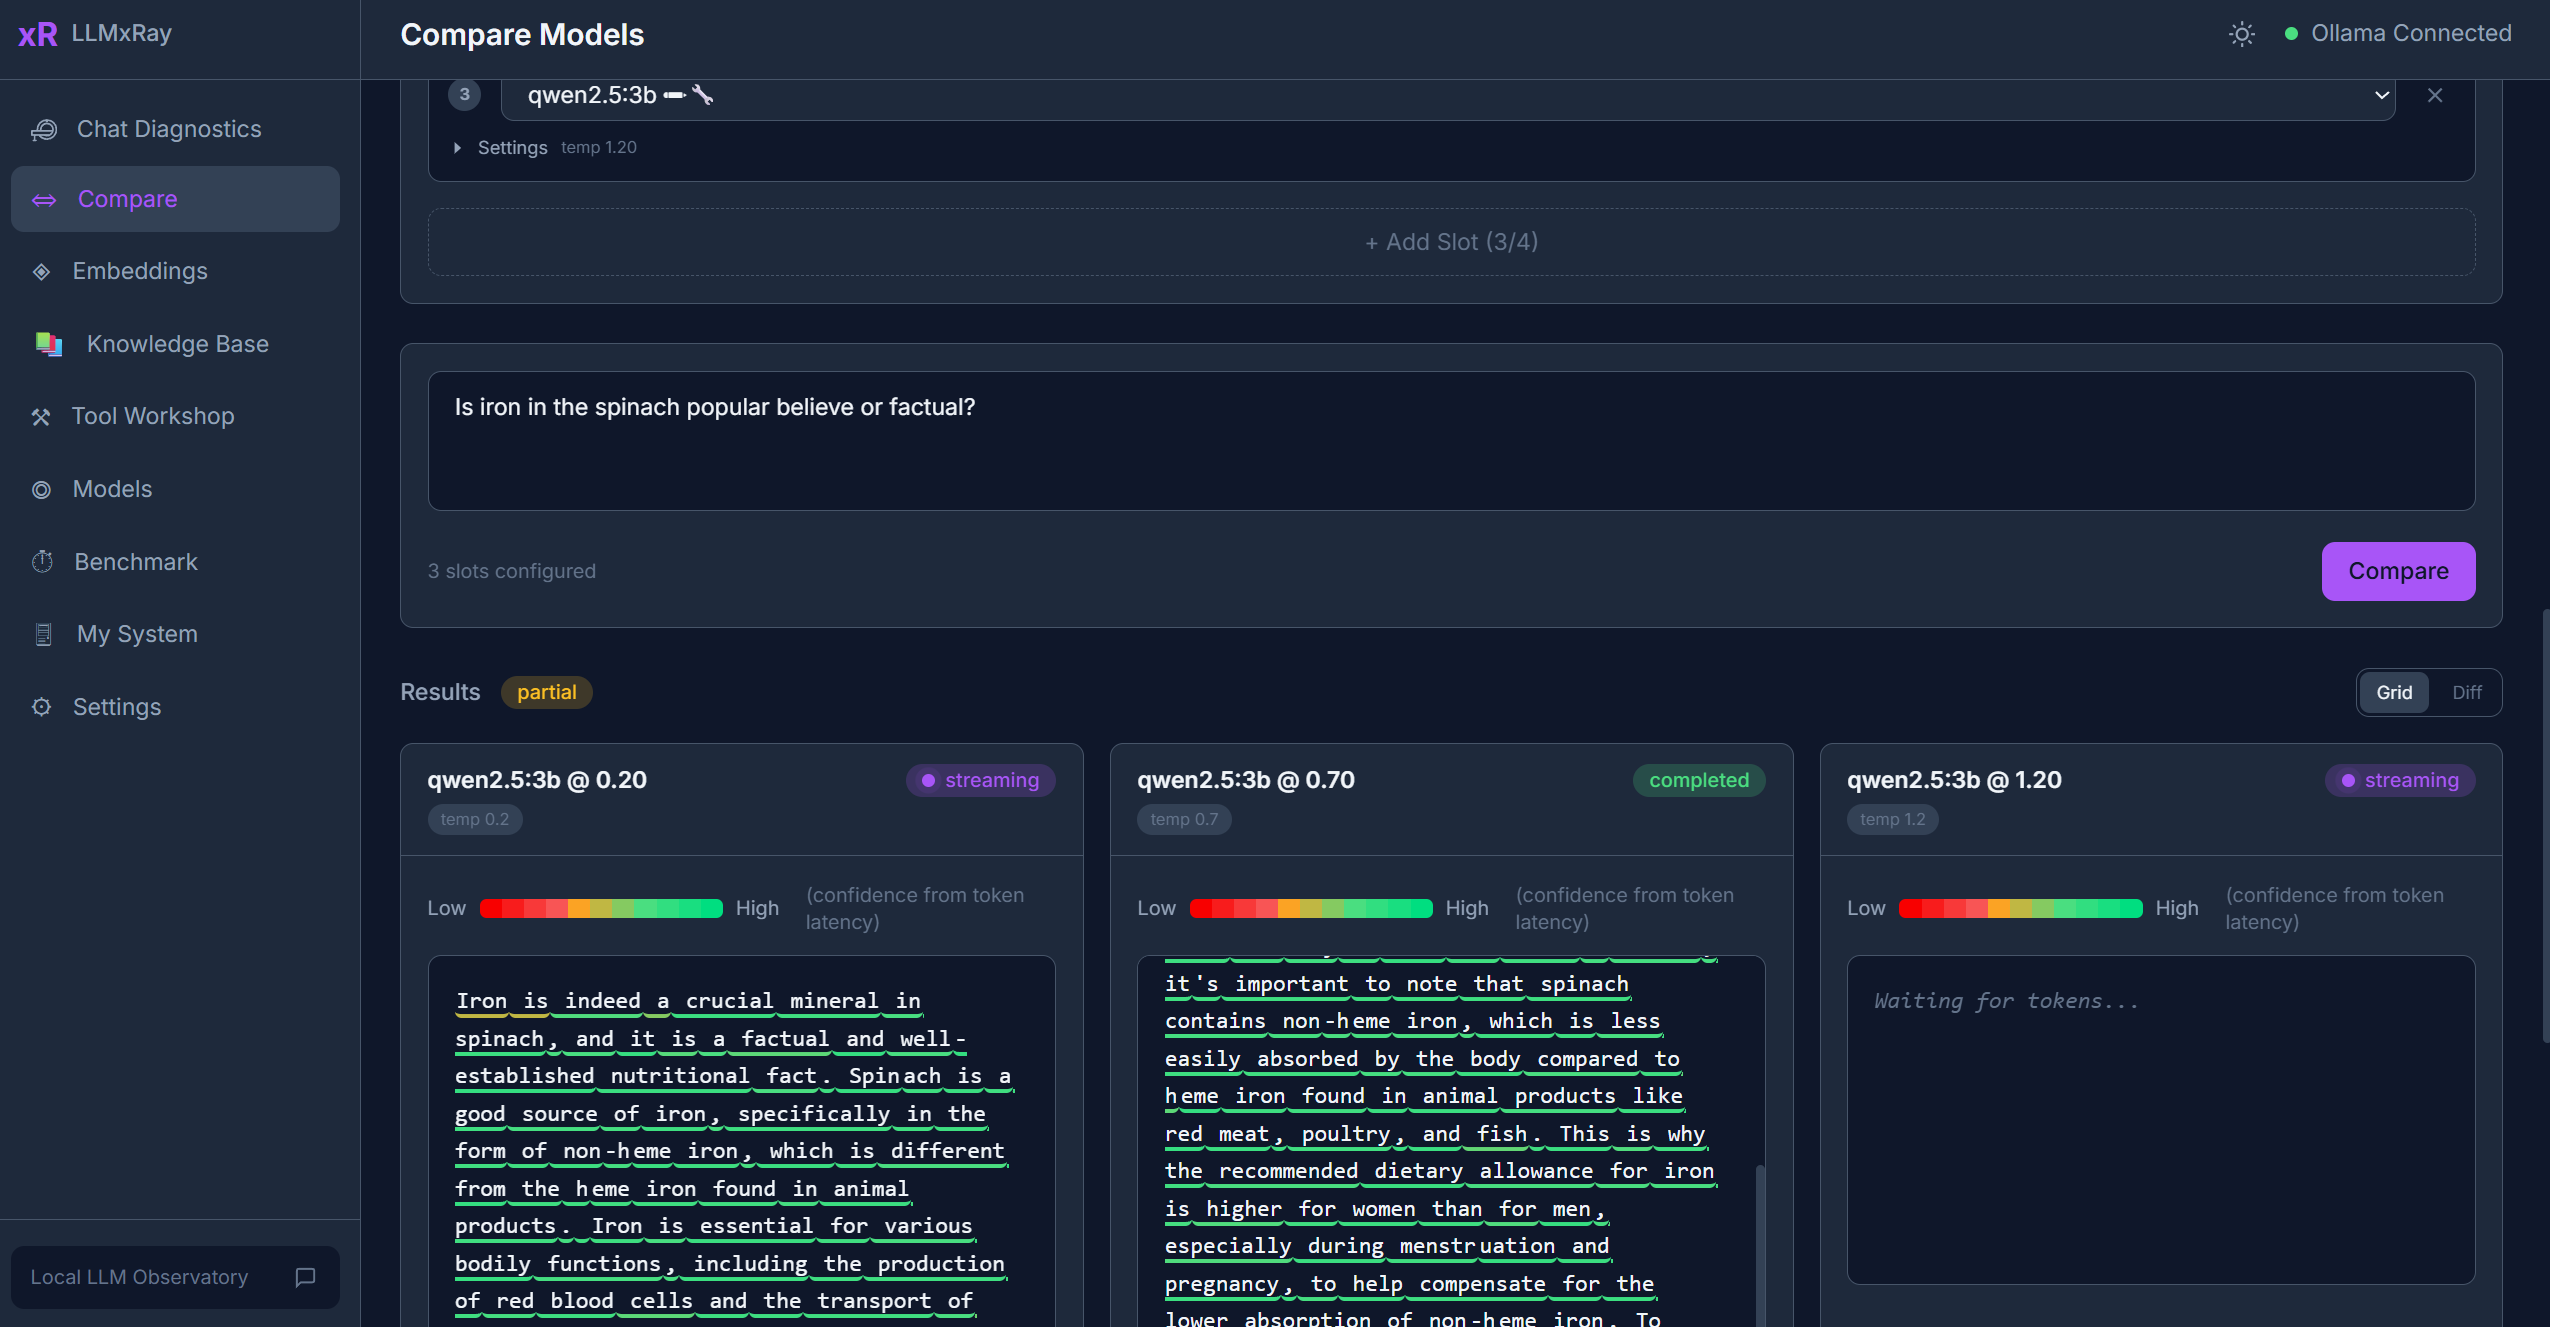
|
|
5
|
-
<h1 align="center">LLMxRay</h1>
|
|
6
|
-
<p align="center"><strong>See what your AI is actually doing.</strong></p>
|
|
7
|
-
<p align="center">
|
|
8
|
-
Real-time token streaming, quality analysis, performance profiling, and cost tracking<br/>
|
|
9
|
-
for local LLMs. No cloud. No API keys. No cost.
|
|
10
|
-
</p>
|
|
11
|
-
|
|
12
|
-
<p align="center">
|
|
13
|
-
<a href="https://www.npmjs.com/package/llmxray"><img src="https://img.shields.io/npm/v/llmxray?color=cb3837&logo=npm&logoColor=white" alt="npm" /></a>
|
|
14
|
-
<a href="https://hub.docker.com/r/djovaneli/llmxray"><img src="https://img.shields.io/docker/pulls/djovaneli/llmxray?color=2496ED&logo=docker&logoColor=white" alt="Docker" /></a>
|
|
15
|
-
<img src="https://img.shields.io/badge/license-Apache%202.0-blue" alt="License" />
|
|
16
|
-
<img src="https://img.shields.io/badge/ollama-local-000?logo=ollama&logoColor=white" alt="Ollama" />
|
|
17
|
-
</p>
|
|
18
|
-
|
|
19
|
-
<p align="center">
|
|
20
|
-
🌐 <strong>English</strong> •
|
|
21
|
-
<a href="README.fr.md">Français</a> •
|
|
22
|
-
<a href="README.zh-CN.md">中文</a> •
|
|
23
|
-
<a href="README.ar.md">العربية</a> •
|
|
24
|
-
<a href="README.sr.md">Srpski</a>
|
|
25
|
-
</p>
|
|
26
|
-
|
|
27
|
-
<p align="center">
|
|
28
|
-
<a href="#quick-start">Quick Start</a> •
|
|
29
|
-
<a href="#features">Features</a> •
|
|
30
|
-
<a href="#screenshots">Screenshots</a> •
|
|
31
|
-
<a href="#who-is-this-for">Who Is This For</a> •
|
|
32
|
-
<a href="CHANGELOG.md">Changelog</a>
|
|
33
|
-
</p>
|
|
34
|
-
|
|
35
|
-
<p align="center">
|
|
36
|
-
<img src="docs/public/screenshots/demo.gif" alt="LLMxRay demo — real-time token streaming with confidence coloring" width="800" />
|
|
37
|
-
</p>
|
|
38
|
-
|
|
39
|
-
---
|
|
40
|
-
|
|
41
|
-
## Quick Start
|
|
42
|
-
|
|
43
|
-
**One command. 30 seconds.**
|
|
44
|
-
|
|
45
|
-
```bash
|
|
46
|
-
npx llmxray
|
|
47
|
-
```
|
|
48
|
-
|
|
49
|
-
Or with Docker:
|
|
50
|
-
|
|
51
|
-
```bash
|
|
52
|
-
docker run -p 5174:5174 djovaneli/llmxray
|
|
53
|
-
```
|
|
54
|
-
|
|
55
|
-
Open **http://localhost:5174** and start chatting. That's it.
|
|
56
|
-
|
|
57
|
-
> **Prerequisite:** [Ollama](https://ollama.com/download) running locally with at least one model pulled (`ollama pull llama3.2`).
|
|
58
|
-
|
|
59
|
-
---
|
|
60
|
-
|
|
61
|
-
## Why LLMxRay?
|
|
62
|
-
|
|
63
|
-
You run a local LLM. You chat with it. But what actually happened?
|
|
64
|
-
|
|
65
|
-
- How fast was each token? Which ones was the model confident about?
|
|
66
|
-
- Is the response quality degrading over long conversations?
|
|
67
|
-
- What would this have cost if you ran it in the cloud?
|
|
68
|
-
- Is the model repeating itself? Refusing? Generating gibberish?
|
|
69
|
-
- How does temperature 0.3 compare to 0.9 on the *same* prompt?
|
|
70
|
-
|
|
71
|
-
**LLMxRay answers all of these, visually, in real time, for free.**
|
|
72
|
-
|
|
73
|
-
---
|
|
74
|
-
|
|
75
|
-
## Features
|
|
76
|
-
|
|
77
|
-
### Real-Time Chat with Token Intelligence
|
|
78
|
-
Chat with any Ollama model and watch tokens arrive with **confidence coloring** — each token is tinted based on generation speed. Supports markdown, multi-turn conversations, file attachments, vision models, and slash commands. For reasoning models, set the thinking budget per conversation — off, model's choice, or an explicit low / medium / high / max effort.
|
|
79
|
-
|
|
80
|
-
### Response Quality Gates
|
|
81
|
-
Every response is automatically analyzed. Colored badges appear only when something is wrong:
|
|
82
|
-
- **Repetition** — excessive repeated phrases (4-gram analysis)
|
|
83
|
-
- **Refusal** — "as an AI language model" and 7 other patterns
|
|
84
|
-
- **Gibberish** — high non-ASCII ratio
|
|
85
|
-
- **Empty** — fewer than 10 words
|
|
86
|
-
- **Truncation** — hit the token limit without finishing
|
|
87
|
-
|
|
88
|
-
### Model Comparison Workbench
|
|
89
|
-
Up to **4 slots** with independent model, temperature, and system prompt. Features include side-by-side streaming, word-level diff highlighting, metrics comparison, and one-click presets (Temperature Sweep, Deterministic Pair, Language Compare with Token Tax visualization).
|
|
90
|
-
|
|
91
|
-
### Performance Analytics
|
|
92
|
-
- **Latency percentiles** (P50/P95/P99) for duration and TTFT
|
|
93
|
-
- **Error intelligence** — 7-category classifier with timeline
|
|
94
|
-
- **Usage heatmap** — 7x24 grid of your active hours
|
|
95
|
-
- **Settings impact** — temperature vs tokens/sec scatter plots
|
|
96
|
-
- **Cold vs warm start** tracking with model load history
|
|
97
|
-
|
|
98
|
-
### Cost Dashboard
|
|
99
|
-
Token usage per model/day with estimated cloud-equivalent pricing. See what you're *saving* by running locally.
|
|
100
|
-
|
|
101
|
-
### Surgical Benchmark
|
|
102
|
-
Test model knowledge with multi-choice question suites. Uses real logprobs via OpenAI-compatible endpoint for accurate confidence measurement. Build custom suites visually or let AI generate them from a topic.
|
|
103
|
-
|
|
104
|
-
### Embeddings Lab & RAG Pipeline
|
|
105
|
-
Embed text, visualize vectors, measure cosine similarity. Request a narrower output vector to see what Matryoshka truncation costs in similarity. Build a local knowledge base from PDFs, DOCX, and CSV — chunked, embedded, and searchable. All stored in IndexedDB. Zero cost.
|
|
106
|
-
|
|
107
|
-
### Tool Workshop (Visual Canvas)
|
|
108
|
-
Drag-and-drop node canvas for building tool definitions. Bidirectional code sync (edit nodes or TypeScript — both update). Probe APIs, auto-generate schemas, test with live execution.
|
|
109
|
-
|
|
110
|
-
### Fill-in-the-Middle Playground *(new in v0.4.7)*
|
|
111
|
-
Code completion for Qwen-Coder, CodeLlama, Codestral, DeepSeek-Coder, and StarCoder. Two textareas (prefix / suffix), the model fills the gap. Uses Ollama's `suffix` field on `/api/generate`. Stitched preview shows the result as it would appear in your editor.
|
|
112
|
-
|
|
113
|
-
###
|
|
114
|
-
|
|
115
|
-
|
|
116
|
-
###
|
|
117
|
-
|
|
118
|
-
|
|
119
|
-
###
|
|
120
|
-
|
|
121
|
-
|
|
122
|
-
###
|
|
123
|
-
|
|
124
|
-
|
|
125
|
-
|
|
126
|
-
|
|
127
|
-
|
|
128
|
-
|
|
129
|
-
|
|
130
|
-
|
|
131
|
-
|
|
132
|
-
|
|
133
|
-
|
|
134
|
-
|
|
|
135
|
-
|
|
136
|
-
| `/api/
|
|
137
|
-
| `/api/
|
|
138
|
-
| `/api/
|
|
139
|
-
| `/
|
|
140
|
-
| `/
|
|
141
|
-
|
|
142
|
-
|
|
143
|
-
|
|
144
|
-
|
|
145
|
-
|
|
146
|
-
|
|
147
|
-
|
|
148
|
-
|
|
149
|
-
|
|
150
|
-
|
|
151
|
-
|
|
152
|
-
|
|
153
|
-
|
|
154
|
-
|
|
155
|
-
|
|
156
|
-
|
|
157
|
-
|
|
158
|
-
|
|
159
|
-
|
|
160
|
-
|
|
161
|
-
|
|
162
|
-
|
|
163
|
-
|
|
164
|
-
|
|
165
|
-
|
|
166
|
-
|
|
167
|
-
|
|
168
|
-
|
|
169
|
-
|
|
170
|
-
|
|
171
|
-
|
|
172
|
-
|
|
173
|
-
|
|
174
|
-
|
|
175
|
-
|
|
176
|
-
|
|
177
|
-
|
|
178
|
-
|
|
179
|
-
|
|
180
|
-
|
|
181
|
-
|
|
182
|
-
|
|
183
|
-
|
|
184
|
-
|
|
185
|
-
|
|
186
|
-
|
|
187
|
-
|
|
188
|
-
|
|
189
|
-
|
|
190
|
-
|
|
191
|
-
|
|
192
|
-
|
|
193
|
-
|
|
194
|
-
|
|
195
|
-
|
|
196
|
-
|
|
197
|
-
|
|
198
|
-
|
|
199
|
-
|
|
200
|
-
|
|
|
201
|
-
|
|
202
|
-
| **
|
|
203
|
-
|
|
204
|
-
|
|
205
|
-
|
|
206
|
-
|
|
207
|
-
|
|
208
|
-
|
|
209
|
-
|
|
210
|
-
|
|
211
|
-
npx
|
|
212
|
-
|
|
213
|
-
|
|
214
|
-
|
|
215
|
-
|
|
216
|
-
```
|
|
217
|
-
|
|
218
|
-
|
|
219
|
-
```
|
|
220
|
-
|
|
221
|
-
|
|
222
|
-
```
|
|
223
|
-
|
|
224
|
-
|
|
225
|
-
|
|
226
|
-
|
|
227
|
-
|
|
228
|
-
|
|
229
|
-
|
|
230
|
-
|
|
231
|
-
|
|
232
|
-
|
|
233
|
-
|
|
234
|
-
|
|
235
|
-
|
|
236
|
-
|
|
|
237
|
-
|
|
238
|
-
|
|
|
239
|
-
|
|
|
240
|
-
|
|
|
241
|
-
|
|
|
242
|
-
|
|
|
243
|
-
|
|
|
244
|
-
|
|
|
245
|
-
|
|
246
|
-
|
|
247
|
-
|
|
248
|
-
|
|
249
|
-
|
|
250
|
-
|
|
251
|
-
|
|
252
|
-
|
|
253
|
-
|
|
254
|
-
|
|
255
|
-
|
|
256
|
-
|
|
257
|
-
|
|
258
|
-
|
|
259
|
-
|
|
260
|
-
|
|
261
|
-
|
|
262
|
-
|
|
263
|
-
|
|
264
|
-
|
|
265
|
-
|
|
|
266
|
-
|
|
267
|
-
| `npm run
|
|
268
|
-
|
|
269
|
-
|
|
270
|
-
|
|
271
|
-
|
|
272
|
-
|
|
273
|
-
|
|
274
|
-
|
|
275
|
-
|
|
276
|
-
|
|
277
|
-
|
|
278
|
-
|
|
279
|
-
|
|
280
|
-
|
|
281
|
-
|
|
282
|
-
|
|
283
|
-
|
|
284
|
-
|
|
285
|
-
|
|
286
|
-
|
|
287
|
-
|
|
288
|
-
|
|
289
|
-
|
|
290
|
-
|
|
291
|
-
|
|
292
|
-
|
|
293
|
-
|
|
294
|
-
|
|
295
|
-
|
|
296
|
-
|
|
297
|
-
|
|
298
|
-
|
|
1
|
+
<p align="center">
|
|
2
|
+
<img src="https://raw.githubusercontent.com/LogneBudo/llmxray/master/public/favicon.svg" alt="LLMxRay" width="80" />
|
|
3
|
+
</p>
|
|
4
|
+
|
|
5
|
+
<h1 align="center">LLMxRay</h1>
|
|
6
|
+
<p align="center"><strong>See what your AI is actually doing.</strong></p>
|
|
7
|
+
<p align="center">
|
|
8
|
+
Real-time token streaming, quality analysis, performance profiling, and cost tracking<br/>
|
|
9
|
+
for local LLMs. No cloud. No API keys. No cost.
|
|
10
|
+
</p>
|
|
11
|
+
|
|
12
|
+
<p align="center">
|
|
13
|
+
<a href="https://www.npmjs.com/package/llmxray"><img src="https://img.shields.io/npm/v/llmxray?color=cb3837&logo=npm&logoColor=white" alt="npm" /></a>
|
|
14
|
+
<a href="https://hub.docker.com/r/djovaneli/llmxray"><img src="https://img.shields.io/docker/pulls/djovaneli/llmxray?color=2496ED&logo=docker&logoColor=white" alt="Docker" /></a>
|
|
15
|
+
<img src="https://img.shields.io/badge/license-Apache%202.0-blue" alt="License" />
|
|
16
|
+
<img src="https://img.shields.io/badge/ollama-local-000?logo=ollama&logoColor=white" alt="Ollama" />
|
|
17
|
+
</p>
|
|
18
|
+
|
|
19
|
+
<p align="center">
|
|
20
|
+
🌐 <strong>English</strong> •
|
|
21
|
+
<a href="README.fr.md">Français</a> •
|
|
22
|
+
<a href="README.zh-CN.md">中文</a> •
|
|
23
|
+
<a href="README.ar.md">العربية</a> •
|
|
24
|
+
<a href="README.sr.md">Srpski</a>
|
|
25
|
+
</p>
|
|
26
|
+
|
|
27
|
+
<p align="center">
|
|
28
|
+
<a href="#quick-start">Quick Start</a> •
|
|
29
|
+
<a href="#features">Features</a> •
|
|
30
|
+
<a href="#screenshots">Screenshots</a> •
|
|
31
|
+
<a href="#who-is-this-for">Who Is This For</a> •
|
|
32
|
+
<a href="CHANGELOG.md">Changelog</a>
|
|
33
|
+
</p>
|
|
34
|
+
|
|
35
|
+
<p align="center">
|
|
36
|
+
<img src="https://raw.githubusercontent.com/LogneBudo/llmxray/master/docs/public/screenshots/demo.gif" alt="LLMxRay demo — real-time token streaming with confidence coloring" width="800" />
|
|
37
|
+
</p>
|
|
38
|
+
|
|
39
|
+
---
|
|
40
|
+
|
|
41
|
+
## Quick Start
|
|
42
|
+
|
|
43
|
+
**One command. 30 seconds.**
|
|
44
|
+
|
|
45
|
+
```bash
|
|
46
|
+
npx llmxray
|
|
47
|
+
```
|
|
48
|
+
|
|
49
|
+
Or with Docker:
|
|
50
|
+
|
|
51
|
+
```bash
|
|
52
|
+
docker run -p 5174:5174 djovaneli/llmxray
|
|
53
|
+
```
|
|
54
|
+
|
|
55
|
+
Open **http://localhost:5174** and start chatting. That's it.
|
|
56
|
+
|
|
57
|
+
> **Prerequisite:** [Ollama](https://ollama.com/download) running locally with at least one model pulled (`ollama pull llama3.2`).
|
|
58
|
+
|
|
59
|
+
---
|
|
60
|
+
|
|
61
|
+
## Why LLMxRay?
|
|
62
|
+
|
|
63
|
+
You run a local LLM. You chat with it. But what actually happened?
|
|
64
|
+
|
|
65
|
+
- How fast was each token? Which ones was the model confident about?
|
|
66
|
+
- Is the response quality degrading over long conversations?
|
|
67
|
+
- What would this have cost if you ran it in the cloud?
|
|
68
|
+
- Is the model repeating itself? Refusing? Generating gibberish?
|
|
69
|
+
- How does temperature 0.3 compare to 0.9 on the *same* prompt?
|
|
70
|
+
|
|
71
|
+
**LLMxRay answers all of these, visually, in real time, for free.**
|
|
72
|
+
|
|
73
|
+
---
|
|
74
|
+
|
|
75
|
+
## Features
|
|
76
|
+
|
|
77
|
+
### Real-Time Chat with Token Intelligence
|
|
78
|
+
Chat with any Ollama model and watch tokens arrive with **confidence coloring** — each token is tinted based on generation speed. Supports markdown, multi-turn conversations, file attachments, vision models, and slash commands. For reasoning models, set the thinking budget per conversation — off, model's choice, or an explicit low / medium / high / max effort.
|
|
79
|
+
|
|
80
|
+
### Response Quality Gates
|
|
81
|
+
Every response is automatically analyzed. Colored badges appear only when something is wrong:
|
|
82
|
+
- **Repetition** — excessive repeated phrases (4-gram analysis)
|
|
83
|
+
- **Refusal** — "as an AI language model" and 7 other patterns
|
|
84
|
+
- **Gibberish** — high non-ASCII ratio
|
|
85
|
+
- **Empty** — fewer than 10 words
|
|
86
|
+
- **Truncation** — hit the token limit without finishing
|
|
87
|
+
|
|
88
|
+
### Model Comparison Workbench
|
|
89
|
+
Up to **4 slots** with independent model, temperature, and system prompt. Features include side-by-side streaming, word-level diff highlighting, metrics comparison, and one-click presets (Temperature Sweep, Deterministic Pair, Language Compare with Token Tax visualization).
|
|
90
|
+
|
|
91
|
+
### Performance Analytics
|
|
92
|
+
- **Latency percentiles** (P50/P95/P99) for duration and TTFT
|
|
93
|
+
- **Error intelligence** — 7-category classifier with timeline
|
|
94
|
+
- **Usage heatmap** — 7x24 grid of your active hours
|
|
95
|
+
- **Settings impact** — temperature vs tokens/sec scatter plots
|
|
96
|
+
- **Cold vs warm start** tracking with model load history
|
|
97
|
+
|
|
98
|
+
### Cost Dashboard
|
|
99
|
+
Token usage per model/day with estimated cloud-equivalent pricing. See what you're *saving* by running locally.
|
|
100
|
+
|
|
101
|
+
### Surgical Benchmark
|
|
102
|
+
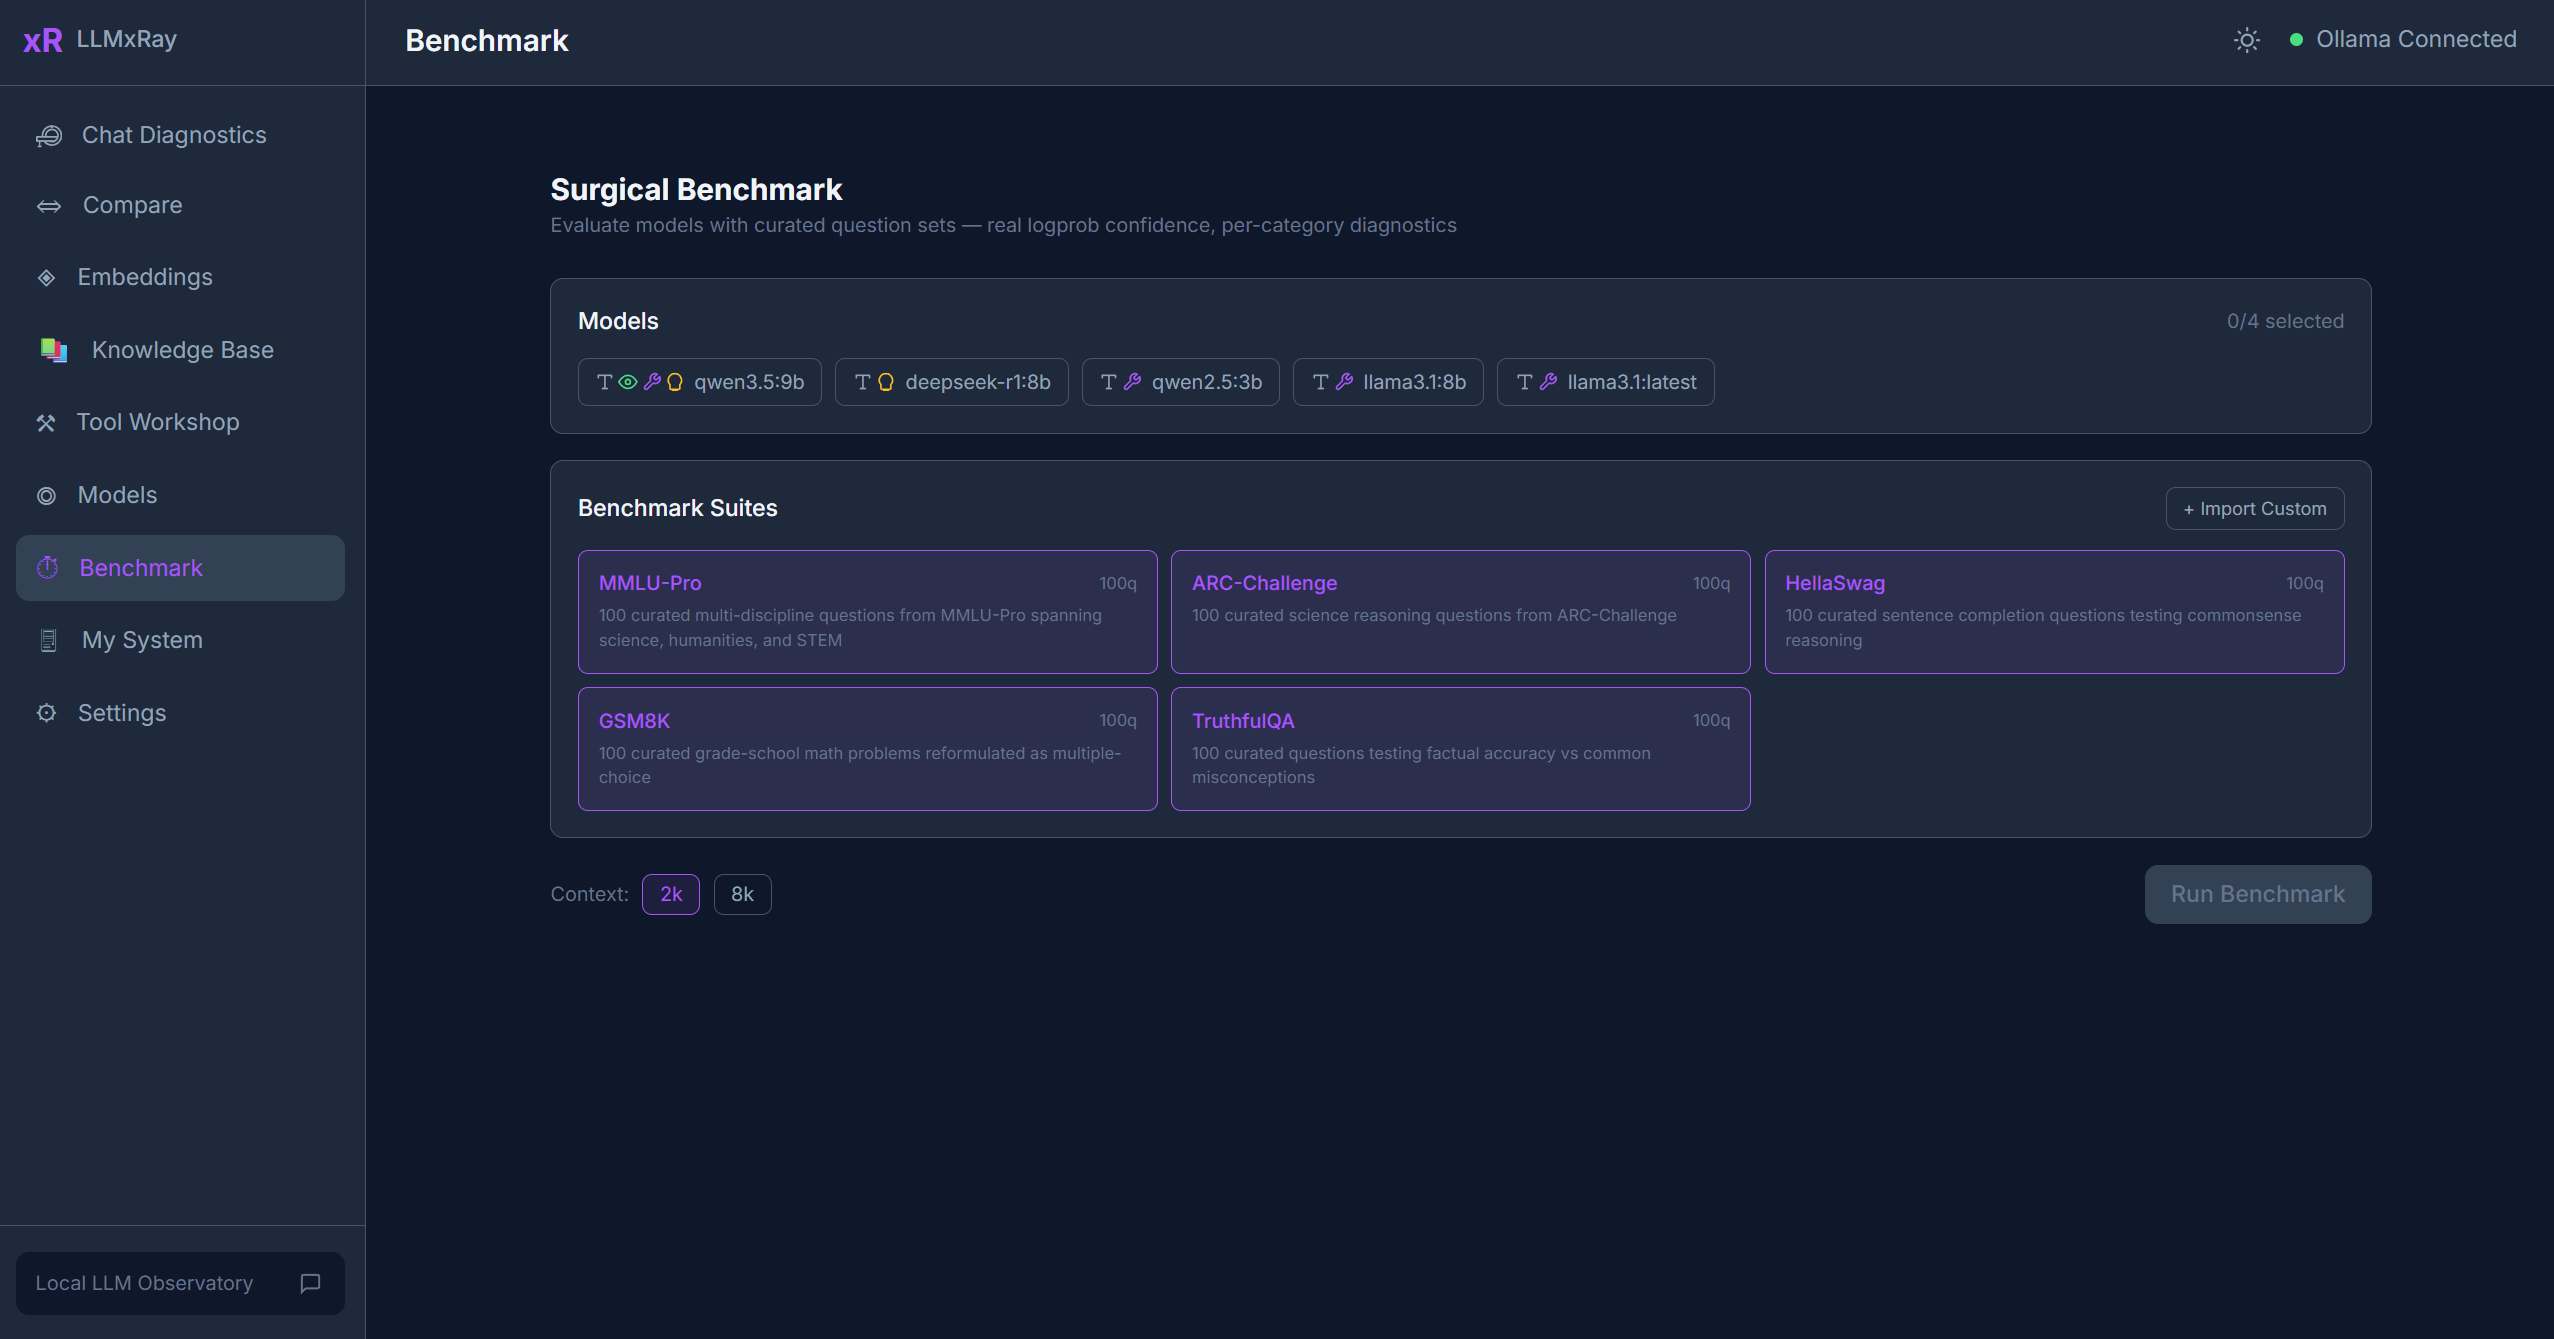
Test model knowledge with multi-choice question suites. Uses real logprobs via OpenAI-compatible endpoint for accurate confidence measurement. Build custom suites visually or let AI generate them from a topic.
|
|
103
|
+
|
|
104
|
+
### Embeddings Lab & RAG Pipeline
|
|
105
|
+
Embed text, visualize vectors, measure cosine similarity. Request a narrower output vector to see what Matryoshka truncation costs in similarity. Build a local knowledge base from PDFs, DOCX, and CSV — chunked, embedded, and searchable. All stored in IndexedDB. Zero cost.
|
|
106
|
+
|
|
107
|
+
### Tool Workshop (Visual Canvas)
|
|
108
|
+
Drag-and-drop node canvas for building tool definitions. Bidirectional code sync (edit nodes or TypeScript — both update). Probe APIs, auto-generate schemas, test with live execution.
|
|
109
|
+
|
|
110
|
+
### Fill-in-the-Middle Playground *(new in v0.4.7)*
|
|
111
|
+
Code completion for Qwen-Coder, CodeLlama, Codestral, DeepSeek-Coder, and StarCoder. Two textareas (prefix / suffix), the model fills the gap. Uses Ollama's `suffix` field on `/api/generate`. Stitched preview shows the result as it would appear in your editor.
|
|
112
|
+
|
|
113
|
+
### Cache Lab *(new in v0.6.0)*
|
|
114
|
+
Find out why your prompt misses the model’s KV cache, and measure what it costs every turn. A local model reuses its cache only while the prompt still matches from the very first token, so a single timestamp near the top forfeits everything below it. The lab finds the values that change between turns, shows the exact point where reuse dies, and then **measures** — sending each layout twice with a changed value, against your own daemon — what moving them to the end actually saves. Measured on a real 324-token prompt: **4 tokens reused and 64.6 ms of prefill with the timestamp at the front, 290 reused and 18.6 ms with it at the back. 3.5x faster, same words.** Requires Ollama 0.33.3+.
|
|
115
|
+
|
|
116
|
+
### Protocol Observatory *(new in v0.4.7)*
|
|
117
|
+
Fire the same prompt through Ollama's three serving protocols — **native** `/api/chat`, **OpenAI-compat** `/v1/chat/completions`, and **Anthropic-compat** `/v1/messages` — in parallel against your local model. Side-by-side streaming, per-protocol metrics, and an envelope-diff tab that shows how each protocol frames finish reasons, token counts, and error envelopes. No cloud, no API keys — all three endpoints are local on `localhost:11434`.
|
|
118
|
+
|
|
119
|
+
### AI Training Pipeline
|
|
120
|
+
Curate training data from your conversations. Tag, review, and export as JSONL for fine-tuning.
|
|
121
|
+
|
|
122
|
+
### Local AI History Database
|
|
123
|
+
Every experiment (benchmarks, comparisons, chats, training pairs) is automatically archived in a queryable IndexedDB database with filters, trends, exports, and retention policies.
|
|
124
|
+
|
|
125
|
+
### Multilingual
|
|
126
|
+
Full translations in English, French, Serbian (Latin + Cyrillic), Chinese, and Arabic. RTL layout support. Community scaffolds for Hebrew and Japanese.
|
|
127
|
+
|
|
128
|
+
---
|
|
129
|
+
|
|
130
|
+
## Ollama Compatibility
|
|
131
|
+
|
|
132
|
+
Tested and verified against **Ollama 0.33.x** (verified on 0.33.3, September 2026). LLMxRay uses these Ollama endpoints:
|
|
133
|
+
|
|
134
|
+
| Endpoint | Used for |
|
|
135
|
+
|---|---|
|
|
136
|
+
| `/api/chat` | Streaming chat (NDJSON, with `tools`, `think` effort levels, `format` schema) |
|
|
137
|
+
| `/api/generate` | Generation + Fill-in-the-Middle via `suffix` |
|
|
138
|
+
| `/api/tags` | Model list + capabilities, context length, and embedding width |
|
|
139
|
+
| `/api/show` | Parameters, template, license, and architecture metadata |
|
|
140
|
+
| `/api/embed` | Vector embeddings for RAG, with optional `dimensions` truncation |
|
|
141
|
+
| `/api/pull`, `/api/delete`, `/api/ps`, `/api/version` | Model management + status |
|
|
142
|
+
| `/v1/chat/completions` | OpenAI-compat path used by Surgical Benchmark for real logprobs and usage totals |
|
|
143
|
+
| `/v1/messages` | Anthropic-compat path used by Protocol Observatory |
|
|
144
|
+
|
|
145
|
+
**Compatible with:** Ollama 0.20 and newer (older versions work for chat/generate but lack `think` and JSON-schema `format`). **Recommended:** Ollama 0.33.3+ — prompt-cache reuse is reported (`prompt_eval_cached_count`, and `usage.prompt_tokens_details.cached_tokens` on the OpenAI-compatible endpoint), so prefill throughput is measured over the tokens actually evaluated. From 0.32: capabilities and context length arrive with the model listing, `think` accepts graded effort levels, and embeddings accept a `dimensions` width.
|
|
146
|
+
|
|
147
|
+
---
|
|
148
|
+
|
|
149
|
+
## Screenshots
|
|
150
|
+
|
|
151
|
+
<table>
|
|
152
|
+
<tr>
|
|
153
|
+
<td width="50%">
|
|
154
|
+
|
|
155
|
+
**Chat with token streaming and confidence**
|
|
156
|
+
|
|
157
|
+
|
|
158
|
+
</td>
|
|
159
|
+
<td width="50%">
|
|
160
|
+
|
|
161
|
+
**Model comparison — side by side**
|
|
162
|
+
|
|
163
|
+
|
|
164
|
+
</td>
|
|
165
|
+
</tr>
|
|
166
|
+
<tr>
|
|
167
|
+
<td width="50%">
|
|
168
|
+
|
|
169
|
+
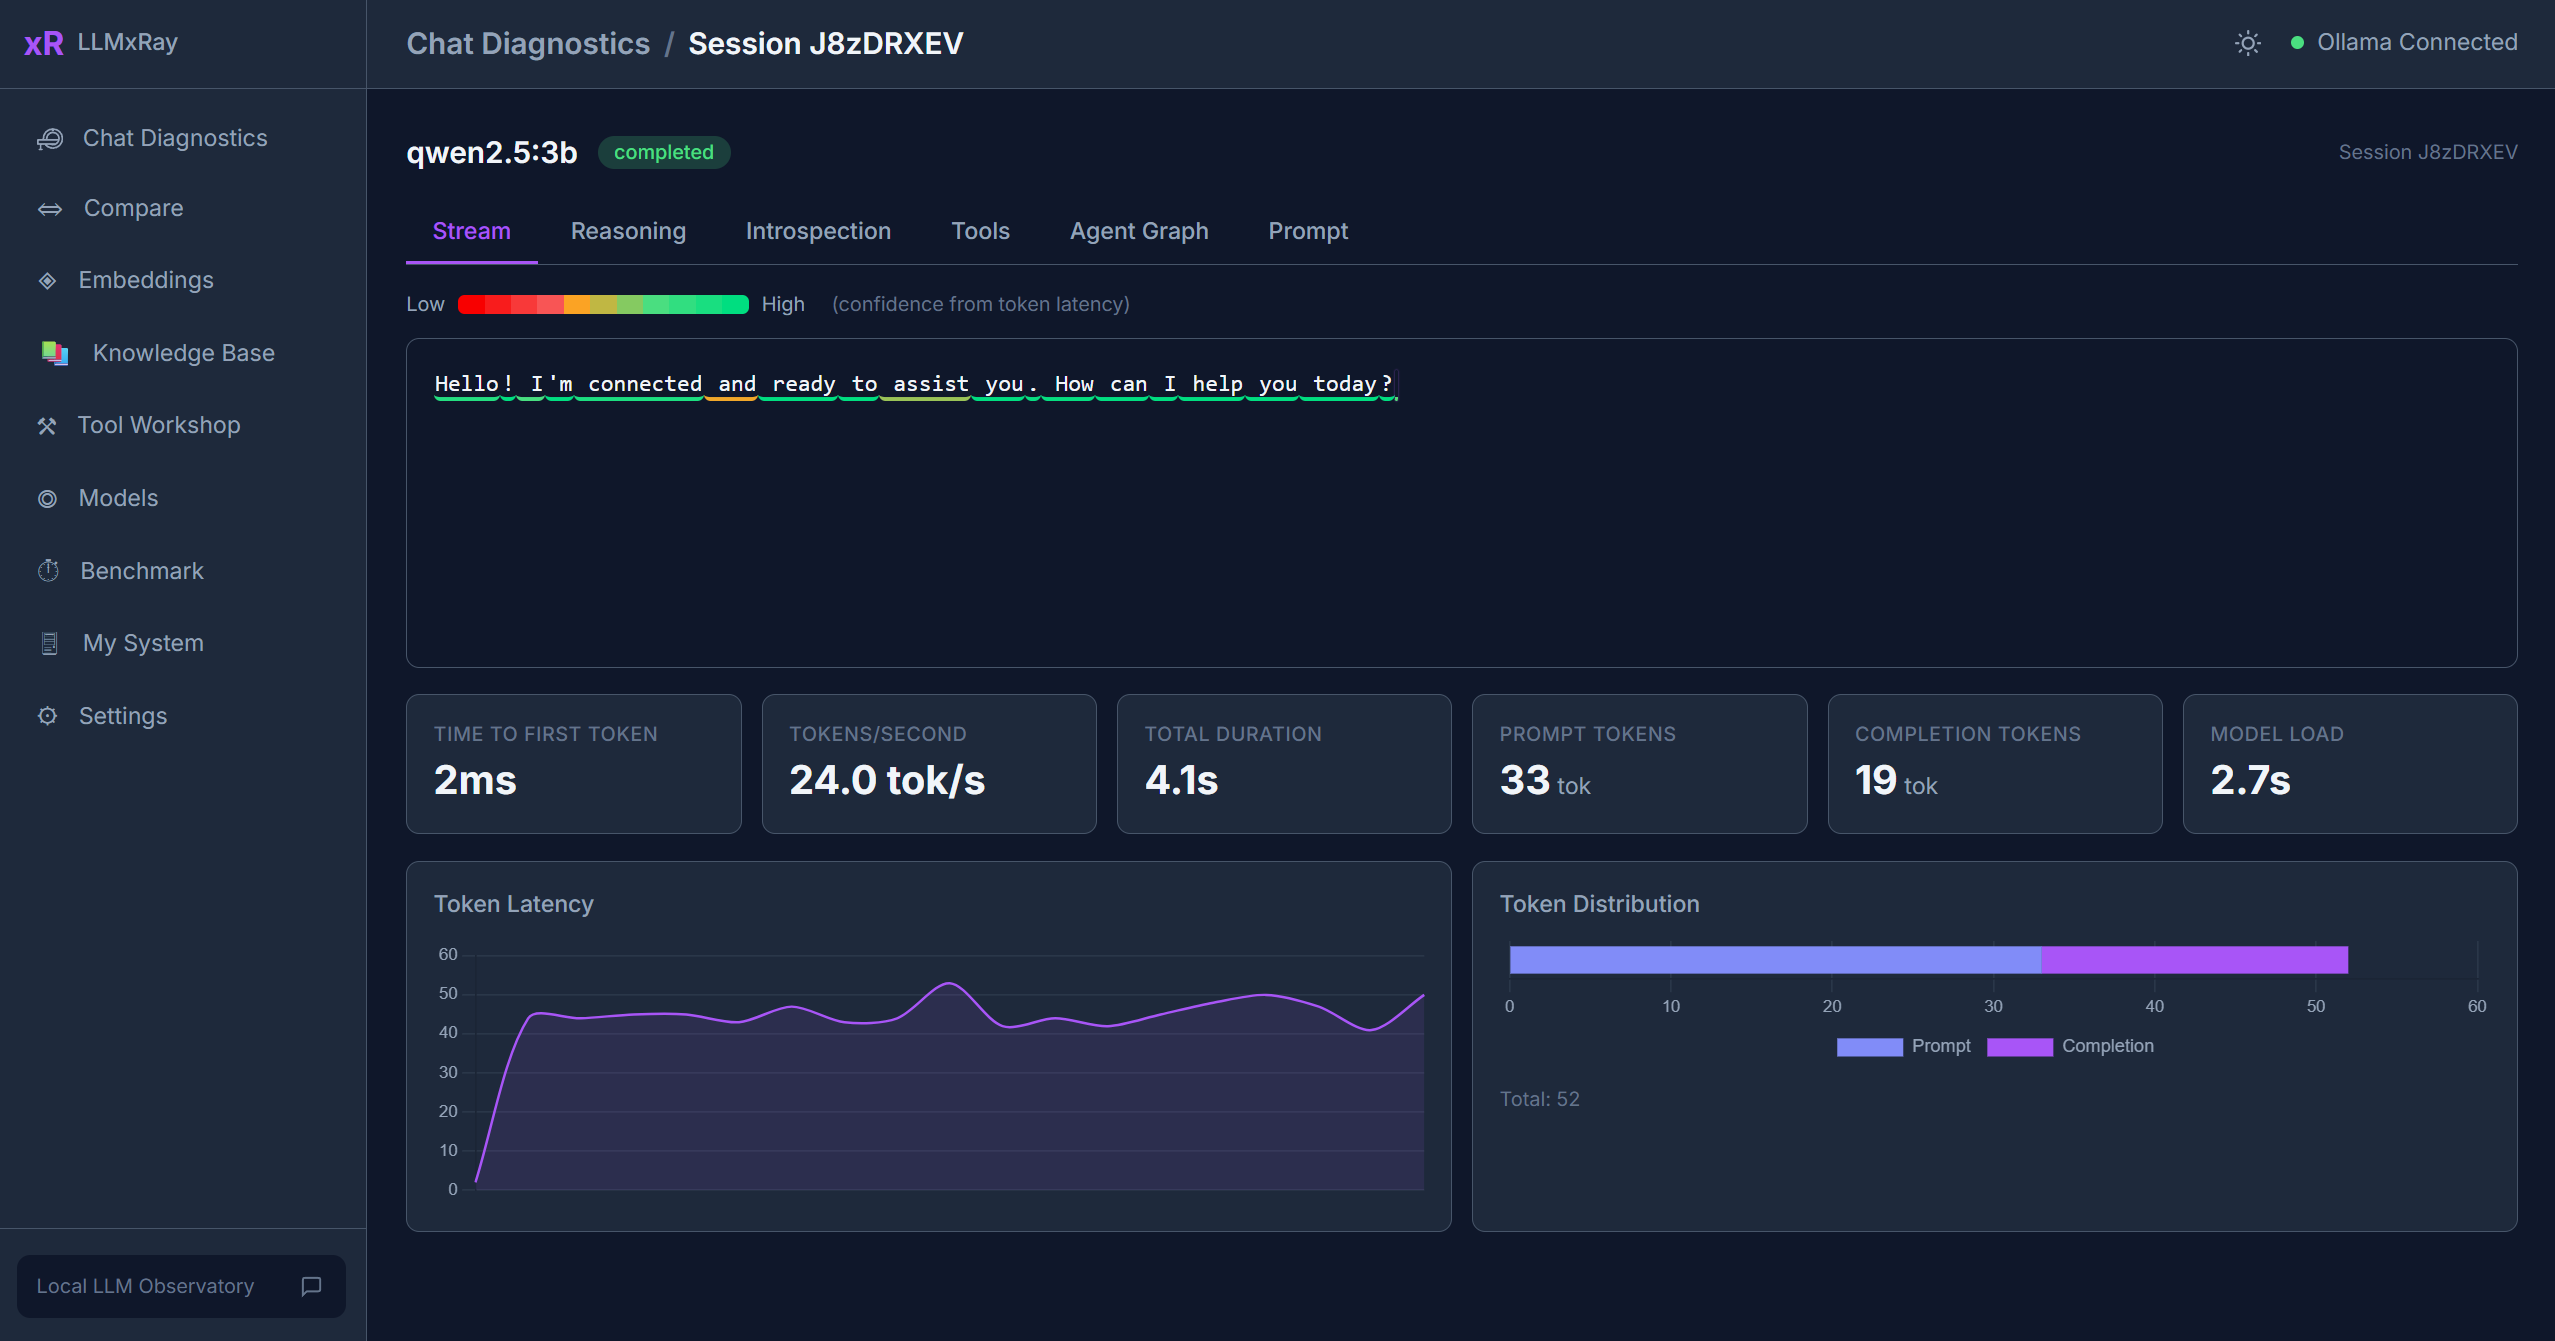
**Session deep dive — metrics and timing**
|
|
170
|
+
|
|
171
|
+
|
|
172
|
+
</td>
|
|
173
|
+
<td width="50%">
|
|
174
|
+
|
|
175
|
+
**Benchmark with confidence radar**
|
|
176
|
+
|
|
177
|
+
|
|
178
|
+
</td>
|
|
179
|
+
</tr>
|
|
180
|
+
<tr>
|
|
181
|
+
<td width="50%">
|
|
182
|
+
|
|
183
|
+
**Embeddings — cosine similarity**
|
|
184
|
+
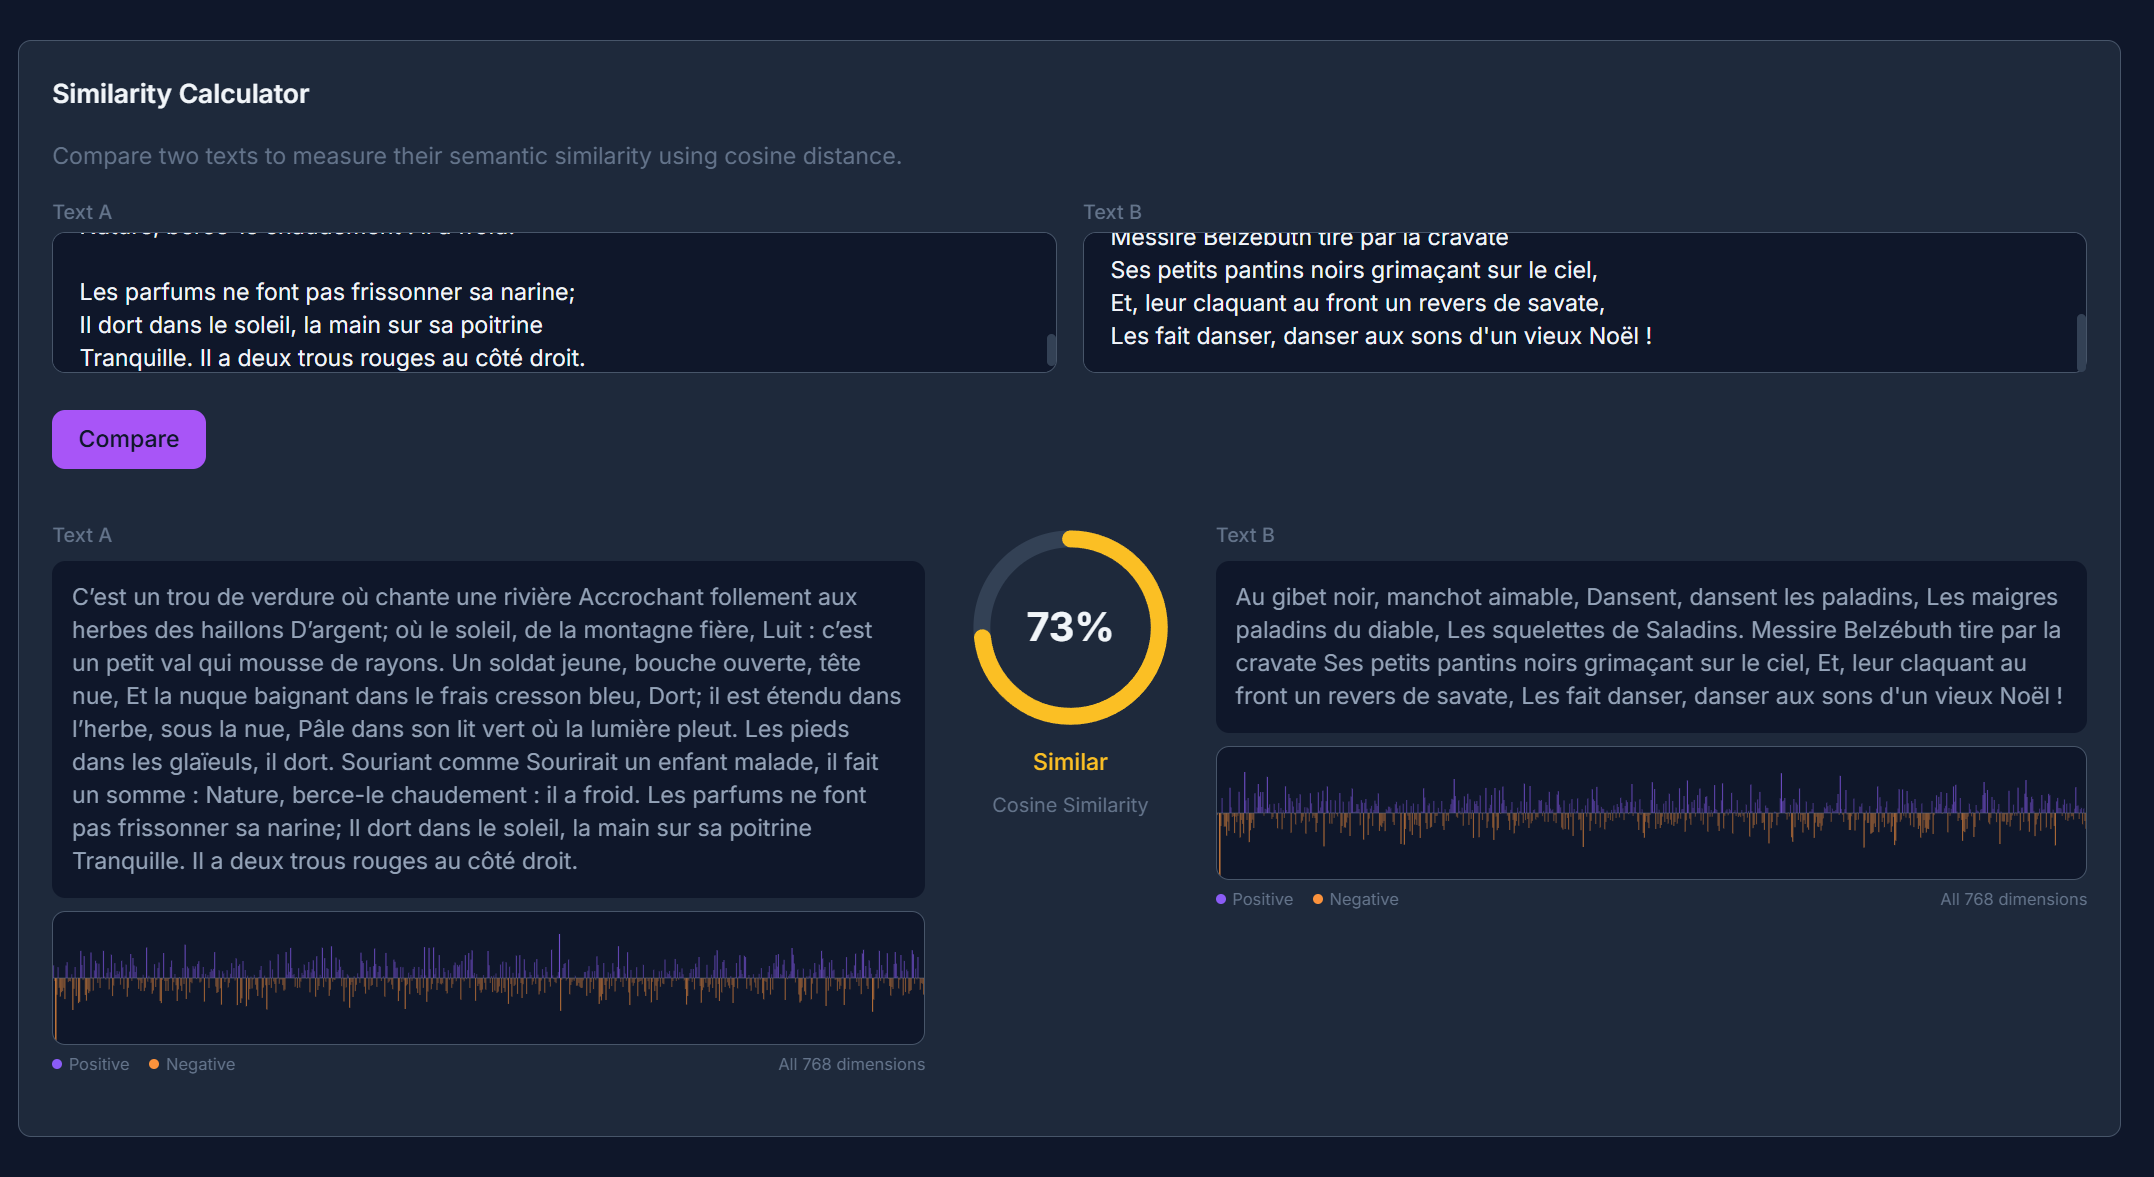
|
|
185
|
+
|
|
186
|
+
</td>
|
|
187
|
+
<td width="50%">
|
|
188
|
+
|
|
189
|
+
**System monitor — hardware and Ollama status**
|
|
190
|
+
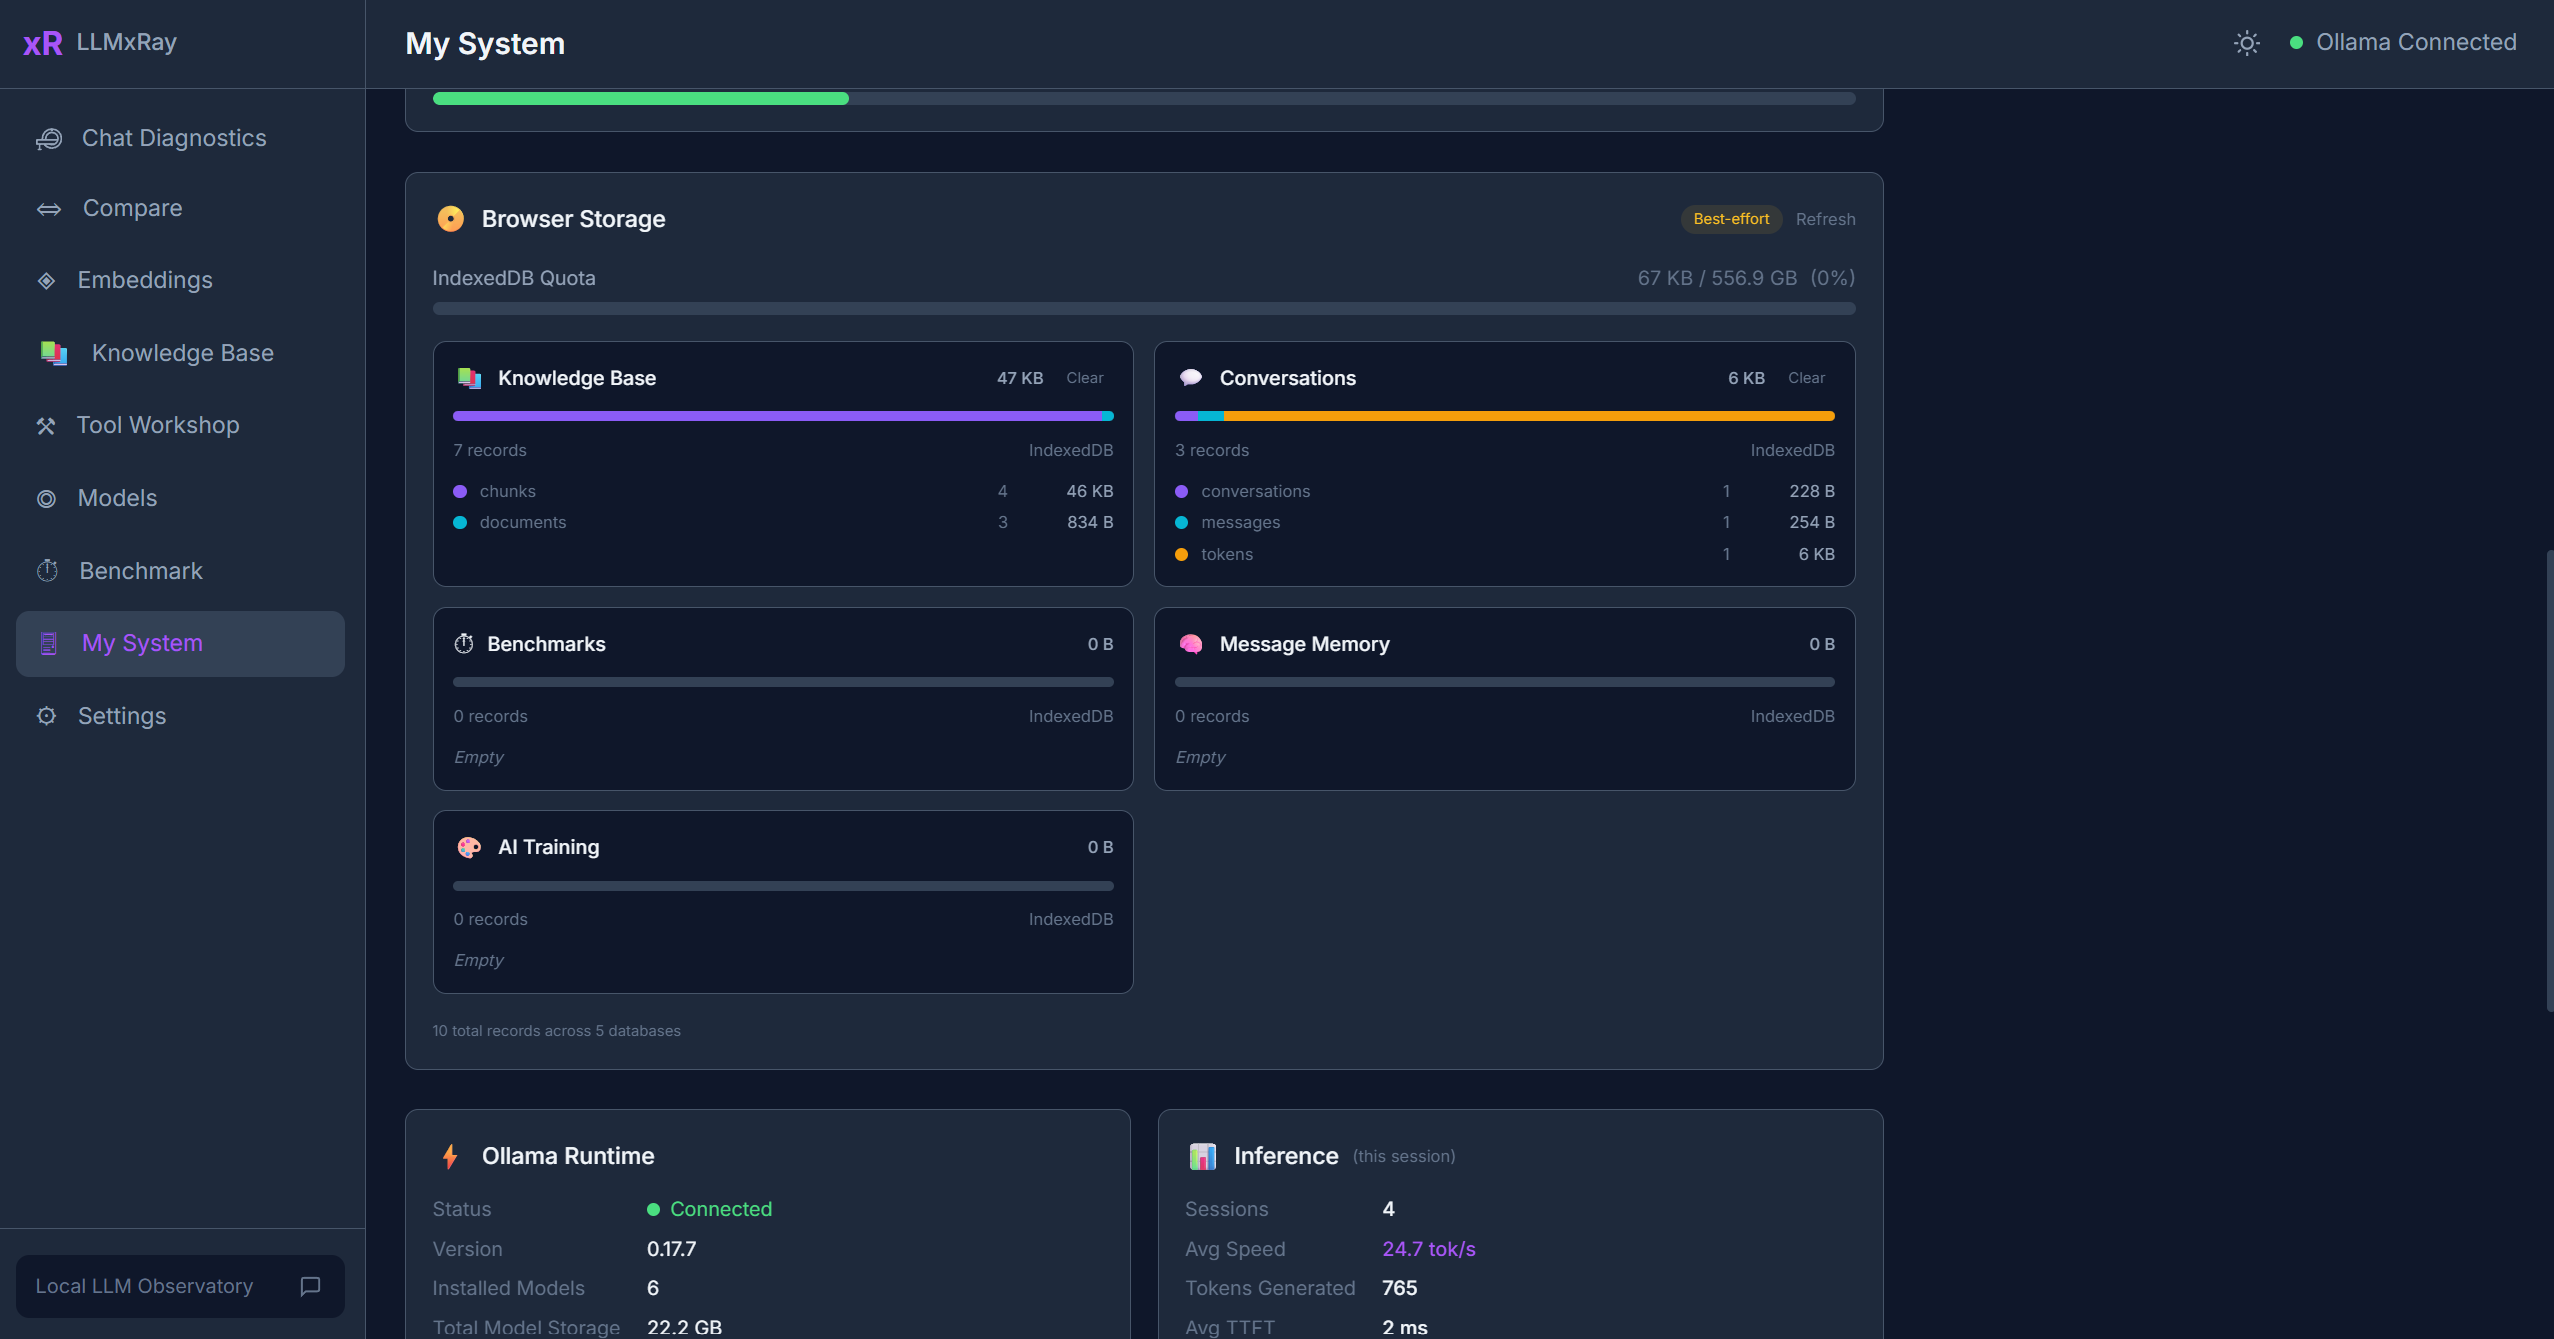
|
|
191
|
+
|
|
192
|
+
</td>
|
|
193
|
+
</tr>
|
|
194
|
+
</table>
|
|
195
|
+
|
|
196
|
+
---
|
|
197
|
+
|
|
198
|
+
## Who Is This For
|
|
199
|
+
|
|
200
|
+
| You are... | LLMxRay helps you... |
|
|
201
|
+
|---|---|
|
|
202
|
+
| **Developer** | Debug prompts, profile latency, compare models, inspect tool calls, track costs |
|
|
203
|
+
| **Researcher** | Run controlled experiments with consistent settings across models and temperatures |
|
|
204
|
+
| **Student / Educator** | Explore model behavior visually — built-in Educators Kit with 9 interactive modules |
|
|
205
|
+
| **AI team lead** | Understand quality trends, error patterns, and resource usage across your local fleet |
|
|
206
|
+
|
|
207
|
+
---
|
|
208
|
+
|
|
209
|
+
## Install Options
|
|
210
|
+
|
|
211
|
+
### npx (recommended)
|
|
212
|
+
```bash
|
|
213
|
+
npx llmxray
|
|
214
|
+
npx llmxray --port 3000
|
|
215
|
+
npx llmxray --ollama-url http://192.168.1.50:11434
|
|
216
|
+
```
|
|
217
|
+
|
|
218
|
+
### Docker
|
|
219
|
+
```bash
|
|
220
|
+
docker run -p 5174:5174 djovaneli/llmxray
|
|
221
|
+
docker run -p 5174:5174 -e OLLAMA_URL=http://host.docker.internal:11434 djovaneli/llmxray
|
|
222
|
+
```
|
|
223
|
+
|
|
224
|
+
### From source
|
|
225
|
+
```bash
|
|
226
|
+
git clone https://github.com/LogneBudo/llmxray.git
|
|
227
|
+
cd llmxray
|
|
228
|
+
npm install
|
|
229
|
+
npm run dev # http://localhost:5173
|
|
230
|
+
```
|
|
231
|
+
|
|
232
|
+
---
|
|
233
|
+
|
|
234
|
+
## Tech Stack
|
|
235
|
+
|
|
236
|
+
| Layer | Technology |
|
|
237
|
+
|---|---|
|
|
238
|
+
| Framework | Vue 3.5 + Composition API |
|
|
239
|
+
| Language | TypeScript 5.9 (strict) |
|
|
240
|
+
| Build | Vite 7.3 |
|
|
241
|
+
| Styling | Tailwind CSS 4.2 |
|
|
242
|
+
| State | Pinia 3 (store-per-concern) |
|
|
243
|
+
| Charts | Chart.js 4, D3.js 7 |
|
|
244
|
+
| Canvas | Vue Flow (visual node editor) |
|
|
245
|
+
| Code Editor | CodeMirror 6 |
|
|
246
|
+
| Storage | IndexedDB (browser-native) |
|
|
247
|
+
| LLM Backend | Ollama (local) |
|
|
248
|
+
|
|
249
|
+
---
|
|
250
|
+
|
|
251
|
+
## Architecture
|
|
252
|
+
|
|
253
|
+
**Streaming** — Reads Ollama NDJSON via `fetch()` + `ReadableStream`. Tokens update the UI reactively through Pinia stores.
|
|
254
|
+
|
|
255
|
+
**Token confidence** — Approximated from inter-token latency (faster = more confident). Clearly labeled as approximation. Benchmarks use real logprobs via OpenAI-compatible endpoint.
|
|
256
|
+
|
|
257
|
+
**Store-per-concern** — Each domain has its own Pinia store: tokens, sessions, metrics, reasoning, comparison, embeddings, quality, cost, and more.
|
|
258
|
+
|
|
259
|
+
**Hardware detection** — Custom Vite plugin queries the OS directly (PowerShell/proc/sysctl) for accurate hardware specs.
|
|
260
|
+
|
|
261
|
+
---
|
|
262
|
+
|
|
263
|
+
## Development
|
|
264
|
+
|
|
265
|
+
| Command | What it does |
|
|
266
|
+
|---|---|
|
|
267
|
+
| `npm run dev` | Dev server (port 5173) |
|
|
268
|
+
| `npm run build` | Type-check + production build |
|
|
269
|
+
| `npm run test` | Unit tests (Vitest) |
|
|
270
|
+
| `npm run test:e2e` | End-to-end (Playwright) |
|
|
271
|
+
|
|
272
|
+
---
|
|
273
|
+
|
|
274
|
+
## Contributing
|
|
275
|
+
|
|
276
|
+
Contributions welcome! See [CONTRIBUTING.md](CONTRIBUTING.md) for setup and guidelines.
|
|
277
|
+
|
|
278
|
+
**Community translations especially welcome** — scaffold files ready for Hebrew and Japanese.
|
|
279
|
+
|
|
280
|
+
---
|
|
281
|
+
|
|
282
|
+
## License
|
|
283
|
+
|
|
284
|
+
[Apache License 2.0](LICENSE)
|
|
285
|
+
|
|
286
|
+
## Trademark
|
|
287
|
+
|
|
288
|
+
**LLMxRay** is a trademark of Ivan Stankovic ([LogneBudo](https://github.com/LogneBudo)). See [TRADEMARK.md](TRADEMARK.md).
|
|
289
|
+
|
|
290
|
+
---
|
|
291
|
+
|
|
292
|
+
<p align="center">
|
|
293
|
+
<strong>If LLMxRay helps you understand your AI better, consider giving it a star.</strong><br/>
|
|
294
|
+
It helps others discover the project.
|
|
295
|
+
</p>
|
|
296
|
+
|
|
297
|
+
<p align="center">
|
|
298
|
+
<a href="https://github.com/LogneBudo/llmxray">
|
|
299
|
+
<img src="https://img.shields.io/github/stars/LogneBudo/llmxray?style=social" alt="GitHub stars" />
|
|
300
|
+
</a>
|
|
301
|
+
</p>
|