dsh-voice-mode 0.5.0 → 0.7.0
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.en.md +6 -5
- package/README.md +5 -4
- package/lib/client.js +486 -71
- package/lib/index.js +107 -35
- package/package.json +24 -10
- package/scripts/check-anchors.mjs +85 -0
- package/scripts/prefetch.mjs +22 -6
package/README.en.md
CHANGED
|
@@ -11,11 +11,11 @@
|
|
|
11
11
|
>
|
|
12
12
|
> 中文说明见 [README.md](./README.md)。
|
|
13
13
|
|
|
14
|
-
> **Version note (0.
|
|
14
|
+
> **Version note (0.6.0)**: Edge cloud TTS by default (fast & natural); local TTS (VITS / Kokoro, privacy-first) optional + HTTP hardening + model SHA256 pinning form the merged core; Kokoro adds a model-precision choice (`int8` default 109 MB / `fp32` better quality 311 MB); `wakeWord` (wake word) and `toolBeep` (tool-call beep) are fully wired; the early fork's `asrModel` (bilingual paraformer) and `punctuate` (neural punctuation) were removed — SenseVoice finalization already adds punctuation, and streaming ASR is fixed to zipformer2. Silence split defaults to 700 ms.
|
|
15
15
|
|
|
16
16
|
## Fork enhancements (this repo)
|
|
17
17
|
|
|
18
|
-
- **Edge cloud TTS by default; local TTS optional (privacy-first)**: local VITS (Chinese) and local Kokoro
|
|
18
|
+
- **Edge cloud TTS by default; local TTS optional (privacy-first)**: local VITS (Chinese) and local Kokoro (zh+en, 103 voices; `int8` default ~109 MB / `fp32` ~311 MB for better quality; native `sherpa-onnx-node` addon, no WASM memory limits) run in an isolated child process;
|
|
19
19
|
- **103 Kokoro voices** (F0-measured gender labels, 4 favourite male voices pinned), browsed with a ◀▶ stepper;
|
|
20
20
|
- **Delta transport**: partials upload only the new 0.9 s — long push-to-talk segments finalize in seconds;
|
|
21
21
|
- **Interaction**: a mode-switch button next to the mic (continuous ⇄ hold, persisted); hold mode records only while held;
|
|
@@ -34,7 +34,7 @@
|
|
|
34
34
|
- `toggle` (default) continuous listening: RMS VAD segmentation → streaming zipformer2 ASR (words appear as you speak, live caption preview) → automatic sentence split and send after 700 ms of silence; hold `Ctrl` to force an immediate send
|
|
35
35
|
- `hold` push-to-talk: short tap to enter/exit, **hold the mic button to talk, release to send** (swipe up to cancel, `Esc`/blur abandons the segment; pauses do not split while held, up to 10 min); hold `Ctrl` to record-by-keyboard, release to send
|
|
36
36
|
- **Wake word (optional, off by default)**: after setting `wakeWord`, entering voice mode starts in standby, and recognition only begins once the wake word is spoken (e.g. `你好小D`), preventing accidental triggers
|
|
37
|
-
- **Output pipeline**: only the final answer's `text-delta` is read (reasoning/tool calls are skipped), streamed sentence-by-sentence (Edge cloud by default; local VITS / Kokoro int8 optional) with a live caption overlay at the bottom-right; tool calls trigger a beep; the full text is still written to the chat; in voice mode a spoken-format system prompt is injected (short natural sentences, no Markdown decoration), and the reader side strips markers as well for a smoother listening experience
|
|
37
|
+
- **Output pipeline**: only the final answer's `text-delta` is read (reasoning/tool calls are skipped), streamed sentence-by-sentence (Edge cloud by default; local VITS / Kokoro, int8/fp32, optional) with a live caption overlay at the bottom-right; tool calls trigger a beep; the full text is still written to the chat; in voice mode a spoken-format system prompt is injected (short natural sentences, no Markdown decoration), and the reader side strips markers as well for a smoother listening experience
|
|
38
38
|
- **Barge-in**: three sensitivity levels of voice-onset detection → local mute + host synth queue invalidation (epoch) + running turn cancellation (the half-finished part is kept and naturally flows into your new message)
|
|
39
39
|
- **Lazy model download with progress**: the zipformer2 Chinese streaming model (~160 MB, `.part` resumable) is downloaded on first use with live progress in the status bar; `npm run prefetch` can pre-download it
|
|
40
40
|
- **Resilience**: mic-denied red hint, visible model-download failure, TTS unreachable status hint (auto retry), failed submit keeps the text in the draft, SSE auto-reconnect
|
|
@@ -100,7 +100,8 @@ If a wake word is configured, you land in standby first (the status bar prompts
|
|
|
100
100
|
|
|
101
101
|
| Key | Default | Description |
|
|
102
102
|
| --- | --- | --- |
|
|
103
|
-
| `ttsEngine` | `edge` | Read-aloud engine: `edge` Microsoft cloud (default, fast) / `vits` local Chinese / `kokoro` local zh+en
|
|
103
|
+
| `ttsEngine` | `edge` | Read-aloud engine: `edge` Microsoft cloud (default, fast) / `vits` local Chinese / `kokoro` local zh+en; **applies live** |
|
|
104
|
+
| `kokoroModel` | `int8` | Kokoro precision: `int8` (default, 109 MB, CPU/low-bandwidth) / `fp32` (311 MB, better quality, GPU/large memory); same 103 voices; **applies live** |
|
|
104
105
|
| `voice` | per engine | Voice: 5 VITS speakers; 103 Kokoro voices (◀▶ stepper; 62/68/75/76 favourite males pinned); Edge ShortNames below. The inline "试听" button previews it at the current rate |
|
|
105
106
|
| `rate` | `1.0` | Reading speed multiplier (0.5 slow ~ 2.0 fast), **applies live** |
|
|
106
107
|
| `interruptLevel` | `0` | Barge-in sensitivity (host-side VAD frame detection + echo gate): 0 high threshold / 1 medium / 2 low |
|
|
@@ -111,7 +112,7 @@ If a wake word is configured, you land in standby first (the status bar prompts
|
|
|
111
112
|
| `mode` | `toggle` | Interaction mode: `toggle` continuous listening + 700 ms silence split; `hold` push-to-talk, release to send (short tap exits) |
|
|
112
113
|
| `wakeWord` | empty (off) | Wake word (e.g. `你好小D`): speak it after entering to activate, avoiding accidental triggers; empty = off |
|
|
113
114
|
|
|
114
|
-
Effect timing: `voice`/`rate` take effect **immediately** (TTS hot-swap); the rest apply on the next voice-mode entry. Defaults come from the plugin config (`base` layer) — they follow the config unless explicitly changed.
|
|
115
|
+
Effect timing: `voice`/`rate`/`ttsEngine`/`kokoroModel`/`spokenFormat` take effect **immediately** (TTS hot-swap); the rest apply on the next voice-mode entry. Defaults come from the plugin config (`base` layer) — they follow the config unless explicitly changed.
|
|
115
116
|
|
|
116
117
|
### Common voices (full list: `node scripts/list-voices.mjs`)
|
|
117
118
|
|
package/README.md
CHANGED
|
@@ -13,7 +13,7 @@ DeepSeek Harness 语音双工对话模式:会话内一键进入 → 边说边
|
|
|
13
13
|
|
|
14
14
|
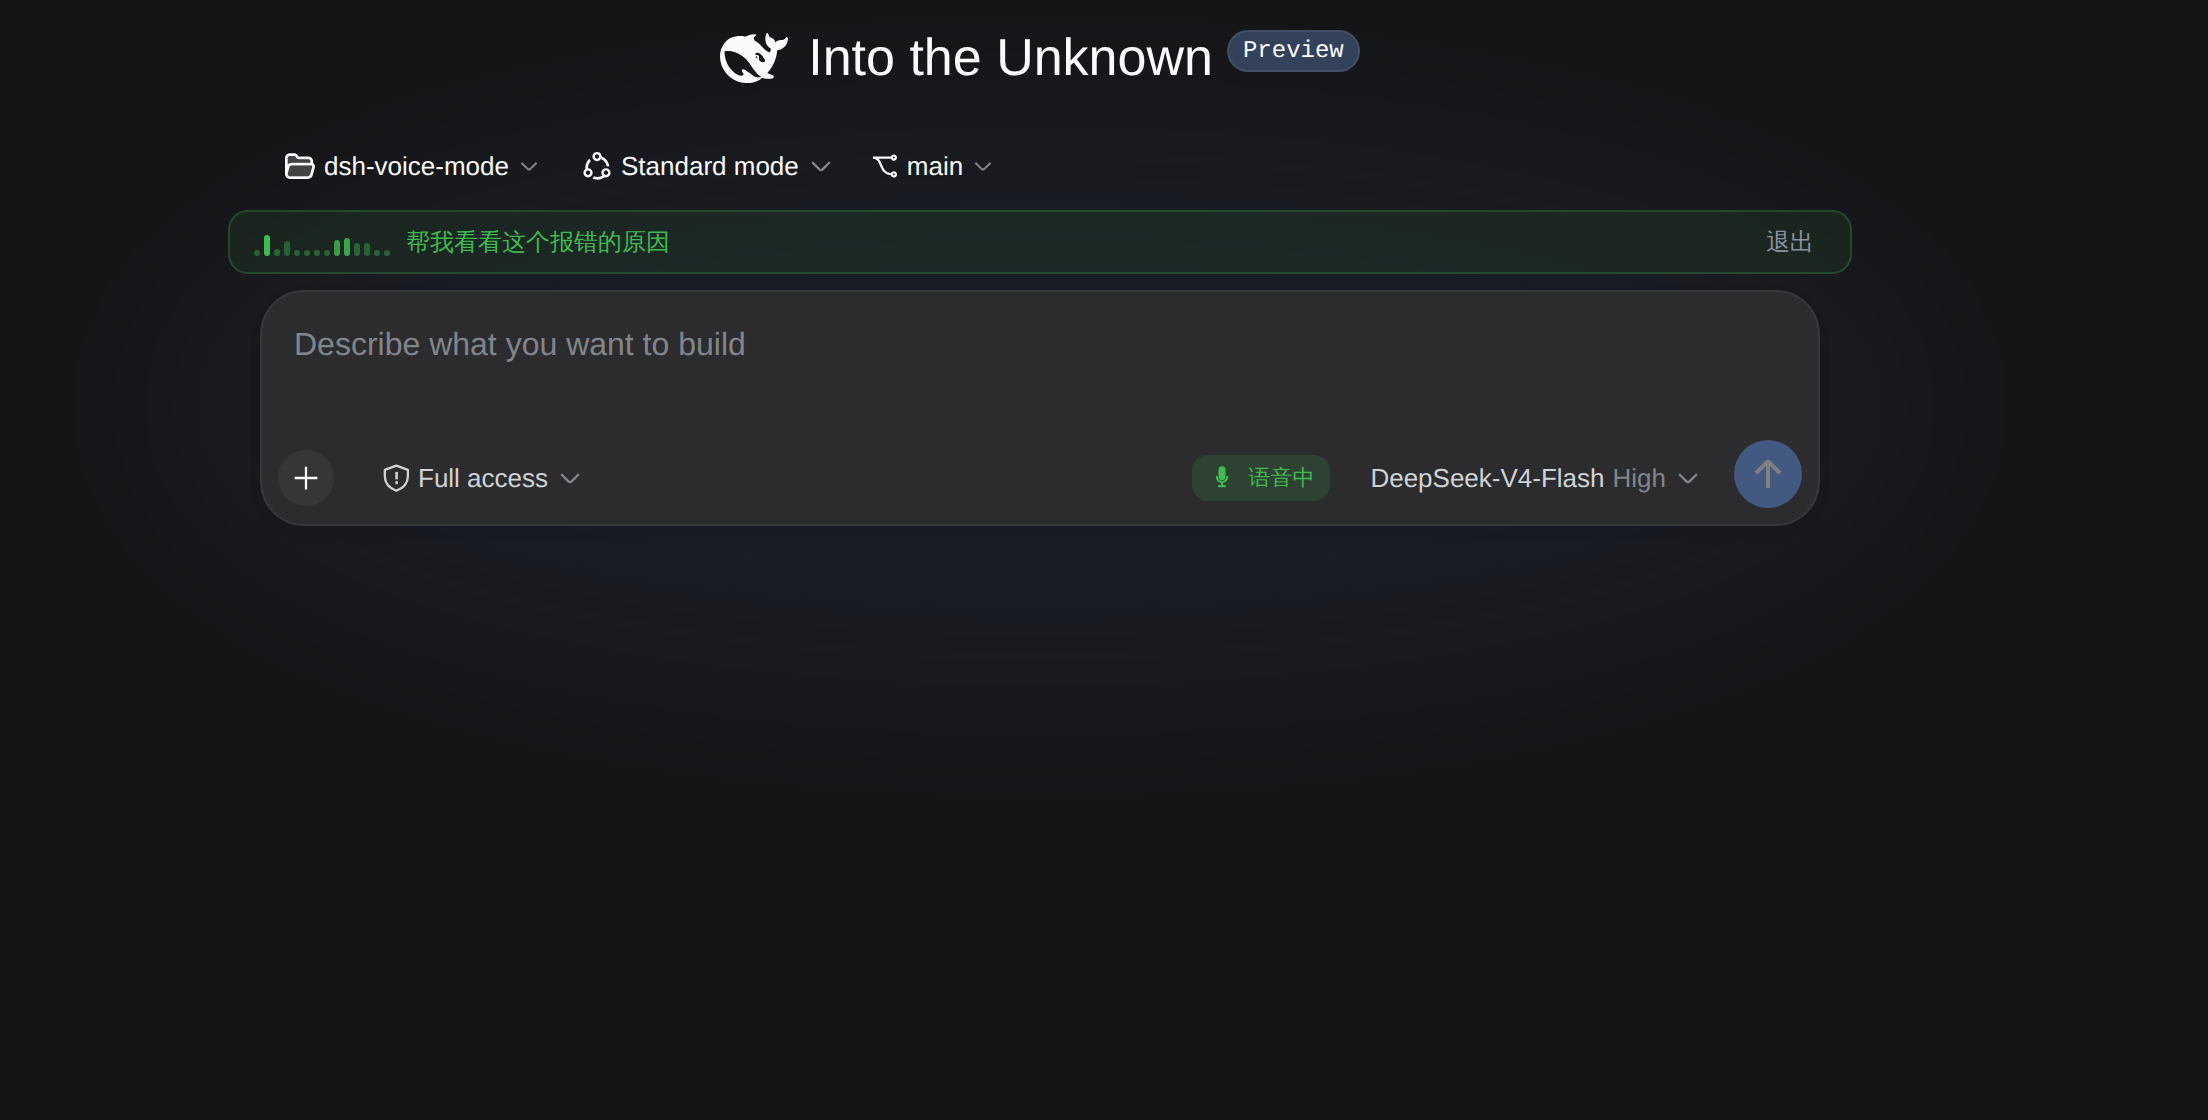
|
|
15
15
|
|
|
16
|
-
> **版本说明(0.
|
|
16
|
+
> **版本说明(0.6.0)**:朗读默认 **Edge 云端**(快速自然),本地 TTS(VITS / Kokoro)可选(隐私优先)+ HTTP 安全加固 + 模型 SHA256 固定为合入核心;Kokoro 新增**模型精度可选**(`int8` 默认 109MB / `fp32` 音质更好 311MB);`wakeWord`(唤醒词)与 `toolBeep`(工具提示音)已完整接入;早期 fork 的 `asrModel`(双语 paraformer)与 `punctuate`(神经标点)已移除——SenseVoice 定稿本身已带标点,流式识别固定为 zipformer2。静音断句默认 700 毫秒。
|
|
17
17
|
|
|
18
18
|
## Fork 增强(本仓库新增)
|
|
19
19
|
|
|
@@ -21,7 +21,7 @@ DeepSeek Harness 语音双工对话模式:会话内一键进入 → 边说边
|
|
|
21
21
|
|
|
22
22
|
- **朗读默认 Edge 云端;本地 TTS 可选(隐私优先)**:选本地则回复文本不出本机——
|
|
23
23
|
- 本地 VITS(`sherpa-onnx-vits-zh-ll`,纯中文,5 说话人);
|
|
24
|
-
- 本地 Kokoro
|
|
24
|
+
- 本地 Kokoro(**中英混读**,103 音色;`int8` 默认约 109MB / 可选 `fp32` 约 311MB 音质更好),经 `sherpa-onnx-node` **原生 addon** 运行(无 WASM 内存上限,连续合成不崩);
|
|
25
25
|
- Edge 云端朗读保留为可选(设置 `ttsEngine: edge`);设置面板「朗读引擎」热切换。
|
|
26
26
|
- **Kokoro 音色全量 103 个**(F0 实测标定性别),四个常用男声置顶带编号;音色面板用 **下拉列表 + ◀▶ 步进**切换;
|
|
27
27
|
- **增量传输**:partial 只传新增 0.9 秒,长段按住说话松手**秒出定稿**(不再整段重传重解码);
|
|
@@ -73,6 +73,7 @@ bundle 插件安装后需重启 dsh 生效(Linux:`systemctl restart dsh`;
|
|
|
73
73
|
| 键 | 默认 | 说明 |
|
|
74
74
|
| --- | --- | --- |
|
|
75
75
|
| `ttsEngine` | `edge` | 朗读引擎:`edge` 微软云端(默认,快)/ `vits` 本地中文 / `kokoro` 本地中英;**即时生效** |
|
|
76
|
+
| `kokoroModel` | `int8` | Kokoro 模型精度:`int8`(默认,109MB,纯 CPU/低带宽推荐)/ `fp32`(311MB,音质更好,独显/大内存推荐);两档共用 103 音色,**即时生效** |
|
|
76
77
|
| `voice` | 按引擎 | 音色:VITS 五说话人;Kokoro 103 个(下拉+◀▶,62 深沉/68 浑厚/75 清亮/76 磁性置顶);Edge 进入时自动加载全量 322 个。行内「试听」可即时预览 |
|
|
77
78
|
| `rate` | `1.0` | 朗读语速倍率(0.5 慢速 ~ 2.0 快速),**即时生效** |
|
|
78
79
|
| `interruptLevel` | `0` | 发声打断灵敏度(服务端 VAD 帧级检测 + 回声门控):0 高门槛 / 1 中 / 2 低 |
|
|
@@ -82,9 +83,9 @@ bundle 插件安装后需重启 dsh 生效(Linux:`systemctl restart dsh`;
|
|
|
82
83
|
| `autoSend` | `true` | 识别定稿后自动发送;关闭则只进草稿(按住 `Ctrl` / hold 松手仍会发送) |
|
|
83
84
|
| `mode` | `toggle` | 交互模式:`toggle` 持续聆听 + 700ms 静音断句;`hold` 按住说话、松手发送(短按退出) |
|
|
84
85
|
| `wakeWord` | 空(关) | 唤醒词(如「你好小D」):进入后先说唤醒词激活,避免误触;空 = 关闭 |
|
|
85
|
-
| `spokenFormat` | `
|
|
86
|
+
| `spokenFormat` | `true` | 语音会话注入口语化提示词:开启后**仅当前语音会话**的回复被注入「口语化短句、不用 Markdown 排版符号」提示词(朗读更顺),**即时生效** |
|
|
86
87
|
|
|
87
|
-
生效范围:`voice`/`rate`/`ttsEngine`/`spokenFormat` **立即生效**;其余设置下次进入语音模式时生效。设置项默认值由插件配置(`base` 层)提供。
|
|
88
|
+
生效范围:`voice`/`rate`/`ttsEngine`/`kokoroModel`/`spokenFormat` **立即生效**;其余设置下次进入语音模式时生效。设置项默认值由插件配置(`base` 层)提供。
|
|
88
89
|
|
|
89
90
|
### 本地音色(VITS / Kokoro)
|
|
90
91
|
|