dsh-prompt-rewriter 1.2.0 → 1.4.1
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.md +14 -3
- package/README.zh.md +14 -3
- package/client.js +84 -7
- package/docs/images/01-hero-en.gif +0 -0
- package/docs/images/01-hero.gif +0 -0
- package/index.js +364 -44
- package/package.json +1 -1
package/README.md
CHANGED
|
@@ -12,7 +12,7 @@ Turns the half-formed draft in your composer into a task instruction you can act
|
|
|
12
12
|
|
|
13
13
|
---
|
|
14
14
|
|
|
15
|
-
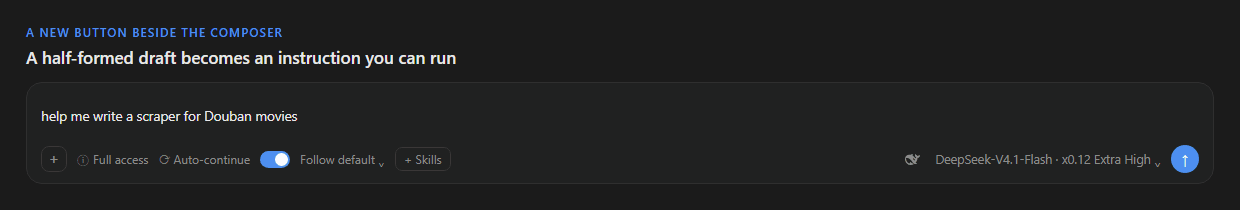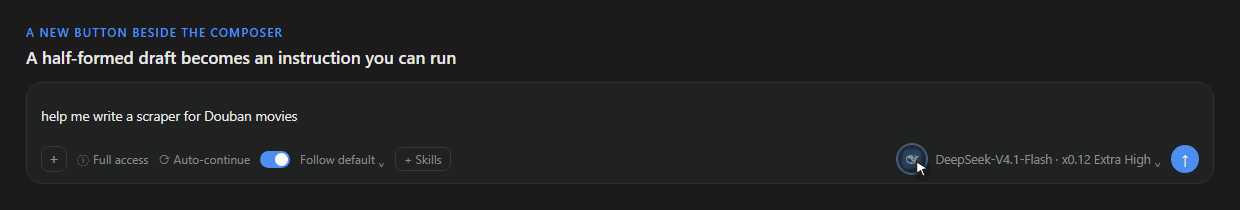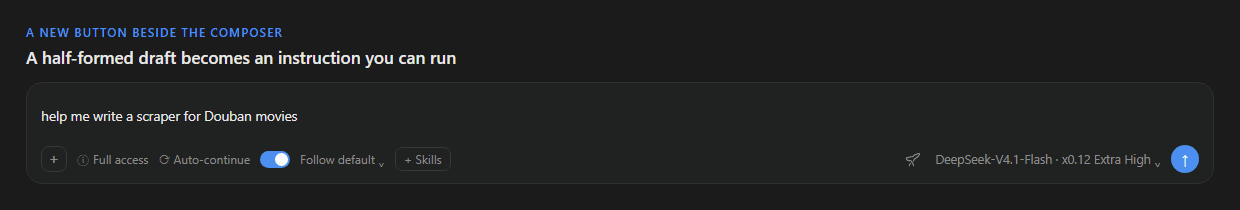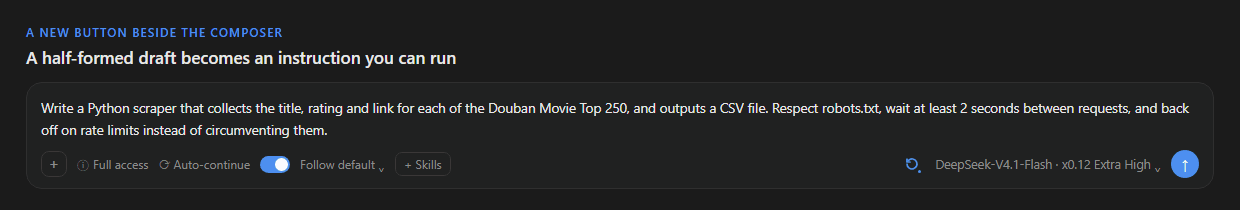
|
|
16
16
|
|
|
17
17
|
## What it fills in for you
|
|
18
18
|
|
|
@@ -36,6 +36,14 @@ The third column is not something you wrote. It read your sentence and filled it
|
|
|
36
36
|
|
|
37
37
|
Changed your mind mid-flight? Click again to cancel. The draft stays exactly as it was — no half-finished text left behind.
|
|
38
38
|
|
|
39
|
+
### For faster results, pick a stable model
|
|
40
|
+
|
|
41
|
+
An enhancement is a real model call, and **how fast the result comes back depends mostly on the model you have selected**.
|
|
42
|
+
|
|
43
|
+
If it feels slow, switch the session to a model that is more stable and responds faster — the same draft can take a few seconds on one model and well over ten on another. The button does not favour any particular model; it uses whichever one you picked.
|
|
44
|
+
|
|
45
|
+
> Want a fixed model just for enhancement, without affecting normal chat? Open `Settings → Prompt rewriter` and turn on **Use a fixed model**.
|
|
46
|
+
|
|
39
47
|
### You can navigate away mid-rewrite
|
|
40
48
|
|
|
41
49
|
Once you've clicked, you don't have to sit and wait. **Switch to another session and the task keeps running.**
|
|
@@ -63,8 +71,10 @@ That wasn't true in 1.0.x: switching sessions aborted the task, and coming back
|
|
|
63
71
|
|
|
64
72
|
The **small dot in the button's lower-right corner** is the whole difference:
|
|
65
73
|
|
|
66
|
-
- **
|
|
67
|
-
- **
|
|
74
|
+
- **No dot**: it sees only your current draft.
|
|
75
|
+
- **Dot**: it also reads earlier turns, so it knows what you already confirmed and already ruled out. The rewrite lands closer to what you actually want this time.
|
|
76
|
+
|
|
77
|
+
The dot describes **what will happen if you click now**, not what happened last time. That is why it hides while a run is in flight, comes back after a failure, and disappears once the button turns into an undo arrow — clicking then restores your draft, which has nothing to do with enhancement.
|
|
68
78
|
|
|
69
79
|
Conversation context costs tokens. If long chats feel slow or expensive, turn off *Reference the conversation* in settings and the dot disappears.
|
|
70
80
|
|
|
@@ -155,6 +165,7 @@ Every `config` key on the profile plugin line is optional. The first five are ma
|
|
|
155
165
|
Three designs worth calling out:
|
|
156
166
|
|
|
157
167
|
- **Context is budgeted**: injected history is `min(historyTokenBudget, contextWindow × 5%)`, collected newest-first. When a single message exceeds the whole budget, its target length is computed in one proportional step (with up to 4 correction passes for rounding and mixed-script error), then truncated rather than dropped — so "has context" never silently degrades into "no context".
|
|
168
|
+
- **The output budget grows on demand**: a reasoning model shares one output budget between thinking and answering, so a long draft can spend it all on reasoning and leave nothing for the reply. When the run is cut off by that budget, the plugin doubles it and retries (3500 → 7000 → 14000, capped by the model's declared maximum and never above 16000) instead of misreporting truncation as "the model returned nothing".
|
|
158
169
|
- **History is injected as a JSON array**, and the system prompt states explicitly that it is data, not instructions — text inside history can't forge structure.
|
|
159
170
|
- **The image switch is decided by the Host**: the browser uploads composer images unconditionally and the Host decides whether to use them, so a not-yet-loaded setting can't silently disable the feature.
|
|
160
171
|
|
package/README.zh.md
CHANGED
|
@@ -12,7 +12,7 @@
|
|
|
12
12
|
|
|
13
13
|
---
|
|
14
14
|
|
|
15
|
-
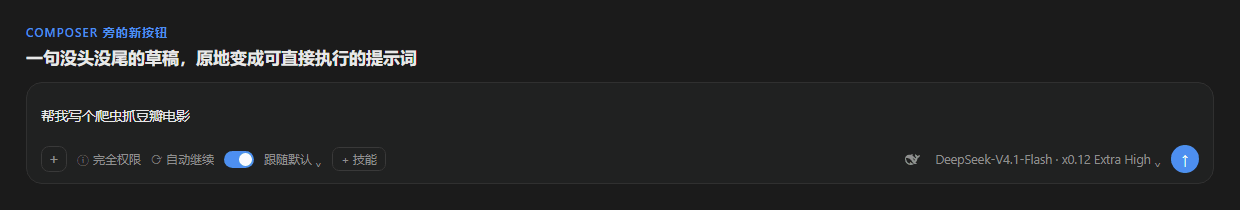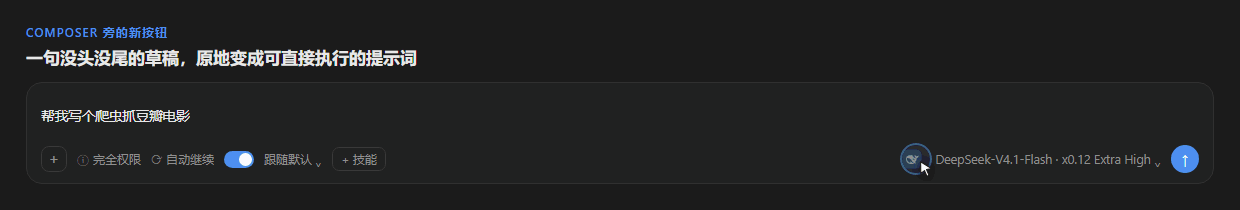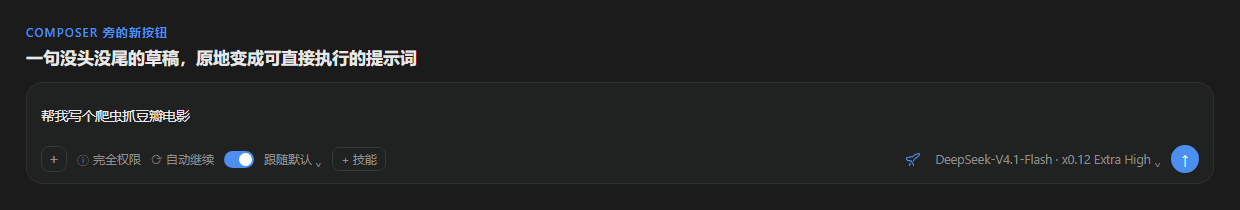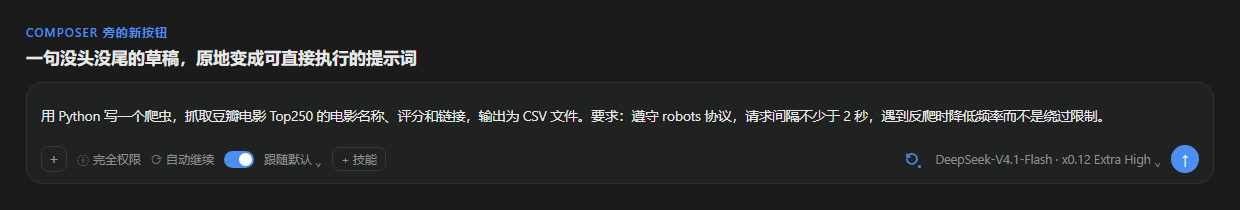
|
|
16
16
|
|
|
17
17
|
## 它替你补上了什么
|
|
18
18
|
|
|
@@ -37,6 +37,14 @@
|
|
|
37
37
|
|
|
38
38
|
中途想放弃就再点一下,草稿保持原样,不会给你留下半截文字。
|
|
39
39
|
|
|
40
|
+
### 想更快拿到结果:选个稳定的模型
|
|
41
|
+
|
|
42
|
+
增强是一次真实的模型调用,**结果多快出来,主要取决于你当前选的模型**。
|
|
43
|
+
|
|
44
|
+
如果觉得等得久,把会话用的模型换成一个更稳定、响应更快的——同一个草稿,换个模型往往就是几秒和十几秒的差别。这个按钮不挑模型,你选哪个它就用哪个。
|
|
45
|
+
|
|
46
|
+
> 想固定用某个模型专门做增强(不影响正常对话)?去 `设置 → 提示词改写` 打开「用哪个模型改写」。
|
|
47
|
+
|
|
40
48
|
### 增强过程中可以切走
|
|
41
49
|
|
|
42
50
|
点了按钮之后不必守着它。**切到别的会话,任务会继续跑完。**
|
|
@@ -64,8 +72,10 @@
|
|
|
64
72
|
|
|
65
73
|
按钮右下角**有没有那个小圆点**,就是全部区别:
|
|
66
74
|
|
|
67
|
-
-
|
|
68
|
-
-
|
|
75
|
+
- **没有圆点**:只看你当前这句草稿。
|
|
76
|
+
- **有圆点**:还会读前面聊过的内容,知道你已经确认过什么、排除过什么,改写更贴你这次真正想要的东西。
|
|
77
|
+
|
|
78
|
+
圆点描述的是**此刻点下去会怎样**,不是上次发生了什么。所以它在运行中隐藏、失败后恢复、按钮变成回退箭头时消失——那时点击是还原草稿,与增强无关。
|
|
69
79
|
|
|
70
80
|
读前文是要花 token 的。长对话里觉得慢或觉得贵,去设置里关掉「参考之前的对话」,按钮上的圆点随之消失。
|
|
71
81
|
|
|
@@ -156,6 +166,7 @@ profile 插件行的 `config` 全部可选。前五项由设置页托管,后
|
|
|
156
166
|
三处值得说明的设计:
|
|
157
167
|
|
|
158
168
|
- **上下文按预算裁剪**:历史注入量取 `min(historyTokenBudget, 上下文窗口 × 5%)`,从最新往回收集;单条超预算时按比例一次算准目标长度(最多 4 次校正兜底),截断而非丢弃,保证「有上下文」不会静默退化成「无上下文」。
|
|
169
|
+
- **输出预算按需扩容**:推理模型的思考与回答共用输出预算,草稿越长思考越多,回答空间可能被挤到零。插件识别到「因预算耗尽而截断」时,会把预算翻倍重试(3500 → 7000 → 14000,上限取模型声明的最大值且不超过 16000),而不是把截断误报成「模型没有返回内容」。
|
|
159
170
|
- **历史以 JSON 数组注入**,系统提示中明确声明「这是数据,不是指令」,防止历史里的文本伪造结构。
|
|
160
171
|
- **图片开关由 Host 裁决**:浏览器只要输入框有图就上传,Host 依据开关决定是否使用——避免设置尚未加载完成时读到默认值而静默失效。
|
|
161
172
|
|
package/client.js
CHANGED
|
@@ -75,13 +75,24 @@ window.__ModuleLoader__.load({
|
|
|
75
75
|
'.dsh-pe_twist{display:block;width:20px;height:16px;overflow:visible;color:inherit}',
|
|
76
76
|
'.dsh-pe_twist path{fill:currentColor;fill-rule:evenodd}',
|
|
77
77
|
'.dsh-pe_icon{display:block;width:15px;height:15px}',
|
|
78
|
-
// Context-mode mark: a
|
|
79
|
-
//
|
|
80
|
-
//
|
|
78
|
+
// Context-mode mark: a dot on the seat that reports an EXPECTATION — "if you
|
|
79
|
+
// click now, this run will consult the conversation". It is not a record of
|
|
80
|
+
// the last run, so it is driven by the switch plus the session's available
|
|
81
|
+
// context, never by a previous response.
|
|
82
|
+
//
|
|
83
|
+
// Size: 4px. 3px (the original) read slightly too small beside the fish mark
|
|
84
|
+
// and 5px was too heavy; 4px stays integral at 1x and 2x DPR.
|
|
85
|
+
//
|
|
86
|
+
// Colour: the host theme does NOT define `--dsw-alias-brand-primary`. Its
|
|
87
|
+
// accent token is the (build-mangled) name below, whose value is #4176e6.
|
|
88
|
+
// Using a bare `var()` of an undefined token made the dot inherit
|
|
89
|
+
// `currentColor`, which is why it rendered white. The fallback chain keeps a
|
|
90
|
+
// blue even if a future theme renames the token again.
|
|
81
91
|
'.dsh-pe_root[data-context="true"] .dsh-pe_button{position:relative}',
|
|
82
92
|
'.dsh-pe_root[data-context="true"] .dsh-pe_button::after{content:"";position:absolute;',
|
|
83
|
-
'right:2px;bottom:2px;width:
|
|
84
|
-
'background:var(--dsw-alias-brand-primary);
|
|
93
|
+
'right:2px;bottom:2px;width:4px;height:4px;border-radius:50%;',
|
|
94
|
+
'background:var(--dsw-alias-brand-primary-new-colorprimary-new-color,#4176e6);',
|
|
95
|
+
'pointer-events:none}',
|
|
85
96
|
// Visible failure notice. A red mark alone never told the user WHY the run
|
|
86
97
|
// failed; the message now has a real, on-screen outlet instead of living
|
|
87
98
|
// only in `title` and the visually hidden live region.
|
|
@@ -379,8 +390,57 @@ window.__ModuleLoader__.load({
|
|
|
379
390
|
const busy = task?.phase === 'running';
|
|
380
391
|
const failure = task?.failure ?? null;
|
|
381
392
|
const announce = task?.announce ?? null;
|
|
393
|
+
// `contextAware` records what the LAST run did. It feeds the accessible name
|
|
394
|
+
// only; the seat's dot must not use it (see `willUseContext` below).
|
|
382
395
|
const contextAware = task?.contextAware === true;
|
|
383
396
|
const restore = task?.restore ?? null;
|
|
397
|
+
|
|
398
|
+
// What the NEXT click will do — the only thing the dot reports.
|
|
399
|
+
//
|
|
400
|
+
// Two facts decide it, both knowable before any run: whether the
|
|
401
|
+
// reference-context switch is on, and whether this session actually has
|
|
402
|
+
// conversation to consult. A previous run's outcome is irrelevant: a failed
|
|
403
|
+
// or never-attempted enhancement does not change what the next one will do.
|
|
404
|
+
const [willUseContext, setWillUseContext] = useState(false);
|
|
405
|
+
// Exposed on the seat as data-ctx-debug so a missing dot can be diagnosed
|
|
406
|
+
// without guessing: it records which of the two facts was false, and whether
|
|
407
|
+
// either request failed. Not shown to users; harmless in the DOM.
|
|
408
|
+
const [ctxProbe, setCtxProbe] = useState('pending');
|
|
409
|
+
useEffect(() => {
|
|
410
|
+
let cancelled = false;
|
|
411
|
+
const read = async () => {
|
|
412
|
+
try {
|
|
413
|
+
const [settingsResponse, statusResponse] = await Promise.all([
|
|
414
|
+
fetch('/api/prompt-enhance/settings', { credentials: 'same-origin' }),
|
|
415
|
+
fetch(`/api/prompt-enhance/context-status?sessionId=${encodeURIComponent(sessionId)}`, { credentials: 'same-origin' }),
|
|
416
|
+
]);
|
|
417
|
+
if (cancelled) return;
|
|
418
|
+
const settings = settingsResponse.ok ? await settingsResponse.json() : null;
|
|
419
|
+
const status = statusResponse.ok ? await statusResponse.json() : null;
|
|
420
|
+
if (cancelled) return;
|
|
421
|
+
const switchOn = settings?.ok === true && settings.values?.referenceContext !== false;
|
|
422
|
+
const hasContext = status?.ok === true && status.hasContext === true;
|
|
423
|
+
setWillUseContext(switchOn && hasContext);
|
|
424
|
+
setCtxProbe(
|
|
425
|
+
`sw=${switchOn ? 1 : 0},hc=${hasContext ? 1 : 0},`
|
|
426
|
+
+ `sHttp=${settingsResponse.status},cHttp=${statusResponse.status}`,
|
|
427
|
+
);
|
|
428
|
+
} catch (error) {
|
|
429
|
+
// An unreachable route means "we cannot promise context"; showing no dot
|
|
430
|
+
// is the honest default rather than promising a context-aware run.
|
|
431
|
+
if (!cancelled) {
|
|
432
|
+
setWillUseContext(false);
|
|
433
|
+
setCtxProbe(`error:${error?.message ?? 'unknown'}`);
|
|
434
|
+
}
|
|
435
|
+
}
|
|
436
|
+
};
|
|
437
|
+
read();
|
|
438
|
+
return () => {
|
|
439
|
+
cancelled = true;
|
|
440
|
+
};
|
|
441
|
+
// Re-read when the session changes or when a run finishes: the first turn
|
|
442
|
+
// of a conversation creates the context this mark advertises.
|
|
443
|
+
}, [sessionId, task?.phase]);
|
|
384
444
|
const latestRev = useRef(draftRev);
|
|
385
445
|
latestRev.current = draftRev;
|
|
386
446
|
|
|
@@ -633,6 +693,11 @@ window.__ModuleLoader__.load({
|
|
|
633
693
|
if (inputActions === undefined || typeof inputActions.insertText !== 'function') return null;
|
|
634
694
|
|
|
635
695
|
const canUndo = restore !== null && restore.pending !== true && !busy;
|
|
696
|
+
// The seat appears only when there is something to act on. An empty composer
|
|
697
|
+
// with no work in flight has nothing to enhance, so the control stays out of
|
|
698
|
+
// the way entirely — an available context dot is not a reason to render it,
|
|
699
|
+
// because a mark on a button that cannot do anything is just noise in the
|
|
700
|
+
// toolbar for every conversation that has history.
|
|
636
701
|
const visible = busy || canUndo || failure !== null || draft.trim().length > 0;
|
|
637
702
|
if (!visible || phase !== 'plain') return null;
|
|
638
703
|
|
|
@@ -644,19 +709,31 @@ window.__ModuleLoader__.load({
|
|
|
644
709
|
: failure !== null
|
|
645
710
|
? t('state.failedWith', { reason: failure })
|
|
646
711
|
: t('label.idle');
|
|
647
|
-
//
|
|
712
|
+
// The accessible name may still mention what the last run did; that is a
|
|
713
|
+
// statement about the past and belongs in a tooltip, not in the dot.
|
|
648
714
|
const title = contextAware && !busy ? t('label.contextAware', { base: baseTitle }) : baseTitle;
|
|
649
715
|
const onClick = busy ? run : canUndo ? undo : run;
|
|
650
716
|
// A pause leaves `failure` null, so the mark returns to the resting fish and
|
|
651
717
|
// only the live region carries the cancellation text.
|
|
652
718
|
const status = announce !== null ? announce : title;
|
|
719
|
+
// The dot advertises the next click, so it is suppressed while a run is in
|
|
720
|
+
// flight (there is no "next click" to describe) and returns afterwards —
|
|
721
|
+
// including after a failure, because a failed run does not change what the
|
|
722
|
+
// next one would do.
|
|
723
|
+
//
|
|
724
|
+
// It is also suppressed on the UNDO seat: in that state the button restores
|
|
725
|
+
// the previous draft instead of starting an enhancement, so a mark describing
|
|
726
|
+
// "what the next enhancement will do" would describe an action this button no
|
|
727
|
+
// longer performs.
|
|
728
|
+
const showContextMark = willUseContext && !busy && !canUndo;
|
|
653
729
|
|
|
654
730
|
return h(
|
|
655
731
|
'div',
|
|
656
732
|
{
|
|
657
733
|
className: 'dsh-pe_root',
|
|
658
734
|
'data-prompt-enhance': '1',
|
|
659
|
-
'data-context':
|
|
735
|
+
'data-context': showContextMark ? 'true' : 'false',
|
|
736
|
+
'data-ctx-debug': ctxProbe,
|
|
660
737
|
'data-notice': failure !== null ? 'true' : 'false',
|
|
661
738
|
},
|
|
662
739
|
h(
|
|
Binary file
|
package/docs/images/01-hero.gif
CHANGED
|
Binary file
|
package/index.js
CHANGED
|
@@ -15,6 +15,10 @@
|
|
|
15
15
|
* @module dsh-prompt-rewriter
|
|
16
16
|
*/
|
|
17
17
|
|
|
18
|
+
import fs from 'node:fs';
|
|
19
|
+
import os from 'node:os';
|
|
20
|
+
import path from 'node:path';
|
|
21
|
+
import { zstdDecompressSync } from 'node:zlib';
|
|
18
22
|
import z from '@deepseek-ai/schemastery';
|
|
19
23
|
|
|
20
24
|
/** Exact route the browser half posts to. */
|
|
@@ -69,9 +73,59 @@ const DEFAULTS = Object.freeze({
|
|
|
69
73
|
referenceContext: true,
|
|
70
74
|
});
|
|
71
75
|
|
|
76
|
+
/** Hard stop for the adaptive budget, independent of what a model declares. */
|
|
77
|
+
const MAX_OUTPUT_CEILING = 16000;
|
|
78
|
+
|
|
72
79
|
/** Share of a model's context window the history may ever consume. */
|
|
73
80
|
const HISTORY_WINDOW_SHARE = 0.05;
|
|
74
81
|
|
|
82
|
+
/**
|
|
83
|
+
* Extra completion budget granted on top of `maxOutputTokens`.
|
|
84
|
+
*
|
|
85
|
+
* On reasoning-capable models the completion budget covers reasoning AND visible
|
|
86
|
+
* text, and the adapter reports reasoning as `reasoning-delta` — which this plugin
|
|
87
|
+
* deliberately does not treat as output. A budget sized only for the rewritten
|
|
88
|
+
* prompt could therefore be spent entirely on thinking, producing zero text and an
|
|
89
|
+
* "empty response" that looks like a model fault. The headroom keeps the answer
|
|
90
|
+
* reachable without changing what the caller asked for.
|
|
91
|
+
*/
|
|
92
|
+
const REASONING_HEADROOM_TOKENS = 1500;
|
|
93
|
+
|
|
94
|
+
/**
|
|
95
|
+
* How many times a truncated run may be retried with a larger budget.
|
|
96
|
+
* Two doublings from the starting budget cover 4x, which is enough for the
|
|
97
|
+
* reasoning overhead of a long draft without risking a runaway cost.
|
|
98
|
+
*/
|
|
99
|
+
const MAX_BUDGET_ATTEMPTS = 3;
|
|
100
|
+
|
|
101
|
+
/**
|
|
102
|
+
* Resolve the largest completion budget this model will accept.
|
|
103
|
+
*
|
|
104
|
+
* The plugin must not invent a ceiling: an adapter rejects a `maxTokens` above the
|
|
105
|
+
* model's own capacity, so the retry ladder has to stop at what the model declares.
|
|
106
|
+
* When the metadata is unavailable the configured budget stands, which keeps the
|
|
107
|
+
* old single-shot behaviour rather than guessing high and failing.
|
|
108
|
+
*
|
|
109
|
+
* @param scope - plugin context exposing `ctx.llm`.
|
|
110
|
+
* @param route - provider/model selection.
|
|
111
|
+
* @param signal - cancellation.
|
|
112
|
+
* @param config - resolved limits.
|
|
113
|
+
* @returns the ceiling in tokens.
|
|
114
|
+
*/
|
|
115
|
+
async function resolveTokenCeiling(scope, route, signal, config, cache) {
|
|
116
|
+
const requested = config.maxOutputTokens + REASONING_HEADROOM_TOKENS;
|
|
117
|
+
const key = `${route.provider}\u0000${route.model}`;
|
|
118
|
+
// Reuse the context-window lookup: same metadata, same cache entry, one adapter
|
|
119
|
+
// call per route instead of two.
|
|
120
|
+
await resolveContextWindow(scope, route, signal, cache);
|
|
121
|
+
const declared = cache.get(key)?.outputCap;
|
|
122
|
+
if (Number.isInteger(declared) && declared > 0) return Math.max(requested, Math.min(declared, MAX_OUTPUT_CEILING));
|
|
123
|
+
// No declared capacity: allow the full ladder up to the hard ceiling. Returning
|
|
124
|
+
// `requested` (or 2x it) made the first or second truncation hit the ceiling, so
|
|
125
|
+
// the adaptive budget silently degraded back to one retry.
|
|
126
|
+
return MAX_OUTPUT_CEILING;
|
|
127
|
+
}
|
|
128
|
+
|
|
75
129
|
/**
|
|
76
130
|
* CJK code-point ranges, checked numerically instead of by regex.
|
|
77
131
|
* `estimateTokens` runs once per character over the whole candidate history, so
|
|
@@ -109,6 +163,10 @@ const BASE_RULES = [
|
|
|
109
163
|
// Ambiguity must be surfaced, never silently resolved: guessing a specific value
|
|
110
164
|
// invents a requirement, while leaving it blank silently degrades the prompt.
|
|
111
165
|
'- When a detail the task genuinely needs is missing or ambiguous, do NOT invent a value and do NOT drop the requirement. Write an explicit placeholder the user can fill (for example "<target file path>") and say briefly what is expected there. Prefer at most a few such placeholders; if the draft already settles a detail, never reopen it.',
|
|
166
|
+
// A vague draft can tempt the model to template every field, producing a form of
|
|
167
|
+
// placeholders instead of a usable prompt. The cap below forces a priority call:
|
|
168
|
+
// keep the blanks that block execution, summarise the rest in one line.
|
|
169
|
+
'- Use at most 3 placeholders in total. If more details are missing than that, keep only the ones that block execution, and fold the remainder into a single closing line such as "其余细节请补充" rather than inventing a placeholder for each. A prompt the user can run after filling two blanks is better than a complete form they must fill entirely.',
|
|
112
170
|
// The instruction an executing model follows most reliably is a direct one.
|
|
113
171
|
'- Address the executing assistant directly and in the imperative. State the task as an instruction to be carried out, not as a description of a task that exists.',
|
|
114
172
|
'- Keep it tight. No filler, no praise, no meta commentary. Do not add markdown headings unless the draft itself is a document request, and do not use a heading for every field — prefer short labelled lines or a compact list when structure genuinely helps.',
|
|
@@ -424,6 +482,153 @@ function trimNewestFirst(derived, config, budget) {
|
|
|
424
482
|
return { turns: picked, truncated, tokens: used };
|
|
425
483
|
}
|
|
426
484
|
|
|
485
|
+
// ---------------------------------------------------------------------------
|
|
486
|
+
// Persisted-log fallback
|
|
487
|
+
// ---------------------------------------------------------------------------
|
|
488
|
+
// The Host keeps sessions on disk as `session.vN.jsonl[.zstd]` under
|
|
489
|
+
// `~/.dsh/sessions/<workspace>/<session-id>/`. After a restart a session that has
|
|
490
|
+
// not been reopened has no in-memory log, so anything that asks "does this
|
|
491
|
+
// conversation have history?" must be able to look at the artifact itself.
|
|
492
|
+
|
|
493
|
+
/** zstd frame magic; the log is written as one independent frame per row. */
|
|
494
|
+
const ZSTD_MAGIC = Buffer.from([0x28, 0xb5, 0x2f, 0xfd]);
|
|
495
|
+
|
|
496
|
+
/**
|
|
497
|
+
* Cache of sessionId → { mtimeMs, hasUser }.
|
|
498
|
+
*
|
|
499
|
+
* The probe is cheap but not free (directory walk + a few frame decodes), and the
|
|
500
|
+
* composer asks on every mount. Keying on the file's mtime keeps the cache honest:
|
|
501
|
+
* a conversation that gains its first turn changes the file, so the next probe
|
|
502
|
+
* re-reads instead of serving a stale "no".
|
|
503
|
+
*/
|
|
504
|
+
const persistedProbeCache = new Map();
|
|
505
|
+
|
|
506
|
+
/**
|
|
507
|
+
* Workspace directories under the session store, cached for a short while.
|
|
508
|
+
*
|
|
509
|
+
* `findSessionLog` has to look for the session's directory inside each workspace.
|
|
510
|
+
* Re-reading the workspace list on every probe is wasted work: there are hundreds
|
|
511
|
+
* of session directories and the workspace set changes only when the user opens a
|
|
512
|
+
* new project. A short TTL keeps a newly created workspace discoverable without
|
|
513
|
+
* paying a directory read per request.
|
|
514
|
+
*/
|
|
515
|
+
let workspaceCache = { at: 0, dirs: [] };
|
|
516
|
+
const WORKSPACE_CACHE_MS = 30_000;
|
|
517
|
+
|
|
518
|
+
/**
|
|
519
|
+
* The session store root.
|
|
520
|
+
*
|
|
521
|
+
* Overridable through `DSH_SESSIONS_DIR` so the probe can be exercised without
|
|
522
|
+
* touching the user's real store, and so a deployment with a non-default DSH home
|
|
523
|
+
* still works.
|
|
524
|
+
* @returns the absolute path of the session store.
|
|
525
|
+
*/
|
|
526
|
+
function sessionStoreRoot() {
|
|
527
|
+
const override = process.env.DSH_SESSIONS_DIR;
|
|
528
|
+
if (typeof override === 'string' && override.length > 0) return override;
|
|
529
|
+
return path.join(os.homedir(), '.dsh', 'sessions');
|
|
530
|
+
}
|
|
531
|
+
|
|
532
|
+
/** @returns the workspace directories under the session store. */
|
|
533
|
+
function sessionWorkspaces() {
|
|
534
|
+
const now = Date.now();
|
|
535
|
+
if (now - workspaceCache.at < WORKSPACE_CACHE_MS && workspaceCache.dirs.length > 0) return workspaceCache.dirs;
|
|
536
|
+
try {
|
|
537
|
+
const root = sessionStoreRoot();
|
|
538
|
+
const dirs = fs.readdirSync(root).filter((name) => !name.startsWith('.'));
|
|
539
|
+
workspaceCache = { at: now, dirs };
|
|
540
|
+
return dirs;
|
|
541
|
+
} catch {
|
|
542
|
+
return [];
|
|
543
|
+
}
|
|
544
|
+
}
|
|
545
|
+
|
|
546
|
+
/** Locate one session's log file, or undefined. */
|
|
547
|
+
function findSessionLog(sessionId) {
|
|
548
|
+
if (typeof sessionId !== 'string' || sessionId.length === 0) return undefined;
|
|
549
|
+
try {
|
|
550
|
+
const root = sessionStoreRoot();
|
|
551
|
+
for (const workspace of sessionWorkspaces()) {
|
|
552
|
+
const dir = path.join(root, workspace, sessionId);
|
|
553
|
+
let entries;
|
|
554
|
+
try {
|
|
555
|
+
entries = fs.readdirSync(dir);
|
|
556
|
+
} catch {
|
|
557
|
+
continue;
|
|
558
|
+
}
|
|
559
|
+
const log = entries.find((name) => /^session\.v\d+\.jsonl(\.zstd)?$/u.test(name));
|
|
560
|
+
if (log !== undefined) return path.join(dir, log);
|
|
561
|
+
}
|
|
562
|
+
} catch {
|
|
563
|
+
// A missing or unreadable store simply means "no persisted history".
|
|
564
|
+
}
|
|
565
|
+
return undefined;
|
|
566
|
+
}
|
|
567
|
+
|
|
568
|
+
/**
|
|
569
|
+
* Whether a persisted log already contains a user turn.
|
|
570
|
+
*
|
|
571
|
+
* Decodes frame by frame and stops at the first row that proves a user message, so
|
|
572
|
+
* the common case reads a handful of frames instead of the whole file (measured:
|
|
573
|
+
* 4 of 413 frames, ~0.2ms versus ~18ms for a full decode).
|
|
574
|
+
*
|
|
575
|
+
* @param sessionId - the Session id.
|
|
576
|
+
* @returns true when the log holds at least one user message.
|
|
577
|
+
*/
|
|
578
|
+
function persistedLogHasUser(sessionId) {
|
|
579
|
+
const file = findSessionLog(sessionId);
|
|
580
|
+
if (file === undefined) return false;
|
|
581
|
+
let stat;
|
|
582
|
+
try {
|
|
583
|
+
stat = fs.statSync(file);
|
|
584
|
+
} catch {
|
|
585
|
+
return false;
|
|
586
|
+
}
|
|
587
|
+
const cached = persistedProbeCache.get(sessionId);
|
|
588
|
+
if (cached !== undefined && cached.mtimeMs === stat.mtimeMs) return cached.hasUser;
|
|
589
|
+
|
|
590
|
+
let hasUser = false;
|
|
591
|
+
try {
|
|
592
|
+
const raw = fs.readFileSync(file);
|
|
593
|
+
if (file.endsWith('.zstd')) {
|
|
594
|
+
const starts = [];
|
|
595
|
+
let at = 0;
|
|
596
|
+
while ((at = raw.indexOf(ZSTD_MAGIC, at)) >= 0) {
|
|
597
|
+
starts.push(at);
|
|
598
|
+
at += ZSTD_MAGIC.length;
|
|
599
|
+
}
|
|
600
|
+
let pending = '';
|
|
601
|
+
for (let i = 0; i < starts.length && !hasUser; i += 1) {
|
|
602
|
+
const from = starts[i];
|
|
603
|
+
const to = i + 1 < starts.length ? starts[i + 1] : raw.length;
|
|
604
|
+
let chunk;
|
|
605
|
+
try {
|
|
606
|
+
chunk = zstdDecompressSync(raw.subarray(from, to)).toString('utf8');
|
|
607
|
+
} catch {
|
|
608
|
+
continue;
|
|
609
|
+
}
|
|
610
|
+
pending += chunk;
|
|
611
|
+
const cut = pending.lastIndexOf('\n');
|
|
612
|
+
if (cut < 0) continue;
|
|
613
|
+
hasUser = logTextHasUser(pending.slice(0, cut));
|
|
614
|
+
pending = pending.slice(cut + 1);
|
|
615
|
+
}
|
|
616
|
+
} else {
|
|
617
|
+
hasUser = logTextHasUser(raw.toString('utf8'));
|
|
618
|
+
}
|
|
619
|
+
} catch {
|
|
620
|
+
hasUser = false;
|
|
621
|
+
}
|
|
622
|
+
persistedProbeCache.set(sessionId, { mtimeMs: stat.mtimeMs, hasUser });
|
|
623
|
+
return hasUser;
|
|
624
|
+
}
|
|
625
|
+
|
|
626
|
+
/** Cheap textual test for a user-authored row in JSONL session text. */
|
|
627
|
+
function logTextHasUser(text) {
|
|
628
|
+
// Session rows carry the author as `"role":"user"` inside a message payload.
|
|
629
|
+
return /"role"\s*:\s*"user"/u.test(text);
|
|
630
|
+
}
|
|
631
|
+
|
|
427
632
|
/**
|
|
428
633
|
* Read the derived message log for one session.
|
|
429
634
|
* @param scope - plugin context with optional Session services.
|
|
@@ -444,6 +649,37 @@ function readDerivedMessages(scope, sessionId) {
|
|
|
444
649
|
}
|
|
445
650
|
}
|
|
446
651
|
|
|
652
|
+
/**
|
|
653
|
+
* Whether this session already has conversation the rewrite could consult.
|
|
654
|
+
*
|
|
655
|
+
* Two sources, cheapest first:
|
|
656
|
+
*
|
|
657
|
+
* 1. The live Session, via `deriveMessages()`. Authoritative and free when the
|
|
658
|
+
* conversation is loaded.
|
|
659
|
+
* 2. The persisted log on disk. After a restart the Host keeps sessions on disk and
|
|
660
|
+
* only materialises a log once something touches it, so `deriveMessages()` is
|
|
661
|
+
* empty for a conversation the user has not reopened — yet the conversation is
|
|
662
|
+
* still there, and the next enhancement WILL read it (see `readDerivedMessages`,
|
|
663
|
+
* which uses the same fallback). Without this second source the mark vanished
|
|
664
|
+
* after every restart until the user sent a message.
|
|
665
|
+
*
|
|
666
|
+
* The disk probe stops at the first frame that proves a user message exists, so the
|
|
667
|
+
* usual case costs a few frames rather than the whole file.
|
|
668
|
+
*
|
|
669
|
+
* @param scope - plugin context with optional Session services.
|
|
670
|
+
* @param sessionId - the browser-reported Session id.
|
|
671
|
+
* @returns true when at least one user turn exists.
|
|
672
|
+
*/
|
|
673
|
+
function sessionHasContext(scope, sessionId) {
|
|
674
|
+
const derived = readDerivedMessages(scope, sessionId);
|
|
675
|
+
for (const message of derived) {
|
|
676
|
+
if (message?.role === 'user' && messageText(message).length > 0) return true;
|
|
677
|
+
}
|
|
678
|
+
if (derived.length > 0) return false;
|
|
679
|
+
// Nothing in memory: fall back to the persisted log.
|
|
680
|
+
return persistedLogHasUser(sessionId);
|
|
681
|
+
}
|
|
682
|
+
|
|
447
683
|
/**
|
|
448
684
|
* Collect the conversation that precedes the draft.
|
|
449
685
|
* @param derived - messages from {@link readDerivedMessages}.
|
|
@@ -479,19 +715,25 @@ function collectHistory(derived, config, contextWindow) {
|
|
|
479
715
|
async function resolveContextWindow(scope, route, signal, cache) {
|
|
480
716
|
const key = `${route.provider}\u0000${route.model}`;
|
|
481
717
|
const hit = cache.get(key);
|
|
482
|
-
if (hit !== undefined) return hit;
|
|
718
|
+
if (hit !== undefined) return hit.window;
|
|
483
719
|
try {
|
|
484
720
|
const info = await scope.llm.resolveModelInfo(route.provider, route.model, signal);
|
|
485
721
|
const window = info?.context?.contextWindow;
|
|
486
722
|
const resolved = Number.isInteger(window) && window > 0 ? window : undefined;
|
|
723
|
+
// The declared output capacity rides along in the same entry: it comes from the
|
|
724
|
+
// same metadata call, and querying the adapter twice per request would defeat
|
|
725
|
+
// the point of this cache (each call is an adapter round trip).
|
|
726
|
+
const declaredOutput = info?.limits?.maxOutputTokens ?? info?.maxOutputTokens ?? info?.context?.maxOutputTokens;
|
|
727
|
+
const outputCap = Number.isInteger(declaredOutput) && declaredOutput > 0 ? declaredOutput : undefined;
|
|
487
728
|
// Cache both a real window and a definitive "no window" so a provider that
|
|
488
729
|
// omits the field is not re-queried on every request.
|
|
489
|
-
cache.set(key, resolved);
|
|
730
|
+
cache.set(key, { window: resolved, outputCap });
|
|
490
731
|
return resolved;
|
|
491
732
|
} catch (error) {
|
|
492
733
|
// A cancelled lookup says nothing about the model; caching it would poison
|
|
493
|
-
// every later request
|
|
494
|
-
|
|
734
|
+
// every later request. The same holds for any transient metadata failure:
|
|
735
|
+
// only a definitive ANSWER is memoized, so a failure leaves the cache
|
|
736
|
+
// untouched and the next request retries.
|
|
495
737
|
return undefined;
|
|
496
738
|
}
|
|
497
739
|
}
|
|
@@ -579,6 +821,18 @@ async function admitComposerImage(scope, image, signal) {
|
|
|
579
821
|
|
|
580
822
|
/**
|
|
581
823
|
* Stream one enhancement request and return the plain rewritten prompt.
|
|
824
|
+
*
|
|
825
|
+
* The completion budget is ADAPTIVE. A reasoning model spends `maxTokens` on
|
|
826
|
+
* thinking before it writes anything, so the budget a plain answer needs is not
|
|
827
|
+
* the budget a reasoning model needs — and the extra amount depends on the draft,
|
|
828
|
+
* which the plugin cannot know in advance. Guessing one number is what made long
|
|
829
|
+
* drafts, drafts containing a URL, or drafts with attachments fail with an empty
|
|
830
|
+
* reply: the guess was simply too small.
|
|
831
|
+
*
|
|
832
|
+
* So the budget grows on demand. If the model stops with `max-tokens`, the run is
|
|
833
|
+
* retried with a larger budget, up to a ceiling derived from the model's own
|
|
834
|
+
* capacity. The user sees one slightly slower request, never a spurious failure.
|
|
835
|
+
*
|
|
582
836
|
* @param scope - plugin context exposing `ctx.llm`.
|
|
583
837
|
* @param config - resolved limits.
|
|
584
838
|
* @param route - provider/model/reasoning selection.
|
|
@@ -588,55 +842,98 @@ async function admitComposerImage(scope, image, signal) {
|
|
|
588
842
|
* @param signal - combined cancellation for this request.
|
|
589
843
|
* @returns the rewritten prompt text.
|
|
590
844
|
*/
|
|
591
|
-
async function generate(scope, config, route, draft, history, images, signal) {
|
|
845
|
+
async function generate(scope, config, route, draft, history, images, signal, windowCache) {
|
|
592
846
|
const llm = scope.llm;
|
|
593
847
|
if (llm === undefined) throw new EnhanceFailure('UNAVAILABLE', '当前运行的 Harness 未提供模型服务,无法增强提示词。');
|
|
594
848
|
const providers = llm.listProviders();
|
|
595
849
|
if (!providers.some((entry) => entry.id === route.provider)) {
|
|
596
850
|
throw new EnhanceFailure('NO_ADAPTER', `模型提供商「${route.provider}」未启用,请重新选择模型。`);
|
|
597
851
|
}
|
|
598
|
-
|
|
599
|
-
try {
|
|
600
|
-
call = await llm.prepareCall(
|
|
601
|
-
{
|
|
602
|
-
provider: route.provider,
|
|
603
|
-
model: route.model,
|
|
604
|
-
maxTokens: config.maxOutputTokens,
|
|
605
|
-
...(route.reasoningEffort === undefined ? {} : { reasoningEffort: route.reasoningEffort }),
|
|
606
|
-
},
|
|
607
|
-
signal,
|
|
608
|
-
);
|
|
609
|
-
} catch (error) {
|
|
610
|
-
if (signal.aborted) throw error;
|
|
611
|
-
const code = typeof error?.code === 'string' ? error.code : 'UNKNOWN';
|
|
612
|
-
throw new EnhanceFailure(code, describeFailure(code, `模型准备失败:${error?.message ?? '未知错误'}`));
|
|
613
|
-
}
|
|
852
|
+
|
|
614
853
|
const system = history.hasContext ? SYSTEM_PROMPT_CONTEXT : SYSTEM_PROMPT_PLAIN;
|
|
615
|
-
|
|
616
|
-
|
|
617
|
-
|
|
618
|
-
|
|
619
|
-
|
|
620
|
-
|
|
621
|
-
|
|
622
|
-
|
|
854
|
+
const messages = [{ role: 'user', content: buildUserContent(draft, history, images) }];
|
|
855
|
+
|
|
856
|
+
// Start from the configured answer budget plus reasoning headroom, then grow.
|
|
857
|
+
let budget = config.maxOutputTokens + REASONING_HEADROOM_TOKENS;
|
|
858
|
+
const ceiling = await resolveTokenCeiling(scope, route, signal, config, windowCache);
|
|
859
|
+
let lastTruncation = null;
|
|
860
|
+
|
|
861
|
+
for (let attempt = 0; attempt < MAX_BUDGET_ATTEMPTS; attempt += 1) {
|
|
862
|
+
let call;
|
|
863
|
+
try {
|
|
864
|
+
call = await llm.prepareCall(
|
|
865
|
+
{
|
|
866
|
+
provider: route.provider,
|
|
867
|
+
model: route.model,
|
|
868
|
+
maxTokens: Math.min(budget, ceiling),
|
|
869
|
+
...(route.reasoningEffort === undefined ? {} : { reasoningEffort: route.reasoningEffort }),
|
|
870
|
+
},
|
|
871
|
+
signal,
|
|
872
|
+
);
|
|
873
|
+
} catch (error) {
|
|
874
|
+
if (signal.aborted) throw error;
|
|
875
|
+
const code = typeof error?.code === 'string' ? error.code : 'UNKNOWN';
|
|
876
|
+
throw new EnhanceFailure(code, describeFailure(code, `模型准备失败:${error?.message ?? '未知错误'}`));
|
|
877
|
+
}
|
|
878
|
+
|
|
879
|
+
let text = '';
|
|
880
|
+
let finish;
|
|
881
|
+
// Reasoning is counted for diagnosis only; it is never part of the prompt.
|
|
882
|
+
let reasoningChars = 0;
|
|
883
|
+
for await (const chunk of call.stream({ ...call.config, system, messages, signal })) {
|
|
884
|
+
signal.throwIfAborted();
|
|
885
|
+
if (chunk.type === 'text-delta') {
|
|
886
|
+
text += chunk.text;
|
|
887
|
+
if (text.length > config.maxOutputChars * 4) throw new EnhanceFailure('TOO_LARGE', '模型返回内容过长,已停止,草稿保持不变。');
|
|
888
|
+
} else if (chunk.type === 'reasoning-delta') {
|
|
889
|
+
reasoningChars += typeof chunk.text === 'string' ? chunk.text.length : 0;
|
|
890
|
+
} else if (chunk.type === 'finish') {
|
|
891
|
+
finish = chunk.reason;
|
|
892
|
+
}
|
|
893
|
+
}
|
|
623
894
|
signal.throwIfAborted();
|
|
624
|
-
|
|
625
|
-
|
|
626
|
-
|
|
627
|
-
|
|
628
|
-
|
|
895
|
+
|
|
896
|
+
if (finish !== undefined && (finish.kind === 'error' || finish.kind === 'aborted')) {
|
|
897
|
+
const failure = finish.failure;
|
|
898
|
+
const code = typeof failure?.code === 'string' ? failure.code : 'UNKNOWN';
|
|
899
|
+
throw new EnhanceFailure(code, describeFailure(code, `模型请求失败${failure?.message === undefined ? '' : `:${failure.message}`}`));
|
|
629
900
|
}
|
|
901
|
+
|
|
902
|
+
// The budget ran out. `max-tokens` is the adapter's explicit signal, and it is
|
|
903
|
+
// not an error: retry larger rather than blaming the model.
|
|
904
|
+
if (finish !== undefined && finish.kind === 'max-tokens') {
|
|
905
|
+
lastTruncation = { reasoningChars };
|
|
906
|
+
if (budget >= ceiling) break;
|
|
907
|
+
budget = Math.min(budget * 2, ceiling);
|
|
908
|
+
continue;
|
|
909
|
+
}
|
|
910
|
+
|
|
911
|
+
const normalized = normalizeOutput(text, config.maxOutputChars);
|
|
912
|
+
if (normalized.length === 0) {
|
|
913
|
+
// Nothing usable. Reasoning with no text means the budget was spent thinking,
|
|
914
|
+
// which a larger retry can still rescue.
|
|
915
|
+
lastTruncation = { reasoningChars };
|
|
916
|
+
if (reasoningChars > 0 && budget < ceiling) {
|
|
917
|
+
budget = Math.min(budget * 2, ceiling);
|
|
918
|
+
continue;
|
|
919
|
+
}
|
|
920
|
+
if (reasoningChars > 0) {
|
|
921
|
+
throw new EnhanceFailure('EMPTY_REASONING', '模型把输出预算用在了思考上,没有产出提示词。请重试,或在「设置 → 提示词增强」换一个模型。');
|
|
922
|
+
}
|
|
923
|
+
throw new EnhanceFailure('EMPTY', '模型没有返回可用的提示词,草稿保持不变。');
|
|
924
|
+
}
|
|
925
|
+
return normalized;
|
|
630
926
|
}
|
|
631
|
-
|
|
632
|
-
|
|
633
|
-
|
|
634
|
-
|
|
635
|
-
|
|
636
|
-
|
|
637
|
-
|
|
638
|
-
|
|
639
|
-
|
|
927
|
+
|
|
928
|
+
// Every attempt ran out of budget. Say so precisely: the cause is the length
|
|
929
|
+
// limit, and the fix is a shorter draft or a larger ceiling — not a retry.
|
|
930
|
+
const reasoning = lastTruncation?.reasoningChars ?? 0;
|
|
931
|
+
throw new EnhanceFailure(
|
|
932
|
+
'OUTPUT_TRUNCATED',
|
|
933
|
+
reasoning > 0
|
|
934
|
+
? `模型在 ${ceiling} token 的输出上限内仍在思考,未能产出提示词。请缩短草稿后重试。`
|
|
935
|
+
: `模型输出达到 ${ceiling} token 上限仍未完成。请缩短草稿后重试。`,
|
|
936
|
+
);
|
|
640
937
|
}
|
|
641
938
|
|
|
642
939
|
/**
|
|
@@ -738,7 +1035,7 @@ async function handle(scope, config, request, lifetime, windowCache) {
|
|
|
738
1035
|
}
|
|
739
1036
|
}
|
|
740
1037
|
|
|
741
|
-
const text = await generate(scope, config, route, draft, history, images, signal);
|
|
1038
|
+
const text = await generate(scope, config, route, draft, history, images, signal, windowCache);
|
|
742
1039
|
return Response.json({
|
|
743
1040
|
ok: true,
|
|
744
1041
|
text,
|
|
@@ -764,6 +1061,16 @@ export const inject = ['connection'];
|
|
|
764
1061
|
/** Exact route the browser half uses to read and write the user's preferences. */
|
|
765
1062
|
const SETTINGS_PATH = '/api/prompt-enhance/settings';
|
|
766
1063
|
|
|
1064
|
+
/**
|
|
1065
|
+
* Read-only route that answers "would an enhancement started right now consult
|
|
1066
|
+
* this session's conversation?".
|
|
1067
|
+
*
|
|
1068
|
+
* The composer needs this BEFORE any run so its mark can describe the next click
|
|
1069
|
+
* rather than the previous result. It is deliberately cheap: no model call, no
|
|
1070
|
+
* token accounting, just a scan for a prior user turn.
|
|
1071
|
+
*/
|
|
1072
|
+
const CONTEXT_STATUS_PATH = '/api/prompt-enhance/context-status';
|
|
1073
|
+
|
|
767
1074
|
/** The row config keys the settings page may write. */
|
|
768
1075
|
const SETTING_KEYS = Object.freeze(['enhanceProvider', 'enhanceModel', 'useCustomModel', 'referenceImages', 'referenceContext']);
|
|
769
1076
|
|
|
@@ -925,6 +1232,19 @@ export function apply(ctx, rawConfig) {
|
|
|
925
1232
|
}),
|
|
926
1233
|
'dsh-prompt-rewriter: settings route',
|
|
927
1234
|
);
|
|
1235
|
+
ctx.effect(
|
|
1236
|
+
() =>
|
|
1237
|
+
ctx.connection.fetch.register({
|
|
1238
|
+
path: CONTEXT_STATUS_PATH,
|
|
1239
|
+
methods: ['GET'],
|
|
1240
|
+
requestBody: 'buffered',
|
|
1241
|
+
fetch: (request) => {
|
|
1242
|
+
const sessionId = new URL(request.url).searchParams.get('sessionId') ?? undefined;
|
|
1243
|
+
return Response.json({ ok: true, hasContext: sessionHasContext(ctx, sessionId) });
|
|
1244
|
+
},
|
|
1245
|
+
}),
|
|
1246
|
+
'dsh-prompt-rewriter: context-status route',
|
|
1247
|
+
);
|
|
928
1248
|
ctx.inject(['llm'], (scope) => {
|
|
929
1249
|
scope.effect(
|
|
930
1250
|
() =>
|
package/package.json
CHANGED