@tychenjiajun/pi-voice 0.7.0 → 0.8.1
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.md +49 -1
- package/assets/demo.gif +0 -0
- package/assets/demo.mp4 +0 -0
- package/assets/preview.png +0 -0
- package/assets/preview.svg +47 -0
- package/assets/social-og.png +0 -0
- package/assets/social.svg +37 -0
- package/catalog/catalog.json +1501 -0
- package/catalog/recommendations.json +67 -27
- package/models/README.md +25 -0
- package/models/silero-vad-v6.2-F32.gguf +0 -0
- package/package.json +21 -10
- package/src/audio-constants.ts +2 -0
- package/src/audio.ts +2 -5
- package/src/catalog.ts +6 -2
- package/src/chinese.ts +17 -6
- package/src/chunking.ts +319 -0
- package/src/dictation-controller.ts +61 -18
- package/src/file-audio.ts +2 -2
- package/src/file-transcription.ts +6 -3
- package/src/language-detection-policy.ts +127 -0
- package/src/languages.ts +4 -3
- package/src/model-activation.ts +50 -4
- package/src/model-cells.ts +28 -6
- package/src/model-picker.ts +29 -12
- package/src/model-selection-controller.ts +14 -9
- package/src/models.ts +15 -1
- package/src/onboarding.ts +13 -1
- package/src/pcm-chunker.ts +14 -4
- package/src/recommendation-picker.ts +9 -7
- package/src/recommendations.ts +4 -2
- package/src/runtime.ts +9 -1
- package/src/settings-menu.ts +40 -9
- package/src/settings.ts +35 -3
- package/src/transcription-service.ts +205 -37
- package/src/transcription.ts +72 -24
- package/src/try-it.ts +11 -2
- package/src/vad.ts +301 -0
- package/src/catalog.generated.ts +0 -1305
package/README.md
CHANGED
|
@@ -4,6 +4,14 @@ Speech-to-text for Pi — on-device model or OpenAI-compatible remote ASR, with
|
|
|
4
4
|
|
|
5
5
|
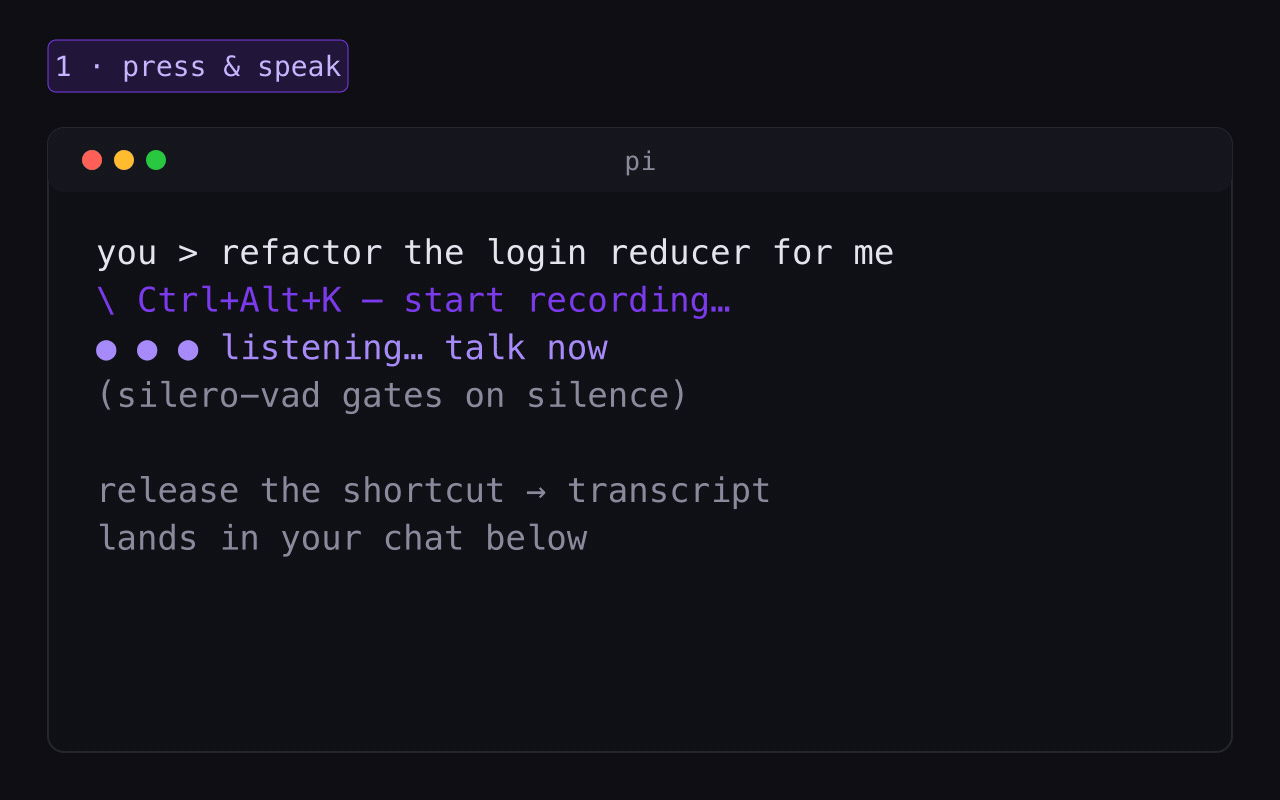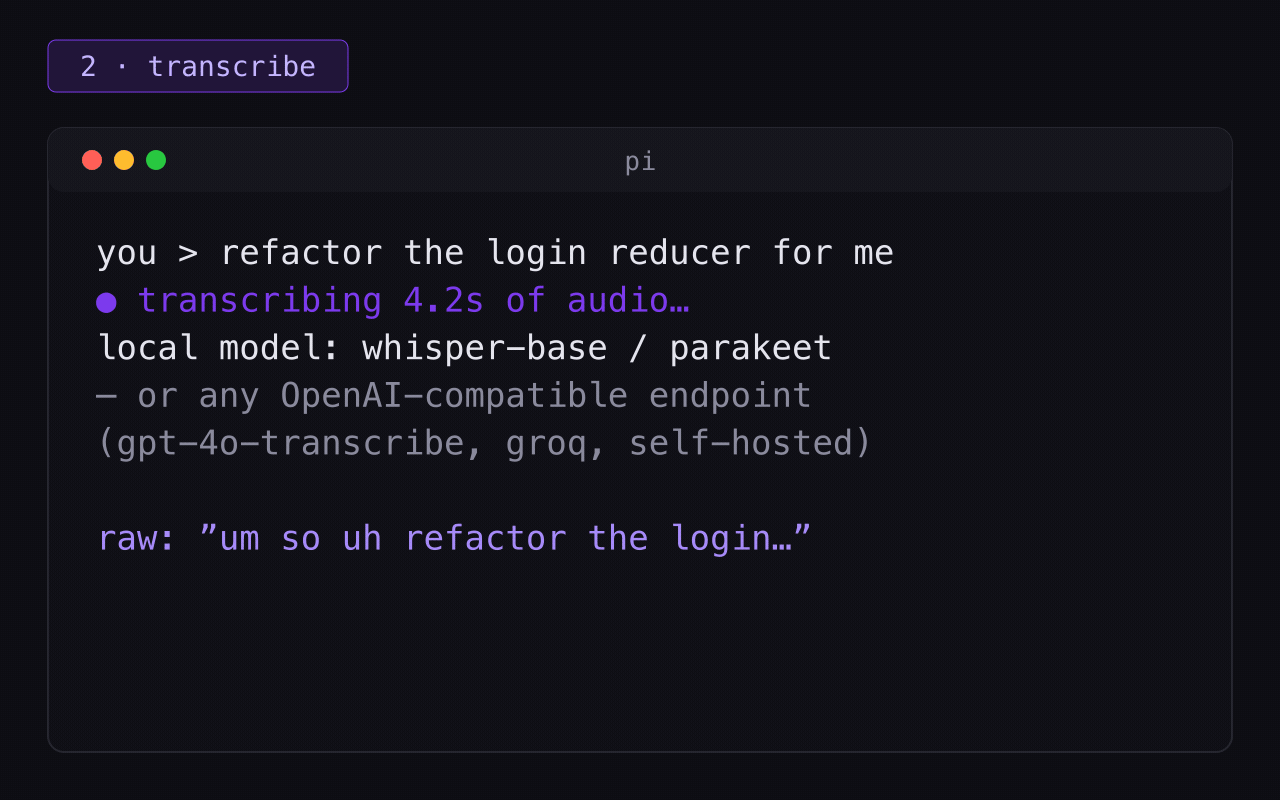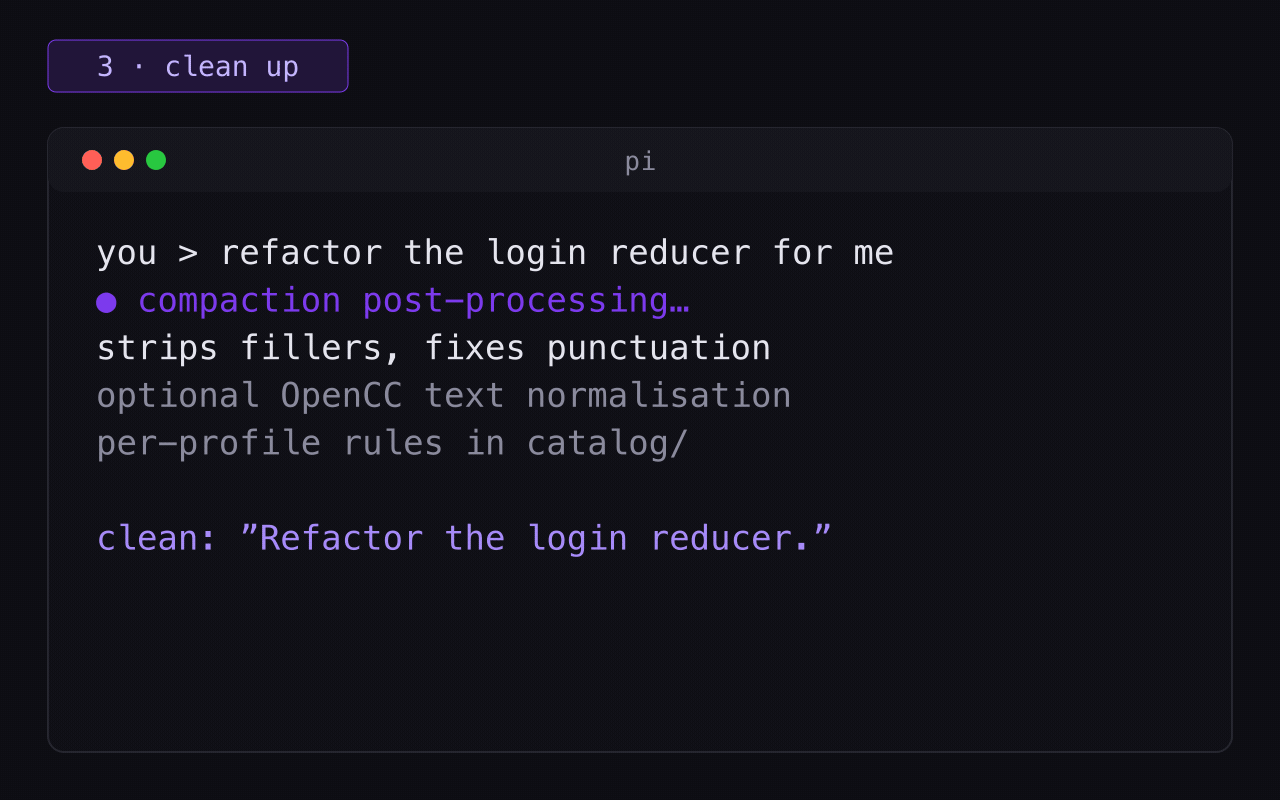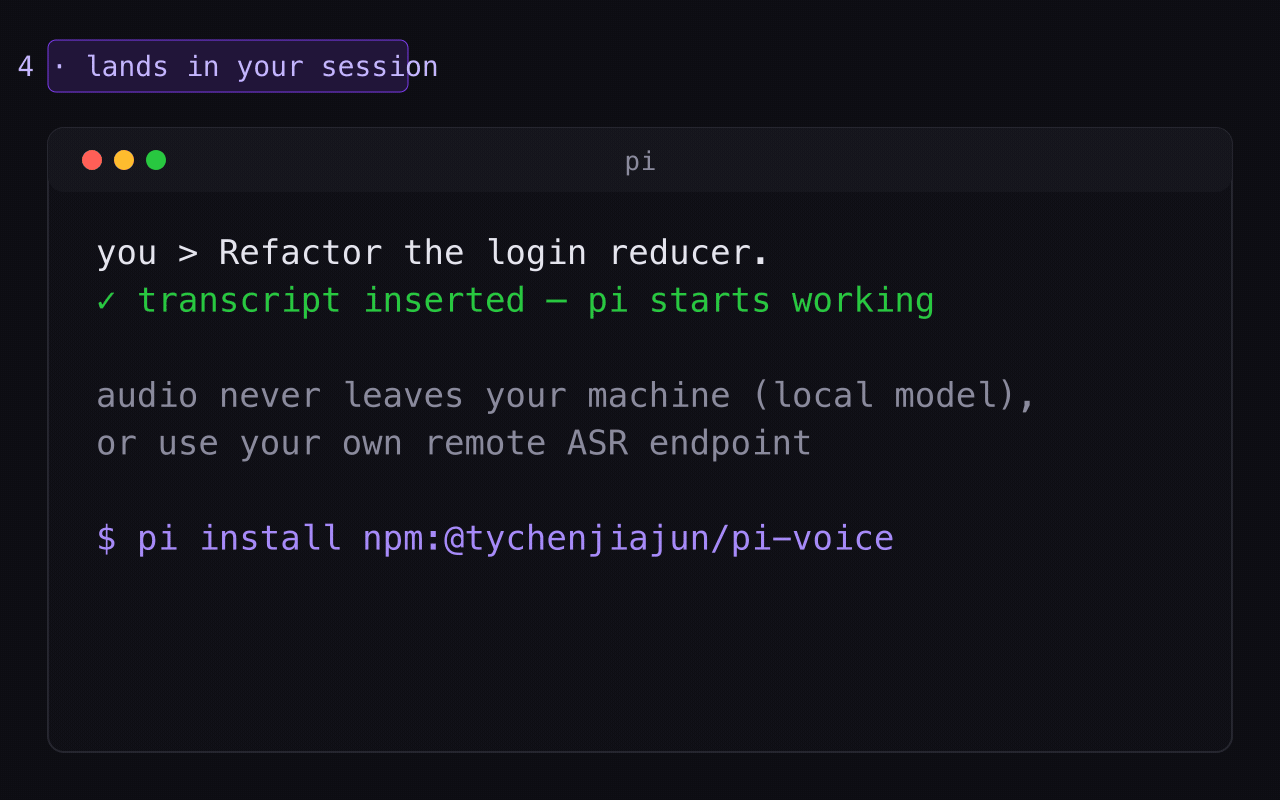
Press a keyboard shortcut, talk, and the resulting transcript will be put directly into your chat.
|
|
6
6
|
|
|
7
|
+
|
|
8
|
+
|
|
9
|
+
|
|
10
|
+
|
|
11
|
+
[](https://pi.dev/docs/latest/packages) [](https://www.npmjs.com/package/@tychenjiajun/pi-voice) [](LICENSE)
|
|
12
|
+
|
|
13
|
+
Browse more Pi packages in the [pi.dev packages gallery](https://pi.dev/packages/@tychenjiajun/pi-voice) and read the [Pi packages documentation](https://pi.dev/docs/latest/packages).
|
|
14
|
+
|
|
7
15
|
> **Fork notice.** `@tychenjiajun/pi-voice` is a fork of [`@earendil-works/pi-voice`](https://github.com/earendil-works/pi-voice) that adds a remote ASR backend (any OpenAI-compatible `input_audio` chat-completions endpoint) in an exclusive local-only or remote-only setup, plus compaction-style post-processing that refines a transcript with Pi's own model. It is published independently under a personal npm scope. See the [changelog](#changelog) for what changed.
|
|
8
16
|
|
|
9
17
|
## Install
|
|
@@ -91,7 +99,7 @@ pi install npm:@tychenjiajun/pi-voice
|
|
|
91
99
|
|
|
92
100
|
## File transcription and FFmpeg
|
|
93
101
|
|
|
94
|
-
The agent can call `transcribe_file` for local audio or video files. Decoded audio is limited to
|
|
102
|
+
The agent can call `transcribe_file` for local audio or video files. Decoded audio is limited to 512 MiB (about 2.3 hours). File decoding requires the `ffmpeg` executable. Install FFmpeg with your system package manager if you don't already have it installed
|
|
95
103
|
|
|
96
104
|
```bash
|
|
97
105
|
# macOS with Homebrew
|
|
@@ -114,8 +122,48 @@ The legacy `PI_TRANSCRIBE_FFMPEG_PATH` variable remains supported when `PI_VOICE
|
|
|
114
122
|
|
|
115
123
|
When FFmpeg is unavailable, `transcribe_file` reports platform-specific guidance to the agent. The agent should ask before running a package-manager command. Model setup is still explicit: run `/voice-settings` once in the interactive TUI to choose a mode and, in local mode, confirm the download of a local model.
|
|
116
124
|
|
|
125
|
+
## FAQ
|
|
126
|
+
|
|
127
|
+
### What models does it support?
|
|
128
|
+
|
|
129
|
+
Local mode downloads GGUF ASR models from a built-in catalog — Whisper (e.g. `whisper-medium`), Parakeet, Canary, Nemotron, Qwen3-ASR and more, picked via a fuzzy-searchable `/voice-settings` model picker. Remote mode works with **any** endpoint that speaks the OpenAI chat-completions `input_audio` dialect (OpenAI, Groq, self-hosted servers, …).
|
|
130
|
+
|
|
131
|
+
### Does audio leave my machine?
|
|
132
|
+
|
|
133
|
+
Not unless you configure remote mode. With a local model, recording and transcription happen entirely on-device. If you switch **Transcription backend** to **Remote ASR**, the 16 kHz mono WAV clip is sent to *your* endpoint — the API key is read from an env var you name and is never stored in settings.
|
|
134
|
+
|
|
135
|
+
### How is this different from `@earendil-works/pi-voice`?
|
|
136
|
+
|
|
137
|
+
This fork adds a remote ASR backend (exclusive local-only or remote-only setup) and compaction-style post-processing that refines transcripts with Pi's own model — stripping filler words, fixing punctuation and capitalisation. See the [changelog](#changelog).
|
|
138
|
+
|
|
139
|
+
### Do I need FFmpeg?
|
|
140
|
+
|
|
141
|
+
Only for the `transcribe_file` tool (transcribing existing audio/video files). Microphone dictation works without it. Install hints for macOS, Debian/Ubuntu and Windows are in [File transcription and FFmpeg](#file-transcription-and-ffmpeg).
|
|
142
|
+
|
|
117
143
|
## Changelog
|
|
118
144
|
|
|
145
|
+
### 0.8.0
|
|
146
|
+
|
|
147
|
+
**Added — Upstream sync: voice activity detection, long-audio chunking, and language detection**
|
|
148
|
+
|
|
149
|
+
- Synced with upstream `@earendil-works/pi-voice` 0.2.0. The remote ASR backend and compaction-style post-processing from this fork are unchanged.
|
|
150
|
+
- **Voice activity detection** using a bundled Silero model (`models/silero-vad-v6.2-F32.gguf`): silence and noise are filtered from dictation so only speech is transcribed. The hidden `voiceActivityDetection` setting in `settings.json` turns it off (default `true`).
|
|
151
|
+
- **Long-audio chunking**: clips that do not fit one model window are cut at pauses before batch transcription, so non-Whisper models no longer truncate long recordings. The hidden `longformChunking` setting turns it off (default `true`); models that handle long audio natively (Whisper, Parakeet Ultra) and streaming models skip it.
|
|
152
|
+
- **Automatic language detection**: when a multilingual model has no native detection and Auto is selected, the shared **VoxLingua107** detector picks the language. Download it from the language picker; Auto is only offered when the model supports at least two of your preferred languages and the detector can identify them.
|
|
153
|
+
- **Chinese output** now keys off the transcript text (Han characters, no kana) instead of language detection, so remote and short-clip transcripts convert reliably.
|
|
154
|
+
- **New catalog models**: Parakeet Ultra and Granite Speech 5.0 470M TurboCTC.
|
|
155
|
+
- Decoded audio for `transcribe_file` is raised to 512 MiB (about 2.3 hours).
|
|
156
|
+
|
|
157
|
+
**Fixed**
|
|
158
|
+
|
|
159
|
+
- Whisper-family out-of-memory failures during transcription now retry on the CPU device instead of failing the take.
|
|
160
|
+
|
|
161
|
+
**Changed**
|
|
162
|
+
|
|
163
|
+
- Dependencies: `transcribe-cpp` 0.4.0 and `@handy-computer/recorder` 0.2.1.
|
|
164
|
+
- Catalog metadata is imported from `catalog/catalog.json` directly; the generated `catalog.generated.ts` copy is gone.
|
|
165
|
+
- Built against `@earendil-works/pi-coding-agent` 1.3.0.
|
|
166
|
+
|
|
119
167
|
### 0.7.0
|
|
120
168
|
|
|
121
169
|
**Added — Searchable post-processing model picker**
|
package/assets/demo.gif
ADDED
|
Binary file
|
package/assets/demo.mp4
ADDED
|
Binary file
|
|
Binary file
|
|
@@ -0,0 +1,47 @@
|
|
|
1
|
+
<svg xmlns="http://www.w3.org/2000/svg" width="1600" height="1000" viewBox="0 0 1600 1000" role="img" aria-label="@tychenjiajun/pi-voice promo card">
|
|
2
|
+
<defs>
|
|
3
|
+
<linearGradient id="accent" x1="0" y1="0" x2="1" y2="0">
|
|
4
|
+
<stop offset="0" stop-color="#7c3aed"/>
|
|
5
|
+
<stop offset="1" stop-color="#a78bfa"/>
|
|
6
|
+
</linearGradient>
|
|
7
|
+
<radialGradient id="glow" cx="0.5" cy="1" r="0.9">
|
|
8
|
+
<stop offset="0" stop-color="#7c3aed" stop-opacity="0.30"/>
|
|
9
|
+
<stop offset="0.6" stop-color="#7c3aed" stop-opacity="0.10"/>
|
|
10
|
+
<stop offset="1" stop-color="#7c3aed" stop-opacity="0"/>
|
|
11
|
+
</radialGradient>
|
|
12
|
+
<pattern id="grid" width="50" height="50" patternUnits="userSpaceOnUse">
|
|
13
|
+
<path d="M50 0H0v50" fill="none" stroke="#ffffff" stroke-opacity="0.05" stroke-width="1"/>
|
|
14
|
+
</pattern>
|
|
15
|
+
</defs>
|
|
16
|
+
|
|
17
|
+
<rect width="1600" height="1000" fill="#0d0d12"/>
|
|
18
|
+
<rect width="1600" height="1000" fill="url(#grid)"/>
|
|
19
|
+
<rect width="1600" height="1000" fill="url(#glow)"/>
|
|
20
|
+
|
|
21
|
+
<!-- corner labels -->
|
|
22
|
+
<rect x="140" y="120" rx="8" width="300" height="56" fill="#7c3aed" fill-opacity="0.18" stroke="#7c3aed"/>
|
|
23
|
+
<text x="290" y="158" text-anchor="middle" font-family="ui-monospace, Menlo, monospace" font-size="30" fill="#c4b5fd">pi-extension</text>
|
|
24
|
+
<text x="1460" y="158" text-anchor="end" font-family="ui-monospace, Menlo, monospace" font-size="30" fill="#8b8b9e">pi.dev/packages</text>
|
|
25
|
+
|
|
26
|
+
<!-- mic glyph -->
|
|
27
|
+
<g transform="translate(800 268)">
|
|
28
|
+
<circle cx="0" cy="0" r="64" fill="#7c3aed" fill-opacity="0.18" stroke="#7c3aed" stroke-width="4"/>
|
|
29
|
+
<rect x="-16" y="-44" width="32" height="56" rx="16" fill="#a78bfa"/>
|
|
30
|
+
<path d="M-32 -2 a32 32 0 0 0 64 0" fill="none" stroke="#a78bfa" stroke-width="6" stroke-linecap="round"/>
|
|
31
|
+
<line x1="0" y1="30" x2="0" y2="52" stroke="#a78bfa" stroke-width="6" stroke-linecap="round"/>
|
|
32
|
+
</g>
|
|
33
|
+
|
|
34
|
+
<!-- name -->
|
|
35
|
+
<text x="800" y="480" text-anchor="middle" font-family="ui-monospace, Menlo, monospace" font-size="132" font-weight="700" fill="#ffffff">pi-voice</text>
|
|
36
|
+
<text x="800" y="540" text-anchor="middle" font-family="ui-monospace, Menlo, monospace" font-size="34" fill="#8b8b9e">@tychenjiajun</text>
|
|
37
|
+
|
|
38
|
+
<!-- tagline -->
|
|
39
|
+
<text x="800" y="620" text-anchor="middle" font-family="system-ui, sans-serif" font-size="44" fill="#c9c9d4">Speak — transcript lands in your chat</text>
|
|
40
|
+
|
|
41
|
+
<!-- install pill -->
|
|
42
|
+
<rect x="270" y="690" rx="14" width="1060" height="92" fill="#16161d" stroke="url(#accent)" stroke-width="3"/>
|
|
43
|
+
<text x="800" y="749" text-anchor="middle" font-family="ui-monospace, Menlo, monospace" font-size="40" fill="#a78bfa">$ pi install npm:@tychenjiajun/pi-voice</text>
|
|
44
|
+
|
|
45
|
+
<!-- accent bar -->
|
|
46
|
+
<rect x="440" y="860" width="720" height="10" rx="5" fill="url(#accent)"/>
|
|
47
|
+
</svg>
|
|
Binary file
|
|
@@ -0,0 +1,37 @@
|
|
|
1
|
+
<svg xmlns="http://www.w3.org/2000/svg" width="1200" height="630" viewBox="0 0 1200 630" role="img" aria-label="@tychenjiajun/pi-voice social card">
|
|
2
|
+
<defs>
|
|
3
|
+
<linearGradient id="accent" x1="0" y1="0" x2="1" y2="0">
|
|
4
|
+
<stop offset="0" stop-color="#7c3aed"/>
|
|
5
|
+
<stop offset="1" stop-color="#a78bfa"/>
|
|
6
|
+
</linearGradient>
|
|
7
|
+
<radialGradient id="glow" cx="0.5" cy="1" r="0.9">
|
|
8
|
+
<stop offset="0" stop-color="#7c3aed" stop-opacity="0.30"/>
|
|
9
|
+
<stop offset="0.6" stop-color="#7c3aed" stop-opacity="0.10"/>
|
|
10
|
+
<stop offset="1" stop-color="#7c3aed" stop-opacity="0"/>
|
|
11
|
+
</radialGradient>
|
|
12
|
+
<pattern id="grid" width="50" height="50" patternUnits="userSpaceOnUse">
|
|
13
|
+
<path d="M50 0H0v50" fill="none" stroke="#ffffff" stroke-opacity="0.05" stroke-width="1"/>
|
|
14
|
+
</pattern>
|
|
15
|
+
</defs>
|
|
16
|
+
|
|
17
|
+
<rect width="1200" height="630" fill="#0d0d12"/>
|
|
18
|
+
<rect width="1200" height="630" fill="url(#grid)"/>
|
|
19
|
+
<rect width="1200" height="630" fill="url(#glow)"/>
|
|
20
|
+
|
|
21
|
+
<rect x="80" y="72" rx="8" width="260" height="50" fill="#7c3aed" fill-opacity="0.18" stroke="#7c3aed"/>
|
|
22
|
+
<text x="210" y="107" text-anchor="middle" font-family="ui-monospace, Menlo, monospace" font-size="27" fill="#c4b5fd">pi-extension</text>
|
|
23
|
+
|
|
24
|
+
<g transform="translate(600 218)">
|
|
25
|
+
<circle cx="0" cy="0" r="48" fill="#7c3aed" fill-opacity="0.18" stroke="#7c3aed" stroke-width="3"/>
|
|
26
|
+
<rect x="-12" y="-33" width="24" height="42" rx="12" fill="#a78bfa"/>
|
|
27
|
+
<path d="M-24 -2 a24 24 0 0 0 48 0" fill="none" stroke="#a78bfa" stroke-width="5" stroke-linecap="round"/>
|
|
28
|
+
<line x1="0" y1="22" x2="0" y2="39" stroke="#a78bfa" stroke-width="5" stroke-linecap="round"/>
|
|
29
|
+
</g>
|
|
30
|
+
|
|
31
|
+
<text x="600" y="360" text-anchor="middle" font-family="ui-monospace, Menlo, monospace" font-size="92" font-weight="700" fill="#ffffff">pi-voice</text>
|
|
32
|
+
<text x="600" y="406" text-anchor="middle" font-family="ui-monospace, Menlo, monospace" font-size="28" fill="#8b8b9e">@tychenjiajun/pi-voice</text>
|
|
33
|
+
<text x="600" y="462" text-anchor="middle" font-family="system-ui, sans-serif" font-size="36" fill="#c9c9d4">Speech-to-text for Pi — local model or remote ASR</text>
|
|
34
|
+
|
|
35
|
+
<rect x="216" y="510" rx="12" width="768" height="70" fill="#16161d" stroke="url(#accent)" stroke-width="3"/>
|
|
36
|
+
<text x="600" y="556" text-anchor="middle" font-family="ui-monospace, Menlo, monospace" font-size="29" fill="#a78bfa">$ pi install npm:@tychenjiajun/pi-voice</text>
|
|
37
|
+
</svg>
|