@octocodeai/freellama 0.9.0 → 0.12.0
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.md +317 -172
- package/bin/freellama.js +69 -29
- package/package.json +9 -6
package/README.md
CHANGED
|
@@ -2,61 +2,100 @@
|
|
|
2
2
|
|
|
3
3
|

|
|
4
4
|
|
|
5
|
-
**Run
|
|
5
|
+
**Run local Ollama models the smart way: the right model for your machine right now, tuned
|
|
6
|
+
prompts, and new loads held until they fit in memory, for your coding agent and for you.**
|
|
6
7
|
|
|
7
|
-
FreeLlama
|
|
8
|
-
|
|
9
|
-
|
|
10
|
-
|
|
11
|
-
|
|
8
|
+
FreeLlama sits between you (or your agent) and [Ollama](https://ollama.com). Ollama runs the
|
|
9
|
+
models; FreeLlama decides which model, how, and whether there is room for it.
|
|
10
|
+
|
|
11
|
+
An optional [managed llama.cpp engine](https://github.com/bgauryy/FreeLlama/blob/main/docs/LLAMACPP.md) also supports explicitly selected,
|
|
12
|
+
bounded text tasks through the Rust service. Automatic model selection, workflows and lifecycle
|
|
13
|
+
management still use Ollama. See the [current assessment](https://github.com/bgauryy/FreeLlama/blob/main/docs/ASSESSMENT.md) for ratings,
|
|
14
|
+
validation coverage and remaining gaps.
|
|
15
|
+
|
|
16
|
+
**In numbers** ([benchmark](https://github.com/bgauryy/FreeLlama/blob/main/docs/BENCHMARK.md), one Apple M2 Pro, 2026-11-14):
|
|
17
|
+
|
|
18
|
+
| | Measured |
|
|
19
|
+
|---|---|
|
|
20
|
+
| Speed | 274 ms median per task against 272 ms for Ollama alone; first streamed token 95 vs 93 ms |
|
|
21
|
+
| Cost of the layer | 3.7 ms per task (p95 9.8 ms), 9.7 ms of CPU, 26–31 MB of RAM |
|
|
22
|
+
| Answers | Built-in workflow prompts passed 45/46 completed graded cases (98%; 45/48 planned, 94%), against 25/48 (52%) for one-line prompts; mean output used 36% fewer tokens |
|
|
23
|
+
| Memory | A 7.2 GB load with 4.2 GB free was refused with the programs holding memory, instead of swapping |
|
|
24
|
+
|
|
25
|
+
```mermaid
|
|
26
|
+
flowchart LR
|
|
27
|
+
ask["An Ollama request:<br/>workflow, job or model"] --> pick["1. Pick<br/>a qualified local calibration,<br/>else a catalog or capability fallback"]
|
|
28
|
+
pick --> tune["2. Tune<br/>the model card's settings<br/>+ tested workflow prompt"]
|
|
29
|
+
tune --> gate{"3. Gate<br/>does the load fit<br/>in free memory?"}
|
|
30
|
+
gate -->|yes| run["Ollama runs it"]
|
|
31
|
+
gate -->|"no, after a wait"| refuse["Refused with the reason<br/>and what holds memory"]
|
|
32
|
+
run --> report["4. Report<br/>answer + check: lines<br/>+ receipt"]
|
|
33
|
+
```
|
|
34
|
+
|
|
35
|
+
| You are | Use | It feels like |
|
|
36
|
+
|---|---|---|
|
|
37
|
+
| A coding agent (Claude Code, Cursor, Codex, any MCP host) | The **MCP server** | Tools such as `run_task {workflow:"fix-bug", files:[…]}` |
|
|
38
|
+
| A person, a script, or an agent with only a shell | **`freellama run`** and **`chat`** | `ollama run`, with workflows, files and memory safety |
|
|
39
|
+
| Any Ollama, OpenAI or Anthropic client (the `ollama` CLI, Continue, opencode, Open WebUI, SDKs) | **`freellama gateway`** | A server that lists models such as `freellama/review-code` |
|
|
12
40
|
|
|
13
41
|
```mermaid
|
|
14
42
|
flowchart LR
|
|
15
43
|
agent["Coding agent<br/>Claude Code, Cursor, any MCP host"]
|
|
16
|
-
|
|
17
|
-
|
|
44
|
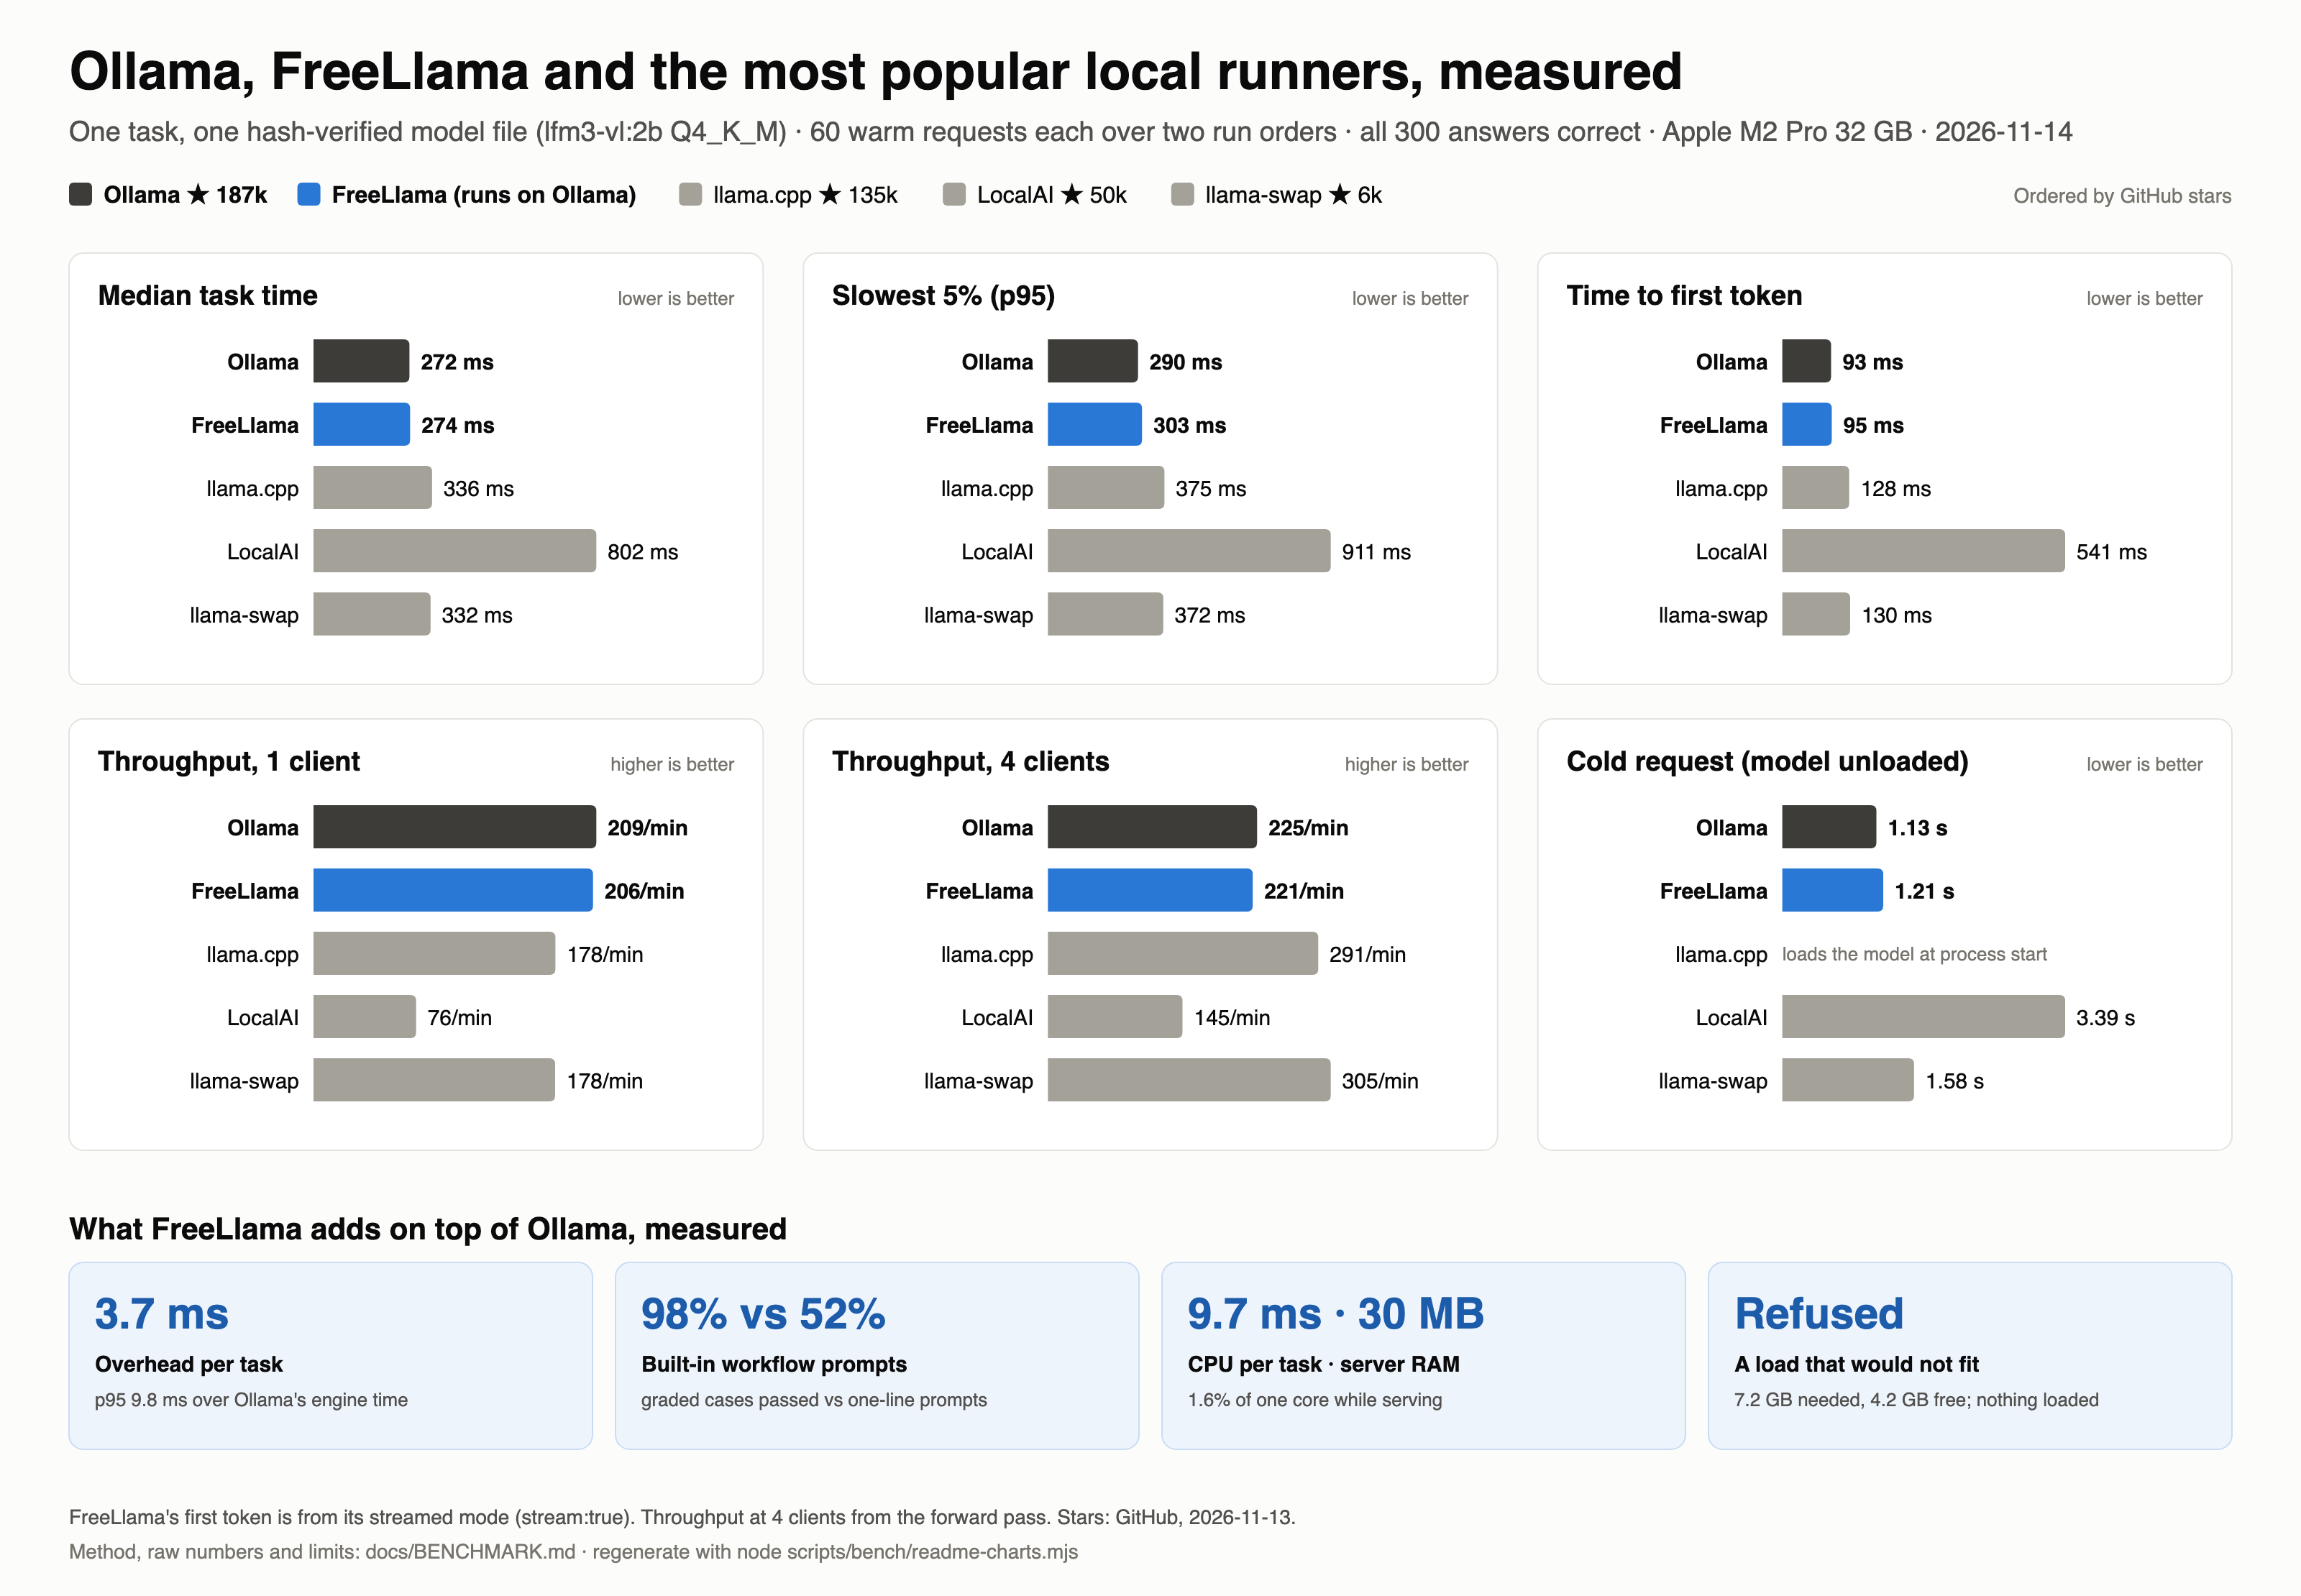
+
you["You or a script"]
|
|
45
|
+
client["Ollama, OpenAI, Anthropic clients"]
|
|
18
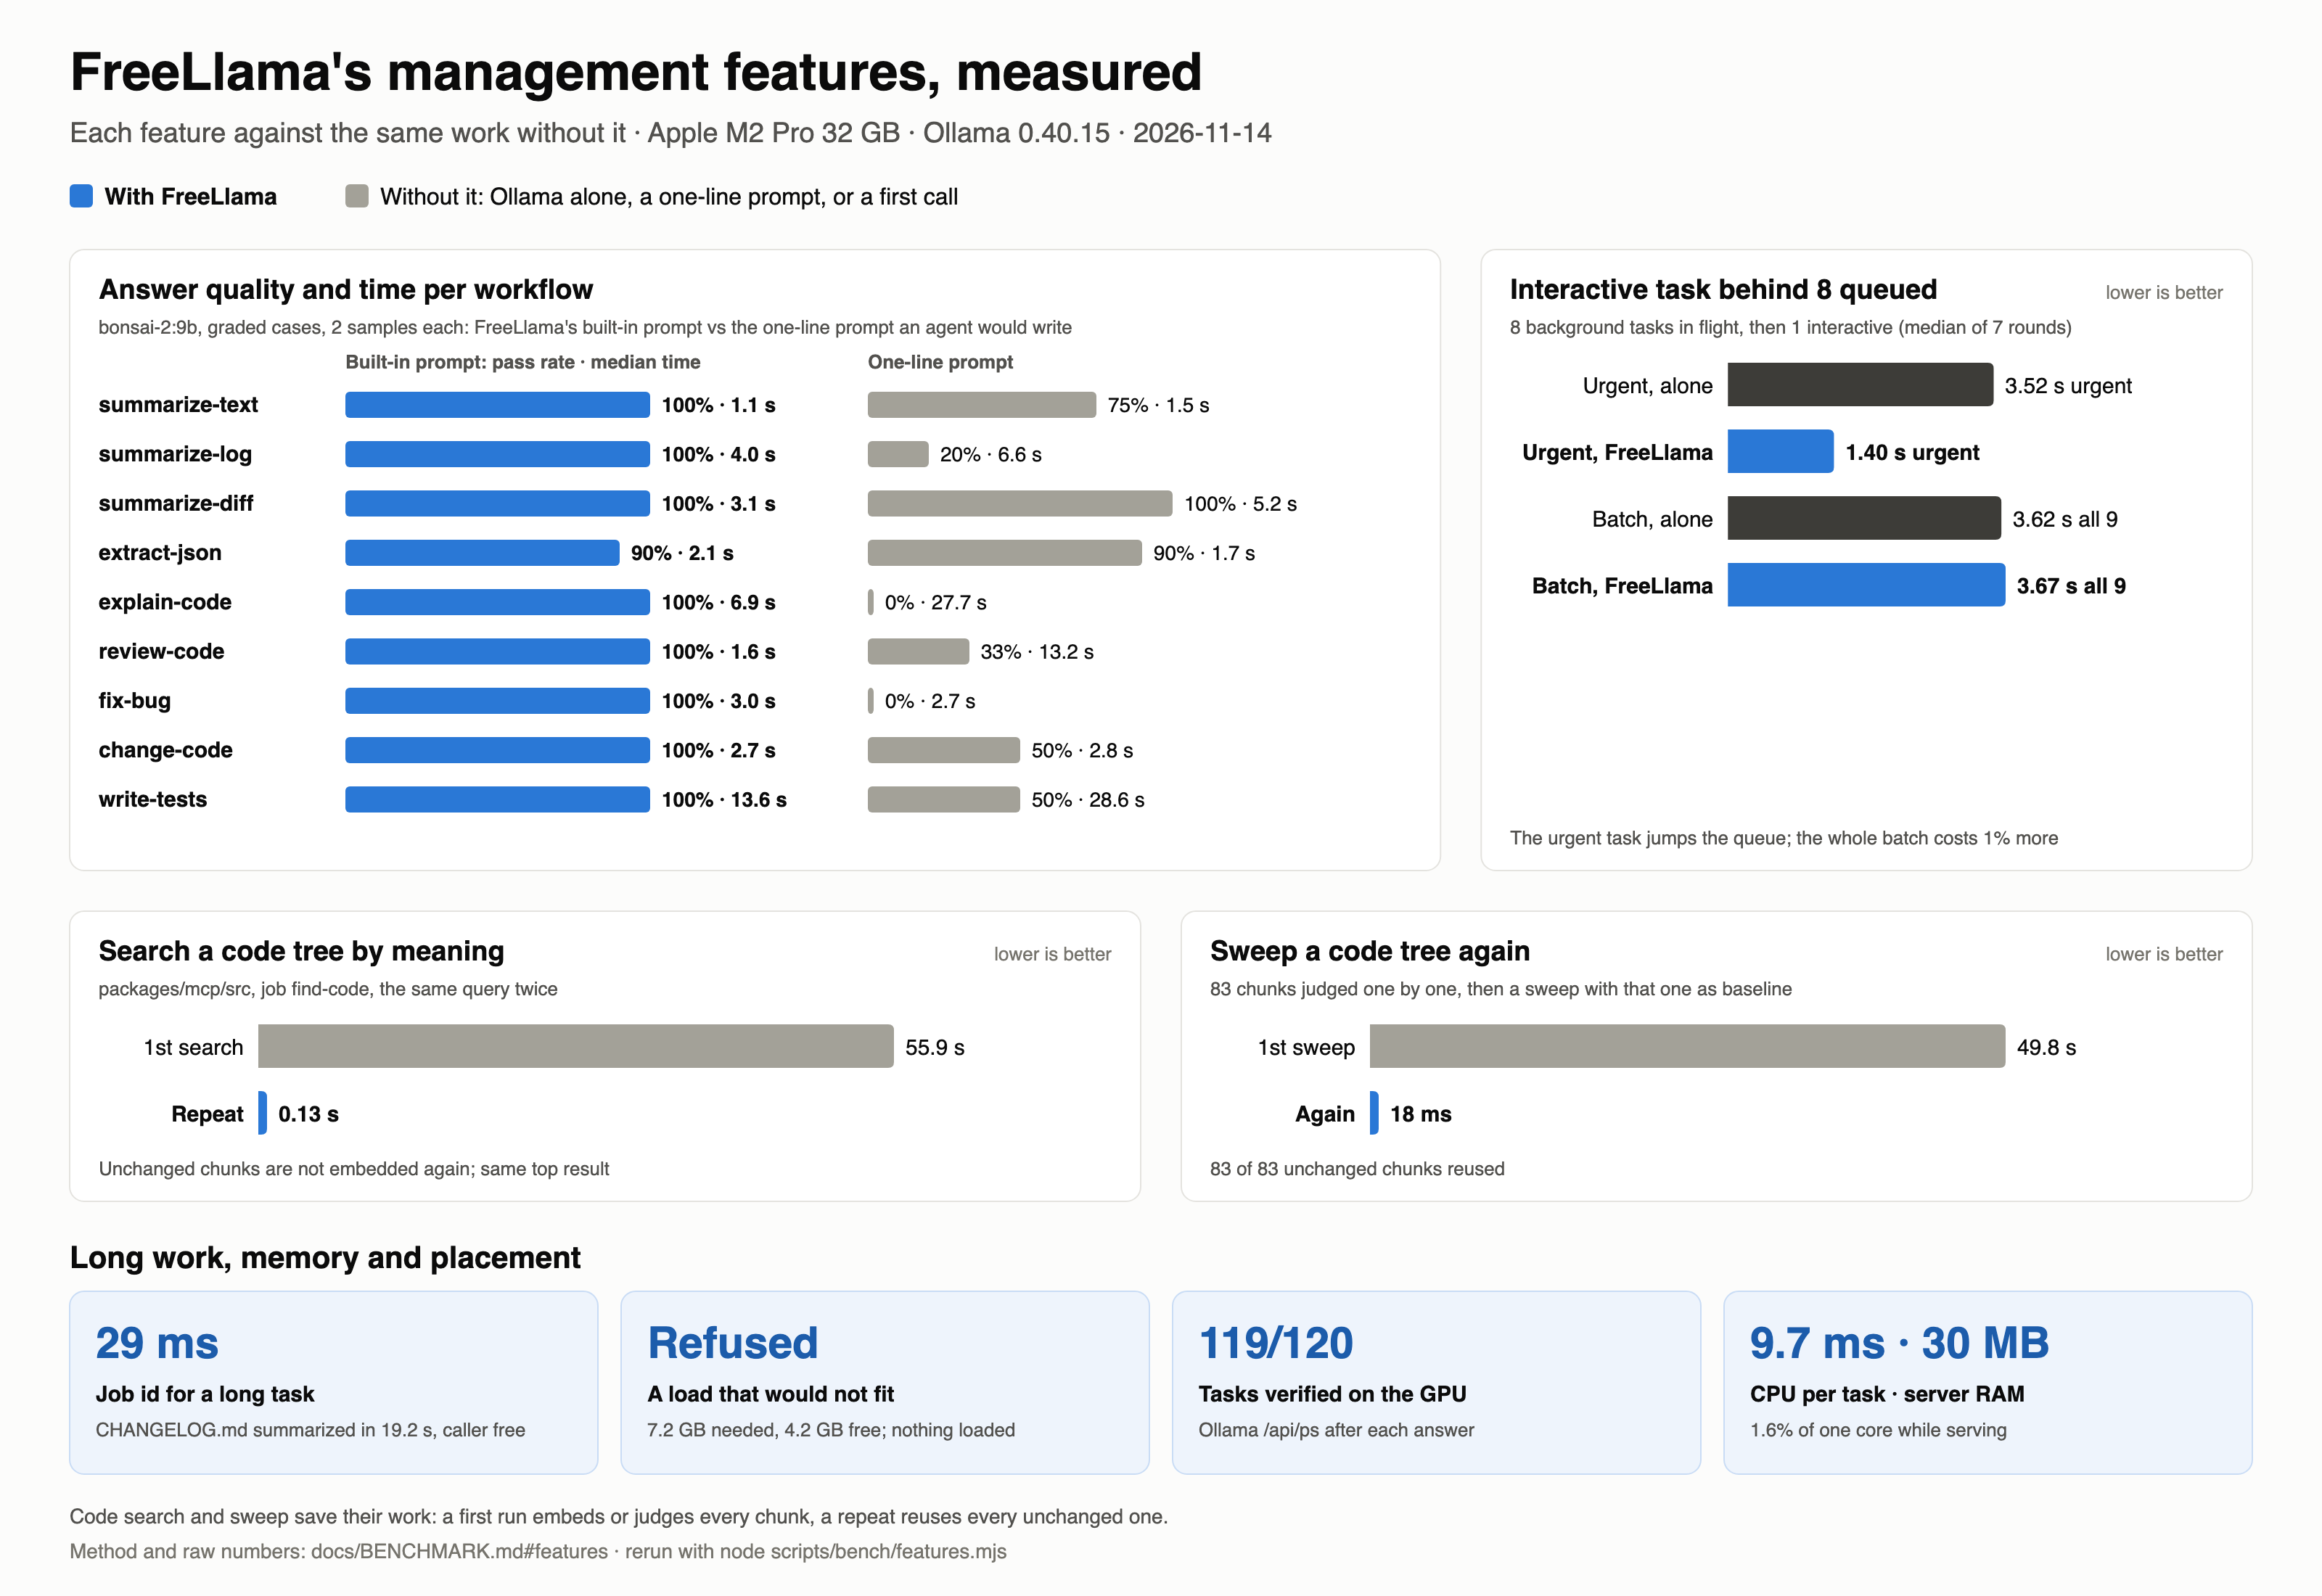
46
|
subgraph fl["FreeLlama, on your machine"]
|
|
19
|
-
mcp["MCP
|
|
20
|
-
|
|
21
|
-
|
|
47
|
+
mcp["MCP tools<br/>workflows, picks, checks"]
|
|
48
|
+
cli["freellama run / chat"]
|
|
49
|
+
gw["freellama gateway<br/>127.0.0.1:11437"]
|
|
50
|
+
serve["freellama serve<br/>127.0.0.1:11435<br/>routing, admission, memory gate"]
|
|
22
51
|
end
|
|
23
|
-
|
|
24
|
-
|
|
25
|
-
|
|
26
|
-
agent -->|"MCP
|
|
27
|
-
|
|
28
|
-
cli -->|"
|
|
29
|
-
|
|
30
|
-
mcp
|
|
31
|
-
|
|
32
|
-
serve
|
|
33
|
-
serve
|
|
52
|
+
ollama[("Ollama<br/>Metal, CUDA, ROCm, CPU")]
|
|
53
|
+
cpp[("Optional llama.cpp server<br/>explicit bounded text tasks")]
|
|
54
|
+
|
|
55
|
+
agent -->|"MCP"| mcp
|
|
56
|
+
you --> cli
|
|
57
|
+
cli -->|"the same tool handlers, in-process"| mcp
|
|
58
|
+
client --> gw
|
|
59
|
+
mcp -->|"managed tasks"| serve
|
|
60
|
+
gw -->|"virtual models: pick, prompts, admitted load"| serve
|
|
61
|
+
serve --> ollama
|
|
62
|
+
serve --> cpp
|
|
34
63
|
```
|
|
35
64
|
|
|
36
|
-
## Why
|
|
65
|
+
## Why not call Ollama directly?
|
|
66
|
+
|
|
67
|
+
Ollama runs the tag and settings you request. Choosing well on a shared workstation requires
|
|
68
|
+
metadata inspection, host observations and coordination. FreeLlama supplies that layer; the answer
|
|
69
|
+
is still yours to check. The [end-to-end review](https://github.com/bgauryy/FreeLlama/blob/main/docs/OLLAMA_REVIEW.md) explains the architecture,
|
|
70
|
+
implemented repairs and remaining evidence gaps.
|
|
37
71
|
|
|
38
|
-
|
|
39
|
-
|
|
40
|
-
the
|
|
72
|
+
| What goes wrong with a direct call | What FreeLlama does | What we measured |
|
|
73
|
+
|---|---|---|
|
|
74
|
+
| **The wrong model for this machine.** A tag name says nothing about capability, context or memory. One load too many and the machine starts swapping. | Uses a qualifying [machine-local route](https://github.com/bgauryy/FreeLlama/blob/main/docs/MODEL_SELECTION.md#turn-measurements-into-routing-evidence) first, then catalog or capability fallbacks. Throughput does not prove quality. A load that does not fit waits, then is refused with the reason and the programs holding the memory. | With 6.5 GB free, a code review moved from a 10 GB model to one that fit. A yes/no question ran on a 1.2 GB decision model instead of a 14.5 GB one that would have been refused. |
|
|
75
|
+
| **Default settings waste tokens.** Thinking models reason before every answer. Small models pad their output. | Applies each model card's documented sampling and think setting, plus step-by-step workflow prompts that were tested on the models. | A direct call spent 61 tokens (0.92 s) thinking before answering "OK"; FreeLlama answered in 2 tokens (0.47 s). Workflow prompts passed 45/46 completed cases against 25/48 for one-line prompts. |
|
|
76
|
+
| **No way to tell a good answer from a bad one.** Answers loop, pad, invent facts, or come back empty. | Returns `check:` lines for filler, numbers or quoted text absent from the source, and edits that do not match the file, plus execution receipts. [Measured misses and false alarms](https://github.com/bgauryy/FreeLlama/blob/main/docs/RELIABILITY.md) remain visible; clean checks do not prove accuracy. | An empty "thinking-only" answer exits 1 with the fix (`--think=false`) instead of looking like success. |
|
|
41
77
|
|
|
42
|
-
|
|
43
|
-
footprint.
|
|
44
|
-
- **Whether there is room.** One more load can push the machine into swap, several agents can pile
|
|
45
|
-
onto one GPU, and a hot or busy machine slows everything.
|
|
46
|
-
- **Whether it worked.** A model can repeat itself until its token cap, and nothing says whether the
|
|
47
|
-
task ran on the GPU or fell back to the CPU.
|
|
78
|
+
Over a session it also keeps the machine efficient:
|
|
48
79
|
|
|
49
|
-
|
|
50
|
-
|
|
51
|
-
|
|
52
|
-
|
|
80
|
+
| Mechanism | Effect | Measured |
|
|
81
|
+
|---|---|---|
|
|
82
|
+
| **Prompt cache kept** | Reuses a loaded model's context window and settings, so Ollama's prompt cache survives between turns | A second question about a 3,144-token document took 5.1 s instead of 11.9 s (attention models; Ollama does not cache hybrid models such as `lfm3` across turns) |
|
|
83
|
+
| **Managed local admission** | Managed Ollama loads, including streams, pass the memory gate; managed llama.cpp tasks reserve their configured memory budget. Direct engine calls and external server startup are outside this gate | — |
|
|
84
|
+
| **Indexed code search** | A repeated search embeds only the chunks that changed | `packages/mcp/src`: 55.9 s first, 0.13 s next |
|
|
85
|
+
| **Long tasks as jobs** | A long task returns a job id at once; the agent polls and stays free | Job id in 29 ms; an interactive task behind 8 queued ones answered in 1.40 s instead of 3.52 s |
|
|
86
|
+
|
|
87
|
+
*Measured on one Apple M2 Pro (32 GB) with Ollama 0.40.15 on 2026-11-14 (the thinking example on
|
|
88
|
+
2026-11-10). These are single-machine results, not general speed claims; method and limits:
|
|
89
|
+
[Benchmark](https://github.com/bgauryy/FreeLlama/blob/main/docs/BENCHMARK.md).*
|
|
90
|
+
|
|
91
|
+
The name means less metered inference, not only Meta's Llama models.
|
|
53
92
|
|
|
54
93
|
## Requirements
|
|
55
94
|
|
|
56
95
|
| You need | Why |
|
|
57
96
|
|---|---|
|
|
58
|
-
| [Ollama](https://ollama.com/download) running (`ollama list` works) with at least one model |
|
|
59
|
-
| Node.js 22 or newer | Runs the MCP server
|
|
97
|
+
| [Ollama](https://ollama.com/download) running (`ollama list` works) with at least one model | Required for the agent workflows below. FreeLlama never downloads a model without your approval. Only the one-line installer offers to install Ollama, and only after asking you |
|
|
98
|
+
| Node.js 22 or newer | Runs the MCP server, the agent commands (`run`, `chat`, `gateway`…) and the npm launcher |
|
|
60
99
|
| One of the platforms below | npm installs the matching prebuilt binary as an optional dependency; do not install with `--omit=optional` |
|
|
61
100
|
|
|
62
101
|
| Platform | Prebuilt package |
|
|
@@ -67,201 +106,307 @@ you can check. The name means less metered inference, not only Meta's Llama mode
|
|
|
67
106
|
| Windows x64 | `@octocodeai/freellama-native-win32-x64-msvc` |
|
|
68
107
|
| Windows arm64 | `@octocodeai/freellama-native-win32-arm64-msvc` |
|
|
69
108
|
|
|
70
|
-
Intel Macs and musl Linux (such as Alpine) have no prebuilt binary: build from source
|
|
71
|
-
or newer
|
|
72
|
-
|
|
109
|
+
Intel Macs and musl Linux (such as Alpine) have no prebuilt binary: [build from source](https://github.com/bgauryy/FreeLlama/blob/main/docs/BUILD_AND_NOTES.md#build-from-source)
|
|
110
|
+
with Rust 1.89 or newer. A second, CPU-only Ollama for small helper models is optional
|
|
111
|
+
([CPU/GPU routing](https://github.com/bgauryy/FreeLlama/blob/main/docs/CPU_GPU_ROUTING.md)).
|
|
73
112
|
|
|
74
|
-
|
|
113
|
+
Published npm installs on supported platforms use prebuilt Rust binaries; they need Node 22+,
|
|
114
|
+
not a Rust toolchain. Source builds need Rust and, for the agent commands and MCP, Node. The
|
|
115
|
+
[explicit llama.cpp operator path](https://github.com/bgauryy/FreeLlama/blob/main/docs/LLAMACPP.md) can run without Ollama; `run`, `chat`,
|
|
116
|
+
`gateway` and global readiness still depend on Ollama.
|
|
75
117
|
|
|
76
|
-
|
|
118
|
+
When Ollama is missing, every command that needs it stops at once and says what to do:
|
|
77
119
|
|
|
78
|
-
|
|
79
|
-
|
|
80
|
-
|
|
81
|
-
|
|
120
|
+
```mermaid
|
|
121
|
+
flowchart LR
|
|
122
|
+
cmd["freellama run, chat,<br/>gateway, status"] --> up{"Ollama answers?"}
|
|
123
|
+
up -->|yes| go["Runs"]
|
|
124
|
+
up -->|no| inst{"Ollama installed?"}
|
|
125
|
+
inst -->|no| m["Ollama is not installed. Install it with<br/>curl -fsSL https://ollama.com/install.sh #124; sh<br/>or from https://ollama.com/download (exit 1)"]
|
|
126
|
+
inst -->|yes| st["Ollama is installed but not running:<br/>open the Ollama app or run ollama serve<br/>(exit 75, retry)"]
|
|
82
127
|
```
|
|
83
128
|
|
|
84
|
-
|
|
129
|
+
## Install
|
|
85
130
|
|
|
86
|
-
|
|
87
|
-
{ "mcpServers": { "freellama": { "command": "npx", "args": ["-y", "@octocodeai/freellama-mcp-server"] } } }
|
|
88
|
-
```
|
|
131
|
+
One line installs FreeLlama and, if you agree, Ollama:
|
|
89
132
|
|
|
90
|
-
|
|
91
|
-
|
|
133
|
+
| System | Command |
|
|
134
|
+
|---|---|
|
|
135
|
+
| macOS, Linux | `curl -fsSL https://raw.githubusercontent.com/bgauryy/FreeLlama/main/scripts/install.sh \| sh` |
|
|
136
|
+
| Windows (PowerShell) | `irm https://raw.githubusercontent.com/bgauryy/FreeLlama/main/scripts/install.ps1 \| iex` |
|
|
92
137
|
|
|
93
|
-
|
|
94
|
-
|
|
95
|
-
`
|
|
96
|
-
|
|
97
|
-
`claude mcp add freellama -e FREELLAMA_MCP_ALLOWED_ROOTS=/absolute/path/to/your-project -- npx -y @octocodeai/freellama-mcp-server`
|
|
98
|
-
or an `"env": { ... }` entry in JSON. All settings: [MCP configuration](packages/mcp/CONFIGURATION.md).
|
|
138
|
+
It installs the npm package when npm is on PATH, otherwise the checksum-verified binary. When
|
|
139
|
+
Ollama is missing it asks before running Ollama's official installer; add `sh -s -- --with-ollama`
|
|
140
|
+
or `sh -s -- --no-ollama` to decide up front. It never downloads a model:
|
|
141
|
+
run `freellama init` next to see what is installed and what fits.
|
|
99
142
|
|
|
100
|
-
|
|
143
|
+
Or install one part yourself:
|
|
101
144
|
|
|
102
|
-
|
|
103
|
-
|
|
104
|
-
freellama --
|
|
145
|
+
| For | Install | Then |
|
|
146
|
+
|---|---|---|
|
|
147
|
+
| Your agent (Claude Code) | `claude mcp add freellama -- npx -y @octocodeai/freellama-mcp-server` | Ask the agent in plain words |
|
|
148
|
+
| Your agent (Claude Desktop, Cursor, other hosts) | `{ "mcpServers": { "freellama": { "command": "npx", "args": ["-y", "@octocodeai/freellama-mcp-server"] } } }` | Same |
|
|
149
|
+
| You, scripts, shell-only agents, operators | `npm install -g @octocodeai/freellama` | `freellama run`, `chat`, `gateway`, `serve`, `doctor`… |
|
|
150
|
+
| Operators without Node.js | `cargo install freellama-cli` (Rust 1.89+) | The operator commands only (`serve`, `doctor`, `catalog`…) |
|
|
151
|
+
|
|
152
|
+
One `freellama` command covers both halves; the npm launcher sends each command to the right one:
|
|
153
|
+
|
|
154
|
+
```mermaid
|
|
155
|
+
flowchart LR
|
|
156
|
+
f["freellama COMMAND"] --> which{"COMMAND"}
|
|
157
|
+
which -->|"run, chat, gateway,<br/>workflows, job, tool(s)<br/>status on a terminal"| node["Agent commands, in Node<br/>(from @octocodeai/freellama-mcp-server,<br/>installed with it)"]
|
|
158
|
+
which -->|"serve, init, doctor, catalog,<br/>models, task, jobs, status --json…"| rust["Operator commands,<br/>the Rust binary"]
|
|
105
159
|
```
|
|
106
160
|
|
|
107
|
-
|
|
108
|
-
|
|
161
|
+
| Note | Detail |
|
|
162
|
+
|---|---|
|
|
163
|
+
| Agent commands on npm | From 0.11.0. From a checkout: `yarn install && yarn build && node packages/cli/bin/freellama.js run --help` |
|
|
164
|
+
| Without installing | Prefix any command with `npx @octocodeai/freellama` |
|
|
165
|
+
| The service | The MCP server and the agent commands start `freellama serve` on `127.0.0.1:11435` if none is running. Neither installs or starts Ollama |
|
|
166
|
+
| `delegate_research` | Reads only the directories in `FREELLAMA_MCP_ALLOWED_ROOTS` (`:`-separated; `;` on Windows), for example `claude mcp add freellama -e FREELLAMA_MCP_ALLOWED_ROOTS=/absolute/path/to/your-project -- npx -y @octocodeai/freellama-mcp-server`. `run_task` `files` uses `FREELLAMA_FILE_ROOTS` instead |
|
|
167
|
+
| Every setting | [MCP configuration](https://github.com/bgauryy/FreeLlama/blob/main/packages/mcp/CONFIGURATION.md) |
|
|
109
168
|
|
|
110
169
|
## Quick start
|
|
111
170
|
|
|
112
171
|
### From your agent
|
|
113
172
|
|
|
114
|
-
Ask in plain words; the agent picks the tool
|
|
173
|
+
Ask in plain words; the agent picks the tool:
|
|
115
174
|
|
|
116
|
-
- "
|
|
117
|
-
- "Use FreeLlama to summarize these 40 files with a local model, then check three summaries."
|
|
175
|
+
- "Use FreeLlama to summarize these 40 log files with a local model, then check three summaries."
|
|
118
176
|
- "Read this screenshot with a local OCR model."
|
|
177
|
+
- "Find where CLI flags are parsed in src/, using a local embedding model."
|
|
119
178
|
|
|
120
|
-
Or
|
|
121
|
-
that `model` (without one, routing picks by capability alone and may choose a model that does
|
|
122
|
-
not fit now).
|
|
179
|
+
Or name a workflow. FreeLlama then picks the model and gives it step-by-step instructions:
|
|
123
180
|
|
|
124
181
|
```jsonc
|
|
182
|
+
{ "tool": "run_task", "arguments": { "workflow": "fix-bug", "files": ["src/parser.ts"], "prompt": "drops the last token" } }
|
|
125
183
|
{ "tool": "models", "arguments": { "view": "catalog", "job": "coding" } }
|
|
126
|
-
{ "tool": "run_task", "arguments": { "task": "coding", "model": "<catalog pick>", "prompt": "Rename foo to bar in: ...", "options": { "num_predict": 512 } } }
|
|
127
184
|
```
|
|
128
185
|
|
|
129
|
-
|
|
186
|
+
| Call | Returns |
|
|
187
|
+
|---|---|
|
|
188
|
+
| `models {view:"catalog", job}` | Shipped recommendations for a job, with current installation and estimated fit; automatic execution can use a qualifying local calibration first |
|
|
189
|
+
| `run_task {preview:true}` | The route, without running or reserving anything |
|
|
130
190
|
|
|
131
191
|
### From the terminal
|
|
132
192
|
|
|
193
|
+
`freellama run` takes the same flags as `ollama run`. It streams tokens on a terminal and prints
|
|
194
|
+
only the answer in a pipe.
|
|
195
|
+
|
|
133
196
|
```bash
|
|
134
|
-
freellama
|
|
135
|
-
freellama
|
|
136
|
-
freellama
|
|
137
|
-
freellama
|
|
138
|
-
|
|
139
|
-
freellama
|
|
140
|
-
freellama models
|
|
141
|
-
freellama task --task completion --model MODEL_TAG "Reply with exactly OK."
|
|
142
|
-
freellama status # queues, memory holds, loaded models
|
|
197
|
+
freellama catalog # catalog recommendations: installed, estimated fit
|
|
198
|
+
git diff | freellama run -w summarize-diff # review summary from the pick that fits
|
|
199
|
+
freellama run -w fix-bug -f src/parser.ts "drops the last token"
|
|
200
|
+
freellama run --ask "Is a refund requested?" < ticket.txt # a yes/no answer with its probability
|
|
201
|
+
freellama run -j find-code -f 'src/**/*.ts' "where are CLI flags parsed"
|
|
202
|
+
freellama chat review-code # the real ollama chat, on a workflow
|
|
203
|
+
freellama status # memory, queues, loaded models, jobs
|
|
143
204
|
```
|
|
144
205
|
|
|
145
|
-
|
|
146
|
-
|
|
147
|
-
|
|
206
|
+
| Stream | Carries |
|
|
207
|
+
|---|---|
|
|
208
|
+
| stdout | The answer only |
|
|
209
|
+
| stderr | `check:` lines (read them before you rely on the answer) and notes |
|
|
210
|
+
|
|
211
|
+
| Exit code | Meaning |
|
|
212
|
+
|---|---|
|
|
213
|
+
| 0 | Answered |
|
|
214
|
+
| 75 | Busy, short of memory, or Ollama stopped; retry later. stderr says when |
|
|
215
|
+
| 1 | Refused, failed, empty, or Ollama not installed |
|
|
216
|
+
| 2 | Usage error |
|
|
217
|
+
| 130 | Interrupted |
|
|
218
|
+
|
|
219
|
+
Model management stays with Ollama: `ollama list`, `ollama pull`, `ollama rm`.
|
|
220
|
+
|
|
221
|
+
### From any Ollama, OpenAI or Anthropic client
|
|
222
|
+
|
|
223
|
+
```bash
|
|
224
|
+
freellama gateway # 127.0.0.1:11437
|
|
225
|
+
OLLAMA_HOST=127.0.0.1:11437 ollama run freellama/explain-code
|
|
226
|
+
```
|
|
227
|
+
|
|
228
|
+
| Client | Point it at | Model |
|
|
229
|
+
|---|---|---|
|
|
230
|
+
| Ollama (CLI, Open WebUI, Continue…) | `OLLAMA_HOST=127.0.0.1:11437` | `freellama/review-code`, or any installed tag |
|
|
231
|
+
| OpenAI Chat and Responses (Codex) | base URL `http://127.0.0.1:11437/v1` | `freellama/review-code` |
|
|
232
|
+
| Anthropic Messages (Claude Code) | `ANTHROPIC_BASE_URL=http://127.0.0.1:11437` | `freellama/review-code` |
|
|
233
|
+
|
|
234
|
+
Each workflow is a model; responses stream token by token. Real tags pass through to Ollama with
|
|
235
|
+
FreeLlama's admission and telemetry.
|
|
236
|
+
|
|
237
|
+
## What you get
|
|
238
|
+
|
|
239
|
+
| Area | What it does | Where |
|
|
240
|
+
|---|---|---|
|
|
241
|
+
| **Model choice** | A qualifying machine-local Rust route takes priority over the shipped catalog. Capable workflows and OCR also require task-quality evidence for that route; otherwise catalog and capability fallbacks apply. The receipt names the selection and any caveats | [Model selection](https://github.com/bgauryy/FreeLlama/blob/main/docs/MODEL_SELECTION.md), `freellama catalog`, `models {view:"catalog"}` |
|
|
242
|
+
| **Second engine** | Explicit local llama.cpp text tasks share the Rust admission pools and resource governor. The operator starts the server and supplies context, output and memory bounds; placement remains unverified | [Managed llama.cpp](https://github.com/bgauryy/FreeLlama/blob/main/docs/LLAMACPP.md) |
|
|
243
|
+
| **Streaming with receipts** | Managed Ollama tasks stream tokens as server-sent events (`route`, `admission`, `delta`, then `done` with the full receipt); measured first token 95 vs 93 ms for direct Ollama. MCP shows "generating on MODEL: N tokens, R tok/s" while a job runs | `POST /_freellama/v1/tasks {stream:true}`, [Every API](https://github.com/bgauryy/FreeLlama/blob/main/docs/API.md) |
|
|
244
|
+
| **Where the time went** | Each receipt's `timing` splits a task by phase (discover, admission, Ollama's answer, placement, learning…) and gives FreeLlama's own `overhead_ms` | `--json`, `response_file`, [Architecture](https://github.com/bgauryy/FreeLlama/blob/main/docs/ARCHITECTURE.md#request-shapes) |
|
|
245
|
+
| **Workflows** | 15 tested instructions for small models: `fix-bug`, `change-code`, `implement`, `write-tests`, `review-code`, `explain-code`, `summarize-log`, `summarize-text`, `summarize-diff`, `extract-json`, `read-text`, `read-table`, `read-fields`, `answer-image`, `describe-screen`. Sampling comes from each model's card; the dated eval reports 45/46 completed passes against 25/48 for one-line prompts, with [denominators and limits](https://github.com/bgauryy/FreeLlama/blob/main/docs/BENCHMARK.md#built-in-prompts-measured) | `-w NAME`, `run_task {workflow}`, `scripts/local-test/workflows.mjs` |
|
|
246
|
+
| **Your own workflows** | A Markdown file per workflow (job, title, instructions) in `~/.octocode/freellama/workflows/`. It runs like a built-in, replaces one of the same name, and the receipt names the file and its digest; a bad file is skipped with the reason | [Your own workflows](https://github.com/bgauryy/FreeLlama/blob/main/docs/PROMPTS.md#your-own-workflows), `freellama workflows` |
|
|
247
|
+
| **Fallback chains** | Up to 4 models to try in order, each only after the one before was refused before it ran (no room, input over its context, not installed). Never after a model started; every attempt is in the receipt | `run_task {fallbackModels}`, `--fallback TAG` |
|
|
248
|
+
| **Structured output** | A field list (`'name, age int, tags list'`) or a JSON schema | `--schema` |
|
|
249
|
+
| **Decisions** | Yes/no, one of a list, or a level, with a probability | `--ask`, `--choice`, `--level` |
|
|
250
|
+
| **Embeddings and completion** | Shorter vectors; fill-in-the-middle on models that support it | `--dimensions`, `--suffix` |
|
|
251
|
+
| **Checkable answers** | Heuristics flag some padding, numbers or quoted text absent from the source, invalid edits, leaked thinking, input instructions, empty extraction fields and malformed tool calls. They miss errors and produce false alarms; a clean result still needs verification. Receipts distinguish configured from observed placement | stderr; MCP `response_file`; [measured reliability and limits](https://github.com/bgauryy/FreeLlama/blob/main/docs/RELIABILITY.md) |
|
|
252
|
+
| **Memory safety** | A model loads only if it fits with a reserve; idle models unload first, otherwise the load waits, then is refused with the reason | [The memory gate](https://github.com/bgauryy/FreeLlama/blob/main/docs/ARCHITECTURE.md#managed-task-execution) |
|
|
253
|
+
| **Fair sharing** | One queue per backend weights interactive, normal and background work 3:2:1; holds apply when the machine is busy, hot or swapping. An optional CPU-only Ollama runs helper models beside the GPU | [Monitoring](https://github.com/bgauryy/FreeLlama/blob/main/docs/MONITORING.md) |
|
|
254
|
+
| **Long answers** | Saved whole and returned as a short view | [Where an answer goes](https://github.com/bgauryy/FreeLlama/blob/main/packages/mcp/CONFIGURATION.md#where-an-answer-goes) |
|
|
255
|
+
| **Batches and jobs** | Up to 64 independent items; background jobs, optionally with durable receipts and idempotency keys; sweeps over a whole code tree or log set | `--each`, `run_task {tasks}`, `--defer` + `freellama job ID --wait`, `idempotencyKey`, `sweep` |
|
|
256
|
+
| **Agent-safe shell** | Answer-only stdout, stable exit codes, no hang on an agent's open stdin; every MCP tool callable from a shell | `freellama tool NAME JSON` |
|
|
257
|
+
|
|
258
|
+
## What to offload
|
|
259
|
+
|
|
260
|
+
Offload bounded work whose result can be checked. Keep judgment in the agent.
|
|
261
|
+
|
|
262
|
+
| Offload | Keep in your agent |
|
|
263
|
+
|---|---|
|
|
264
|
+
| Embeddings, code search and deduplication | Small lookups (describing the task costs more than doing it) |
|
|
265
|
+
| OCR and image reading | High-stakes judgment: security review, design, merge decisions |
|
|
266
|
+
| Bulk rewrites, summaries, classification of many files | Edits across files |
|
|
267
|
+
| Questions about workspace files (`delegate_research`) | Final verification of any local answer |
|
|
268
|
+
|
|
269
|
+
Treat local answers as candidates: spot-check a few before you rely on the rest.
|
|
270
|
+
|
|
271
|
+
## How it compares
|
|
272
|
+
|
|
273
|
+
Model loading, eviction, compatible APIs, MCP and presets are common. Ollama itself queues work and
|
|
274
|
+
evicts idle models; the llama.cpp router, llama-swap, LocalAI, Lemonade, LM Studio and oMLX each
|
|
275
|
+
manage model memory their own way. FreeLlama adds a specific combination for an agent offloading
|
|
276
|
+
work on a machine that is also doing other work:
|
|
277
|
+
|
|
278
|
+
- admission against live host signals (free memory with a reserve, OS pressure, swap, CPU load,
|
|
279
|
+
heat) that holds a cold load but lets a loaded model keep serving;
|
|
280
|
+
- per-job selection using qualifying local calibration, with catalog fallbacks and tested workflow prompts;
|
|
281
|
+
- compact answers with `check:` lines and a receipt of what ran, where and why.
|
|
282
|
+
|
|
283
|
+
| Choose | When |
|
|
284
|
+
|---|---|
|
|
285
|
+
| FreeLlama | An agent offloads bounded, checkable work to local Ollama models on a shared workstation |
|
|
286
|
+
| Ollama alone | One application, one explicitly chosen model, little contention |
|
|
287
|
+
| LocalAI, Lemonade | You want the server to supply agents, many backends or routing policies itself |
|
|
288
|
+
| LM Studio, Open WebUI | You want a desktop or web app for people |
|
|
289
|
+
| LiteLLM | An organization-wide gateway with retries, budgets and caching across providers |
|
|
290
|
+
| llama.cpp, oMLX, vLLM | You want engine-level control: batching, KV caches, kernels |
|
|
291
|
+
|
|
292
|
+
FreeLlama does not make Ollama decode faster, has no chat UI, no automatic failover between engines
|
|
293
|
+
and no scheduling across machines. It does not automatically escalate failed checks to a cloud
|
|
294
|
+
model; the caller owns that decision. The second engine is currently limited to explicit text tasks.
|
|
295
|
+
|
|
296
|
+
### Benchmarks
|
|
297
|
+
|
|
298
|
+
Ollama alone, FreeLlama on Ollama, and the most popular alternatives by GitHub stars, on one task
|
|
299
|
+
and one hash-verified model file (Apple M2 Pro, 32 GB, 2026-11-14). All 300 answers were correct.
|
|
300
|
+
|
|
301
|
+
|
|
302
|
+
|
|
303
|
+
| | Ollama | **FreeLlama** | llama.cpp | LocalAI | llama-swap |
|
|
304
|
+
|---|---:|---:|---:|---:|---:|
|
|
305
|
+
| Median task time | 272 ms | **274 ms** | 336 ms | 802 ms | 332 ms |
|
|
306
|
+
| First token | 93 ms | **95 ms** | 128 ms | 541 ms | 130 ms |
|
|
307
|
+
| Tasks/min, 4 clients | 225 | **221** | 291 | 145 | 305 |
|
|
308
|
+
|
|
309
|
+
FreeLlama keeps Ollama's speed and adds what an agent needs on a shared machine:
|
|
310
|
+
|
|
311
|
+
|
|
312
|
+
|
|
313
|
+
The historical charts use completed-case accuracy: 45/46 (98%) for workflow prompts. Relative to
|
|
314
|
+
the nominal 48 planned cases, that is 45/48 (94%), with two completions missing from the retained
|
|
315
|
+
aggregate; the baseline is 25/48 (52%). This small public workload does not estimate general accuracy.
|
|
316
|
+
|
|
317
|
+
llama.cpp and llama-swap serve concurrent clients faster with Ollama's default settings, and
|
|
318
|
+
LocalAI trades speed for breadth. What to use for what you are building, and how every number was
|
|
319
|
+
measured: [Benchmark](https://github.com/bgauryy/FreeLlama/blob/main/docs/BENCHMARK.md).
|
|
148
320
|
|
|
149
321
|
## Under the hood
|
|
150
322
|
|
|
151
|
-
Every managed
|
|
152
|
-
|
|
323
|
+
Every managed request, whether from MCP, the agent commands, the operator CLI or the HTTP API, goes through the same
|
|
324
|
+
Rust core: route, admit, load, run, observe. Nothing is decided from a model's name.
|
|
153
325
|
|
|
154
326
|
| Owner | Does |
|
|
155
327
|
|---|---|
|
|
156
|
-
| Your agent | Decides what to
|
|
328
|
+
| Your agent, or you | Decides what to run, writes the request, verifies the answer |
|
|
157
329
|
| FreeLlama | Picks the model, queues fairly, checks memory and host signals, coordinates loads, writes the receipt |
|
|
158
|
-
| Ollama |
|
|
330
|
+
| Ollama, or the explicitly configured llama.cpp server | Executes inference; Ollama also supplies discovery, lifecycle operations and observed placement |
|
|
159
331
|
|
|
160
|
-
|
|
332
|
+
The sequence below shows the default Ollama workflow. The [llama.cpp guide](https://github.com/bgauryy/FreeLlama/blob/main/docs/LLAMACPP.md)
|
|
333
|
+
describes its narrower execution path and unsupported controls.
|
|
161
334
|
|
|
162
335
|
```mermaid
|
|
163
336
|
sequenceDiagram
|
|
164
337
|
autonumber
|
|
165
|
-
participant A as Agent
|
|
166
|
-
participant
|
|
338
|
+
participant A as Agent or you
|
|
339
|
+
participant F as MCP server or freellama run
|
|
167
340
|
participant S as freellama serve
|
|
168
341
|
participant O as Ollama
|
|
169
|
-
A->>
|
|
170
|
-
|
|
171
|
-
Note over S: Route:
|
|
172
|
-
Note over S: Admit: fair queue
|
|
173
|
-
alt
|
|
174
|
-
S-->>
|
|
342
|
+
A->>F: a workflow, job or model, plus the request
|
|
343
|
+
F->>S: managed task (or a streamed request)
|
|
344
|
+
Note over S: Route: installed models by capability,<br/>context window, policy and local calibration
|
|
345
|
+
Note over S: Admit: fair queue, then memory, swap,<br/>CPU-load and heat checks
|
|
346
|
+
alt no room before the wait budget
|
|
347
|
+
S-->>F: 503 naming the hold and what holds memory
|
|
175
348
|
else admitted
|
|
176
|
-
opt model not
|
|
177
|
-
S->>O: load it
|
|
349
|
+
opt model not loaded
|
|
350
|
+
S->>O: load it, unloading idle models if needed
|
|
178
351
|
end
|
|
179
352
|
S->>O: chat, generate or embed
|
|
180
|
-
O-->>S:
|
|
181
|
-
S->>O: GET /api/ps
|
|
182
|
-
|
|
183
|
-
S-->>M: result + receipt
|
|
353
|
+
O-->>S: tokens
|
|
354
|
+
S->>O: GET /api/ps (where it really ran)
|
|
355
|
+
S-->>F: answer + receipt
|
|
184
356
|
end
|
|
185
|
-
|
|
186
|
-
```
|
|
187
|
-
|
|
188
|
-
An explicit `model` always wins over routing; FreeLlama never swaps in another model. With
|
|
189
|
-
`defer:true` the same path runs in the background and `task_jobs` returns the receipt.
|
|
190
|
-
|
|
191
|
-
### The memory gate
|
|
192
|
-
|
|
193
|
-
A model load has to fit before it starts, so a new load cannot push the machine into swap:
|
|
194
|
-
|
|
195
|
-
```mermaid
|
|
196
|
-
flowchart TD
|
|
197
|
-
T(["Task admitted"]) --> R{"Model already<br/>resident?"}
|
|
198
|
-
R -->|"yes"| Run(["Run on the resident runner<br/>no new memory"])
|
|
199
|
-
R -->|"no"| P{"OS memory pressure,<br/>or swapping on a large load?"}
|
|
200
|
-
P -->|"yes"| Hold["Hold the load"]
|
|
201
|
-
P -->|"no"| F{"Fits in available memory<br/>and leaves the reserve free?"}
|
|
202
|
-
F -->|"yes"| Load(["Load, then run"])
|
|
203
|
-
F -->|"no"| U["Unload idle runners"]
|
|
204
|
-
U --> F2{"Fits now?"}
|
|
205
|
-
F2 -->|"yes"| Load
|
|
206
|
-
F2 -->|"no"| Hold
|
|
207
|
-
Hold --> W{"Room freed before<br/>the deadline?"}
|
|
208
|
-
W -->|"yes"| P
|
|
209
|
-
W -->|"no"| X(["503 naming the hold<br/>and the largest memory users"])
|
|
357
|
+
F-->>A: answer, check: lines, receipt
|
|
210
358
|
```
|
|
211
359
|
|
|
212
|
-
|
|
213
|
-
|
|
214
|
-
|
|
215
|
-
waiting. Details: [Architecture](docs/ARCHITECTURE.md#managed-task-execution).
|
|
216
|
-
|
|
217
|
-
## What to offload
|
|
218
|
-
|
|
219
|
-
Offload bounded work whose result your agent can check; keep judgment in the agent.
|
|
220
|
-
|
|
221
|
-
| Offload | Keep in your agent |
|
|
222
|
-
|---|---|
|
|
223
|
-
| Embeddings, search and deduplication | Small lookups (describing the task costs more than doing it) |
|
|
224
|
-
| OCR and image reading | High-stakes judgment: security review, design, merge decisions |
|
|
225
|
-
| Bulk rewrites, summaries, classification of many files | Edits across files |
|
|
226
|
-
| Questions about workspace files (`delegate_research`) | Final verification of any local answer |
|
|
227
|
-
|
|
228
|
-
Many independent items: `run_task {tasks}`. Long work: `run_task {defer:true}` then `task_jobs`.
|
|
229
|
-
Treat local answers as candidates and spot-check some before relying on the rest.
|
|
360
|
+
An explicit `model` always wins over routing; FreeLlama never swaps in another model unless you
|
|
361
|
+
list one in `fallbackModels`. The memory
|
|
362
|
+
gate, admission and routing are described in [Architecture](https://github.com/bgauryy/FreeLlama/blob/main/docs/ARCHITECTURE.md).
|
|
230
363
|
|
|
231
364
|
## Safety
|
|
232
365
|
|
|
233
|
-
- Never pulls a model without approval for one exact tag and size
|
|
234
|
-
the exact installed tag.
|
|
235
|
-
-
|
|
236
|
-
|
|
237
|
-
-
|
|
366
|
+
- Never pulls a model without approval for one exact tag and its size. Never deletes one unless you
|
|
367
|
+
name the exact installed tag.
|
|
368
|
+
- Never swaps in another model on its own: an explicit `model` always wins, and a `fallbackModels`
|
|
369
|
+
chain moves on only after a refusal before execution, so no work is replayed.
|
|
370
|
+
- Checks each load against live free memory. A load that does not fit waits, then is refused with
|
|
371
|
+
the reason; models already loaded keep serving.
|
|
372
|
+
- Unloads only models it loaded, or models you name. Idle models are unloaded under memory pressure.
|
|
238
373
|
- Holds CPU-bound work on a busy or hot machine and names the signal in the receipt.
|
|
239
|
-
- Binds to loopback
|
|
374
|
+
- Binds to loopback. The gateway refuses browser requests from other origins and rebound DNS names.
|
|
375
|
+
Over HTTP it reads no files and fetches no URLs. For remote access, see
|
|
376
|
+
[Production](https://github.com/bgauryy/FreeLlama/blob/main/docs/PRODUCTION.md).
|
|
240
377
|
|
|
241
378
|
## Documentation
|
|
242
379
|
|
|
243
380
|
| Topic | Page |
|
|
244
381
|
|---|---|
|
|
245
|
-
| All guides | [Documentation index](docs/README.md) |
|
|
246
|
-
|
|
|
247
|
-
|
|
|
248
|
-
|
|
|
249
|
-
|
|
|
250
|
-
|
|
|
251
|
-
|
|
|
252
|
-
|
|
|
253
|
-
|
|
|
254
|
-
|
|
|
255
|
-
|
|
|
256
|
-
|
|
|
257
|
-
|
|
|
258
|
-
|
|
|
259
|
-
|
|
|
260
|
-
|
|
|
261
|
-
|
|
|
262
|
-
|
|
|
382
|
+
| All guides | [Documentation index](https://github.com/bgauryy/FreeLlama/blob/main/docs/README.md) |
|
|
383
|
+
| Current ratings, evidence and remaining priorities | [Assessment](https://github.com/bgauryy/FreeLlama/blob/main/docs/ASSESSMENT.md) |
|
|
384
|
+
| End-to-end feature review and Ollama resource strategy | [Ollama review](https://github.com/bgauryy/FreeLlama/blob/main/docs/OLLAMA_REVIEW.md) |
|
|
385
|
+
| Every API on one page: MCP tools, agent commands, gateway, CLI, control API | [Every API](https://github.com/bgauryy/FreeLlama/blob/main/docs/API.md) |
|
|
386
|
+
| `freellama run`, `chat`, `gateway`: flags, virtual models, endpoints | [Agent commands](https://github.com/bgauryy/FreeLlama/blob/main/docs/AGENT_CLI.md) |
|
|
387
|
+
| Operator commands (`serve`, `doctor`, `catalog`…) and flags | [CLI](https://github.com/bgauryy/FreeLlama/blob/main/docs/CLI.md) |
|
|
388
|
+
| MCP tools, schemas, configuration | [MCP reference](https://github.com/bgauryy/FreeLlama/blob/main/packages/mcp/README.md), [MCP configuration](https://github.com/bgauryy/FreeLlama/blob/main/packages/mcp/CONFIGURATION.md) |
|
|
389
|
+
| Operating procedure for agents | [FreeLlama skill](https://github.com/bgauryy/FreeLlama/blob/main/skills/freellama/SKILL.md) |
|
|
390
|
+
| Features, routing and admission in depth | [Features](https://github.com/bgauryy/FreeLlama/blob/main/docs/FEATURES.md) |
|
|
391
|
+
| Actual vendor checks, numbers, limits and protocol | [Benchmark](https://github.com/bgauryy/FreeLlama/blob/main/docs/BENCHMARK.md) |
|
|
392
|
+
| Choosing a model | [Model selection](https://github.com/bgauryy/FreeLlama/blob/main/docs/MODEL_SELECTION.md), [local model catalog](https://github.com/bgauryy/FreeLlama/blob/main/docs/LOCAL_MODELS.md) |
|
|
393
|
+
| Explicit bounded text tasks on a second engine | [Managed llama.cpp](https://github.com/bgauryy/FreeLlama/blob/main/docs/LLAMACPP.md) |
|
|
394
|
+
| Check accuracy and public local-model tool-calling results | [Reliability](https://github.com/bgauryy/FreeLlama/blob/main/docs/RELIABILITY.md) |
|
|
395
|
+
| Model forms, measured results | [Model forms and results](https://github.com/bgauryy/FreeLlama/blob/main/docs/MODEL_FORMS_AND_RESULTS.md) |
|
|
396
|
+
| Recipes per job | [Cookbooks](https://github.com/bgauryy/FreeLlama/blob/main/docs/cookbooks/README.md) |
|
|
397
|
+
| CPU/GPU setup and placement | [CPU/GPU routing](https://github.com/bgauryy/FreeLlama/blob/main/docs/CPU_GPU_ROUTING.md) |
|
|
398
|
+
| Queues, memory, live tuning | [Monitoring](https://github.com/bgauryy/FreeLlama/blob/main/docs/MONITORING.md) |
|
|
399
|
+
| Faster, lighter local models; Ollama settings | [Tuning](https://github.com/bgauryy/FreeLlama/blob/main/docs/TUNING.md) |
|
|
400
|
+
| Background jobs, durable receipts and idempotency | [Deferred jobs](https://github.com/bgauryy/FreeLlama/blob/main/docs/DEFERRED_JOBS.md) |
|
|
401
|
+
| Writing your own workflows | [Local prompts](https://github.com/bgauryy/FreeLlama/blob/main/docs/PROMPTS.md#your-own-workflows) |
|
|
402
|
+
| History, affinity, warming | [Scopes and warming](https://github.com/bgauryy/FreeLlama/blob/main/docs/SCOPES_AND_WARMING.md) |
|
|
403
|
+
| Deployment and releases | [Production](https://github.com/bgauryy/FreeLlama/blob/main/docs/PRODUCTION.md) |
|
|
404
|
+
| Build from source, tests and evals | [Build and notes](https://github.com/bgauryy/FreeLlama/blob/main/docs/BUILD_AND_NOTES.md), [Testing](https://github.com/bgauryy/FreeLlama/blob/main/docs/TESTING.md) |
|
|
405
|
+
| Production panic/lock review and Windows memory evidence | [Rust resource audit](https://github.com/bgauryy/FreeLlama/blob/main/docs/RUST_RESOURCE_AUDIT.md) |
|
|
406
|
+
| Architecture and ownership | [Architecture](https://github.com/bgauryy/FreeLlama/blob/main/docs/ARCHITECTURE.md) |
|
|
407
|
+
| Embedding the Rust core | [Rust core](https://github.com/bgauryy/FreeLlama/blob/main/packages/rust-core/README.md) |
|
|
263
408
|
|
|
264
409
|
## License
|
|
265
410
|
|
|
266
|
-
Copyright (c) 2026 Guy Bary. Licensed under [Apache-2.0](LICENSE-APACHE) or [MIT](LICENSE-MIT),
|
|
411
|
+
Copyright (c) 2026 Guy Bary. Licensed under [Apache-2.0](https://github.com/bgauryy/FreeLlama/blob/main/LICENSE-APACHE) or [MIT](https://github.com/bgauryy/FreeLlama/blob/main/LICENSE-MIT),
|
|
267
412
|
at your option.
|
package/bin/freellama.js
CHANGED
|
@@ -1,5 +1,6 @@
|
|
|
1
1
|
#!/usr/bin/env node
|
|
2
|
-
// Launcher so `npx @octocodeai/freellama` works:
|
|
2
|
+
// Launcher so `npx @octocodeai/freellama` works: hands the process to the compiled Rust binary, or,
|
|
3
|
+
// for the agent commands (run, chat, gateway…), to the agent CLI in Node.
|
|
3
4
|
//
|
|
4
5
|
// The binary is platform-specific and compiled by Cargo, so it is shipped in the tarball rather
|
|
5
6
|
// than built on install — an install-time `cargo build` would need a Rust toolchain on every
|
|
@@ -27,39 +28,78 @@ try {
|
|
|
27
28
|
// Optional packages for other platforms are intentionally absent after install.
|
|
28
29
|
}
|
|
29
30
|
|
|
30
|
-
|
|
31
|
-
|
|
31
|
+
// `freellama run`, `chat`, `gateway`… run in Node: they reuse the MCP server's workflows, model
|
|
32
|
+
// picks, prompts and checks (packages/mcp/src/agent-cli), installed with this package as a
|
|
33
|
+
// dependency. On a terminal, `status` is their human view; piped or with --json it stays the
|
|
34
|
+
// binary's JSON receipt, so scripts keep working (and it falls back to the binary if the agent
|
|
35
|
+
// CLI is missing).
|
|
36
|
+
const AGENT_COMMANDS = new Set(["run", "chat", "gateway", "workflows", "job", "tool", "tools"]);
|
|
37
|
+
const args = process.argv.slice(2);
|
|
38
|
+
const agentCommand = AGENT_COMMANDS.has(args[0]);
|
|
39
|
+
const humanStatus = args[0] === "status" && process.stdout.isTTY === true && !args.includes("--json");
|
|
40
|
+
const agent = agentCommand || humanStatus ? agentCli() : undefined;
|
|
41
|
+
|
|
42
|
+
if (agent) {
|
|
43
|
+
hand(process.execPath, [agent, ...args]);
|
|
44
|
+
} else if (agentCommand) {
|
|
32
45
|
console.error(
|
|
33
|
-
`freellama:
|
|
34
|
-
|
|
35
|
-
"Build it from a checkout with:\n cargo build --release\n" +
|
|
36
|
-
"Reinstall without --omit=optional. From a source checkout, run `cargo build --release`.",
|
|
46
|
+
`freellama: \`${args[0]}\` runs in Node from @octocodeai/freellama-mcp-server, which was not found.\n` +
|
|
47
|
+
"Reinstall @octocodeai/freellama (it depends on it), or from a checkout run `yarn build`.",
|
|
37
48
|
);
|
|
38
49
|
process.exit(1);
|
|
50
|
+
} else {
|
|
51
|
+
const binary = candidates.find((p) => existsSync(p));
|
|
52
|
+
if (!binary) {
|
|
53
|
+
console.error(
|
|
54
|
+
`freellama: no binary for ${process.platform}-${process.arch}.\n` +
|
|
55
|
+
`Looked in:\n${candidates.map((c) => ` ${c}`).join("\n")}\n` +
|
|
56
|
+
"Build it from a checkout with:\n cargo build --release\n" +
|
|
57
|
+
"Reinstall without --omit=optional. From a source checkout, run `cargo build --release`.",
|
|
58
|
+
);
|
|
59
|
+
process.exit(1);
|
|
60
|
+
}
|
|
61
|
+
// The binary's `status` always prints JSON and has no --json flag: the flag only keeps the
|
|
62
|
+
// human view away, so it is not passed on.
|
|
63
|
+
hand(binary, args[0] === "status" ? args.filter((arg) => arg !== "--json") : args);
|
|
39
64
|
}
|
|
40
65
|
|
|
41
|
-
|
|
42
|
-
|
|
43
|
-
|
|
44
|
-
|
|
45
|
-
|
|
46
|
-
|
|
47
|
-
|
|
48
|
-
|
|
49
|
-
|
|
50
|
-
|
|
51
|
-
});
|
|
66
|
+
/** The agent CLI: a checkout's build first, then the installed MCP package's. */
|
|
67
|
+
function agentCli() {
|
|
68
|
+
const local = path.join(root, "..", "mcp", "dist", "agent-cli.js");
|
|
69
|
+
if (existsSync(local)) return local;
|
|
70
|
+
try {
|
|
71
|
+
const file = path.join(path.dirname(requireFromHere.resolve("@octocodeai/freellama-mcp-server/package.json")), "dist", "agent-cli.js");
|
|
72
|
+
return existsSync(file) ? file : undefined;
|
|
73
|
+
} catch {
|
|
74
|
+
return undefined;
|
|
75
|
+
}
|
|
52
76
|
}
|
|
53
77
|
|
|
54
|
-
|
|
55
|
-
|
|
56
|
-
|
|
57
|
-
|
|
58
|
-
|
|
78
|
+
/**
|
|
79
|
+
* Run `file` with stdio passed through, forwarding termination signals and the exit code: this is
|
|
80
|
+
* a launcher, not a wrapper that reinterprets output.
|
|
81
|
+
*/
|
|
82
|
+
function hand(file, argv) {
|
|
83
|
+
const child = spawn(file, argv, { stdio: "inherit" });
|
|
84
|
+
// Forward termination to the child. Without this, a supervisor (or `kill`) that signals the npx
|
|
85
|
+
// process by PID kills only this launcher, and `freellama serve` is orphaned still holding its
|
|
86
|
+
// listener — the next start then fails with "address already in use" and nothing explains why.
|
|
87
|
+
// Ctrl-C already reaches both via the process group; this covers the targeted-signal case.
|
|
88
|
+
for (const signal of ["SIGINT", "SIGTERM", "SIGHUP"]) {
|
|
89
|
+
process.on(signal, () => {
|
|
90
|
+
if (!child.killed) child.kill(signal);
|
|
91
|
+
});
|
|
59
92
|
}
|
|
60
|
-
|
|
61
|
-
|
|
62
|
-
child.on("
|
|
63
|
-
|
|
64
|
-
|
|
65
|
-
}
|
|
93
|
+
// Reproduce the shell's own convention for a signalled child (128 + signal number) so callers can
|
|
94
|
+
// tell "interrupted" from "failed"; both used to collapse into a bare 1.
|
|
95
|
+
child.on("exit", (code, signal) => {
|
|
96
|
+
if (signal) {
|
|
97
|
+
process.exit(128 + (os.constants.signals[signal] ?? 15));
|
|
98
|
+
}
|
|
99
|
+
process.exit(code ?? 0);
|
|
100
|
+
});
|
|
101
|
+
child.on("error", (err) => {
|
|
102
|
+
console.error(`freellama: failed to start ${file}: ${err.message}`);
|
|
103
|
+
process.exit(1);
|
|
104
|
+
});
|
|
105
|
+
}
|
package/package.json
CHANGED
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
{
|
|
2
2
|
"name": "@octocodeai/freellama",
|
|
3
|
-
"version": "0.
|
|
3
|
+
"version": "0.12.0",
|
|
4
4
|
"description": "Local Ollama model gateway, router, and benchmarker — CLI. Wraps the compiled Rust binary from packages/rust-core.",
|
|
5
5
|
"repository": {
|
|
6
6
|
"type": "git",
|
|
@@ -35,12 +35,15 @@
|
|
|
35
35
|
},
|
|
36
36
|
"author": "Guy Bary",
|
|
37
37
|
"license": "Apache-2.0 OR MIT",
|
|
38
|
+
"dependencies": {
|
|
39
|
+
"@octocodeai/freellama-mcp-server": "0.12.0"
|
|
40
|
+
},
|
|
38
41
|
"optionalDependencies": {
|
|
39
|
-
"@octocodeai/freellama-native-darwin-arm64": "0.
|
|
40
|
-
"@octocodeai/freellama-native-linux-arm64-gnu": "0.
|
|
41
|
-
"@octocodeai/freellama-native-linux-x64-gnu": "0.
|
|
42
|
-
"@octocodeai/freellama-native-win32-arm64-msvc": "0.
|
|
43
|
-
"@octocodeai/freellama-native-win32-x64-msvc": "0.
|
|
42
|
+
"@octocodeai/freellama-native-darwin-arm64": "0.12.0",
|
|
43
|
+
"@octocodeai/freellama-native-linux-arm64-gnu": "0.12.0",
|
|
44
|
+
"@octocodeai/freellama-native-linux-x64-gnu": "0.12.0",
|
|
45
|
+
"@octocodeai/freellama-native-win32-arm64-msvc": "0.12.0",
|
|
46
|
+
"@octocodeai/freellama-native-win32-x64-msvc": "0.12.0"
|
|
44
47
|
},
|
|
45
48
|
"publishConfig": {
|
|
46
49
|
"access": "public",
|