@liustack/modlens 2.7.9 → 2.7.11
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.md +30 -50
- package/README.zh-CN.md +30 -50
- package/dist/main.js +1 -1
- package/package.json +1 -1
- package/skills/modlens/SKILL.md +3 -3
package/README.md
CHANGED
|
@@ -9,75 +9,55 @@
|
|
|
9
9
|
<p><a href="./README.zh-CN.md">简体中文</a></p>
|
|
10
10
|
</div>
|
|
11
11
|
|
|
12
|
-
DeepSeek-V4-Flash gives you a lot of model for very little money: fast,
|
|
12
|
+
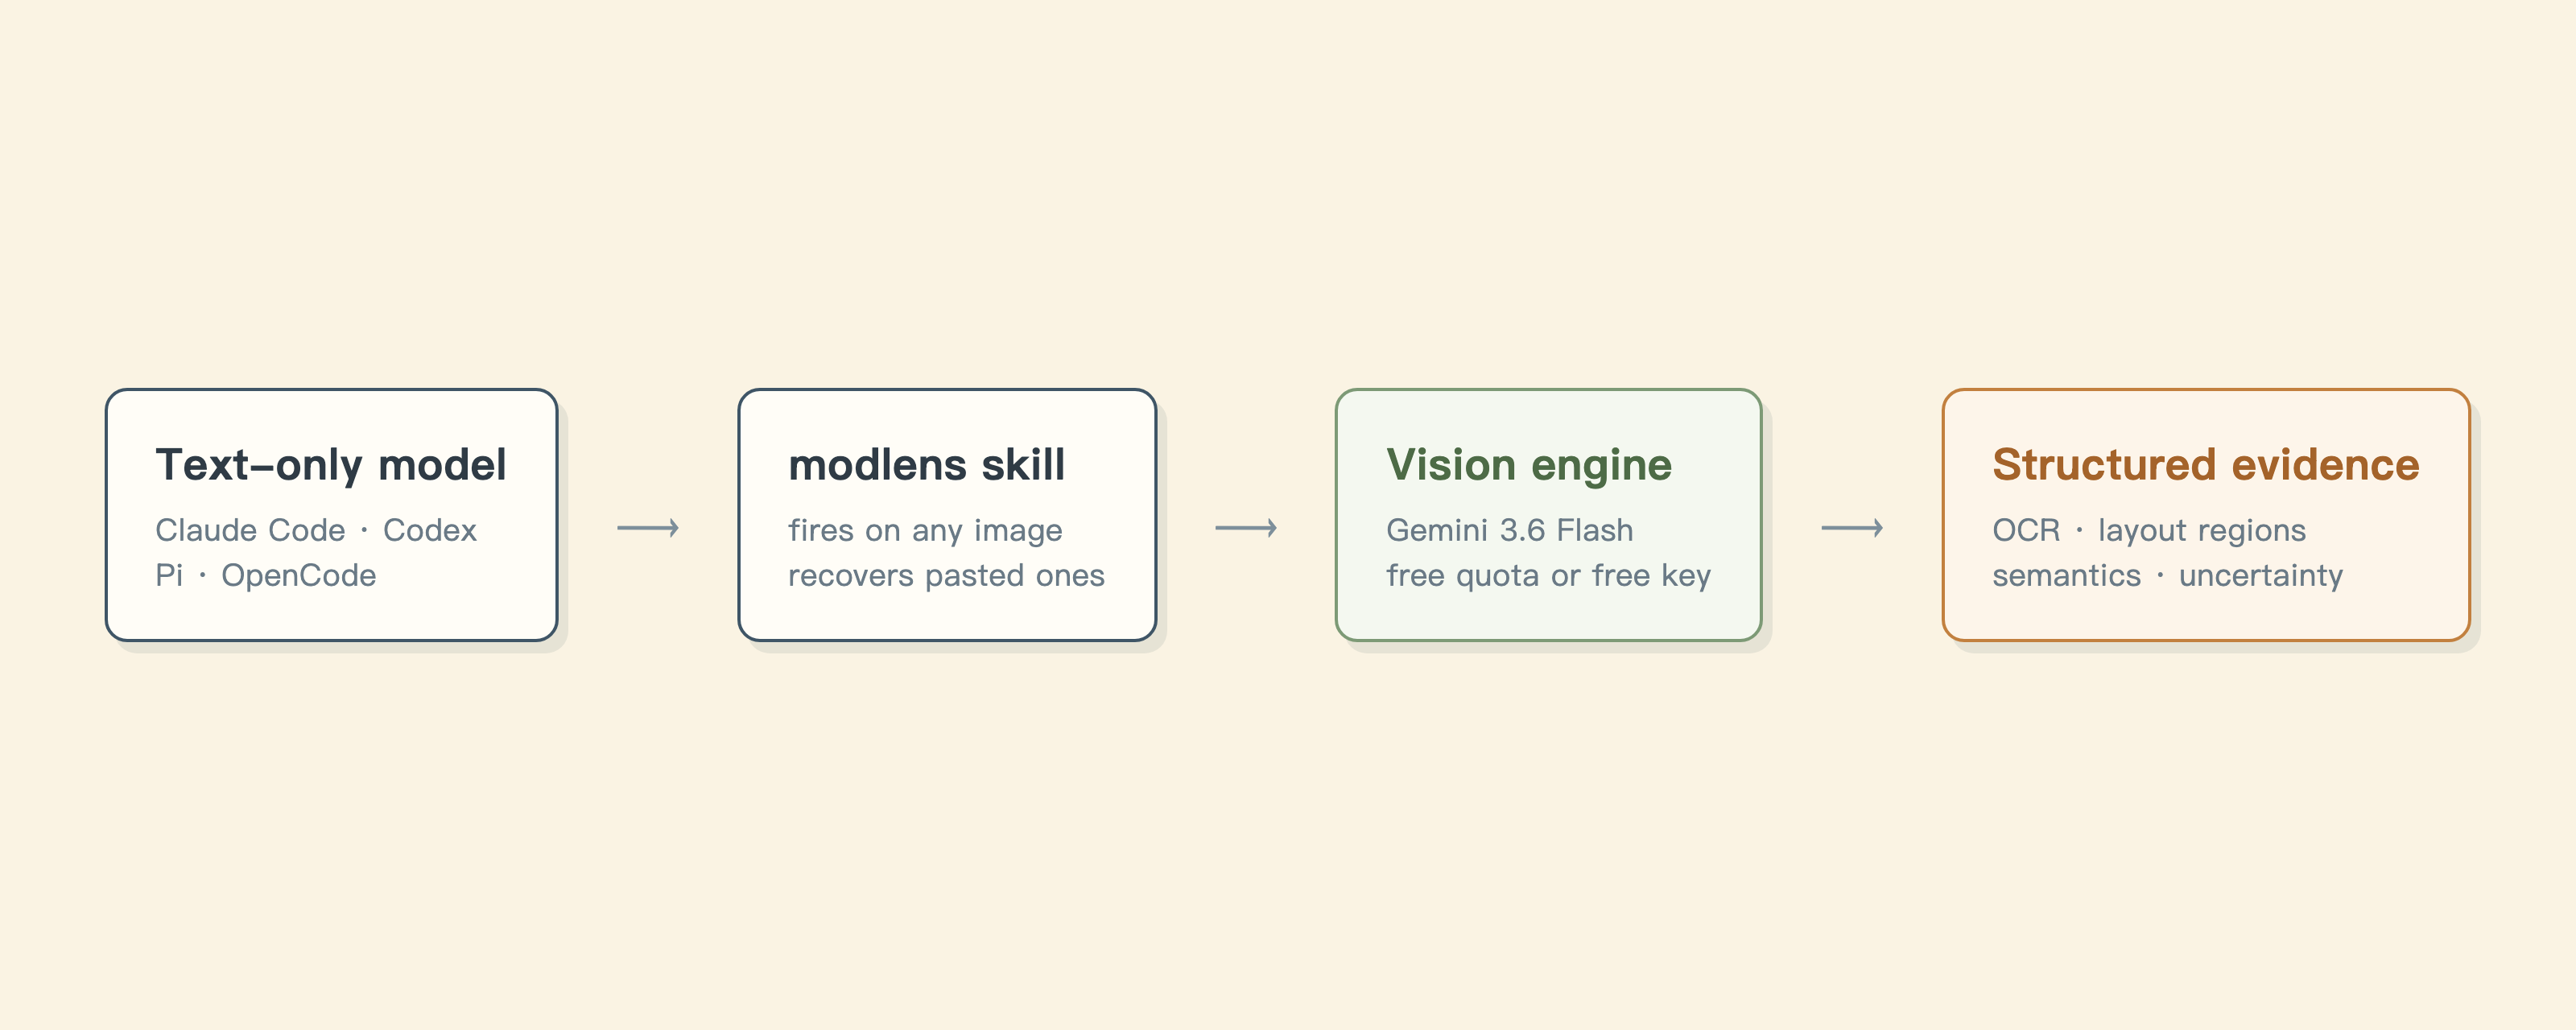
DeepSeek-V4-Flash gives you a lot of model for very little money: fast, cheap, capable, and blind. It is not just DeepSeek either. Any text-only model running inside Codex, Claude Code, Pi, or OpenCode hits the same wall: you throw it a screenshot of an error and it sees nothing.
|
|
13
13
|
|
|
14
|
-
ModLens
|
|
14
|
+
ModLens gives it sight, and **you just paste**. Every other bridge makes you save the image to a file and then mention the path in the chat. ModLens pulls the pasted image back out of session storage instead. What comes back is not "this is a screenshot of an error", it is evidence you can quote: every word in the image transcribed, the layout cut into regions in reading order, and the entities and relations on screen listed separately.
|
|
15
15
|
|
|
16
|
-
|
|
17
|
-
|
|
18
|
-
- **You just paste.** Every other bridge makes you save a file and report its path. ModLens pulls the pasted image back out of session storage.
|
|
19
|
-
- **Evidence, not an impression.** Full OCR text, layout regions in reading order, semantic entities, visual clues. Your model can quote specifics.
|
|
20
|
-
- **It says when it cannot read something.** Anything uncertain lands in `uncertainty` rather than being invented. Pixel coordinates and confidence scores, the two things models fabricate most, were dropped in v2.
|
|
21
|
-
- **No model swap, no config changes, no local proxy.** You picked your model for price and reasoning, not eyesight. That choice stays.
|
|
22
|
-
- **Starts with no key, gets faster with a free one.** agy needs no key at all, and a free AI Studio Gemini key takes three minutes and reads an image in 5-10 seconds.
|
|
23
|
-
- **Install once, works in four harnesses.** Verified in Claude Code, Codex, Pi, and OpenCode.
|
|
24
|
-
|
|
25
|
-
**Requirements**: Node 18+ (22.5+ for OpenCode paste recovery), macOS or Linux. Hit a problem? [Troubleshooting](docs/troubleshooting.md) lists every error this CLI prints, with causes and fixes.
|
|
26
|
-
|
|
27
|
-
## You can just paste the image
|
|
28
|
-
|
|
29
|
-
Every other bridge makes you save the image to a file first, then mention the path in the chat. ModLens lets you paste it.
|
|
30
|
-
|
|
31
|
-
That is not laziness on their part. Pasting is handled end to end by the client: the moment an image lands in the chat box it is encoded and sent, and a vision MCP server never gets a chance to step in, which is why their docs can only tell you to save the file and report the path. ModLens takes the other route. Before those bytes are ever sent, the harness has already written them to local session storage, so the skill goes there, pulls them back out into a real file, and feeds that to the vision engine. You do nothing, and the model answers with the full image instead of asking you for a path.
|
|
32
|
-
|
|
33
|
-
Verified on real machines across four harnesses: Claude Code pinpoints the exact session from its injected session id, Pi stores sessions the same way, OpenCode swaps in SQLite, and Codex's pasted images already carry a temp path so the path-tag route handles them. Before touching anything, `recover-paste` works out which harness it is running inside, by walking the process ancestry and checking environment fingerprints, and reads only that harness's storage, so another tool's stale sessions can't impersonate it.
|
|
34
|
-
|
|
35
|
-
Side by side:
|
|
36
|
-
|
|
37
|
-
| | Swap in a multimodal model | Vision MCP servers | ModLens |
|
|
38
|
-
| :-- | :-- | :-- | :-- |
|
|
39
|
-
| Your chosen model | has to change | stays | stays |
|
|
40
|
-
| An image pasted into the chat | visible if the model supports it | not reachable, their docs say save a file and report the path | handled directly |
|
|
41
|
-
| What you get back | the model's own reading | usually a description | OCR text, layout regions, semantics, visual clues |
|
|
42
|
-
| Where it cannot read | may invent | may invent | says so in `uncertainty` |
|
|
43
|
-
| Cost | multimodal model pricing | usually per API call | agy's free quota, or a free Gemini key |
|
|
44
|
-
| Setup | change config, change model | install a server, edit config | one CLI or one skill |
|
|
16
|
+
No model swap, no prompt surgery, no local proxy. It starts with no key at all.
|
|
45
17
|
|
|
46
|
-
|
|
18
|
+
|
|
47
19
|
|
|
48
|
-
##
|
|
20
|
+
## Three steps
|
|
49
21
|
|
|
50
|
-
**1. Install the skill.**
|
|
22
|
+
**1. Install the skill.** Tell your agent (Claude Code, Codex, OpenClaw, and Cursor all take this):
|
|
51
23
|
|
|
52
24
|
```text
|
|
53
25
|
Install the skill from https://github.com/liustack/modlens
|
|
54
26
|
```
|
|
55
27
|
|
|
56
|
-
|
|
28
|
+
Or do it yourself: `npx -y skills add liustack/modlens`
|
|
57
29
|
|
|
58
|
-
|
|
59
|
-
npx -y skills add liustack/modlens
|
|
60
|
-
```
|
|
61
|
-
|
|
62
|
-
Harnesses look for skills in different places: Claude Code reads `~/.claude/skills/`, Codex reads `~/.codex/skills/`, Pi and OpenCode read `~/.agents/skills/`. Symlinks work in all of them, so linking the skill folder once keeps every agent on the latest version.
|
|
63
|
-
|
|
64
|
-
**2. Wire up a vision engine.** Recommended: a free Gemini key from [aistudio.google.com](https://aistudio.google.com). Three minutes, no credit card, 5-10 seconds per image:
|
|
30
|
+
**2. Give it a vision engine.** A free Gemini key from [aistudio.google.com](https://aistudio.google.com) is the fast answer: three minutes, no credit card, 5 to 10 seconds per image.
|
|
65
31
|
|
|
66
32
|
```bash
|
|
67
33
|
modlens config set gemini-api.apiKey <key>
|
|
68
34
|
modlens config set provider gemini-api
|
|
69
35
|
```
|
|
70
36
|
|
|
71
|
-
Don't feel like typing those
|
|
37
|
+
Don't feel like typing those? Tell your agent "set my Gemini key in modlens" and it runs them. Skipping the sign-up is fine too: Antigravity CLI works with no key, it is just slower (15 to 40 seconds) and its free quota is tight.
|
|
72
38
|
|
|
73
|
-
|
|
39
|
+
**3. Use it.** Paste an image, or throw a path at it, and ask anything. The skill fires on its own.
|
|
74
40
|
|
|
75
|
-
|
|
76
|
-
curl -fsSL https://antigravity.google/cli/install.sh | bash
|
|
77
|
-
agy # opens browser sign-in, then exit
|
|
78
|
-
```
|
|
41
|
+
Requirements, in one line: Node 18+ (22.5+ for OpenCode paste recovery), macOS or Linux.
|
|
79
42
|
|
|
80
|
-
|
|
43
|
+
## Why pasting works here and nowhere else
|
|
44
|
+
|
|
45
|
+
Pasting is handled end to end by the client. The moment an image lands in the chat box it is encoded and sent, and a vision MCP server never gets a chance to step in, which is why their docs can only tell you to save the file and report the path.
|
|
46
|
+
|
|
47
|
+
ModLens takes the other route. Before those bytes are sent anywhere, the harness has already written them to local session storage. The skill goes there, pulls them back into a real file, and hands that to the vision engine. You do nothing, and the model gets the whole image instead of asking you for a path.
|
|
48
|
+
|
|
49
|
+
All four harnesses are verified on real machines: Claude Code pinpoints the exact session from its injected session id, Pi stores sessions the same way, OpenCode swaps in SQLite, and Codex's pasted images already carry a temp path, so the path-tag route handles them. Before touching anything, `recover-paste` works out which harness it is running inside (process ancestry, then environment fingerprints) and reads only that harness's storage, so a neighbouring project's old sessions cannot impersonate it. Recovered files are written 0600.
|
|
50
|
+
|
|
51
|
+
| | Swap in a multimodal model | Vision MCP servers | ModLens |
|
|
52
|
+
| :-- | :-- | :-- | :-- |
|
|
53
|
+
| Your chosen model | has to change | stays | stays |
|
|
54
|
+
| An image pasted into the chat | visible if the model supports it | out of reach, save a file and report the path | handled directly |
|
|
55
|
+
| What you get back | the model's own reading | usually a description | full transcription, layout regions, entities and relations, visual clues |
|
|
56
|
+
| Where it cannot read | may invent | may invent | says so in `uncertainty` |
|
|
57
|
+
| Cost | multimodal model pricing | usually per API call | agy's free quota, or a free Gemini key |
|
|
58
|
+
| Setup | change config, change model | install a server, edit config | one CLI or one skill |
|
|
59
|
+
|
|
60
|
+
The weaknesses sit here too: agy's free tier is a weekly quota and heavy use hits the wall (a free Gemini key sidesteps it). Session storage layouts are each harness's internals with no compatibility promise, so if recovery ever breaks, dragging the file in still works everywhere.
|
|
81
61
|
|
|
82
62
|
## See it work
|
|
83
63
|
|
|
@@ -213,7 +193,7 @@ Pointing OpenCode at DeepSeek takes two lines of setup: `opencode auth login`, p
|
|
|
213
193
|
## Why a bridge instead of a multimodal model?
|
|
214
194
|
|
|
215
195
|
- **Keep your model.** You picked DeepSeek-V4-Flash (or gpt-oss, or whatever else) for its price and its reasoning, not its eyesight. ModLens adds sight without touching that choice.
|
|
216
|
-
- **Evidence beats pixels.** Text models reason best over structured text, not raw pixels. ModLens hands them
|
|
196
|
+
- **Evidence beats pixels.** Text models reason best over structured text, not raw pixels. ModLens hands them the transcribed words, the segmented layout, and the extracted meaning, not a base64 blob.
|
|
217
197
|
- **Engines die, the bridge survives.** v1 ran on Gemini CLI's free tier until Google shut it down in June 2026. v2 moved to its successor, Antigravity CLI, behind the same provider interface, so the next engine swap costs one file, not a rewrite.
|
|
218
198
|
|
|
219
199
|
ModSearch, ModLens's sibling project, plays the same trick for web search and page fetching: [liustack/modsearch](https://github.com/liustack/modsearch).
|
package/README.zh-CN.md
CHANGED
|
@@ -9,75 +9,55 @@
|
|
|
9
9
|
<p><a href="./README.md">English</a></p>
|
|
10
10
|
</div>
|
|
11
11
|
|
|
12
|
-
DeepSeek-V4-Flash
|
|
12
|
+
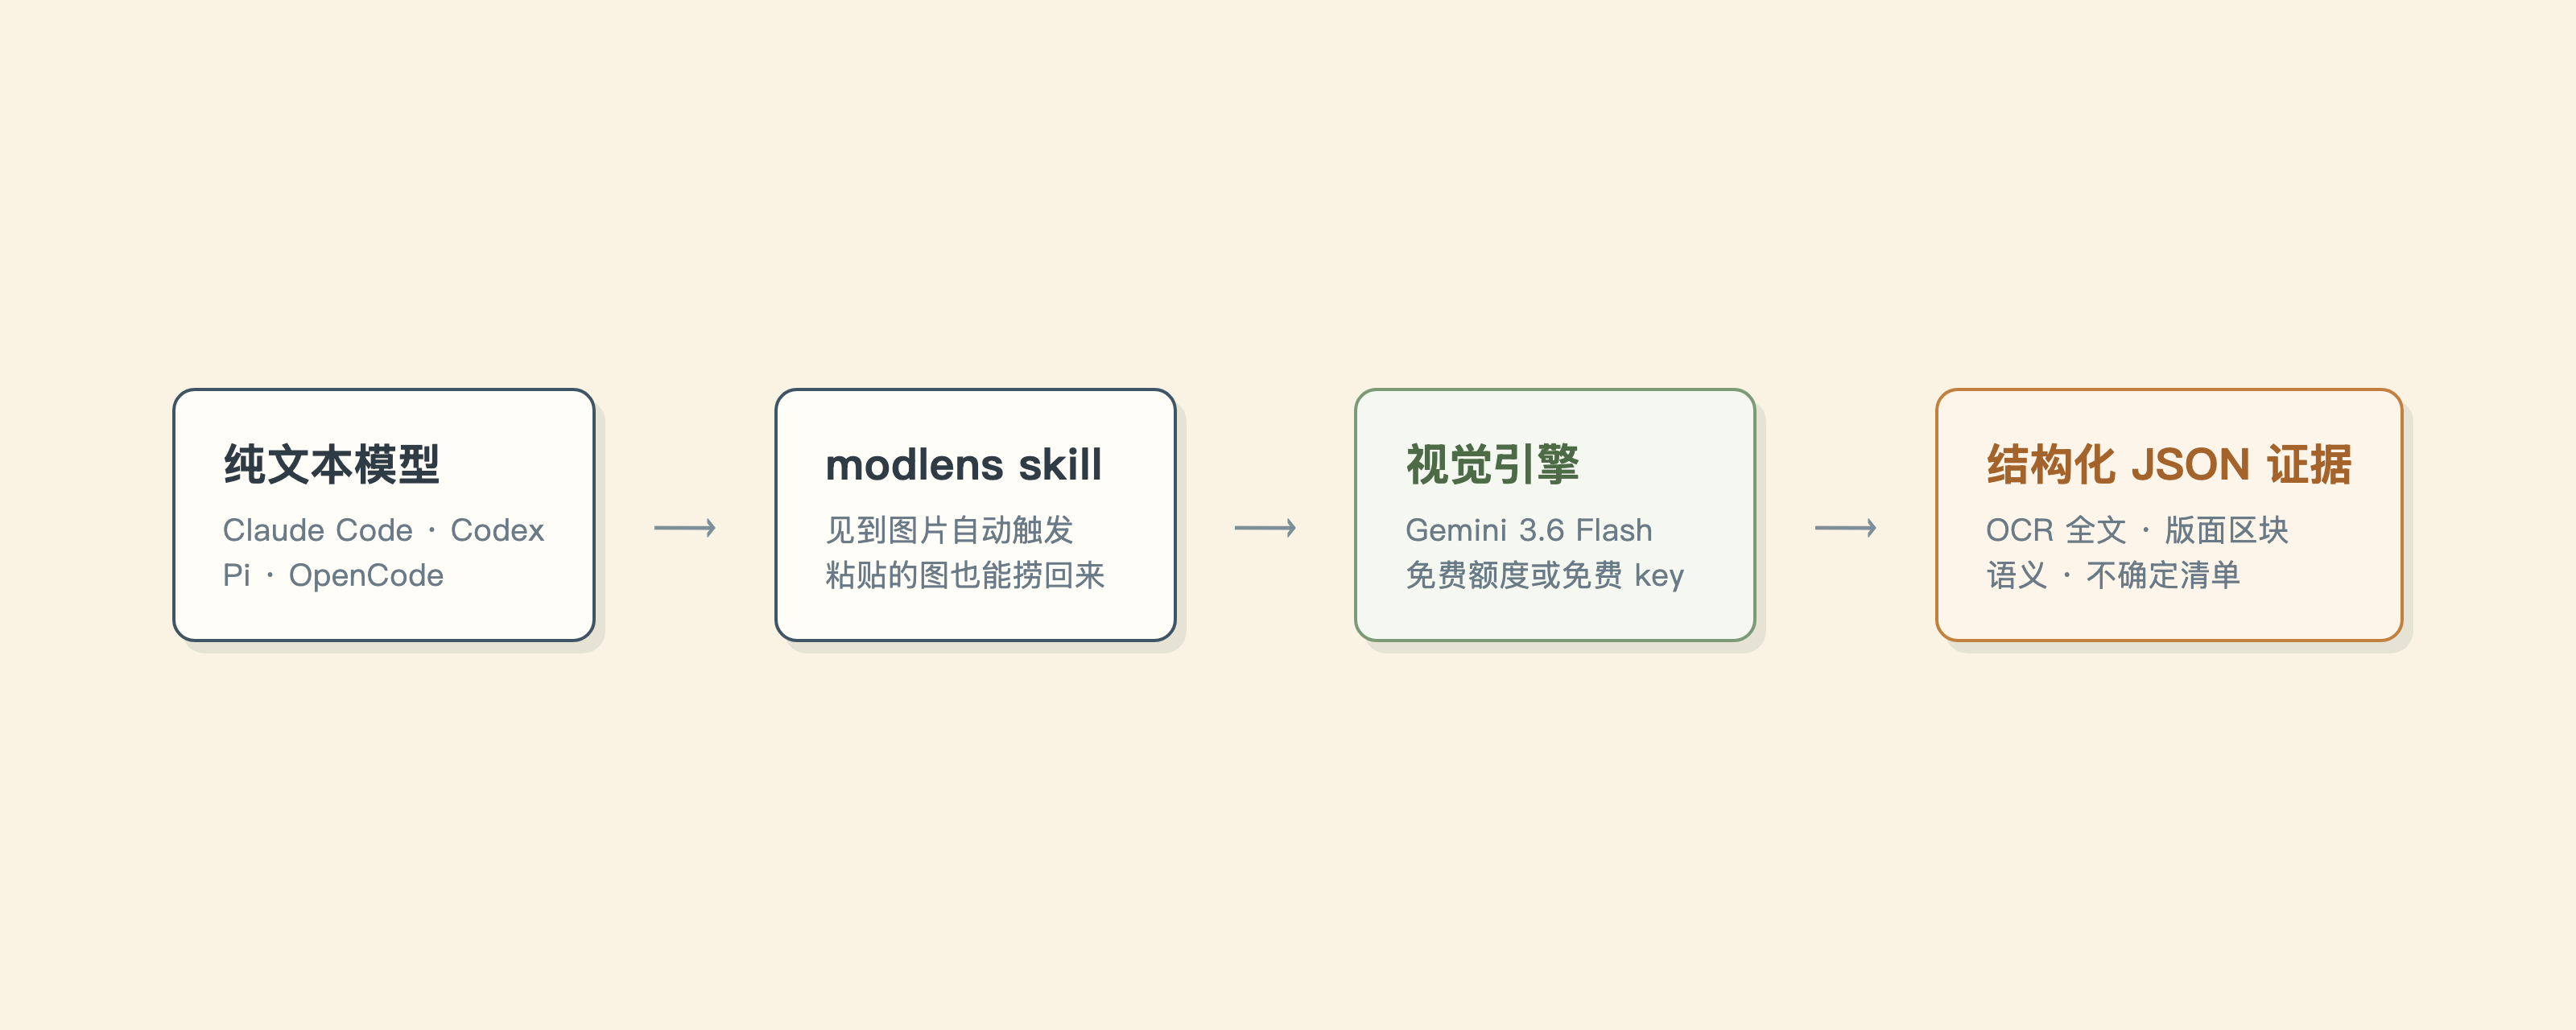
DeepSeek-V4-Flash 碗大又好吃,速度快、便宜、能打,唯独没有多模态。不止它,任何纯文本模型跑在 Codex、Claude Code、Pi、OpenCode 里,都撞同一堵墙:你甩过去一张报错截图,它看不见。
|
|
13
13
|
|
|
14
|
-
ModLens
|
|
14
|
+
ModLens 给它装上视力,而且**你直接粘贴就行**。别的方案都要你先把图存成文件、再在对话里报一句路径,ModLens 直接从会话存储里把粘贴的图捞回来。回来的不是一句「这是一张报错截图」,是能引用的证据:图里的字一句不落地抄下来,版面按阅读顺序切成区块,画面里的实体和关系单列一份。
|
|
15
15
|
|
|
16
|
-
|
|
17
|
-
|
|
18
|
-
- **你直接粘贴就行。** 别的方案让你先存成文件再报路径,ModLens 从会话存储里把粘贴的图捞回来。
|
|
19
|
-
- **给的是证据,不是印象。** OCR 全文、按阅读顺序排好的版面区块、语义实体、视觉线索,模型能引用具体内容。
|
|
20
|
-
- **读不准就说读不准。** 拿不准的地方进 `uncertainty`,不编。像素坐标和置信度分数这两样模型最爱编的,v2 直接删了。
|
|
21
|
-
- **不换模型,不改配置,不装代理。** 你选 DeepSeek 图的是价格和推理,不是视力,这个选择不用动。
|
|
22
|
-
- **零 key 起步,想快就领个免费 key。** agy 不要 key,AI Studio 的免费 Gemini key 三分钟到手,识图 5-10 秒。
|
|
23
|
-
- **装一次,四家 harness 通用。** Claude Code、Codex、Pi、OpenCode 都验证过。
|
|
24
|
-
|
|
25
|
-
**环境要求**:Node 18+(OpenCode 的粘贴恢复需要 22.5+),macOS 或 Linux。 出问题看[故障排查](docs/troubleshooting.md),里面按报错原文列了每一条的成因和解法。
|
|
26
|
-
|
|
27
|
-
## 你可以直接粘贴图片
|
|
28
|
-
|
|
29
|
-
别的方案让你先把图存成文件,再在对话里报一句路径。ModLens 让你直接粘贴。
|
|
16
|
+
模型不用换,提示词不用改,本地不装代理。零 key 就能开跑。
|
|
30
17
|
|
|
31
|
-
|
|
32
|
-
|
|
33
|
-
四家 harness 真机验证过:Claude Code 按注入的会话 ID 精确定位,Pi 的存储路数和它同构,OpenCode 换成了 SQLite,Codex 的粘贴图本来就带临时路径,走路径标签就行。动手之前 `recover-paste` 会先认清自己跑在哪一家(查进程祖先链,核对环境变量指纹),只读那一家的存储,别家的旧会话冒充不了。
|
|
34
|
-
|
|
35
|
-
放在一起看更清楚:
|
|
36
|
-
|
|
37
|
-
| | 换个多模态模型 | 识图类 MCP server | ModLens |
|
|
38
|
-
| :-- | :-- | :-- | :-- |
|
|
39
|
-
| 你选的模型 | 得换掉 | 不用换 | 不用换 |
|
|
40
|
-
| 粘贴进对话的图 | 模型支持就能看 | 接不住,文档让你先存文件报路径 | 直接接住 |
|
|
41
|
-
| 拿到手的是什么 | 模型自己的理解 | 通常是一段描述 | OCR 全文、版面区块、语义、视觉线索 |
|
|
42
|
-
| 读不准的地方 | 可能编 | 可能编 | 进 `uncertainty`,明说读不准 |
|
|
43
|
-
| 花费 | 多模态模型的价格 | 多数按 API 计费 | agy 免费额度,或免费 Gemini key |
|
|
44
|
-
| 上手 | 改配置换模型 | 装 server、改配置 | 一个 CLI 或一个 skill |
|
|
45
|
-
|
|
46
|
-
诚实说短板:agy 的免费额度是周配额,重度用会撞墙(换成免费 Gemini key 就绕开了)。会话存储格式是各家 harness 的内部实现,没有兼容承诺,哪天捞不动了,拖文件永远是保底。
|
|
18
|
+
|
|
47
19
|
|
|
48
|
-
##
|
|
20
|
+
## 三步用起来
|
|
49
21
|
|
|
50
|
-
|
|
22
|
+
**一、装 skill。** 跟你的 agent 说一句就行(Claude Code、Codex、OpenClaw、Cursor 都吃这套):
|
|
51
23
|
|
|
52
24
|
```text
|
|
53
25
|
安装这个 skill https://github.com/liustack/modlens
|
|
54
26
|
```
|
|
55
27
|
|
|
56
|
-
|
|
28
|
+
自己动手也行:`npx -y skills add liustack/modlens`
|
|
57
29
|
|
|
58
|
-
|
|
59
|
-
npx -y skills add liustack/modlens
|
|
60
|
-
```
|
|
61
|
-
|
|
62
|
-
各家 harness 找 skill 的位置不一样:Claude Code 读 `~/.claude/skills/`,Codex 读 `~/.codex/skills/`,Pi 和 OpenCode 读 `~/.agents/skills/`。软链接在哪家都好使,把 skill 目录链一次,各家永远用最新版。
|
|
63
|
-
|
|
64
|
-
**2. 接一个视觉引擎。** 推荐去 [aistudio.google.com](https://aistudio.google.com) 领个免费 Gemini key,三分钟,不要信用卡,出图 5-10 秒:
|
|
30
|
+
**二、接一个视觉引擎。** 推荐去 [aistudio.google.com](https://aistudio.google.com) 领个免费 Gemini key,三分钟,不要信用卡,识图 5 到 10 秒:
|
|
65
31
|
|
|
66
32
|
```bash
|
|
67
33
|
modlens config set gemini-api.apiKey <key>
|
|
68
34
|
modlens config set provider gemini-api
|
|
69
35
|
```
|
|
70
36
|
|
|
71
|
-
懒得敲这两行?跟 agent
|
|
37
|
+
懒得敲这两行?跟 agent 说「帮我把 Gemini key 配进 modlens」,它自己会跑。不想注册也行,装上 Antigravity CLI 零 key 开跑,代价是慢(15 到 40 秒),免费额度也紧。
|
|
72
38
|
|
|
73
|
-
|
|
39
|
+
**三、直接用。** 粘一张图,或者甩个图片路径,随便问。skill 自己会触发。
|
|
74
40
|
|
|
75
|
-
|
|
76
|
-
|
|
77
|
-
|
|
78
|
-
|
|
41
|
+
环境要求就一行:Node 18+(OpenCode 的粘贴恢复需要 22.5+),macOS 或 Linux。
|
|
42
|
+
|
|
43
|
+
## 粘贴这件事,为什么只有它接得住
|
|
44
|
+
|
|
45
|
+
粘贴从头到尾是客户端办的事。图一进对话框就被转码发走,识图类 MCP server 连插手的机会都没有,所以它们的文档只能教你:先存文件,再报路径。
|
|
46
|
+
|
|
47
|
+
ModLens 走的是另一条路。图片字节在发给模型之前,早被 harness 原样写进了本地会话存储。skill 直接去那儿把它捞回来落成文件,喂给视觉引擎。你什么都不用做,模型拿到的是完整图片,而不是一句「麻烦告诉我路径」。
|
|
48
|
+
|
|
49
|
+
四家 harness 都在真机上验证过:Claude Code 按注入的会话 ID 精确定位,Pi 的存储路数和它同构,OpenCode 换成了 SQLite,Codex 的粘贴图本来就带临时路径、走路径标签即可。动手之前 `recover-paste` 会先认清自己跑在哪一家(查进程祖先链,核对环境变量指纹),只读那一家的存储,隔壁项目的旧会话冒充不了,捞出来的文件权限是 0600。
|
|
50
|
+
|
|
51
|
+
| | 换个多模态模型 | 识图类 MCP server | ModLens |
|
|
52
|
+
| :-- | :-- | :-- | :-- |
|
|
53
|
+
| 你选的模型 | 得换掉 | 不用换 | 不用换 |
|
|
54
|
+
| 粘贴进对话的图 | 模型支持就能看 | 接不住,得先存文件报路径 | 直接接住 |
|
|
55
|
+
| 拿到手的是什么 | 模型自己的理解 | 通常一段描述 | 全文转录、版面区块、实体关系、视觉线索 |
|
|
56
|
+
| 读不准的地方 | 可能编 | 可能编 | 进 `uncertainty`,明说读不准 |
|
|
57
|
+
| 花费 | 多模态模型的价格 | 多数按 API 计费 | agy 免费额度,或免费 Gemini key |
|
|
58
|
+
| 上手 | 改配置换模型 | 装 server、改配置 | 一个 CLI 或一个 skill |
|
|
79
59
|
|
|
80
|
-
|
|
60
|
+
短板也摆这儿:agy 的免费额度是周配额,重度用会撞墙(换成免费 Gemini key 就绕开了)。会话存储格式是各家 harness 的内部实现,没有兼容承诺,哪天捞不动了,拖文件永远是保底。
|
|
81
61
|
|
|
82
62
|
## 看看效果
|
|
83
63
|
|
|
@@ -213,7 +193,7 @@ OpenCode 接 DeepSeek 只要两步:`opencode auth login` 选 DeepSeek 贴上 k
|
|
|
213
193
|
## 为什么外挂,而不是换多模态模型?
|
|
214
194
|
|
|
215
195
|
- **模型不用换。** 你选 DeepSeek-V4-Flash(或 gpt-oss,或别的什么)图的是价格和推理能力,不是视力。ModLens 只加视力,不碰这个选择。
|
|
216
|
-
- **证据强过像素。**
|
|
196
|
+
- **证据强过像素。** 文本模型最擅长在结构化文本上推理,不是盯着原始像素。ModLens 递过去的是转录好的文字、切好的版面、拆好的语义,不是一坨 base64。
|
|
217
197
|
- **引擎会死,桥不会死。** v1 跑在 Gemini CLI 免费档上,2026 年 6 月被 Google 一刀切停掉。v2 换到继任者 Antigravity CLI,还是同一个 provider 接口,下次再换引擎,改一个文件就行,不用重写。
|
|
218
198
|
|
|
219
199
|
姊妹项目 ModSearch 用同一招补上联网搜索和网页抓取:[liustack/modsearch](https://github.com/liustack/modsearch)。
|
package/dist/main.js
CHANGED
|
@@ -1478,7 +1478,7 @@ function recoverPastedImages(options = {}) {
|
|
|
1478
1478
|
return result;
|
|
1479
1479
|
}
|
|
1480
1480
|
const program = new Command();
|
|
1481
|
-
program.name("modlens").description("Plug-in vision for text-only LLMs: image in, structured JSON evidence out").version("2.7.
|
|
1481
|
+
program.name("modlens").description("Plug-in vision for text-only LLMs: image in, structured JSON evidence out").version("2.7.11");
|
|
1482
1482
|
program.command("analyze", { isDefault: true }).description("Analyze an image into structured JSON evidence (default command)").requiredOption("-i, --input <path|url>", "Input image path or https URL").option("-o, --output <path>", "Write result JSON to a file").option("-m, --model <name>", "Provider model name").option("-p, --provider <name>", `Vision provider (${listProviders().join(", ")})`).option("--prompt <text>", "Extra focus for this image").option("--timeout <ms>", "Provider timeout in milliseconds", "180000").option("--provider-bin <path>", "Provider binary path (default: agy)").option("--workdir <path>", "Working directory for the provider").action(async (options) => {
|
|
1483
1483
|
try {
|
|
1484
1484
|
const timeoutMs = Number.parseInt(options.timeout, 10);
|
package/package.json
CHANGED
package/skills/modlens/SKILL.md
CHANGED
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
---
|
|
2
2
|
name: modlens
|
|
3
|
-
description: "Plug-in vision for text-only models. Use whenever the user shares an image (local path, screenshot, photo, chart, document scan, or image URL) and the active model cannot see images or has no vision tool. Runs the modlens CLI to convert the image into structured JSON evidence:
|
|
3
|
+
description: "Plug-in vision for text-only models. Use whenever the user shares an image (local path, screenshot, photo, chart, document scan, or image URL) and the active model cannot see images or has no vision tool. Runs the modlens CLI to convert the image into structured JSON evidence: every word transcribed, layout regions, semantics, visual clues. Also use when the user asks how to install, configure, or switch modlens providers (Gemini API key, OpenAI-compatible endpoints, Claude API or Claude Code CLI)."
|
|
4
4
|
allowed-tools:
|
|
5
5
|
- Bash
|
|
6
6
|
---
|
|
@@ -11,7 +11,7 @@ Use this skill when:
|
|
|
11
11
|
|
|
12
12
|
- The user provides an image path or image URL and asks anything about it
|
|
13
13
|
- The active model has no native vision (text-only model in a coding agent)
|
|
14
|
-
- You need
|
|
14
|
+
- You need the text inside an image, its layout, or a chart's structure as evidence before reasoning
|
|
15
15
|
- The user asks how to configure modlens, get an API key for it, or switch its provider: follow `references/configure.md` and run the commands for them
|
|
16
16
|
|
|
17
17
|
Do not use this skill for:
|
|
@@ -91,7 +91,7 @@ Harnesses rarely hand you a clean path. First identify which harness you are in,
|
|
|
91
91
|
Top level: `{ image, provider, result, meta }`. Inside `result`:
|
|
92
92
|
|
|
93
93
|
- `summary`: one-paragraph description of the image
|
|
94
|
-
- `ocr.full_text` + `ocr.lines[]`: transcribed
|
|
94
|
+
- `ocr.full_text` + `ocr.lines[]`: every word in the image, transcribed (the field keeps the familiar `ocr` name, though a vision model does the reading, not an OCR engine)
|
|
95
95
|
- `layout.regions[]`: typed blocks (`title`, `paragraph`, `table`, `chart`, `code`, ...) in reading order
|
|
96
96
|
- `semantics`: scene, intent, entities, relations
|
|
97
97
|
- `visual`: colors and style clues
|