@liustack/modlens 0.1.0 → 2.1.0
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.md +138 -41
- package/README.zh-CN.md +141 -36
- package/dist/main.js +693 -136
- package/package.json +4 -3
- package/skills/modlens/SKILL.md +53 -33
- package/skills/modlens/references/output-schema.md +28 -24
package/README.md
CHANGED
|
@@ -1,76 +1,173 @@
|
|
|
1
|
-
|
|
1
|
+
<div align="center">
|
|
2
|
+
<img src="https://raw.githubusercontent.com/liustack/modlens/main/assets/banner.jpg" width="100%" alt="ModLens, plug-in vision for text-only LLMs" />
|
|
3
|
+
<h1>ModLens</h1>
|
|
4
|
+
<p><b>Free plug-in vision for your text-only LLM.</b></p>
|
|
5
|
+
<p>
|
|
6
|
+
<a href="https://www.npmjs.com/package/@liustack/modlens"><img src="https://img.shields.io/npm/v/@liustack/modlens" alt="npm"></a>
|
|
7
|
+
<a href="LICENSE"><img src="https://img.shields.io/badge/license-MIT-blue.svg" alt="License"></a>
|
|
8
|
+
</p>
|
|
9
|
+
<p><a href="./README.zh-CN.md">简体中文</a></p>
|
|
10
|
+
</div>
|
|
11
|
+
|
|
12
|
+
DeepSeek-V4-Flash gives you a lot of model for very little money: fast, strong, and its one real flaw is no multimodal. And it's not just DeepSeek. Every text-only model running inside Codex, Claude Code, Pi Agent, or OpenClaw hits the same wall.
|
|
13
|
+
|
|
14
|
+
ModLens fixes this the lightest way possible. It never touches your config and never adds a local proxy. It's just a vision plug-in, usable as a CLI or as an Agent Skill, that turns any image into structured visual evidence: text, layout, regions, entities, relations, visual clues. Under the hood it runs on [Antigravity CLI](https://antigravity.google) (`agy`), whose vision comes from free-quota Gemini 3.6 Flash. And Gemini's image understanding is famously good, good enough to embarrass most flagships, Fable 5 included. How it works:
|
|
15
|
+
|
|
16
|
+
```text
|
|
17
|
+
text-only model in your agent harness ──▶ modlens skill (auto-triggers on images)
|
|
18
|
+
│
|
|
19
|
+
▼
|
|
20
|
+
agy · Gemini 3.6 Flash (free quota)
|
|
21
|
+
│
|
|
22
|
+
▼
|
|
23
|
+
structured JSON evidence ──▶ model answers with sight
|
|
24
|
+
```
|
|
2
25
|
|
|
3
|
-
|
|
26
|
+
## Quick start
|
|
4
27
|
|
|
5
|
-
|
|
28
|
+
**1. Install Antigravity CLI and sign in** (one-time):
|
|
6
29
|
|
|
7
|
-
|
|
30
|
+
```bash
|
|
31
|
+
curl -fsSL https://antigravity.google/cli/install.sh | bash
|
|
32
|
+
agy # opens browser sign-in, then exit
|
|
33
|
+
```
|
|
8
34
|
|
|
9
|
-
|
|
10
|
-
- Supports local image paths and remote image URLs
|
|
11
|
-
- Pluggable vision backend — ships with Gemini CLI; more engines (PaddleOCR, DeepSeek, etc.) planned
|
|
12
|
-
- Outputs machine-consumable JSON (OCR + layout + semantics + visual clues)
|
|
13
|
-
- Designed to be called from Agent Skills (Claude Code, Codex, Cursor, etc.)
|
|
35
|
+
**2. Install the skill.** Just tell your agent (Claude Code, Codex, OpenClaw, Cursor, ...):
|
|
14
36
|
|
|
15
|
-
|
|
37
|
+
```text
|
|
38
|
+
Install the skill from https://github.com/liustack/modlens
|
|
39
|
+
```
|
|
40
|
+
|
|
41
|
+
or do it yourself:
|
|
16
42
|
|
|
17
43
|
```bash
|
|
18
|
-
|
|
44
|
+
npx -y skills add liustack/modlens
|
|
19
45
|
```
|
|
20
46
|
|
|
21
|
-
|
|
47
|
+
**3. Use it.** Paste an image path into the CLI and ask anything. The skill fires on its own.
|
|
48
|
+
|
|
49
|
+
## See it work
|
|
22
50
|
|
|
23
51
|
```bash
|
|
24
|
-
|
|
25
|
-
gemini
|
|
52
|
+
npx @liustack/modlens -i workflow.jpg
|
|
26
53
|
```
|
|
27
54
|
|
|
28
|
-
|
|
55
|
+
Real output, truncated:
|
|
56
|
+
|
|
57
|
+
```json
|
|
58
|
+
{
|
|
59
|
+
"image": "/Users/leon/projects/liustack/assets/loop.jpg",
|
|
60
|
+
"provider": "antigravity-cli",
|
|
61
|
+
"result": {
|
|
62
|
+
"summary": "A workflow diagram with four nodes connected by labeled arrows.",
|
|
63
|
+
"ocr": {
|
|
64
|
+
"full_text": "/shaping\nBEFORE YOU BUILD\n\n/coding\nWHILE YOU BUILD\n\nIT BREAKS\n/dig\nROOT CAUSE FIRST\n...",
|
|
65
|
+
"lines": [
|
|
66
|
+
{ "language": "en", "text": "/shaping" },
|
|
67
|
+
{ "language": "en", "text": "BEFORE YOU BUILD" }
|
|
68
|
+
]
|
|
69
|
+
},
|
|
70
|
+
"layout": {
|
|
71
|
+
"regions": [
|
|
72
|
+
{
|
|
73
|
+
"reading_order": 1,
|
|
74
|
+
"text": "/shaping BEFORE YOU BUILD",
|
|
75
|
+
"type": "other"
|
|
76
|
+
}
|
|
77
|
+
]
|
|
78
|
+
},
|
|
79
|
+
"uncertainty": []
|
|
80
|
+
},
|
|
81
|
+
"meta": { "model": "gemini-3.6-flash-low", "durationSeconds": 25.4 }
|
|
82
|
+
}
|
|
83
|
+
```
|
|
84
|
+
|
|
85
|
+
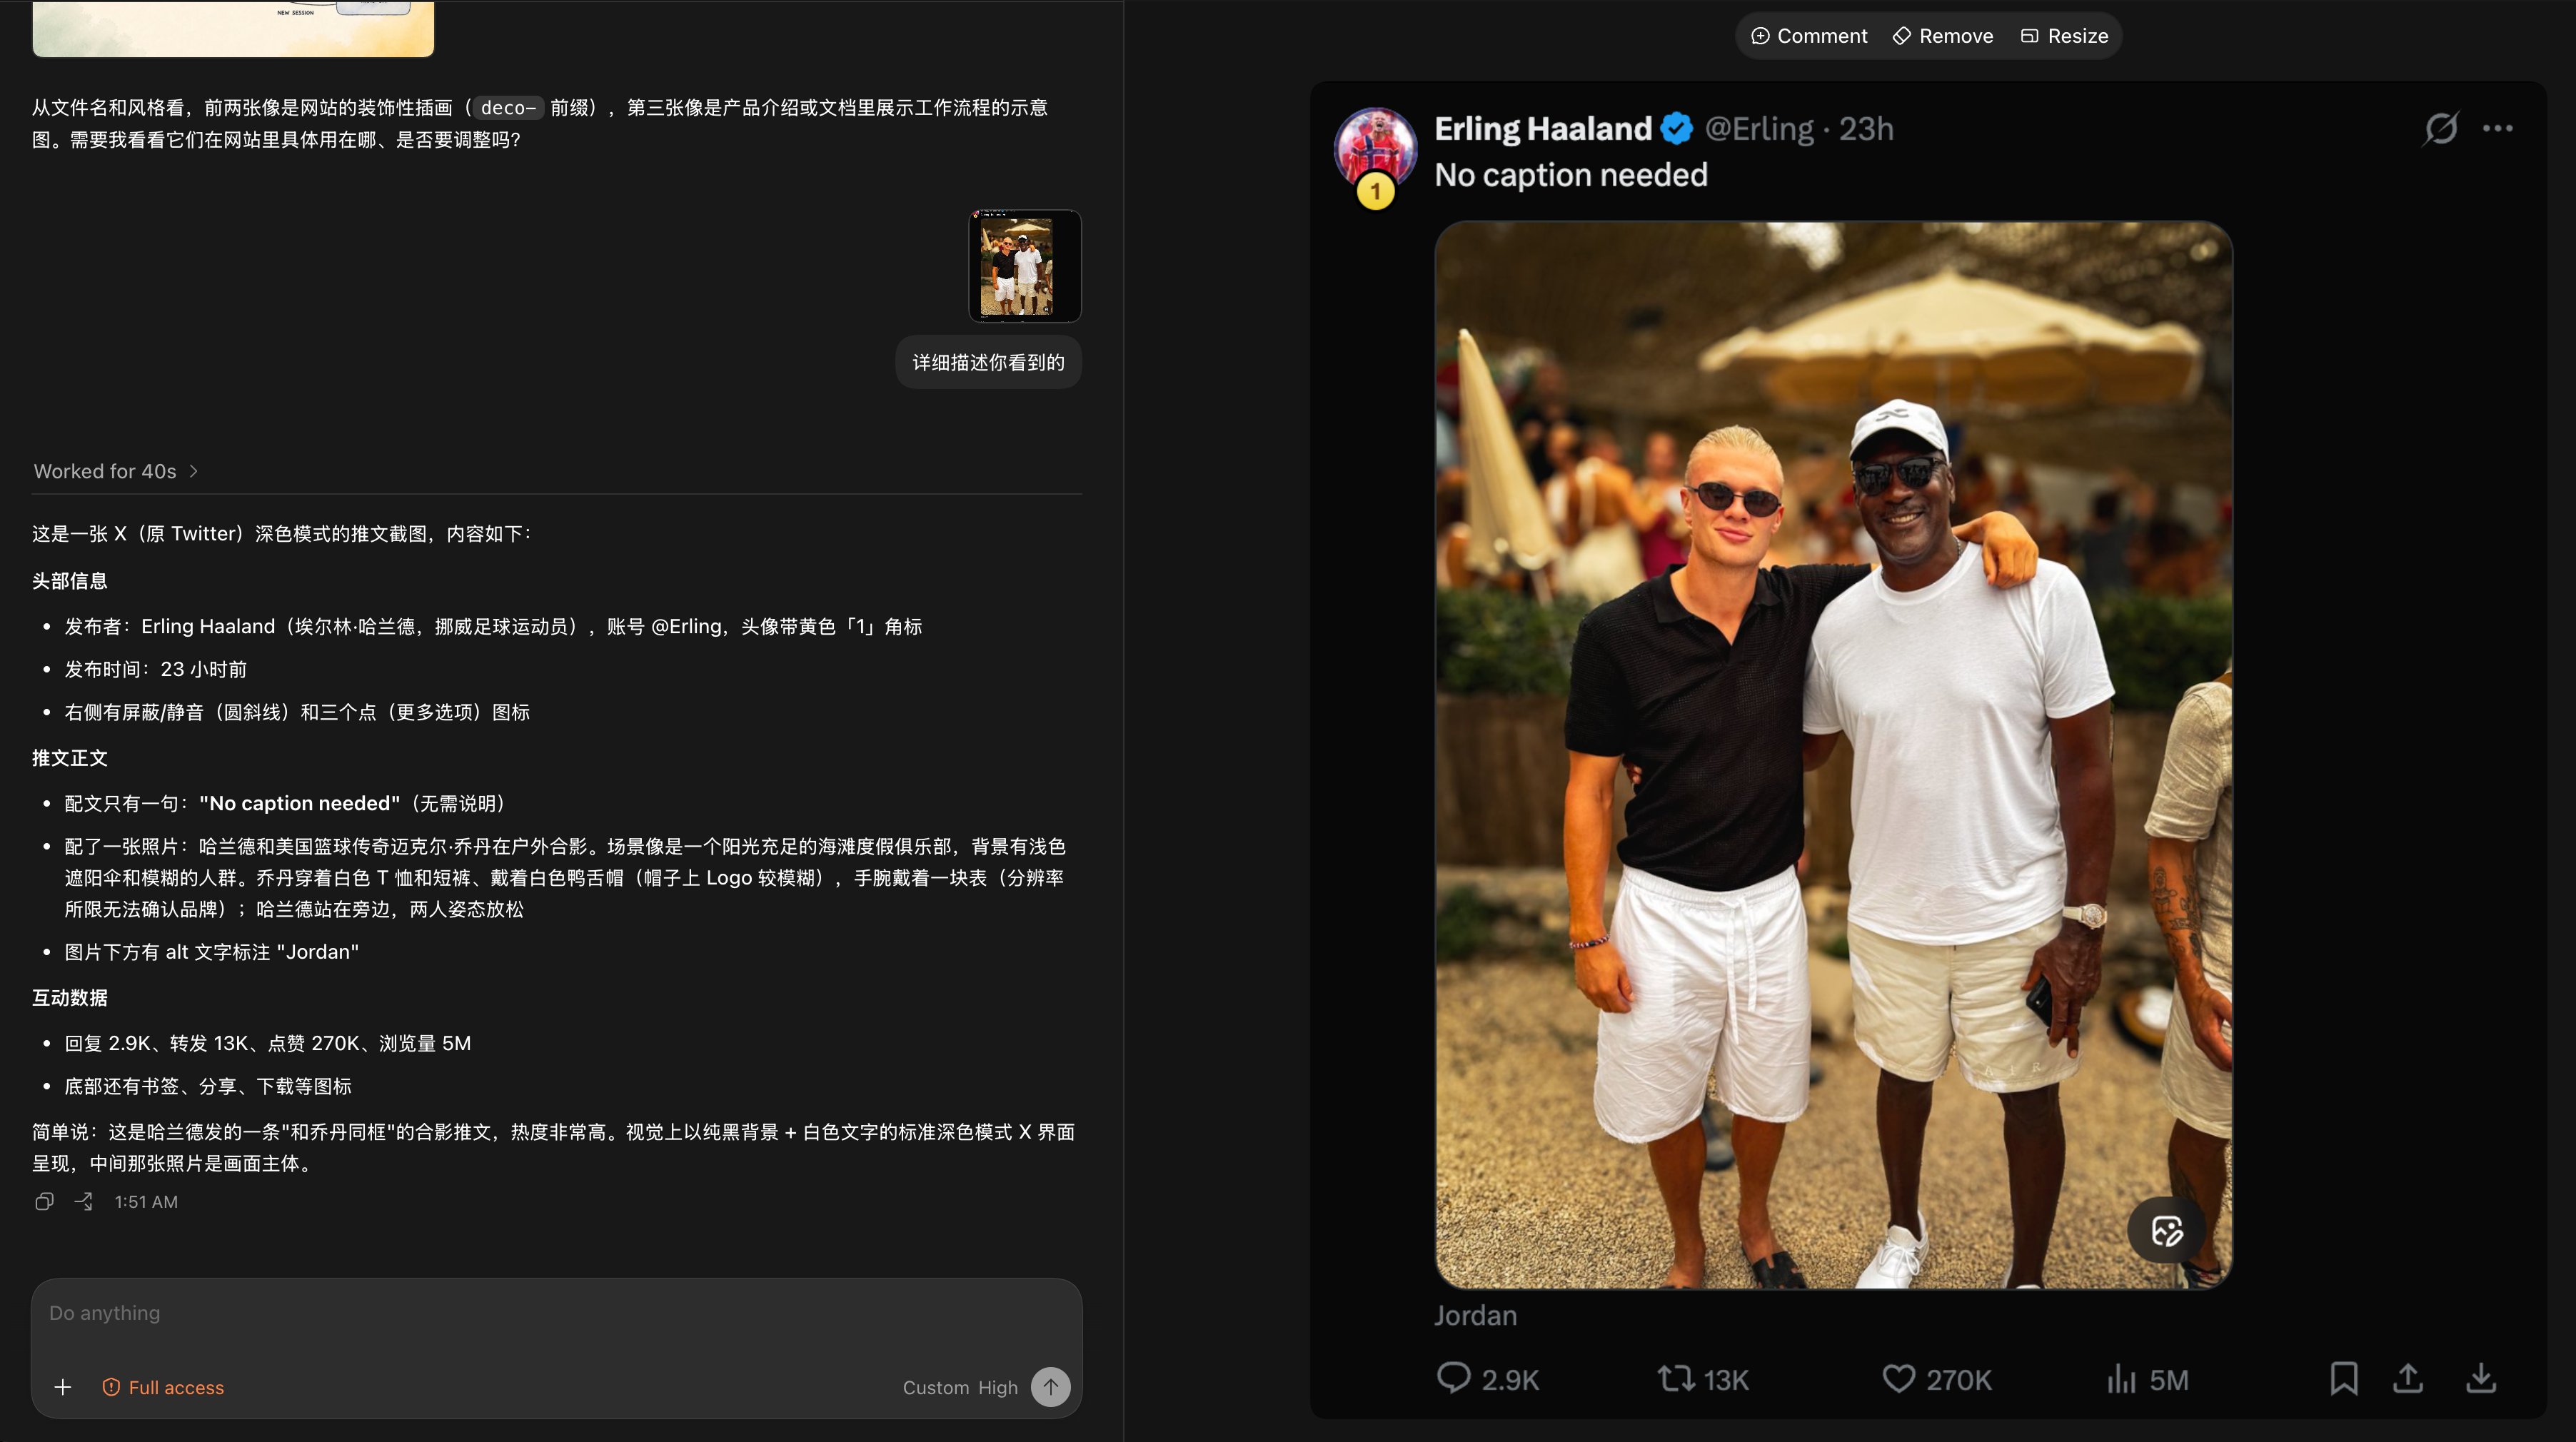
Here is the whole loop inside the Codex desktop app: drop in a tweet screenshot, and a text-only DeepSeek-V4-Flash reads all of it through ModLens: the caption, the engagement numbers (2.9K replies, 270K likes, 5M views), even the image's alt text. Where the resolution runs out, it says so instead of guessing.
|
|
86
|
+
|
|
87
|
+
|
|
88
|
+
|
|
89
|
+
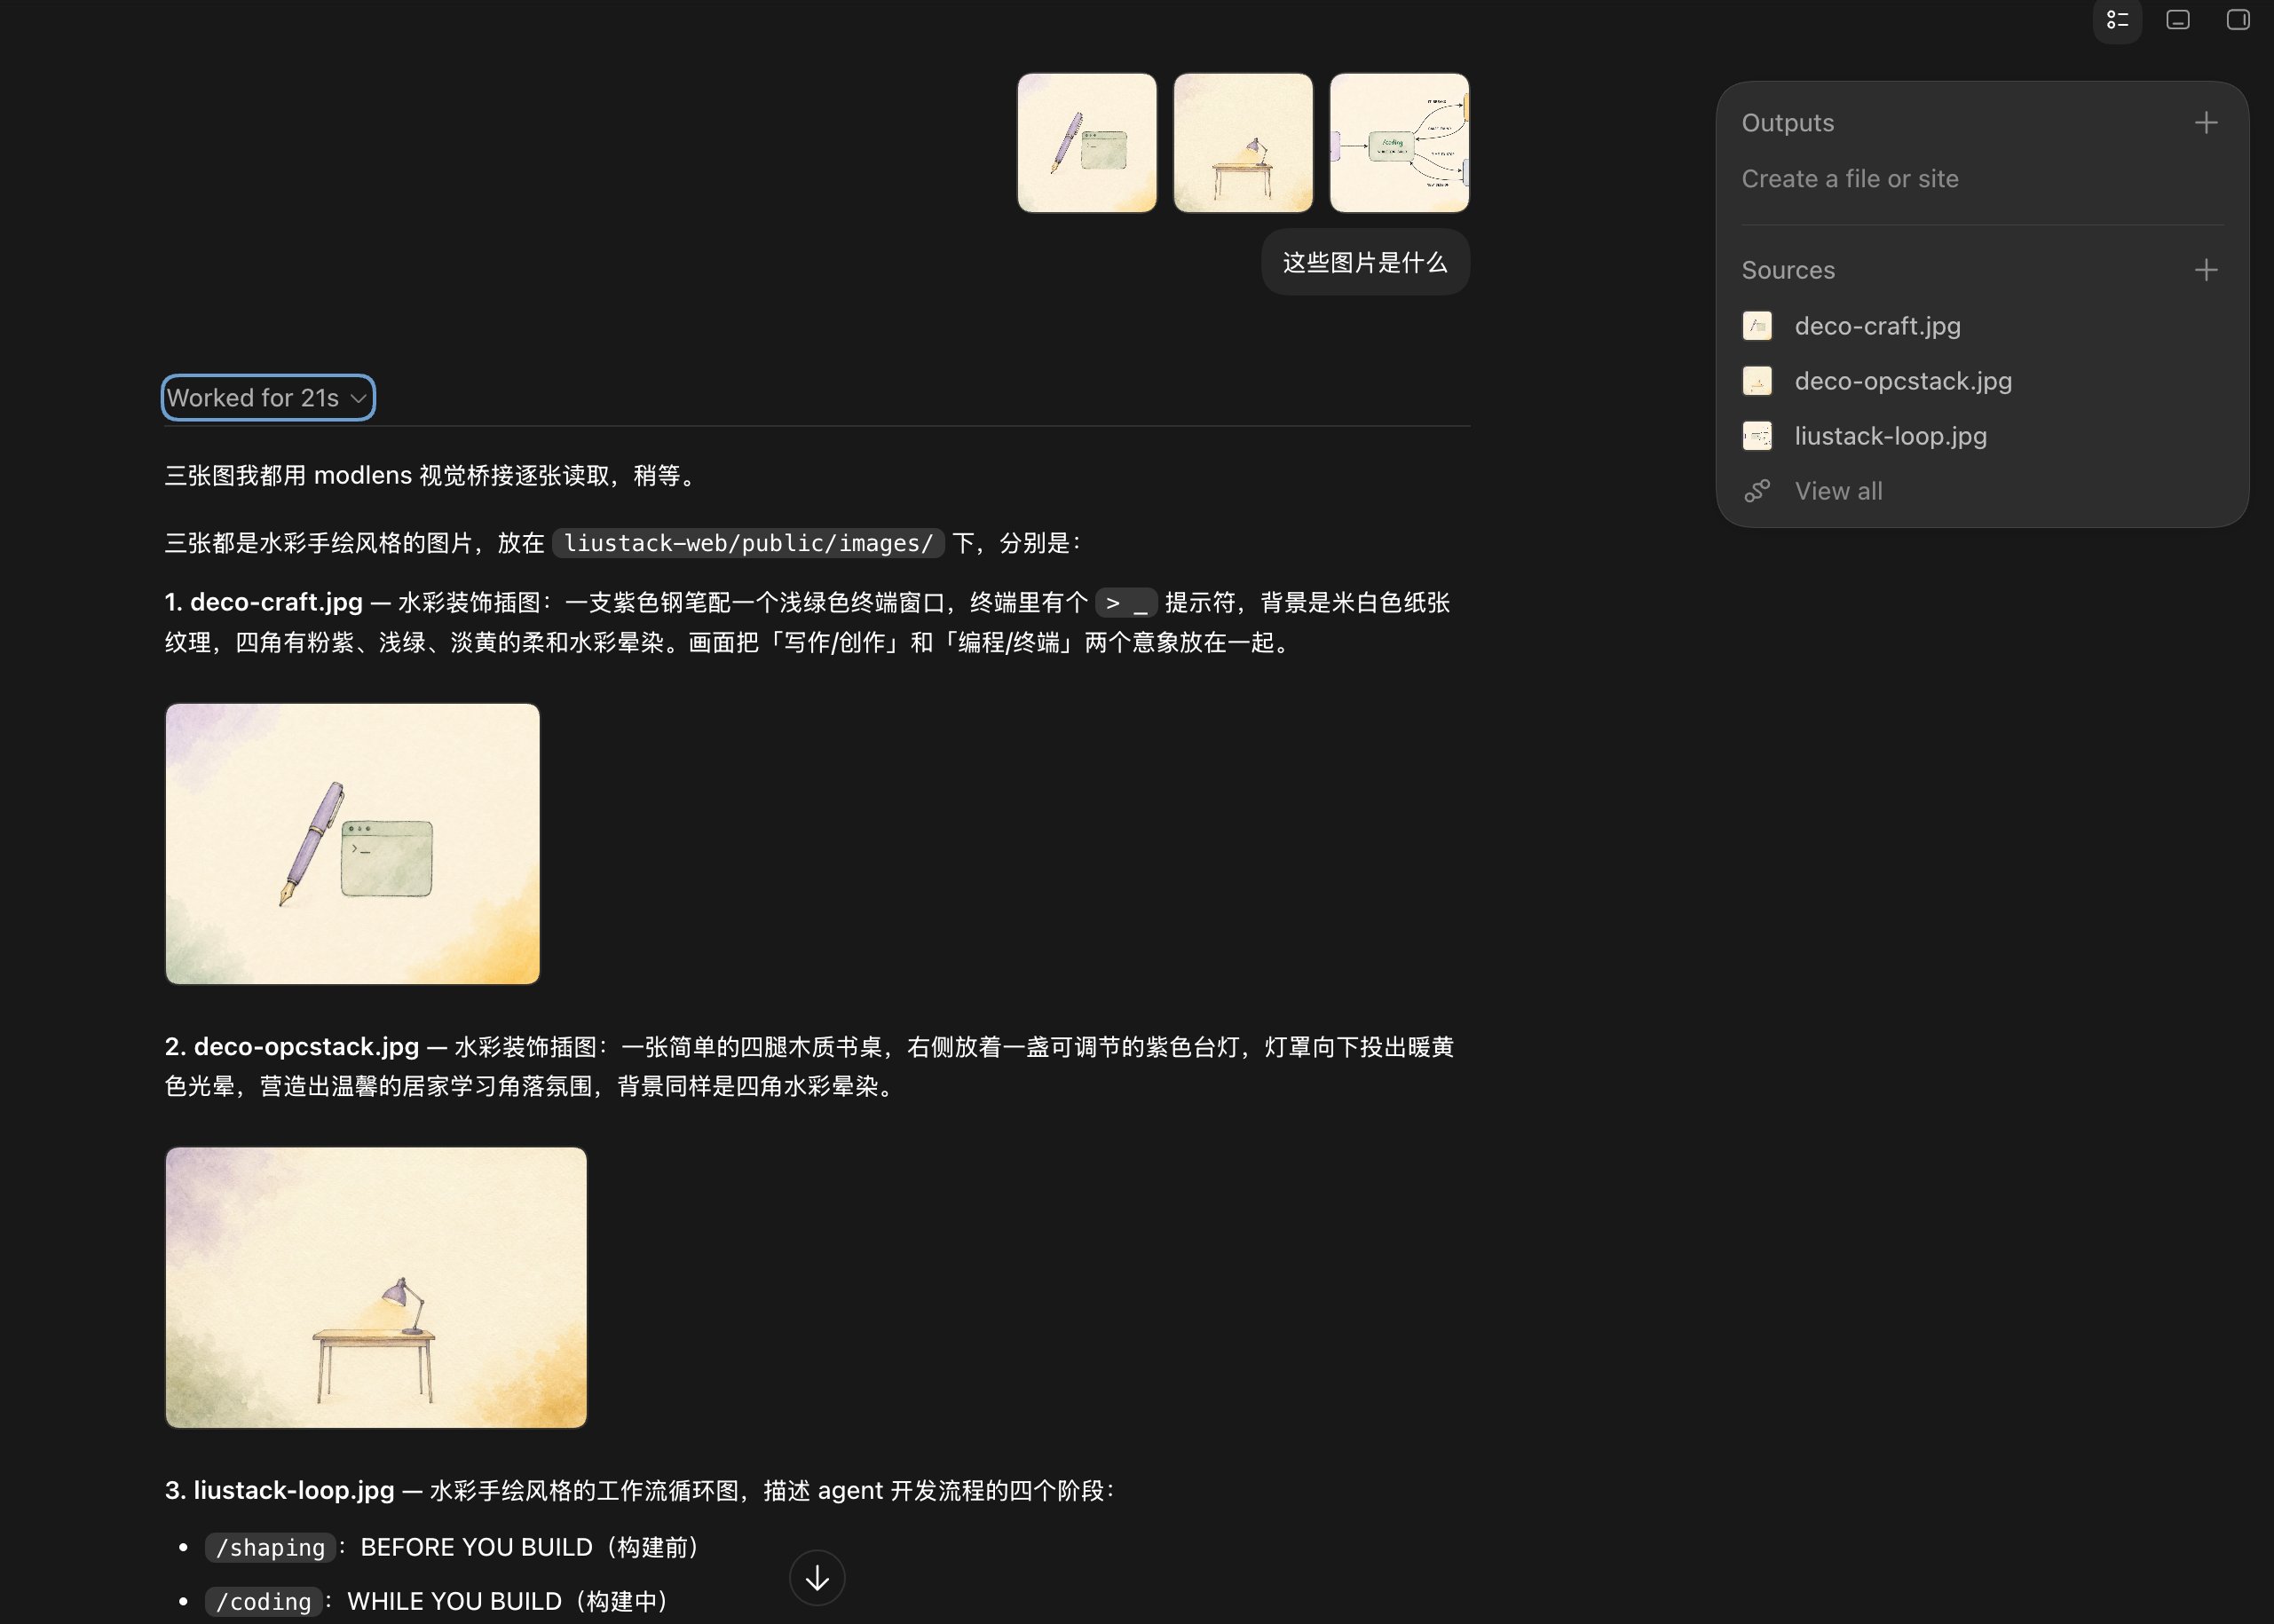
Batch mode works too: drop three illustrations at once, and the model announces it will read them one by one through ModLens, then delivers all three descriptions in 21 seconds, design intent included.
|
|
90
|
+
|
|
91
|
+
|
|
92
|
+
|
|
93
|
+
## CLI reference
|
|
29
94
|
|
|
30
95
|
```bash
|
|
31
|
-
|
|
96
|
+
modlens -i <image-path-or-url> [options]
|
|
32
97
|
```
|
|
33
98
|
|
|
34
|
-
|
|
99
|
+
| Flag | Meaning | Default |
|
|
100
|
+
| :-- | :-- | :-- |
|
|
101
|
+
| `-i, --input <path\|url>` | Image to analyze (required) | |
|
|
102
|
+
| `-o, --output <path>` | Also write JSON to a file | |
|
|
103
|
+
| `-m, --model <name>` | Provider model | `gemini-3.6-flash-low` |
|
|
104
|
+
| `-p, --provider <name>` | Vision provider | `antigravity-cli` |
|
|
105
|
+
| `--prompt <text>` | Extra focus, e.g. `"extract the table"` | |
|
|
106
|
+
| `--timeout <ms>` | Provider timeout | `180000` |
|
|
107
|
+
| `--provider-bin <path>` | Provider binary | `agy` |
|
|
108
|
+
| `--workdir <path>` | Working directory for the provider | |
|
|
35
109
|
|
|
36
|
-
|
|
37
|
-
# Print JSON result to stdout
|
|
38
|
-
modlens -i screenshot.png
|
|
110
|
+
Reach for `-m gemini-3.1-pro-high` on dense screenshots or tricky documents. Output contract: [skills/modlens/references/output-schema.md](skills/modlens/references/output-schema.md).
|
|
39
111
|
|
|
40
|
-
|
|
41
|
-
modlens -i screenshot.png -o lens.json
|
|
112
|
+
## Providers and config
|
|
42
113
|
|
|
43
|
-
|
|
44
|
-
|
|
114
|
+
ModLens ships four vision providers. `antigravity-cli` stays the default: zero keys, pure free quota.
|
|
115
|
+
|
|
116
|
+
| Provider | Needs | Typical speed | Notes |
|
|
117
|
+
| :-- | :-- | :-- | :-- |
|
|
118
|
+
| `antigravity-cli` (default) | `agy` signed in | 15-40s | free quota, full agent loop |
|
|
119
|
+
| `gemini-api` | free AI Studio key | 5-10s | fastest free route, schema enforced server-side |
|
|
120
|
+
| `openai` | baseUrl + apiKey + model | endpoint-dependent | any OpenAI-compatible multimodal endpoint (qwen-vl, GLM, ...) |
|
|
121
|
+
| `anthropic` | `ANTHROPIC_API_KEY` | a few seconds | Claude Haiku by default, schema via forced tool call |
|
|
122
|
+
|
|
123
|
+
Config lives in `~/.modlens/config.json`. Environment variables override the file (`GEMINI_API_KEY`, `OPENAI_API_KEY`, `OPENAI_BASE_URL`, `ANTHROPIC_API_KEY`), and CLI flags override everything.
|
|
124
|
+
|
|
125
|
+
```bash
|
|
126
|
+
modlens config init # write a starter config
|
|
127
|
+
modlens config set gemini-api.apiKey <key> # saved with 0600 perms
|
|
128
|
+
modlens config show # keys come out masked
|
|
129
|
+
modlens config set provider gemini-api # switch the default provider
|
|
45
130
|
```
|
|
46
131
|
|
|
47
|
-
|
|
132
|
+
The free Gemini key takes three minutes at [aistudio.google.com](https://aistudio.google.com), no credit card. Or skip the manual work entirely and tell your agent: "configure modlens with my Gemini API key".
|
|
133
|
+
|
|
134
|
+
## Using it in Codex (DeepSeek and friends)
|
|
135
|
+
|
|
136
|
+
Codex speaks only the Responses API, and DeepSeek's official endpoint supports it natively. Start with the [official integration guide](https://api-docs.deepseek.com/quick_start/agent_integrations/codex/): its `models.json` declares deepseek-v4-flash as text-only (`input_modalities: ["text"]`), and that one line is what unlocks the whole flow.
|
|
137
|
+
|
|
138
|
+
One catch: once text-only is declared, the Codex TUI **blocks Ctrl+V image paste outright** (`Model deepseek-v4-flash does not support image inputs`). The gate sits in the input box itself, so the image never makes it into the message. Two moves get around it, both verified end to end with deepseek-v4-flash:
|
|
48
139
|
|
|
49
|
-
|
|
50
|
-
|
|
51
|
-
| `-i, --input <path>` | Input image path (required) |
|
|
52
|
-
| `-o, --output <path>` | Write result JSON to a file |
|
|
53
|
-
| `-m, --model <name>` | Vision model name (backend-specific) |
|
|
54
|
-
| `--prompt <text>` | Extra extraction constraints |
|
|
55
|
-
| `--timeout <ms>` | Timeout in milliseconds (default: `180000`) |
|
|
56
|
-
| `--gemini-bin <path>` | Gemini CLI binary path (default: `gemini`) |
|
|
140
|
+
- **Drag the image file into the terminal**, or type its path. The path lands as plain text, and the modlens skill picks it up from there.
|
|
141
|
+
- Attach it with `codex exec -i image.png "..."`. The skill reads the path out of the message tag.
|
|
57
142
|
|
|
58
|
-
##
|
|
143
|
+
## Why a bridge instead of a multimodal model?
|
|
59
144
|
|
|
60
|
-
|
|
145
|
+
- **Keep your model.** You picked DeepSeek-V4-Flash (or gpt-oss, or whatever else) for its price and its reasoning, not its eyesight. ModLens adds sight without touching that choice.
|
|
146
|
+
- **Evidence beats pixels.** Text models reason best over structured text, not raw pixels. ModLens hands them OCR plus layout plus semantics, already decoded, not a base64 blob.
|
|
147
|
+
- **Engines die, the bridge survives.** v1 ran on Gemini CLI's free tier until Google shut it down in June 2026. v2 moved to its successor, Antigravity CLI, behind the same provider interface, so the next engine swap costs one file, not a rewrite.
|
|
61
148
|
|
|
62
|
-
|
|
149
|
+
ModSearch, ModLens's sibling project, plays the same trick for web search and page fetching: [liustack/modsearch](https://github.com/liustack/modsearch).
|
|
150
|
+
|
|
151
|
+
## Shameless plug
|
|
152
|
+
|
|
153
|
+
This project runs on LIUSTACK Skills. ModLens v2 was shaped, coded, and shipped with **[liustack](https://github.com/liustack/liustack)** end to end: `shaping` before you build, `coding` while you build, `dig` when it breaks, `snapshot` when you hand off. Lighter than Superpowers, and sharper.
|
|
154
|
+
|
|
155
|
+
**ModLens gives your model eyes. LIUSTACK Skills gives your dev workflow wings:**
|
|
156
|
+
|
|
157
|
+
```bash
|
|
158
|
+
npx -y skills add liustack/liustack -g
|
|
159
|
+
```
|
|
63
160
|
|
|
64
|
-
|
|
161
|
+
⭐ Like it? [Star ModLens](https://github.com/liustack/modlens) and [star liustack](https://github.com/liustack/liustack). Stars are how the next developer finds them.
|
|
65
162
|
|
|
66
|
-
##
|
|
163
|
+
## Security notes
|
|
67
164
|
|
|
68
|
-
- `
|
|
69
|
-
-
|
|
165
|
+
- ModLens runs `agy` with `--dangerously-skip-permissions`, because print mode can fail in some setups without it. The prompt keeps the agent to reading that one image and tells it to treat image content as data, never as instructions. Even so, only point it at images you would open yourself, and run it inside a sandboxed workspace when you can.
|
|
166
|
+
- Vision output is evidence. Anything the engine cannot read lands in `uncertainty` instead of getting invented. Pixel bounding boxes and confidence scores were dropped in v2 because models fabricate them.
|
|
70
167
|
|
|
71
168
|
## Disclaimer
|
|
72
169
|
|
|
73
|
-
|
|
170
|
+
Personal learning and experimentation only, not for commercial use. Antigravity CLI usage runs under your own Google account's terms and quota.
|
|
74
171
|
|
|
75
172
|
## License
|
|
76
173
|
|
package/README.zh-CN.md
CHANGED
|
@@ -1,68 +1,173 @@
|
|
|
1
|
-
|
|
1
|
+
<div align="center">
|
|
2
|
+
<img src="https://raw.githubusercontent.com/liustack/modlens/main/assets/banner.jpg" width="100%" alt="ModLens,给纯文本 LLM 外挂视觉" />
|
|
3
|
+
<h1>ModLens</h1>
|
|
4
|
+
<p><b>免费给你的大语言模型(纯文本 LLM)外挂视觉能力。</b></p>
|
|
5
|
+
<p>
|
|
6
|
+
<a href="https://www.npmjs.com/package/@liustack/modlens"><img src="https://img.shields.io/npm/v/@liustack/modlens" alt="npm"></a>
|
|
7
|
+
<a href="LICENSE"><img src="https://img.shields.io/badge/license-MIT-blue.svg" alt="License"></a>
|
|
8
|
+
</p>
|
|
9
|
+
<p><a href="./README.md">English</a></p>
|
|
10
|
+
</div>
|
|
11
|
+
|
|
12
|
+
DeepSeek-V4-Flash 碗大又好吃,速度快,性能强,要说唯一的缺点就是没有多模态。不仅 DeepSeek-V4-Flash,只要是纯文本语言模型,跑在 Codex、Claude Code、Pi Agent、OpenClaw 中,都有这个问题。
|
|
13
|
+
|
|
14
|
+
ModLens 用最轻量级方案解决这个问题。ModLens 不会入侵你的配置,也不会给你添加本地代理,ModLens 只是一个视觉外挂,有 cli 或 skill 两种模式。ModLens 能产出结构化的视觉证据:文字、版面、区块、实体、关系、视觉线索。ModLens 由 Antigravity [Antigravity CLI](https://antigravity.google)(`agy`)驱动,而 Antigravity 的视觉由免费额度的 Gemini 3.6 Flash 驱动。众所周知,Gemini 的识图能力,连 Fable 5 都吊打。原理如下:
|
|
15
|
+
|
|
16
|
+
```text
|
|
17
|
+
Agent Harness 中的纯文本模型 ──▶ modlens skill(遇到图片自动触发)
|
|
18
|
+
│
|
|
19
|
+
▼
|
|
20
|
+
agy · Gemini 3.6 Flash(免费额度)
|
|
21
|
+
│
|
|
22
|
+
▼
|
|
23
|
+
结构化 JSON 证据 ──▶ 模型带着视力回答
|
|
24
|
+
```
|
|
2
25
|
|
|
3
|
-
|
|
26
|
+
## 快速开始
|
|
4
27
|
|
|
5
|
-
|
|
28
|
+
**1. 安装 Antigravity CLI 并登录**(一次性):
|
|
6
29
|
|
|
7
|
-
|
|
8
|
-
-
|
|
9
|
-
|
|
10
|
-
|
|
11
|
-
- 适合作为 Agent Skill 工具被 Claude Code / Codex 等调用
|
|
30
|
+
```bash
|
|
31
|
+
curl -fsSL https://antigravity.google/cli/install.sh | bash
|
|
32
|
+
agy # 浏览器完成登录后退出
|
|
33
|
+
```
|
|
12
34
|
|
|
13
|
-
|
|
35
|
+
**2. 安装 skill。** 直接告诉你的 agent(Claude Code、Codex、OpenClaw、Cursor 等):
|
|
14
36
|
|
|
15
|
-
```
|
|
16
|
-
|
|
37
|
+
```text
|
|
38
|
+
安装这个 skill https://github.com/liustack/modlens
|
|
17
39
|
```
|
|
18
40
|
|
|
19
|
-
|
|
41
|
+
或者自己动手:
|
|
20
42
|
|
|
21
43
|
```bash
|
|
22
|
-
|
|
23
|
-
gemini
|
|
44
|
+
npx -y skills add liustack/modlens
|
|
24
45
|
```
|
|
25
46
|
|
|
26
|
-
|
|
47
|
+
**3. 用起来。** 在 cli 里粘贴个图片路径,随便问,skill 会自动触发。
|
|
48
|
+
|
|
49
|
+
## 看看效果
|
|
27
50
|
|
|
28
51
|
```bash
|
|
29
|
-
npx @liustack/modlens
|
|
52
|
+
npx @liustack/modlens -i workflow.jpg
|
|
53
|
+
```
|
|
54
|
+
|
|
55
|
+
真实输出(已截断):
|
|
56
|
+
|
|
57
|
+
```json
|
|
58
|
+
{
|
|
59
|
+
"image": "/Users/leon/projects/liustack/assets/loop.jpg",
|
|
60
|
+
"provider": "antigravity-cli",
|
|
61
|
+
"result": {
|
|
62
|
+
"summary": "A workflow diagram with four nodes connected by labeled arrows.",
|
|
63
|
+
"ocr": {
|
|
64
|
+
"full_text": "/shaping\nBEFORE YOU BUILD\n\n/coding\nWHILE YOU BUILD\n\nIT BREAKS\n/dig\nROOT CAUSE FIRST\n...",
|
|
65
|
+
"lines": [
|
|
66
|
+
{ "language": "en", "text": "/shaping" },
|
|
67
|
+
{ "language": "en", "text": "BEFORE YOU BUILD" }
|
|
68
|
+
]
|
|
69
|
+
},
|
|
70
|
+
"layout": {
|
|
71
|
+
"regions": [
|
|
72
|
+
{
|
|
73
|
+
"reading_order": 1,
|
|
74
|
+
"text": "/shaping BEFORE YOU BUILD",
|
|
75
|
+
"type": "other"
|
|
76
|
+
}
|
|
77
|
+
]
|
|
78
|
+
},
|
|
79
|
+
"uncertainty": []
|
|
80
|
+
},
|
|
81
|
+
"meta": { "model": "gemini-3.6-flash-low", "durationSeconds": 25.4 }
|
|
82
|
+
}
|
|
30
83
|
```
|
|
31
84
|
|
|
32
|
-
|
|
85
|
+
整条链路在 Codex 桌面 App 里跑起来是这样:丢一张推文截图,纯文本的 DeepSeek-V4-Flash 通过 ModLens 读出了全部内容:配文、互动数据(2.9K 回复、270K 点赞、5M 浏览)、连图片的 alt 文字都没放过。分辨率不够的地方,它老实说读不清,不瞎编。
|
|
86
|
+
|
|
87
|
+

|
|
88
|
+
|
|
89
|
+
批量也不在话下:一次丢三张插画进去,模型自己说「三张图我都用 modlens 视觉桥接逐张读取」,21 秒后逐张交卷,连画面的设计意图都点出来了。
|
|
90
|
+
|
|
91
|
+

|
|
92
|
+
|
|
93
|
+
## CLI 参数
|
|
33
94
|
|
|
34
95
|
```bash
|
|
35
|
-
|
|
36
|
-
|
|
96
|
+
modlens -i <图片路径或 URL> [选项]
|
|
97
|
+
```
|
|
98
|
+
|
|
99
|
+
| 参数 | 含义 | 默认值 |
|
|
100
|
+
| :------------------------ | :-------------------------------- | :--------------------- |
|
|
101
|
+
| `-i, --input <path\|url>` | 要解析的图片(必填) | |
|
|
102
|
+
| `-o, --output <path>` | 同时把 JSON 写入文件 | |
|
|
103
|
+
| `-m, --model <name>` | provider 模型 | `gemini-3.6-flash-low` |
|
|
104
|
+
| `-p, --provider <name>` | 视觉 provider | `antigravity-cli` |
|
|
105
|
+
| `--prompt <text>` | 额外关注点,比如 `"重点提取表格"` | |
|
|
106
|
+
| `--timeout <ms>` | provider 超时 | `180000` |
|
|
107
|
+
| `--provider-bin <path>` | provider 可执行文件 | `agy` |
|
|
108
|
+
| `--workdir <path>` | provider 运行目录 | |
|
|
109
|
+
|
|
110
|
+
截图信息密集或文档难啃,换成 `-m gemini-3.1-pro-high`。输出契约见 [skills/modlens/references/output-schema.md](skills/modlens/references/output-schema.md)。
|
|
111
|
+
|
|
112
|
+
## Provider 与配置
|
|
37
113
|
|
|
38
|
-
|
|
39
|
-
modlens -i screenshot.png -o lens.json
|
|
114
|
+
ModLens 内置四个视觉 provider,默认还是 `antigravity-cli`:零 key,纯免费额度。
|
|
40
115
|
|
|
41
|
-
|
|
42
|
-
|
|
116
|
+
| Provider | 需要什么 | 速度 | 说明 |
|
|
117
|
+
| :-- | :-- | :-- | :-- |
|
|
118
|
+
| `antigravity-cli`(默认) | `agy` 登录过 | 15-40 秒 | 免费额度,完整 agent 循环 |
|
|
119
|
+
| `gemini-api` | 免费 AI Studio key | 5-10 秒 | 最快的免费路线,服务端强制 schema |
|
|
120
|
+
| `openai` | baseUrl + apiKey + model | 看端点 | 任何 OpenAI 兼容的多模态端点(qwen-vl、GLM 等) |
|
|
121
|
+
| `anthropic` | `ANTHROPIC_API_KEY` | 几秒 | 默认 Claude Haiku,强制工具调用保 schema |
|
|
122
|
+
|
|
123
|
+
配置放在 `~/.modlens/config.json`,环境变量能盖过它(`GEMINI_API_KEY`、`OPENAI_API_KEY`、`OPENAI_BASE_URL`、`ANTHROPIC_API_KEY`),CLI 参数最大。
|
|
124
|
+
|
|
125
|
+
```bash
|
|
126
|
+
modlens config init # 生成配置骨架
|
|
127
|
+
modlens config set gemini-api.apiKey <key> # 落盘即 0600 权限
|
|
128
|
+
modlens config show # key 打码显示
|
|
129
|
+
modlens config set provider gemini-api # 换默认 provider
|
|
43
130
|
```
|
|
44
131
|
|
|
45
|
-
|
|
132
|
+
免费 Gemini key 去 [aistudio.google.com](https://aistudio.google.com) 领,三分钟,不要信用卡。嫌麻烦就直接跟你的 agent 说一句「帮我把 Gemini key 配进 modlens」,让它自己跑命令。
|
|
133
|
+
|
|
134
|
+
## 在 Codex 里用(DeepSeek 等纯文本模型)
|
|
135
|
+
|
|
136
|
+
Codex 只认 Responses API,DeepSeek 官方端点原生支持。先照着[官方集成文档](https://api-docs.deepseek.com/zh-cn/quick_start/agent_integrations/codex)配好:它的 `models.json` 把 deepseek-v4-flash 声明成纯文本(`input_modalities: ["text"]`),这一行就是打通下面整条链路的钥匙。
|
|
137
|
+
|
|
138
|
+
有个坑要注意:声明纯文本之后,Codex TUI 会**直接拦下 Ctrl+V 粘贴图片**(报错 `Model deepseek-v4-flash does not support image inputs`),闸门卡在输入框那一层,图片压根到不了消息里。能用的招数有两个,都拿 deepseek-v4-flash 端到端验证过:
|
|
139
|
+
|
|
140
|
+
- **把图片文件拖进终端**,或者手打路径。路径以纯文本形式落进消息,modlens skill 接着从这里接手。
|
|
141
|
+
- 用 `codex exec -i 图片.png "..."` skill 从这里把路径抠出来。
|
|
46
142
|
|
|
47
|
-
|
|
48
|
-
- `-o, --output <path>` 可选输出 JSON 路径
|
|
49
|
-
- `-m, --model <name>` Gemini 模型名
|
|
50
|
-
- `--prompt <text>` 额外解析约束
|
|
51
|
-
- `--timeout <ms>` 超时毫秒(默认 `180000`)
|
|
52
|
-
- `--gemini-bin <path>` Gemini 可执行路径(默认 `gemini`)
|
|
143
|
+
## 为什么外挂,而不是换多模态模型?
|
|
53
144
|
|
|
54
|
-
|
|
145
|
+
- **模型不用换。** 你选 DeepSeek-V4-Flash(或 gpt-oss,或别的什么)图的是价格和推理能力,不是视力。ModLens 只加视力,不碰这个选择。
|
|
146
|
+
- **证据强过像素。** 文本模型最会在结构化文本上推理,不是盯着原始像素。ModLens 递过去的是 OCR 加版面加语义,都是解好码的证据,不是一坨 base64。
|
|
147
|
+
- **引擎会死,桥不会死。** v1 跑在 Gemini CLI 免费档上,2026 年 6 月被 Google 一刀切停掉。v2 换到继任者 Antigravity CLI,还是同一个 provider 接口,下次再换引擎,改一个文件就行,不用重写。
|
|
148
|
+
|
|
149
|
+
姊妹项目 ModSearch 用同一招补上联网搜索和网页抓取:[liustack/modsearch](https://github.com/liustack/modsearch)。
|
|
150
|
+
|
|
151
|
+
## 插入一条硬广告
|
|
152
|
+
|
|
153
|
+
本项目由 LIUSTACK Skills 驱动,ModLens v2 从需求成形、编码到交付,全程用 **[liustack](https://github.com/liustack/liustack)** 驱动:动手前 `shaping` 捋清楚,编码时 `coding` 上纪律,出问题 `dig` 挖根因,交接时 `snapshot` 留快照。比 Superpowers 更轻,也更强。
|
|
154
|
+
|
|
155
|
+
**ModLens 给你的模型装上眼睛,LIUSTACK Skills 给你的开发工作流装上翅膀:**
|
|
156
|
+
|
|
157
|
+
```bash
|
|
158
|
+
npx -y skills add liustack/liustack -g
|
|
159
|
+
```
|
|
55
160
|
|
|
56
|
-
|
|
161
|
+
⭐ 好用的话,给 [ModLens](https://github.com/liustack/modlens) 和 [liustack](https://github.com/liustack/liustack) 各点一个 star。star 是下一个开发者找到它们的方式。
|
|
57
162
|
|
|
58
|
-
##
|
|
163
|
+
## 安全说明
|
|
59
164
|
|
|
60
|
-
- `
|
|
61
|
-
-
|
|
165
|
+
- ModLens 调用 `agy` 时带上 `--dangerously-skip-permissions`,因为 prompt/print 模式不带这个参数在某些场景会失败。提示词已经把 agent 限定在只读那一张图,并要求把图片内容当数据看,绝不当指令执行。即便如此,也只解析你自己敢打开的图片,尽量在沙箱化的工作目录里跑。
|
|
166
|
+
- 视觉输出是证据,引擎读不准的地方会进 `uncertainty`,而不是被编出来凑数。v2 把像素坐标和置信度分数都删了,因为模型会瞎编这两样。
|
|
62
167
|
|
|
63
168
|
## 免责声明
|
|
64
169
|
|
|
65
|
-
|
|
170
|
+
仅供个人学习与实验,不用于商业用途。Antigravity CLI 的使用受你自己的 Google 账号条款和额度约束。
|
|
66
171
|
|
|
67
172
|
## License
|
|
68
173
|
|