@lincoln504/pi-research 1.5.3 → 1.6.1
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.md +11 -11
- package/agent-skill/pi-research/SKILL.md +1 -1
- package/dist/cli.mjs +204 -132
- package/dist/prompts/researcher.md +2 -0
- package/dist/thread-worker.mjs +112 -17
- package/docs/CHANGELOG.md +63 -0
- package/docs/SDK.md +72 -9
- package/package.json +2 -2
- package/src/constants.ts +30 -0
- package/src/infrastructure/browser/browser-client.ts +24 -6
- package/src/infrastructure/browser/browser-error-utils.ts +53 -0
- package/src/infrastructure/browser/browser-server.ts +9 -1
- package/src/infrastructure/browser/thread-worker-browser.ts +4 -1
- package/src/infrastructure/browser/thread-worker-messaging.ts +196 -3
- package/src/infrastructure/browser/thread-worker.mjs +112 -17
- package/src/knowledge/store-operations.ts +18 -7
- package/src/knowledge/store.ts +21 -3
- package/src/orchestration/deep-research-orchestrator.ts +37 -11
- package/src/orchestration/quick-research-orchestrator.ts +40 -2
- package/src/orchestration/research-synthesis-service.ts +6 -1
- package/src/prompts/researcher.md +2 -0
- package/src/utils/text-utils.ts +99 -0
- package/src/web-research/scraper-utils.ts +4 -36
- package/src/youtube/potoken.ts +47 -34
package/README.md
CHANGED
|
@@ -27,7 +27,7 @@
|
|
|
27
27
|
<a href="LICENSE"><img alt="License: MIT" src="https://img.shields.io/badge/license-MIT-97ca00?style=flat-square" /></a><br />
|
|
28
28
|
<a href="https://github.com/Lincoln504/pi-research"><img alt="GitHub repository" src="https://img.shields.io/badge/GitHub-Lincoln504%2Fpi--research-181717?style=flat-square&logo=github&logoColor=white" /></a>
|
|
29
29
|
|
|
30
|
-
Search and scraping run locally through a stealth browser with no search provider and no monthly cap.
|
|
30
|
+
Search and scraping run locally through a stealth browser with no search provider and no monthly cap. The only cost is LLM tokens.
|
|
31
31
|
|
|
32
32
|
### Install
|
|
33
33
|
|
|
@@ -44,38 +44,38 @@ npm install -g @lincoln504/pi-research
|
|
|
44
44
|
pi-research skill install
|
|
45
45
|
```
|
|
46
46
|
|
|
47
|
-
In pi it works out of the box on
|
|
47
|
+
In pi it works out of the box on the session's model and pi's configuration. Standalone use ([agent skill](docs/AGENT-SKILL.md) or [SDK](docs/SDK.md)) needs a model configured. See [Configuration](docs/CONFIGURATION.md). The first install pulls the stealth browser engine, which takes a few minutes.
|
|
48
48
|
|
|
49
49
|
### How it works
|
|
50
50
|
|
|
51
51
|
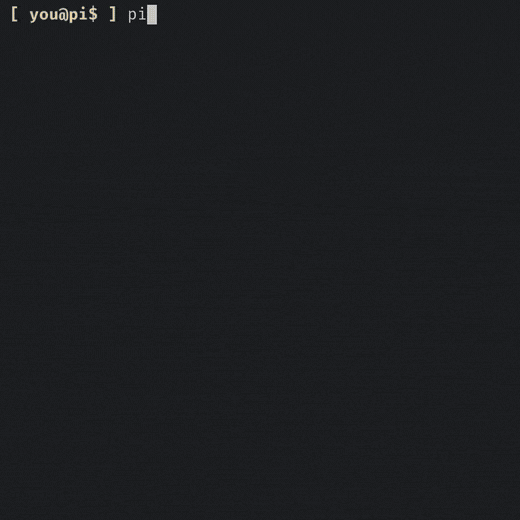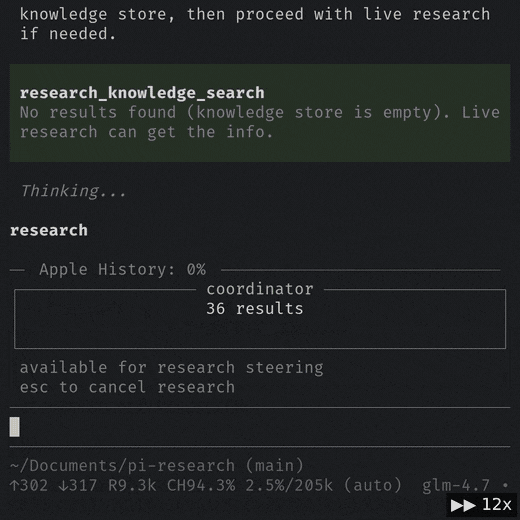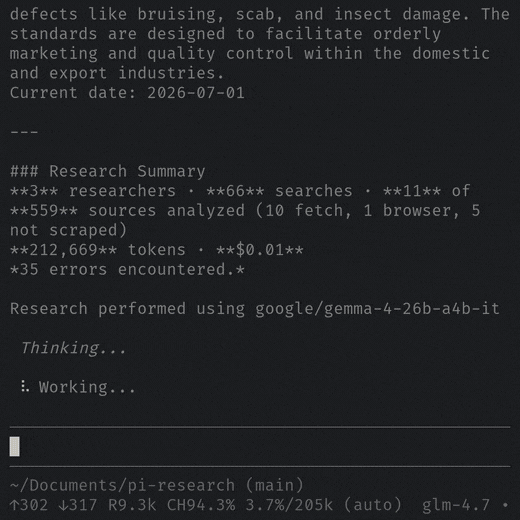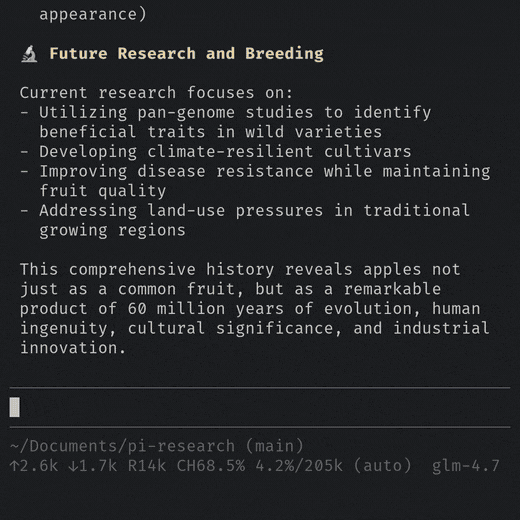
A research run loops through agent teams: a coordinator plans and opens with a search, researcher agents scrape and read in parallel, and a research lead decides whether to go another round — then writes the report from every report collected. The result is one cited Markdown report with findings optionally saved to the knowledge store.
|
|
52
52
|
|
|
53
|
-
Three depth levels (normal, deep, ultra) set the team size and number of rounds.
|
|
53
|
+
Three depth levels (normal, deep, ultra) set the team size and number of rounds. A natural-language request is enough — the tool picks the right one:
|
|
54
54
|
|
|
55
55
|
|
|
56
56
|
|
|
57
57
|
### Use cases
|
|
58
58
|
|
|
59
|
-
- Researching
|
|
60
|
-
- Researching from Claude Code, Codex, or another coding agent while a cheaper or local model drives the run so it doesn't spend
|
|
59
|
+
- Researching inside pi. Plug and play with no API key needed.
|
|
60
|
+
- Researching from Claude Code, Codex, or another coding agent while a cheaper or local model drives the run, so it doesn't spend the main agent's budget.
|
|
61
61
|
- Keeping a persistent and searchable knowledge store of findings, scoped globally or per project.
|
|
62
|
-
- Building agent systems that find and read web content or populating a dataset of web sources.
|
|
62
|
+
- Building agent systems that find and read web content, or populating a dataset of web sources.
|
|
63
63
|
|
|
64
64
|
### Why pi-research
|
|
65
65
|
|
|
66
66
|
- **No quota and no monthly fee.** Most AI search providers cap free searches and then charge, with results served from their index on their servers. pi-research searches and scrapes locally through DuckDuckGo in a stealth browser.
|
|
67
|
-
- **
|
|
68
|
-
- **Cited reports rather than raw dumps.**
|
|
69
|
-
- **Read-only by design.** The research agent cannot run shell commands or write, edit, or delete anything
|
|
67
|
+
- **The index stays local.** Every finding can be saved to a local [LanceDB](https://lancedb.com) knowledge store that seeds future runs, so repeat questions get faster and cheaper answers.
|
|
68
|
+
- **Cited reports rather than raw dumps.** Each run returns one sourced Markdown report instead of raw web content pasted into the conversation. Context efficient and easy to verify.
|
|
69
|
+
- **Read-only by design.** The research agent cannot run shell commands or write, edit, or delete anything — the right shape for an agent whose whole job is reading untrusted web pages. Prompt injection picked up mid-run has nothing to act on.
|
|
70
70
|
- **Search a little or a lot.** Depth levels span a quick pass to a large-scale investigation.
|
|
71
71
|
|
|
72
72
|
### Requirements / limitations
|
|
73
73
|
|
|
74
74
|
- Node.js >= 22.19.0
|
|
75
|
-
- An LLM with a 100k+ context window (
|
|
75
|
+
- An LLM with a 100k+ context window (an API key or a local model)
|
|
76
76
|
- Internet access on a residential IP, since search, scraping, and YouTube transcripts get bot-blocked from datacenter/VPS/cloud IPs
|
|
77
77
|
- pi. The pi extension uses the host's copy while the standalone CLI and agent skill install it as a dependency.
|
|
78
|
-
- Cloudflare and similar systems block scraping on some sites. A run flags pages
|
|
78
|
+
- Cloudflare and similar systems block scraping on some sites. A run flags unreachable pages and compensates with a wide pool of search results to cite.
|
|
79
79
|
|
|
80
80
|
### Channels
|
|
81
81
|
|
|
@@ -2,7 +2,7 @@
|
|
|
2
2
|
name: pi-research
|
|
3
3
|
description: "Multi-agent web research for any coding agent. Use for anything requiring current information from the internet — news, trends, product/service/company facts, statistics, people, places, events, APIs, library behavior, or 'what is X / how does X work' questions. Also use to search a local knowledge store of previously researched findings before doing live research. Powered by the pi-research engine (search, stealth scraping, security databases, Stack Exchange). Not for reading local files, running project commands, or analyzing this repository's own source."
|
|
4
4
|
license: MIT
|
|
5
|
-
metadata: { "author": "Lincoln Deen", "version": "1.
|
|
5
|
+
metadata: { "author": "Lincoln Deen", "version": "1.6.1", "package": "@lincoln504/pi-research", "engine": "pi-research-sdk", "openclaw": { "requires": { "bins": ["node"] } } }
|
|
6
6
|
allowed-tools: Bash(node:*)
|
|
7
7
|
---
|
|
8
8
|
|
package/dist/cli.mjs
CHANGED
|
@@ -2216,6 +2216,29 @@ function lastCitedLinksHeader(text) {
|
|
|
2216
2216
|
}
|
|
2217
2217
|
return { lineStart, textStart };
|
|
2218
2218
|
}
|
|
2219
|
+
function stripReportPreamble(text) {
|
|
2220
|
+
const trimmed = text.trimStart();
|
|
2221
|
+
const breakAt = trimmed.indexOf("\n\n");
|
|
2222
|
+
if (breakAt < 0) return { body: text, preamble: "" };
|
|
2223
|
+
const head = trimmed.slice(0, breakAt).trim();
|
|
2224
|
+
const rest = trimmed.slice(breakAt + 2).trimStart();
|
|
2225
|
+
if (head.includes("\n")) return { body: text, preamble: "" };
|
|
2226
|
+
if (!rest) return { body: text, preamble: "" };
|
|
2227
|
+
if (!REPORT_NARRATION_OPENER.test(head)) return { body: text, preamble: "" };
|
|
2228
|
+
if (!REPORT_NARRATION_SUBJECT.test(head)) return { body: text, preamble: "" };
|
|
2229
|
+
return { body: rest, preamble: head };
|
|
2230
|
+
}
|
|
2231
|
+
function synthesisProseBody(text) {
|
|
2232
|
+
const { lineStart } = lastCitedLinksHeader(text);
|
|
2233
|
+
return (lineStart < 0 ? text : text.slice(0, lineStart)).trim();
|
|
2234
|
+
}
|
|
2235
|
+
function isAnalysisFreeSynthesis(text, minProseChars) {
|
|
2236
|
+
const prose = synthesisProseBody(text);
|
|
2237
|
+
const stripped = prose.replace(/^[ \t]*(?:#{1,6}[ \t]*|>[ \t]*|\*\*)/gm, "").trim();
|
|
2238
|
+
if (minProseChars > 0 && stripped.length < minProseChars) return true;
|
|
2239
|
+
if (!/[.!?。!?।॥۔؟።]/.test(stripped)) return true;
|
|
2240
|
+
return false;
|
|
2241
|
+
}
|
|
2219
2242
|
function parseCitations(report) {
|
|
2220
2243
|
const headerIdx = lastCitedLinksHeaderIndex(report);
|
|
2221
2244
|
if (headerIdx < 0) return [];
|
|
@@ -2268,11 +2291,14 @@ function parseCitations(report) {
|
|
|
2268
2291
|
}
|
|
2269
2292
|
return citations;
|
|
2270
2293
|
}
|
|
2294
|
+
var REPORT_NARRATION_OPENER, REPORT_NARRATION_SUBJECT;
|
|
2271
2295
|
var init_text_utils = __esm({
|
|
2272
2296
|
"src/utils/text-utils.ts"() {
|
|
2273
2297
|
"use strict";
|
|
2274
2298
|
init_logger();
|
|
2275
2299
|
init_url_utils();
|
|
2300
|
+
REPORT_NARRATION_OPENER = /^(?:I|I'll|I'm|Let me|Now I|Next I|First,? I)\b/i;
|
|
2301
|
+
REPORT_NARRATION_SUBJECT = /\b(?:report|synthesi[sz]\w*|findings|material|sources|scraped|gathered|research\w*|summar\w+)\b/i;
|
|
2276
2302
|
}
|
|
2277
2303
|
});
|
|
2278
2304
|
|
|
@@ -3217,7 +3243,7 @@ function getMaxScrapeBatches(config, cachingActive = false) {
|
|
|
3217
3243
|
function resolveExcludedTools(callerExclusions, configDisabled = []) {
|
|
3218
3244
|
return [.../* @__PURE__ */ new Set([...DEFAULT_EXCLUDED_TOOLS, ...callerExclusions ?? [], ...configDisabled])];
|
|
3219
3245
|
}
|
|
3220
|
-
var MAX_GATHERING_CALLS, MAX_GREP_CALLS, MAX_SCRAPE_URLS, MAX_TEAM_SIZE_LEVEL_1, MAX_TEAM_SIZE_LEVEL_2, MAX_TEAM_SIZE_LEVEL_3, MAX_ROUNDS_LEVEL_1, MAX_ROUNDS_LEVEL_2, MAX_ROUNDS_LEVEL_3, MAX_EXTRA_ROUNDS_WITH_STEERING, OSV_TIMEOUT_MS, WEBGPU_PROBE_TIMEOUT_MS, MAX_QUERY_LENGTH, MAX_FILENAME_QUERY_LENGTH, MIN_QUERY_LENGTH, MAX_EXPORT_RETRIES, DEFAULT_MAX_RETRIES, DEFAULT_INITIAL_DELAY_MS, DEFAULT_MAX_DELAY_MS, DEFAULT_MODEL_CONTEXT_WINDOW, BATCH_2_DEFAULT_CONCURRENCY, MAX_SCRAPE_CONTENT_CHARS_PER_DOC, RESEARCHER_LAUNCH_DELAY_MS, MAX_QUERIES_PER_RESEARCHER_LEVEL_1, MAX_QUERIES_PER_RESEARCHER_LEVEL_2, MAX_QUERIES_PER_RESEARCHER_LEVEL_3, DEFAULT_EXCLUDED_TOOLS, RESEARCH_TOOL_NAMES;
|
|
3246
|
+
var MAX_GATHERING_CALLS, MAX_GREP_CALLS, MAX_SCRAPE_URLS, MAX_TEAM_SIZE_LEVEL_1, MAX_TEAM_SIZE_LEVEL_2, MAX_TEAM_SIZE_LEVEL_3, MAX_ROUNDS_LEVEL_1, MAX_ROUNDS_LEVEL_2, MAX_ROUNDS_LEVEL_3, MAX_EXTRA_ROUNDS_WITH_STEERING, OSV_TIMEOUT_MS, WEBGPU_PROBE_TIMEOUT_MS, MAX_QUERY_LENGTH, MAX_FILENAME_QUERY_LENGTH, MIN_QUERY_LENGTH, MAX_EXPORT_RETRIES, DEFAULT_MAX_RETRIES, DEFAULT_INITIAL_DELAY_MS, DEFAULT_MAX_DELAY_MS, DEFAULT_MODEL_CONTEXT_WINDOW, BATCH_2_DEFAULT_CONCURRENCY, MAX_SCRAPE_CONTENT_CHARS_PER_DOC, RESEARCHER_LAUNCH_DELAY_MS, MAX_QUERIES_PER_RESEARCHER_LEVEL_1, MAX_QUERIES_PER_RESEARCHER_LEVEL_2, MAX_QUERIES_PER_RESEARCHER_LEVEL_3, DEFAULT_EXCLUDED_TOOLS, MIN_SYNTHESIS_PROSE_CHARS, QUICK_THIN_REPORT_NOTICE, SYNTHESIS_FALLBACK_NOTICE, RESEARCH_TOOL_NAMES;
|
|
3221
3247
|
var init_constants = __esm({
|
|
3222
3248
|
"src/constants.ts"() {
|
|
3223
3249
|
"use strict";
|
|
@@ -3249,6 +3275,9 @@ var init_constants = __esm({
|
|
|
3249
3275
|
MAX_QUERIES_PER_RESEARCHER_LEVEL_2 = 15;
|
|
3250
3276
|
MAX_QUERIES_PER_RESEARCHER_LEVEL_3 = 20;
|
|
3251
3277
|
DEFAULT_EXCLUDED_TOOLS = ["grep"];
|
|
3278
|
+
MIN_SYNTHESIS_PROSE_CHARS = 800;
|
|
3279
|
+
QUICK_THIN_REPORT_NOTICE = "_Note: this run did not produce a substantive write-up. The sources below were retrieved and are cited accurately, but the summary above should not be treated as a complete answer \u2014 consider re-running, or running at a deeper level._";
|
|
3280
|
+
SYNTHESIS_FALLBACK_NOTICE = "_Note: the synthesis step did not produce a usable summary for this run, so the individual researcher reports are included below in full. The sources cited at the end of this document are unaffected._";
|
|
3252
3281
|
RESEARCH_TOOL_NAMES = [
|
|
3253
3282
|
"search",
|
|
3254
3283
|
"scrape",
|
|
@@ -7273,11 +7302,10 @@ function assertValidEmbeddingVectors(vectors, expectedCount, declaredDim) {
|
|
|
7273
7302
|
}
|
|
7274
7303
|
}
|
|
7275
7304
|
async function addDocumentsToStore(table, docs, embedder, isClosing, workspace, isGlobal) {
|
|
7276
|
-
if (docs.length === 0) return;
|
|
7305
|
+
if (docs.length === 0) return "empty";
|
|
7277
7306
|
if (isClosing()) {
|
|
7278
7307
|
logger.warn("[store] Ignoring addDocuments during close");
|
|
7279
|
-
|
|
7280
|
-
return;
|
|
7308
|
+
return "ignored_closing";
|
|
7281
7309
|
}
|
|
7282
7310
|
const startTime = Date.now();
|
|
7283
7311
|
try {
|
|
@@ -7297,14 +7325,13 @@ async function addDocumentsToStore(table, docs, embedder, isClosing, workspace,
|
|
|
7297
7325
|
await table.add(data);
|
|
7298
7326
|
const duration = Date.now() - startTime;
|
|
7299
7327
|
metrics.observe("knowledge_store_add_documents_duration_ms", duration);
|
|
7300
|
-
metrics.increment("knowledge_store_add_documents_total", 1, { status: "success" });
|
|
7301
7328
|
metrics.increment("knowledge_store_chunks_added_total", docs.length);
|
|
7302
7329
|
logger.log(`[store] Added ${docs.length} chunk(s) for ${docs[0]?.url} [workspace=${workspace}, global=${isGlobal}]`);
|
|
7330
|
+
return "written";
|
|
7303
7331
|
} catch (err) {
|
|
7304
7332
|
const duration = Date.now() - startTime;
|
|
7305
7333
|
metrics.observe("knowledge_store_add_documents_duration_ms", duration, { status: "error" });
|
|
7306
|
-
|
|
7307
|
-
logger.error("[store] Failed to add documents:", err);
|
|
7334
|
+
logger.debug(`[store] add attempt failed after ${duration}ms: ${err instanceof Error ? err.message : String(err)}`);
|
|
7308
7335
|
throw err;
|
|
7309
7336
|
}
|
|
7310
7337
|
}
|
|
@@ -7876,18 +7903,19 @@ var init_store = __esm({
|
|
|
7876
7903
|
try {
|
|
7877
7904
|
if (this.isClosing) {
|
|
7878
7905
|
logger.warn(`[store] Skipping addDocuments \u2014 store is closing`);
|
|
7906
|
+
metrics.increment("knowledge_store_add_documents_total", 1, { status: "ignored_closing" });
|
|
7879
7907
|
return;
|
|
7880
7908
|
}
|
|
7881
7909
|
let table = await this.getFreshTable();
|
|
7882
7910
|
const workspace = this.getWorkspace();
|
|
7883
|
-
await this.withEmbedderReconnect(async (embedder) => {
|
|
7911
|
+
const outcome = await this.withEmbedderReconnect(async (embedder) => {
|
|
7884
7912
|
let retryCount = 0;
|
|
7885
7913
|
const MAX_RETRIES = 5;
|
|
7886
7914
|
const BASE_DELAY = 100;
|
|
7887
7915
|
while (retryCount <= MAX_RETRIES) {
|
|
7888
7916
|
try {
|
|
7889
7917
|
const isGlobal = this.options.knowledgeMode === "global";
|
|
7890
|
-
await addDocumentsToStore(
|
|
7918
|
+
return await addDocumentsToStore(
|
|
7891
7919
|
table,
|
|
7892
7920
|
docs,
|
|
7893
7921
|
embedder,
|
|
@@ -7895,7 +7923,6 @@ var init_store = __esm({
|
|
|
7895
7923
|
workspace,
|
|
7896
7924
|
isGlobal
|
|
7897
7925
|
);
|
|
7898
|
-
return;
|
|
7899
7926
|
} catch (err) {
|
|
7900
7927
|
if (isLanceCommitConflict(err)) {
|
|
7901
7928
|
retryCount++;
|
|
@@ -7909,7 +7936,17 @@ var init_store = __esm({
|
|
|
7909
7936
|
throw err;
|
|
7910
7937
|
}
|
|
7911
7938
|
}
|
|
7939
|
+
throw new Error("[store] addDocuments retry loop exited without result");
|
|
7912
7940
|
});
|
|
7941
|
+
if (outcome !== "empty") {
|
|
7942
|
+
metrics.increment("knowledge_store_add_documents_total", 1, {
|
|
7943
|
+
status: outcome === "ignored_closing" ? "ignored_closing" : "success"
|
|
7944
|
+
});
|
|
7945
|
+
}
|
|
7946
|
+
} catch (err) {
|
|
7947
|
+
metrics.increment("knowledge_store_add_documents_total", 1, { status: "error" });
|
|
7948
|
+
logger.error("[store] Failed to add documents:", err);
|
|
7949
|
+
throw err;
|
|
7913
7950
|
} finally {
|
|
7914
7951
|
this.activeWrites.delete(writePromise);
|
|
7915
7952
|
writeResolve();
|
|
@@ -12436,6 +12473,101 @@ function getClientAgent() {
|
|
|
12436
12473
|
return clientAgent;
|
|
12437
12474
|
}
|
|
12438
12475
|
|
|
12476
|
+
// src/infrastructure/browser/browser-error-utils.ts
|
|
12477
|
+
init_circuit_breaker();
|
|
12478
|
+
function isTransientSocketError(error) {
|
|
12479
|
+
if (!error || typeof error !== "object") return false;
|
|
12480
|
+
const err = error;
|
|
12481
|
+
return typeof err.message === "string" && (err.message.includes("ECONNREFUSED") || err.message.includes("ECONNRESET") || err.message.includes("socket hang up") || err.message.includes("EPIPE") || err.message.includes("ETIMEDOUT") || err.message.includes("timed out") || err.message.includes("pool busy") || err.message.includes("unreachable") || // WorkerPoolManager throws this during the window between forceSchedulerRestart
|
|
12482
|
+
// clearing the scheduler reference and the old pool's 1500ms drain completing.
|
|
12483
|
+
// It is a transient state — retry after a short delay succeeds once drain finishes.
|
|
12484
|
+
err.message.includes("Worker pool is shutting down") || // Poolifier throws this when pool.execute() is called while the pool is being
|
|
12485
|
+
// destroyed (e.g., during scheduler restart). Treat as transient — the pool will
|
|
12486
|
+
// be ready for new tasks once destruction completes and a new pool is initialized.
|
|
12487
|
+
err.message.includes("Cannot execute a task on destroying pool") || err.message.includes("destroying pool") || // The leader answered 503 because it is shutting down after losing
|
|
12488
|
+
// leadership. Retrying re-elects and reaches the new leader, so this is
|
|
12489
|
+
// transient in exactly the same sense as a pool drain.
|
|
12490
|
+
err.message.includes("Browser pool leader is draining"));
|
|
12491
|
+
}
|
|
12492
|
+
function isCloudflareBlockError(error) {
|
|
12493
|
+
if (!error || typeof error !== "object") return false;
|
|
12494
|
+
const err = error;
|
|
12495
|
+
return typeof err.message === "string" && (err.message.includes("Fetch blocked: Cloudflare") || err.message.includes("Cloudflare challenge"));
|
|
12496
|
+
}
|
|
12497
|
+
function isTaskTimeoutError(error) {
|
|
12498
|
+
if (!error || typeof error !== "object") return false;
|
|
12499
|
+
const err = error;
|
|
12500
|
+
return typeof err.message === "string" && (err.message.includes("timed out after") || err.message.includes("Search task timed out") || err.message.includes("Scrape task timed out") || err.message.includes("Health check timed out") || err.message.includes("[BrowserClient] Request to"));
|
|
12501
|
+
}
|
|
12502
|
+
function isServerDrainingError(error) {
|
|
12503
|
+
if (!error || typeof error !== "object") return false;
|
|
12504
|
+
const err = error;
|
|
12505
|
+
return typeof err.message === "string" && err.message.includes("Browser pool leader is draining");
|
|
12506
|
+
}
|
|
12507
|
+
function isPoolShutdownError(error) {
|
|
12508
|
+
if (!error || typeof error !== "object") return false;
|
|
12509
|
+
const err = error;
|
|
12510
|
+
return typeof err.message === "string" && (err.message.includes("Worker pool is shutting down") || err.message.includes("Cannot execute a task on destroying pool") || err.message.includes("destroying pool") || // worker-pool-manager throws this when auto-recovery is still swapping the
|
|
12511
|
+
// pool. Its own text says "please retry", but until it was listed here no
|
|
12512
|
+
// classifier matched it, so the first attempt rethrew instead of retrying —
|
|
12513
|
+
// and auto-recovery fires only after 3 consecutive worker failures, i.e.
|
|
12514
|
+
// exactly when a burst of tasks is in flight and would all die together.
|
|
12515
|
+
err.message.includes("Worker pool is being reset") || // poolifier's wording once destroy() has COMPLETED (vs "destroying pool"
|
|
12516
|
+
// while it is in progress). A queued closure holding a pool captured before
|
|
12517
|
+
// an auto-recovery destroy dispatches into exactly this window; it is the
|
|
12518
|
+
// same transient swap the "being reset" string covers, not a hard fault.
|
|
12519
|
+
err.message.includes("Cannot execute a task on not started pool"));
|
|
12520
|
+
}
|
|
12521
|
+
var BENIGN_NAVIGATION_FAILURE = /page\.goto: (?:Timeout \d+ *ms exceeded|net::|NS_ERROR_|SEC_ERROR_|MOZILLA_PKIX_ERROR_)/;
|
|
12522
|
+
function isBenignScrapeFailure(error) {
|
|
12523
|
+
const msg2 = error instanceof Error ? error.message : String(error);
|
|
12524
|
+
return msg2.startsWith("Fetch blocked:") || // bot-protection interstitial (Cloudflare, DDoS-Guard, …)
|
|
12525
|
+
msg2.startsWith("Fetch returned stub:") || // nav-only / near-empty page
|
|
12526
|
+
msg2.startsWith("Could not extract content from PDF") || // malformed/encrypted/scanned-only PDF
|
|
12527
|
+
msg2.startsWith("PDF too large") || // exceeds the deliberate 100MB policy cap
|
|
12528
|
+
msg2.startsWith("Unsupported download:") || // attachment-served non-PDF (zip/xlsx/…) — nothing to extract
|
|
12529
|
+
BENIGN_NAVIGATION_FAILURE.test(msg2) || // remote TLS/DNS/timeout — the URL could not be loaded
|
|
12530
|
+
msg2.startsWith("HTML response too large") || // fetch-layer 25MB policy cap — same class as the PDF cap
|
|
12531
|
+
msg2.startsWith("Browser HTML too large") || // browser-layer 25MB policy cap
|
|
12532
|
+
/^HTTP \d{3}\b/.test(msg2) || // remote 4xx/5xx status
|
|
12533
|
+
isCloudflareBlockError(error) || isTaskTimeoutError(error) || isPoolShutdownError(error);
|
|
12534
|
+
}
|
|
12535
|
+
var sessionCircuitBreakers = /* @__PURE__ */ new Map();
|
|
12536
|
+
var MAX_SESSION_BREAKERS = 256;
|
|
12537
|
+
var DEFAULT_BREAKER_CONFIG = {
|
|
12538
|
+
// Raised from 3→8: parallel search bursts of 20 queries frequently produce
|
|
12539
|
+
// simultaneous timeouts on slow/CF-protected sites. A threshold of 3 caused
|
|
12540
|
+
// the breaker to open mid-burst, blocking all subsequent requests for the round.
|
|
12541
|
+
failureThreshold: 8,
|
|
12542
|
+
// Raised from 15s→45s: enough time for one full search burst + retry window
|
|
12543
|
+
// to complete before the breaker attempts to half-open.
|
|
12544
|
+
resetTimeoutMs: 45e3,
|
|
12545
|
+
name: "BrowserPool",
|
|
12546
|
+
isTransientError: (error) => {
|
|
12547
|
+
if (isPoolShutdownError(error)) return false;
|
|
12548
|
+
if (isServerDrainingError(error)) return false;
|
|
12549
|
+
if (isCloudflareBlockError(error)) return false;
|
|
12550
|
+
if (isTaskTimeoutError(error)) return false;
|
|
12551
|
+
return isTransientSocketError(error);
|
|
12552
|
+
}
|
|
12553
|
+
};
|
|
12554
|
+
function getBrowserCircuitBreaker(sessionId) {
|
|
12555
|
+
let breaker2 = sessionCircuitBreakers.get(sessionId);
|
|
12556
|
+
if (!breaker2) {
|
|
12557
|
+
if (sessionCircuitBreakers.size >= MAX_SESSION_BREAKERS) {
|
|
12558
|
+
const oldest = sessionCircuitBreakers.keys().next().value;
|
|
12559
|
+
if (oldest !== void 0) sessionCircuitBreakers.delete(oldest);
|
|
12560
|
+
}
|
|
12561
|
+
breaker2 = new CircuitBreaker({ ...DEFAULT_BREAKER_CONFIG, name: `BrowserPool-${sessionId}` });
|
|
12562
|
+
sessionCircuitBreakers.set(sessionId, breaker2);
|
|
12563
|
+
}
|
|
12564
|
+
return breaker2;
|
|
12565
|
+
}
|
|
12566
|
+
function clearSessionCircuitBreaker(sessionId) {
|
|
12567
|
+
sessionCircuitBreakers.delete(sessionId);
|
|
12568
|
+
}
|
|
12569
|
+
var browserCircuitBreaker = new CircuitBreaker(DEFAULT_BREAKER_CONFIG);
|
|
12570
|
+
|
|
12439
12571
|
// src/infrastructure/browser/browser-client.ts
|
|
12440
12572
|
var CLIENT_PATIENCE_MARGIN_MS = 15e3;
|
|
12441
12573
|
var CLIENT_TIMEOUT_CAP_MS = 3e5;
|
|
@@ -12597,12 +12729,16 @@ var BrowserClient = class {
|
|
|
12597
12729
|
errorType = "unknown";
|
|
12598
12730
|
}
|
|
12599
12731
|
const error = new Error(errorMsg);
|
|
12600
|
-
|
|
12601
|
-
|
|
12602
|
-
|
|
12603
|
-
|
|
12604
|
-
|
|
12605
|
-
|
|
12732
|
+
if (isTransientSocketError(error)) {
|
|
12733
|
+
logger.debug(`[BrowserClient] Transient failure talking to http://127.0.0.1:${this.port}${path20} (caller will retry): ${errorMsg}`);
|
|
12734
|
+
} else {
|
|
12735
|
+
logger.error(`[BrowserClient] Request to http://127.0.0.1:${this.port}${path20} failed:`, errorMsg);
|
|
12736
|
+
errorTracker.trackError(error, {
|
|
12737
|
+
component: "browser-manager",
|
|
12738
|
+
operation,
|
|
12739
|
+
errorType
|
|
12740
|
+
});
|
|
12741
|
+
}
|
|
12606
12742
|
reject(error);
|
|
12607
12743
|
});
|
|
12608
12744
|
req.write(JSON.stringify(data));
|
|
@@ -12644,89 +12780,6 @@ init_logger();
|
|
|
12644
12780
|
init_http_body();
|
|
12645
12781
|
import * as http5 from "node:http";
|
|
12646
12782
|
import * as crypto5 from "node:crypto";
|
|
12647
|
-
|
|
12648
|
-
// src/infrastructure/browser/browser-error-utils.ts
|
|
12649
|
-
init_circuit_breaker();
|
|
12650
|
-
function isTransientSocketError(error) {
|
|
12651
|
-
if (!error || typeof error !== "object") return false;
|
|
12652
|
-
const err = error;
|
|
12653
|
-
return typeof err.message === "string" && (err.message.includes("ECONNREFUSED") || err.message.includes("ECONNRESET") || err.message.includes("socket hang up") || err.message.includes("EPIPE") || err.message.includes("ETIMEDOUT") || err.message.includes("timed out") || err.message.includes("pool busy") || err.message.includes("unreachable") || // WorkerPoolManager throws this during the window between forceSchedulerRestart
|
|
12654
|
-
// clearing the scheduler reference and the old pool's 1500ms drain completing.
|
|
12655
|
-
// It is a transient state — retry after a short delay succeeds once drain finishes.
|
|
12656
|
-
err.message.includes("Worker pool is shutting down") || // Poolifier throws this when pool.execute() is called while the pool is being
|
|
12657
|
-
// destroyed (e.g., during scheduler restart). Treat as transient — the pool will
|
|
12658
|
-
// be ready for new tasks once destruction completes and a new pool is initialized.
|
|
12659
|
-
err.message.includes("Cannot execute a task on destroying pool") || err.message.includes("destroying pool") || // The leader answered 503 because it is shutting down after losing
|
|
12660
|
-
// leadership. Retrying re-elects and reaches the new leader, so this is
|
|
12661
|
-
// transient in exactly the same sense as a pool drain.
|
|
12662
|
-
err.message.includes("Browser pool leader is draining"));
|
|
12663
|
-
}
|
|
12664
|
-
function isCloudflareBlockError(error) {
|
|
12665
|
-
if (!error || typeof error !== "object") return false;
|
|
12666
|
-
const err = error;
|
|
12667
|
-
return typeof err.message === "string" && (err.message.includes("Fetch blocked: Cloudflare") || err.message.includes("Cloudflare challenge"));
|
|
12668
|
-
}
|
|
12669
|
-
function isTaskTimeoutError(error) {
|
|
12670
|
-
if (!error || typeof error !== "object") return false;
|
|
12671
|
-
const err = error;
|
|
12672
|
-
return typeof err.message === "string" && (err.message.includes("timed out after") || err.message.includes("Search task timed out") || err.message.includes("Scrape task timed out") || err.message.includes("Health check timed out") || err.message.includes("[BrowserClient] Request to"));
|
|
12673
|
-
}
|
|
12674
|
-
function isServerDrainingError(error) {
|
|
12675
|
-
if (!error || typeof error !== "object") return false;
|
|
12676
|
-
const err = error;
|
|
12677
|
-
return typeof err.message === "string" && err.message.includes("Browser pool leader is draining");
|
|
12678
|
-
}
|
|
12679
|
-
function isPoolShutdownError(error) {
|
|
12680
|
-
if (!error || typeof error !== "object") return false;
|
|
12681
|
-
const err = error;
|
|
12682
|
-
return typeof err.message === "string" && (err.message.includes("Worker pool is shutting down") || err.message.includes("Cannot execute a task on destroying pool") || err.message.includes("destroying pool") || // worker-pool-manager throws this when auto-recovery is still swapping the
|
|
12683
|
-
// pool. Its own text says "please retry", but until it was listed here no
|
|
12684
|
-
// classifier matched it, so the first attempt rethrew instead of retrying —
|
|
12685
|
-
// and auto-recovery fires only after 3 consecutive worker failures, i.e.
|
|
12686
|
-
// exactly when a burst of tasks is in flight and would all die together.
|
|
12687
|
-
err.message.includes("Worker pool is being reset") || // poolifier's wording once destroy() has COMPLETED (vs "destroying pool"
|
|
12688
|
-
// while it is in progress). A queued closure holding a pool captured before
|
|
12689
|
-
// an auto-recovery destroy dispatches into exactly this window; it is the
|
|
12690
|
-
// same transient swap the "being reset" string covers, not a hard fault.
|
|
12691
|
-
err.message.includes("Cannot execute a task on not started pool"));
|
|
12692
|
-
}
|
|
12693
|
-
var sessionCircuitBreakers = /* @__PURE__ */ new Map();
|
|
12694
|
-
var MAX_SESSION_BREAKERS = 256;
|
|
12695
|
-
var DEFAULT_BREAKER_CONFIG = {
|
|
12696
|
-
// Raised from 3→8: parallel search bursts of 20 queries frequently produce
|
|
12697
|
-
// simultaneous timeouts on slow/CF-protected sites. A threshold of 3 caused
|
|
12698
|
-
// the breaker to open mid-burst, blocking all subsequent requests for the round.
|
|
12699
|
-
failureThreshold: 8,
|
|
12700
|
-
// Raised from 15s→45s: enough time for one full search burst + retry window
|
|
12701
|
-
// to complete before the breaker attempts to half-open.
|
|
12702
|
-
resetTimeoutMs: 45e3,
|
|
12703
|
-
name: "BrowserPool",
|
|
12704
|
-
isTransientError: (error) => {
|
|
12705
|
-
if (isPoolShutdownError(error)) return false;
|
|
12706
|
-
if (isServerDrainingError(error)) return false;
|
|
12707
|
-
if (isCloudflareBlockError(error)) return false;
|
|
12708
|
-
if (isTaskTimeoutError(error)) return false;
|
|
12709
|
-
return isTransientSocketError(error);
|
|
12710
|
-
}
|
|
12711
|
-
};
|
|
12712
|
-
function getBrowserCircuitBreaker(sessionId) {
|
|
12713
|
-
let breaker2 = sessionCircuitBreakers.get(sessionId);
|
|
12714
|
-
if (!breaker2) {
|
|
12715
|
-
if (sessionCircuitBreakers.size >= MAX_SESSION_BREAKERS) {
|
|
12716
|
-
const oldest = sessionCircuitBreakers.keys().next().value;
|
|
12717
|
-
if (oldest !== void 0) sessionCircuitBreakers.delete(oldest);
|
|
12718
|
-
}
|
|
12719
|
-
breaker2 = new CircuitBreaker({ ...DEFAULT_BREAKER_CONFIG, name: `BrowserPool-${sessionId}` });
|
|
12720
|
-
sessionCircuitBreakers.set(sessionId, breaker2);
|
|
12721
|
-
}
|
|
12722
|
-
return breaker2;
|
|
12723
|
-
}
|
|
12724
|
-
function clearSessionCircuitBreaker(sessionId) {
|
|
12725
|
-
sessionCircuitBreakers.delete(sessionId);
|
|
12726
|
-
}
|
|
12727
|
-
var browserCircuitBreaker = new CircuitBreaker(DEFAULT_BREAKER_CONFIG);
|
|
12728
|
-
|
|
12729
|
-
// src/infrastructure/browser/browser-server.ts
|
|
12730
12783
|
var _authSecret = null;
|
|
12731
12784
|
function getOrCreateAuthSecret() {
|
|
12732
12785
|
if (!_authSecret) {
|
|
@@ -12868,6 +12921,8 @@ var BrowserServer = class {
|
|
|
12868
12921
|
logger.warn("[BrowserServer] Request blocked by bot protection:", error instanceof Error ? error.message : String(error));
|
|
12869
12922
|
} else if (isPoolShutdownError(error)) {
|
|
12870
12923
|
logger.debug("[BrowserServer] Request abandoned during shutdown:", error instanceof Error ? error.message : String(error));
|
|
12924
|
+
} else if (isBenignScrapeFailure(error)) {
|
|
12925
|
+
logger.debug("[BrowserServer] Expected per-URL scrape outcome:", error instanceof Error ? error.message.split("\n")[0] : String(error));
|
|
12871
12926
|
} else {
|
|
12872
12927
|
logger.error("[BrowserServer] Error handling request:", error);
|
|
12873
12928
|
}
|
|
@@ -18060,17 +18115,6 @@ import * as dnsCb from "node:dns";
|
|
|
18060
18115
|
import * as net3 from "node:net";
|
|
18061
18116
|
import crypto9 from "node:crypto";
|
|
18062
18117
|
import { NodeHtmlMarkdown } from "node-html-markdown";
|
|
18063
|
-
function isBenignScrapeFailure(error) {
|
|
18064
|
-
const msg2 = error instanceof Error ? error.message : String(error);
|
|
18065
|
-
return msg2.startsWith("Fetch blocked:") || // bot-protection interstitial (Cloudflare, DDoS-Guard, …)
|
|
18066
|
-
msg2.startsWith("Fetch returned stub:") || // nav-only / near-empty page
|
|
18067
|
-
msg2.startsWith("Could not extract content from PDF") || // malformed/encrypted/scanned-only PDF
|
|
18068
|
-
msg2.startsWith("PDF too large") || // exceeds the deliberate 100MB policy cap
|
|
18069
|
-
msg2.startsWith("HTML response too large") || // fetch-layer 25MB policy cap — same class as the PDF cap
|
|
18070
|
-
msg2.startsWith("Browser HTML too large") || // browser-layer 25MB policy cap
|
|
18071
|
-
/^HTTP \d{3}\b/.test(msg2) || // remote 4xx/5xx status
|
|
18072
|
-
isCloudflareBlockError(error) || isTaskTimeoutError(error) || isPoolShutdownError(error);
|
|
18073
|
-
}
|
|
18074
18118
|
function getRandomUserAgent() {
|
|
18075
18119
|
try {
|
|
18076
18120
|
const index = crypto9.randomInt(0, USER_AGENTS.length);
|
|
@@ -21971,9 +22015,14 @@ async function doMint(identifiers, opts) {
|
|
|
21971
22015
|
const requestKey = opts.requestKey || process.env["PI_RESEARCH_YOUTUBE_POTOKEN_REQUEST_KEY"] || DEFAULT_REQUEST_KEY;
|
|
21972
22016
|
const fetchImpl = opts.fetchImpl ?? fetch;
|
|
21973
22017
|
const started = Date.now();
|
|
21974
|
-
const
|
|
21975
|
-
|
|
21976
|
-
|
|
22018
|
+
const [bgGuard, bgWebPo, bgUtils] = await Promise.all([
|
|
22019
|
+
import("bgutils-js/botguard"),
|
|
22020
|
+
import("bgutils-js/webpo"),
|
|
22021
|
+
import("bgutils-js/utils")
|
|
22022
|
+
]);
|
|
22023
|
+
const { getChallenge, BotGuardClient } = bgGuard;
|
|
22024
|
+
const { WebPoMinter } = bgWebPo;
|
|
22025
|
+
const { buildURL: buildURL2, getHeaders } = bgUtils;
|
|
21977
22026
|
const { JSDOM } = await import("jsdom");
|
|
21978
22027
|
const dom = new JSDOM('<!DOCTYPE html><html lang="en"><body></body></html>', {
|
|
21979
22028
|
url: "https://www.youtube.com/"
|
|
@@ -22004,24 +22053,24 @@ async function doMint(identifiers, opts) {
|
|
|
22004
22053
|
};
|
|
22005
22054
|
bridge();
|
|
22006
22055
|
try {
|
|
22007
|
-
const
|
|
22008
|
-
|
|
22056
|
+
const challenge = await getChallenge({
|
|
22057
|
+
requestKey,
|
|
22058
|
+
fetchFunction: ((input, init) => fetchImpl(input, {
|
|
22009
22059
|
...init,
|
|
22010
22060
|
signal: init?.signal ?? opts.signal
|
|
22011
|
-
})
|
|
22012
|
-
|
|
22013
|
-
identifier: identifiers[0],
|
|
22014
|
-
requestKey
|
|
22015
|
-
};
|
|
22016
|
-
const challenge = await BG.Challenge.create(bgConfig);
|
|
22061
|
+
}))
|
|
22062
|
+
});
|
|
22017
22063
|
if (!challenge) throw new Error("BotGuard challenge unavailable");
|
|
22018
22064
|
const interpreter = challenge.interpreterJavascript?.privateDoNotAccessOrElseSafeScriptWrappedValue;
|
|
22019
22065
|
if (!interpreter) throw new Error("BotGuard interpreter script missing");
|
|
22020
22066
|
new Function(interpreter)();
|
|
22021
|
-
|
|
22067
|
+
if (!challenge.program || !challenge.globalName) {
|
|
22068
|
+
throw new Error("BotGuard challenge missing program/globalName");
|
|
22069
|
+
}
|
|
22070
|
+
const botguard = await BotGuardClient.create({
|
|
22022
22071
|
program: challenge.program,
|
|
22023
22072
|
globalName: challenge.globalName,
|
|
22024
|
-
|
|
22073
|
+
globalObject: globalThis
|
|
22025
22074
|
});
|
|
22026
22075
|
const webPoSignalOutput = [];
|
|
22027
22076
|
const botguardResponse = await botguard.snapshot({ webPoSignalOutput });
|
|
@@ -22039,7 +22088,7 @@ async function doMint(identifiers, opts) {
|
|
|
22039
22088
|
if (!integrityToken) {
|
|
22040
22089
|
throw new Error("Integrity token rejected by attestation server (likely a non-residential IP)");
|
|
22041
22090
|
}
|
|
22042
|
-
const minter = await
|
|
22091
|
+
const minter = await WebPoMinter.create({ integrityToken }, webPoSignalOutput);
|
|
22043
22092
|
const tokens = /* @__PURE__ */ new Map();
|
|
22044
22093
|
for (const id of identifiers) {
|
|
22045
22094
|
tokens.set(id, await minter.mintAsWebsafeString(id));
|
|
@@ -23846,6 +23895,19 @@ ${userMessage}`);
|
|
|
23846
23895
|
const synthesisService = await getService(ServiceNames.RESEARCH_SYNTHESIS_SERVICE, ctx, container);
|
|
23847
23896
|
synthesisService.storeReport(this.options.researchId, "quick", result);
|
|
23848
23897
|
result = synthesisService.getReport(this.options.researchId, "quick") ?? result;
|
|
23898
|
+
const { body: withoutPreamble, preamble } = stripReportPreamble(result);
|
|
23899
|
+
if (preamble) {
|
|
23900
|
+
logger.debug(`[QuickOrchestrator] Dropped a ${preamble.length}-char narration preamble from the report: ${preamble.slice(0, 120)}`);
|
|
23901
|
+
metrics.increment("research_report_preamble_stripped_total", 1, { mode: "quick" });
|
|
23902
|
+
result = withoutPreamble;
|
|
23903
|
+
}
|
|
23904
|
+
if (isAnalysisFreeSynthesis(result, 0)) {
|
|
23905
|
+
logger.warn(`[QuickOrchestrator] Report contains no complete sentence (${synthesisProseBody(result).length} char(s) of prose) \u2014 flagging it in the report`);
|
|
23906
|
+
metrics.increment("research_synthesis_analysis_free_total", 1, { mode: "quick" });
|
|
23907
|
+
result = `${result.trim()}
|
|
23908
|
+
|
|
23909
|
+
${QUICK_THIN_REPORT_NOTICE}`;
|
|
23910
|
+
}
|
|
23849
23911
|
result = synthesisService.ensureCitedLinks(this.options.researchId, result);
|
|
23850
23912
|
const citationSource = result;
|
|
23851
23913
|
const finalSteeringMessages = getActiveSteeringMessages(this.options.sessionId);
|
|
@@ -23956,6 +24018,7 @@ ${result}`);
|
|
|
23956
24018
|
init_logger();
|
|
23957
24019
|
init_metrics();
|
|
23958
24020
|
init_constants();
|
|
24021
|
+
init_text_utils();
|
|
23959
24022
|
init_service_interfaces();
|
|
23960
24023
|
init_service_registry();
|
|
23961
24024
|
init_config();
|
|
@@ -24271,6 +24334,13 @@ var DeepResearchOrchestrator = class {
|
|
|
24271
24334
|
observer?.onEvaluationDecision?.("synthesize", finalReport, this.currentRound);
|
|
24272
24335
|
}
|
|
24273
24336
|
let result = finalReport.content || "";
|
|
24337
|
+
try {
|
|
24338
|
+
const parsed = JSON.parse(result);
|
|
24339
|
+
if (parsed && typeof parsed === "object" && typeof parsed["content"] === "string") {
|
|
24340
|
+
result = parsed["content"];
|
|
24341
|
+
}
|
|
24342
|
+
} catch {
|
|
24343
|
+
}
|
|
24274
24344
|
if (!result.trim()) {
|
|
24275
24345
|
if (hasReports) {
|
|
24276
24346
|
logger.warn(`[DeepOrchestrator] LLM returned empty synthesis for ${researchId}, building fallback from ${synthesisCheckService.getReportCount(researchId)} reports`);
|
|
@@ -24278,13 +24348,15 @@ var DeepResearchOrchestrator = class {
|
|
|
24278
24348
|
} else {
|
|
24279
24349
|
throw new Error("Research produced no report \u2014 no source material was collected.");
|
|
24280
24350
|
}
|
|
24281
|
-
}
|
|
24282
|
-
|
|
24283
|
-
|
|
24284
|
-
|
|
24285
|
-
|
|
24286
|
-
|
|
24287
|
-
|
|
24351
|
+
} else if (hasReports && isAnalysisFreeSynthesis(result, MIN_SYNTHESIS_PROSE_CHARS)) {
|
|
24352
|
+
const proseChars = synthesisProseBody(result).length;
|
|
24353
|
+
logger.warn(`[DeepOrchestrator] LLM synthesis for ${researchId} carried no analysis (${proseChars} char(s) of prose, min ${MIN_SYNTHESIS_PROSE_CHARS}) \u2014 appending ${synthesisCheckService.getReportCount(researchId)} researcher report(s) below it`);
|
|
24354
|
+
metrics.increment("research_synthesis_analysis_free_total", 1, { mode: "deep" });
|
|
24355
|
+
result = [
|
|
24356
|
+
result.trim(),
|
|
24357
|
+
SYNTHESIS_FALLBACK_NOTICE,
|
|
24358
|
+
synthesisCheckService.buildFallbackSynthesis(researchId, this.currentRound)
|
|
24359
|
+
].join("\n\n");
|
|
24288
24360
|
}
|
|
24289
24361
|
const synthesisService = await getService(ServiceNames.RESEARCH_SYNTHESIS_SERVICE, ctx, container);
|
|
24290
24362
|
result = synthesisService.ensureCitedLinks(researchId, result);
|
|
@@ -25152,7 +25224,7 @@ var ResearchSynthesisService = class _ResearchSynthesisService {
|
|
|
25152
25224
|
if (reportCount === 0) {
|
|
25153
25225
|
synthesis += "No researcher reports were generated before the process stopped.";
|
|
25154
25226
|
} else {
|
|
25155
|
-
synthesis += `This is an automated
|
|
25227
|
+
synthesis += `This is an automated compilation of ${reportCount} individual researcher report(s). The synthesis step did not produce a usable summary for this run, so the findings are presented as collected.
|
|
25156
25228
|
|
|
25157
25229
|
`;
|
|
25158
25230
|
synthesis += Array.from(reports.entries()).map(([id, report]) => `Researcher ${id}
|
|
@@ -62,6 +62,8 @@ Write your report immediately after scraping is complete, or as soon as a tool r
|
|
|
62
62
|
## Report Format
|
|
63
63
|
|
|
64
64
|
{{digest_section}}
|
|
65
|
+
Emit the report and nothing else. No preamble, and no narration of what you are about to do — not "I have gathered extensive material…", not "Let me now synthesize my findings…". Begin at the report's own first line.
|
|
66
|
+
|
|
65
67
|
Use [N] inline citations throughout. Write in plain prose — no markdown headings, no bullet points, no bold or italic text. Use clear paragraphs separated by blank lines. The full CITED LINKS list goes at the very end.
|
|
66
68
|
|
|
67
69
|
[Topic Title]
|