@lincoln504/pi-research 1.5.3 → 1.6.0
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.md +11 -11
- package/agent-skill/pi-research/SKILL.md +1 -1
- package/dist/cli.mjs +143 -123
- package/dist/thread-worker.mjs +105 -17
- package/docs/CHANGELOG.md +38 -0
- package/docs/SDK.md +72 -9
- package/package.json +2 -2
- package/src/infrastructure/browser/browser-client.ts +24 -6
- package/src/infrastructure/browser/browser-error-utils.ts +53 -0
- package/src/infrastructure/browser/browser-server.ts +9 -1
- package/src/infrastructure/browser/thread-worker-browser.ts +4 -1
- package/src/infrastructure/browser/thread-worker-messaging.ts +186 -3
- package/src/infrastructure/browser/thread-worker.mjs +105 -17
- package/src/knowledge/store-operations.ts +18 -7
- package/src/knowledge/store.ts +21 -3
- package/src/web-research/scraper-utils.ts +4 -36
- package/src/youtube/potoken.ts +47 -34
package/README.md
CHANGED
|
@@ -27,7 +27,7 @@
|
|
|
27
27
|
<a href="LICENSE"><img alt="License: MIT" src="https://img.shields.io/badge/license-MIT-97ca00?style=flat-square" /></a><br />
|
|
28
28
|
<a href="https://github.com/Lincoln504/pi-research"><img alt="GitHub repository" src="https://img.shields.io/badge/GitHub-Lincoln504%2Fpi--research-181717?style=flat-square&logo=github&logoColor=white" /></a>
|
|
29
29
|
|
|
30
|
-
Search and scraping run locally through a stealth browser with no search provider and no monthly cap.
|
|
30
|
+
Search and scraping run locally through a stealth browser with no search provider and no monthly cap. The only cost is LLM tokens.
|
|
31
31
|
|
|
32
32
|
### Install
|
|
33
33
|
|
|
@@ -44,38 +44,38 @@ npm install -g @lincoln504/pi-research
|
|
|
44
44
|
pi-research skill install
|
|
45
45
|
```
|
|
46
46
|
|
|
47
|
-
In pi it works out of the box on
|
|
47
|
+
In pi it works out of the box on the session's model and pi's configuration. Standalone use ([agent skill](docs/AGENT-SKILL.md) or [SDK](docs/SDK.md)) needs a model configured. See [Configuration](docs/CONFIGURATION.md). The first install pulls the stealth browser engine, which takes a few minutes.
|
|
48
48
|
|
|
49
49
|
### How it works
|
|
50
50
|
|
|
51
51
|
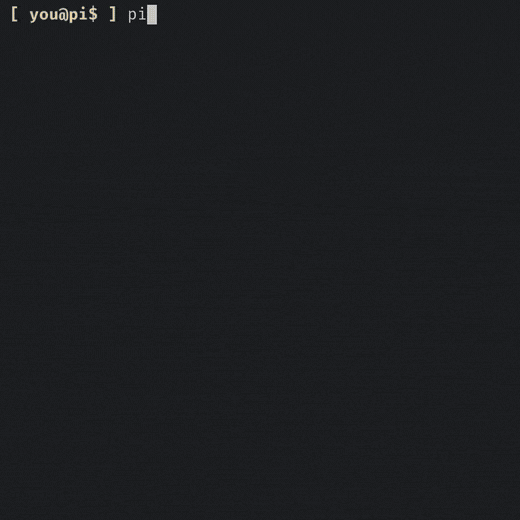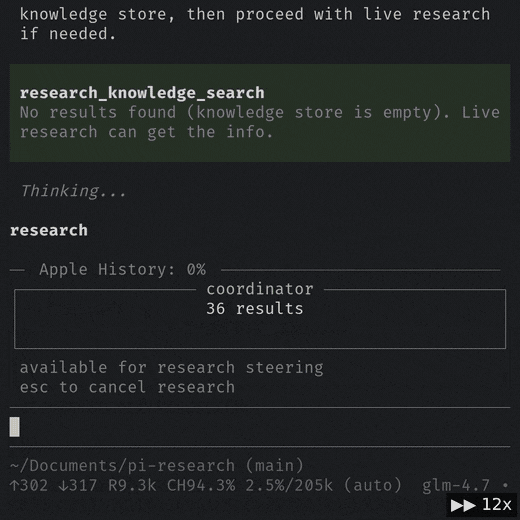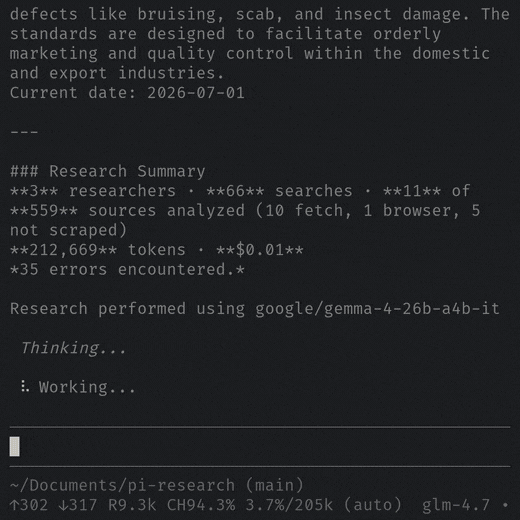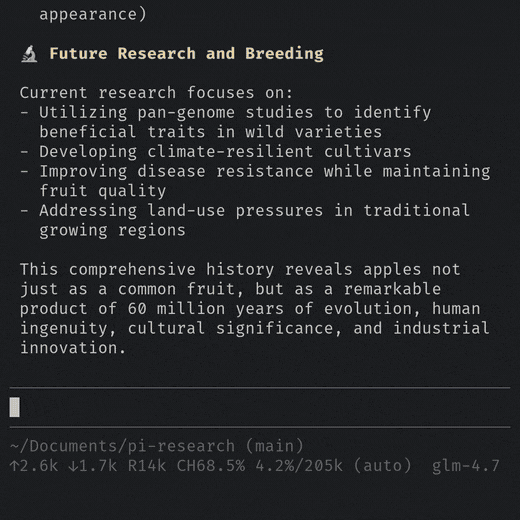
A research run loops through agent teams: a coordinator plans and opens with a search, researcher agents scrape and read in parallel, and a research lead decides whether to go another round — then writes the report from every report collected. The result is one cited Markdown report with findings optionally saved to the knowledge store.
|
|
52
52
|
|
|
53
|
-
Three depth levels (normal, deep, ultra) set the team size and number of rounds.
|
|
53
|
+
Three depth levels (normal, deep, ultra) set the team size and number of rounds. A natural-language request is enough — the tool picks the right one:
|
|
54
54
|
|
|
55
55
|
|
|
56
56
|
|
|
57
57
|
### Use cases
|
|
58
58
|
|
|
59
|
-
- Researching
|
|
60
|
-
- Researching from Claude Code, Codex, or another coding agent while a cheaper or local model drives the run so it doesn't spend
|
|
59
|
+
- Researching inside pi. Plug and play with no API key needed.
|
|
60
|
+
- Researching from Claude Code, Codex, or another coding agent while a cheaper or local model drives the run, so it doesn't spend the main agent's budget.
|
|
61
61
|
- Keeping a persistent and searchable knowledge store of findings, scoped globally or per project.
|
|
62
|
-
- Building agent systems that find and read web content or populating a dataset of web sources.
|
|
62
|
+
- Building agent systems that find and read web content, or populating a dataset of web sources.
|
|
63
63
|
|
|
64
64
|
### Why pi-research
|
|
65
65
|
|
|
66
66
|
- **No quota and no monthly fee.** Most AI search providers cap free searches and then charge, with results served from their index on their servers. pi-research searches and scrapes locally through DuckDuckGo in a stealth browser.
|
|
67
|
-
- **
|
|
68
|
-
- **Cited reports rather than raw dumps.**
|
|
69
|
-
- **Read-only by design.** The research agent cannot run shell commands or write, edit, or delete anything
|
|
67
|
+
- **The index stays local.** Every finding can be saved to a local [LanceDB](https://lancedb.com) knowledge store that seeds future runs, so repeat questions get faster and cheaper answers.
|
|
68
|
+
- **Cited reports rather than raw dumps.** Each run returns one sourced Markdown report instead of raw web content pasted into the conversation. Context efficient and easy to verify.
|
|
69
|
+
- **Read-only by design.** The research agent cannot run shell commands or write, edit, or delete anything — the right shape for an agent whose whole job is reading untrusted web pages. Prompt injection picked up mid-run has nothing to act on.
|
|
70
70
|
- **Search a little or a lot.** Depth levels span a quick pass to a large-scale investigation.
|
|
71
71
|
|
|
72
72
|
### Requirements / limitations
|
|
73
73
|
|
|
74
74
|
- Node.js >= 22.19.0
|
|
75
|
-
- An LLM with a 100k+ context window (
|
|
75
|
+
- An LLM with a 100k+ context window (an API key or a local model)
|
|
76
76
|
- Internet access on a residential IP, since search, scraping, and YouTube transcripts get bot-blocked from datacenter/VPS/cloud IPs
|
|
77
77
|
- pi. The pi extension uses the host's copy while the standalone CLI and agent skill install it as a dependency.
|
|
78
|
-
- Cloudflare and similar systems block scraping on some sites. A run flags pages
|
|
78
|
+
- Cloudflare and similar systems block scraping on some sites. A run flags unreachable pages and compensates with a wide pool of search results to cite.
|
|
79
79
|
|
|
80
80
|
### Channels
|
|
81
81
|
|
|
@@ -2,7 +2,7 @@
|
|
|
2
2
|
name: pi-research
|
|
3
3
|
description: "Multi-agent web research for any coding agent. Use for anything requiring current information from the internet — news, trends, product/service/company facts, statistics, people, places, events, APIs, library behavior, or 'what is X / how does X work' questions. Also use to search a local knowledge store of previously researched findings before doing live research. Powered by the pi-research engine (search, stealth scraping, security databases, Stack Exchange). Not for reading local files, running project commands, or analyzing this repository's own source."
|
|
4
4
|
license: MIT
|
|
5
|
-
metadata: { "author": "Lincoln Deen", "version": "1.
|
|
5
|
+
metadata: { "author": "Lincoln Deen", "version": "1.6.0", "package": "@lincoln504/pi-research", "engine": "pi-research-sdk", "openclaw": { "requires": { "bins": ["node"] } } }
|
|
6
6
|
allowed-tools: Bash(node:*)
|
|
7
7
|
---
|
|
8
8
|
|
package/dist/cli.mjs
CHANGED
|
@@ -7273,11 +7273,10 @@ function assertValidEmbeddingVectors(vectors, expectedCount, declaredDim) {
|
|
|
7273
7273
|
}
|
|
7274
7274
|
}
|
|
7275
7275
|
async function addDocumentsToStore(table, docs, embedder, isClosing, workspace, isGlobal) {
|
|
7276
|
-
if (docs.length === 0) return;
|
|
7276
|
+
if (docs.length === 0) return "empty";
|
|
7277
7277
|
if (isClosing()) {
|
|
7278
7278
|
logger.warn("[store] Ignoring addDocuments during close");
|
|
7279
|
-
|
|
7280
|
-
return;
|
|
7279
|
+
return "ignored_closing";
|
|
7281
7280
|
}
|
|
7282
7281
|
const startTime = Date.now();
|
|
7283
7282
|
try {
|
|
@@ -7297,14 +7296,13 @@ async function addDocumentsToStore(table, docs, embedder, isClosing, workspace,
|
|
|
7297
7296
|
await table.add(data);
|
|
7298
7297
|
const duration = Date.now() - startTime;
|
|
7299
7298
|
metrics.observe("knowledge_store_add_documents_duration_ms", duration);
|
|
7300
|
-
metrics.increment("knowledge_store_add_documents_total", 1, { status: "success" });
|
|
7301
7299
|
metrics.increment("knowledge_store_chunks_added_total", docs.length);
|
|
7302
7300
|
logger.log(`[store] Added ${docs.length} chunk(s) for ${docs[0]?.url} [workspace=${workspace}, global=${isGlobal}]`);
|
|
7301
|
+
return "written";
|
|
7303
7302
|
} catch (err) {
|
|
7304
7303
|
const duration = Date.now() - startTime;
|
|
7305
7304
|
metrics.observe("knowledge_store_add_documents_duration_ms", duration, { status: "error" });
|
|
7306
|
-
|
|
7307
|
-
logger.error("[store] Failed to add documents:", err);
|
|
7305
|
+
logger.debug(`[store] add attempt failed after ${duration}ms: ${err instanceof Error ? err.message : String(err)}`);
|
|
7308
7306
|
throw err;
|
|
7309
7307
|
}
|
|
7310
7308
|
}
|
|
@@ -7876,18 +7874,19 @@ var init_store = __esm({
|
|
|
7876
7874
|
try {
|
|
7877
7875
|
if (this.isClosing) {
|
|
7878
7876
|
logger.warn(`[store] Skipping addDocuments \u2014 store is closing`);
|
|
7877
|
+
metrics.increment("knowledge_store_add_documents_total", 1, { status: "ignored_closing" });
|
|
7879
7878
|
return;
|
|
7880
7879
|
}
|
|
7881
7880
|
let table = await this.getFreshTable();
|
|
7882
7881
|
const workspace = this.getWorkspace();
|
|
7883
|
-
await this.withEmbedderReconnect(async (embedder) => {
|
|
7882
|
+
const outcome = await this.withEmbedderReconnect(async (embedder) => {
|
|
7884
7883
|
let retryCount = 0;
|
|
7885
7884
|
const MAX_RETRIES = 5;
|
|
7886
7885
|
const BASE_DELAY = 100;
|
|
7887
7886
|
while (retryCount <= MAX_RETRIES) {
|
|
7888
7887
|
try {
|
|
7889
7888
|
const isGlobal = this.options.knowledgeMode === "global";
|
|
7890
|
-
await addDocumentsToStore(
|
|
7889
|
+
return await addDocumentsToStore(
|
|
7891
7890
|
table,
|
|
7892
7891
|
docs,
|
|
7893
7892
|
embedder,
|
|
@@ -7895,7 +7894,6 @@ var init_store = __esm({
|
|
|
7895
7894
|
workspace,
|
|
7896
7895
|
isGlobal
|
|
7897
7896
|
);
|
|
7898
|
-
return;
|
|
7899
7897
|
} catch (err) {
|
|
7900
7898
|
if (isLanceCommitConflict(err)) {
|
|
7901
7899
|
retryCount++;
|
|
@@ -7909,7 +7907,17 @@ var init_store = __esm({
|
|
|
7909
7907
|
throw err;
|
|
7910
7908
|
}
|
|
7911
7909
|
}
|
|
7910
|
+
throw new Error("[store] addDocuments retry loop exited without result");
|
|
7912
7911
|
});
|
|
7912
|
+
if (outcome !== "empty") {
|
|
7913
|
+
metrics.increment("knowledge_store_add_documents_total", 1, {
|
|
7914
|
+
status: outcome === "ignored_closing" ? "ignored_closing" : "success"
|
|
7915
|
+
});
|
|
7916
|
+
}
|
|
7917
|
+
} catch (err) {
|
|
7918
|
+
metrics.increment("knowledge_store_add_documents_total", 1, { status: "error" });
|
|
7919
|
+
logger.error("[store] Failed to add documents:", err);
|
|
7920
|
+
throw err;
|
|
7913
7921
|
} finally {
|
|
7914
7922
|
this.activeWrites.delete(writePromise);
|
|
7915
7923
|
writeResolve();
|
|
@@ -12436,6 +12444,101 @@ function getClientAgent() {
|
|
|
12436
12444
|
return clientAgent;
|
|
12437
12445
|
}
|
|
12438
12446
|
|
|
12447
|
+
// src/infrastructure/browser/browser-error-utils.ts
|
|
12448
|
+
init_circuit_breaker();
|
|
12449
|
+
function isTransientSocketError(error) {
|
|
12450
|
+
if (!error || typeof error !== "object") return false;
|
|
12451
|
+
const err = error;
|
|
12452
|
+
return typeof err.message === "string" && (err.message.includes("ECONNREFUSED") || err.message.includes("ECONNRESET") || err.message.includes("socket hang up") || err.message.includes("EPIPE") || err.message.includes("ETIMEDOUT") || err.message.includes("timed out") || err.message.includes("pool busy") || err.message.includes("unreachable") || // WorkerPoolManager throws this during the window between forceSchedulerRestart
|
|
12453
|
+
// clearing the scheduler reference and the old pool's 1500ms drain completing.
|
|
12454
|
+
// It is a transient state — retry after a short delay succeeds once drain finishes.
|
|
12455
|
+
err.message.includes("Worker pool is shutting down") || // Poolifier throws this when pool.execute() is called while the pool is being
|
|
12456
|
+
// destroyed (e.g., during scheduler restart). Treat as transient — the pool will
|
|
12457
|
+
// be ready for new tasks once destruction completes and a new pool is initialized.
|
|
12458
|
+
err.message.includes("Cannot execute a task on destroying pool") || err.message.includes("destroying pool") || // The leader answered 503 because it is shutting down after losing
|
|
12459
|
+
// leadership. Retrying re-elects and reaches the new leader, so this is
|
|
12460
|
+
// transient in exactly the same sense as a pool drain.
|
|
12461
|
+
err.message.includes("Browser pool leader is draining"));
|
|
12462
|
+
}
|
|
12463
|
+
function isCloudflareBlockError(error) {
|
|
12464
|
+
if (!error || typeof error !== "object") return false;
|
|
12465
|
+
const err = error;
|
|
12466
|
+
return typeof err.message === "string" && (err.message.includes("Fetch blocked: Cloudflare") || err.message.includes("Cloudflare challenge"));
|
|
12467
|
+
}
|
|
12468
|
+
function isTaskTimeoutError(error) {
|
|
12469
|
+
if (!error || typeof error !== "object") return false;
|
|
12470
|
+
const err = error;
|
|
12471
|
+
return typeof err.message === "string" && (err.message.includes("timed out after") || err.message.includes("Search task timed out") || err.message.includes("Scrape task timed out") || err.message.includes("Health check timed out") || err.message.includes("[BrowserClient] Request to"));
|
|
12472
|
+
}
|
|
12473
|
+
function isServerDrainingError(error) {
|
|
12474
|
+
if (!error || typeof error !== "object") return false;
|
|
12475
|
+
const err = error;
|
|
12476
|
+
return typeof err.message === "string" && err.message.includes("Browser pool leader is draining");
|
|
12477
|
+
}
|
|
12478
|
+
function isPoolShutdownError(error) {
|
|
12479
|
+
if (!error || typeof error !== "object") return false;
|
|
12480
|
+
const err = error;
|
|
12481
|
+
return typeof err.message === "string" && (err.message.includes("Worker pool is shutting down") || err.message.includes("Cannot execute a task on destroying pool") || err.message.includes("destroying pool") || // worker-pool-manager throws this when auto-recovery is still swapping the
|
|
12482
|
+
// pool. Its own text says "please retry", but until it was listed here no
|
|
12483
|
+
// classifier matched it, so the first attempt rethrew instead of retrying —
|
|
12484
|
+
// and auto-recovery fires only after 3 consecutive worker failures, i.e.
|
|
12485
|
+
// exactly when a burst of tasks is in flight and would all die together.
|
|
12486
|
+
err.message.includes("Worker pool is being reset") || // poolifier's wording once destroy() has COMPLETED (vs "destroying pool"
|
|
12487
|
+
// while it is in progress). A queued closure holding a pool captured before
|
|
12488
|
+
// an auto-recovery destroy dispatches into exactly this window; it is the
|
|
12489
|
+
// same transient swap the "being reset" string covers, not a hard fault.
|
|
12490
|
+
err.message.includes("Cannot execute a task on not started pool"));
|
|
12491
|
+
}
|
|
12492
|
+
var BENIGN_NAVIGATION_FAILURE = /page\.goto: (?:Timeout \d+ *ms exceeded|net::|NS_ERROR_|SEC_ERROR_|MOZILLA_PKIX_ERROR_)/;
|
|
12493
|
+
function isBenignScrapeFailure(error) {
|
|
12494
|
+
const msg2 = error instanceof Error ? error.message : String(error);
|
|
12495
|
+
return msg2.startsWith("Fetch blocked:") || // bot-protection interstitial (Cloudflare, DDoS-Guard, …)
|
|
12496
|
+
msg2.startsWith("Fetch returned stub:") || // nav-only / near-empty page
|
|
12497
|
+
msg2.startsWith("Could not extract content from PDF") || // malformed/encrypted/scanned-only PDF
|
|
12498
|
+
msg2.startsWith("PDF too large") || // exceeds the deliberate 100MB policy cap
|
|
12499
|
+
msg2.startsWith("Unsupported download:") || // attachment-served non-PDF (zip/xlsx/…) — nothing to extract
|
|
12500
|
+
BENIGN_NAVIGATION_FAILURE.test(msg2) || // remote TLS/DNS/timeout — the URL could not be loaded
|
|
12501
|
+
msg2.startsWith("HTML response too large") || // fetch-layer 25MB policy cap — same class as the PDF cap
|
|
12502
|
+
msg2.startsWith("Browser HTML too large") || // browser-layer 25MB policy cap
|
|
12503
|
+
/^HTTP \d{3}\b/.test(msg2) || // remote 4xx/5xx status
|
|
12504
|
+
isCloudflareBlockError(error) || isTaskTimeoutError(error) || isPoolShutdownError(error);
|
|
12505
|
+
}
|
|
12506
|
+
var sessionCircuitBreakers = /* @__PURE__ */ new Map();
|
|
12507
|
+
var MAX_SESSION_BREAKERS = 256;
|
|
12508
|
+
var DEFAULT_BREAKER_CONFIG = {
|
|
12509
|
+
// Raised from 3→8: parallel search bursts of 20 queries frequently produce
|
|
12510
|
+
// simultaneous timeouts on slow/CF-protected sites. A threshold of 3 caused
|
|
12511
|
+
// the breaker to open mid-burst, blocking all subsequent requests for the round.
|
|
12512
|
+
failureThreshold: 8,
|
|
12513
|
+
// Raised from 15s→45s: enough time for one full search burst + retry window
|
|
12514
|
+
// to complete before the breaker attempts to half-open.
|
|
12515
|
+
resetTimeoutMs: 45e3,
|
|
12516
|
+
name: "BrowserPool",
|
|
12517
|
+
isTransientError: (error) => {
|
|
12518
|
+
if (isPoolShutdownError(error)) return false;
|
|
12519
|
+
if (isServerDrainingError(error)) return false;
|
|
12520
|
+
if (isCloudflareBlockError(error)) return false;
|
|
12521
|
+
if (isTaskTimeoutError(error)) return false;
|
|
12522
|
+
return isTransientSocketError(error);
|
|
12523
|
+
}
|
|
12524
|
+
};
|
|
12525
|
+
function getBrowserCircuitBreaker(sessionId) {
|
|
12526
|
+
let breaker2 = sessionCircuitBreakers.get(sessionId);
|
|
12527
|
+
if (!breaker2) {
|
|
12528
|
+
if (sessionCircuitBreakers.size >= MAX_SESSION_BREAKERS) {
|
|
12529
|
+
const oldest = sessionCircuitBreakers.keys().next().value;
|
|
12530
|
+
if (oldest !== void 0) sessionCircuitBreakers.delete(oldest);
|
|
12531
|
+
}
|
|
12532
|
+
breaker2 = new CircuitBreaker({ ...DEFAULT_BREAKER_CONFIG, name: `BrowserPool-${sessionId}` });
|
|
12533
|
+
sessionCircuitBreakers.set(sessionId, breaker2);
|
|
12534
|
+
}
|
|
12535
|
+
return breaker2;
|
|
12536
|
+
}
|
|
12537
|
+
function clearSessionCircuitBreaker(sessionId) {
|
|
12538
|
+
sessionCircuitBreakers.delete(sessionId);
|
|
12539
|
+
}
|
|
12540
|
+
var browserCircuitBreaker = new CircuitBreaker(DEFAULT_BREAKER_CONFIG);
|
|
12541
|
+
|
|
12439
12542
|
// src/infrastructure/browser/browser-client.ts
|
|
12440
12543
|
var CLIENT_PATIENCE_MARGIN_MS = 15e3;
|
|
12441
12544
|
var CLIENT_TIMEOUT_CAP_MS = 3e5;
|
|
@@ -12597,12 +12700,16 @@ var BrowserClient = class {
|
|
|
12597
12700
|
errorType = "unknown";
|
|
12598
12701
|
}
|
|
12599
12702
|
const error = new Error(errorMsg);
|
|
12600
|
-
|
|
12601
|
-
|
|
12602
|
-
|
|
12603
|
-
|
|
12604
|
-
|
|
12605
|
-
|
|
12703
|
+
if (isTransientSocketError(error)) {
|
|
12704
|
+
logger.debug(`[BrowserClient] Transient failure talking to http://127.0.0.1:${this.port}${path20} (caller will retry): ${errorMsg}`);
|
|
12705
|
+
} else {
|
|
12706
|
+
logger.error(`[BrowserClient] Request to http://127.0.0.1:${this.port}${path20} failed:`, errorMsg);
|
|
12707
|
+
errorTracker.trackError(error, {
|
|
12708
|
+
component: "browser-manager",
|
|
12709
|
+
operation,
|
|
12710
|
+
errorType
|
|
12711
|
+
});
|
|
12712
|
+
}
|
|
12606
12713
|
reject(error);
|
|
12607
12714
|
});
|
|
12608
12715
|
req.write(JSON.stringify(data));
|
|
@@ -12644,89 +12751,6 @@ init_logger();
|
|
|
12644
12751
|
init_http_body();
|
|
12645
12752
|
import * as http5 from "node:http";
|
|
12646
12753
|
import * as crypto5 from "node:crypto";
|
|
12647
|
-
|
|
12648
|
-
// src/infrastructure/browser/browser-error-utils.ts
|
|
12649
|
-
init_circuit_breaker();
|
|
12650
|
-
function isTransientSocketError(error) {
|
|
12651
|
-
if (!error || typeof error !== "object") return false;
|
|
12652
|
-
const err = error;
|
|
12653
|
-
return typeof err.message === "string" && (err.message.includes("ECONNREFUSED") || err.message.includes("ECONNRESET") || err.message.includes("socket hang up") || err.message.includes("EPIPE") || err.message.includes("ETIMEDOUT") || err.message.includes("timed out") || err.message.includes("pool busy") || err.message.includes("unreachable") || // WorkerPoolManager throws this during the window between forceSchedulerRestart
|
|
12654
|
-
// clearing the scheduler reference and the old pool's 1500ms drain completing.
|
|
12655
|
-
// It is a transient state — retry after a short delay succeeds once drain finishes.
|
|
12656
|
-
err.message.includes("Worker pool is shutting down") || // Poolifier throws this when pool.execute() is called while the pool is being
|
|
12657
|
-
// destroyed (e.g., during scheduler restart). Treat as transient — the pool will
|
|
12658
|
-
// be ready for new tasks once destruction completes and a new pool is initialized.
|
|
12659
|
-
err.message.includes("Cannot execute a task on destroying pool") || err.message.includes("destroying pool") || // The leader answered 503 because it is shutting down after losing
|
|
12660
|
-
// leadership. Retrying re-elects and reaches the new leader, so this is
|
|
12661
|
-
// transient in exactly the same sense as a pool drain.
|
|
12662
|
-
err.message.includes("Browser pool leader is draining"));
|
|
12663
|
-
}
|
|
12664
|
-
function isCloudflareBlockError(error) {
|
|
12665
|
-
if (!error || typeof error !== "object") return false;
|
|
12666
|
-
const err = error;
|
|
12667
|
-
return typeof err.message === "string" && (err.message.includes("Fetch blocked: Cloudflare") || err.message.includes("Cloudflare challenge"));
|
|
12668
|
-
}
|
|
12669
|
-
function isTaskTimeoutError(error) {
|
|
12670
|
-
if (!error || typeof error !== "object") return false;
|
|
12671
|
-
const err = error;
|
|
12672
|
-
return typeof err.message === "string" && (err.message.includes("timed out after") || err.message.includes("Search task timed out") || err.message.includes("Scrape task timed out") || err.message.includes("Health check timed out") || err.message.includes("[BrowserClient] Request to"));
|
|
12673
|
-
}
|
|
12674
|
-
function isServerDrainingError(error) {
|
|
12675
|
-
if (!error || typeof error !== "object") return false;
|
|
12676
|
-
const err = error;
|
|
12677
|
-
return typeof err.message === "string" && err.message.includes("Browser pool leader is draining");
|
|
12678
|
-
}
|
|
12679
|
-
function isPoolShutdownError(error) {
|
|
12680
|
-
if (!error || typeof error !== "object") return false;
|
|
12681
|
-
const err = error;
|
|
12682
|
-
return typeof err.message === "string" && (err.message.includes("Worker pool is shutting down") || err.message.includes("Cannot execute a task on destroying pool") || err.message.includes("destroying pool") || // worker-pool-manager throws this when auto-recovery is still swapping the
|
|
12683
|
-
// pool. Its own text says "please retry", but until it was listed here no
|
|
12684
|
-
// classifier matched it, so the first attempt rethrew instead of retrying —
|
|
12685
|
-
// and auto-recovery fires only after 3 consecutive worker failures, i.e.
|
|
12686
|
-
// exactly when a burst of tasks is in flight and would all die together.
|
|
12687
|
-
err.message.includes("Worker pool is being reset") || // poolifier's wording once destroy() has COMPLETED (vs "destroying pool"
|
|
12688
|
-
// while it is in progress). A queued closure holding a pool captured before
|
|
12689
|
-
// an auto-recovery destroy dispatches into exactly this window; it is the
|
|
12690
|
-
// same transient swap the "being reset" string covers, not a hard fault.
|
|
12691
|
-
err.message.includes("Cannot execute a task on not started pool"));
|
|
12692
|
-
}
|
|
12693
|
-
var sessionCircuitBreakers = /* @__PURE__ */ new Map();
|
|
12694
|
-
var MAX_SESSION_BREAKERS = 256;
|
|
12695
|
-
var DEFAULT_BREAKER_CONFIG = {
|
|
12696
|
-
// Raised from 3→8: parallel search bursts of 20 queries frequently produce
|
|
12697
|
-
// simultaneous timeouts on slow/CF-protected sites. A threshold of 3 caused
|
|
12698
|
-
// the breaker to open mid-burst, blocking all subsequent requests for the round.
|
|
12699
|
-
failureThreshold: 8,
|
|
12700
|
-
// Raised from 15s→45s: enough time for one full search burst + retry window
|
|
12701
|
-
// to complete before the breaker attempts to half-open.
|
|
12702
|
-
resetTimeoutMs: 45e3,
|
|
12703
|
-
name: "BrowserPool",
|
|
12704
|
-
isTransientError: (error) => {
|
|
12705
|
-
if (isPoolShutdownError(error)) return false;
|
|
12706
|
-
if (isServerDrainingError(error)) return false;
|
|
12707
|
-
if (isCloudflareBlockError(error)) return false;
|
|
12708
|
-
if (isTaskTimeoutError(error)) return false;
|
|
12709
|
-
return isTransientSocketError(error);
|
|
12710
|
-
}
|
|
12711
|
-
};
|
|
12712
|
-
function getBrowserCircuitBreaker(sessionId) {
|
|
12713
|
-
let breaker2 = sessionCircuitBreakers.get(sessionId);
|
|
12714
|
-
if (!breaker2) {
|
|
12715
|
-
if (sessionCircuitBreakers.size >= MAX_SESSION_BREAKERS) {
|
|
12716
|
-
const oldest = sessionCircuitBreakers.keys().next().value;
|
|
12717
|
-
if (oldest !== void 0) sessionCircuitBreakers.delete(oldest);
|
|
12718
|
-
}
|
|
12719
|
-
breaker2 = new CircuitBreaker({ ...DEFAULT_BREAKER_CONFIG, name: `BrowserPool-${sessionId}` });
|
|
12720
|
-
sessionCircuitBreakers.set(sessionId, breaker2);
|
|
12721
|
-
}
|
|
12722
|
-
return breaker2;
|
|
12723
|
-
}
|
|
12724
|
-
function clearSessionCircuitBreaker(sessionId) {
|
|
12725
|
-
sessionCircuitBreakers.delete(sessionId);
|
|
12726
|
-
}
|
|
12727
|
-
var browserCircuitBreaker = new CircuitBreaker(DEFAULT_BREAKER_CONFIG);
|
|
12728
|
-
|
|
12729
|
-
// src/infrastructure/browser/browser-server.ts
|
|
12730
12754
|
var _authSecret = null;
|
|
12731
12755
|
function getOrCreateAuthSecret() {
|
|
12732
12756
|
if (!_authSecret) {
|
|
@@ -12868,6 +12892,8 @@ var BrowserServer = class {
|
|
|
12868
12892
|
logger.warn("[BrowserServer] Request blocked by bot protection:", error instanceof Error ? error.message : String(error));
|
|
12869
12893
|
} else if (isPoolShutdownError(error)) {
|
|
12870
12894
|
logger.debug("[BrowserServer] Request abandoned during shutdown:", error instanceof Error ? error.message : String(error));
|
|
12895
|
+
} else if (isBenignScrapeFailure(error)) {
|
|
12896
|
+
logger.debug("[BrowserServer] Expected per-URL scrape outcome:", error instanceof Error ? error.message.split("\n")[0] : String(error));
|
|
12871
12897
|
} else {
|
|
12872
12898
|
logger.error("[BrowserServer] Error handling request:", error);
|
|
12873
12899
|
}
|
|
@@ -18060,17 +18086,6 @@ import * as dnsCb from "node:dns";
|
|
|
18060
18086
|
import * as net3 from "node:net";
|
|
18061
18087
|
import crypto9 from "node:crypto";
|
|
18062
18088
|
import { NodeHtmlMarkdown } from "node-html-markdown";
|
|
18063
|
-
function isBenignScrapeFailure(error) {
|
|
18064
|
-
const msg2 = error instanceof Error ? error.message : String(error);
|
|
18065
|
-
return msg2.startsWith("Fetch blocked:") || // bot-protection interstitial (Cloudflare, DDoS-Guard, …)
|
|
18066
|
-
msg2.startsWith("Fetch returned stub:") || // nav-only / near-empty page
|
|
18067
|
-
msg2.startsWith("Could not extract content from PDF") || // malformed/encrypted/scanned-only PDF
|
|
18068
|
-
msg2.startsWith("PDF too large") || // exceeds the deliberate 100MB policy cap
|
|
18069
|
-
msg2.startsWith("HTML response too large") || // fetch-layer 25MB policy cap — same class as the PDF cap
|
|
18070
|
-
msg2.startsWith("Browser HTML too large") || // browser-layer 25MB policy cap
|
|
18071
|
-
/^HTTP \d{3}\b/.test(msg2) || // remote 4xx/5xx status
|
|
18072
|
-
isCloudflareBlockError(error) || isTaskTimeoutError(error) || isPoolShutdownError(error);
|
|
18073
|
-
}
|
|
18074
18089
|
function getRandomUserAgent() {
|
|
18075
18090
|
try {
|
|
18076
18091
|
const index = crypto9.randomInt(0, USER_AGENTS.length);
|
|
@@ -21971,9 +21986,14 @@ async function doMint(identifiers, opts) {
|
|
|
21971
21986
|
const requestKey = opts.requestKey || process.env["PI_RESEARCH_YOUTUBE_POTOKEN_REQUEST_KEY"] || DEFAULT_REQUEST_KEY;
|
|
21972
21987
|
const fetchImpl = opts.fetchImpl ?? fetch;
|
|
21973
21988
|
const started = Date.now();
|
|
21974
|
-
const
|
|
21975
|
-
|
|
21976
|
-
|
|
21989
|
+
const [bgGuard, bgWebPo, bgUtils] = await Promise.all([
|
|
21990
|
+
import("bgutils-js/botguard"),
|
|
21991
|
+
import("bgutils-js/webpo"),
|
|
21992
|
+
import("bgutils-js/utils")
|
|
21993
|
+
]);
|
|
21994
|
+
const { getChallenge, BotGuardClient } = bgGuard;
|
|
21995
|
+
const { WebPoMinter } = bgWebPo;
|
|
21996
|
+
const { buildURL: buildURL2, getHeaders } = bgUtils;
|
|
21977
21997
|
const { JSDOM } = await import("jsdom");
|
|
21978
21998
|
const dom = new JSDOM('<!DOCTYPE html><html lang="en"><body></body></html>', {
|
|
21979
21999
|
url: "https://www.youtube.com/"
|
|
@@ -22004,24 +22024,24 @@ async function doMint(identifiers, opts) {
|
|
|
22004
22024
|
};
|
|
22005
22025
|
bridge();
|
|
22006
22026
|
try {
|
|
22007
|
-
const
|
|
22008
|
-
|
|
22027
|
+
const challenge = await getChallenge({
|
|
22028
|
+
requestKey,
|
|
22029
|
+
fetchFunction: ((input, init) => fetchImpl(input, {
|
|
22009
22030
|
...init,
|
|
22010
22031
|
signal: init?.signal ?? opts.signal
|
|
22011
|
-
})
|
|
22012
|
-
|
|
22013
|
-
identifier: identifiers[0],
|
|
22014
|
-
requestKey
|
|
22015
|
-
};
|
|
22016
|
-
const challenge = await BG.Challenge.create(bgConfig);
|
|
22032
|
+
}))
|
|
22033
|
+
});
|
|
22017
22034
|
if (!challenge) throw new Error("BotGuard challenge unavailable");
|
|
22018
22035
|
const interpreter = challenge.interpreterJavascript?.privateDoNotAccessOrElseSafeScriptWrappedValue;
|
|
22019
22036
|
if (!interpreter) throw new Error("BotGuard interpreter script missing");
|
|
22020
22037
|
new Function(interpreter)();
|
|
22021
|
-
|
|
22038
|
+
if (!challenge.program || !challenge.globalName) {
|
|
22039
|
+
throw new Error("BotGuard challenge missing program/globalName");
|
|
22040
|
+
}
|
|
22041
|
+
const botguard = await BotGuardClient.create({
|
|
22022
22042
|
program: challenge.program,
|
|
22023
22043
|
globalName: challenge.globalName,
|
|
22024
|
-
|
|
22044
|
+
globalObject: globalThis
|
|
22025
22045
|
});
|
|
22026
22046
|
const webPoSignalOutput = [];
|
|
22027
22047
|
const botguardResponse = await botguard.snapshot({ webPoSignalOutput });
|
|
@@ -22039,7 +22059,7 @@ async function doMint(identifiers, opts) {
|
|
|
22039
22059
|
if (!integrityToken) {
|
|
22040
22060
|
throw new Error("Integrity token rejected by attestation server (likely a non-residential IP)");
|
|
22041
22061
|
}
|
|
22042
|
-
const minter = await
|
|
22062
|
+
const minter = await WebPoMinter.create({ integrityToken }, webPoSignalOutput);
|
|
22043
22063
|
const tokens = /* @__PURE__ */ new Map();
|
|
22044
22064
|
for (const id of identifiers) {
|
|
22045
22065
|
tokens.set(id, await minter.mintAsWebsafeString(id));
|
package/dist/thread-worker.mjs
CHANGED
|
@@ -1516,11 +1516,25 @@ function isPoolShutdownError(error) {
|
|
|
1516
1516
|
// same transient swap the "being reset" string covers, not a hard fault.
|
|
1517
1517
|
err.message.includes("Cannot execute a task on not started pool"));
|
|
1518
1518
|
}
|
|
1519
|
-
|
|
1519
|
+
function isBenignScrapeFailure(error) {
|
|
1520
|
+
const msg = error instanceof Error ? error.message : String(error);
|
|
1521
|
+
return msg.startsWith("Fetch blocked:") || // bot-protection interstitial (Cloudflare, DDoS-Guard, …)
|
|
1522
|
+
msg.startsWith("Fetch returned stub:") || // nav-only / near-empty page
|
|
1523
|
+
msg.startsWith("Could not extract content from PDF") || // malformed/encrypted/scanned-only PDF
|
|
1524
|
+
msg.startsWith("PDF too large") || // exceeds the deliberate 100MB policy cap
|
|
1525
|
+
msg.startsWith("Unsupported download:") || // attachment-served non-PDF (zip/xlsx/…) — nothing to extract
|
|
1526
|
+
BENIGN_NAVIGATION_FAILURE.test(msg) || // remote TLS/DNS/timeout — the URL could not be loaded
|
|
1527
|
+
msg.startsWith("HTML response too large") || // fetch-layer 25MB policy cap — same class as the PDF cap
|
|
1528
|
+
msg.startsWith("Browser HTML too large") || // browser-layer 25MB policy cap
|
|
1529
|
+
/^HTTP \d{3}\b/.test(msg) || // remote 4xx/5xx status
|
|
1530
|
+
isCloudflareBlockError(error) || isTaskTimeoutError(error) || isPoolShutdownError(error);
|
|
1531
|
+
}
|
|
1532
|
+
var BENIGN_NAVIGATION_FAILURE, DEFAULT_BREAKER_CONFIG, browserCircuitBreaker;
|
|
1520
1533
|
var init_browser_error_utils = __esm({
|
|
1521
1534
|
"src/infrastructure/browser/browser-error-utils.ts"() {
|
|
1522
1535
|
"use strict";
|
|
1523
1536
|
init_circuit_breaker();
|
|
1537
|
+
BENIGN_NAVIGATION_FAILURE = /page\.goto: (?:Timeout \d+ *ms exceeded|net::|NS_ERROR_|SEC_ERROR_|MOZILLA_PKIX_ERROR_)/;
|
|
1524
1538
|
DEFAULT_BREAKER_CONFIG = {
|
|
1525
1539
|
// Raised from 3→8: parallel search bursts of 20 queries frequently produce
|
|
1526
1540
|
// simultaneous timeouts on slow/CF-protected sites. A threshold of 3 caused
|
|
@@ -1565,17 +1579,6 @@ import * as dnsCb from "node:dns";
|
|
|
1565
1579
|
import * as net from "node:net";
|
|
1566
1580
|
import crypto from "node:crypto";
|
|
1567
1581
|
import { NodeHtmlMarkdown } from "node-html-markdown";
|
|
1568
|
-
function isBenignScrapeFailure(error) {
|
|
1569
|
-
const msg = error instanceof Error ? error.message : String(error);
|
|
1570
|
-
return msg.startsWith("Fetch blocked:") || // bot-protection interstitial (Cloudflare, DDoS-Guard, …)
|
|
1571
|
-
msg.startsWith("Fetch returned stub:") || // nav-only / near-empty page
|
|
1572
|
-
msg.startsWith("Could not extract content from PDF") || // malformed/encrypted/scanned-only PDF
|
|
1573
|
-
msg.startsWith("PDF too large") || // exceeds the deliberate 100MB policy cap
|
|
1574
|
-
msg.startsWith("HTML response too large") || // fetch-layer 25MB policy cap — same class as the PDF cap
|
|
1575
|
-
msg.startsWith("Browser HTML too large") || // browser-layer 25MB policy cap
|
|
1576
|
-
/^HTTP \d{3}\b/.test(msg) || // remote 4xx/5xx status
|
|
1577
|
-
isCloudflareBlockError(error) || isTaskTimeoutError(error) || isPoolShutdownError(error);
|
|
1578
|
-
}
|
|
1579
1582
|
function getRandomUserAgent() {
|
|
1580
1583
|
try {
|
|
1581
1584
|
const index = crypto.randomInt(0, USER_AGENTS.length);
|
|
@@ -2014,7 +2017,7 @@ import { platform as platform2 } from "node:os";
|
|
|
2014
2017
|
|
|
2015
2018
|
// src/infrastructure/browser/thread-worker-messaging.ts
|
|
2016
2019
|
init_log_utils();
|
|
2017
|
-
import { appendFileSync as appendFileSync2 } from "node:fs";
|
|
2020
|
+
import { appendFileSync as appendFileSync2, promises as fsp } from "node:fs";
|
|
2018
2021
|
|
|
2019
2022
|
// src/utils/safe-unref.ts
|
|
2020
2023
|
function safeUnref(timer) {
|
|
@@ -2286,6 +2289,66 @@ function seedSubresourceVerdict(validatedUrl) {
|
|
|
2286
2289
|
} catch {
|
|
2287
2290
|
}
|
|
2288
2291
|
}
|
|
2292
|
+
function isEvictedBodyError(err) {
|
|
2293
|
+
const msg = err instanceof Error ? err.message : String(err);
|
|
2294
|
+
return /was evicted|Response body is unavailable/i.test(msg);
|
|
2295
|
+
}
|
|
2296
|
+
var PDF_REFETCH_TIMEOUT_MS = 9e4;
|
|
2297
|
+
async function refetchPdfBody(page, url, validateForWorker, signal) {
|
|
2298
|
+
await validateForWorker(url);
|
|
2299
|
+
if (signal?.aborted) throw new Error("Aborted");
|
|
2300
|
+
const requestPromise = page.context().request.get(url, {
|
|
2301
|
+
maxRedirects: 0,
|
|
2302
|
+
timeout: PDF_REFETCH_TIMEOUT_MS
|
|
2303
|
+
});
|
|
2304
|
+
requestPromise.catch(() => {
|
|
2305
|
+
});
|
|
2306
|
+
const response = await (signal ? Promise.race([
|
|
2307
|
+
requestPromise,
|
|
2308
|
+
new Promise((_, reject) => {
|
|
2309
|
+
if (signal.aborted) return reject(new Error("Aborted"));
|
|
2310
|
+
signal.addEventListener("abort", () => reject(new Error("Aborted")), { once: true });
|
|
2311
|
+
})
|
|
2312
|
+
]) : requestPromise);
|
|
2313
|
+
const status = Number(response.status?.() ?? 0);
|
|
2314
|
+
if (!response.ok?.()) throw new Error(`HTTP ${status}`);
|
|
2315
|
+
const declared = parseInt(String((await response.headersArray?.() ?? []).find?.((h) => String(h.name).toLowerCase() === "content-length")?.value ?? ""), 10);
|
|
2316
|
+
if (Number.isFinite(declared) && declared > MAX_PDF_SIZE) {
|
|
2317
|
+
throw new Error(`PDF too large (${Math.round(declared / 1024 / 1024)}MB, max 100MB)`);
|
|
2318
|
+
}
|
|
2319
|
+
const buffer = await response.body();
|
|
2320
|
+
if (buffer.byteLength > MAX_PDF_SIZE) {
|
|
2321
|
+
throw new Error(`PDF too large (${Math.round(buffer.byteLength / 1024 / 1024)}MB, max 100MB)`);
|
|
2322
|
+
}
|
|
2323
|
+
logToDebugFile2("DEBUG", `[Worker-${workerId2}] Re-fetched evicted PDF body (${buffer.byteLength} bytes) for: ${url}`);
|
|
2324
|
+
return buffer;
|
|
2325
|
+
}
|
|
2326
|
+
async function readPdfDownload(download, url, page, pendingAddrChecks, getPoisonedError) {
|
|
2327
|
+
const failure = await download.failure?.().catch(() => null);
|
|
2328
|
+
if (failure) throw new Error(`Fetch blocked: download failed (${failure})`);
|
|
2329
|
+
const suggested = String(download.suggestedFilename?.() ?? "");
|
|
2330
|
+
const downloadUrl = String(download.url?.() ?? url);
|
|
2331
|
+
const looksLikePdf = suggested.toLowerCase().endsWith(".pdf") || downloadUrl.toLowerCase().split("?")[0].endsWith(".pdf");
|
|
2332
|
+
if (!looksLikePdf) {
|
|
2333
|
+
throw new Error(`Unsupported download: ${suggested || downloadUrl} is not a PDF`);
|
|
2334
|
+
}
|
|
2335
|
+
const filePath = await download.path();
|
|
2336
|
+
if (!filePath) throw new Error("Fetch blocked: download produced no readable file");
|
|
2337
|
+
const { size } = await fsp.stat(filePath);
|
|
2338
|
+
if (size > MAX_PDF_SIZE) {
|
|
2339
|
+
const sizeMB = Math.round(size / 1024 / 1024);
|
|
2340
|
+
throw new Error(`PDF too large (${sizeMB}MB, max 100MB)`);
|
|
2341
|
+
}
|
|
2342
|
+
const buffer = await fsp.readFile(filePath);
|
|
2343
|
+
await Promise.allSettled(pendingAddrChecks);
|
|
2344
|
+
const poisoned = getPoisonedError();
|
|
2345
|
+
if (poisoned) throw poisoned;
|
|
2346
|
+
await download.delete?.().catch(() => {
|
|
2347
|
+
});
|
|
2348
|
+
await page.close();
|
|
2349
|
+
logToDebugFile2("DEBUG", `[Worker-${workerId2}] Recovered attachment-served PDF (${buffer.byteLength} bytes) for: ${url}`);
|
|
2350
|
+
return { contentType: "application/pdf", bufferB64: buffer.toString("base64"), jitter: 0 };
|
|
2351
|
+
}
|
|
2289
2352
|
async function executeScrapeTask(_context, url, signal) {
|
|
2290
2353
|
const page = await createPageSafe(_context);
|
|
2291
2354
|
const SCRAPE_TIMEOUT = parseTimeoutMs(process.env["PI_RESEARCH_SCRAPE_TIMEOUT_MS"], 15e3);
|
|
@@ -2302,6 +2365,7 @@ async function executeScrapeTask(_context, url, signal) {
|
|
|
2302
2365
|
let poisonedError = null;
|
|
2303
2366
|
const pendingAddrChecks = [];
|
|
2304
2367
|
let oversizedPdfError = null;
|
|
2368
|
+
let pendingDownload = null;
|
|
2305
2369
|
try {
|
|
2306
2370
|
logToDebugFile2("DEBUG", `[Worker-${workerId2}] Starting scrape for: ${url}`);
|
|
2307
2371
|
const { validateUrlForSSRF: validateForWorker, validateUrlForSSRFSync: validateForWorkerSync } = await Promise.resolve().then(() => (init_scraper_utils(), scraper_utils_exports));
|
|
@@ -2368,7 +2432,25 @@ async function executeScrapeTask(_context, url, signal) {
|
|
|
2368
2432
|
} catch {
|
|
2369
2433
|
}
|
|
2370
2434
|
});
|
|
2371
|
-
|
|
2435
|
+
page.on("download", (d) => {
|
|
2436
|
+
pendingDownload ??= d;
|
|
2437
|
+
});
|
|
2438
|
+
let response;
|
|
2439
|
+
try {
|
|
2440
|
+
response = await page.goto(url, { waitUntil: "domcontentloaded" });
|
|
2441
|
+
} catch (navErr) {
|
|
2442
|
+
const navMsg = navErr instanceof Error ? navErr.message : String(navErr);
|
|
2443
|
+
const isDownloadNav = /download is starting/i.test(navMsg);
|
|
2444
|
+
if (!isDownloadNav) throw navErr;
|
|
2445
|
+
if (!pendingDownload) {
|
|
2446
|
+
await Promise.race([
|
|
2447
|
+
page.waitForEvent("download", { timeout: 5e3 }).catch(() => null),
|
|
2448
|
+
new Promise((r) => setTimeout(r, 5e3))
|
|
2449
|
+
]);
|
|
2450
|
+
}
|
|
2451
|
+
if (!pendingDownload) throw navErr;
|
|
2452
|
+
return await readPdfDownload(pendingDownload, url, page, pendingAddrChecks, () => poisonedError);
|
|
2453
|
+
}
|
|
2372
2454
|
const serverAddr = await response?.serverAddr().catch(() => null);
|
|
2373
2455
|
if (serverAddr?.ipAddress) {
|
|
2374
2456
|
const ip = serverAddr.ipAddress;
|
|
@@ -2386,7 +2468,13 @@ async function executeScrapeTask(_context, url, signal) {
|
|
|
2386
2468
|
throw new Error(`PDF too large (${sizeMB}MB, max 100MB)`);
|
|
2387
2469
|
}
|
|
2388
2470
|
if (oversizedPdfError) throw oversizedPdfError;
|
|
2389
|
-
|
|
2471
|
+
let buffer;
|
|
2472
|
+
try {
|
|
2473
|
+
buffer = await response.body();
|
|
2474
|
+
} catch (bodyErr) {
|
|
2475
|
+
if (!isEvictedBodyError(bodyErr)) throw bodyErr;
|
|
2476
|
+
buffer = await refetchPdfBody(page, finalUrl, validateForWorker, signal);
|
|
2477
|
+
}
|
|
2390
2478
|
if (buffer.byteLength > MAX_PDF_SIZE) {
|
|
2391
2479
|
const sizeMB = Math.round(buffer.byteLength / 1024 / 1024);
|
|
2392
2480
|
throw new Error(`PDF too large (${sizeMB}MB, max 100MB)`);
|
|
@@ -2749,7 +2837,7 @@ function logToDebugFile3(level, ...args) {
|
|
|
2749
2837
|
return String(arg);
|
|
2750
2838
|
}).join(" "))
|
|
2751
2839
|
};
|
|
2752
|
-
import("node:fs/promises").then((
|
|
2840
|
+
import("node:fs/promises").then((fsp2) => fsp2.appendFile(logFile, `${JSON.stringify(entry)}
|
|
2753
2841
|
`)).catch(() => {
|
|
2754
2842
|
});
|
|
2755
2843
|
} catch {
|
|
@@ -2888,7 +2976,7 @@ async function initBrowser() {
|
|
|
2888
2976
|
return initPromise;
|
|
2889
2977
|
}
|
|
2890
2978
|
async function acquireTaskContext() {
|
|
2891
|
-
const contextPromise = browser.newContext();
|
|
2979
|
+
const contextPromise = browser.newContext({ acceptDownloads: true });
|
|
2892
2980
|
contextPromise.catch((err) => logToDebugFile3("DEBUG", `[ThreadWorker] Background browser context rejection: ${err.message}`));
|
|
2893
2981
|
let contextTimeoutId;
|
|
2894
2982
|
let contextRaceLost = false;
|