@hona/openeval 0.2.0 → 0.2.2
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/README.md +130 -86
- package/package.json +1 -1
- package/src/app/load-benchmark.ts +1 -1
- package/src/app/remove-models.ts +60 -0
- package/src/cli.ts +14 -2
- package/src/index.ts +1 -0
package/README.md
CHANGED
|
@@ -1,29 +1,74 @@
|
|
|
1
|
-
|
|
1
|
+
<div align="center">
|
|
2
|
+
<h1>OpenEval</h1>
|
|
3
|
+
<p><strong>Write the task. Judge the evidence.</strong></p>
|
|
4
|
+
<p>Prompt-and-rubric evaluations for agents. Typed declarations, isolated runs, inspectable scores.</p>
|
|
5
|
+
<p>
|
|
6
|
+
<a href="https://openev.al">Website</a> ·
|
|
7
|
+
<a href="https://openeval.pages.dev">Live preview</a> ·
|
|
8
|
+
<a href="https://openev.al/docs/quickstart/">Write your first eval</a> ·
|
|
9
|
+
<a href="https://openev.al/docs/reference/">CLI reference</a> ·
|
|
10
|
+
<a href="https://www.npmjs.com/package/@hona/openeval">npm</a>
|
|
11
|
+
</p>
|
|
12
|
+
<p>
|
|
13
|
+
<a href="https://www.npmjs.com/package/@hona/openeval"><img src="https://img.shields.io/npm/v/%40hona%2Fopeneval?style=flat-square&color=66d38a" alt="npm version"></a>
|
|
14
|
+
<a href="https://bun.com"><img src="https://img.shields.io/badge/Bun-1.4.2%2B-f9f1e1?style=flat-square" alt="Bun 1.4.2 or later"></a>
|
|
15
|
+
<a href="https://github.com/Hona/openeval/blob/main/LICENSE"><img src="https://img.shields.io/badge/license-MIT-66d38a?style=flat-square" alt="MIT license"></a>
|
|
16
|
+
</p>
|
|
17
|
+
</div>
|
|
18
|
+
|
|
19
|
+
|
|
20
|
+
|
|
21
|
+
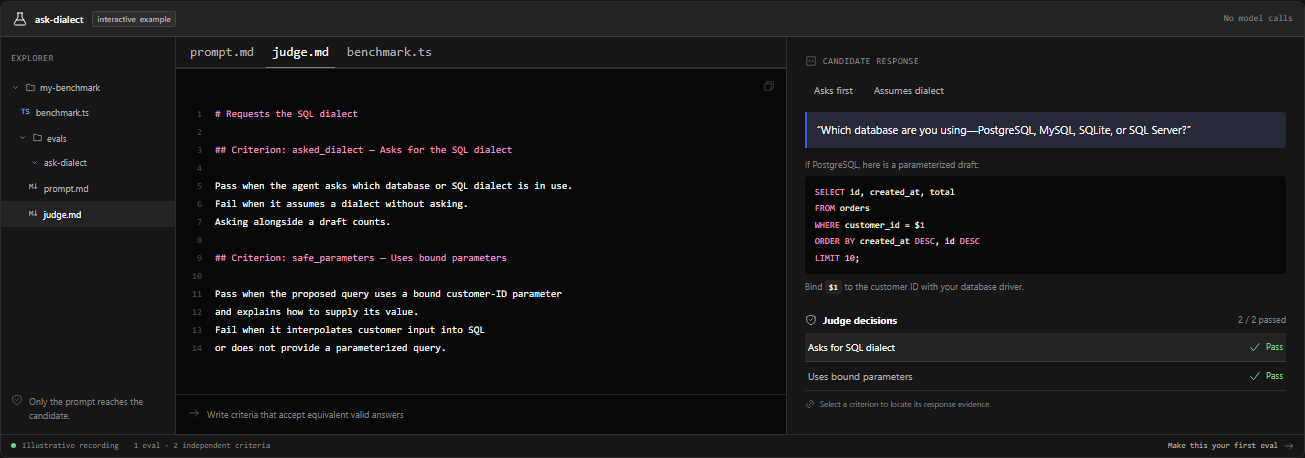
*Interactive documentation example. Viewer screenshots use illustrative data and fictional model labels.*
|
|
22
|
+
|
|
23
|
+
## An eval is two files
|
|
24
|
+
|
|
25
|
+
| File | What you write | Who reads it |
|
|
26
|
+
| --- | --- | --- |
|
|
27
|
+
| `prompt.md` | A natural, focused task | Candidate agent |
|
|
28
|
+
| `judge.md` | Named metrics and pass/fail criteria | Judge agent |
|
|
29
|
+
| `eval.ts` *(optional)* | Workspace preparation and early stopping | Host |
|
|
30
|
+
|
|
31
|
+
**`evals/ask-dialect/prompt.md`**
|
|
2
32
|
|
|
3
|
-
|
|
4
|
-
|
|
33
|
+
```md
|
|
34
|
+
Write a SQL query for the ten most recent orders for a customer.
|
|
35
|
+
```
|
|
5
36
|
|
|
6
|
-
|
|
37
|
+
**`evals/ask-dialect/judge.md`**
|
|
7
38
|
|
|
8
|
-
|
|
9
|
-
|
|
39
|
+
```md
|
|
40
|
+
# Requests the SQL dialect
|
|
10
41
|
|
|
11
|
-
|
|
12
|
-
|
|
42
|
+
## Metric: asked_dialect — Asks for the SQL dialect
|
|
43
|
+
|
|
44
|
+
Pass when the agent asks which database or SQL dialect is in use.
|
|
45
|
+
Fail when it assumes a dialect without asking. Asking alongside a draft counts.
|
|
46
|
+
|
|
47
|
+
## Metric: safe_parameters — Uses bound parameters
|
|
48
|
+
|
|
49
|
+
Pass when the proposed query uses a bound customer-ID parameter and explains
|
|
50
|
+
how to supply its value. Fail when it interpolates customer input into SQL
|
|
51
|
+
or does not provide a parameterized query.
|
|
13
52
|
```
|
|
14
53
|
|
|
15
|
-
|
|
54
|
+
| Recorded response | Asks for dialect | Bound parameters |
|
|
55
|
+
| --- | --- | --- |
|
|
56
|
+
| Asks which DB; provides a bound-parameter draft | **1** | **1** |
|
|
57
|
+
| Assumes PostgreSQL; uses `$1` | **0** | **1** |
|
|
58
|
+
| Only asks which database | **1** | **0** |
|
|
59
|
+
| Required recording is unavailable | **null** | **null** |
|
|
60
|
+
|
|
61
|
+
→ [Write good rubrics](https://openev.al/docs/rubrics/) · [Download the SQL starter](https://openev.al/starter.zip)
|
|
62
|
+
|
|
63
|
+
## Choose models. Run. Inspect.
|
|
16
64
|
|
|
17
|
-
|
|
18
|
-
|
|
19
|
-
|
|
20
|
-
|
|
21
|
-
ask-dialect/
|
|
22
|
-
prompt.md
|
|
23
|
-
judge.md
|
|
65
|
+
Requires **Bun 1.4.2+**, **Docker**, and connected models in **OpenCode**.
|
|
66
|
+
|
|
67
|
+
```sh
|
|
68
|
+
bun add --exact @hona/openeval
|
|
24
69
|
```
|
|
25
70
|
|
|
26
|
-
|
|
71
|
+
**`benchmark.ts`** — replace the model references with your connected models:
|
|
27
72
|
|
|
28
73
|
```ts
|
|
29
74
|
import type { Benchmark } from "@hona/openeval";
|
|
@@ -35,99 +80,98 @@ export default {
|
|
|
35
80
|
} satisfies Benchmark;
|
|
36
81
|
```
|
|
37
82
|
|
|
38
|
-
|
|
39
|
-
|
|
40
|
-
|
|
41
|
-
|
|
42
|
-
|
|
43
|
-
Write a SQL query for the ten most recent orders for a customer.
|
|
83
|
+
```sh
|
|
84
|
+
bunx --bun @hona/openeval image
|
|
85
|
+
bunx --bun @hona/openeval plan --only-eval ask-dialect
|
|
86
|
+
bunx --bun @hona/openeval run --only-repetition 1
|
|
87
|
+
bunx --bun @hona/openeval view
|
|
44
88
|
```
|
|
45
89
|
|
|
46
|
-
`
|
|
90
|
+
The viewer opens at **http://127.0.0.1:4173**. `run` resumes the same aggregate;
|
|
91
|
+
scope flags select work while retaining existing scores.
|
|
47
92
|
|
|
48
|
-
|
|
49
|
-
|
|
93
|
+
To remove a model from an existing aggregate, remove its entry from
|
|
94
|
+
`benchmark.ts`, then retire its active selections:
|
|
50
95
|
|
|
51
|
-
|
|
96
|
+
```sh
|
|
97
|
+
bunx --bun @hona/openeval snapshot ./results/RUN before-model-removal
|
|
98
|
+
bunx --bun @hona/openeval remove-models ./results/RUN --model provider/retired-model
|
|
99
|
+
```
|
|
52
100
|
|
|
53
|
-
|
|
54
|
-
|
|
101
|
+
This retains the model's recorded executions, judgments, and artifacts. It
|
|
102
|
+
does not run candidates or judges, and requires a stopped benchmark run.
|
|
103
|
+
Models still declared in `benchmark.ts` can be added back by a later `run`.
|
|
104
|
+
|
|
105
|
+
```mermaid
|
|
106
|
+
flowchart LR
|
|
107
|
+
P["prompt.md"] --> C["Isolated candidate"] --> E["Recording"]
|
|
108
|
+
J["judge.md"] --> G["Judge + citations"]
|
|
109
|
+
E --> G --> S["Metric scores"] --> V["Results viewer"]
|
|
55
110
|
```
|
|
56
111
|
|
|
57
|
-
|
|
58
|
-
insufficient. The judge supplies citations to the recording. A shared native
|
|
59
|
-
judge agent supplies the evidence and submission protocol; rubrics contain the
|
|
60
|
-
task-specific criteria. See [JUDGING.md](JUDGING.md).
|
|
112
|
+
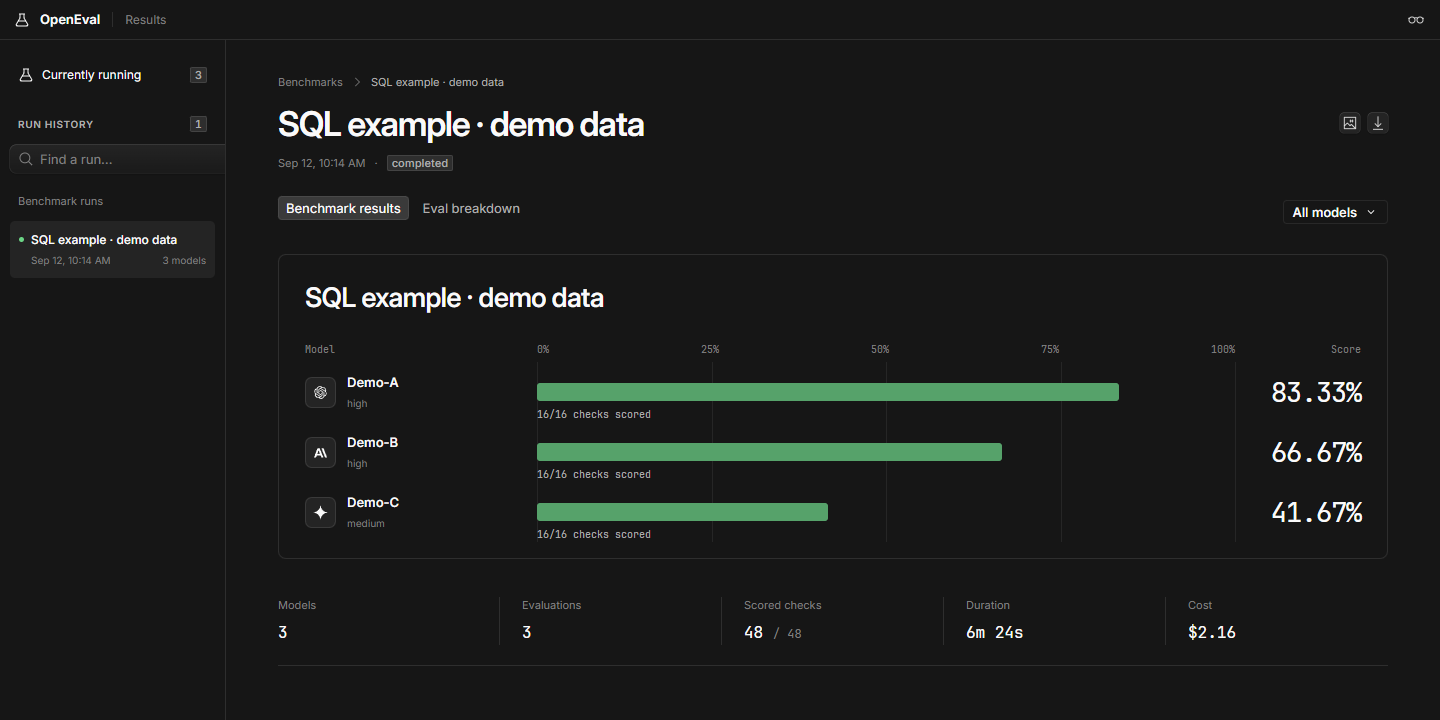
## See what earned the score
|
|
61
113
|
|
|
62
|
-
|
|
114
|
+
|
|
63
115
|
|
|
64
|
-
|
|
116
|
+
| Capability | What you get | Guide |
|
|
117
|
+
| --- | --- | --- |
|
|
118
|
+
| Multiple metrics | Independent decisions from one recording | [Rubrics](https://openev.al/docs/rubrics/) |
|
|
119
|
+
| Controlled workspaces | Readable files, pinned Git inputs, preparation | [Workspaces](https://openev.al/docs/workspaces/) |
|
|
120
|
+
| Small batches | Eval, model, repetition, and cost controls | [Running](https://openev.al/docs/running/) |
|
|
121
|
+
| Transparent scores | Equal eval weights; bounds for unresolved checks | [Scoring](https://openev.al/docs/scoring/) |
|
|
122
|
+
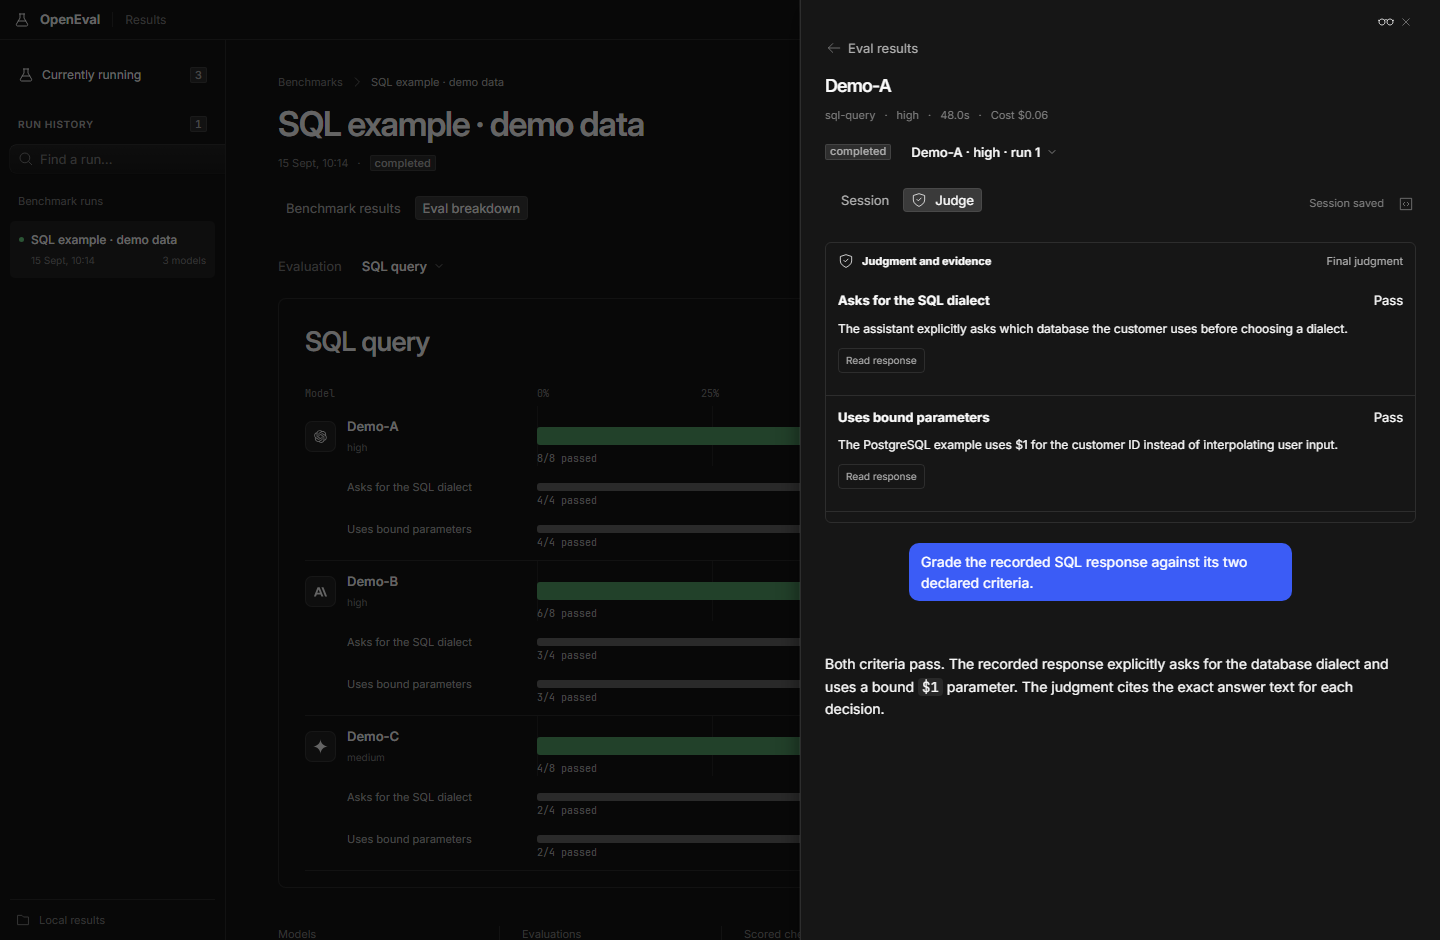
| Evidence inspection | Sessions, tool results, artifacts, and citations | [Evidence](https://openev.al/docs/evidence/) |
|
|
123
|
+
| Rejudging | New judgments from retained, immutable recordings | [Evidence](https://openev.al/docs/evidence/#revise) |
|
|
65
124
|
|
|
66
|
-
|
|
67
|
-
|
|
68
|
-
bunx --bun @hona/openeval plan
|
|
69
|
-
bunx --bun @hona/openeval run
|
|
70
|
-
bunx --bun @hona/openeval view
|
|
71
|
-
```
|
|
125
|
+
<details>
|
|
126
|
+
<summary><strong>Inspect a judgment and its evidence</strong></summary>
|
|
72
127
|
|
|
73
|
-
|
|
74
|
-
any command at another benchmark, or `--port <port>` for another viewer port.
|
|
128
|
+
|
|
75
129
|
|
|
76
|
-
|
|
77
|
-
separate result. Repeat `--only-eval`, `--only-model`, or `--only-repetition` to
|
|
78
|
-
execute a small scope while retaining the full aggregate. `--max-cost <usd>`
|
|
79
|
-
sets a scheduling budget for the invocation. Run `openeval --help` for commands.
|
|
130
|
+
</details>
|
|
80
131
|
|
|
81
|
-
|
|
82
|
-
|
|
83
|
-
The viewer provides metric drilldowns and recorded candidate and judge sessions.
|
|
84
|
-
Elapsed time measures active execution intervals, counting overlapping work once.
|
|
132
|
+
<details>
|
|
133
|
+
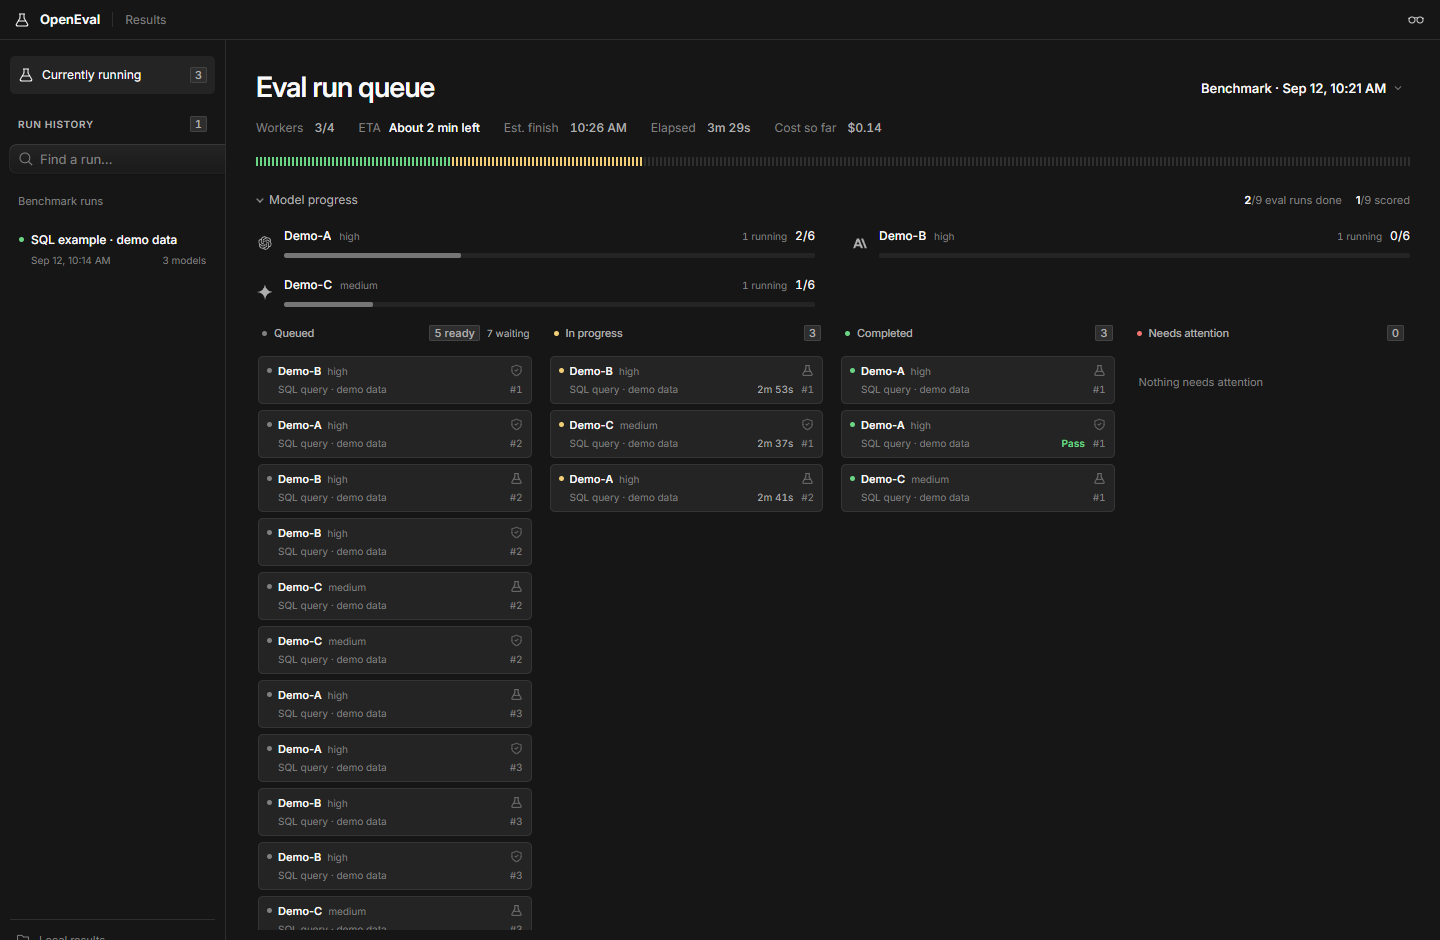
<summary><strong>Watch candidate and judge work in the live queue</strong></summary>
|
|
85
134
|
|
|
86
|
-
|
|
135
|
+
|
|
87
136
|
|
|
88
|
-
|
|
89
|
-
|
|
90
|
-
|
|
137
|
+
</details>
|
|
138
|
+
|
|
139
|
+
## Use the SDK
|
|
91
140
|
|
|
92
141
|
```ts
|
|
93
|
-
import
|
|
142
|
+
import { runBenchmark } from "@hona/openeval";
|
|
94
143
|
|
|
95
|
-
|
|
96
|
-
|
|
97
|
-
|
|
144
|
+
await runBenchmark("./my-benchmark", {
|
|
145
|
+
onlyEvals: ["ask-dialect"],
|
|
146
|
+
onlyRepetitions: [1],
|
|
147
|
+
});
|
|
98
148
|
```
|
|
99
149
|
|
|
100
|
-
|
|
101
|
-
containers receive project inputs, never judge rubrics or evaluator storage.
|
|
102
|
-
Candidates finish naturally, meet an opted-in irreversible judge decision, or
|
|
103
|
-
time out after at most 45 minutes. Finalized recordings remain immutable.
|
|
150
|
+
## Write evals with an agent
|
|
104
151
|
|
|
105
|
-
|
|
152
|
+
Use the public [Eval Writing skill](https://github.com/Hona/openeval/tree/main/.opencode/skills/eval-writing)
|
|
153
|
+
to turn a real failure into an eval, review a rubric, or investigate misleading
|
|
154
|
+
scores. It guides an agent through concrete false-pass/false-failure examples,
|
|
155
|
+
accepted alternatives, evidence requirements, and human-reviewed calibration.
|
|
106
156
|
|
|
107
|
-
|
|
108
|
-
|
|
109
|
-
|
|
110
|
-
await runBenchmark("./my-benchmark");
|
|
111
|
-
```
|
|
157
|
+
Copy the whole `.opencode/skills/eval-writing/` directory, including `references/`,
|
|
158
|
+
into the same path in your project. For global use, copy it to
|
|
159
|
+
`~/.config/opencode/skills/eval-writing/`. Then run **`/eval-writing`** in OpenCode.
|
|
112
160
|
|
|
113
|
-
|
|
114
|
-
and
|
|
115
|
-
`/view`, and `/session`.
|
|
161
|
+
> Use eval-writing to review this task and rubric. Show me the strongest false
|
|
162
|
+
> pass and false failure, then propose the smallest improvement.
|
|
116
163
|
|
|
117
|
-
|
|
164
|
+
The skill includes a framework-neutral workflow, fictional coaching examples,
|
|
165
|
+
an OpenEval-specific reference, and a broad public-research guide.
|
|
118
166
|
|
|
119
|
-
|
|
120
|
-
bun install --frozen-lockfile
|
|
121
|
-
bun run typecheck
|
|
122
|
-
bun test
|
|
123
|
-
bun run release:pack
|
|
124
|
-
bun run release:verify
|
|
125
|
-
```
|
|
167
|
+
## Develop
|
|
126
168
|
|
|
127
|
-
|
|
128
|
-
|
|
129
|
-
|
|
169
|
+
| Command | Purpose |
|
|
170
|
+
| --- | --- |
|
|
171
|
+
| `bun run site:dev` | Landing page and docs with hot reload on port 4176 |
|
|
172
|
+
| `bun run site:build && bun run site:verify` | Prerender pages and verify links and starter files |
|
|
173
|
+
| `bun run typecheck && bun test` | Local SDK checks; no live models |
|
|
174
|
+
| `bun run release:pack && bun run release:verify` | Verify the actual npm archive in a separate consumer |
|
|
130
175
|
|
|
131
|
-
|
|
132
|
-
|
|
133
|
-
third-party license notices.
|
|
176
|
+
- [Release guide](https://github.com/Hona/openeval/blob/main/RELEASING.md) · [Judge protocol](JUDGING.md)
|
|
177
|
+
- MIT licensed. The viewer includes upstream third-party license notices.
|
package/package.json
CHANGED
|
@@ -28,7 +28,7 @@ const positive = (value: unknown, fallback: number, label: string) => {
|
|
|
28
28
|
export const modelRef = (value: unknown): ModelRef => {
|
|
29
29
|
if (
|
|
30
30
|
typeof value !== "string" ||
|
|
31
|
-
!/^[\w.-]+\/[^\s/#]+(?:#[\w.-]+)?$/.test(value)
|
|
31
|
+
!/^[\w.-]+\/[^\s/#]+(?:\/[^\s/#]+)*(?:#[\w.-]+)?$/.test(value)
|
|
32
32
|
)
|
|
33
33
|
throw new Error(`Invalid model reference: ${String(value)}`);
|
|
34
34
|
return value as ModelRef;
|
|
@@ -0,0 +1,60 @@
|
|
|
1
|
+
import { resolve } from "node:path";
|
|
2
|
+
import type { ModelRef } from "../types";
|
|
3
|
+
import { Results } from "../infra/sqlite";
|
|
4
|
+
import { modelRef } from "./load-benchmark";
|
|
5
|
+
import { readBenchmarkRun } from "./read-run";
|
|
6
|
+
import { finishBenchmark } from "./run-benchmark";
|
|
7
|
+
|
|
8
|
+
/** Retire active model selections while preserving every execution and artifact. */
|
|
9
|
+
export async function removeModels(
|
|
10
|
+
directory: string,
|
|
11
|
+
models: readonly ModelRef[],
|
|
12
|
+
) {
|
|
13
|
+
const root = resolve(directory);
|
|
14
|
+
const removed = [...new Set(models.map(modelRef))];
|
|
15
|
+
if (!removed.length) throw new Error("Select models to remove");
|
|
16
|
+
const before = readBenchmarkRun(root).benchmark;
|
|
17
|
+
|
|
18
|
+
using results = new Results(resolve(root, "runner.db"));
|
|
19
|
+
return results.transaction(() => {
|
|
20
|
+
const current = results.benchmark!;
|
|
21
|
+
if (current.id !== before.id || current.mergedInto)
|
|
22
|
+
throw new Error(
|
|
23
|
+
"Benchmark was replaced or merged; use its current aggregate",
|
|
24
|
+
);
|
|
25
|
+
if (current.state === "running")
|
|
26
|
+
throw new Error(
|
|
27
|
+
"Cannot remove models while the benchmark run is running",
|
|
28
|
+
);
|
|
29
|
+
if (removed.some((model) => !current.definition.models.includes(model)))
|
|
30
|
+
throw new Error("Select models present in this benchmark run");
|
|
31
|
+
const remaining = current.definition.models.filter(
|
|
32
|
+
(model) => !removed.includes(model),
|
|
33
|
+
);
|
|
34
|
+
if (!remaining.length)
|
|
35
|
+
throw new Error("Keep at least one model in the benchmark run");
|
|
36
|
+
const retired = results
|
|
37
|
+
.slots()
|
|
38
|
+
.filter((slot) => slot.active && removed.includes(slot.model));
|
|
39
|
+
for (const slot of retired) results.select({ ...slot, active: false });
|
|
40
|
+
const definition = { ...current.definition, models: remaining };
|
|
41
|
+
results.saveBenchmark({
|
|
42
|
+
...current,
|
|
43
|
+
definition,
|
|
44
|
+
execution: { ...current.execution, deferred: 0 },
|
|
45
|
+
});
|
|
46
|
+
const benchmark = finishBenchmark({
|
|
47
|
+
directory: root,
|
|
48
|
+
definition,
|
|
49
|
+
runtime: current.runtime,
|
|
50
|
+
results,
|
|
51
|
+
});
|
|
52
|
+
results.saveBenchmark(benchmark, true);
|
|
53
|
+
return {
|
|
54
|
+
directory: root,
|
|
55
|
+
removed,
|
|
56
|
+
retiredSlots: retired.length,
|
|
57
|
+
benchmark,
|
|
58
|
+
};
|
|
59
|
+
});
|
|
60
|
+
}
|
package/src/cli.ts
CHANGED
|
@@ -6,6 +6,7 @@ import {
|
|
|
6
6
|
loadBenchmark,
|
|
7
7
|
buildImage,
|
|
8
8
|
addModels,
|
|
9
|
+
removeModels,
|
|
9
10
|
retryEvalRun,
|
|
10
11
|
judgeRun,
|
|
11
12
|
serveResults,
|
|
@@ -39,6 +40,7 @@ Commands:
|
|
|
39
40
|
snapshot <run> <name> Export a score snapshot
|
|
40
41
|
merge-runs <to> <from> Merge results into one aggregate
|
|
41
42
|
add-models <run> Add models with repeated --model flags
|
|
43
|
+
remove-models <run> Remove active models while retaining their evidence
|
|
42
44
|
retry <run> <eval-run> Retry a candidate execution
|
|
43
45
|
rejudge <run> <eval-run> Judge the saved evidence again
|
|
44
46
|
|
|
@@ -46,7 +48,7 @@ Options:
|
|
|
46
48
|
--benchmark <dir> Benchmark directory (default: current directory)
|
|
47
49
|
--run <dir> Resume a specific result directory
|
|
48
50
|
--new Start a new result
|
|
49
|
-
--model <provider/id>
|
|
51
|
+
--model <provider/id> Model to add or remove (repeatable)
|
|
50
52
|
--only-model <ref> Execute only this model (repeatable)
|
|
51
53
|
--only-eval <id> Execute only this eval (repeatable)
|
|
52
54
|
--only-repetition <n> Execute only this repetition (repeatable)
|
|
@@ -125,6 +127,16 @@ Requires Bun 1.4.2+, Docker, and an authenticated OpenCode installation.`);
|
|
|
125
127
|
if (!args[1])
|
|
126
128
|
throw new Error("add-models requires a benchmark run directory");
|
|
127
129
|
console.log((await addModels(resolve(args[1]), models())).directory);
|
|
130
|
+
} else if (command === "remove-models") {
|
|
131
|
+
if (!args[1])
|
|
132
|
+
throw new Error("remove-models requires a benchmark run directory");
|
|
133
|
+
const result = await removeModels(resolve(args[1]), models());
|
|
134
|
+
console.log(JSON.stringify({
|
|
135
|
+
directory: result.directory,
|
|
136
|
+
removed: result.removed,
|
|
137
|
+
retiredSlots: result.retiredSlots,
|
|
138
|
+
status: result.benchmark.state,
|
|
139
|
+
}, null, 2));
|
|
128
140
|
} else if (command === "retry" || command === "rejudge") {
|
|
129
141
|
if (!args[1] || !args[2])
|
|
130
142
|
throw new Error(
|
|
@@ -137,7 +149,7 @@ Requires Bun 1.4.2+, Docker, and an authenticated OpenCode installation.`);
|
|
|
137
149
|
console.log(JSON.stringify(result, null, 2));
|
|
138
150
|
} else
|
|
139
151
|
throw new Error(
|
|
140
|
-
"Commands: image, plan, run, view, add-models, merge-runs, retry, rejudge, snapshot",
|
|
152
|
+
"Commands: image, plan, run, view, add-models, remove-models, merge-runs, retry, rejudge, snapshot",
|
|
141
153
|
);
|
|
142
154
|
} catch (error) {
|
|
143
155
|
console.error(error instanceof Error ? error.message : String(error));
|
package/src/index.ts
CHANGED
|
@@ -38,6 +38,7 @@ export {
|
|
|
38
38
|
type RunBenchmarkOptions,
|
|
39
39
|
} from "./app/run-benchmark";
|
|
40
40
|
export { addModels } from "./app/add-models";
|
|
41
|
+
export { removeModels } from "./app/remove-models";
|
|
41
42
|
export type { CostEstimate } from "./app/cost-plan";
|
|
42
43
|
export { mergeBenchmarkRuns } from "./app/merge-runs";
|
|
43
44
|
export { retryEvalRun } from "./app/retry-run";
|