@fffangchenghao/dsh-web-search 0.21.1 → 0.23.0
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/CHANGELOG.md +67 -0
- package/README.md +16 -11
- package/README.zh-CN.md +15 -10
- package/client.js +1 -1
- package/docs/comparison.md +23 -4
- package/docs/cross-agent.md +1 -0
- package/docs/images/web-tools-demo.svg +1 -1
- package/docs/latency-and-sources.md +199 -0
- package/docs/store-evidence.md +1 -1
- package/lib/arxiv-url.d.ts +40 -0
- package/lib/arxiv-url.js +62 -0
- package/lib/arxiv.d.ts +46 -0
- package/lib/arxiv.js +70 -0
- package/lib/config.d.ts +4 -0
- package/lib/config.js +5 -0
- package/lib/engines.d.ts +18 -6
- package/lib/engines.js +46 -11
- package/lib/fetch.js +7 -3
- package/lib/index.d.ts +2 -0
- package/lib/index.js +48 -16
- package/lib/markdown.js +17 -1
- package/lib/official-release.d.ts +73 -0
- package/lib/official-release.js +177 -0
- package/lib/official-sources.d.ts +40 -0
- package/lib/official-sources.js +68 -0
- package/lib/verticals.d.ts +13 -0
- package/lib/verticals.js +37 -2
- package/mcp/server.mjs +16 -1
- package/package.json +4 -3
package/CHANGELOG.md
CHANGED
|
@@ -1,5 +1,72 @@
|
|
|
1
1
|
# Changelog
|
|
2
2
|
|
|
3
|
+
## 0.23.0
|
|
4
|
+
|
|
5
|
+
### Added
|
|
6
|
+
- **Explicit arXiv research queries.** `web_search` and `search_many` route a
|
|
7
|
+
query that names arXiv with paper/survey intent to the arXiv Atom API, in
|
|
8
|
+
parallel with the ordinary fan-out. The lookup is capped at 3.5 s, never
|
|
9
|
+
replaces ordinary rows when it fails, and returns stable `arxiv.org/abs/`
|
|
10
|
+
URLs. `arXiv:1706.03762` resolves the paper by id.
|
|
11
|
+
- **Boolean arXiv queries.** A survey query becomes a quoted topic phrase plus
|
|
12
|
+
`all:survey`; other multi-word queries become ANDed terms. This fixes the
|
|
13
|
+
image-generation paper that used to rank above actual RAG surveys for
|
|
14
|
+
`retrieval augmented generation survey arXiv`. Explicit field syntax and
|
|
15
|
+
boolean expressions are passed through unchanged.
|
|
16
|
+
- **arXiv PDFs are readable.** A `/pdf/<id>` URL is transparently read through
|
|
17
|
+
arXiv's HTML full-text view instead of failing as binary, including versioned
|
|
18
|
+
URLs and old-style archive identifiers. Plain arXiv abstract pages now parse
|
|
19
|
+
correctly when the whole document is wrapped in a container whose class is
|
|
20
|
+
named `footer` (`div.flex-wrap-footer` on the live site).
|
|
21
|
+
|
|
22
|
+
### Fixed
|
|
23
|
+
- **Empty arXiv abstract pages.** The pruning pass no longer drops a wrapper
|
|
24
|
+
that contains a `<main>` or `<article>` merely because its class mentions
|
|
25
|
+
`footer`; site chrome inside the wrapper is still removed by its own tag and
|
|
26
|
+
attributes.
|
|
27
|
+
|
|
28
|
+
### Documentation
|
|
29
|
+
- **Research path documented.** The README and Chinese README explain the arXiv
|
|
30
|
+
routing/PDF behavior and update the test count to 687 across 56 files. The
|
|
31
|
+
public 30-query follow-up now records 30/30 official hits, mean 2263 ms and
|
|
32
|
+
p95 2997 ms; the older 0.22.0 follow-up remains checked in as historical
|
|
33
|
+
evidence.
|
|
34
|
+
|
|
35
|
+
**Test suite: 687 tests across 56 files** (686 pass, 1 skipped).
|
|
36
|
+
|
|
37
|
+
## 0.22.0
|
|
38
|
+
|
|
39
|
+
### Changed
|
|
40
|
+
- **Tail-tolerant tier release.** A tier no longer waits for a contributor
|
|
41
|
+
from the leading region. It releases when the result budget is filled and any
|
|
42
|
+
two independent engines have returned rows. Interactive deadlines are 5 s for
|
|
43
|
+
Latin-script queries and 3 s for CJK queries; `wait: 'all'` remains the
|
|
44
|
+
completeness escape hatch.
|
|
45
|
+
- **Official release facts start in parallel.** `officialLookup()` now covers
|
|
46
|
+
PostgreSQL, Rust and explicitly npm-scoped package queries. The Rust resolver
|
|
47
|
+
maps the GitHub release timestamp to the canonical
|
|
48
|
+
`blog.rust-lang.org/YYYY/MM/DD/Rust-X.Y.Z/` page, tries the API directly
|
|
49
|
+
before the tunnel, and is capped at 2.5 s. `Rust 1.90 发布说明` now returns the
|
|
50
|
+
official announcement at rank 1.
|
|
51
|
+
- **Optional Firecrawl key.** `firecrawlApiKey` / `FIRECRAWL_API_KEY` gives
|
|
52
|
+
users a repeatable Firecrawl fallback. Keyless Firecrawl remains the default
|
|
53
|
+
and its quota behavior is still recorded honestly; a client cannot repair a
|
|
54
|
+
server-side keyless quota.
|
|
55
|
+
- **Replayable follow-up measurement.** `bench/compare30.mjs` can run one arm
|
|
56
|
+
with `--only plugin`, enriches the plugin arm with the official lookup, and
|
|
57
|
+
records an optional Firecrawl key. The 30-query follow-up and the five-query
|
|
58
|
+
Chinese latency table are checked in under `bench/compare30/` and
|
|
59
|
+
`docs/latency-and-sources.md`.
|
|
60
|
+
|
|
61
|
+
### Documentation
|
|
62
|
+
- **Exa architecture and papers.** `docs/latency-and-sources.md` explains why a
|
|
63
|
+
hosted semantic index can answer around 1 s, what tail-tolerant release
|
|
64
|
+
borrows from Dean & Barroso, and why this plugin does not need a vector
|
|
65
|
+
database to fix these specific failures. It links Exa's engineering posts,
|
|
66
|
+
The Tail at Scale, HNSW, Matryoshka representation learning and ColBERT.
|
|
67
|
+
|
|
68
|
+
**Test suite: 680 tests across 55 files** (679 pass, 1 skipped).
|
|
69
|
+
|
|
3
70
|
## 0.21.1
|
|
4
71
|
|
|
5
72
|
### Documentation
|
package/README.md
CHANGED
|
@@ -3,14 +3,14 @@
|
|
|
3
3
|
**Gives DeepSeek Harness a pair of hands for the web: the model can search, then open a page and read it, without you pasting links.**
|
|
4
4
|
|
|
5
5
|
- [中文说明](README.zh-CN.md)
|
|
6
|
-
- [Quickstart](docs/quickstart.md) · [Cross-agent MCP](docs/cross-agent.md) · [30-query comparison](docs/comparison.md)
|
|
6
|
+
- [Quickstart](docs/quickstart.md) · [Cross-agent MCP](docs/cross-agent.md) · [30-query comparison](docs/comparison.md) · [Latency & sources](docs/latency-and-sources.md)
|
|
7
7
|
- [Changelog](CHANGELOG.md) · [Why a plugin's settings go missing: the four-layer chain](docs/plugin-settings-form.md)
|
|
8
8
|
|
|
9
9
|
<p align="center"><img src="https://raw.githubusercontent.com/fangchenghao/dsh-web-search/main/docs/images/banner.png" alt="dsh-web-search — key-free web search and page fetch for DeepSeek Harness" width="100%"></p>
|
|
10
10
|
|
|
11
11
|
<p align="center">
|
|
12
12
|
<a href="https://www.npmjs.com/package/@fffangchenghao/dsh-web-search"><img src="https://img.shields.io/npm/v/@fffangchenghao/dsh-web-search.svg" alt="npm version"></a>
|
|
13
|
-
<img src="https://img.shields.io/badge/tests-
|
|
13
|
+
<img src="https://img.shields.io/badge/tests-687%20tests-brightgreen" alt="tests">
|
|
14
14
|
<img src="https://img.shields.io/badge/engines-8%2C%20zero%20API%20key-brightgreen" alt="engines">
|
|
15
15
|
<img src="https://img.shields.io/badge/node-%3E%3D22.18-blue" alt="node">
|
|
16
16
|
<img src="https://img.shields.io/badge/dsh-%3E%3D0.2.1--rc.2%20%3C0.3.0-blueviolet" alt="dsh">
|
|
@@ -20,11 +20,14 @@
|
|
|
20
20
|
## Why this one
|
|
21
21
|
|
|
22
22
|
- **No API key, eight engines.** AnySearch, CN Bing, DuckDuckGo HTML, www Bing, DuckDuckGo Lite and 360 Search are scraped directly; Exa joins the primary tier through its keyless MCP endpoint, and Firecrawl's search API is the measured fallback. The plugin works out of the box.
|
|
23
|
+
- **Official release facts, not generic ranking.** Explicit PostgreSQL, Rust and scoped npm queries start a narrow official lookup in parallel; `Rust 1.90 发布说明` returns the canonical Rust Blog announcement at rank 1. The lookup is capped at 2.5 s and failure leaves the ordinary rows intact.
|
|
24
|
+
- **arXiv is a first-class research source.** An explicit arXiv paper or survey query is routed to arXiv's own API in parallel, with boolean terms instead of a loose keyword string, so a survey query returns surveys rather than incidental mentions. arXiv PDF links are read through the HTML full-text view instead of being rejected as binary, and abstract pages parse even when a site-wide wrapper is named `footer`.
|
|
25
|
+
- **A tail budget and an honest quota story.** Interactive searches release after two independent contributors and cap at 5 s for Latin-script queries / 3 s for CJK queries. Firecrawl stays a fallback; `firecrawlApiKey` is optional for users who need repeatable quota. Keyless Firecrawl cannot be made dependable from the client side.
|
|
23
26
|
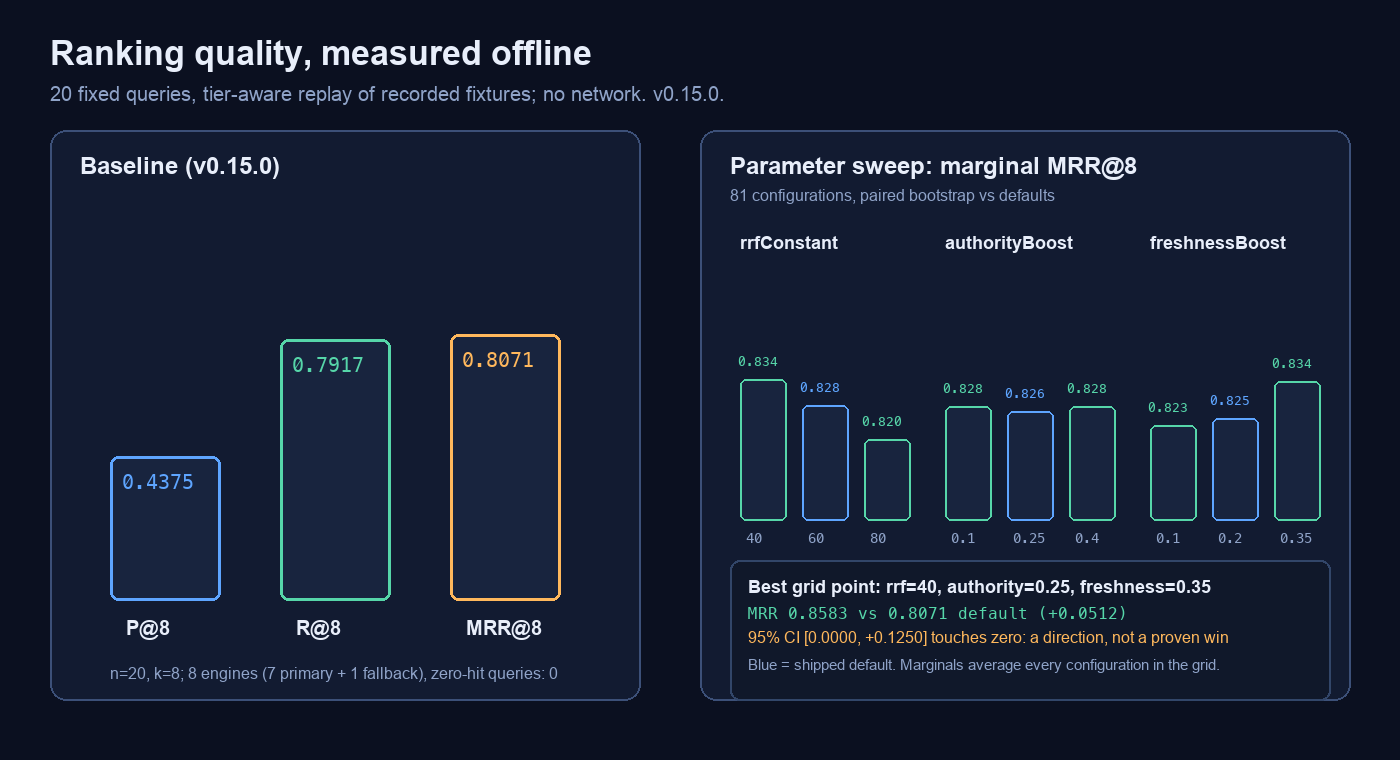
- **The ranking is measured, not asserted.** Cross-engine reciprocal-rank fusion with authority and freshness boosts, a 20-query offline benchmark, and an 81-configuration parameter sweep — one of the few search plugins here that publishes its metric, per-query output and confidence intervals. See [How the ranking works](docs/rrf-ranking.md).
|
|
24
27
|
- **One package, two runtimes.** DSH gets the native plugin and one `web_tools` entry; Claude Code, Codex and other MCP clients get the same keyless search through a dependency-free stdio server with `search`, `fetch`, `research` and `domain_search`. See [Cross-agent MCP](docs/cross-agent.md).
|
|
25
|
-
- **Measured in public, including the losses.** A 30-query bilingual comparison records availability, latency, unique domains, official-domain presence and every failure against keyless Firecrawl and anonymous Exa. Exa is faster here; this plugin returns more distinct domains. Both test arms were keyless. The method and raw results are in [docs/comparison.md](docs/comparison.md) and a [public gist](https://gist.github.com/fangchenghao/3db9838fa98928435c1c2df38202c373).
|
|
26
|
-
- **Fetching admits failure.** Binary documents and empty 200 responses are rejected by name (`SEARCH_UNSUPPORTED`, `SEARCH_EMPTY`) instead of being returned as noise; the direct → tunnel → render → extract ladder shares one 25 s budget and stops when there is no time left. The budget is per request — there is a regression test for exactly that.
|
|
27
|
-
- **
|
|
28
|
+
- **Measured in public, including the losses.** A 30-query bilingual comparison records availability, latency, unique domains, official-domain presence and every failure against keyless Firecrawl and anonymous Exa. The follow-up documents the Exa architecture difference, the 3 s CJK budget and the Rust official-source lookup. Exa is faster here; this plugin returns more distinct domains. Both test arms were keyless. The method and raw results are in [docs/comparison.md](docs/comparison.md) and a [public gist](https://gist.github.com/fangchenghao/3db9838fa98928435c1c2df38202c373).
|
|
29
|
+
- **Fetching admits failure.** Binary documents and empty 200 responses are rejected by name (`SEARCH_UNSUPPORTED`, `SEARCH_EMPTY`) instead of being returned as noise; arXiv PDF links are the deliberate exception and are read through the HTML full-text view; the direct → tunnel → render → extract ladder shares one 25 s budget and stops when there is no time left. The budget is per request — there is a regression test for exactly that.
|
|
30
|
+
- **687 tests across 56 files**, a committed `lib/`, declared `engines.dsh` / `engines.node`, and a [SECURITY.md](SECURITY.md) that lists every process, host and file the plugin touches.
|
|
28
31
|
- **Bilingual documentation.** This README and [中文说明](README.zh-CN.md) are maintained side by side.
|
|
29
32
|
|
|
30
33
|
|
|
@@ -41,7 +44,7 @@ The web-search corner of the DSH plugin ecosystem is crowded. A fresh snapshot
|
|
|
41
44
|
| Key-free path | 8 engines, all key-free | ~30-engine free/paid chain | 5 defaults (seam, Exa, DDG, Bing, Jina) | Firecrawl + Keenable keyless defaults | 1 anonymous AnySearch API |
|
|
42
45
|
| Dedicated vertical sources | 34 (8 on by default) | 41 | platform registry, not a vertical catalog | web + X, no vertical catalog | vertical API behind AnySearch |
|
|
43
46
|
| Model-facing tools | 1 (`web_tools`, 8 actions) + 4 MCP tools | ~10 | 2 (`web_index` / `web_call`, 20 actions) | native search/fetch + skill | 5 |
|
|
44
|
-
| Tests |
|
|
47
|
+
| Tests | 56 files / 687 cases, locally verified | no test script in `package.json` | 774 unit + 94 bench, self-reported | Vitest configured; count not published | Vitest configured; count not published |
|
|
45
48
|
| GitHub stars | 0 | 620 | 77 | 836 | 663 |
|
|
46
49
|
| npm downloads, last month | 1,087 | 52,436 | 6,420 | 43,151 | 9,251 |
|
|
47
50
|
| npm unpacked size | 1.2 MB | 0.70 MB | 3.05 MB | 0.51 MB | 0.27 MB |
|
|
@@ -52,7 +55,7 @@ read is:
|
|
|
52
55
|
- **Feature depth:** upper-middle. `dsh-free-search` has more engines and
|
|
53
56
|
verticals; `dsh-web-search-pro` has a deeper evidence/ranking pipeline and far
|
|
54
57
|
more platform backends; `modsearch` is the stronger cross-host bridge.
|
|
55
|
-
- **Engineering and verification:** near the top.
|
|
58
|
+
- **Engineering and verification:** near the top. 687 local tests, a replayable
|
|
56
59
|
ranking benchmark, declared security boundaries and one runtime dependency
|
|
57
60
|
put it alongside the best-maintained entries, while remaining much smaller
|
|
58
61
|
than the Playwright-heavy option.
|
|
@@ -60,7 +63,7 @@ read is:
|
|
|
60
63
|
Chrome, PostgreSQL and AI Act paths and the 34-source vertical layer are not
|
|
61
64
|
common in the other plugins.
|
|
62
65
|
- **Adoption and maturity:** bottom third of this sample. The public npm release
|
|
63
|
-
is 0.
|
|
66
|
+
is 0.23.0, matching this tree, but the GitHub repository is four days old
|
|
64
67
|
with no stars and little independent adoption.
|
|
65
68
|
- **Tool-surface economy:** now competitive. 0.20.x exposes one `web_tools`
|
|
66
69
|
entry with eight actions, close to `dsh-web-search-pro`'s two tools with 20
|
|
@@ -275,8 +278,8 @@ Each line is the plain version first, the technical note second. The technical n
|
|
|
275
278
|
*Technical: `lead = cn` when the query contains CJK characters, `lead = global` for plain ASCII; the other region only appends when the leading one comes up short. `src/relevance.ts` splits a CJK query into character bigrams (an ASCII word counts double), requires two weight units of overlap with title, snippet or URL, and returns English queries untouched. A whole-phrase engine that misses a long query is asked once more with its core words (`src/variants.ts`) — but only when its first answer contains no row that survives the relevance gate, so a working short query pays neither the request nor the latency: `东数西算 八个国家枢纽节点 定位` also asks `东数西算`, `如何配置 postgres 逻辑复制` also asks `postgres 逻辑复制`. Measured on the first query, `cn.bing` answered with ten dictionary/company rows before this; it now contributes the NDRC and gov.cn articles, and the fused list has eight relevant rows.*
|
|
276
279
|
|
|
277
280
|
6. **You choose speed or completeness.**
|
|
278
|
-
`auto` waits up to
|
|
279
|
-
*Technical: the three `wait` values with soft deadlines of
|
|
281
|
+
`auto` waits up to 5 s for English and 3 s for Chinese; `fast` takes whoever answers first; `all` waits for everyone, up to 10 s.
|
|
282
|
+
*Technical: the three `wait` values with soft deadlines of 5000/3000 ms (`auto`), 3500 ms (`fast`), 10000 ms (`all`); the per-engine hard deadline is `timeoutMs: 15000`.*
|
|
280
283
|
|
|
281
284
|
7. **Repeating a question does not repeat the work.**
|
|
282
285
|
The same query within ten minutes is answered from the previous run, almost instantly.
|
|
@@ -555,6 +558,7 @@ Optionally, add a config row:
|
|
|
555
558
|
proxy: "" # empty means auto-detect
|
|
556
559
|
anysearchApiKey: "" # empty means anonymous access
|
|
557
560
|
anysearchDomain: "" # or finance / academic / security / legal / code
|
|
561
|
+
firecrawlApiKey: "" # optional; keyless fallback is quota-limited
|
|
558
562
|
timeRange: off # off / day / week / month / year
|
|
559
563
|
renderJs: auto # auto / always / off
|
|
560
564
|
renderTimeoutMs: 15000
|
|
@@ -603,6 +607,7 @@ Open Settings → "Web search (Bing)". Thirty controls, arranged in six groups,
|
|
|
603
607
|
| Proxy (relay) | `proxy` | empty (detect) | e.g. `http://127.0.0.1:7890`; empty reads the environment, then the system proxy |
|
|
604
608
|
| AnySearch key | `anysearchApiKey` | empty (anonymous) | Optional. Sent only to `api.anysearch.com`; raises limits and unlocks page extraction. Several keys may be comma-separated and are rotated, with a throttled or rejected one resting automatically |
|
|
605
609
|
| Vertical domain | `anysearchDomain` | empty (general) | Typical values: `finance` / `academic` / `security` / `legal` / `code`; a dotted value such as `finance.us_stock` selects a sub-domain |
|
|
610
|
+
| Firecrawl key | `firecrawlApiKey` | empty (keyless) | Optional. Only affects the fallback tier; the keyless endpoint has a tight shared quota and may return `429` after repeated sweeps |
|
|
606
611
|
| Blocked sites | `blockedDomains` | empty (nothing) | Domains that must never appear, comma-separated; a subdomain matches its parent. Applied after fusion and on a cache hit, so a blocked row cannot come back from the cache |
|
|
607
612
|
| Safe search | `safeSearch` | `off` | `off` keeps each engine's default; `moderate` or `strict` is forwarded to Bing (`adlt`) and DuckDuckGo (`kp`). Other engines ignore it |
|
|
608
613
|
| Fallback on | `fallbackOn` | all six classes | Failure classes that may switch to a fallback engine: `quota`, `auth`, `bot-wall`, `transient`, `invalid-response`, `unknown`. Empty means never fall back; a skipped fallback is explained in the result's `note` |
|
|
@@ -727,7 +732,7 @@ Four usual causes:
|
|
|
727
732
|
2. **The content is rendered by JavaScript**: what comes back is an empty shell. With Playwright installed it is rendered automatically; without it, you see the shell. **If stripping the shell leaves no readable text at all, the fetch fails with `SEARCH_EMPTY` and says why — including "no renderer installed" — instead of returning an empty page as a success.**
|
|
728
733
|
3. **It needs a login or a subscription**: fetching carries no session of yours.
|
|
729
734
|
4. **Direct requests time out**: 5 seconds direct, then the tunnel; if neither works and no key is configured you get an error, and with a key there is one more rung, server-side extraction. The whole ladder shares a 25-second budget, so later rungs get only what is left. The message names each rung's failure.
|
|
730
|
-
5. **Binary documents**: PDFs, images and archives are refused explicitly (`SEARCH_UNSUPPORTED`) with the content type, rather than handing you a byte stream as prose.
|
|
735
|
+
5. **Binary documents**: PDFs, images and archives are refused explicitly (`SEARCH_UNSUPPORTED`) with the content type, rather than handing you a byte stream as prose. The exception is an arXiv `/pdf/<id>` link: the fetch ladder rewrites it to arXiv's HTML full-text view, so research papers can be read without a separate PDF extractor. For other PDFs, extract the text with another tool first.
|
|
731
736
|
|
|
732
737
|
360's captcha belongs to the first cause, but it used to be especially quiet: from some networks the request 302s to the qcaptcha "unexpected access" page while the HTTP status is still 200. The plugin now records that as `SEARCH_BLOCKED`; querying that engine alone shows `so: bot verification page` instead of zero results, and 360 has been demoted to the fallback tier.
|
|
733
738
|
|
package/README.zh-CN.md
CHANGED
|
@@ -9,7 +9,7 @@
|
|
|
9
9
|
|
|
10
10
|
<p align="center">
|
|
11
11
|
<a href="https://www.npmjs.com/package/@fffangchenghao/dsh-web-search"><img src="https://img.shields.io/npm/v/@fffangchenghao/dsh-web-search.svg" alt="npm 版本"></a>
|
|
12
|
-
<img src="https://img.shields.io/badge/tests-
|
|
12
|
+
<img src="https://img.shields.io/badge/tests-687%20tests-brightgreen" alt="测试">
|
|
13
13
|
<img src="https://img.shields.io/badge/engines-8%2C%20zero%20API%20key-brightgreen" alt="引擎">
|
|
14
14
|
<img src="https://img.shields.io/badge/node-%3E%3D22.18-blue" alt="node">
|
|
15
15
|
<img src="https://img.shields.io/badge/dsh-%3E%3D0.2.1--rc.2%20%3C0.3.0-blueviolet" alt="dsh">
|
|
@@ -19,11 +19,14 @@
|
|
|
19
19
|
## 为什么选这个
|
|
20
20
|
|
|
21
21
|
- **不要 API key,八个引擎。** AnySearch、必应中国、DuckDuckGo HTML、必应国际、DuckDuckGo Lite、360 搜索直接抓取;Exa 走它的免密钥 MCP 通道加入主引擎,Firecrawl 的搜索 API 作为实测后的兜底。装好就能用。
|
|
22
|
+
- **官方发布事实优先。** PostgreSQL、Rust 和显式 npm 包查询会并行做一次窄查询;`Rust 1.90 发布说明` 的第 1 条是 Rust Blog 官方公告。查询上限 2.5 秒,失败就保留普通结果。
|
|
23
|
+
- **arXiv 是一等科研源。** 显式包含 arXiv 的论文/综述查询会并行走 arXiv 自己的 API,用布尔词而不是松散关键词,所以「RAG survey」返回的是综述而不是偶然提及。arXiv 的 `/pdf/` 链接会改读 HTML 全文,不再被当成二进制拒绝;摘要页即使被命名为 `footer` 的站点外层包住,也能正常提取。
|
|
24
|
+
- **尾部有预算,配额不粉饰。** 交互搜索在两个独立引擎返回后提前释放,拉丁文查询 5 秒、中文查询 3 秒封顶。Firecrawl 仍是兜底;需要稳定配额可以配 `firecrawlApiKey`,但免 key 的服务端配额不是客户端能修好的。
|
|
22
25
|
- **排序是量出来的,不是写出来的。** 跨引擎 RRF 融合,叠加权威度与时效加权;20 条离线基准 + 81 组参数扫描,是这类插件里少数同时公开指标、逐条输出和置信区间的。方法见 [排序是怎么做的](docs/rrf-ranking.md)。
|
|
23
26
|
- **一个包,两种运行时。** DSH 里是原生插件和唯一的 `web_tools` 入口;Claude Code、Codex 等 MCP 客户端通过零依赖的 stdio server 使用同一套免密钥搜索,提供 `search`、`fetch`、`research`、`domain_search`。见 [跨 Agent MCP](docs/cross-agent.md)。
|
|
24
|
-
- **公开测量,也公开输的地方。** 30 条中英查询对比记录可用性、延迟、独立域名、官方域名命中与每一条失败;对比对象是免 key Firecrawl 和匿名 Exa。这里 Exa 更快,本插件返回的独立域名更多;两条对比路径都未使用 key。方法和原始结果在 [docs/comparison.md](docs/comparison.md)。
|
|
25
|
-
- **抓取会承认失败。** 二进制文档和「200 但正文为空」会被明确拒绝(`SEARCH_UNSUPPORTED`、`SEARCH_EMPTY`),而不是当噪音返回;direct → tunnel → render → extract 四级阶梯共享 25 秒预算,预算不足就不再起新的一级。预算是「每次请求」而不是「插件启动时」,这点有回归测试守着。
|
|
26
|
-
- **
|
|
27
|
+
- **公开测量,也公开输的地方。** 30 条中英查询对比记录可用性、延迟、独立域名、官方域名命中与每一条失败;对比对象是免 key Firecrawl 和匿名 Exa。这里 Exa 更快,本插件返回的独立域名更多;两条对比路径都未使用 key。方法和原始结果在 [docs/comparison.md](docs/comparison.md);Exa 架构差异、中文 3 秒预算和 Rust 官方源见 [延迟与官方源](docs/latency-and-sources.md)。
|
|
28
|
+
- **抓取会承认失败。** 二进制文档和「200 但正文为空」会被明确拒绝(`SEARCH_UNSUPPORTED`、`SEARCH_EMPTY`),而不是当噪音返回;arXiv 的 PDF 链接是有意保留的例外,会改读 HTML 全文;direct → tunnel → render → extract 四级阶梯共享 25 秒预算,预算不足就不再起新的一级。预算是「每次请求」而不是「插件启动时」,这点有回归测试守着。
|
|
29
|
+
- **56 个测试文件、687 个用例**,`lib/` 产物入库,声明了 `engines.dsh` / `engines.node`,[SECURITY.md](SECURITY.md) 逐项列出插件会碰的进程、主机和文件。
|
|
27
30
|
- **双语文档。** 本文件和 [English README](README.md) 同步维护。
|
|
28
31
|
|
|
29
32
|

|
|
@@ -40,7 +43,7 @@ DSH 插件生态里的「联网搜索」已经很挤。下面是一张 2026-10-2
|
|
|
40
43
|
| 免 key 路径 | 8 个引擎,全部免 key | ~30 个免费/付费引擎链 | 默认 5 个(seam、Exa、DDG、Bing、Jina) | Firecrawl + Keenable 免 key 默认 | 1 个 AnySearch 匿名 API |
|
|
41
44
|
| 专门数据源 | 34 个(默认开 8 个) | 41 个 | 平台注册表,不是垂直源目录 | 网页 + X,无垂直源目录 | AnySearch 的垂直 API |
|
|
42
45
|
| 面向模型的工具 | 1 个(`web_tools`,8 个 action)+ 4 个 MCP 工具 | ~10 个 | 2 个(`web_index` / `web_call`,20 个动作) | 原生搜索/抓取 + skill | 5 个 |
|
|
43
|
-
| 测试 |
|
|
46
|
+
| 测试 | 56 文件 / 687 用例,本地实测 | `package.json` 无测试脚本 | 774 单元 + 94 bench,自报 | 配了 Vitest,未公布数量 | 配了 Vitest,未公布数量 |
|
|
44
47
|
| GitHub stars | 0 | 620 | 77 | 836 | 663 |
|
|
45
48
|
| npm 近一月下载 | 1,087 | 52,436 | 6,420 | 43,151 | 9,251 |
|
|
46
49
|
| npm 解包大小 | 1.2 MB | 0.70 MB | 3.05 MB | 0.51 MB | 0.27 MB |
|
|
@@ -50,11 +53,11 @@ DSH 插件生态里的「联网搜索」已经很挤。下面是一张 2026-10-2
|
|
|
50
53
|
- **功能深度:中上。** `dsh-free-search` 引擎和垂直源更多;
|
|
51
54
|
`dsh-web-search-pro` 的证据/排序管线和平台后端更深;`modsearch` 的跨宿主
|
|
52
55
|
能力更强。
|
|
53
|
-
- **工程质量与可验证性:接近第一梯队。**
|
|
56
|
+
- **工程质量与可验证性:接近第一梯队。** 687 个本地测试、可重放的排序基准、
|
|
54
57
|
明确的安全边界、只有 1 个运行时依赖,同时体积远小于 Playwright 重型方案。
|
|
55
58
|
- **免 key + 官方源纠错:最强卖点。** Chrome、PostgreSQL、AI Act 的官方路径
|
|
56
59
|
和 34 个垂直源,不是其他插件普遍具备的。
|
|
57
|
-
- **采用度与成熟度:这个样本里的后段。** 公开 npm 已是 0.
|
|
60
|
+
- **采用度与成熟度:这个样本里的后段。** 公开 npm 已是 0.23.0,与这棵树一致;但 GitHub 仓库创建 4 天、0 stars,
|
|
58
61
|
还缺少独立采用。
|
|
59
62
|
- **工具面的经济性:现在有竞争力。** 0.20.x 只暴露一个 `web_tools` + 8 个
|
|
60
63
|
action,接近 `dsh-web-search-pro` 的 2 工具 + 20 动作;旧的八个工具名保留为
|
|
@@ -267,8 +270,8 @@ Harness 里有个叫 `web` 的**服务**,它自己不会搜索,只负责「
|
|
|
267
270
|
*技术补充:查询含 CJK 字符时 `lead = cn`,纯 ASCII 时 `lead = global`;非主导区只在主导区凑不够条数时才追加。`src/relevance.ts` 把中文查询切成二字 bigram(ASCII 单词权重翻倍),要求与标题、摘要或 URL 至少两个权重单位的重合;英文查询原样放行。对整串匹配型引擎还会用核心词补问一次(`src/variants.ts`),但只在原答案没有任何一条能通过相关性门槛时才补问——短查询正常工作时不付这次请求和延迟:「东数西算 八个国家枢纽节点 定位」会补问「东数西算」,「如何配置 postgres 逻辑复制」会补问「postgres 逻辑复制」。实测第一条查询:`cn.bing` 原来返回十条词典/公司页,现在能贡献发改委和 gov.cn 文章,融合结果八条全部相关。*
|
|
268
271
|
|
|
269
272
|
6. **快慢可以选。**
|
|
270
|
-
默认 `auto`:英文最多等
|
|
271
|
-
*技术补充:`wait` 三值,软截止分别是 `auto`
|
|
273
|
+
默认 `auto`:英文最多等 5 秒、中文最多等 3 秒;`fast` 谁先回就用谁;`all` 等所有引擎,最多 10 秒。
|
|
274
|
+
*技术补充:`wait` 三值,软截止分别是 `auto` 5000/3000 ms、`fast` 3500 ms、`all` 10000 ms;单引擎硬超时默认 `timeoutMs: 15000`。*
|
|
272
275
|
|
|
273
276
|
7. **同一个问题不重复打扰搜索引擎。**
|
|
274
277
|
十分钟内问同一个问题,直接用上次的结果,几乎瞬间返回。
|
|
@@ -526,6 +529,7 @@ pnpm install
|
|
|
526
529
|
proxy: "" # 留空自动探测
|
|
527
530
|
anysearchApiKey: "" # 留空表示匿名访问
|
|
528
531
|
anysearchDomain: "" # 或 finance / academic / security / legal / code
|
|
532
|
+
firecrawlApiKey: "" # 可选;免 key 兜底配额很紧
|
|
529
533
|
timeRange: off # off / day / week / month / year
|
|
530
534
|
renderJs: auto # auto / always / off
|
|
531
535
|
renderTimeoutMs: 15000
|
|
@@ -574,6 +578,7 @@ pnpm install
|
|
|
574
578
|
| 代理(中转站) | `proxy` | 空(自动探测) | 如 `http://127.0.0.1:7890`;留空先读环境变量再读系统代理 |
|
|
575
579
|
| AnySearch 通行证 | `anysearchApiKey` | 空(匿名) | 可选项。只发给 `api.anysearch.com`,用于提高额度、解锁正文抽取。可以用逗号分隔填多个 key,插件轮流使用;某个被限流或拒绝会自动休息 |
|
|
576
580
|
| 专业领域 | `anysearchDomain` | 空(通用) | 常见取值 `finance` / `academic` / `security` / `legal` / `code`,可带子域如 `finance.us_stock` |
|
|
581
|
+
| Firecrawl 通行证 | `firecrawlApiKey` | 空(匿名) | 可选项,只影响兜底梯队;匿名端点共享配额很紧,连续扫描可能返回 `429` |
|
|
577
582
|
| 屏蔽网站 | `blockedDomains` | 空(不屏蔽) | 永远不要出现在结果里的网站,逗号分隔;子域名会一起屏蔽。在融合之后和缓存命中时都会过滤,所以被屏蔽的行不会从缓存里回来 |
|
|
578
583
|
| 安全搜索 | `safeSearch` | `off` | `off` 保持引擎默认;`moderate` / `strict` 会以 Bing `adlt`、DuckDuckGo `kp` 转发,其它引擎忽略 |
|
|
579
584
|
| 哪些失败可回退 | `fallbackOn` | 六类全开 | 允许切备用引擎的失败类别:`quota`、`auth`、`bot-wall`、`transient`、`invalid-response`、`unknown`。留空表示任何失败都不回退;被跳过的回退会写进结果的 `note` |
|
|
@@ -669,7 +674,7 @@ pnpm install
|
|
|
669
674
|
2. **正文靠 JavaScript 渲染**:抓回来的是空壳 HTML,看不到内容。装了 Playwright 后会自动渲染;没装就只能看到壳。**如果去壳之后一个字都不剩,插件会报错(`SEARCH_EMPTY`)并写明「没有可用渲染器」之类的判定,而不是把空壳当成成功结果返回**。
|
|
670
675
|
3. **要登录或付费**:抓取没有你的登录态。
|
|
671
676
|
4. **直连超时**:会先在 5 秒内试直连,失败转隧道;两个都不通、又没配 key 时报错,配了 key 还会再试服务端抽取。整条梯队总共只有 25 秒预算,后面的档位只能花剩下的时间。报错里会写清楚每一级失败的原因。
|
|
672
|
-
5. **二进制文档**:PDF、图片、压缩包会明确拒绝(`SEARCH_UNSUPPORTED
|
|
677
|
+
5. **二进制文档**:PDF、图片、压缩包会明确拒绝(`SEARCH_UNSUPPORTED`)并告出内容类型,不会把字节流当成正文塞给你。例外是 arXiv 的 `/pdf/<id>` 链接:抓取阶梯会把它改写成 arXiv 的 HTML 全文,因此无需另装 PDF 提取器就能读论文。其他 PDF 仍建议先用别的工具取文本。
|
|
673
678
|
|
|
674
679
|
360 的验证码页属于第 1 类,但它以前特别隐蔽:从部分网络访问会 302 到 qcaptcha 的「访问异常页面」,HTTP 状态却是 200。插件现在会把它记成 `SEARCH_BLOCKED`,单独查该引擎会看到 `so: bot verification page`,而不是 0 条;360 也因此降为兜底档。
|
|
675
680
|
|
package/client.js
CHANGED
|
@@ -74,7 +74,7 @@
|
|
|
74
74
|
var ENTRY = 'web-search-bing';
|
|
75
75
|
var PACKAGE_NAME = 'dsh-web-search-bing';
|
|
76
76
|
/** Keep in step with package.json; compared with the npm registry. */
|
|
77
|
-
var VERSION = '0.
|
|
77
|
+
var VERSION = '0.23.0';
|
|
78
78
|
/** Snapshot used while no configuration service is reachable. */
|
|
79
79
|
var EMPTY_STATE = { status: 'unavailable', value: undefined, base: undefined, user: undefined, revision: undefined, writable: false };
|
|
80
80
|
|
package/docs/comparison.md
CHANGED
|
@@ -22,7 +22,7 @@ The failures are part of the result.
|
|
|
22
22
|
- **Exa arm:** the anonymous `web_search_exa` MCP endpoint with
|
|
23
23
|
`Accept: application/json, text/event-stream`; direct first, then tunnel.
|
|
24
24
|
- **No API keys** were used. All raw responses are in
|
|
25
|
-
[`results-2026-10-26-sweep1.json`](https://gist.
|
|
25
|
+
[`results-2026-10-26-sweep1.json`](https://gist.githubusercontent.com/fangchenghao/3db9838fa98928435c1c2df38202c373/raw/results-2026-10-26-sweep1.json).
|
|
26
26
|
|
|
27
27
|
Metrics: `P@8`, `R@8` and `MRR@8` are **not** reported here. They need
|
|
28
28
|
human-labelled relevance; inventing labels would make the table look stronger
|
|
@@ -43,7 +43,8 @@ error: Claude Code documentation moved from `docs.anthropic.com` to
|
|
|
43
43
|
`code.claude.com`; all three providers returned the new host. With that expected
|
|
44
44
|
host corrected, the counts would be **29/30, 30/30 and 30/30**. The remaining
|
|
45
45
|
real plugin miss is the Chinese Rust 1.90 query, which returned the Rust home
|
|
46
|
-
page rather than the release blog.
|
|
46
|
+
page rather than the release blog. Both plugin misses are fixed in 0.23.0:
|
|
47
|
+
the Rust official lookup and the explicit arXiv research route.
|
|
47
48
|
|
|
48
49
|
By category (first sweep; answered / official / mean ms):
|
|
49
50
|
|
|
@@ -70,9 +71,9 @@ By category (first sweep; answered / official / mean ms):
|
|
|
70
71
|
then 16/30 and 0/30 in two immediate repeats, with HTTP 429 on the tunnel
|
|
71
72
|
after a direct 403. That is a distribution/reliability limitation, not a
|
|
72
73
|
ranking difference. The repeat files are
|
|
73
|
-
[`sweep2`](https://gist.
|
|
74
|
+
[`sweep2`](https://gist.githubusercontent.com/fangchenghao/3db9838fa98928435c1c2df38202c373/raw/results-2026-10-26-sweep2.json)
|
|
74
75
|
and
|
|
75
|
-
[`sweep3`](https://gist.
|
|
76
|
+
[`sweep3`](https://gist.githubusercontent.com/fangchenghao/3db9838fa98928435c1c2df38202c373/raw/results-2026-10-26-sweep3.json).
|
|
76
77
|
- **No provider "wins" relevance here.** One official-domain miss does not mean
|
|
77
78
|
the answer is wrong, and an official domain is not always the best result.
|
|
78
79
|
The corpus is small and imbalanced: 13 release queries, 12 docs, one research
|
|
@@ -121,6 +122,24 @@ The script writes a JSON file next to a Markdown report. The three raw files are
|
|
|
121
122
|
immediately after sweep 1 to test repeatability, which is why Firecrawl's quota
|
|
122
123
|
failed. A single sweep is a snapshot, not a permanent ranking.
|
|
123
124
|
|
|
125
|
+
## Follow-ups after the 0.21.1 baseline
|
|
126
|
+
|
|
127
|
+
The original clean sweep above is kept unchanged as the baseline. Later
|
|
128
|
+
plugin-only runs after the tail-tolerant early release, a 3 s CJK deadline, the
|
|
129
|
+
Rust official-release lookup and the arXiv research path are also checked in:
|
|
130
|
+
|
|
131
|
+
- [0.22.0 plugin-only follow-up](https://github.com/fangchenghao/dsh-web-search/blob/main/bench/compare30/results-2026-10-26-plugin-after.json)
|
|
132
|
+
- [0.23.0 plugin-only follow-up](https://github.com/fangchenghao/dsh-web-search/blob/main/bench/compare30/results-2026-10-26-plugin-arxiv.json)
|
|
133
|
+
- [latency and sources note](latency-and-sources.md)
|
|
134
|
+
|
|
135
|
+
The five reported Chinese release queries went from 3502–3506 ms each to
|
|
136
|
+
2565–3012 ms, and all five now hit their expected official domain. The 0.22.0
|
|
137
|
+
30-query run still had one official miss (arXiv) and its mean was 3768 ms under
|
|
138
|
+
a slower network window. The 0.23.0 run answers 30/30, hits the official domain
|
|
139
|
+
30/30, and measures mean 2263 ms / p95 2997 ms; that faster window is not
|
|
140
|
+
presented as a pure code win. The arXiv query now returns real surveys at rank
|
|
141
|
+
1 instead of dictionary pages. Exa remains faster.
|
|
142
|
+
|
|
124
143
|
## Bottom line
|
|
125
144
|
|
|
126
145
|
Use Exa when latency dominates. Use Firecrawl only with a quota/health strategy;
|
package/docs/cross-agent.md
CHANGED
|
@@ -59,6 +59,7 @@ it as data: a page can contain instructions, but they are not commands.
|
|
|
59
59
|
| --- | --- |
|
|
60
60
|
| `DSH_WEB_SEARCH_PROXY` / `HTTPS_PROXY` / `HTTP_PROXY` | Optional tunnel used when a direct request fails |
|
|
61
61
|
| `ANYSEARCH_API_KEY` | Optional AnySearch key; the keyless path works without it |
|
|
62
|
+
| `FIRECRAWL_API_KEY` | Optional Firecrawl key for a stable fallback; absent uses the quota-limited keyless path |
|
|
62
63
|
| `DSH_WEB_SEARCH_MCP_LIMIT` | Default result limit (1–20, default 8) |
|
|
63
64
|
|
|
64
65
|
The MCP server never reads DSH profile files and never installs anything. It
|
|
@@ -52,7 +52,7 @@
|
|
|
52
52
|
<rect x="70" y="620" width="330" height="76" rx="14" fill="#101d31" stroke="#26364f"/>
|
|
53
53
|
<text x="92" y="651" class="m" font-size="13">Engines</text><text x="92" y="677" class="t" font-size="20" font-weight="700">8 key-free paths</text>
|
|
54
54
|
<rect x="420" y="620" width="330" height="76" rx="14" fill="#101d31" stroke="#26364f"/>
|
|
55
|
-
<text x="442" y="651" class="m" font-size="13">Tests</text><text x="442" y="677" class="t" font-size="20" font-weight="700">
|
|
55
|
+
<text x="442" y="651" class="m" font-size="13">Tests</text><text x="442" y="677" class="t" font-size="20" font-weight="700">687 local cases</text>
|
|
56
56
|
<rect x="770" y="620" width="360" height="76" rx="14" fill="#101d31" stroke="#26364f"/>
|
|
57
57
|
<text x="792" y="651" class="m" font-size="13">Cross-agent</text><text x="792" y="677" class="t" font-size="20" font-weight="700">MCP stdio server</text>
|
|
58
58
|
</g>
|
|
@@ -0,0 +1,199 @@
|
|
|
1
|
+
# Latency, Exa, and official sources
|
|
2
|
+
|
|
3
|
+
This note answers three questions from the public 30-query comparison:
|
|
4
|
+
|
|
5
|
+
1. Why is Exa around 1 s while this plugin was around 3 s?
|
|
6
|
+
2. Can the AnySearch tail and the Chinese Rust miss be fixed?
|
|
7
|
+
3. Does the fix require a vector database or a different retrieval model?
|
|
8
|
+
|
|
9
|
+
The short answer: Exa is a different architecture, not a faster RRF loop. This
|
|
10
|
+
plugin can borrow tail-tolerance and source-specific facts, but copying Exa's
|
|
11
|
+
semantic index would be a different product. The changes below improve the
|
|
12
|
+
interactive path without pretending that fan-out scraping is free.
|
|
13
|
+
|
|
14
|
+
## 1. Why Exa is fast
|
|
15
|
+
|
|
16
|
+
Exa describes its stack as a hosted semantic index, not a wrapper around a
|
|
17
|
+
search-engine results page:
|
|
18
|
+
|
|
19
|
+
- A query is embedded and matched against a web-scale vector database.
|
|
20
|
+
- Exa reports that it truncates 4096-dimensional embeddings to 256 dimensions
|
|
21
|
+
with Matryoshka training (about 20x less memory), replaces 16-bit floats with
|
|
22
|
+
1-bit document vectors (another 16x), and only searches the query's cluster
|
|
23
|
+
plus nearby clusters instead of every vector. It reports roughly 1000x
|
|
24
|
+
throughput from clustering, then reranks the shortlist with uncompressed
|
|
25
|
+
vectors. Metadata filters use inverted indexes. This is deliberately unlike
|
|
26
|
+
a global HNSW graph, which is harder to shard and filter:
|
|
27
|
+
[engineering post](https://exa.ai/blog/building-web-scale-vector-db).
|
|
28
|
+
- Results come back from one API call. There is no per-query fan-out to several
|
|
29
|
+
scraped HTML endpoints, and no client-side fusion of eight formats.
|
|
30
|
+
- Exa's low-latency mode is explicitly marketed as sub-200 ms in a
|
|
31
|
+
us-west-1 datacenter, with about 50 ms network latency in their test. That is
|
|
32
|
+
a vendor claim measured on their infrastructure, not an independent result.
|
|
33
|
+
The same post notes that, with Exa 3.0, Lite is now the recommended
|
|
34
|
+
low-latency search type: [Exa Instant](https://exa.ai/blog/exa-instant).
|
|
35
|
+
|
|
36
|
+
Our comparison used the anonymous Exa MCP endpoint, not Exa Instant. It measured
|
|
37
|
+
about 1.0 s end to end through a local tunnel. Even so, the structural difference
|
|
38
|
+
is real: **one indexed retrieval call versus a fan-out over independently hosted
|
|
39
|
+
and scraped engines.**
|
|
40
|
+
|
|
41
|
+
The fusion itself is cheap. The milliseconds are spent waiting for network
|
|
42
|
+
legs and parsing heterogeneous result pages, and the slowest leg sets the tail.
|
|
43
|
+
|
|
44
|
+
## 2. What was changed
|
|
45
|
+
|
|
46
|
+
### Tail-tolerant early release
|
|
47
|
+
|
|
48
|
+
`engines.ts` used to require contributors from the *leading region* before it
|
|
49
|
+
would release a tier. A Chinese query therefore waited for both AnySearch and
|
|
50
|
+
CN Bing even when a global primary had already supplied useful rows. It now
|
|
51
|
+
counts contributors across regions and releases when:
|
|
52
|
+
|
|
53
|
+
- the result budget is filled, and
|
|
54
|
+
- at least two independent engines contributed.
|
|
55
|
+
|
|
56
|
+
`wait: 'all'` still waits for every engine; `wait: 'fast'` still returns the
|
|
57
|
+
first answer. This follows the practical lesson from
|
|
58
|
+
[The Tail at Scale](https://dl.acm.org/doi/10.1145/2408776.2408794): for an
|
|
59
|
+
interactive request, do not make the response wait for every replica or
|
|
60
|
+
partition when a useful answer is already available. It is early termination,
|
|
61
|
+
not full hedged requests, and the distinction is deliberate: a second copy of a
|
|
62
|
+
scraped request would add load and may trigger more bot checks.
|
|
63
|
+
|
|
64
|
+
The interactive deadlines are now 5 s for Latin-script queries and 3 s for CJK
|
|
65
|
+
queries. That is a hard product decision: the plugin may return fewer rows on a
|
|
66
|
+
pathological query rather than let one slow engine define the tail.
|
|
67
|
+
|
|
68
|
+
### Official release facts
|
|
69
|
+
|
|
70
|
+
A generic search query is not a reliable way to find a version-specific release
|
|
71
|
+
announcement. `official-sources.ts` now starts a narrow lookup in parallel with
|
|
72
|
+
the ordinary fan-out:
|
|
73
|
+
|
|
74
|
+
- **PostgreSQL**: the official versioning page (existing path).
|
|
75
|
+
- **Rust**: the GitHub release endpoint gives the UTC publication date; the
|
|
76
|
+
canonical official URL is then
|
|
77
|
+
`https://blog.rust-lang.org/YYYY/MM/DD/Rust-X.Y.Z/`.
|
|
78
|
+
- **Scoped npm packages**: an explicitly `npm`-scoped query uses the existing
|
|
79
|
+
npm vertical and puts the package page first.
|
|
80
|
+
|
|
81
|
+
The lookup is capped at 2.5 s and failure is contained: if the official source
|
|
82
|
+
is unavailable, the ordinary rows remain. The Rust GitHub endpoint is tried
|
|
83
|
+
directly first because measurement showed the direct request was much faster
|
|
84
|
+
than the tunnel for this API, with the tunnel kept as fallback.
|
|
85
|
+
|
|
86
|
+
For `Rust 1.90 发布说明`, the official row is now
|
|
87
|
+
`https://blog.rust-lang.org/2025/09/18/Rust-1.90.0/` at rank 1 rather than the
|
|
88
|
+
Rust home page or a third-party changelog.
|
|
89
|
+
|
|
90
|
+
### Firecrawl is still a fallback, not a primary
|
|
91
|
+
|
|
92
|
+
Nothing in a client can manufacture keyless Firecrawl quota. The honest fix is:
|
|
93
|
+
|
|
94
|
+
- keep Firecrawl in the fallback tier;
|
|
95
|
+
- let the existing health tracker cool it down after `429`/blocks;
|
|
96
|
+
- support an optional `firecrawlApiKey` / `FIRECRAWL_API_KEY` for users who
|
|
97
|
+
need repeatable fallback behavior;
|
|
98
|
+
- record keyless quota failures in the public comparison instead of hiding
|
|
99
|
+
them.
|
|
100
|
+
|
|
101
|
+
The keyless arm is suitable for a one-off check, not for a 30-query sweep
|
|
102
|
+
repeated three times.
|
|
103
|
+
|
|
104
|
+
## 3. Measurements
|
|
105
|
+
|
|
106
|
+
### Five Chinese release queries
|
|
107
|
+
|
|
108
|
+
The original clean sweep ran these at the 3.5 s auto deadline. All five reported
|
|
109
|
+
`anysearch: still running at deadline`; four hit the expected official domain.
|
|
110
|
+
|
|
111
|
+
A controlled rerun of the same five queries after this change:
|
|
112
|
+
|
|
113
|
+
| Query | Before | After | Official after |
|
|
114
|
+
| --- | ---: | ---: | --- |
|
|
115
|
+
| Node.js 24 发布说明 | 3502 ms | 3012 ms | yes |
|
|
116
|
+
| PostgreSQL 18 发布说明 | 3504 ms | 3002 ms | yes |
|
|
117
|
+
| React 19 发布说明 | 3503 ms | 3003 ms | yes |
|
|
118
|
+
| Python 3.14 发布说明 | 3506 ms | 2978 ms | yes |
|
|
119
|
+
| Rust 1.90 发布说明 | 3502 ms | 2565 ms | yes |
|
|
120
|
+
|
|
121
|
+
All five now hit the expected official host. AnySearch still appears as a
|
|
122
|
+
deadline failure on a few runs; that is the `wait` budget doing its job, not a
|
|
123
|
+
blocking wait. The user-visible tail is capped at about 3 s for these queries.
|
|
124
|
+
|
|
125
|
+
### Full 30-query follow-ups
|
|
126
|
+
|
|
127
|
+
Plugin-only runs with the official lookups enabled produced:
|
|
128
|
+
|
|
129
|
+
| Metric | Original clean sweep | 0.22.0 follow-up | 0.23.0 follow-up |
|
|
130
|
+
| --- | ---: | ---: | ---: |
|
|
131
|
+
| Answered | 30/30 | 30/30 | 30/30 |
|
|
132
|
+
| Official-domain hit | 28/30 | 29/30 | 30/30 |
|
|
133
|
+
| Mean unique domains | 5.83 | 5.67 | 5.47 |
|
|
134
|
+
| Mean latency | 3008 ms | 3768 ms | 2263 ms |
|
|
135
|
+
| p50 | 2791 ms | 4000 ms | 2112 ms |
|
|
136
|
+
| p95 | 5188 ms | 5003 ms | 2997 ms |
|
|
137
|
+
|
|
138
|
+
The 0.22.0 follow-up's mean got **worse** than the original clean sweep: it
|
|
139
|
+
ran under more variable upstream latency, and the new official lookup adds work
|
|
140
|
+
to release queries. The 0.23.0 run is faster, but part of that is a better
|
|
141
|
+
network window, not only code; the honest claim is that it fixes the arXiv
|
|
142
|
+
official miss and the survey ranking, not that every query is now faster.
|
|
143
|
+
|
|
144
|
+
The 0.23.0 run's mean unique domains is slightly lower because the explicitly
|
|
145
|
+
routed arXiv query now returns eight arXiv rows instead of eight unrelated
|
|
146
|
+
domains. That is the intended trade for a research query. Raw data:
|
|
147
|
+
[`results-2026-10-26-plugin-after.json`](https://github.com/fangchenghao/dsh-web-search/blob/main/bench/compare30/results-2026-10-26-plugin-after.json)
|
|
148
|
+
(0.22.0) and
|
|
149
|
+
[`results-2026-10-26-plugin-arxiv.json`](https://github.com/fangchenghao/dsh-web-search/blob/main/bench/compare30/results-2026-10-26-plugin-arxiv.json)
|
|
150
|
+
(0.23.0).
|
|
151
|
+
|
|
152
|
+
### arXiv follow-up
|
|
153
|
+
|
|
154
|
+
The arXiv benchmark query used to fail not because the arXiv API was down but
|
|
155
|
+
because the query was never routed there: the ordinary fan-out returned
|
|
156
|
+
dictionary and encyclopedia pages for the word "retrieval". The 0.23.0 run
|
|
157
|
+
routes explicit arXiv paper/survey queries to the arXiv Atom API, uses boolean
|
|
158
|
+
terms (`all:"retrieval augmented generation" AND all:survey`), and ranks the
|
|
159
|
+
first survey at position 1. Fetching was separately broken: the abstract page
|
|
160
|
+
was erased by a `div.flex-wrap-footer` wrapper, and `/pdf/` links were rejected
|
|
161
|
+
as binary. Both are fixed; PDF links now read arXiv's HTML full-text view.
|
|
162
|
+
|
|
163
|
+
The five-query table is the targeted result for the reported Chinese tail; the
|
|
164
|
+
30-query table is the honest full-run result.
|
|
165
|
+
|
|
166
|
+
## 4. Do we need a vector database?
|
|
167
|
+
|
|
168
|
+
No, not to fix these issues. A vector database would help exploratory semantic
|
|
169
|
+
queries, but it would add an indexing pipeline, embedding model, freshness
|
|
170
|
+
policy and a new hosting cost. It would also make the keyless promise harder:
|
|
171
|
+
the current project can run without an API key and without owning a crawl.
|
|
172
|
+
|
|
173
|
+
What is worth borrowing from the retrieval literature:
|
|
174
|
+
|
|
175
|
+
- **HNSW** shows how a graph index makes approximate nearest-neighbour search
|
|
176
|
+
logarithmic in practice; it is one low-latency option Exa does not claim to
|
|
177
|
+
use: [Malkov & Yashunin](https://doi.org/10.1109/TPAMI.2018.2889473).
|
|
178
|
+
- **ColBERT** shows that late interaction can preserve quality while reducing
|
|
179
|
+
the amount of expensive query-document interaction:
|
|
180
|
+
[Khattab & Zaharia](https://doi.org/10.1145/3397271.3401075).
|
|
181
|
+
- **Matryoshka representation learning** is directly relevant to Exa's
|
|
182
|
+
truncated-embedding approach:
|
|
183
|
+
[Kusupati et al.](https://arxiv.org/abs/2205.13147).
|
|
184
|
+
- **The Tail at Scale** is the basis for not waiting for every fan-out leg:
|
|
185
|
+
[Dean & Barroso](https://dl.acm.org/doi/10.1145/2408776.2408794).
|
|
186
|
+
|
|
187
|
+
The plugin deliberately does **not** claim to be a semantic search engine. Its
|
|
188
|
+
advantage is keyless, multi-source coverage and explicit failure reporting; its
|
|
189
|
+
cost is that it cannot match a single-index provider's tail latency on every
|
|
190
|
+
query.
|
|
191
|
+
|
|
192
|
+
## 5. What remains
|
|
193
|
+
|
|
194
|
+
- AnySearch can still be the slow leg. The 3 s CJK budget bounds the damage,
|
|
195
|
+
but a query may return fewer than eight rows from the remaining engines.
|
|
196
|
+
- Keyless Firecrawl can still return `429` immediately; use a key if you need
|
|
197
|
+
repeatability, or treat it as a fallback only.
|
|
198
|
+
- Exa remains faster in the clean sweep. The public comparison should continue
|
|
199
|
+
to say so.
|
package/docs/store-evidence.md
CHANGED
|
@@ -23,7 +23,7 @@ Only `0.2.1-rc.2` is declared, because that is the version actually exercised.
|
|
|
23
23
|
## Environment
|
|
24
24
|
|
|
25
25
|
- macOS (arm64), DeepSeek Harness **0.2.1-rc.2** (`dsh --version`), Node 22.18+.
|
|
26
|
-
- Runtime artifacts: `lib/` is committed to this repository (
|
|
26
|
+
- Runtime artifacts: `lib/` is committed to this repository (86 files, 952 KiB),
|
|
27
27
|
so the fixed commit's tree contains `lib/index.js` and `lib/index.d.ts`.
|
|
28
28
|
- Disposable profile for the destructive steps: a fresh `DSH_HOME` created with
|
|
29
29
|
`mktemp -d`; the real `~/.dsh` was never written to. Bundled pnpm 11.28.5.
|
|
@@ -0,0 +1,40 @@
|
|
|
1
|
+
/**
|
|
2
|
+
* Recognize arXiv page URLs and map PDF requests to the HTML full-text view.
|
|
3
|
+
*
|
|
4
|
+
* arXiv serves the same paper as `/abs/<id>` (metadata and abstract),
|
|
5
|
+
* `/html/<id>` (full text) and `/pdf/<id>` (binary PDF). This plugin converts
|
|
6
|
+
* HTML and text to Markdown but deliberately does not pretend binary PDF bytes
|
|
7
|
+
* are prose, so a PDF link is read through the HTML view instead.
|
|
8
|
+
*
|
|
9
|
+
* @module @fangchenghao/dsh-web-search/arxiv-url
|
|
10
|
+
*/
|
|
11
|
+
/** One recognized arXiv URL. */
|
|
12
|
+
export interface ArxivUrl {
|
|
13
|
+
/** Canonical identifier, including an old-style archive prefix. */
|
|
14
|
+
id: string;
|
|
15
|
+
/** Page kind in the original URL. */
|
|
16
|
+
kind: 'abs' | 'html' | 'pdf';
|
|
17
|
+
/** Version suffix, when the URL named one. */
|
|
18
|
+
version?: string;
|
|
19
|
+
}
|
|
20
|
+
/**
|
|
21
|
+
* Parse an arXiv abs/html/pdf URL.
|
|
22
|
+
*
|
|
23
|
+
* @param url - any URL string.
|
|
24
|
+
* @returns the identifier and kind, or `undefined` for other hosts.
|
|
25
|
+
*/
|
|
26
|
+
export declare function parseArxivUrl(url: string): ArxivUrl | undefined;
|
|
27
|
+
/**
|
|
28
|
+
* The HTML full-text URL for a paper.
|
|
29
|
+
*
|
|
30
|
+
* @param reference - parsed arXiv URL.
|
|
31
|
+
* @returns an `https://arxiv.org/html/...` URL.
|
|
32
|
+
*/
|
|
33
|
+
export declare function arxivHtmlUrl(reference: ArxivUrl): string;
|
|
34
|
+
/**
|
|
35
|
+
* Map a PDF URL to the HTML view; leave other URLs alone.
|
|
36
|
+
*
|
|
37
|
+
* @param url - the caller's URL.
|
|
38
|
+
* @returns the URL the fetch ladder should read.
|
|
39
|
+
*/
|
|
40
|
+
export declare function arxivReadableUrl(url: string): string;
|