@fffangchenghao/dsh-web-search 0.19.3 → 0.20.0
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/CHANGELOG.md +150 -0
- package/README.md +194 -33
- package/README.zh-CN.md +171 -34
- package/SECURITY.md +42 -7
- package/client.js +131 -9
- package/docs/store-evidence.md +10 -5
- package/lib/advanced-search.d.ts +107 -0
- package/lib/advanced-search.js +255 -0
- package/lib/bridge.d.ts +16 -0
- package/lib/bridge.js +160 -0
- package/lib/cache.d.ts +11 -4
- package/lib/cache.js +9 -5
- package/lib/config.d.ts +19 -3
- package/lib/config.js +24 -0
- package/lib/domain-tool.d.ts +5 -0
- package/lib/domain-tool.js +45 -6
- package/lib/engine-test.d.ts +116 -0
- package/lib/engine-test.js +256 -0
- package/lib/engines.d.ts +11 -1
- package/lib/engines.js +118 -19
- package/lib/errors.d.ts +16 -2
- package/lib/errors.js +40 -1
- package/lib/index.d.ts +24 -2
- package/lib/index.js +304 -20
- package/lib/inject.d.ts +43 -0
- package/lib/inject.js +1 -0
- package/lib/markdown.js +18 -1
- package/lib/mirrors.d.ts +23 -0
- package/lib/mirrors.js +69 -0
- package/lib/official-feed.d.ts +114 -0
- package/lib/official-feed.js +288 -0
- package/lib/official-support.d.ts +74 -0
- package/lib/official-support.js +134 -0
- package/lib/platform-tool.d.ts +77 -0
- package/lib/platform-tool.js +173 -0
- package/lib/platforms.d.ts +178 -0
- package/lib/platforms.js +1035 -0
- package/lib/query-router.d.ts +29 -0
- package/lib/query-router.js +58 -0
- package/lib/read-page.js +2 -1
- package/lib/research-cache.d.ts +115 -0
- package/lib/research-cache.js +275 -0
- package/lib/research.d.ts +45 -4
- package/lib/research.js +505 -22
- package/lib/search-many.d.ts +7 -1
- package/lib/search-many.js +7 -2
- package/lib/system-prompt.d.ts +27 -0
- package/lib/system-prompt.js +50 -0
- package/lib/tool-suite.d.ts +97 -0
- package/lib/tool-suite.js +224 -0
- package/lib/transport.d.ts +33 -2
- package/lib/transport.js +42 -9
- package/lib/types.d.ts +20 -0
- package/lib/types.js +9 -1
- package/lib/untrusted.d.ts +33 -0
- package/lib/untrusted.js +42 -0
- package/lib/verticals.d.ts +3 -1
- package/lib/verticals.js +26 -7
- package/package.json +5 -3
- package/skills/dsh-web-search/SKILL.md +21 -6
package/CHANGELOG.md
CHANGED
|
@@ -1,5 +1,155 @@
|
|
|
1
1
|
# Changelog
|
|
2
2
|
|
|
3
|
+
## 0.20.0
|
|
4
|
+
|
|
5
|
+
### Added
|
|
6
|
+
- **One `web_tools` action surface.** The eight optional capabilities are now
|
|
7
|
+
one model-facing tool with `action` set to `search_many`, `advanced_search`,
|
|
8
|
+
`domain_search`, `platform_search`, `read_page`, `research`, `cache_search`
|
|
9
|
+
or `engine_test`. This cuts the always-visible optional surface from eight
|
|
10
|
+
names to one while keeping each handler's validation and rendering; the old
|
|
11
|
+
names remain available with `toolSurface: legacy`. The real DSH registry
|
|
12
|
+
accepts the unified schema (see `scripts/verify-tool-registration.mjs`).
|
|
13
|
+
- **Auto-update compatibility.** The package is documented and installed as an
|
|
14
|
+
npm bundle so the profile-level `dsh-autoupdater` manages it; `link:`/`file:`
|
|
15
|
+
checkouts are intentionally excluded by that updater. The Settings card shows
|
|
16
|
+
the latest npm version and the running build; the plugin never hot-swaps its
|
|
17
|
+
own loaded code. The desktop profile is switched to the npm install after
|
|
18
|
+
0.20.0 is published.
|
|
19
|
+
- **`advanced_search` uses the official Chrome Releases feed for a windowed
|
|
20
|
+
Chrome security/release query.** The feed carries the real post date that a
|
|
21
|
+
search snippet often loses; the result note states how many posts fell inside
|
|
22
|
+
the window and whether any title or summary mentions zero-day. A feed miss
|
|
23
|
+
falls back to the previous engine path.
|
|
24
|
+
- **`search_many` routes explicit package-registry queries.** A query that names
|
|
25
|
+
npm, PyPI or crates.io is answered from that existing domain source (one exact
|
|
26
|
+
lookup per extracted package name) and falls back to ordinary web results if
|
|
27
|
+
the registry returns nothing.
|
|
28
|
+
- **`platform_search`: community and video sources.** A new model tool queries
|
|
29
|
+
Bilibili, V2EX, Reddit, YouTube, Zhihu and Juejin. It uses each site's keyless
|
|
30
|
+
public endpoint where one exists and falls back to `site:<domain> <query>`
|
|
31
|
+
through the normal search path. Fallback rows are filtered to the platform
|
|
32
|
+
host (and aliases such as `b23.tv`, `youtu.be`, `redd.it`), so a generic page
|
|
33
|
+
cannot become a platform result; one blocked platform does not empty the
|
|
34
|
+
batch. Zhihu has no usable keyless API and is therefore fallback-only.
|
|
35
|
+
- **`cache_search`: a second retrieval over `research` bodies.** `research` now
|
|
36
|
+
fetches up to 200,000 characters per page and stores the full body in an
|
|
37
|
+
in-process cache through an optional `onPage` sink. `cache_search` searches
|
|
38
|
+
those bodies (24 pages, 400,000 characters each, 7-day TTL) and returns the
|
|
39
|
+
matching passages with the same URLs, without another network request. The
|
|
40
|
+
first excerpt is query-aware too: instead of only the opening 6,000
|
|
41
|
+
characters, it scores paragraph windows against the query and keeps the best
|
|
42
|
+
windows plus opening context.
|
|
43
|
+
- **Official-source query expansion is focused, not generic.** When the first
|
|
44
|
+
result set lacks a known issuer, `research` spends an unused query slot on a
|
|
45
|
+
focused `site:` query for the EU AI Act, Chinese CAC, Chrome Releases, Python,
|
|
46
|
+
Redis or WCAG, filters the rows to that issuer's domain, and never promotes a
|
|
47
|
+
landing/home page on authority alone. W3C WCAG pages that return 403 are
|
|
48
|
+
retried through `w3c.github.io`.
|
|
49
|
+
- **`advanced_search` drops a redundant relative-time phrase.** When the caller
|
|
50
|
+
passes an explicit window, a `过去 7 天内` / `last 7 days` fragment is removed
|
|
51
|
+
from the engine query but kept in the returned `query`; the structured window
|
|
52
|
+
already carries that constraint.
|
|
53
|
+
- **`domain_search` accepts `timeRange`.** `off`/`day`/`week`/`month`/`year`
|
|
54
|
+
filters parsed publication dates for that call; undated rows survive only
|
|
55
|
+
when no dated row qualifies, with a `note` explaining the outcome. arXiv
|
|
56
|
+
switches to `submittedDate` order and a quoted phrase when a window is set,
|
|
57
|
+
so "last month" returns recent papers rather than old relevance matches.
|
|
58
|
+
- **Chrome Stable filtering and security summary.** A Stable-only Chrome query now removes Beta, Dev, Early Stable and Extended Stable posts from the official feed; its snippets preview the version, fix count and listed Critical/High/Medium/Low CVE counts when the post states them. An empty Stable result falls back to the ordinary engine path.
|
|
59
|
+
|
|
60
|
+
- **Bilibili rows carry play counts, a topic gate, recency/popularity controls and an alternate endpoint.** Rows show `UP主`, play count and duration when the API returns them; adjacent topics are dropped; queries that explicitly ask for recency or high play apply a bounded date filter and play-count sort; and `/search/all/v2` is tried when `/search/type` is blocked with 412. Juejin rows also surface `点赞`/`阅读`, sort by likes for a `高赞` query, and Zhihu fallback drops a broad unrelated question when at least two specific answers remain.
|
|
61
|
+
|
|
62
|
+
- **PostgreSQL version/EOL questions use the official support table.** A PostgreSQL query that asks about the current version, support or EOL now prepends the project's official versioning row (current major/minor, first release and final release/EOL), while ordinary PostgreSQL how-to queries keep the normal engine path.
|
|
63
|
+
- **A clause/date AI Act question gets the official Article 113 page.** `research` adds the Article 113 page directly for a question that asks when a GPAI obligation applies or which article governs it, so a Chinese-language question does not depend on the English page winning a search ranking. The page is fetched through the normal ladder and its operative date windows are excerpted.
|
|
64
|
+
- **Legal article excerpts target the operative clause.** Research excerpts now keep standalone article numbers and pick the late clause that combines an operative verb with a date, so an EU AI Act Article 113 pack shows `2 August 2025` instead of only the table-of-contents links.
|
|
65
|
+
- **Longer, date-aware research excerpts.** `research` now keeps up to 1,800 characters per page and preserves the final window when a regulation query asks when a rule takes effect, so the effective-date article is not crowded out by definitions.
|
|
66
|
+
|
|
67
|
+
- **Ecosystem comparison refreshed.** The README now carries a 2026-10-25 snapshot with GitHub stars, last-month npm downloads, test evidence and package size for the main DSH competitors; stale claims about tool counts, store status and test leadership were removed.
|
|
68
|
+
|
|
69
|
+
**Test suite: 655 tests across 49 files** (654 pass, 1 skipped). The new
|
|
70
|
+
unified-tool, platform, cache, mirror and landing-page tests are included.
|
|
71
|
+
- **`engine_test`: one probe per engine, with a reason.** A new model tool tests
|
|
72
|
+
one engine or all eight, bypasses the cache and never changes cooldown state,
|
|
73
|
+
and returns `ok`, latency, result count, and a failure class (`quota`, `auth`,
|
|
74
|
+
`bot-wall`, `transient`, `invalid-response`, `unknown`). The Settings page's
|
|
75
|
+
**Test engines** button calls the same runner through a loopback-only
|
|
76
|
+
`POST /api/dsh-web-search/engine-test` bridge, so a person can see which
|
|
77
|
+
engine is slow or blocked without reading a failure log.
|
|
78
|
+
- **`fallbackOn` and a result `Note`.** A primary failure now carries a
|
|
79
|
+
structured `FailureKind`; the fallback tier runs only for the classes enabled
|
|
80
|
+
in `fallbackOn`. The default keeps every class enabled, so the old
|
|
81
|
+
always-fall-back behaviour is unchanged. When policy skips or uses the
|
|
82
|
+
fallback, the result says so in a short `note` (also rendered by
|
|
83
|
+
`search_many`).
|
|
84
|
+
- **`blockedDomains`.** A comma-separated blocklist applied to merged and cached
|
|
85
|
+
results; a subdomain matches its parent. Empty by default, so it cannot change
|
|
86
|
+
existing searches.
|
|
87
|
+
- **`safeSearch`.** `off` (default, engine default), `moderate` or `strict`.
|
|
88
|
+
Forwarded as `adlt` to Bing and `kp` to DuckDuckGo; other engines are left
|
|
89
|
+
untouched.
|
|
90
|
+
- **`advanced_search`: a per-call date window.** One query can ask for `day`,
|
|
91
|
+
`week`, `month` or `year` without changing the global Settings value; `off`
|
|
92
|
+
disables the window for that call and omitting it keeps the setting. It shares
|
|
93
|
+
the engine, cache, cooldown and failure path with `web_search`, and falls back
|
|
94
|
+
to `web_search_advanced` if the name is taken.
|
|
95
|
+
- **An explicit untrusted-content boundary.** Every plugin-owned tool wraps its
|
|
96
|
+
web-derived render in `<untrusted-web-content>...</untrusted-web-content>`,
|
|
97
|
+
strips forged boundary tags from the payload, and a short `systemPrompt`
|
|
98
|
+
section tells the model those contents are data, not instructions. The host's
|
|
99
|
+
own `web_search`/`web_fetch` notice is left in place.
|
|
100
|
+
|
|
101
|
+
### Changed
|
|
102
|
+
- **`research` now prefers authoritative sources on equal relevance.** A new
|
|
103
|
+
authority signal recognises government/academic TLDs, standards bodies and
|
|
104
|
+
well-known official documentation hosts, and uses documentation/legal/release
|
|
105
|
+
paths as a small boost. A credible official page that matches the query leads
|
|
106
|
+
the pack even when a generic page repeats more query words; relevance still
|
|
107
|
+
gates out official pages that match none of it. The signal is structural, not
|
|
108
|
+
a query-specific allowlist. Three regression tests.
|
|
109
|
+
- The retry-policy code now records HTTP `status` on failures and classifies
|
|
110
|
+
them, but cooldown timing and retryability are unchanged.
|
|
111
|
+
- Cache keys include a non-default `safeSearch`, a non-default `fallbackOn`
|
|
112
|
+
and a non-empty `blockedDomains`; the default paths keep their old keys, and
|
|
113
|
+
removing a block cannot reuse a filtered entry.
|
|
114
|
+
|
|
115
|
+
### Fixed
|
|
116
|
+
- **`research` rejects bot challenges and login redirects.** A challenge page can
|
|
117
|
+
be well over the 160-character floor (Anubis/Cloudflare shells, for example),
|
|
118
|
+
and a redirect can still carry a readable login URL. Both are now reported as
|
|
119
|
+
failed pages with a reason, instead of being quoted as evidence. Two
|
|
120
|
+
regression tests.
|
|
121
|
+
- **npm publish dates are publish dates.** `domain_search` read the npm search
|
|
122
|
+
index's `updated` field, which moves when the index refreshes; it now reads
|
|
123
|
+
`package.date`, the version's actual publish time, and keeps an undated
|
|
124
|
+
package undated instead of inventing a date. One regression test.
|
|
125
|
+
- **`advanced_search` says when a window is not proven.** If a caller asks for
|
|
126
|
+
`day`/`week`/`month`/`year` and some results have no publication date, the
|
|
127
|
+
result carries a note naming the count, instead of letting undated rows look
|
|
128
|
+
like they passed the filter. One regression test.
|
|
129
|
+
- **Domain rows are readable and carry the metadata the API already returns.**
|
|
130
|
+
Stack Exchange entities (`->`, `'`) are decoded; Hacker News rows show
|
|
131
|
+
points and comment counts; GitHub rows show the SPDX license and stars; PyPI
|
|
132
|
+
rows show `Requires-Python`. These are presentation-only additions on the
|
|
133
|
+
existing `Source` shape.
|
|
134
|
+
- **`research` rejects shells and boilerplate instead of citing them.** A fetch
|
|
135
|
+
that comes back as a raw HTML document, or as fewer than 160 characters of
|
|
136
|
+
text, is now reported as a failed page with a reason rather than quoted as
|
|
137
|
+
evidence. Two regression tests.
|
|
138
|
+
- **Long RFC-style pages keep the document, not one appendix.** The reading-root
|
|
139
|
+
heuristics could pick a code-heavy ABNF appendix (RFC 9110 returned only the
|
|
140
|
+
collected ABNF) or one dense section of a long document with no
|
|
141
|
+
`<article>`/`<main>`. A code-dominated container is now skipped, and a single
|
|
142
|
+
section is trusted only when it holds at least half the page's text. Two
|
|
143
|
+
regression tests; live RFC 9110 now converts to 603,506 characters of
|
|
144
|
+
document text instead of an ABNF-only excerpt.
|
|
145
|
+
|
|
146
|
+
### Verification
|
|
147
|
+
- 579 tests / 41 files (578 pass, 1 skip); `npm run typecheck` clean.
|
|
148
|
+
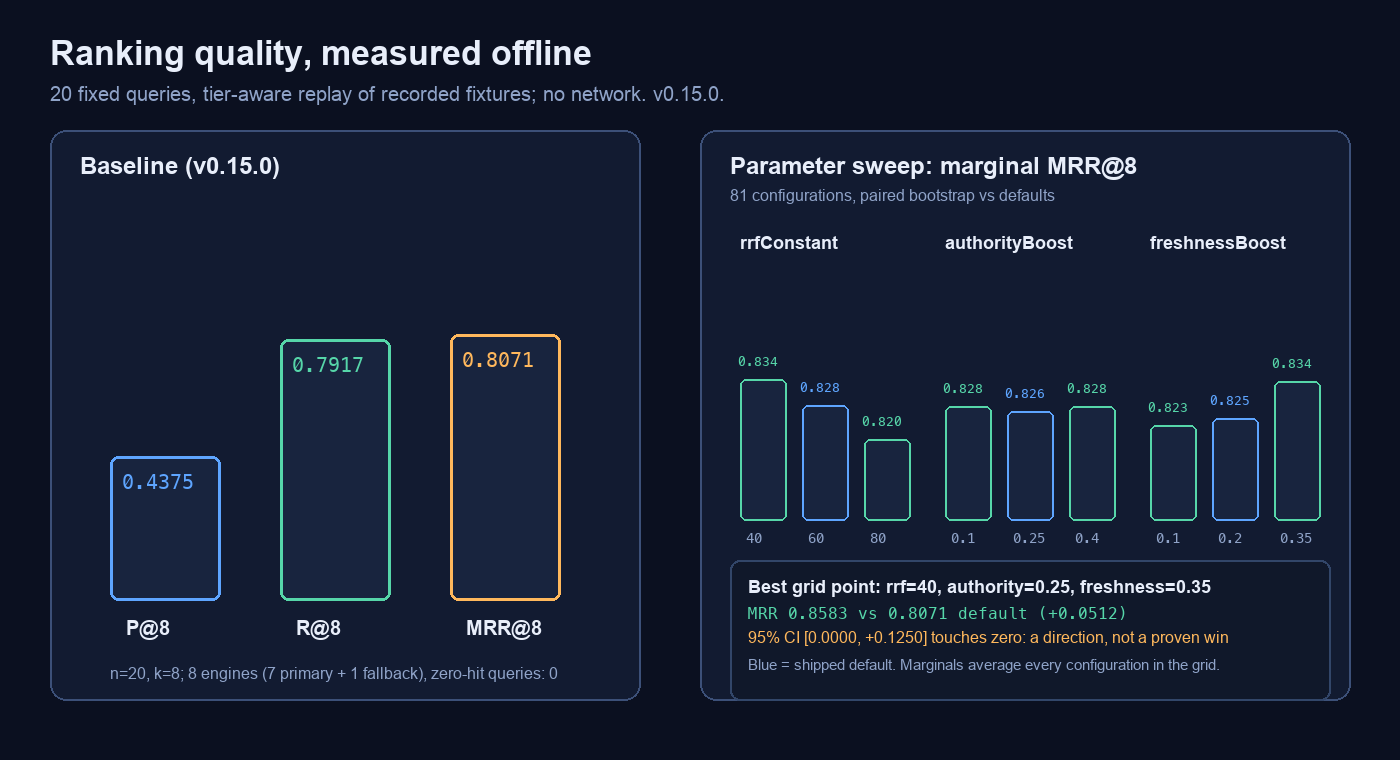
- Replay bench unchanged: 20 queries P@8 `0.4375`, R@8 `0.7917`, MRR@8
|
|
149
|
+
`0.8071`; long corpus `0.4500 / 1.0000 / 0.7667`.
|
|
150
|
+
- No publish yet: the version is bumped for the prepared package, not pushed to
|
|
151
|
+
npm.
|
|
152
|
+
|
|
3
153
|
## 0.19.3
|
|
4
154
|
|
|
5
155
|
### Fixed
|
package/README.md
CHANGED
|
@@ -9,7 +9,7 @@
|
|
|
9
9
|
|
|
10
10
|
<p align="center">
|
|
11
11
|
<a href="https://www.npmjs.com/package/@fffangchenghao/dsh-web-search"><img src="https://img.shields.io/npm/v/@fffangchenghao/dsh-web-search.svg" alt="npm version"></a>
|
|
12
|
-
<img src="https://img.shields.io/badge/tests-
|
|
12
|
+
<img src="https://img.shields.io/badge/tests-655%20passing-brightgreen" alt="tests">
|
|
13
13
|
<img src="https://img.shields.io/badge/engines-8%2C%20zero%20API%20key-brightgreen" alt="engines">
|
|
14
14
|
<img src="https://img.shields.io/badge/node-%3E%3D22.18-blue" alt="node">
|
|
15
15
|
<img src="https://img.shields.io/badge/dsh-%3E%3D0.2.1--rc.2%20%3C0.3.0-blueviolet" alt="dsh">
|
|
@@ -19,9 +19,9 @@
|
|
|
19
19
|
## Why this one
|
|
20
20
|
|
|
21
21
|
- **No API key, eight engines.** AnySearch, CN Bing, DuckDuckGo HTML, www Bing, DuckDuckGo Lite and 360 Search are scraped directly; Exa joins the primary tier through its keyless MCP endpoint, and Firecrawl's search API is the measured fallback. The plugin works out of the box.
|
|
22
|
-
- **The ranking is measured, not asserted.** Cross-engine reciprocal-rank fusion with authority and freshness boosts, a 20-query offline benchmark, and an 81-configuration parameter sweep — the
|
|
22
|
+
- **The ranking is measured, not asserted.** Cross-engine reciprocal-rank fusion with authority and freshness boosts, a 20-query offline benchmark, and an 81-configuration parameter sweep — one of the few search plugins here that publishes its metric, per-query output and confidence intervals. See [How the ranking works](docs/rrf-ranking.md).
|
|
23
23
|
- **Fetching admits failure.** Binary documents and empty 200 responses are rejected by name (`SEARCH_UNSUPPORTED`, `SEARCH_EMPTY`) instead of being returned as noise; the direct → tunnel → render → extract ladder shares one 25 s budget and stops when there is no time left. The budget is per request — there is a regression test for exactly that.
|
|
24
|
-
- **
|
|
24
|
+
- **655 tests across 49 files**, a committed `lib/`, declared `engines.dsh` / `engines.node`, and a [SECURITY.md](SECURITY.md) that lists every process, host and file the plugin touches.
|
|
25
25
|
- **Bilingual documentation.** This README and [中文说明](README.zh-CN.md) are maintained side by side.
|
|
26
26
|
|
|
27
27
|
|
|
@@ -30,24 +30,51 @@ The benchmark is offline and deterministic: 20 recorded queries, precision/recal
|
|
|
30
30
|
|
|
31
31
|
## Where it stands
|
|
32
32
|
|
|
33
|
-
The web-search corner of the DSH plugin ecosystem is crowded
|
|
34
|
-
|
|
35
|
-
|
|
36
|
-
|
|
37
|
-
|
|
38
|
-
|
|
|
39
|
-
|
|
|
40
|
-
|
|
|
41
|
-
|
|
|
42
|
-
|
|
|
43
|
-
|
|
44
|
-
|
|
33
|
+
The web-search corner of the DSH plugin ecosystem is crowded. A fresh snapshot
|
|
34
|
+
(2026-10-25; stars and npm downloads are adoption signals, not quality scores):
|
|
35
|
+
|
|
36
|
+
| | this plugin | [dsh-free-search](https://github.com/DDDMUC/dsh-free-search) | [dsh-web-search-pro](https://github.com/anweat/dsh-web-search-pro) | [modsearch](https://github.com/liustack/modsearch) | [anysearch-dsh](https://github.com/anysearch-team/anysearch-dsh) |
|
|
37
|
+
|---|---|---|---|---|---|
|
|
38
|
+
| Key-free path | 8 engines, all key-free | ~30-engine free/paid chain | 5 defaults (seam, Exa, DDG, Bing, Jina) | Firecrawl + Keenable keyless defaults | 1 anonymous AnySearch API |
|
|
39
|
+
| Dedicated vertical sources | 34 (8 on by default) | 41 | platform registry, not a vertical catalog | web + X, no vertical catalog | vertical API behind AnySearch |
|
|
40
|
+
| Model-facing tools | 1 (`web_tools`, 8 actions) | ~10 | 2 (`web_index` / `web_call`, 20 actions) | native search/fetch + skill | 5 |
|
|
41
|
+
| Tests | 49 files / 655 cases, locally verified | no test script in `package.json` | 774 unit + 94 bench, self-reported | Vitest configured; count not published | Vitest configured; count not published |
|
|
42
|
+
| GitHub stars | 0 | 620 | 77 | 836 | 663 |
|
|
43
|
+
| npm downloads, last month | 1,087 | 52,436 | 6,420 | 43,151 | 9,251 |
|
|
44
|
+
| npm unpacked size | 0.81 MB | 0.70 MB | 3.05 MB | 0.51 MB | 0.27 MB |
|
|
45
|
+
|
|
46
|
+
This is a capability snapshot, not a league table with one winner. The honest
|
|
47
|
+
read is:
|
|
48
|
+
|
|
49
|
+
- **Feature depth:** upper-middle. `dsh-free-search` has more engines and
|
|
50
|
+
verticals; `dsh-web-search-pro` has a deeper evidence/ranking pipeline and far
|
|
51
|
+
more platform backends; `modsearch` is the stronger cross-host bridge.
|
|
52
|
+
- **Engineering and verification:** near the top. 655 local tests, a replayable
|
|
53
|
+
ranking benchmark, declared security boundaries and one runtime dependency
|
|
54
|
+
put it alongside the best-maintained entries, while remaining much smaller
|
|
55
|
+
than the Playwright-heavy option.
|
|
56
|
+
- **Key-free + official-source correctness:** its strongest niche. The official
|
|
57
|
+
Chrome, PostgreSQL and AI Act paths and the 34-source vertical layer are not
|
|
58
|
+
common in the other plugins.
|
|
59
|
+
- **Adoption and maturity:** bottom third of this sample. The public npm release
|
|
60
|
+
is 0.19.3; the 0.20.0 tree described here is newer and unpublished, and the
|
|
61
|
+
GitHub repository is four days old with no stars.
|
|
62
|
+
- **Tool-surface economy:** now competitive. 0.20.0 exposes one `web_tools`
|
|
63
|
+
entry with eight actions, close to `dsh-web-search-pro`'s two tools with 20
|
|
64
|
+
actions; the legacy eight-name surface remains opt-in for old prompts.
|
|
65
|
+
|
|
66
|
+
If you need maximum install base and engine breadth, start with
|
|
67
|
+
`dsh-free-search` or `modsearch`. If you need the deepest evidence/scoring
|
|
68
|
+
pipeline and browser-backed platforms, look at `dsh-web-search-pro`. This plugin
|
|
69
|
+
is the compact, fully key-free option for search plus vertical lookup, research
|
|
70
|
+
packs and official-source correction. It is not the most popular, and it should
|
|
71
|
+
not claim to be the largest.
|
|
45
72
|
|
|
46
73
|
> The latest version and install command live on [npm](https://www.npmjs.com/package/@fffangchenghao/dsh-web-search); no version number is hard-coded here, so the docs cannot drift from the release. What follows starts with what this means for you; the technical detail is collected in the appendix.
|
|
47
74
|
|
|
48
75
|
## In one sentence
|
|
49
76
|
|
|
50
|
-
With this plugin installed, you can ask something like "how do I configure the version released last week?" and the model can call `web_search` against public search engines by itself, then work from a ranked list of titles, links and snippets. When a snippet is not enough, it can call `web_fetch` on one of those links and get the page back as clean Markdown instead of a wall of HTML. When one question needs several separate searches, it can call `search_many` and get each query's results separately. When the question is about an npm package, a GitHub repository, a paper or a Q&A thread, it can call `domain_search` instead and ask those dedicated sources directly. And when a page is too long to read in one pass, it can call `read_page` and continue from where the last chunk stopped.
|
|
77
|
+
With this plugin installed, you can ask something like "how do I configure the version released last week?" and the model can call `web_search` against public search engines by itself, then work from a ranked list of titles, links and snippets. When a snippet is not enough, it can call `web_fetch` on one of those links and get the page back as clean Markdown instead of a wall of HTML. When one question needs several separate searches, it can call `search_many` and get each query's results separately. When the question is about an npm package, a GitHub repository, a paper or a Q&A thread, it can call `domain_search` instead and ask those dedicated sources directly. When it needs a forum, community or video site, it can call `platform_search` for Bilibili, V2EX, Reddit, YouTube, Zhihu or Juejin. A PostgreSQL version/EOL question also gets the project's official support-table row prepended, rather than trusting a stale press kit. And when a page is too long to read in one pass, it can call `read_page` and continue from where the last chunk stopped.
|
|
51
78
|
|
|
52
79
|
Three things change for you:
|
|
53
80
|
|
|
@@ -55,7 +82,7 @@ Three things change for you:
|
|
|
55
82
|
- When a question is about a package, a repository or a paper, the model can ask the matching source directly instead of hoping a web search understands.
|
|
56
83
|
- You do not need a search API key, and you do not pay for search separately.
|
|
57
84
|
|
|
58
|
-
Under the hood it is one sentence too: the plugin registers two providers with the harness's `web` service — `bing` for search and `http-proxy` for fetching pages — and
|
|
85
|
+
Under the hood it is one sentence too: the plugin registers two providers with the harness's `web` service — `bing` for search and `http-proxy` for fetching pages — and one model-facing `web_tools` action tool: `action: "domain_search"` for packages, repositories, papers, Q&A and reference entries; `search_many` for several searches in one call; `advanced_search` for one query with a per-call date window; `read_page` for walking a long page in chunks; `research` for turning a few searches into one cited evidence pack; `platform_search` for community and video sites; `cache_search` for searching the full texts research already fetched; and `engine_test` for checking which engine is healthy. These are eight capabilities of one plugin, behind one tool registration — not eight separate plugins or eight always-visible tools.
|
|
59
86
|
|
|
60
87
|
## The problem it solves
|
|
61
88
|
|
|
@@ -152,7 +179,7 @@ Analogy: `web_search` is asking passers-by where the hardware shop is and gettin
|
|
|
152
179
|
|
|
153
180
|
They team up well: use `domain_search` to find the package or paper, then `web_fetch` to open its homepage or README and read the detail.
|
|
154
181
|
|
|
155
|
-
|
|
182
|
+
Four more helpers sit beside them: **`search_many`**, **`advanced_search`**, **`read_page`** and **`research`**. When one question needs several distinct searches — one per candidate library, say — `search_many` runs one to five queries in a single call and keeps each query's results apart, so one failed query cannot empty the batch; when only one question needs a date window, `advanced_search` applies it for that call alone; when a page is too long for one fetch, `read_page` continues from where the previous chunk stopped; and when snippets are not enough but the model still has to decide which page to trust, `research` searches up to three queries, opens the leading pages and returns one evidence pack with a citation under every excerpt.
|
|
156
183
|
|
|
157
184
|
### Reading a long page in chunks (read_page): when one pass is not enough
|
|
158
185
|
|
|
@@ -250,7 +277,7 @@ Each line is the plain version first, the technical note second. The technical n
|
|
|
250
277
|
|
|
251
278
|
7. **Repeating a question does not repeat the work.**
|
|
252
279
|
The same query within ten minutes is answered from the previous run, almost instantly.
|
|
253
|
-
*Technical: TTL + LRU cache, `cacheTtlMs: 600000` (ten minutes) and `cacheEntries: 100`; the key is `lead|wait|limit|sorted engine ids|time window|normalised query`, where the window only appears when it is not `off
|
|
280
|
+
*Technical: TTL + LRU cache, `cacheTtlMs: 600000` (ten minutes) and `cacheEntries: 100`; the key is `lead|wait|limit|sorted engine ids|time window|policy fields|normalised query`, where the window only appears when it is not `off` and the policy fields only when they are non-default, so an ordinary search keeps its old cache behaviour.*
|
|
254
281
|
|
|
255
282
|
8. **A throttled engine takes a rest.**
|
|
256
283
|
If one engine serves a verification page, it is skipped for a few minutes while the rest keep working.
|
|
@@ -277,8 +304,8 @@ Each line is the plain version first, the technical note second. The technical n
|
|
|
277
304
|
*Technical: proxy sources in order — the `proxy` setting, then `DSH_WEB_SEARCH_PROXY` / `HTTPS_PROXY` / `ALL_PROXY` / `HTTP_PROXY`, then macOS `scutil --proxy`; HTTP proxies only (`CONNECT`), not `socks5://`.*
|
|
278
305
|
|
|
279
306
|
14. **Every setting is editable in the UI.**
|
|
280
|
-
Twenty-
|
|
281
|
-
*Technical: all twenty-
|
|
307
|
+
Twenty-nine controls in five groups; a save takes effect on the next search, apart from `cachePersist` and `cacheFile`, which decide the cache wiring at mount.
|
|
308
|
+
*Technical: all twenty-nine fields carry `.volatile()`, so the Host commits them in place instead of remounting the plugin; `cacheTtlMs` and `cacheEntries` are re-read per use, `fetchFormat` and `fetchMaxLength` are resolved per request, `renderJs` and `renderTimeoutMs` per fetch; `proxy` and `timeoutMs` are taken at mount, and so is the cache wiring that `cachePersist` and `cacheFile` decide.*
|
|
282
309
|
|
|
283
310
|
15. **Failures are explained, not silently empty.**
|
|
284
311
|
When nothing succeeds, the error lists which engines were tried and why each one failed.
|
|
@@ -290,15 +317,15 @@ Each line is the plain version first, the technical note second. The technical n
|
|
|
290
317
|
|
|
291
318
|
17. **Packages, repositories, papers and Q&A are one hop away.**
|
|
292
319
|
For "is this npm package still maintained?" or "is there a paper on RAG?", the model can call `domain_search` against 34 dedicated sources instead of hoping a web search finds them.
|
|
293
|
-
*Technical: 34 keyless sources, eight on by default — `github`, `npm`, `pypi`, `arxiv`, `wikipedia`, `hn` (Hacker News), `stackexchange`, `crates` (crates.io); the other 26 are reachable through `sources`. Arguments `query` (required), `sources` (optional array, default = the default eight), `limit` (optional, default 5, capped at 20). Each source has its own deadline (8000 ms by default), one failure never affects the others, and the failed names come back in `failures`. Measured with `react` at limit 3: github 3, npm 3, pypi 1, arxiv 3, wikipedia 3, hn 3, stackexchange 3, crates 3. Known limits: PyPI has no public search API, so it matches the **exact package name** taken from the first word of the query; Wikipedia searches one language only (`zh` for CJK, otherwise `en`). A host without `ctx.tools` does not register the tool and the rest of the plugin works as usual.*
|
|
320
|
+
*Technical: 34 keyless sources, eight on by default — `github`, `npm`, `pypi`, `arxiv`, `wikipedia`, `hn` (Hacker News), `stackexchange`, `crates` (crates.io); the other 26 are reachable through `sources`. Arguments `query` (required), `sources` (optional array, default = the default eight), `limit` (optional, default 5, capped at 20), and `timeRange` (optional `off`/`day`/`week`/`month`/`year`; undated rows survive only when no dated row qualifies, with a `note`). With a window, the arXiv adapter asks for `submittedDate` order and quotes the phrase before the local date filter. Each source has its own deadline (8000 ms by default), one failure never affects the others, and the failed names come back in `failures`. Measured with `react` at limit 3: github 3, npm 3, pypi 1, arxiv 3, wikipedia 3, hn 3, stackexchange 3, crates 3. Known limits: PyPI has no public search API, so it matches the **exact package name** taken from the first word of the query; Wikipedia searches one language only (`zh` for CJK, otherwise `en`). A host without `ctx.tools` does not register the tool and the rest of the plugin works as usual.*
|
|
294
321
|
|
|
295
322
|
18. **You can look only at recently published results.**
|
|
296
323
|
Choose "last 24 hours / 7 days / 30 days / 1 year" in Settings and only results inside that window stay — useful for news and releases.
|
|
297
|
-
*Technical: `timeRange` takes `off` (default) / `day` / `week` / `month` / `year` — 24 hours, 7 days, 30 days, 1 year. Publication dates are parsed from each engine's results (Bing's snippet date and `news_dt`, 360's `发贴时间`, DuckDuckGo's timestamp and snippet, AnySearch's `date:` trailer). DuckDuckGo receives the window as `df=d/w/m/y`; Bing's and 360's parameters were measured to have no effect (the page shows the option selected while the results stay the same), so those two and AnySearch filter locally. With a window on, only **dated** results inside it are kept; only when not one dated result falls inside does the undated list come back, so the answer is never empty for that reason alone.*
|
|
324
|
+
*Technical: `timeRange` takes `off` (default) / `day` / `week` / `month` / `year` — 24 hours, 7 days, 30 days, 1 year. Publication dates are parsed from each engine's results (Bing's snippet date and `news_dt`, 360's `发贴时间`, DuckDuckGo's timestamp and snippet, AnySearch's `date:` trailer). DuckDuckGo receives the window as `df=d/w/m/y`; Bing's and 360's parameters were measured to have no effect (the page shows the option selected while the results stay the same), so those two and AnySearch filter locally. With a window on, only **dated** results inside it are kept; only when not one dated result falls inside does the undated list come back, so the answer is never empty for that reason alone. This Settings window is global; `advanced_search` can override it for one model call (see below).*
|
|
298
325
|
|
|
299
326
|
19. **Several questions, one call.**
|
|
300
327
|
For "compare these three libraries", the model can hand `search_many` one to five queries and get each query's results back separately; up to three run at once, and one failed query does not take the others down.
|
|
301
|
-
*Technical: `queries` (1–5, required), `limit` (default 5, 1–20), `withSites` (default false; true attaches each result's hostname). `SEARCH_MANY_CONCURRENCY = 3`. Each query goes through the same engine layer, cache and cooldown tracker as `web_search`; a thrown search becomes that query's `failures` entry, never the batch's. Use `search_many` for several questions at once, `web_search` for one, `domain_search` for packages, papers or Q&A. The tool's deadline is 30 s and it is concurrency-safe. It registers as `web_search_many` if the name is taken, and is not registered at all when the host has no `ctx.tools`.*
|
|
328
|
+
*Technical: `queries` (1–5, required), `limit` (default 5, 1–20), `withSites` (default false; true attaches each result's hostname). `SEARCH_MANY_CONCURRENCY = 3`. Each query goes through the same engine layer, cache and cooldown tracker as `web_search`; a thrown search becomes that query's `failures` entry, never the batch's. A query that explicitly names npm, PyPI or crates.io is routed to that package registry; it falls back to the ordinary path if the registry returns nothing. Use `search_many` for several questions at once, `web_search` for one, `domain_search` for packages, papers or Q&A. The tool's deadline is 30 s and it is concurrency-safe. It registers as `web_search_many` if the name is taken, and is not registered at all when the host has no `ctx.tools`.*
|
|
302
329
|
|
|
303
330
|
20. **The cache survives a restart.**
|
|
304
331
|
Ask the same question again after restarting DSH within ten minutes and the previous result is still there; nothing is sent to the engines.
|
|
@@ -309,11 +336,123 @@ Each line is the plain version first, the technical note second. The technical n
|
|
|
309
336
|
*Technical: `bench/` holds 20 queries (10 Chinese, 10 English), five in each of docs / release / package / news, each annotated with 1–3 expected domains. `node scripts/bench.mjs` replays recorded fixtures offline, never touches the network, and prints precision@8, recall@8, MRR@8 plus each engine's contribution; `--record` re-records live (1.5 s between queries) to refresh the fixtures; `--json` gives machine-readable output for version comparisons, and past results live in `bench/results/`. Baseline for 0.15.0 (tier-aware replay, so the recorded fallback engines only count when production would run them): P@8 `0.4375`, R@8 `0.7917`, MRR@8 `0.8071`; Chinese `0.4000 / 0.8167 / 0.7976`, English `0.4750 / 0.7667 / 0.8167`. A separate five-query long-Chinese diagnostic (`bench/queries-long.json`, recorded with `--queries ... --fixtures ...`) scores `0.4500 / 1.0000 / 0.7667`, with every query hitting an expected domain; it is kept separate so the 20-query baseline stays comparable. The controlled experiments and known gaps are in the appendix.*
|
|
310
337
|
|
|
311
338
|
22. **Research, in one call.**
|
|
312
|
-
For "what do the official docs and two other sources actually say about X", `research` runs up to three searches, opens the leading pages through the same fetch ladder, and returns one evidence pack in which every excerpt sits under its URL. A page that will not load is reported by URL and reason instead of aborting the pack.
|
|
313
|
-
*Technical: `query` (required), `queries` (up to three extra), `maxSources` (1–5, default 3); one 45 s budget for the whole call, three page fetches in flight, and a page fetch is not started with less than 2.5 s left.
|
|
339
|
+
For "what do the official docs and two other sources actually say about X", `research` runs up to three searches, opens the leading pages through the same fetch ladder, and returns one evidence pack in which every excerpt sits under its URL. A page that will not load is reported by URL and reason instead of aborting the pack; bot challenges and login redirects are rejected rather than quoted as evidence.
|
|
340
|
+
*Technical: `query` (required), `queries` (up to three extra), `maxSources` (1–5, default 3); one 45 s budget for the whole call, three page fetches in flight, and a page fetch is not started with less than 2.5 s left. A credible government, academic, standards-body or well-known official documentation page that matches the query leads the pack; a landing/home page is never promoted by authority alone, and relevance still excludes unrelated official pages. Up to the remaining query slots (three in total) can be spent on a focused official `site:` query (EU/europa, Chinese CAC, Chrome Releases, Python, Redis, W3C), with results filtered to the issuer's domain. The fetch side reads up to 200,000 characters so the excerpt selector can find a fact deep in the page; it uses its own `http-proxy-research` provider and does not disturb the host `web_fetch` renderer cache. W3C WCAG pages that return 403 are retried once through `w3c.github.io`; the body comes from that official mirror and the citation names the canonical W3C page. The search side is the same `web_search` path, cache and cooling included. The tool registers as `web_research` if another plugin owns `research`.*
|
|
341
|
+
|
|
342
|
+
### Community and video platforms
|
|
343
|
+
|
|
344
|
+
`platform_search` is the forum/video counterpart to `domain_search`. It asks
|
|
345
|
+
Bilibili, V2EX, Reddit, YouTube, Zhihu and Juejin directly through keyless
|
|
346
|
+
public endpoints where one exists, and falls back to a `site:<domain>` search
|
|
347
|
+
when the endpoint is blocked or has changed. One platform failing does not
|
|
348
|
+
empty the answer; the result names the platform, the URL, the snippet and a
|
|
349
|
+
date when one is available. Fallback rows are filtered to the platform's own
|
|
350
|
+
domain, so a generic page cannot masquerade as a platform result. Bilibili retries `/search/all/v2` when `/search/type` answers 412, applies recency and play-count sorting only when the query asks for them, and Juejin rows expose like/read counts when the API provides them.
|
|
351
|
+
|
|
352
|
+
*Technical: `query` (required), `platforms` (optional subset of `bilibili`,
|
|
353
|
+
`v2ex`, `reddit`, `youtube`, `zhihu`, `juejin`; omitted = all six), `limit`
|
|
354
|
+
(1–10, default 5). Direct requests use a browser UA and the configured proxy;
|
|
355
|
+
falls back to `site:<domain> <query>` through the normal search path. Each
|
|
356
|
+
platform has an 8 s direct deadline, the tool has a 40 s budget, results are
|
|
357
|
+
de-duplicated and interleaved by rank. It registers as
|
|
358
|
+
`web_platform_search` if the name is taken. Zhihu has no usable keyless search
|
|
359
|
+
endpoint, so it is fallback-only; if the fallback is blocked as well, it is
|
|
360
|
+
reported as a platform failure rather than silently omitted.*
|
|
361
|
+
|
|
362
|
+
### A second retrieval over research bodies
|
|
363
|
+
|
|
364
|
+
`research` fetches full pages but only puts selected passages into the evidence
|
|
365
|
+
pack. `cache_search` searches those full texts again, in-process, without a
|
|
366
|
+
second network request. This is useful when a first answer needs an exact
|
|
367
|
+
number, quote or section: ask `cache_search` for the detail and it returns the
|
|
368
|
+
matching passages with the same source URLs. The cache holds at most 24 bodies,
|
|
369
|
+
400,000 characters each, expires after seven days and is cleared when the plugin
|
|
370
|
+
unloads; it never writes page bodies to disk.
|
|
371
|
+
|
|
372
|
+
The first retrieval is also query-aware: the excerpt is not simply the first
|
|
373
|
+
6,000 characters. Research splits the fetched body into windows, scores them
|
|
374
|
+
against the query terms and keeps the best windows plus enough opening context
|
|
375
|
+
to make the excerpt intelligible. This is deterministic and makes no model
|
|
376
|
+
call.
|
|
377
|
+
|
|
378
|
+
*Technical: `cache_search` takes `query` and optional `limit` (1–10, default 3);
|
|
379
|
+
it returns `matches` with `url`, `title`, `snippet`, `score` and `fetchedAt`.
|
|
380
|
+
The cache is in-memory only; a restart is a clean slate. `research` fetches up
|
|
381
|
+
to 200,000 characters per page for this second pass and stores the full body
|
|
382
|
+
via an optional `onPage` sink.*
|
|
383
|
+
|
|
384
|
+
23. **You can test the engines without guessing.**
|
|
385
|
+
A model tool and a Settings button both run one tiny query through each engine and report which answered, how fast, and why the rest did not. It is diagnostics only: no cache entry, no cooldown, no fallback.
|
|
386
|
+
*Technical: `engine_test` takes optional `engine` and `query`, tests one engine or all eight (three in flight), and returns per-engine `ok`, `latencyMs`, `count`, `failureKind`, `code`, `status` and `reason`. The Settings button posts to a loopback-only `POST /api/dsh-web-search/engine-test` bridge, which shares the same runner. The endpoint refuses non-POST, non-loopback and cross-origin callers; it is registered only when the host exposes an injectable `webServer`, so a headless deployment simply has no button.*
|
|
387
|
+
|
|
388
|
+
24. **A failure carries a class, and the fallback is a policy.**
|
|
389
|
+
"Blocked", "out of quota" and "temporarily slow" used to produce the same fallback; now each primary failure is classified, and you can decide which classes may switch to a backup engine. When a fallback is skipped or used, the result says so.
|
|
390
|
+
*Technical: `FailureKind` is `quota` / `auth` / `bot-wall` / `transient` / `invalid-response` / `unknown`, derived from the existing `SearchError` code plus HTTP status and message clues. `fallbackOn` defaults to all six, preserving the old always-fall-back behaviour; an empty list means never. `SearchOutcome.failureDetails` exposes the class, code and status, and `note` explains a skipped or used fallback (also rendered by `search_many`). Cooldown timing is unchanged.*
|
|
391
|
+
|
|
392
|
+
25. **A site can be blocked, and safe search can be forwarded.**
|
|
393
|
+
Put a domain on the blocklist and it disappears from merged and cached results; choose a safe-search level and Bing and DuckDuckGo receive it.
|
|
394
|
+
*Technical: `blockedDomains` is a comma-separated suffix list (a subdomain matches its parent), applied after fusion and to cache hits; empty by default. `safeSearch` is `off` (leave the engine's own default), `moderate` or `strict`, forwarded as Bing `adlt` and DuckDuckGo `kp`; other engines are untouched. A non-empty blocklist and a non-default safe-search level join the cache key, so removing a block cannot reuse a filtered entry, while the default path keeps its old keys.*
|
|
395
|
+
|
|
396
|
+
26. **A date window is available per call, not only as a setting.**
|
|
397
|
+
When only one question needs fresh results — "what changed this week?" — the model can call `advanced_search` and ask for `day`, `week`, `month` or `year` without changing the global setting. Omitting the window keeps the Settings value; `off` disables it for that one query.
|
|
398
|
+
*Technical: `advanced_search` takes `query` (required), `maxResults` (default 5, capped at 20 and by the deployment's `limit`), and `timeRange` (`off` / `day` / `week` / `month` / `year`; omitted = Settings). It shares the engine, cache, cooldown and failure path with `web_search`, so an `off` call can reuse an ordinary cache entry and a `week` call gets its own key. With an explicit window it removes a redundant `过去 7 天内` / `last 7 days` phrase from the engine query (the structured window already carries it) while returning the original query in the result. For a windowed Chrome security/release query, it reads the official Chrome Releases feed and returns the feed's real publication dates plus a note saying whether any title or summary mentions zero-day; a Stable-only query filters out Beta/Dev/Early Stable/Extended Stable posts, and each post snippet previews the version, fix count and listed CVE severity distribution when the post states them. A feed miss or an empty Stable filter falls back to the ordinary engine path. It registers as `web_search_advanced` if the name is taken, and is not registered at all when the host has no `ctx.tools`.*
|
|
399
|
+
|
|
400
|
+
27. **Web text is explicitly marked as untrusted.**
|
|
401
|
+
Every custom tool now wraps its web-derived body in `<untrusted-web-content>...</untrusted-web-content>`, strips forged copies of the markers from the payload, and a short system-prompt section tells the model that the contents are data, not instructions.
|
|
402
|
+
*Technical: the wrapper is applied to `domain_search`, `search_many`, `advanced_search`, `read_page`, `research` and `engine_test` renders. The boundary tags are removed from page text (including whitespace/attribute variants) before wrapping, so a page cannot close the boundary early. The host's own `web_search`/`web_fetch` external-content notice is left in place; the plugin does not duplicate it or mutate `Source` objects that DSH also renders in result cards. The prompt section is installed through an optional `systemPrompt` injection and is absent on hosts without that service.*
|
|
314
403
|
|
|
315
404
|
> **What 0.13.0 fixes (a real defect)**: from some networks 360 (`so`) returns a verification page — a 302 to the qcaptcha "unexpected access" page — while the HTTP status is still 200. The old code read that as "zero results" and swallowed it: the engine effectively disappeared and its cooldown never fired. Such pages now fail as `SEARCH_BLOCKED`, and 360 has been demoted to the **fallback tier** (tried only when the primary engines are empty), so it no longer slows every search. Measured: querying that engine alone now returns the failure `so: bot verification page` instead of zero results.
|
|
316
405
|
|
|
406
|
+
## Tool surface: one entry point, eight actions
|
|
407
|
+
|
|
408
|
+
0.20.0 changes the model-facing surface. The eight capabilities above are now
|
|
409
|
+
actions on one `web_tools` tool instead of eight separate registrations. A call
|
|
410
|
+
looks like:
|
|
411
|
+
|
|
412
|
+
```json
|
|
413
|
+
{ "action": "domain_search", "query": "react", "sources": ["github"] }
|
|
414
|
+
```
|
|
415
|
+
|
|
416
|
+
The host's own `web_search` and `web_fetch` stay as they were. This keeps the
|
|
417
|
+
common path unchanged while cutting the optional tool surface from eight names
|
|
418
|
+
to one.
|
|
419
|
+
|
|
420
|
+
Older prompts that call `domain_search`, `search_many`, `research` and the rest
|
|
421
|
+
directly can opt back into the old names in the plugin config:
|
|
422
|
+
|
|
423
|
+
```yaml
|
|
424
|
+
- id: web-search-bing
|
|
425
|
+
name: '@fffangchenghao/dsh-web-search'
|
|
426
|
+
config:
|
|
427
|
+
toolSurface: legacy
|
|
428
|
+
```
|
|
429
|
+
|
|
430
|
+
`unified` is the default and is recommended. Changing the mode requires a
|
|
431
|
+
plugin reload because the registry is built at mount time. The sections below
|
|
432
|
+
still use the action names as labels; read them as `web_tools` actions unless
|
|
433
|
+
you explicitly chose `legacy`.
|
|
434
|
+
|
|
435
|
+
## Automatic updates
|
|
436
|
+
|
|
437
|
+
The plugin is a DSH bundle and does **not** replace its own running code: Node
|
|
438
|
+
has already loaded `lib/index.js`, and swapping files underneath it is not a
|
|
439
|
+
safe update mechanism. Automatic updates belong to the profile-level updater.
|
|
440
|
+
|
|
441
|
+
Use an npm install, not a `link:`/local checkout:
|
|
442
|
+
|
|
443
|
+
```sh
|
|
444
|
+
dsh plugin --profile web add @fffangchenghao/dsh-web-search@latest
|
|
445
|
+
```
|
|
446
|
+
|
|
447
|
+
Then keep [`dsh-autoupdater`](https://github.com/raomaiping-hash/dsh-self-upgrade)
|
|
448
|
+
or your own profile updater enabled. The updater checks the npm dist-tag,
|
|
449
|
+
updates in an idle window, and asks for a restart on desktop. `link:` and
|
|
450
|
+
`file:` installs are deliberately skipped by such updaters because replacing a
|
|
451
|
+
local checkout with the registry package would destroy the checkout.
|
|
452
|
+
|
|
453
|
+
The Settings card always shows the latest npm version and whether it differs
|
|
454
|
+
from the running build; that check is read-only and never installs anything.
|
|
455
|
+
|
|
317
456
|
## Installing and enabling it
|
|
318
457
|
|
|
319
458
|
### What you need
|
|
@@ -323,6 +462,17 @@ Each line is the plain version first, the technical note second. The technical n
|
|
|
323
462
|
- Ordinary outbound network access. A tunnel is not required — you just get fewer engines without one.
|
|
324
463
|
- Optional: to read pages whose body is built by JavaScript, install Playwright yourself (item 12 above); not installing it changes nothing else.
|
|
325
464
|
|
|
465
|
+
### Production install (auto-updatable)
|
|
466
|
+
|
|
467
|
+
For a normal user install, add the published package to the profile. Do not use
|
|
468
|
+
a `link:` if you want the profile updater to manage it:
|
|
469
|
+
|
|
470
|
+
```sh
|
|
471
|
+
dsh plugin --profile web add @fffangchenghao/dsh-web-search@latest
|
|
472
|
+
```
|
|
473
|
+
|
|
474
|
+
The rest of this section is the source-checkout development path.
|
|
475
|
+
|
|
326
476
|
### Step 1: build
|
|
327
477
|
|
|
328
478
|
`main` points at `lib/index.js`, and `lib/` is **committed** — DSH STORE scans the fixed Git tree, so the runtime artifacts have to live in the repository — which means a fresh checkout runs as-is. Rebuild only after changing `src/`:
|
|
@@ -417,17 +567,17 @@ If the Settings card appears but search still fails, start with [docs/troublesho
|
|
|
417
567
|
|
|
418
568
|
## Using the Settings page
|
|
419
569
|
|
|
420
|
-
Open Settings → "Web search (Bing)". Twenty-
|
|
570
|
+
Open Settings → "Web search (Bing)". Twenty-nine controls, arranged in five groups, plus an **Engine health** check. A sticky jump bar at the top scrolls to any group, and a line under the title compares the installed version with the latest one on npm (it stays hidden when the registry cannot be reached, so it never guesses). Each group owns one kind of decision:
|
|
421
571
|
|
|
422
572
|
| Group | Controls | What it decides |
|
|
423
573
|
| --- | --- | --- |
|
|
424
|
-
| Engines and transport |
|
|
574
|
+
| Engines and transport | 9 | Which engines run, how long to wait, whether to use a proxy, AnySearch credentials and vertical domain, blocked sites, safe search and fallback policy |
|
|
425
575
|
| Results and ranking | 7 | How many results, how far back to look, how they merge and sort, how much official docs and fresh content count |
|
|
426
576
|
| Dedicated search | 3 | Which sources `domain_search` queries, results per source, deadline per source |
|
|
427
577
|
| Fetching | 4 | What `web_fetch` returns — Markdown or plain text, how many characters, whether a browser may render a shell, and how long that render may take |
|
|
428
578
|
| Cache and cooldowns | 6 | How long results are remembered, how many, whether the cache is saved to disk, and how long a throttled engine rests |
|
|
429
579
|
|
|
430
|
-
### Engines and transport (
|
|
580
|
+
### Engines and transport (9)
|
|
431
581
|
|
|
432
582
|
| Control | Key | Default | Plain meaning |
|
|
433
583
|
| --- | --- | --- | --- |
|
|
@@ -437,13 +587,16 @@ Open Settings → "Web search (Bing)". Twenty-six controls, arranged in five gro
|
|
|
437
587
|
| Proxy (relay) | `proxy` | empty (detect) | e.g. `http://127.0.0.1:7890`; empty reads the environment, then the system proxy |
|
|
438
588
|
| AnySearch key | `anysearchApiKey` | empty (anonymous) | Optional. Sent only to `api.anysearch.com`; raises limits and unlocks page extraction. Several keys may be comma-separated and are rotated, with a throttled or rejected one resting automatically |
|
|
439
589
|
| Vertical domain | `anysearchDomain` | empty (general) | Typical values: `finance` / `academic` / `security` / `legal` / `code`; a dotted value such as `finance.us_stock` selects a sub-domain |
|
|
590
|
+
| Blocked sites | `blockedDomains` | empty (nothing) | Domains that must never appear, comma-separated; a subdomain matches its parent. Applied after fusion and on a cache hit, so a blocked row cannot come back from the cache |
|
|
591
|
+
| Safe search | `safeSearch` | `off` | `off` keeps each engine's default; `moderate` or `strict` is forwarded to Bing (`adlt`) and DuckDuckGo (`kp`). Other engines ignore it |
|
|
592
|
+
| Fallback on | `fallbackOn` | all six classes | Failure classes that may switch to a fallback engine: `quota`, `auth`, `bot-wall`, `transient`, `invalid-response`, `unknown`. Empty means never fall back; a skipped fallback is explained in the result's `note` |
|
|
440
593
|
|
|
441
594
|
### Results and ranking (7)
|
|
442
595
|
|
|
443
596
|
| Control | Key | Default | Plain meaning |
|
|
444
597
|
| --- | --- | --- | --- |
|
|
445
598
|
| Results per search | `limit` | `8` | How many results at most, 1–20; a smaller caller budget still wins |
|
|
446
|
-
| Date window | `timeRange` | `off` | `off` disables it; `day` 24 hours, `week` 7 days, `month` 30 days, `year` 1 year. A window keeps only results inside it |
|
|
599
|
+
| Date window | `timeRange` | `off` | `off` disables it; `day` 24 hours, `week` 7 days, `month` 30 days, `year` 1 year. A window keeps only results inside it. `advanced_search` can override it for one query |
|
|
447
600
|
| Result blending | `rrfConstant` | `60` | Larger flattens the curve; smaller favours each engine's own top results |
|
|
448
601
|
| Trusted sites | `authorityDomains` | empty (built-in list) | Extra domains to boost, on top of the built-in official-docs list |
|
|
449
602
|
| Trusted-site boost | `authorityBoost` | `0.25` | Multiplies an authoritative result by `1 + this`, 0–10 |
|
|
@@ -480,7 +633,7 @@ Open Settings → "Web search (Bing)". Twenty-six controls, arranged in five gro
|
|
|
480
633
|
|
|
481
634
|
### My advice
|
|
482
635
|
|
|
483
|
-
**For normal use: leave all twenty-
|
|
636
|
+
**For normal use: leave all twenty-nine alone. The defaults are the tuned values.**
|
|
484
637
|
|
|
485
638
|
Only these situations are worth changing:
|
|
486
639
|
|
|
@@ -859,10 +1012,15 @@ Resolution order: the `proxy` setting → the environment (`DSH_WEB_SEARCH_PROXY
|
|
|
859
1012
|
- **The benchmark is only 20 queries**: news recall is 0.367 and `zh-linux-612` has zero hits; a difference of 1–4 hits cannot separate versions. It shows direction, not statistical significance.
|
|
860
1013
|
- **`search_many` is capped at five queries and three in flight.**
|
|
861
1014
|
- **Two processes sharing one cache file write last-writer-wins**: neither can corrupt the file, but one process's newer snapshot can be replaced by another's older one.
|
|
862
|
-
- **A time window can only filter results that carry a date**: dates are parsed from result pages, so an engine that prints none leaves that row without an age; when nothing dated falls inside the window the undated list comes back. Bing's and 360's time parameters were measured to have no effect; only DuckDuckGo's `df=` is a real pushdown.
|
|
1015
|
+
- **A time window can only filter results that carry a date**: dates are parsed from result pages, so an engine that prints none leaves that row without an age; when nothing dated falls inside the window the undated list comes back, with a `Note` saying the window is not proven for those rows. Bing's and 360's time parameters were measured to have no effect; only DuckDuckGo's `df=` is a real pushdown.
|
|
1016
|
+
- **Domain search is discovery, not a complete record**: GitHub search omits release tags, Wikipedia search omits revision timestamps, Hacker News search omits the top comment, and Stack Overflow search omits accepted-answer text. Follow up with `web_fetch` or `read_page` when the exact record matters.
|
|
863
1017
|
- **PyPI matches exact package names only**: it has no public search API, so the plugin uses the first word of the query; a typo yields an empty answer.
|
|
1018
|
+
- **Community platforms are best-effort.** Bilibili, V2EX, Reddit, YouTube and Juejin change or block their public endpoints; the tool falls back to a domain-scoped web search and filters the rows to the platform host. Zhihu has no usable keyless API in this environment, so it is fallback-only and can still return nothing.
|
|
1019
|
+
- **`cache_search` is in-process.** Research bodies live for at most seven days, 24 pages and 400,000 characters each, and disappear on restart; they are never written to the search-result cache.
|
|
1020
|
+
- **Official-site hints are bounded.** `research` adds a focused `site:` query only for a small set of issuers (EU, CAC, Chrome Releases, Python, Redis, W3C); other official bodies rely on the ordinary ranking.
|
|
1021
|
+
- **A window cannot invent dates.** When all rows are undated, `advanced_search` / `domain_search` say so in the note; they do not label an undated row as in-window.
|
|
864
1022
|
- **Wikipedia searches one language only**: `zh` for CJK queries, `en` otherwise.
|
|
865
|
-
-
|
|
1023
|
+
- **The plugin-owned tools need a host tool registry**: without `ctx.tools`, `domain_search`, `search_many`, `advanced_search`, `read_page`, `research`, `cache_search`, `platform_search` and `engine_test` are not registered, and `web_search` is unaffected.
|
|
866
1024
|
- **Anonymous AnySearch caps at 10 results per call.**
|
|
867
1025
|
- **HTTP proxies only** — no `socks5://`.
|
|
868
1026
|
- **`limit` is capped at 20, and so is `domainLimit`.**
|
|
@@ -873,6 +1031,9 @@ Resolution order: the `proxy` setting → the environment (`DSH_WEB_SEARCH_PROXY
|
|
|
873
1031
|
| --- | --- |
|
|
874
1032
|
| Result budget `limit` | `8` (1–20) |
|
|
875
1033
|
| Time window `timeRange` | `off` (no limit; `day` / `week` / `month` / `year`) |
|
|
1034
|
+
| `domain_search` window | omitted (uses no local filter); `off` / `day` / `week` / `month` / `year` |
|
|
1035
|
+
| `platform_search` limit | `5` (1–10) |
|
|
1036
|
+
| Research body cache | 24 pages, 400,000 characters, 7 days, in memory |
|
|
876
1037
|
| Results per source `domainLimit` | `5` (1–20) |
|
|
877
1038
|
| Per-source deadline `domainTimeoutMs` | `8000` ms |
|
|
878
1039
|
| Cache TTL `cacheTtlMs` | `600000` ms = 600 s |
|