@fffangchenghao/dsh-web-search 0.16.0 → 0.17.0
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/CHANGELOG.md +40 -0
- package/README.md +3 -3
- package/README.zh-CN.md +3 -3
- package/client.js +7 -7
- package/lib/config.js +1 -1
- package/lib/engines.js +5 -0
- package/lib/fetch.d.ts +26 -0
- package/lib/fetch.js +115 -34
- package/lib/markdown.js +10 -1
- package/lib/research.js +114 -35
- package/lib/semaphore.d.ts +45 -0
- package/lib/semaphore.js +100 -0
- package/lib/transport.js +17 -5
- package/lib/types.d.ts +8 -0
- package/package.json +1 -1
package/CHANGELOG.md
CHANGED
|
@@ -1,5 +1,45 @@
|
|
|
1
1
|
# Changelog
|
|
2
2
|
|
|
3
|
+
## 0.17.0
|
|
4
|
+
|
|
5
|
+
### Fixed
|
|
6
|
+
- **Moved documentation URLs now arrive as pages, not redirect stubs.** PyTorch's
|
|
7
|
+
`stable` docs answer an obsolete path with HTTP 200 and a body that only says
|
|
8
|
+
"Redirecting…"; the fetch ladder rendered that stub as if it were the page.
|
|
9
|
+
Both the direct and tunnelled rungs now follow up to two HTML-level redirects
|
|
10
|
+
(`<meta http-equiv="refresh">`, or a redirect-titled page's
|
|
11
|
+
`location.replace`/canonical link) inside the same deadline.
|
|
12
|
+
- **Bursts of searches no longer trip Exa's rate limit.** Five parallel
|
|
13
|
+
`search_many` queries made the anonymous Exa endpoint return 429 on four of
|
|
14
|
+
them. Engines can now declare a process-wide concurrency gate (`exa` and
|
|
15
|
+
`firecrawl` two at a time, `anysearch` two), held for the whole
|
|
16
|
+
direct-then-tunnel attempt and cancelled with the caller.
|
|
17
|
+
- **`research` fills its page quota.** A candidate that failed to load used to
|
|
18
|
+
leave the pack one page short while a later candidate was never tried; workers
|
|
19
|
+
now pull the next candidate until `maxSources` pages succeed. Candidates are
|
|
20
|
+
also ranked by query-token overlap first, so a dictionary entry for the single
|
|
21
|
+
character `东` no longer displaces an article about `东数西算`, and a failed
|
|
22
|
+
URL is no longer listed under "found but not fetched".
|
|
23
|
+
- **Failure reasons are deduplicated**, so a page that fails the same renderer
|
|
24
|
+
check three times no longer repeats the sentence three times in one message.
|
|
25
|
+
- **Markdown no longer carries Sphinx-style permalink noise**: a link whose
|
|
26
|
+
whole text is `¶`, `#` or `§` is dropped, and a link whose text is its own URL
|
|
27
|
+
is emitted as an autolink.
|
|
28
|
+
|
|
29
|
+
### Tests
|
|
30
|
+
- 487 cases (486 pass, one environment skip): new coverage for redirect
|
|
31
|
+
detection and loop bounds, the engine gate, research quota filling and
|
|
32
|
+
relevance ranking, and the cleaned Markdown links.
|
|
33
|
+
|
|
34
|
+
## 0.16.1
|
|
35
|
+
|
|
36
|
+
### Fixed
|
|
37
|
+
- The Settings page never showed which engines exist: the allow-list field now
|
|
38
|
+
names all eight (four primary: `anysearch`, `exa`, `ddg-html`, `cn.bing`;
|
|
39
|
+
four fallback: `firecrawl`, `www.bing`, `ddg-lite`, `so`) and the group label
|
|
40
|
+
says "8 total". The page description now also lists the model-facing tools,
|
|
41
|
+
including `research`, which is a tool rather than a setting.
|
|
42
|
+
|
|
3
43
|
## 0.16.0
|
|
4
44
|
|
|
5
45
|
### Added
|
package/README.md
CHANGED
|
@@ -9,7 +9,7 @@
|
|
|
9
9
|
|
|
10
10
|
<p align="center">
|
|
11
11
|
<a href="https://www.npmjs.com/package/@fffangchenghao/dsh-web-search"><img src="https://img.shields.io/npm/v/@fffangchenghao/dsh-web-search.svg" alt="npm version"></a>
|
|
12
|
-
<img src="https://img.shields.io/badge/tests-
|
|
12
|
+
<img src="https://img.shields.io/badge/tests-486%20passing-brightgreen" alt="tests">
|
|
13
13
|
<img src="https://img.shields.io/badge/engines-8%2C%20zero%20API%20key-brightgreen" alt="engines">
|
|
14
14
|
<img src="https://img.shields.io/badge/node-%3E%3D22.18-blue" alt="node">
|
|
15
15
|
<img src="https://img.shields.io/badge/dsh-%3E%3D0.2.1--rc.2%20%3C0.3.0-blueviolet" alt="dsh">
|
|
@@ -21,7 +21,7 @@
|
|
|
21
21
|
- **No API key, eight engines.** AnySearch, CN Bing, DuckDuckGo HTML, www Bing, DuckDuckGo Lite and 360 Search are scraped directly; Exa joins the primary tier through its keyless MCP endpoint, and Firecrawl's search API is the measured fallback. The plugin works out of the box.
|
|
22
22
|
- **The ranking is measured, not asserted.** Cross-engine reciprocal-rank fusion with authority and freshness boosts, a 20-query offline benchmark, and an 81-configuration parameter sweep — the only search plugin here that publishes both its metric and its confidence intervals. See [How the ranking works](docs/rrf-ranking.md).
|
|
23
23
|
- **Fetching admits failure.** Binary documents and empty 200 responses are rejected by name (`SEARCH_UNSUPPORTED`, `SEARCH_EMPTY`) instead of being returned as noise; the direct → tunnel → render → extract ladder shares one 25 s budget and stops when there is no time left. The budget is per request — there is a regression test for exactly that.
|
|
24
|
-
- **
|
|
24
|
+
- **487 tests across 31 files**, a committed `lib/`, declared `engines.dsh` / `engines.node`, and a [SECURITY.md](SECURITY.md) that lists every process, host and file the plugin touches.
|
|
25
25
|
- **Bilingual documentation.** This README and [中文说明](README.zh-CN.md) are maintained side by side.
|
|
26
26
|
|
|
27
27
|
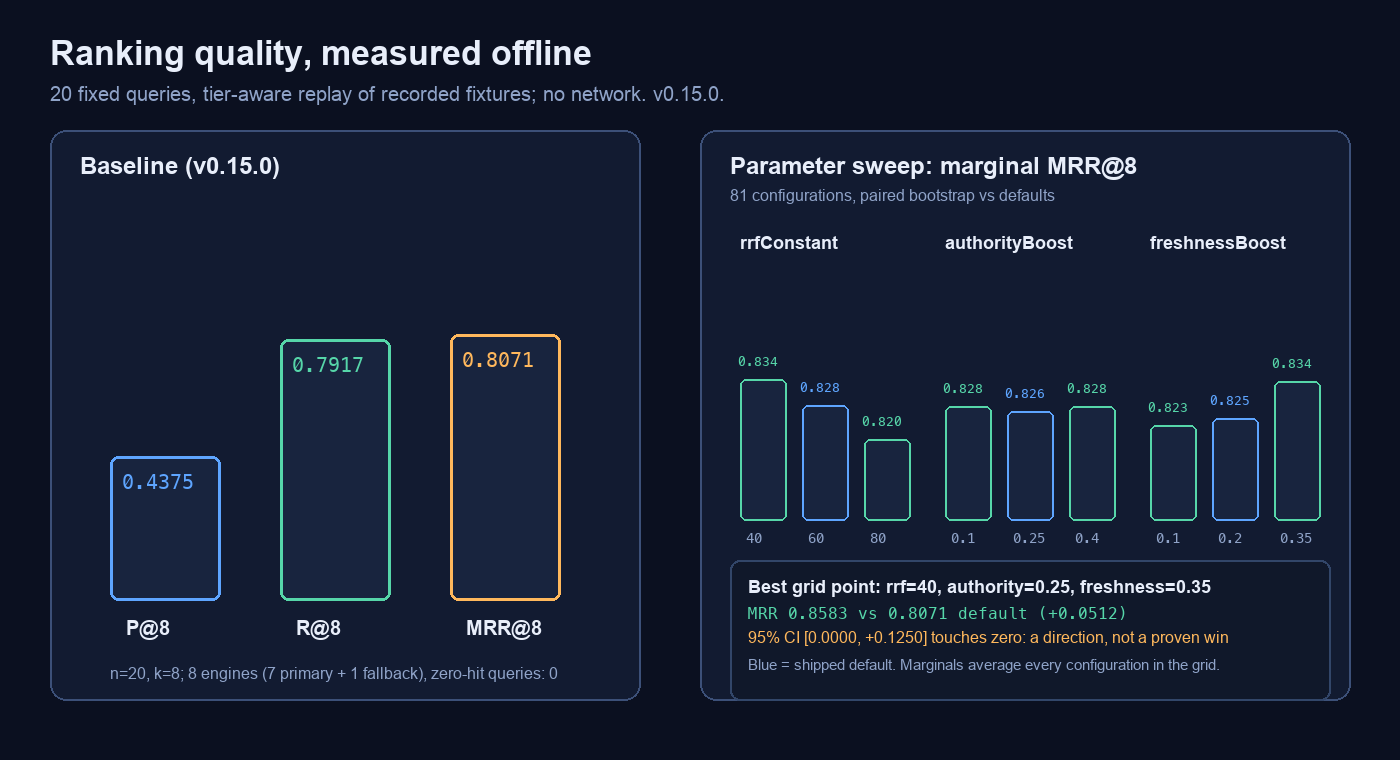
|
|
@@ -37,7 +37,7 @@ The web-search corner of the DSH plugin ecosystem is crowded, and most rivals ar
|
|
|
37
37
|
| Key-free engines | 8 | ~30 | 7 channels (+X) | 1 official API |
|
|
38
38
|
| Dedicated vertical sources | 34 (8 on by default) | 41 | — | — |
|
|
39
39
|
| Model-facing tools | 6 | ~10 | 3 | 5 |
|
|
40
|
-
| Test suite |
|
|
40
|
+
| Test suite | 31 files / 487 cases | none | 29 files | 6 files |
|
|
41
41
|
| Ranking benchmark | 20 queries + 81-config sweep | — | — | — |
|
|
42
42
|
| Store status | source contract satisfied, awaiting review | unlisted | no entry | blocked (review-required) |
|
|
43
43
|
|
package/README.zh-CN.md
CHANGED
|
@@ -9,7 +9,7 @@
|
|
|
9
9
|
|
|
10
10
|
<p align="center">
|
|
11
11
|
<a href="https://www.npmjs.com/package/@fffangchenghao/dsh-web-search"><img src="https://img.shields.io/npm/v/@fffangchenghao/dsh-web-search.svg" alt="npm 版本"></a>
|
|
12
|
-
<img src="https://img.shields.io/badge/tests-
|
|
12
|
+
<img src="https://img.shields.io/badge/tests-486%20passing-brightgreen" alt="测试">
|
|
13
13
|
<img src="https://img.shields.io/badge/engines-8%2C%20zero%20API%20key-brightgreen" alt="引擎">
|
|
14
14
|
<img src="https://img.shields.io/badge/node-%3E%3D22.18-blue" alt="node">
|
|
15
15
|
<img src="https://img.shields.io/badge/dsh-%3E%3D0.2.1--rc.2%20%3C0.3.0-blueviolet" alt="dsh">
|
|
@@ -21,7 +21,7 @@
|
|
|
21
21
|
- **不要 API key,八个引擎。** AnySearch、必应中国、DuckDuckGo HTML、必应国际、DuckDuckGo Lite、360 搜索直接抓取;Exa 走它的免密钥 MCP 通道加入主引擎,Firecrawl 的搜索 API 作为实测后的兜底。装好就能用。
|
|
22
22
|
- **排序是量出来的,不是写出来的。** 跨引擎 RRF 融合,叠加权威度与时效加权;20 条离线基准 + 81 组参数扫描,是这类插件里唯一同时公开指标和置信区间的。方法见 [排序是怎么做的](docs/rrf-ranking.md)。
|
|
23
23
|
- **抓取会承认失败。** 二进制文档和「200 但正文为空」会被明确拒绝(`SEARCH_UNSUPPORTED`、`SEARCH_EMPTY`),而不是当噪音返回;direct → tunnel → render → extract 四级阶梯共享 25 秒预算,预算不足就不再起新的一级。预算是「每次请求」而不是「插件启动时」,这点有回归测试守着。
|
|
24
|
-
- **
|
|
24
|
+
- **31 个测试文件、487 个用例**,`lib/` 产物入库,声明了 `engines.dsh` / `engines.node`,[SECURITY.md](SECURITY.md) 逐项列出插件会碰的进程、主机和文件。
|
|
25
25
|
- **双语文档。** 本文件和 [English README](README.md) 同步维护。
|
|
26
26
|
|
|
27
27
|

|
|
@@ -37,7 +37,7 @@ DSH 插件生态里的「联网搜索」这一块已经很挤,大多数竞品
|
|
|
37
37
|
| 免 key 引擎 | 8 | ~30 | 7 条通道(含 X) | 1 个官方 API |
|
|
38
38
|
| 专门数据源 | 34(默认开 8 个)| 41 | — | — |
|
|
39
39
|
| 面向模型的工具 | 6 | ~10 | 3 | 5 |
|
|
40
|
-
| 测试 |
|
|
40
|
+
| 测试 | 31 文件 / 487 用例 | 无 | 29 文件 | 6 文件 |
|
|
41
41
|
| 排序基准 | 20 查询 + 81 组扫描 | — | — | — |
|
|
42
42
|
| 商店状态 | 源码契约已满足,待复核 | unlisted | 无条目 | blocked(review-required) |
|
|
43
43
|
|
package/client.js
CHANGED
|
@@ -47,14 +47,14 @@
|
|
|
47
47
|
var ENTRY = 'web-search-bing';
|
|
48
48
|
var PACKAGE_NAME = 'dsh-web-search-bing';
|
|
49
49
|
/** Keep in step with package.json; compared with the npm registry. */
|
|
50
|
-
var VERSION = '0.
|
|
50
|
+
var VERSION = '0.17.0';
|
|
51
51
|
/** Snapshot used while no configuration service is reachable. */
|
|
52
52
|
var EMPTY_STATE = { status: 'unavailable', value: undefined, base: undefined, user: undefined, revision: undefined, writable: false };
|
|
53
53
|
|
|
54
54
|
// English copy. Every label the page renders lives here.
|
|
55
55
|
var en = {
|
|
56
56
|
title: 'Web search (Bing)',
|
|
57
|
-
description: 'Edit the key-free search provider: engine allow-list, wait policy, proxy, result budget, ranking, cache, cooldowns and dedicated sources.',
|
|
57
|
+
description: 'Edit the key-free search provider: engine allow-list, wait policy, proxy, result budget, ranking, cache, cooldowns and dedicated sources. Model tools: web_search, research, domain_search, search_many, read_page.',
|
|
58
58
|
jumpTo: 'Jump to',
|
|
59
59
|
latest: 'Latest on npm',
|
|
60
60
|
upToDate: 'up to date',
|
|
@@ -75,8 +75,8 @@
|
|
|
75
75
|
discard: 'Discard changes',
|
|
76
76
|
saved: 'Saved.',
|
|
77
77
|
saveFailed: 'The deployment did not accept these values; they were kept for correction.',
|
|
78
|
-
'field.hosts': 'Only these engines',
|
|
79
|
-
'hint.hosts': '
|
|
78
|
+
'field.hosts': 'Only these engines (8 total)',
|
|
79
|
+
'hint.hosts': 'Four primary: anysearch, exa, ddg-html, cn.bing. Four fallback: firecrawl, www.bing, ddg-lite, so. Empty means all eight; a comma-separated list narrows the set.',
|
|
80
80
|
'field.timeoutMs': 'Wait limit (ms)',
|
|
81
81
|
'hint.timeoutMs': 'How long one engine may take; raise it on a slow network',
|
|
82
82
|
'field.wait': 'How long to wait',
|
|
@@ -147,7 +147,7 @@
|
|
|
147
147
|
latest: 'npm 最新版',
|
|
148
148
|
upToDate: '已是最新',
|
|
149
149
|
updateAvailable: '有新版本',
|
|
150
|
-
description: '
|
|
150
|
+
description: '编辑免密钥搜索提供方:引擎白名单、等待策略、代理、结果上限、排序、缓存、冷却与专用检索源。模型工具:web_search、research、domain_search、search_many、read_page。',
|
|
151
151
|
'group.engines': '引擎与传输',
|
|
152
152
|
'group.ranking': '结果与排序',
|
|
153
153
|
'group.cache': '缓存与冷却',
|
|
@@ -164,8 +164,8 @@
|
|
|
164
164
|
discard: '放弃更改',
|
|
165
165
|
saved: '已保存。',
|
|
166
166
|
saveFailed: '本部署没有接受这些值,已保留供你修改。',
|
|
167
|
-
'field.hosts': '
|
|
168
|
-
'hint.hosts': '
|
|
167
|
+
'field.hosts': '只查哪些引擎(共 8 个)',
|
|
168
|
+
'hint.hosts': '主引擎 4 个:anysearch、exa、ddg-html、cn.bing;兜底 4 个:firecrawl、www.bing、ddg-lite、so。留空表示全部八个,逗号分隔可只留几个。',
|
|
169
169
|
'field.timeoutMs': '等待上限(毫秒)',
|
|
170
170
|
'hint.timeoutMs': '单个引擎最多等多久;网络慢可加到 20000',
|
|
171
171
|
'field.wait': '等多久',
|
package/lib/config.js
CHANGED
|
@@ -27,7 +27,7 @@ export const Config = z.object({
|
|
|
27
27
|
hosts: z
|
|
28
28
|
.array(z.string())
|
|
29
29
|
.default([])
|
|
30
|
-
.description('只启用列出的搜索引擎(如 anysearch、cn.bing
|
|
30
|
+
.description('只启用列出的搜索引擎(如 anysearch、cn.bing),多个用逗号分隔;留空表示全部八个(主引擎 anysearch、exa、ddg-html、cn.bing;兜底 firecrawl、www.bing、ddg-lite、so)。不想限制就留空。')
|
|
31
31
|
.volatile(),
|
|
32
32
|
timeoutMs: z.natural().min(500).default(15000).description('每次向搜索引擎要结果,最多等它多久(毫秒,1000 = 1 秒)。网络慢可加到 20000;平时保持 15000 就行。').volatile(),
|
|
33
33
|
fetchFormat: z
|
package/lib/engines.js
CHANGED
|
@@ -20,6 +20,7 @@ const ANYSEARCH_MAX_RESULTS = 10;
|
|
|
20
20
|
export const HOSTS = [
|
|
21
21
|
{
|
|
22
22
|
id: 'anysearch',
|
|
23
|
+
maxConcurrent: 3,
|
|
23
24
|
tier: 'primary',
|
|
24
25
|
// Serves both languages: it answers Chinese queries with the original
|
|
25
26
|
// documentation and book translations rather than SEO farms, so it leads a
|
|
@@ -38,6 +39,9 @@ export const HOSTS = [
|
|
|
38
39
|
},
|
|
39
40
|
{
|
|
40
41
|
id: 'exa',
|
|
42
|
+
// Anonymous MCP rejects bursts (five parallel `search_many` queries came
|
|
43
|
+
// back 429 on four); two at a time kept every answer inside the deadline.
|
|
44
|
+
maxConcurrent: 2,
|
|
41
45
|
// A semantic (embedding) index rather than a keyword page: it answers with
|
|
42
46
|
// the page itself plus highlights. The MCP endpoint accepts anonymous
|
|
43
47
|
// calls, so it costs no key. Measured on the same recorded fixtures with the
|
|
@@ -61,6 +65,7 @@ export const HOSTS = [
|
|
|
61
65
|
},
|
|
62
66
|
{
|
|
63
67
|
id: 'firecrawl',
|
|
68
|
+
maxConcurrent: 1,
|
|
64
69
|
// The keyless tier of the Firecrawl search API. It returns extracted page
|
|
65
70
|
// Markdown rather than snippets, so only the opening prose is kept as the
|
|
66
71
|
// row's snippet; it handled a Chinese query with the same shape. It ships as
|
package/lib/fetch.d.ts
CHANGED
|
@@ -81,6 +81,32 @@ export interface FetchDependencies {
|
|
|
81
81
|
*/
|
|
82
82
|
render: (renderer: RendererModule, url: string, timeoutMs: number, signal: AbortSignal | undefined) => Promise<RenderedPage>;
|
|
83
83
|
}
|
|
84
|
+
/**
|
|
85
|
+
* Find the target of an HTML-level redirect.
|
|
86
|
+
*
|
|
87
|
+
* Some documentation sites keep old URLs alive with a page whose only content
|
|
88
|
+
* is `<meta http-equiv="refresh">` plus a JavaScript `location.replace`. The
|
|
89
|
+
* HTTP status is 200, so `fetch` reports success and the model receives a page
|
|
90
|
+
* that says "Redirecting…" and nothing else. PyTorch's `stable` docs do this
|
|
91
|
+
* for every moved page. Following the declaration once turns that into the page
|
|
92
|
+
* the browser would have shown.
|
|
93
|
+
*
|
|
94
|
+
* Only an explicit `<meta refresh>` or a page whose `<title>` says it is a
|
|
95
|
+
* redirect is followed. A normal page that happens to mention `location.href`
|
|
96
|
+
* in a script is left alone.
|
|
97
|
+
* @param html - raw HTML body.
|
|
98
|
+
* @param baseUrl - URL the body came from, for resolving relative targets.
|
|
99
|
+
* @returns absolute target URL, or `undefined` when this is a normal page.
|
|
100
|
+
*/
|
|
101
|
+
export declare function documentRedirect(html: string, baseUrl: string): string | undefined;
|
|
102
|
+
/**
|
|
103
|
+
* Direct request used by the first rung.
|
|
104
|
+
*
|
|
105
|
+
* Follows up to {@link REDIRECT_HOPS} HTML-level redirects inside the same
|
|
106
|
+
* deadline, which is what makes a moved docs URL readable instead of a page
|
|
107
|
+
* that only says "Redirecting…".
|
|
108
|
+
*/
|
|
109
|
+
export declare function directFetch(url: string, timeoutMs: number, signal: AbortSignal | undefined, userAgent: string, maxBytes: number): Promise<FetchOutcome>;
|
|
84
110
|
/**
|
|
85
111
|
* Build the fetch provider.
|
|
86
112
|
* @param options - timeouts, tunnel and extraction settings.
|
package/lib/fetch.js
CHANGED
|
@@ -103,41 +103,122 @@ function abortFetch(signal) {
|
|
|
103
103
|
throw reason;
|
|
104
104
|
throw new DOMException('The fetch was aborted', 'AbortError');
|
|
105
105
|
}
|
|
106
|
-
/**
|
|
107
|
-
|
|
108
|
-
|
|
109
|
-
|
|
110
|
-
|
|
111
|
-
|
|
112
|
-
|
|
113
|
-
|
|
114
|
-
|
|
115
|
-
|
|
116
|
-
|
|
117
|
-
|
|
118
|
-
|
|
119
|
-
|
|
120
|
-
|
|
121
|
-
|
|
122
|
-
|
|
106
|
+
/** How many document-level redirects one fetch follows before giving up. */
|
|
107
|
+
const REDIRECT_HOPS = 2;
|
|
108
|
+
/**
|
|
109
|
+
* Find the target of an HTML-level redirect.
|
|
110
|
+
*
|
|
111
|
+
* Some documentation sites keep old URLs alive with a page whose only content
|
|
112
|
+
* is `<meta http-equiv="refresh">` plus a JavaScript `location.replace`. The
|
|
113
|
+
* HTTP status is 200, so `fetch` reports success and the model receives a page
|
|
114
|
+
* that says "Redirecting…" and nothing else. PyTorch's `stable` docs do this
|
|
115
|
+
* for every moved page. Following the declaration once turns that into the page
|
|
116
|
+
* the browser would have shown.
|
|
117
|
+
*
|
|
118
|
+
* Only an explicit `<meta refresh>` or a page whose `<title>` says it is a
|
|
119
|
+
* redirect is followed. A normal page that happens to mention `location.href`
|
|
120
|
+
* in a script is left alone.
|
|
121
|
+
* @param html - raw HTML body.
|
|
122
|
+
* @param baseUrl - URL the body came from, for resolving relative targets.
|
|
123
|
+
* @returns absolute target URL, or `undefined` when this is a normal page.
|
|
124
|
+
*/
|
|
125
|
+
export function documentRedirect(html, baseUrl) {
|
|
126
|
+
if (html.length === 0)
|
|
127
|
+
return undefined;
|
|
128
|
+
const sample = html.slice(0, 200_000);
|
|
129
|
+
let target;
|
|
130
|
+
const meta = /<meta[^>]+http-equiv\s*=\s*["']?refresh["']?[^>]*>/iu.exec(sample);
|
|
131
|
+
if (meta !== null) {
|
|
132
|
+
const content = /content\s*=\s*["']([^"']*)["']/iu.exec(meta[0])?.[1];
|
|
133
|
+
const url = content === undefined ? undefined : /url\s*=\s*([^"'\s>]+)/iu.exec(content)?.[1];
|
|
134
|
+
target = url;
|
|
135
|
+
}
|
|
136
|
+
if (target === undefined) {
|
|
137
|
+
const title = /<title>([^<]*)<\/title>/iu.exec(sample)?.[1]?.trim() ?? '';
|
|
138
|
+
if (/redirect|jump|transfer|跳转/iu.test(title)) {
|
|
139
|
+
const script = /location\s*\.\s*(?:replace|assign)\s*\(\s*["']([^"']+)["']/iu.exec(sample);
|
|
140
|
+
const canonical = /<link[^>]+rel\s*=\s*["']?canonical["']?[^>]*href\s*=\s*["']([^"']+)["']/iu.exec(sample)
|
|
141
|
+
?? /<link[^>]+href\s*=\s*["']([^"']+)["'][^>]*rel\s*=\s*["']?canonical/iu.exec(sample);
|
|
142
|
+
target = script?.[1] ?? canonical?.[1];
|
|
143
|
+
}
|
|
144
|
+
}
|
|
145
|
+
if (target === undefined)
|
|
146
|
+
return undefined;
|
|
147
|
+
try {
|
|
148
|
+
const resolved = new URL(target, baseUrl);
|
|
149
|
+
return resolved.protocol === 'http:' || resolved.protocol === 'https:' ? resolved.href : undefined;
|
|
150
|
+
}
|
|
151
|
+
catch {
|
|
152
|
+
return undefined;
|
|
153
|
+
}
|
|
154
|
+
}
|
|
155
|
+
/**
|
|
156
|
+
* Direct request used by the first rung.
|
|
157
|
+
*
|
|
158
|
+
* Follows up to {@link REDIRECT_HOPS} HTML-level redirects inside the same
|
|
159
|
+
* deadline, which is what makes a moved docs URL readable instead of a page
|
|
160
|
+
* that only says "Redirecting…".
|
|
161
|
+
*/
|
|
162
|
+
export async function directFetch(url, timeoutMs, signal, userAgent, maxBytes) {
|
|
163
|
+
const startedAt = Date.now();
|
|
164
|
+
let target = url;
|
|
165
|
+
let last;
|
|
166
|
+
for (let hop = 0; hop <= REDIRECT_HOPS; hop += 1) {
|
|
167
|
+
const left = Math.max(500, timeoutMs - (Date.now() - startedAt));
|
|
168
|
+
const response = await fetch(target, {
|
|
169
|
+
signal: deadline(left, signal),
|
|
170
|
+
redirect: 'follow',
|
|
171
|
+
headers: { 'user-agent': userAgent, accept: 'text/html,application/xhtml+xml,application/json;q=0.9,*/*;q=0.8' },
|
|
172
|
+
});
|
|
173
|
+
const contentType = response.headers.get('content-type');
|
|
174
|
+
const text = await response.text();
|
|
175
|
+
const { content, truncated } = clamp(text, maxBytes);
|
|
176
|
+
last = {
|
|
177
|
+
url: response.url === '' ? target : response.url,
|
|
178
|
+
statusCode: response.status,
|
|
179
|
+
body: { kind: kindOf(contentType), content },
|
|
180
|
+
contentType: mimeOf(contentType),
|
|
181
|
+
truncated,
|
|
182
|
+
};
|
|
183
|
+
if (last.body.kind !== 'html')
|
|
184
|
+
return last;
|
|
185
|
+
const next = documentRedirect(last.body.content, last.url);
|
|
186
|
+
if (next === undefined || next === last.url)
|
|
187
|
+
return last;
|
|
188
|
+
target = next;
|
|
189
|
+
}
|
|
190
|
+
return last;
|
|
123
191
|
}
|
|
124
192
|
/** Tunnelled request used by the second rung. */
|
|
125
193
|
async function tunnelFetch(url, proxy, timeoutMs, signal, userAgent, maxBytes) {
|
|
126
|
-
const
|
|
127
|
-
|
|
128
|
-
|
|
129
|
-
|
|
130
|
-
|
|
131
|
-
|
|
132
|
-
|
|
133
|
-
|
|
134
|
-
|
|
135
|
-
|
|
136
|
-
|
|
137
|
-
|
|
138
|
-
contentType
|
|
139
|
-
|
|
140
|
-
|
|
194
|
+
const startedAt = Date.now();
|
|
195
|
+
let target = url;
|
|
196
|
+
let last;
|
|
197
|
+
for (let hop = 0; hop <= REDIRECT_HOPS; hop += 1) {
|
|
198
|
+
const left = Math.max(500, timeoutMs - (Date.now() - startedAt));
|
|
199
|
+
const response = await proxyGet(target, {
|
|
200
|
+
proxy,
|
|
201
|
+
headers: { 'user-agent': userAgent, accept: 'text/html,application/xhtml+xml,application/json;q=0.9,*/*;q=0.8' },
|
|
202
|
+
timeoutMs: left,
|
|
203
|
+
...(signal === undefined ? {} : { signal }),
|
|
204
|
+
});
|
|
205
|
+
const { content, truncated } = clamp(response.text, maxBytes);
|
|
206
|
+
const contentType = response.headers?.['content-type'] ?? null;
|
|
207
|
+
last = {
|
|
208
|
+
url: target,
|
|
209
|
+
statusCode: response.status,
|
|
210
|
+
body: { kind: kindOf(contentType), content },
|
|
211
|
+
contentType: mimeOf(contentType),
|
|
212
|
+
truncated,
|
|
213
|
+
};
|
|
214
|
+
if (last.body.kind !== 'html')
|
|
215
|
+
return last;
|
|
216
|
+
const next = documentRedirect(last.body.content, target);
|
|
217
|
+
if (next === undefined || next === target)
|
|
218
|
+
return last;
|
|
219
|
+
target = next;
|
|
220
|
+
}
|
|
221
|
+
return last;
|
|
141
222
|
}
|
|
142
223
|
/** Server-side extraction used by the third rung. */
|
|
143
224
|
async function extractFetch(url, apiKey, timeoutMs, signal) {
|
|
@@ -295,7 +376,7 @@ export function createFetchProvider(options = {}, overrides = {}) {
|
|
|
295
376
|
// The render rung's reason describes the raw bytes, not the extraction
|
|
296
377
|
// result, so never lead with it: "7387 readable characters" next to "empty
|
|
297
378
|
// page" reads like a contradiction.
|
|
298
|
-
const detail = failures.length === 0 ? '' : `; ${failures.join('; ')}`;
|
|
379
|
+
const detail = failures.length === 0 ? '' : `; ${[...new Set(failures)].join('; ')}`;
|
|
299
380
|
const render = outcome.render?.reason === undefined || outcome.render.reason === ''
|
|
300
381
|
? ''
|
|
301
382
|
: `; renderer: ${outcome.render.reason}`;
|
|
@@ -496,7 +577,7 @@ export function createFetchProvider(options = {}, overrides = {}) {
|
|
|
496
577
|
: reportFor();
|
|
497
578
|
return assertUsable(finalize(fallback, report), failures);
|
|
498
579
|
}
|
|
499
|
-
throw new SearchError(`cannot fetch ${target} (${failures.join('; ')})`, 'SEARCH_NETWORK', true);
|
|
580
|
+
throw new SearchError(`cannot fetch ${target} (${[...new Set(failures)].join('; ')})`, 'SEARCH_NETWORK', true);
|
|
500
581
|
},
|
|
501
582
|
};
|
|
502
583
|
}
|
package/lib/markdown.js
CHANGED
|
@@ -570,7 +570,16 @@ function inlineElement(node, ctx) {
|
|
|
570
570
|
return href.length === 0 ? inner : `${inner} (${href})`;
|
|
571
571
|
if (href.length === 0)
|
|
572
572
|
return inner;
|
|
573
|
-
|
|
573
|
+
const label = inner.trim();
|
|
574
|
+
// Documentation sites (Python's Sphinx, many others) attach a "¶" permalink
|
|
575
|
+
// to every heading. Keeping it turns every heading into a broken-looking
|
|
576
|
+
// `[¶](...#id)` fragment in the Markdown a model has to read.
|
|
577
|
+
if (label === '¶' || label === '#' || label === '§' || label === '🔗' || label === '↩')
|
|
578
|
+
return '';
|
|
579
|
+
// A link whose text is its own URL adds nothing over an autolink.
|
|
580
|
+
if (label === href)
|
|
581
|
+
return `<${href}>`;
|
|
582
|
+
return `[${label.length === 0 ? href : inner}](${href})`;
|
|
574
583
|
}
|
|
575
584
|
case 'code': {
|
|
576
585
|
const text = textOf(node).replace(/\s+/g, ' ').trim();
|
package/lib/research.js
CHANGED
|
@@ -67,6 +67,52 @@ async function mapLimit(items, limit, worker) {
|
|
|
67
67
|
await Promise.all(runners);
|
|
68
68
|
return results;
|
|
69
69
|
}
|
|
70
|
+
/** Words that carry no retrieval signal in a research query. */
|
|
71
|
+
const QUERY_STOPWORDS = new Set([
|
|
72
|
+
'the', 'a', 'an', 'and', 'or', 'of', 'to', 'in', 'on', 'for', 'with', 'from',
|
|
73
|
+
'what', 'which', 'who', 'whom', 'how', 'why', 'when', 'where', 'is', 'are',
|
|
74
|
+
'was', 'were', 'be', 'been', 'do', 'does', 'did', 'vs', 'versus', 'about',
|
|
75
|
+
'please', 'tell', 'give', 'show', 'find', 'compare', 'difference', 'between',
|
|
76
|
+
]);
|
|
77
|
+
/** CJK stopword bigrams that would match almost any Chinese page. */
|
|
78
|
+
const CJK_STOPWORDS = new Set(['的是', '了吗', '什么', '怎么', '如何', '哪些', '多少', '一下', '请问', '最近', '以及']);
|
|
79
|
+
/**
|
|
80
|
+
* Tokens a candidate should contain to count as relevant.
|
|
81
|
+
*
|
|
82
|
+
* ASCII words shorter than three characters are dropped, and Chinese runs are
|
|
83
|
+
* cut into bigrams; that is enough to tell an article about `东数西算` from a
|
|
84
|
+
* dictionary entry for the single character `东`.
|
|
85
|
+
* @param queries - the queries this call ran.
|
|
86
|
+
* @returns distinct lowercase tokens.
|
|
87
|
+
*/
|
|
88
|
+
function queryTokens(queries) {
|
|
89
|
+
const text = queries.join(' ').toLowerCase();
|
|
90
|
+
const tokens = new Set();
|
|
91
|
+
for (const word of text.match(/[a-z][a-z0-9.+#-]{2,}/gu) ?? []) {
|
|
92
|
+
if (!QUERY_STOPWORDS.has(word))
|
|
93
|
+
tokens.add(word);
|
|
94
|
+
}
|
|
95
|
+
for (const run of text.match(/[\u4e00-\u9fff]{2,}/gu) ?? []) {
|
|
96
|
+
if (run.length === 2) {
|
|
97
|
+
if (!CJK_STOPWORDS.has(run))
|
|
98
|
+
tokens.add(run);
|
|
99
|
+
continue;
|
|
100
|
+
}
|
|
101
|
+
for (let index = 0; index < run.length - 1; index += 1) {
|
|
102
|
+
const bigram = run.slice(index, index + 2);
|
|
103
|
+
if (!CJK_STOPWORDS.has(bigram))
|
|
104
|
+
tokens.add(bigram);
|
|
105
|
+
}
|
|
106
|
+
}
|
|
107
|
+
return [...tokens];
|
|
108
|
+
}
|
|
109
|
+
/** Count how many query tokens appear in a row's title and snippet. */
|
|
110
|
+
function relevanceScore(source, tokens) {
|
|
111
|
+
if (tokens.length === 0)
|
|
112
|
+
return 0;
|
|
113
|
+
const haystack = `${source.title ?? ''} ${source.snippet ?? ''}`.toLowerCase();
|
|
114
|
+
return tokens.reduce((score, token) => (haystack.includes(token) ? score + 1 : score), 0);
|
|
115
|
+
}
|
|
70
116
|
/** Interleave per-query result lists by rank, so one query cannot fill the pack. */
|
|
71
117
|
function interleave(sourcesByQuery) {
|
|
72
118
|
const merged = [];
|
|
@@ -273,53 +319,86 @@ export function createResearchDefinition(name, search, fetchPage) {
|
|
|
273
319
|
if (cancelled())
|
|
274
320
|
throw new Error('research was cancelled');
|
|
275
321
|
const candidates = interleave(outcomes.map((outcome) => outcome.sources));
|
|
322
|
+
// Prefer rows whose title or snippet actually contains a query token.
|
|
323
|
+
// Search engines return a few singletons for a long Chinese query (the
|
|
324
|
+
// character `东`, a company named 东…); fetching those spends the budget
|
|
325
|
+
// on prose that cannot answer the question. The filter is only a
|
|
326
|
+
// preference: when too few rows match, every candidate is still eligible.
|
|
327
|
+
const tokens = queryTokens(parsed.queries);
|
|
328
|
+
const scored = candidates.map((source, index) => ({ source, index, score: relevanceScore(source, tokens) }));
|
|
329
|
+
const matched = scored.filter((entry) => entry.score > 0);
|
|
330
|
+
const pool = matched.length >= parsed.maxSources ? matched : scored;
|
|
331
|
+
pool.sort((left, right) => right.score - left.score || left.index - right.index);
|
|
332
|
+
const ranked = pool.map((entry) => entry.source);
|
|
276
333
|
const failures = [];
|
|
277
|
-
|
|
278
|
-
|
|
279
|
-
|
|
280
|
-
|
|
281
|
-
|
|
282
|
-
|
|
283
|
-
|
|
284
|
-
|
|
285
|
-
|
|
286
|
-
|
|
287
|
-
|
|
288
|
-
|
|
289
|
-
|
|
290
|
-
|
|
291
|
-
const
|
|
292
|
-
if (
|
|
293
|
-
|
|
294
|
-
|
|
334
|
+
// Fill the quota even when a page fails: with `wanted = candidates.slice(0,
|
|
335
|
+
// maxSources)`, one dead candidate produced a pack with two pages out of
|
|
336
|
+
// three and a successful candidate never tried. Workers share a cursor and
|
|
337
|
+
// stop pulling new candidates once enough pages have succeeded, so the
|
|
338
|
+
// extra attempts stay bounded by the concurrency (three) plus the failures.
|
|
339
|
+
const attempts = [];
|
|
340
|
+
let cursor = 0;
|
|
341
|
+
let succeeded = 0;
|
|
342
|
+
const workers = Array.from({ length: Math.min(RESEARCH_PAGE_CONCURRENCY, candidates.length) }, async () => {
|
|
343
|
+
for (;;) {
|
|
344
|
+
if (succeeded >= parsed.maxSources || cancelled())
|
|
345
|
+
return;
|
|
346
|
+
const index = cursor;
|
|
347
|
+
cursor += 1;
|
|
348
|
+
const source = ranked[index];
|
|
349
|
+
if (source === undefined)
|
|
350
|
+
return;
|
|
351
|
+
const budget = Math.min(20_000, remaining());
|
|
352
|
+
if (budget < RESEARCH_MIN_PAGE_MS) {
|
|
353
|
+
failures.push({ url: source.url, reason: 'no time left in the research budget' });
|
|
354
|
+
return;
|
|
355
|
+
}
|
|
356
|
+
const bound = signal === undefined
|
|
357
|
+
? AbortSignal.timeout(budget)
|
|
358
|
+
: AbortSignal.any([signal, AbortSignal.timeout(budget)]);
|
|
359
|
+
try {
|
|
360
|
+
const fetched = await fetchPage(source.url, bound);
|
|
361
|
+
const excerpt = excerptOf(fetched.text, RESEARCH_EXCERPT_CHARS);
|
|
362
|
+
if (excerpt.length === 0) {
|
|
363
|
+
failures.push({ url: source.url, reason: 'the page carried no readable text' });
|
|
364
|
+
continue;
|
|
365
|
+
}
|
|
366
|
+
succeeded += 1;
|
|
367
|
+
attempts.push({
|
|
368
|
+
index,
|
|
369
|
+
page: {
|
|
370
|
+
url: fetched.url.length > 0 ? fetched.url : source.url,
|
|
371
|
+
...(source.title === undefined || source.title.length === 0 ? {} : { title: source.title }),
|
|
372
|
+
status: fetched.status,
|
|
373
|
+
chars: fetched.text.length,
|
|
374
|
+
excerpt,
|
|
375
|
+
truncated: fetched.truncated || fetched.text.length > RESEARCH_EXCERPT_CHARS,
|
|
376
|
+
},
|
|
377
|
+
});
|
|
378
|
+
}
|
|
379
|
+
catch (error) {
|
|
380
|
+
if (cancelled())
|
|
381
|
+
throw error;
|
|
382
|
+
failures.push({ url: source.url, reason: error instanceof Error ? error.message : String(error) });
|
|
295
383
|
}
|
|
296
|
-
const page = {
|
|
297
|
-
url: fetched.url.length > 0 ? fetched.url : source.url,
|
|
298
|
-
...(source.title === undefined || source.title.length === 0 ? {} : { title: source.title }),
|
|
299
|
-
status: fetched.status,
|
|
300
|
-
chars: fetched.text.length,
|
|
301
|
-
excerpt,
|
|
302
|
-
truncated: fetched.truncated || fetched.text.length > RESEARCH_EXCERPT_CHARS,
|
|
303
|
-
};
|
|
304
|
-
return page;
|
|
305
|
-
}
|
|
306
|
-
catch (error) {
|
|
307
|
-
if (cancelled())
|
|
308
|
-
throw error;
|
|
309
|
-
failures.push({ url: source.url, reason: error instanceof Error ? error.message : String(error) });
|
|
310
|
-
return undefined;
|
|
311
384
|
}
|
|
312
385
|
});
|
|
386
|
+
await Promise.all(workers);
|
|
313
387
|
if (cancelled())
|
|
314
388
|
throw new Error('research was cancelled');
|
|
315
|
-
const fetchedPages =
|
|
389
|
+
const fetchedPages = attempts
|
|
390
|
+
.sort((left, right) => left.index - right.index)
|
|
391
|
+
.map((attempt) => attempt.page)
|
|
392
|
+
.filter((page) => page !== undefined)
|
|
393
|
+
.slice(0, parsed.maxSources);
|
|
316
394
|
const fetchedUrls = new Set(fetchedPages.map((page) => page.url));
|
|
395
|
+
const failedUrls = new Set(failures.map((failure) => failure.url));
|
|
317
396
|
return {
|
|
318
397
|
query: parsed.queries[0],
|
|
319
398
|
queries: parsed.queries,
|
|
320
399
|
pages: fetchedPages,
|
|
321
400
|
sources: candidates
|
|
322
|
-
.filter((source) => !fetchedUrls.has(source.url))
|
|
401
|
+
.filter((source) => !fetchedUrls.has(source.url) && !failedUrls.has(source.url))
|
|
323
402
|
.slice(0, 20)
|
|
324
403
|
.map((source) => ({
|
|
325
404
|
url: source.url,
|
|
@@ -0,0 +1,45 @@
|
|
|
1
|
+
/**
|
|
2
|
+
* A small counting semaphore for engines with a strict request budget.
|
|
3
|
+
*
|
|
4
|
+
* Exa's anonymous MCP endpoint and Firecrawl's keyless API answer one request at
|
|
5
|
+
* a time gracefully and reject bursts with 429. `search_many` and `research`
|
|
6
|
+
* legitimately fire several searches at once, so the limit has to live outside
|
|
7
|
+
* one `search()` call: a global gate per host id, shared by every concurrent
|
|
8
|
+
* caller in the process.
|
|
9
|
+
*
|
|
10
|
+
* Waiting is cancellable, and a permit is always returned through `finally` so
|
|
11
|
+
* a rejected request cannot shrink the pool permanently.
|
|
12
|
+
*
|
|
13
|
+
* @module @fangchenghao/dsh-web-search/semaphore
|
|
14
|
+
*/
|
|
15
|
+
/** A counting semaphore whose waiters can be cancelled. */
|
|
16
|
+
export declare class Semaphore {
|
|
17
|
+
private active;
|
|
18
|
+
private readonly waiting;
|
|
19
|
+
private readonly permits;
|
|
20
|
+
/**
|
|
21
|
+
* @param permits - how many holders may run at once; at least one.
|
|
22
|
+
*/
|
|
23
|
+
constructor(permits: number);
|
|
24
|
+
/** Holders currently inside the gate. */
|
|
25
|
+
get running(): number;
|
|
26
|
+
/** Waiters queued behind the gate. */
|
|
27
|
+
get pending(): number;
|
|
28
|
+
/**
|
|
29
|
+
* Take a permit, waiting for one when the gate is full.
|
|
30
|
+
* @param signal - caller cancellation; waiting rejects when it fires.
|
|
31
|
+
* @returns the release function; calling it more than once is harmless.
|
|
32
|
+
*/
|
|
33
|
+
acquire(signal?: AbortSignal): Promise<() => void>;
|
|
34
|
+
/** Build the idempotent release function handed to the caller. */
|
|
35
|
+
private releaser;
|
|
36
|
+
}
|
|
37
|
+
/**
|
|
38
|
+
* Get the process-wide gate for one engine.
|
|
39
|
+
* @param id - engine id.
|
|
40
|
+
* @param permits - concurrency limit declared by the engine.
|
|
41
|
+
* @returns the shared semaphore.
|
|
42
|
+
*/
|
|
43
|
+
export declare function gateFor(id: string, permits: number): Semaphore;
|
|
44
|
+
/** Drop cached gates; used by tests. */
|
|
45
|
+
export declare function resetGates(): void;
|
package/lib/semaphore.js
ADDED
|
@@ -0,0 +1,100 @@
|
|
|
1
|
+
/**
|
|
2
|
+
* A small counting semaphore for engines with a strict request budget.
|
|
3
|
+
*
|
|
4
|
+
* Exa's anonymous MCP endpoint and Firecrawl's keyless API answer one request at
|
|
5
|
+
* a time gracefully and reject bursts with 429. `search_many` and `research`
|
|
6
|
+
* legitimately fire several searches at once, so the limit has to live outside
|
|
7
|
+
* one `search()` call: a global gate per host id, shared by every concurrent
|
|
8
|
+
* caller in the process.
|
|
9
|
+
*
|
|
10
|
+
* Waiting is cancellable, and a permit is always returned through `finally` so
|
|
11
|
+
* a rejected request cannot shrink the pool permanently.
|
|
12
|
+
*
|
|
13
|
+
* @module @fangchenghao/dsh-web-search/semaphore
|
|
14
|
+
*/
|
|
15
|
+
/** A counting semaphore whose waiters can be cancelled. */
|
|
16
|
+
export class Semaphore {
|
|
17
|
+
active = 0;
|
|
18
|
+
waiting = [];
|
|
19
|
+
permits;
|
|
20
|
+
/**
|
|
21
|
+
* @param permits - how many holders may run at once; at least one.
|
|
22
|
+
*/
|
|
23
|
+
constructor(permits) {
|
|
24
|
+
this.permits = permits;
|
|
25
|
+
if (!Number.isInteger(permits) || permits < 1) {
|
|
26
|
+
throw new Error(`a semaphore needs at least one permit, got ${permits}`);
|
|
27
|
+
}
|
|
28
|
+
}
|
|
29
|
+
/** Holders currently inside the gate. */
|
|
30
|
+
get running() {
|
|
31
|
+
return this.active;
|
|
32
|
+
}
|
|
33
|
+
/** Waiters queued behind the gate. */
|
|
34
|
+
get pending() {
|
|
35
|
+
return this.waiting.length;
|
|
36
|
+
}
|
|
37
|
+
/**
|
|
38
|
+
* Take a permit, waiting for one when the gate is full.
|
|
39
|
+
* @param signal - caller cancellation; waiting rejects when it fires.
|
|
40
|
+
* @returns the release function; calling it more than once is harmless.
|
|
41
|
+
*/
|
|
42
|
+
async acquire(signal) {
|
|
43
|
+
if (signal?.aborted === true)
|
|
44
|
+
throw signal.reason ?? new Error('the wait was cancelled');
|
|
45
|
+
if (this.active < this.permits) {
|
|
46
|
+
this.active += 1;
|
|
47
|
+
return this.releaser();
|
|
48
|
+
}
|
|
49
|
+
return new Promise((resolve, reject) => {
|
|
50
|
+
const grant = () => {
|
|
51
|
+
cleanup();
|
|
52
|
+
this.active += 1;
|
|
53
|
+
resolve(this.releaser());
|
|
54
|
+
};
|
|
55
|
+
const onAbort = () => {
|
|
56
|
+
cleanup();
|
|
57
|
+
const index = this.waiting.indexOf(grant);
|
|
58
|
+
if (index >= 0)
|
|
59
|
+
this.waiting.splice(index, 1);
|
|
60
|
+
reject(signal?.reason ?? new Error('the wait was cancelled'));
|
|
61
|
+
};
|
|
62
|
+
const cleanup = () => signal?.removeEventListener('abort', onAbort);
|
|
63
|
+
signal?.addEventListener('abort', onAbort, { once: true });
|
|
64
|
+
this.waiting.push(grant);
|
|
65
|
+
});
|
|
66
|
+
}
|
|
67
|
+
/** Build the idempotent release function handed to the caller. */
|
|
68
|
+
releaser() {
|
|
69
|
+
let released = false;
|
|
70
|
+
return () => {
|
|
71
|
+
if (released)
|
|
72
|
+
return;
|
|
73
|
+
released = true;
|
|
74
|
+
this.active -= 1;
|
|
75
|
+
const next = this.waiting.shift();
|
|
76
|
+
if (next !== undefined)
|
|
77
|
+
next();
|
|
78
|
+
};
|
|
79
|
+
}
|
|
80
|
+
}
|
|
81
|
+
/** Gates keyed by engine id; created lazily and never removed. */
|
|
82
|
+
const gates = new Map();
|
|
83
|
+
/**
|
|
84
|
+
* Get the process-wide gate for one engine.
|
|
85
|
+
* @param id - engine id.
|
|
86
|
+
* @param permits - concurrency limit declared by the engine.
|
|
87
|
+
* @returns the shared semaphore.
|
|
88
|
+
*/
|
|
89
|
+
export function gateFor(id, permits) {
|
|
90
|
+
const existing = gates.get(id);
|
|
91
|
+
if (existing !== undefined)
|
|
92
|
+
return existing;
|
|
93
|
+
const created = new Semaphore(permits);
|
|
94
|
+
gates.set(id, created);
|
|
95
|
+
return created;
|
|
96
|
+
}
|
|
97
|
+
/** Drop cached gates; used by tests. */
|
|
98
|
+
export function resetGates() {
|
|
99
|
+
gates.clear();
|
|
100
|
+
}
|
package/lib/transport.js
CHANGED
|
@@ -1,6 +1,7 @@
|
|
|
1
1
|
import { SearchError, parseRetryAfter } from "./errors.js";
|
|
2
2
|
import { proxyGet } from "./proxy.js";
|
|
3
3
|
import { echoesQuery } from "./parsers.js";
|
|
4
|
+
import { gateFor } from "./semaphore.js";
|
|
4
5
|
/** Markers of an interstitial anti-bot page, narrow enough not to hit prose. */
|
|
5
6
|
const BOT_WALL_MARKERS = ['qcaptcha', '访问异常', 'unusual traffic', 'verify you are human', '安全验证'];
|
|
6
7
|
/**
|
|
@@ -149,9 +150,20 @@ async function attempt(host, url, signal, timeoutMs, proxy, query) {
|
|
|
149
150
|
export async function searchHost(host, query, signal, timeoutMs = 15000, proxy, timeRange) {
|
|
150
151
|
const url = host.build(query, timeRange);
|
|
151
152
|
const route = host.viaProxy === true ? proxy : undefined;
|
|
152
|
-
|
|
153
|
-
|
|
154
|
-
|
|
155
|
-
const
|
|
156
|
-
|
|
153
|
+
// A gate holds the permit for the whole engine attempt, including the
|
|
154
|
+
// direct-then-tunnel retry, so a burst of concurrent searches cannot stack
|
|
155
|
+
// two requests on an engine that only tolerates a couple.
|
|
156
|
+
const release = host.maxConcurrent === undefined
|
|
157
|
+
? undefined
|
|
158
|
+
: await gateFor(host.id, host.maxConcurrent).acquire(signal);
|
|
159
|
+
try {
|
|
160
|
+
const first = await attempt(host, url, signal, timeoutMs, route, query);
|
|
161
|
+
if (first.ok || route !== undefined || proxy === undefined || signal?.aborted === true)
|
|
162
|
+
return first;
|
|
163
|
+
const retry = await attempt(host, url, signal, timeoutMs, proxy, query);
|
|
164
|
+
return retry.ok ? retry : first;
|
|
165
|
+
}
|
|
166
|
+
finally {
|
|
167
|
+
release?.();
|
|
168
|
+
}
|
|
157
169
|
}
|
package/lib/types.d.ts
CHANGED
|
@@ -40,6 +40,14 @@ export interface HostSpec {
|
|
|
40
40
|
weight?: number;
|
|
41
41
|
/** Tunnel from the start instead of trying a direct request first. */
|
|
42
42
|
viaProxy?: boolean;
|
|
43
|
+
/**
|
|
44
|
+
* Requests this engine accepts at once, process-wide.
|
|
45
|
+
*
|
|
46
|
+
* Exa and Firecrawl reject bursts with 429, and `search_many` legitimately
|
|
47
|
+
* starts several searches together; a gate per engine id keeps those calls
|
|
48
|
+
* from fighting each other.
|
|
49
|
+
*/
|
|
50
|
+
maxConcurrent?: number;
|
|
43
51
|
/** Send `body(query)` as a JSON POST rather than a GET. */
|
|
44
52
|
method?: 'POST';
|
|
45
53
|
/** Skip the echoed-query check: a JSON API validates itself. */
|
package/package.json
CHANGED
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
{
|
|
2
2
|
"name": "@fffangchenghao/dsh-web-search",
|
|
3
|
-
"version": "0.
|
|
3
|
+
"version": "0.17.0",
|
|
4
4
|
"description": "DSH bundle: a key-free web search provider. Leads with the anonymous AnySearch API and falls back to public result pages (DuckDuckGo, Bing, 360), merged by reciprocal-rank fusion with a bilingual region policy, an engine cooldown and a TTL cache.",
|
|
5
5
|
"type": "module",
|
|
6
6
|
"main": "lib/index.js",
|