@fffangchenghao/dsh-web-search 0.14.0 → 0.16.0
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- package/CHANGELOG.md +53 -0
- package/README.md +43 -35
- package/README.zh-CN.md +37 -33
- package/SECURITY.md +4 -0
- package/client.js +72 -5
- package/docs/rrf-ranking.md +40 -22
- package/lib/config.js +5 -5
- package/lib/domain-tool.js +2 -2
- package/lib/engines.js +96 -6
- package/lib/fetch.js +43 -3
- package/lib/index.d.ts +3 -1
- package/lib/index.js +30 -1
- package/lib/keys.d.ts +101 -0
- package/lib/keys.js +163 -0
- package/lib/parsers.d.ts +25 -0
- package/lib/parsers.js +139 -0
- package/lib/research.d.ts +158 -0
- package/lib/research.js +393 -0
- package/lib/verticals.d.ts +240 -3
- package/lib/verticals.js +1185 -78
- package/package.json +2 -1
- package/skills/dsh-web-search/SKILL.md +47 -0
package/CHANGELOG.md
CHANGED
|
@@ -1,5 +1,58 @@
|
|
|
1
1
|
# Changelog
|
|
2
2
|
|
|
3
|
+
## 0.16.0
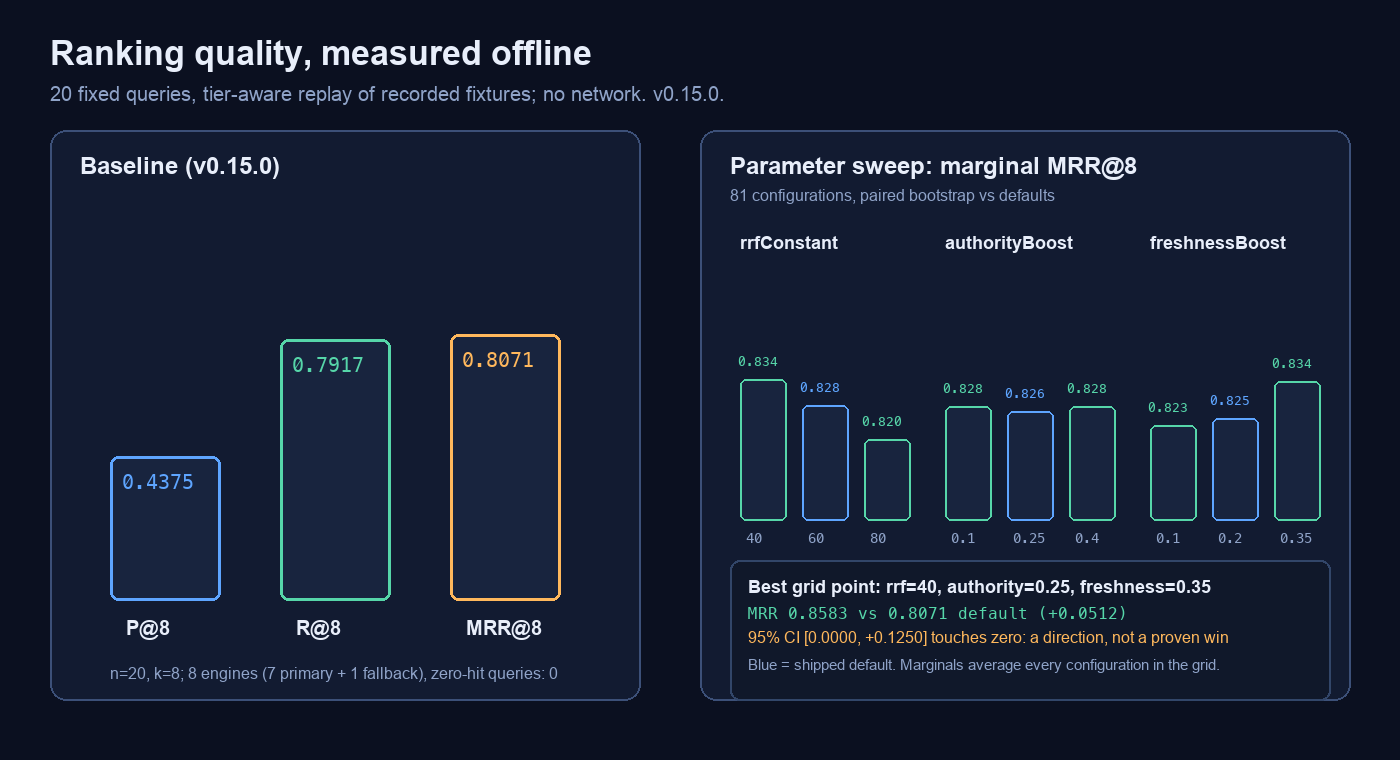
|
|
4
|
+
|
|
5
|
+
### Added
|
|
6
|
+
- **Key rotation.** `anysearchApiKey` now accepts several keys separated by
|
|
7
|
+
commas, spaces or newlines. They are used round-robin; a 401 retires the key
|
|
8
|
+
for a day, a 429 rests it for 60 s doubling to 30 min, a 403 for ten minutes,
|
|
9
|
+
and a success clears its strikes. A throttled or rejected key retries the same
|
|
10
|
+
request on the next key once, in both search and page extraction. Pools are
|
|
11
|
+
cached per Settings value, so editing the field starts clean.
|
|
12
|
+
- **Settings page polish.** A sticky jump bar scrolls to any of the five groups,
|
|
13
|
+
and a line under the title compares the installed version with npm's latest
|
|
14
|
+
(hidden when the registry is unreachable rather than guessed).
|
|
15
|
+
- **Portable skill.** `skills/dsh-web-search/SKILL.md` states when to search,
|
|
16
|
+
fetch, or use `research`, and how to cite; it can be copied into any harness
|
|
17
|
+
that reads `SKILL.md` from disk.
|
|
18
|
+
|
|
19
|
+
### Changed
|
|
20
|
+
- The AnySearch user agent reports `dsh-web-search/0.15`.
|
|
21
|
+
- Both READMEs document the rotation, the jump bar and the skill file.
|
|
22
|
+
|
|
23
|
+
## 0.15.0
|
|
24
|
+
|
|
25
|
+
### Added
|
|
26
|
+
- **`research` tool.** One call runs up to three searches, opens the leading
|
|
27
|
+
pages through the same fetch ladder as `web_fetch`, and returns an evidence
|
|
28
|
+
pack in which every excerpt sits under its URL. Pages that fail to load are
|
|
29
|
+
reported by URL and reason; the search rows still arrive. Registers as
|
|
30
|
+
`web_research` when another plugin owns the name, and uses its own
|
|
31
|
+
`http-proxy-research` fetch provider so it cannot disturb the host renderer
|
|
32
|
+
cache.
|
|
33
|
+
- **Two keyless engines.** `exa` (anonymous MCP semantic search) joins the
|
|
34
|
+
primary tier; `firecrawl` (key-free search API) ships as the fallback.
|
|
35
|
+
- **26 new `domain_search` sources** (34 in total): GitLab, Codeberg, Docker
|
|
36
|
+
Hub, Maven, NuGet, RubyGems, Packagist, pub.dev, Hugging Face models and
|
|
37
|
+
datasets, Open VSX, Terraform modules and providers, WordPress, JetBrains,
|
|
38
|
+
OpenAlex, Crossref, Europe PMC, UniProt, ClinicalTrials.gov, NVD, CoinGecko,
|
|
39
|
+
Internet Archive, Wikidata, Nominatim, GitHub issues. All are opt-in through
|
|
40
|
+
`sources`; the default remains the historical eight so GitHub's anonymous
|
|
41
|
+
10-requests-per-minute limit is not spent by every call.
|
|
42
|
+
|
|
43
|
+
### Changed
|
|
44
|
+
- The benchmark replay is **tier-aware**: a fallback engine only contributes
|
|
45
|
+
when every recorded primary came back empty, matching what `search()` does in
|
|
46
|
+
production. The baseline was restated accordingly (MRR@8 0.8071, P@8 0.4375,
|
|
47
|
+
zero-hit queries 0) and the 81-configuration sweep was re-run; numbers before
|
|
48
|
+
0.15.0 used a different replay and are not directly comparable.
|
|
49
|
+
- Engine tiers were decided by measurement on one recorded fixture set: previous
|
|
50
|
+
primaries 0.7738 MRR, +Exa 0.8071, +Firecrawl 0.7208, +both 0.7542.
|
|
51
|
+
- `SECURITY.md` lists the two new providers and all 34 vertical hosts.
|
|
52
|
+
|
|
53
|
+
### Fixed
|
|
54
|
+
- See 0.13.11: the 25 s fetch budget is per request instead of per plugin mount.
|
|
55
|
+
|
|
3
56
|
## 0.14.0
|
|
4
57
|
|
|
5
58
|
Distribution release. No runtime behaviour changed; the search and fetch paths are
|
package/README.md
CHANGED
|
@@ -9,8 +9,8 @@
|
|
|
9
9
|
|
|
10
10
|
<p align="center">
|
|
11
11
|
<a href="https://www.npmjs.com/package/@fffangchenghao/dsh-web-search"><img src="https://img.shields.io/npm/v/@fffangchenghao/dsh-web-search.svg" alt="npm version"></a>
|
|
12
|
-
<img src="https://img.shields.io/badge/tests-
|
|
13
|
-
<img src="https://img.shields.io/badge/engines-
|
|
12
|
+
<img src="https://img.shields.io/badge/tests-474%20passing-brightgreen" alt="tests">
|
|
13
|
+
<img src="https://img.shields.io/badge/engines-8%2C%20zero%20API%20key-brightgreen" alt="engines">
|
|
14
14
|
<img src="https://img.shields.io/badge/node-%3E%3D22.18-blue" alt="node">
|
|
15
15
|
<img src="https://img.shields.io/badge/dsh-%3E%3D0.2.1--rc.2%20%3C0.3.0-blueviolet" alt="dsh">
|
|
16
16
|
<a href="LICENSE"><img src="https://img.shields.io/badge/license-MIT-blue" alt="license"></a>
|
|
@@ -18,10 +18,10 @@
|
|
|
18
18
|
|
|
19
19
|
## Why this one
|
|
20
20
|
|
|
21
|
-
- **No API key,
|
|
21
|
+
- **No API key, eight engines.** AnySearch, CN Bing, DuckDuckGo HTML, www Bing, DuckDuckGo Lite and 360 Search are scraped directly; Exa joins the primary tier through its keyless MCP endpoint, and Firecrawl's search API is the measured fallback. The plugin works out of the box.
|
|
22
22
|
- **The ranking is measured, not asserted.** Cross-engine reciprocal-rank fusion with authority and freshness boosts, a 20-query offline benchmark, and an 81-configuration parameter sweep — the only search plugin here that publishes both its metric and its confidence intervals. See [How the ranking works](docs/rrf-ranking.md).
|
|
23
23
|
- **Fetching admits failure.** Binary documents and empty 200 responses are rejected by name (`SEARCH_UNSUPPORTED`, `SEARCH_EMPTY`) instead of being returned as noise; the direct → tunnel → render → extract ladder shares one 25 s budget and stops when there is no time left. The budget is per request — there is a regression test for exactly that.
|
|
24
|
-
- **
|
|
24
|
+
- **474 tests across 29 files**, a committed `lib/`, declared `engines.dsh` / `engines.node`, and a [SECURITY.md](SECURITY.md) that lists every process, host and file the plugin touches.
|
|
25
25
|
- **Bilingual documentation.** This README and [中文说明](README.zh-CN.md) are maintained side by side.
|
|
26
26
|
|
|
27
27
|
|
|
@@ -34,10 +34,10 @@ The web-search corner of the DSH plugin ecosystem is crowded, and most rivals ar
|
|
|
34
34
|
|
|
35
35
|
| | this plugin | [dsh-free-search](https://github.com/DDDMUC/dsh-free-search) | [modsearch](https://github.com/liustack/modsearch) | [anysearch-dsh](https://github.com/anysearch-team/anysearch-dsh) |
|
|
36
36
|
|---|---|---|---|---|
|
|
37
|
-
| Key-free engines |
|
|
38
|
-
| Dedicated vertical sources | 8 | 41 | — | — |
|
|
39
|
-
| Model-facing tools |
|
|
40
|
-
| Test suite |
|
|
37
|
+
| Key-free engines | 8 | ~30 | 7 channels (+X) | 1 official API |
|
|
38
|
+
| Dedicated vertical sources | 34 (8 on by default) | 41 | — | — |
|
|
39
|
+
| Model-facing tools | 6 | ~10 | 3 | 5 |
|
|
40
|
+
| Test suite | 29 files / 474 cases | none | 29 files | 6 files |
|
|
41
41
|
| Ranking benchmark | 20 queries + 81-config sweep | — | — | — |
|
|
42
42
|
| Store status | source contract satisfied, awaiting review | unlisted | no entry | blocked (review-required) |
|
|
43
43
|
|
|
@@ -55,7 +55,7 @@ Three things change for you:
|
|
|
55
55
|
- When a question is about a package, a repository or a paper, the model can ask the matching source directly instead of hoping a web search understands.
|
|
56
56
|
- You do not need a search API key, and you do not pay for search separately.
|
|
57
57
|
|
|
58
|
-
Under the hood it is one sentence too: the plugin registers two providers with the harness's `web` service — `bing` for search and `http-proxy` for fetching pages — and adds
|
|
58
|
+
Under the hood it is one sentence too: the plugin registers two providers with the harness's `web` service — `bing` for search and `http-proxy` for fetching pages — and adds four more tools: `domain_search` for packages, repositories, papers, Q&A and reference entries, `search_many` for several searches in one call, `read_page` for walking a long page in chunks, and `research` for turning a few searches into one cited evidence pack. These names come up again below.
|
|
59
59
|
|
|
60
60
|
## The problem it solves
|
|
61
61
|
|
|
@@ -138,7 +138,7 @@ What fetch hands back is the **article**, not the page's furniture: navigation,
|
|
|
138
138
|
|
|
139
139
|
`web_search` asks "what is on the open web". `domain_search` asks something narrower: "does this package exist, is this repository maintained, is there a paper on this, has someone answered this?"
|
|
140
140
|
|
|
141
|
-
It queries
|
|
141
|
+
It queries 34 public sources directly; eight are on by default: GitHub, npm, PyPI, arXiv, Wikipedia, Hacker News, Stack Exchange and crates.io. The other 26 — GitLab, Codeberg, Docker Hub, Maven, NuGet, RubyGems, Packagist, pub.dev, Hugging Face models and datasets, Open VSX, Terraform modules and providers, WordPress, JetBrains, OpenAlex, Crossref, Europe PMC, UniProt, ClinicalTrials.gov, NVD, CoinGecko, Internet Archive, Wikidata and Nominatim — are opt-in through the `sources` argument. Each offers a keyless public endpoint and returns structured records — title, link, snippet — rather than a page of search results.
|
|
142
142
|
|
|
143
143
|
Analogy: `web_search` is asking passers-by where the hardware shop is and getting directions; `domain_search` is walking to the counter and quoting a part number. Ask the right shop and the answer is short.
|
|
144
144
|
|
|
@@ -152,7 +152,7 @@ Analogy: `web_search` is asking passers-by where the hardware shop is and gettin
|
|
|
152
152
|
|
|
153
153
|
They team up well: use `domain_search` to find the package or paper, then `web_fetch` to open its homepage or README and read the detail.
|
|
154
154
|
|
|
155
|
-
|
|
155
|
+
Three more helpers sit beside them: **`search_many`**, **`read_page`** and **`research`**. When one question needs several distinct searches — one per candidate library, say — `search_many` runs one to five queries in a single call and keeps each query's results apart, so one failed query cannot empty the batch; when a page is too long for one fetch, `read_page` continues from where the previous chunk stopped; and when snippets are not enough but the model still has to decide which page to trust, `research` searches up to three queries, opens the leading pages and returns one evidence pack with a citation under every excerpt.
|
|
156
156
|
|
|
157
157
|
### Reading a long page in chunks (read_page): when one pass is not enough
|
|
158
158
|
|
|
@@ -225,8 +225,8 @@ Why does a code change need a restart? Because Node.js evaluates a module once p
|
|
|
225
225
|
Each line is the plain version first, the technical note second. The technical note is safe to skip.
|
|
226
226
|
|
|
227
227
|
1. **Ask several search engines at once.**
|
|
228
|
-
|
|
229
|
-
*Technical: `tier: primary` and `tier: fallback` in `HOSTS`; 360 is a fallback because of its verification wall; the three `viaProxy` engines (`ddg-html`, `www.bing`, `ddg-lite`) only join when a proxy is detected.*
|
|
228
|
+
Four primaries run together (AnySearch, DuckDuckGo HTML, Bing China, Exa). If none of them returns anything, Bing International, 360, DuckDuckGo Lite and Firecrawl step in. Eight sources in total.
|
|
229
|
+
*Technical: `tier: primary` and `tier: fallback` in `HOSTS`; 360 is a fallback because of its verification wall; the three `viaProxy` engines (`ddg-html`, `www.bing`, `ddg-lite`, `exa`, `firecrawl`) only join when a proxy is detected.*
|
|
230
230
|
|
|
231
231
|
2. **No API key at all.**
|
|
232
232
|
AnySearch answers anonymously; the domestic engines and DuckDuckGo are scraped from public result pages. No sign-up needed.
|
|
@@ -289,8 +289,8 @@ Each line is the plain version first, the technical note second. The technical n
|
|
|
289
289
|
*Technical: `looksLikeBotWall` checks for `qcaptcha`, `访问异常`, `unusual traffic`, `verify you are human` and `安全验证` before parsing; a hit returns `SEARCH_BLOCKED` (retryable and subject to cooldown) instead of an empty list. `so` moved from `tier: primary` to `tier: fallback`, so it is tried only when no primary engine returned anything and no longer slows every search. Measured: querying that engine alone now returns the failure `so: bot verification page`, not zero results.*
|
|
290
290
|
|
|
291
291
|
17. **Packages, repositories, papers and Q&A are one hop away.**
|
|
292
|
-
For "is this npm package still maintained?" or "is there a paper on RAG?", the model can call `domain_search` against
|
|
293
|
-
*Technical:
|
|
292
|
+
For "is this npm package still maintained?" or "is there a paper on RAG?", the model can call `domain_search` against 34 dedicated sources instead of hoping a web search finds them.
|
|
293
|
+
*Technical: 34 keyless sources, eight on by default — `github`, `npm`, `pypi`, `arxiv`, `wikipedia`, `hn` (Hacker News), `stackexchange`, `crates` (crates.io); the other 26 are reachable through `sources`. Arguments `query` (required), `sources` (optional array, default = the default eight), `limit` (optional, default 5, capped at 20). Each source has its own deadline (8000 ms by default), one failure never affects the others, and the failed names come back in `failures`. Measured with `react` at limit 3: github 3, npm 3, pypi 1, arxiv 3, wikipedia 3, hn 3, stackexchange 3, crates 3. Known limits: PyPI has no public search API, so it matches the **exact package name** taken from the first word of the query; Wikipedia searches one language only (`zh` for CJK, otherwise `en`). A host without `ctx.tools` does not register the tool and the rest of the plugin works as usual.*
|
|
294
294
|
|
|
295
295
|
18. **You can look only at recently published results.**
|
|
296
296
|
Choose "last 24 hours / 7 days / 30 days / 1 year" in Settings and only results inside that window stay — useful for news and releases.
|
|
@@ -306,7 +306,11 @@ Each line is the plain version first, the technical note second. The technical n
|
|
|
306
306
|
|
|
307
307
|
21. **Search quality has a repeatable benchmark.**
|
|
308
308
|
Ranking changes are no longer judged by feel: a fixed set of 20 queries produces the same scores every time.
|
|
309
|
-
*Technical: `bench/` holds 20 queries (10 Chinese, 10 English), five in each of docs / release / package / news, each annotated with 1–3 expected domains. `node scripts/bench.mjs` replays recorded fixtures offline, never touches the network, and prints precision@8, recall@8, MRR@8 plus each engine's contribution; `--record` re-records live (1.5 s between queries) to refresh the fixtures; `--json` gives machine-readable output for version comparisons, and past results live in `bench/results/`. Baseline for 0.
|
|
309
|
+
*Technical: `bench/` holds 20 queries (10 Chinese, 10 English), five in each of docs / release / package / news, each annotated with 1–3 expected domains. `node scripts/bench.mjs` replays recorded fixtures offline, never touches the network, and prints precision@8, recall@8, MRR@8 plus each engine's contribution; `--record` re-records live (1.5 s between queries) to refresh the fixtures; `--json` gives machine-readable output for version comparisons, and past results live in `bench/results/`. Baseline for 0.15.0 (tier-aware replay, so the recorded fallback engines only count when production would run them): P@8 `0.4375`, R@8 `0.7917`, MRR@8 `0.8071`; Chinese `0.4000 / 0.8167 / 0.7976`, English `0.4750 / 0.7667 / 0.8167`. The controlled experiments and known gaps are in the appendix.*
|
|
310
|
+
|
|
311
|
+
22. **Research, in one call.**
|
|
312
|
+
For "what do the official docs and two other sources actually say about X", `research` runs up to three searches, opens the leading pages through the same fetch ladder, and returns one evidence pack in which every excerpt sits under its URL. A page that will not load is reported by URL and reason instead of aborting the pack.
|
|
313
|
+
*Technical: `query` (required), `queries` (up to three extra), `maxSources` (1–5, default 3); one 45 s budget for the whole call, three page fetches in flight, and a page fetch is not started with less than 2.5 s left. The tool registers as `web_research` if another plugin owns `research`. Its fetch side uses its own `http-proxy-research` provider so it cannot disturb the host `web_fetch` renderer cache. The search side is the same `web_search` path, cache and cooling included.*
|
|
310
314
|
|
|
311
315
|
> **What 0.13.0 fixes (a real defect)**: from some networks 360 (`so`) returns a verification page — a 302 to the qcaptcha "unexpected access" page — while the HTTP status is still 200. The old code read that as "zero results" and swallowed it: the engine effectively disappeared and its cooldown never fired. Such pages now fail as `SEARCH_BLOCKED`, and 360 has been demoted to the **fallback tier** (tried only when the primary engines are empty), so it no longer slows every search. Measured: querying that engine alone now returns the failure `so: bot verification page` instead of zero results.
|
|
312
316
|
|
|
@@ -413,7 +417,7 @@ If the Settings card appears but search still fails, start with [docs/troublesho
|
|
|
413
417
|
|
|
414
418
|
## Using the Settings page
|
|
415
419
|
|
|
416
|
-
Open Settings → "Web search (Bing)". Twenty-six controls, arranged in five groups. Each group owns one kind of decision:
|
|
420
|
+
Open Settings → "Web search (Bing)". Twenty-six controls, arranged in five groups. A sticky jump bar at the top scrolls to any group, and a line under the title compares the installed version with the latest one on npm (it stays hidden when the registry cannot be reached, so it never guesses). Each group owns one kind of decision:
|
|
417
421
|
|
|
418
422
|
| Group | Controls | What it decides |
|
|
419
423
|
| --- | --- | --- |
|
|
@@ -431,7 +435,7 @@ Open Settings → "Web search (Bing)". Twenty-six controls, arranged in five gro
|
|
|
431
435
|
| How long to wait | `wait` | `auto` | `auto` follows the query language; `all` waits for everyone; `fast` takes the first answer |
|
|
432
436
|
| Wait limit (ms) | `timeoutMs` | `15000` | Per-engine deadline, at least 500 |
|
|
433
437
|
| Proxy (relay) | `proxy` | empty (detect) | e.g. `http://127.0.0.1:7890`; empty reads the environment, then the system proxy |
|
|
434
|
-
| AnySearch key | `anysearchApiKey` | empty (anonymous) | Optional. Sent only to `api.anysearch.com`; raises limits and unlocks page extraction |
|
|
438
|
+
| AnySearch key | `anysearchApiKey` | empty (anonymous) | Optional. Sent only to `api.anysearch.com`; raises limits and unlocks page extraction. Several keys may be comma-separated and are rotated, with a throttled or rejected one resting automatically |
|
|
435
439
|
| Vertical domain | `anysearchDomain` | empty (general) | Typical values: `finance` / `academic` / `security` / `legal` / `code`; a dotted value such as `finance.us_stock` selects a sub-domain |
|
|
436
440
|
|
|
437
441
|
### Results and ranking (7)
|
|
@@ -450,7 +454,7 @@ Open Settings → "Web search (Bing)". Twenty-six controls, arranged in five gro
|
|
|
450
454
|
|
|
451
455
|
| Control | Key | Default | Plain meaning |
|
|
452
456
|
| --- | --- | --- | --- |
|
|
453
|
-
| Sources | `domainSources` |
|
|
457
|
+
| Sources | `domainSources` | the default eight | Keep only some of the 34 sources (e.g. `github,npm`), comma-separated; empty means the default eight. `sources` on the tool call can name any of the 34 |
|
|
454
458
|
| Results per source | `domainLimit` | `5` | How many results `domain_search` takes from each source, 1–20 |
|
|
455
459
|
| Deadline per source | `domainTimeoutMs` | `8000` | Per-source deadline in ms, at least 500; raise it to 15000 on a slow network |
|
|
456
460
|
|
|
@@ -482,7 +486,7 @@ Only these situations are worth changing:
|
|
|
482
486
|
|
|
483
487
|
- **Your proxy is not detected**: put the local proxy address in `proxy`, for example `http://127.0.0.1:7890`. HTTP proxies only — swap `socks5://` for the client's HTTP/mixed port.
|
|
484
488
|
- **You want AnySearch's higher limits or page extraction**: fill in `anysearchApiKey`, and add `anysearchDomain` if you want one vertical index.
|
|
485
|
-
- **You only want `domain_search` to hit a few sources**: narrow `domainSources` to a set such as `github,npm`; empty means
|
|
489
|
+
- **You only want `domain_search` to hit a few sources**: narrow `domainSources` to a set such as `github,npm`; empty means the default eight. The other 26 (e.g. `dockerhub,openalex`) are opt-in through `sources`.
|
|
486
490
|
- **A fetched page is cut too early, or you want plain text**: raise `fetchMaxLength` to `50000`, or set `fetchFormat` to `text`; if that is still not enough and you need the other half, use `read_page` (item 11 above).
|
|
487
491
|
- **A fetched page is an empty shell**: first check whether its body is built by JavaScript. If Playwright is installed, leave `renderJs` on `auto` and reload the plugin, then retry; without it, try another source (a print view, a static mirror, the site's API). Raising `fetchMaxLength` only helps when text was fetched but cut at the tail — it cannot turn a shell into an article.
|
|
488
492
|
- **Browser rendering is too slow**: set `renderJs` to `off`, or lower `renderTimeoutMs`.
|
|
@@ -494,6 +498,10 @@ Three things to keep in mind:
|
|
|
494
498
|
- **Ranking changes can be hidden by the cache**: the cache key holds `lead|wait|limit|engine set|time window|query`, not the ranking knobs. Ask the same question within ten minutes and you get the old order — and with persistence on, restarting DSH does not clear it. Rephrase it, or wait ten minutes. Changing the window changes the key, so an old entry cannot interfere.
|
|
495
499
|
- **`web_fetch` cannot continue from the middle**: it makes one request per URL, so if the tail is missing, raise `fetchMaxLength` or use `read_page` to continue from the break; fetching a narrower page still costs the least context.
|
|
496
500
|
|
|
501
|
+
## Using the skill from another harness
|
|
502
|
+
|
|
503
|
+
`skills/dsh-web-search/SKILL.md` is a plain skill file: it states when to search, when to open pages, when to use `research`, and how to cite. Copy the folder into any harness that reads `SKILL.md` files from disk (for example `~/.claude/skills/`). The plugin itself is a DSH plugin, so another harness still needs its own search and fetch tools; the file is the part that transfers.
|
|
504
|
+
|
|
497
505
|
## FAQ
|
|
498
506
|
|
|
499
507
|
### Do I need an API key?
|
|
@@ -559,7 +567,7 @@ No. `package.json` does not list Playwright, and the plugin never downloads or i
|
|
|
559
567
|
|
|
560
568
|
### How do you know search quality improved?
|
|
561
569
|
|
|
562
|
-
From the fixed query set in `bench/`, not from intuition. There are 20 queries (10 Chinese, 10 English), five in each of docs / release / package / news, each annotated with 1–3 expected domains. `node scripts/bench.mjs` replays recorded fixtures offline and prints P@8 / R@8 / MRR@8. The 0.
|
|
570
|
+
From the fixed query set in `bench/`, not from intuition. There are 20 queries (10 Chinese, 10 English), five in each of docs / release / package / news, each annotated with 1–3 expected domains. `node scripts/bench.mjs` replays recorded fixtures offline and prints P@8 / R@8 / MRR@8. The 0.15.0 baseline (tier-aware replay) is **0.4375 / 0.7917 / 0.8071**; Chinese 0.4000 / 0.8167 / 0.7976, English 0.4750 / 0.7667 / 0.8167. Run it before and after a ranking change and the direction is a number. Twenty queries are not statistical significance; news recall is only 0.467 and the per-query table still prints every miss — the appendix says so.
|
|
563
571
|
|
|
564
572
|
### Why do the results differ from what I get searching by hand?
|
|
565
573
|
|
|
@@ -740,12 +748,12 @@ domain_search call
|
|
|
740
748
|
→ read config (domainSources / domainLimit / domainTimeoutMs, re-read per call)
|
|
741
749
|
→ resolve the proxy (config → environment → system proxy)
|
|
742
750
|
→ sources default to the enabled set; limit clamped to 1–20, default domainLimit
|
|
743
|
-
→ eight sources in parallel GET, each with its own deadline (domainTimeoutMs)
|
|
751
|
+
→ the default eight sources in parallel GET, each with its own deadline (domainTimeoutMs); 26 more are opt-in
|
|
744
752
|
→ interleave by source, slice to limit
|
|
745
753
|
→ return { sources, failures, truncated }
|
|
746
754
|
```
|
|
747
755
|
|
|
748
|
-
All
|
|
756
|
+
All 34 are public, keyless endpoints. The default eight are GitHub repository search, the npm registry, PyPI, arXiv Atom, the Wikipedia API, Hacker News (Algolia), the Stack Exchange API and crates.io; the opt-in 26 cover package registries (Docker Hub, Maven, NuGet, RubyGems, Packagist, pub.dev), code hosts (GitLab, Codeberg, GitHub issues), models and datasets (Hugging Face), editors (Open VSX, JetBrains), infrastructure (Terraform modules and providers, WordPress), and data sources (OpenAlex, Crossref, Europe PMC, UniProt, ClinicalTrials.gov, NVD, CoinGecko, Internet Archive, Wikidata, Nominatim). Each has its own parser; when upstream markup drifts, that source degrades to an empty answer instead of failing the run. A timeout, a 5xx or an unreachable host on one source adds one `failures` line and leaves the others answering. GitHub and crates.io require a `User-Agent`, which every request carries.
|
|
749
757
|
|
|
750
758
|
Two sources need a word of their own:
|
|
751
759
|
|
|
@@ -807,28 +815,28 @@ Measured on `https://docs.python.org/3/library/asyncio-task.html`: starting at `
|
|
|
807
815
|
|
|
808
816
|
Metrics: P@8 = matched rows in the top 8 ÷ 8 (fixed denominator; a short list is not excused); R@8 = distinct expected domains found in the top 8 ÷ all expected domains; MRR@8 = the mean reciprocal rank of the first match over 20 queries, with a miss scoring 0. Domain matching is one-way from subdomain to parent: `docs.python.org` matches expected `python.org`, but the reverse does not.
|
|
809
817
|
|
|
810
|
-
**0.
|
|
818
|
+
**0.15.0 baseline** (tier-aware replay):
|
|
811
819
|
|
|
812
820
|
| Scope | P@8 | R@8 | MRR@8 |
|
|
813
821
|
| --- | --- | --- | --- |
|
|
814
|
-
| All 20 queries | 0.
|
|
815
|
-
| Chinese (10) | 0.
|
|
816
|
-
| English (10) | 0.
|
|
822
|
+
| All 20 queries | 0.4375 | 0.7917 | 0.8071 |
|
|
823
|
+
| Chinese (10) | 0.4000 | 0.8167 | 0.7976 |
|
|
824
|
+
| English (10) | 0.4750 | 0.7667 | 0.8167 |
|
|
817
825
|
|
|
818
826
|
**Controlled experiments** (same fixtures, one knob changed):
|
|
819
827
|
|
|
820
828
|
| Configuration | P@8 | R@8 | MRR@8 |
|
|
821
829
|
| --- | --- | --- | --- |
|
|
822
|
-
| Default (rrf 60, AnySearch weight 2) | 0.
|
|
823
|
-
| AnySearch weight 1 | 0.
|
|
824
|
-
| rrf 40 | 0.
|
|
825
|
-
| rrf 120 | 0.
|
|
826
|
-
| Authority domains off (authority 0) | 0.
|
|
830
|
+
| Default (rrf 60, AnySearch weight 2) | 0.4375 | 0.7917 | 0.8071 |
|
|
831
|
+
| AnySearch weight 1 | 0.4625 | 0.7917 | 0.8167 |
|
|
832
|
+
| rrf 40 | 0.4313 | 0.7833 | 0.8333 |
|
|
833
|
+
| rrf 120 | 0.4375 | 0.7917 | 0.8167 |
|
|
834
|
+
| Authority domains off (authority 0) | 0.3438 | 0.7917 | 0.8071 |
|
|
827
835
|
|
|
828
836
|
Conclusions:
|
|
829
837
|
|
|
830
|
-
-
|
|
831
|
-
- Authority weighting
|
|
838
|
+
- No single-knob change separates from the default on this corpus. `rrf 40` raises MRR from 0.8071 to 0.8333 but lowers P@8 from 0.4375 to 0.4313 and introduces one zero-hit query; `rrf 120` and weight 1 raise MRR by about 0.01 with no P@8 loss, but the 81-configuration sweep puts every one of those differences inside a paired-bootstrap interval that touches zero. The defaults therefore did not change.
|
|
839
|
+
- Authority weighting reorders ties rather than finding new rows: turning it off drops P@8 from 0.4375 to 0.3438 while MRR and R@8 stay put. It exists to put `kubernetes.io` above an SEO page at the same rank, and that is what the numbers show.
|
|
832
840
|
- AnySearch at weight 2 takes 76% of the top-8 slots (122 of 160 rows); at weight 1, P@8 rises to 0.3875 but MRR falls to 0.7433, so heavier and lighter both cost something. These settings differ by only 1–4 hits on 20 queries, so the defaults stay.
|
|
833
841
|
- Known gaps: news recall is only 0.3667 (about 0.367); `zh-linux-612` has zero hits (AWS docs and a runoob tutorial outrank kernel.org and LWN); and 20 queries carry no statistical significance. The numbers show direction, not a claim that quality has arrived.
|
|
834
842
|
|
|
@@ -899,7 +907,7 @@ npm run build # compile src/ to lib/
|
|
|
899
907
|
npm run check # typecheck + tests
|
|
900
908
|
```
|
|
901
909
|
|
|
902
|
-
The suite runs offline by default and passes in full; the one live paging check is skipped unless `READ_PAGE_LIVE=1`: parser tests replay captured fixtures from `test/fixtures/` (normal and empty responses for
|
|
910
|
+
The suite runs offline by default and passes in full; the one live paging check is skipped unless `READ_PAGE_LIVE=1`: parser tests replay captured fixtures from `test/fixtures/` (normal and empty responses for the default eight and the 26 opt-in sources), transport tests open no sockets, proxy tests cover `parseProxy`, `proxyFromEnv` and the pure response framer, time-window tests pin the date with an injected `now`, and the newer suites cover Markdown extraction (`markdown.test.ts`), batch search (`search-many.test.ts`), chunked reading (`read-page.test.ts`), the disk snapshot (`cache-persist.test.ts`), optional JS rendering (`render-js.test.ts`) and benchmark scoring/replay (`bench-metrics.test.ts`, `bench-replay.test.ts`). One live-network test in `read-page.test.ts` is skipped by default; run it with `READ_PAGE_LIVE=1 node --test test/read-page.test.ts`.
|
|
903
911
|
|
|
904
912
|
CI (`.github/workflows/ci.yml`) runs `npm ci`, `npm run typecheck`, `npm test` and `npm run build` on Node 24 for Ubuntu and macOS, then checks that the build emitted `lib/index.js` and `lib/index.d.ts` and that both `apply` and `Config` import.
|
|
905
913
|
|
package/README.zh-CN.md
CHANGED
|
@@ -9,8 +9,8 @@
|
|
|
9
9
|
|
|
10
10
|
<p align="center">
|
|
11
11
|
<a href="https://www.npmjs.com/package/@fffangchenghao/dsh-web-search"><img src="https://img.shields.io/npm/v/@fffangchenghao/dsh-web-search.svg" alt="npm 版本"></a>
|
|
12
|
-
<img src="https://img.shields.io/badge/tests-
|
|
13
|
-
<img src="https://img.shields.io/badge/engines-
|
|
12
|
+
<img src="https://img.shields.io/badge/tests-474%20passing-brightgreen" alt="测试">
|
|
13
|
+
<img src="https://img.shields.io/badge/engines-8%2C%20zero%20API%20key-brightgreen" alt="引擎">
|
|
14
14
|
<img src="https://img.shields.io/badge/node-%3E%3D22.18-blue" alt="node">
|
|
15
15
|
<img src="https://img.shields.io/badge/dsh-%3E%3D0.2.1--rc.2%20%3C0.3.0-blueviolet" alt="dsh">
|
|
16
16
|
<a href="LICENSE"><img src="https://img.shields.io/badge/license-MIT-blue" alt="许可证"></a>
|
|
@@ -18,10 +18,10 @@
|
|
|
18
18
|
|
|
19
19
|
## 为什么选这个
|
|
20
20
|
|
|
21
|
-
- **不要 API key
|
|
21
|
+
- **不要 API key,八个引擎。** AnySearch、必应中国、DuckDuckGo HTML、必应国际、DuckDuckGo Lite、360 搜索直接抓取;Exa 走它的免密钥 MCP 通道加入主引擎,Firecrawl 的搜索 API 作为实测后的兜底。装好就能用。
|
|
22
22
|
- **排序是量出来的,不是写出来的。** 跨引擎 RRF 融合,叠加权威度与时效加权;20 条离线基准 + 81 组参数扫描,是这类插件里唯一同时公开指标和置信区间的。方法见 [排序是怎么做的](docs/rrf-ranking.md)。
|
|
23
23
|
- **抓取会承认失败。** 二进制文档和「200 但正文为空」会被明确拒绝(`SEARCH_UNSUPPORTED`、`SEARCH_EMPTY`),而不是当噪音返回;direct → tunnel → render → extract 四级阶梯共享 25 秒预算,预算不足就不再起新的一级。预算是「每次请求」而不是「插件启动时」,这点有回归测试守着。
|
|
24
|
-
- **
|
|
24
|
+
- **29 个测试文件、474 个用例**,`lib/` 产物入库,声明了 `engines.dsh` / `engines.node`,[SECURITY.md](SECURITY.md) 逐项列出插件会碰的进程、主机和文件。
|
|
25
25
|
- **双语文档。** 本文件和 [English README](README.md) 同步维护。
|
|
26
26
|
|
|
27
27
|

|
|
@@ -34,10 +34,10 @@ DSH 插件生态里的「联网搜索」这一块已经很挤,大多数竞品
|
|
|
34
34
|
|
|
35
35
|
| | 本插件 | [dsh-free-search](https://github.com/DDDMUC/dsh-free-search) | [modsearch](https://github.com/liustack/modsearch) | [anysearch-dsh](https://github.com/anysearch-team/anysearch-dsh) |
|
|
36
36
|
|---|---|---|---|---|
|
|
37
|
-
| 免 key 引擎 |
|
|
38
|
-
| 专门数据源 | 8
|
|
39
|
-
| 面向模型的工具 |
|
|
40
|
-
| 测试 |
|
|
37
|
+
| 免 key 引擎 | 8 | ~30 | 7 条通道(含 X) | 1 个官方 API |
|
|
38
|
+
| 专门数据源 | 34(默认开 8 个)| 41 | — | — |
|
|
39
|
+
| 面向模型的工具 | 6 | ~10 | 3 | 5 |
|
|
40
|
+
| 测试 | 29 文件 / 474 用例 | 无 | 29 文件 | 6 文件 |
|
|
41
41
|
| 排序基准 | 20 查询 + 81 组扫描 | — | — | — |
|
|
42
42
|
| 商店状态 | 源码契约已满足,待复核 | unlisted | 无条目 | blocked(review-required) |
|
|
43
43
|
|
|
@@ -55,7 +55,7 @@ DSH 插件生态里的「联网搜索」这一块已经很挤,大多数竞品
|
|
|
55
55
|
- 问包、仓库、论文、问答时,模型能直接查对应的数据源,不用拿网页搜索去碰运气。
|
|
56
56
|
- 你不需要准备搜索 API key,也不需要为搜索单独付费。
|
|
57
57
|
|
|
58
|
-
说白了就一句话:它给 Harness 的 `web` 服务插上两个「提供方」——搜索用 `bing`,抓网页用 `http-proxy
|
|
58
|
+
说白了就一句话:它给 Harness 的 `web` 服务插上两个「提供方」——搜索用 `bing`,抓网页用 `http-proxy`;再给模型加四个工具:`domain_search` 专查包、代码仓库、论文、问答和百科,`search_many` 一次跑多条查询,`read_page` 把长页面分段接着读,`research` 把几次搜索变成一份带引用的证据包。这几个名字后面会反复出现,先混个脸熟就行。
|
|
59
59
|
|
|
60
60
|
## 它解决什么问题
|
|
61
61
|
|
|
@@ -138,7 +138,7 @@ fetch 拿回来的则是**正文**,不是页面的装修:导航、广告、
|
|
|
138
138
|
|
|
139
139
|
`web_search` 问的是「公开网页上有什么」。`domain_search` 问的是更窄的一件事:「这个包存在吗、这个仓库还维护吗、有没有这篇论文、这个问题有人答过吗」。
|
|
140
140
|
|
|
141
|
-
|
|
141
|
+
它直接问 34 家公开数据源,其中 8 家默认开启:GitHub、npm、PyPI、arXiv、Wikipedia、Hacker News、Stack Exchange、crates.io。另外 26 家——GitLab、Codeberg、Docker Hub、Maven、NuGet、RubyGems、Packagist、pub.dev、Hugging Face 模型与数据集、Open VSX、Terraform 模块与 provider、WordPress、JetBrains、OpenAlex、Crossref、Europe PMC、UniProt、ClinicalTrials.gov、NVD、CoinGecko、Internet Archive、Wikidata、Nominatim——通过 `sources` 参数按需开启。每家都提供不用密钥的公开接口,拿回的是结构化条目(标题、链接、摘要),而不是一张搜索结果页。
|
|
142
142
|
|
|
143
143
|
类比:`web_search` 像在街上问路人「这附近哪有五金店」,得到的是各种指路;`domain_search` 像直接走到五金店柜台报型号——问对了店,回答就干脆。
|
|
144
144
|
|
|
@@ -152,7 +152,7 @@ fetch 拿回来的则是**正文**,不是页面的装修:导航、广告、
|
|
|
152
152
|
|
|
153
153
|
两个一起用最顺:先用 `domain_search` 找到包或论文,再用 `web_fetch` 打开它的主页或 README 读细节。
|
|
154
154
|
|
|
155
|
-
|
|
155
|
+
旁边还有三个帮手:**`search_many`**、**`read_page`** 和 **`research`**。当一个问题需要分别查好几件事——比如每个候选库各查一次——`search_many` 一次接住 1–5 条查询,把每条查询的结果分开返回,某一条失败也不会拖垮整批;`read_page` 则在网页长到一次抓不完时,接着上一次的位置继续往下读;`research` 则在摘要不够、又必须决定该信哪一页时,先跑最多三条查询,再打开靠前的页面,返回一份每个摘录都带出处的证据包。
|
|
156
156
|
|
|
157
157
|
### 分段读长页(read_page):一次读不完,就接着读
|
|
158
158
|
|
|
@@ -289,8 +289,8 @@ Harness 里有个叫 `web` 的**服务**,它自己不会搜索,只负责「
|
|
|
289
289
|
*技术补充:`looksLikeBotWall` 在解析前检查 `qcaptcha`、`访问异常`、`unusual traffic`、`verify you are human`、`安全验证` 等标记;命中就返回 `SEARCH_BLOCKED`(可重试、参与冷却),而不是空列表。`so` 的 `tier` 从 `primary` 改为 `fallback`,只在主引擎一条都没给时才尝试,不再拖慢每次搜索。实测单独查该引擎现在返回失败 `so: bot verification page`,而不是 0 条。*
|
|
290
290
|
|
|
291
291
|
17. **包、仓库、论文、问答能直接查。**
|
|
292
|
-
问「这个 npm 包还维护吗」「有没有讲 RAG 的论文」时,模型可以用 `domain_search`
|
|
293
|
-
|
|
292
|
+
问「这个 npm 包还维护吗」「有没有讲 RAG 的论文」时,模型可以用 `domain_search` 直接查 34 个专门的数据源,而不是拿网页搜索碰运气。
|
|
293
|
+
*技术补充:34 个免密钥源,默认开 8 个——`github`、`npm`、`pypi`、`arxiv`、`wikipedia`、`hn`(Hacker News)、`stackexchange`、`crates`(crates.io);其余 26 个通过 `sources` 指定。参数 `query`(必填)、`sources`(可选数组,缺省 = 默认 8 个)、`limit`(可选,默认 5、上限 20)。每个源独立超时(默认 8000 毫秒),单源失败不影响其他源,失败名单从 `failures` 返回。实测 `react`、limit 3 时 github/npm/arxiv/wikipedia/hn/stackexchange/crates 各 3 条、pypi 1 条。已知限制:PyPI 没有公开搜索 API,只按**精确包名**查(取查询的第一个词);Wikipedia 按提问语言只查单一语言(含中日韩字符查 `zh`,否则查 `en`)。宿主没有 `ctx.tools` 服务时,工具不注册,插件其余功能照常。*
|
|
294
294
|
|
|
295
295
|
18. **可以只看最近发布的结果。**
|
|
296
296
|
设置里选「最近 24 小时 / 7 天 / 30 天 / 1 年」,就只留窗口内发布的结果,适合追新闻和版本更新。
|
|
@@ -306,7 +306,11 @@ Harness 里有个叫 `web` 的**服务**,它自己不会搜索,只负责「
|
|
|
306
306
|
|
|
307
307
|
21. **搜索质量有了可重复的基准。**
|
|
308
308
|
改排序不再靠感觉:仓库里有一组固定的 20 条查询,每次改完都能跑出同一套分数。
|
|
309
|
-
*技术补充:`bench/` 下 20 条查询(中文 10、英文 10),四类各 5 条(文档 / 版本发布 / 包与库 / 新闻),每条标注 1–3 个期望域名。`node scripts/bench.mjs` 离线读夹具重放,不联网,输出 precision@8、recall@8、MRR@8 与每个引擎的贡献;`--record` 联网重新录制(每条限速 1.5 秒),用于更新夹具;`--json` 输出机器可读结果,便于版本间对比,历史结果存在 `bench/results/`。当前基线(0.
|
|
309
|
+
*技术补充:`bench/` 下 20 条查询(中文 10、英文 10),四类各 5 条(文档 / 版本发布 / 包与库 / 新闻),每条标注 1–3 个期望域名。`node scripts/bench.mjs` 离线读夹具重放,不联网,输出 precision@8、recall@8、MRR@8 与每个引擎的贡献;`--record` 联网重新录制(每条限速 1.5 秒),用于更新夹具;`--json` 输出机器可读结果,便于版本间对比,历史结果存在 `bench/results/`。当前基线(0.15.0,按 tier 回放):P@8 `0.4375`、R@8 `0.7917`、MRR@8 `0.8071`;中文 `0.4000 / 0.8167 / 0.7976`,英文 `0.4750 / 0.7667 / 0.8167`。对照实验和已知短板见附录。*
|
|
310
|
+
|
|
311
|
+
22. **一次调用完成小调研。**
|
|
312
|
+
问「官方文档和另外两个来源到底怎么说」时,`research` 先跑最多三条查询,再用与 `web_fetch` 相同的抓取阶梯打开靠前的页面,最后返回一份证据包:每段摘录下面就是它的 URL。打不开的页面按 URL 和原因列出,不会让整份证据包失败。
|
|
313
|
+
*技术补充:参数 `query`(必填)、`queries`(最多再加三条)、`maxSources`(1–5,默认 3);整次调用共享 45 秒预算,最多 3 个页面并发抓,剩余不足 2.5 秒就不再开新页。若 `research` 名字已被别的插件占用,则注册为 `web_research`。抓取侧使用独立的 `http-proxy-research` provider,不会干扰宿主的 `web_fetch` 渲染缓存;搜索侧复用 `web_search` 的同一条链路、缓存与冷却。*
|
|
310
314
|
|
|
311
315
|
> **0.13.0 修了什么(一个真实缺陷)**:360(`so`)从部分网络访问会返回验证码页(302 到 qcaptcha 的「访问异常页面」),但 HTTP 状态是 200。旧代码把它当作「0 条结果」静默吞掉:引擎等于消失,冷却也没触发。现在识别到验证码/人机校验页面就报 `SEARCH_BLOCKED` 失败,并把 360 降为**兜底档**(主引擎都空时才尝试),不再拖慢每次搜索。实测:单独查该引擎现在返回失败 `so: bot verification page`,而不是 0 条。
|
|
312
316
|
|
|
@@ -413,7 +417,7 @@ pnpm install
|
|
|
413
417
|
|
|
414
418
|
## 设置页怎么用
|
|
415
419
|
|
|
416
|
-
打开 设置 → 「网页搜索(Bing)」。页面上一共 26
|
|
420
|
+
打开 设置 → 「网页搜索(Bing)」。页面上一共 26 个控件,按五组排列。顶部有一条随滚动固定的跳转栏,点组名直接跳过去;标题下还会拿当前版本和 npm 上的最新版比一下(连不上 npm 时这行不显示,不会瞎猜)。每组只管一类事:
|
|
417
421
|
|
|
418
422
|
| 组 | 控件数 | 这组管什么 |
|
|
419
423
|
| --- | --- | --- |
|
|
@@ -431,7 +435,7 @@ pnpm install
|
|
|
431
435
|
| 等多久 | `wait` | `auto` | `auto` 按提问语言等;`all` 等全部;`fast` 谁先回用谁 |
|
|
432
436
|
| 等待上限(毫秒) | `timeoutMs` | `15000` | 单个引擎最多等多久,最小 500 |
|
|
433
437
|
| 代理(中转站) | `proxy` | 空(自动探测) | 如 `http://127.0.0.1:7890`;留空先读环境变量再读系统代理 |
|
|
434
|
-
| AnySearch 通行证 | `anysearchApiKey` | 空(匿名) | 可选项。只发给 `api.anysearch.com
|
|
438
|
+
| AnySearch 通行证 | `anysearchApiKey` | 空(匿名) | 可选项。只发给 `api.anysearch.com`,用于提高额度、解锁正文抽取。可以用逗号分隔填多个 key,插件轮流使用;某个被限流或拒绝会自动休息 |
|
|
435
439
|
| 专业领域 | `anysearchDomain` | 空(通用) | 常见取值 `finance` / `academic` / `security` / `legal` / `code`,可带子域如 `finance.us_stock` |
|
|
436
440
|
|
|
437
441
|
### 结果与排序(7 个)
|
|
@@ -450,7 +454,7 @@ pnpm install
|
|
|
450
454
|
|
|
451
455
|
| 控件 | 配置键 | 默认 | 人话 |
|
|
452
456
|
| --- | --- | --- | --- |
|
|
453
|
-
| 查哪些专用源 | `domainSources` |
|
|
457
|
+
| 查哪些专用源 | `domainSources` | 默认八个 | 在 34 个源里只留几个(如 `github,npm`),逗号分隔;留空表示默认八个。`sources` 参数可以点名任意一个源 |
|
|
454
458
|
| 每个源返回几条 | `domainLimit` | `5` | `domain_search` 每个源最多返回几条,1–20 |
|
|
455
459
|
| 每个源等多久 | `domainTimeoutMs` | `8000` | 单个专用源最多等多久(毫秒),最小 500;网慢可调到 15000 |
|
|
456
460
|
|
|
@@ -482,7 +486,7 @@ pnpm install
|
|
|
482
486
|
|
|
483
487
|
- **代理没被自动探测到**:在 `proxy` 里填上你的本地代理地址,比如 `http://127.0.0.1:7890`。只支持 HTTP 代理,`socks5://` 要换成客户端的 HTTP/mixed 端口。
|
|
484
488
|
- **你想要 AnySearch 的更高额度或正文抽取**:填 `anysearchApiKey`;想只搜某个垂直领域再填 `anysearchDomain`。
|
|
485
|
-
- **你只想让 `domain_search` 查某几个源**:把 `domainSources` 收窄成 `github,npm`
|
|
489
|
+
- **你只想让 `domain_search` 查某几个源**:把 `domainSources` 收窄成 `github,npm` 这类组合;留空就是默认八个;其余 26 个(如 `dockerhub,openalex`)通过 `sources` 按需开启。
|
|
486
490
|
- **抓回来的正文断得太早,或只想要纯文字**:把 `fetchMaxLength` 调到 `50000`,或把 `fetchFormat` 改成 `text`;如果调大也不够、要接着读下半段,用 `read_page`(见能力清单第 11 条)。
|
|
487
491
|
- **抓回来是个空壳页面**:先确认正文是不是靠 JavaScript 生成。自己装了 Playwright 就把 `renderJs` 留在 `auto`,重载插件后再试;没装就换一个来源(打印版、静态镜像、站点 API)。调大 `fetchMaxLength` 只对「抓到了但被截断」有用,变不出正文。
|
|
488
492
|
- **浏览器渲染太慢**:把 `renderJs` 改成 `off`,或把 `renderTimeoutMs` 调小。
|
|
@@ -559,7 +563,7 @@ pnpm install
|
|
|
559
563
|
|
|
560
564
|
### 你们怎么知道搜索质量变好了?
|
|
561
565
|
|
|
562
|
-
靠 `bench/` 里的固定查询集,而不是拍脑袋。20 条查询(中文 10、英文 10),文档 / 版本发布 / 包与库 / 新闻四类各 5 条,每条标注 1–3 个期望域名。`node scripts/bench.mjs` 离线重放录好的夹具,输出 P@8 / R@8 / MRR@8。0.
|
|
566
|
+
靠 `bench/` 里的固定查询集,而不是拍脑袋。20 条查询(中文 10、英文 10),文档 / 版本发布 / 包与库 / 新闻四类各 5 条,每条标注 1–3 个期望域名。`node scripts/bench.mjs` 离线重放录好的夹具,输出 P@8 / R@8 / MRR@8。0.15.0 的基线(按 tier 回放)是 **0.4375 / 0.7917 / 0.8071**;中文 0.4000 / 0.8167 / 0.7976,英文 0.4750 / 0.7667 / 0.8167。改排序前后各跑一次,数字是变好还是变坏一目了然。样本只有 20 条,不能当统计显著性;新闻类 recall 只有 0.467,逐条输出会把每次没命中都打出来——这些短板都写在附录里。
|
|
563
567
|
|
|
564
568
|
### 为什么搜索结果和我手动搜的不一样?
|
|
565
569
|
|
|
@@ -740,12 +744,12 @@ domain_search 调用
|
|
|
740
744
|
→ 读配置(domainSources / domainLimit / domainTimeoutMs 每次调用重读)
|
|
741
745
|
→ 解析代理(配置 → 环境变量 → 系统代理)
|
|
742
746
|
→ sources 缺省 = 设置里启用的源;limit 夹到 1–20,缺省用 domainLimit
|
|
743
|
-
→
|
|
747
|
+
→ 默认八个源并发 GET,各自独立超时(domainTimeoutMs);其余 26 个按需开启
|
|
744
748
|
→ 按源交错合并,截到 limit
|
|
745
749
|
→ 返回 { sources, failures, truncated }
|
|
746
750
|
```
|
|
747
751
|
|
|
748
|
-
|
|
752
|
+
34 个源都是公开、免密钥的接口。默认八个是 GitHub 仓库搜索、npm registry、PyPI、arXiv Atom、Wikipedia API、Hacker News(Algolia)、Stack Exchange API、crates.io;按需的 26 个覆盖包仓库(Docker Hub、Maven、NuGet、RubyGems、Packagist、pub.dev)、代码托管(GitLab、Codeberg、GitHub issues)、模型与数据集(Hugging Face)、编辑器(Open VSX、JetBrains)、基础设施(Terraform 模块与 provider、WordPress)和数据源(OpenAlex、Crossref、Europe PMC、UniProt、ClinicalTrials.gov、NVD、CoinGecko、Internet Archive、Wikidata、Nominatim)。每个源各有解析器,上游改版时该源退化成空结果,不会让整次调用失败;单个源超时、回 5xx 或网络不通,只记一条 `failures`,其余源照常返回。GitHub 与 crates.io 要求带 `User-Agent`,请求里已经带上。
|
|
749
753
|
|
|
750
754
|
两个源的行为需要单独说明:
|
|
751
755
|
|
|
@@ -807,28 +811,28 @@ read_page 调用
|
|
|
807
811
|
|
|
808
812
|
指标:P@8 = 前 8 条里命中期望域名的行数 ÷ 8(固定分母,返回不足 8 条也不放宽);R@8 = 前 8 条覆盖的期望域名 ÷ 全部期望域名;MRR@8 = 第一条命中的排名倒数,20 条取平均,没命中记 0。域名匹配允许「子域命中父域」单向成立:`docs.python.org` 命中期望的 `python.org`,反过来不算。
|
|
809
813
|
|
|
810
|
-
**0.
|
|
814
|
+
**0.15.0 基线**(按 tier 回放):
|
|
811
815
|
|
|
812
816
|
| 范围 | P@8 | R@8 | MRR@8 |
|
|
813
817
|
| --- | --- | --- | --- |
|
|
814
|
-
| 全部 20 条 | 0.
|
|
815
|
-
| 中文 10 条 | 0.
|
|
816
|
-
| 英文 10 条 | 0.
|
|
818
|
+
| 全部 20 条 | 0.4375 | 0.7917 | 0.8071 |
|
|
819
|
+
| 中文 10 条 | 0.4000 | 0.8167 | 0.7976 |
|
|
820
|
+
| 英文 10 条 | 0.4750 | 0.7667 | 0.8167 |
|
|
817
821
|
|
|
818
822
|
**对照实验**(同一批夹具,只改一个参数):
|
|
819
823
|
|
|
820
824
|
| 配置 | P@8 | R@8 | MRR@8 |
|
|
821
825
|
| --- | --- | --- | --- |
|
|
822
|
-
| 默认(rrf 60、AnySearch 权重 2) | 0.
|
|
823
|
-
| AnySearch 权重 1 | 0.
|
|
824
|
-
| rrf 40 | 0.
|
|
825
|
-
| rrf 120 | 0.
|
|
826
|
-
| 关掉权威域名(authority 0) | 0.
|
|
826
|
+
| 默认(rrf 60、AnySearch 权重 2) | 0.4375 | 0.7917 | 0.8071 |
|
|
827
|
+
| AnySearch 权重 1 | 0.4625 | 0.7917 | 0.8167 |
|
|
828
|
+
| rrf 40 | 0.4313 | 0.7833 | 0.8333 |
|
|
829
|
+
| rrf 120 | 0.4375 | 0.7917 | 0.8167 |
|
|
830
|
+
| 关掉权威域名(authority 0) | 0.3438 | 0.7917 | 0.8071 |
|
|
827
831
|
|
|
828
832
|
结论:
|
|
829
833
|
|
|
830
|
-
-
|
|
831
|
-
-
|
|
834
|
+
- 在这份语料上,单变量改动都不能与默认显著分开。`rrf 40` 把 MRR 从 0.8071 抬到 0.8333,但 P@8 从 0.4375 降到 0.4313,还多出一条 0 命中;`rrf 120` 和权重 1 大约提升 0.01 MRR、P@8 不掉,但 81 组扫描的配对 bootstrap 区间都压到 0,所以默认值都没有改。
|
|
835
|
+
- 权威域名加权改变的是同分排序,而不是找出新行:关掉后 P@8 从 0.4375 掉到 0.3438,但 MRR 和 R@8 不变。它存在的意义就是把同排名上的 `kubernetes.io` 压过 SEO 页,数字与这个定位一致。
|
|
832
836
|
- AnySearch 权重 2 时它占了 76% 的 top-8 槽位(160 行里 122 行);降到权重 1,P@8 升到 0.3875,但 MRR 掉到 0.7433,偏重与偏轻各有代价。这几组参数的差异只值 1–4 个命中,样本又只有 20 条,所以默认暂时不改。
|
|
833
837
|
- 已知短板:新闻类 recall 只有 0.3667(约 0.367);`zh-linux-612` 0 命中(kernel.org / lwn 被 AWS 文档、菜鸟教程压过);20 条样本没有统计显著性。这些数字用来判断方向,不用来宣布「质量已达标」。
|
|
834
838
|
|
|
@@ -899,7 +903,7 @@ npm run build # 编译 src/ 到 lib/
|
|
|
899
903
|
npm run check # typecheck + 测试
|
|
900
904
|
```
|
|
901
905
|
|
|
902
|
-
测试默认全程离线、全部通过;唯一需要联网的分段验证默认跳过(`READ_PAGE_LIVE=1` 时才跑):解析器测试回放 `test/fixtures/`
|
|
906
|
+
测试默认全程离线、全部通过;唯一需要联网的分段验证默认跳过(`READ_PAGE_LIVE=1` 时才跑):解析器测试回放 `test/fixtures/` 里抓下来的真实响应(含默认八个与 26 个按需源的真实响应),传输测试不开 socket,代理测试只验 `parseProxy`、`proxyFromEnv` 和纯函数式的响应分帧,时间窗测试用注入的 `now` 固定日期;新增的几组覆盖 Markdown 正文提取(`markdown.test.ts`)、批量查询(`search-many.test.ts`)、分段续读(`read-page.test.ts`)、硬盘快照(`cache-persist.test.ts`)、可选 JS 渲染(`render-js.test.ts`)和基准计分/重放(`bench-metrics.test.ts`、`bench-replay.test.ts`)。其中 `read-page.test.ts` 有一条真实联网用例默认跳过,联网验证时用 `READ_PAGE_LIVE=1 node --test test/read-page.test.ts` 运行。
|
|
903
907
|
|
|
904
908
|
CI(`.github/workflows/ci.yml`)在 Node 24 的 Ubuntu 与 macOS 上跑 `npm ci`、`npm run typecheck`、`npm test`、`npm run build`,并检查构建确实产出了 `lib/index.js` 和 `lib/index.d.ts`,且 `apply` 与 `Config` 都可导入。
|
|
905
909
|
|
package/SECURITY.md
CHANGED
|
@@ -28,6 +28,10 @@ Outbound TCP/HTTPS only, plus one local system query described below.
|
|
|
28
28
|
| `cn.bing.com`, `www.bing.com` | key-free HTML search |
|
|
29
29
|
| `html.duckduckgo.com` | key-free HTML search |
|
|
30
30
|
| `www.so.com` | key-free HTML search, fallback tier, usually bot-walled |
|
|
31
|
+
| `mcp.exa.ai` | key-free semantic search (anonymous MCP endpoint), primary tier |
|
|
32
|
+
| `api.firecrawl.dev` | key-free search API, fallback tier |
|
|
33
|
+
| `api.github.com`, `registry.npmjs.org`, `pypi.org`, `export.arxiv.org`, `*.wikipedia.org`, `hn.algolia.com`, `api.stackexchange.com`, `crates.io` | the eight default `domain_search` sources |
|
|
34
|
+
| `gitlab.com`, `codeberg.org`, `hub.docker.com`, `search.maven.org`, `azuresearch-usnc.nuget.org`, `rubygems.org`, `packagist.org`, `pub.dev`, `huggingface.co`, `open-vsx.org`, `registry.terraform.io`, `api.wordpress.org`, `plugins.jetbrains.com`, `api.openalex.org`, `api.crossref.org`, `www.ebi.ac.uk`, `rest.uniprot.org`, `clinicaltrials.gov`, `services.nvd.nist.gov`, `api.coingecko.com`, `archive.org`, `www.wikidata.org`, `nominatim.openstreetmap.org` | the 26 opt-in `domain_search` sources; contacted only when named in `sources` or `domainSources` |
|
|
31
35
|
| `api.anysearch.com` | optional: search and page extraction, **only when an AnySearch key is configured** |
|
|
32
36
|
| your configured proxy | HTTP `CONNECT` tunnel for the hosts above |
|
|
33
37
|
|