completion-kit 0.29.2 → 0.30.0
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- checksums.yaml +4 -4
- data/LICENSE +4 -1
- data/README.md +94 -127
- data/app/assets/stylesheets/completion_kit/application.css +29 -0
- data/app/controllers/completion_kit/api/v1/base_controller.rb +1 -0
- data/app/controllers/completion_kit/api/v1/prompts_controller.rb +14 -2
- data/app/controllers/completion_kit/prompts_controller.rb +1 -6
- data/app/controllers/completion_kit/runs_controller.rb +8 -1
- data/app/models/completion_kit/prompt.rb +7 -0
- data/app/services/completion_kit/mcp_tools/agreements.rb +4 -2
- data/app/services/completion_kit/mcp_tools/base.rb +7 -1
- data/app/services/completion_kit/mcp_tools/datasets.rb +12 -6
- data/app/services/completion_kit/mcp_tools/imports.rb +2 -1
- data/app/services/completion_kit/mcp_tools/judges.rb +4 -2
- data/app/services/completion_kit/mcp_tools/metric_groups.rb +10 -5
- data/app/services/completion_kit/mcp_tools/metric_versions.rb +6 -3
- data/app/services/completion_kit/mcp_tools/metrics.rb +12 -6
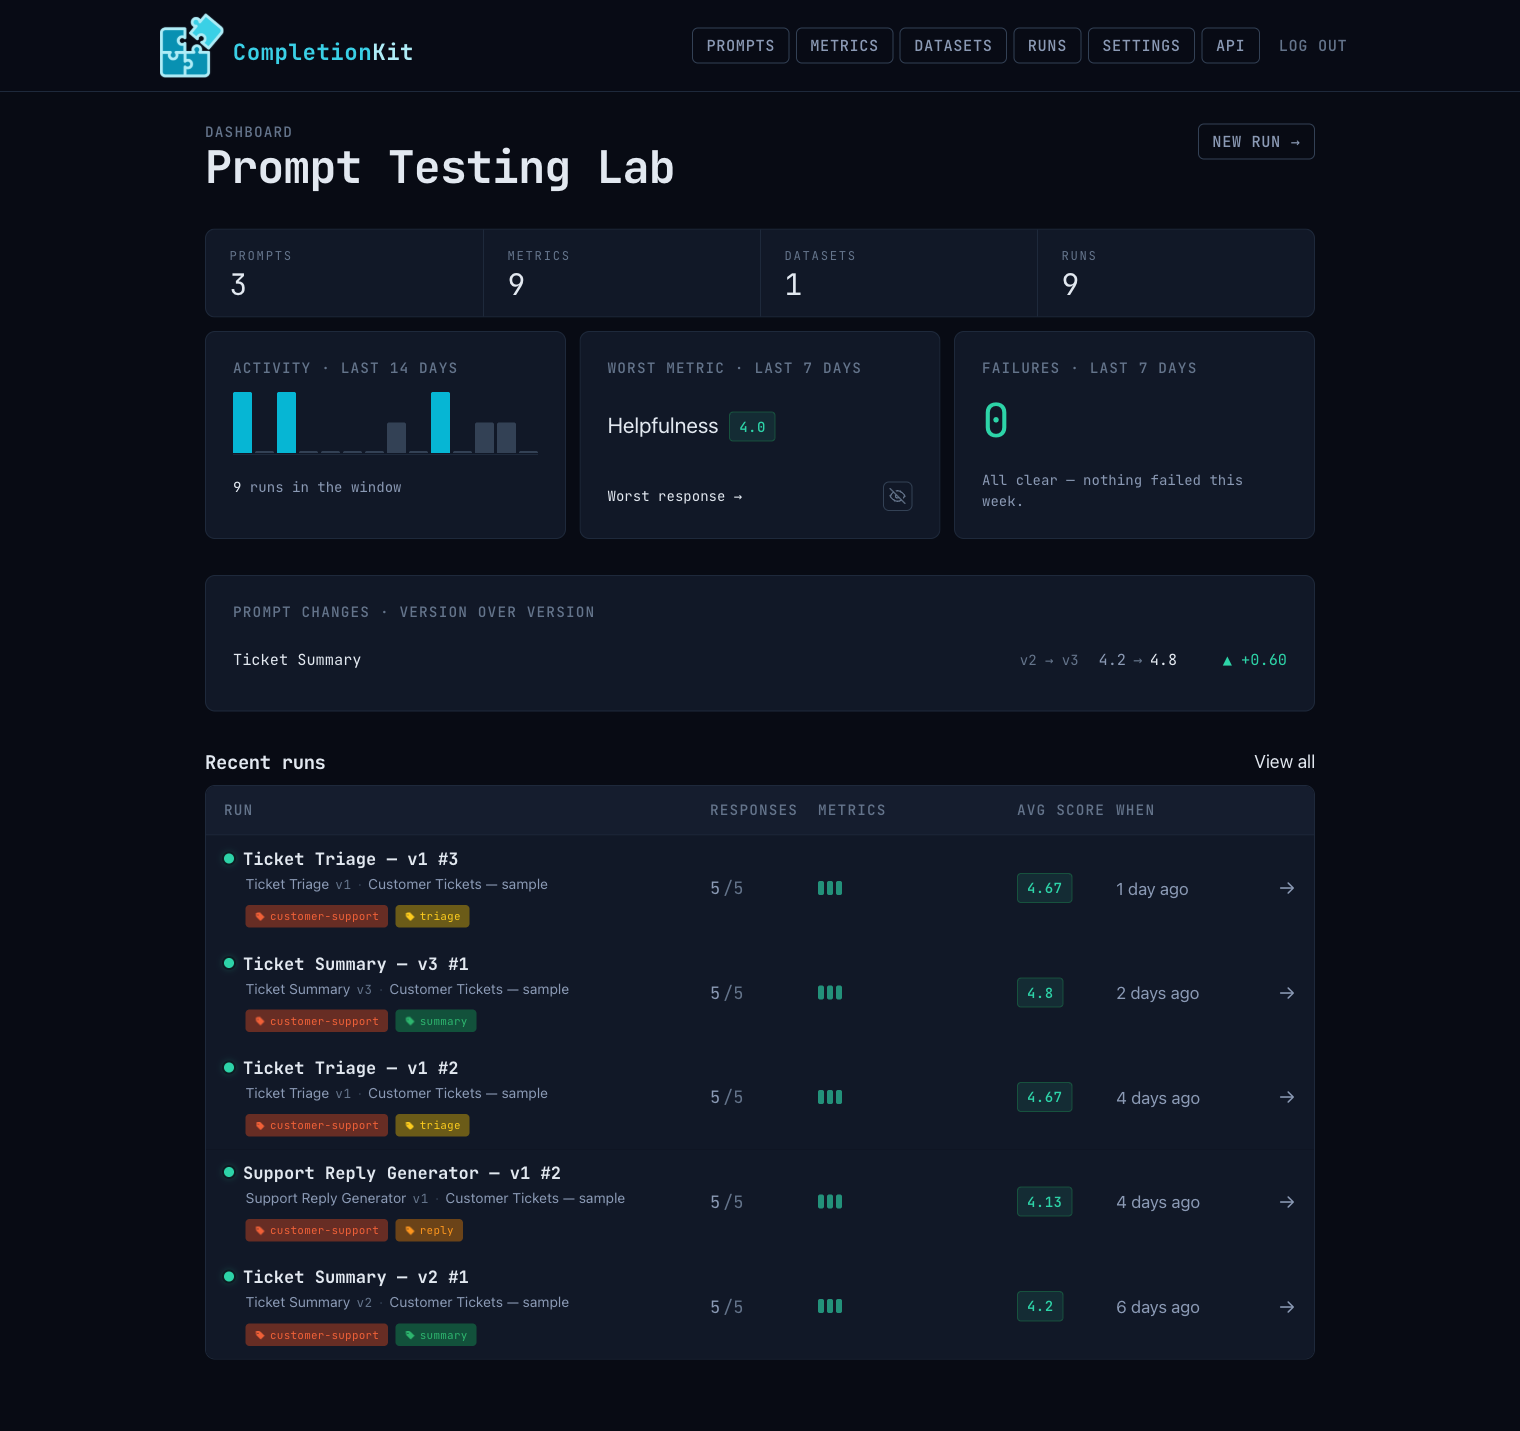
- data/app/services/completion_kit/mcp_tools/prompts.rb +18 -9
- data/app/services/completion_kit/mcp_tools/provider_credentials.rb +10 -5
- data/app/services/completion_kit/mcp_tools/responses.rb +4 -6
- data/app/services/completion_kit/mcp_tools/runs.rb +18 -11
- data/app/services/completion_kit/mcp_tools/tags.rb +10 -5
- data/app/views/completion_kit/api_reference/_body.html.erb +4 -6
- data/app/views/completion_kit/provider_credentials/_form.html.erb +4 -2
- data/app/views/completion_kit/runs/compare_picker.html.erb +5 -3
- data/lib/completion_kit/version.rb +1 -1
- data/lib/completion_kit.rb +2 -1
- metadata +1 -1
checksums.yaml
CHANGED
|
@@ -1,7 +1,7 @@
|
|
|
1
1
|
---
|
|
2
2
|
SHA256:
|
|
3
|
-
metadata.gz:
|
|
4
|
-
data.tar.gz:
|
|
3
|
+
metadata.gz: 7a88e90a186d2b535eb032d4ae9ecbae34605c622cc015f605044e5aaf570598
|
|
4
|
+
data.tar.gz: bcf073d39956a5ccd1ac1ccf2e95a69eba4e08998228b2d3ef264c1708daa523
|
|
5
5
|
SHA512:
|
|
6
|
-
metadata.gz:
|
|
7
|
-
data.tar.gz:
|
|
6
|
+
metadata.gz: 99a8354ff64bb6339c44a5074787292d112eba92c9e9ba133b9e8fb3ab7364535f3a32b8e5e8d012264aaffea3572482b753f7e1c136a8ee303d55ef5232d3b3
|
|
7
|
+
data.tar.gz: 6de209e19ec52332cfa510e8abf2e33298bd674ff8b1fba239039cc64215e620a59f30cf6745990c5da448e40f49aa84cdb722dba2afd2f7985788469fb97e09
|
data/LICENSE
CHANGED
|
@@ -12,7 +12,10 @@ Additional Use Grant: You may use the Licensed Work for any purpose,
|
|
|
12
12
|
hosted or managed service whose primary value is the
|
|
13
13
|
functionality of the Licensed Work itself.
|
|
14
14
|
|
|
15
|
-
Change Date:
|
|
15
|
+
Change Date: Three years from the date each version of the
|
|
16
|
+
Licensed Work is first publicly released.
|
|
17
|
+
Versions 0.3.0 through 0.29.3 keep the Change
|
|
18
|
+
Date of 2029-04-25 they were released with.
|
|
16
19
|
|
|
17
20
|
Change License: GNU General Public License (GPL) Version 3
|
|
18
21
|
|
data/README.md
CHANGED
|
@@ -10,27 +10,50 @@
|
|
|
10
10
|
|
|
11
11
|
Your prompts need tests too.
|
|
12
12
|
|
|
13
|
-
Run every prompt against real data. Score each output with an LLM judge
|
|
13
|
+
Run every prompt against real data. Score each output against criteria you define, with an LLM judge or a plain check. Change anything: the prompt, the model, the temperature, the dataset. Re-run and see exactly what got better and what broke. When the scores tell you something's off, CompletionKit suggests an improved prompt based on the judge's feedback on your runs. You inspect the diff, apply it as a new version, and check the improvement.
|
|
14
14
|
|
|
15
15
|
It's the difference between "this prompt seems to work" and "this prompt scores 4.3 out of 5 across 200 inputs, up from 3.8 last version."
|
|
16
16
|
|
|
17
17
|
**[Start on completionkit.com →](https://completionkit.com)** | **[RubyGems](https://rubygems.org/gems/completion-kit)**
|
|
18
18
|
|
|
19
|
-
|
|
19
|
+
|
|
20
20
|
|
|
21
|
-
|
|
21
|
+
## How it works
|
|
22
|
+
|
|
23
|
+
<p align="center">
|
|
24
|
+
<img src="https://raw.githubusercontent.com/homemade-software-inc/completion-kit/main/docs/diagrams/workflow.png" alt="CompletionKit workflow: a prompt and a dataset feed a run against a model, an LLM judge scores each output on your rubric, low scores drive an AI-suggested rewrite, and the new prompt version re-runs so you can compare" width="820" />
|
|
25
|
+
</p>
|
|
26
|
+
|
|
27
|
+
It's a loop. Each pass leaves you with a score you can compare against the last one.
|
|
28
|
+
|
|
29
|
+
1. **Create a prompt** with `{{variable}}` placeholders.
|
|
30
|
+
2. **Upload a dataset.** A CSV whose column headers match the variable names.
|
|
31
|
+
3. **Run it** against a model and score the outputs against your metrics.
|
|
32
|
+
4. **Iterate.** Change the prompt, the model, the temperature, or the dataset and re-run. CompletionKit versions your prompts, so you can always compare against earlier results.
|
|
33
|
+
5. **Get suggestions.** When scores drop, ask CompletionKit for an improved prompt. The suggestion comes from the judge's feedback on each response, not generic prompt advice. Inspect the diff and apply it as a new version.
|
|
34
|
+
|
|
35
|
+
## Concepts
|
|
36
|
+
|
|
37
|
+
- **Prompt.** A versioned template with `{{variable}}` placeholders. Editing a prompt that has already run creates a new version, so earlier results stay reproducible.
|
|
38
|
+
- **Dataset.** A CSV of real inputs. Each row becomes one test case.
|
|
39
|
+
- **Run.** One execution of a prompt against a dataset. It records every input (model, temperature, metrics) and stores every output and score.
|
|
40
|
+
- **Response.** The model's output for one dataset row, with its scores attached.
|
|
41
|
+
- **Metric.** What you score each response on. A judge metric has an instruction, evaluation steps and a 1 to 5 scale, and an LLM judge applies it. A check metric is a pass or fail test with no LLM involved: contains, does not contain, equals, regex, valid JSON, JSON field equals, length bounds, list overlap, number bounds, and number equals.
|
|
42
|
+
- **Metric group.** A set of metrics you can apply to a run together.
|
|
43
|
+
- **Tag.** A label for prompts, runs, metrics and datasets. Filter any list by tag (`?tag[]=...`).
|
|
44
|
+
- **Provider credential.** An API key for a model provider. It is encrypted at rest and never returned through the API.
|
|
22
45
|
|
|
23
46
|
## Three ways to run it
|
|
24
47
|
|
|
25
|
-
|
|
48
|
+
Every option has the same engine, UI, REST API and MCP server. The first two work with any stack: you run CompletionKit as a product and talk to it over HTTP and MCP, whatever language your app is written in. The third is for teams already on Rails.
|
|
26
49
|
|
|
27
|
-
### 1. Hosted
|
|
50
|
+
### 1. Hosted at [completionkit.com](https://completionkit.com) (recommended)
|
|
28
51
|
|
|
29
|
-
|
|
52
|
+
Sign up and start testing prompts. There's no Rails app to run, no migrations, no job worker and no servers to keep up. Your whole team shares a workspace. Plans are at [completionkit.com/pricing](https://completionkit.com/pricing).
|
|
30
53
|
|
|
31
|
-
### 2. Self-hosted
|
|
54
|
+
### 2. Self-hosted standalone app
|
|
32
55
|
|
|
33
|
-
Run it on your own
|
|
56
|
+
Run it on your own servers as a self-contained product. There's nothing to integrate and no Ruby to write: once it's up, you drive it through the web UI, the REST API and the MCP server. It needs Postgres and a host that can run a Rails app.
|
|
34
57
|
|
|
35
58
|
```bash
|
|
36
59
|
git clone https://github.com/homemade-software-inc/completion-kit.git
|
|
@@ -40,7 +63,7 @@ bin/rails completion_kit:install:migrations
|
|
|
40
63
|
bin/rails db:migrate
|
|
41
64
|
```
|
|
42
65
|
|
|
43
|
-
Run
|
|
66
|
+
Run a web server and a Solid Queue worker, in two terminals:
|
|
44
67
|
|
|
45
68
|
```bash
|
|
46
69
|
bin/rails server
|
|
@@ -50,11 +73,11 @@ bin/rails server
|
|
|
50
73
|
bin/jobs
|
|
51
74
|
```
|
|
52
75
|
|
|
53
|
-
Or with [foreman](https://github.com/ddollar/foreman)
|
|
76
|
+
Or run both in one terminal with [foreman](https://github.com/ddollar/foreman): `foreman start -f Procfile.dev`.
|
|
54
77
|
|
|
55
|
-
Visit `http://localhost:3000`. Add a provider credential
|
|
78
|
+
Visit `http://localhost:3000`. Add a provider credential under Settings, create a prompt, upload a CSV dataset, and run it. See [Deploying self-hosted](#deploying-self-hosted) when you're ready for production.
|
|
56
79
|
|
|
57
|
-
### 3.
|
|
80
|
+
### 3. Mounted in your Rails app
|
|
58
81
|
|
|
59
82
|
```ruby
|
|
60
83
|
gem "completion-kit"
|
|
@@ -65,22 +88,24 @@ bin/rails generate completion_kit:install
|
|
|
65
88
|
bin/rails db:migrate
|
|
66
89
|
```
|
|
67
90
|
|
|
68
|
-
The engine mounts at `/completion_kit`.
|
|
91
|
+
The engine mounts at `/completion_kit`. Runs work through Active Job (`CompletionKit::GenerateRowJob`, `CompletionKit::JudgeReviewJob`, `CompletionKit::RunCompletionCheckJob` and others), so your app needs a real job backend such as Solid Queue, Sidekiq or GoodJob. Don't use the `:async` adapter in production. It runs jobs inside Puma's thread pool with no durability or retries, and a long LLM call will hold up web requests.
|
|
92
|
+
|
|
93
|
+
#### Using your own layout
|
|
69
94
|
|
|
70
|
-
|
|
95
|
+
If your app renders the engine's pages inside its own layout, include the engine's stylesheet and JavaScript there:
|
|
71
96
|
|
|
72
97
|
```erb
|
|
73
98
|
<%= stylesheet_link_tag "completion_kit/application", media: "all" %>
|
|
74
99
|
<%= javascript_include_tag "completion_kit/application", defer: true, nonce: true %>
|
|
75
100
|
```
|
|
76
101
|
|
|
77
|
-
Without the JavaScript
|
|
102
|
+
Without the JavaScript, much of the UI quietly stops working: clickable rows, dialogs, copy buttons, the run form, live run status and local times among them.
|
|
78
103
|
|
|
79
|
-
|
|
104
|
+
#### Content Security Policy
|
|
80
105
|
|
|
81
|
-
|
|
106
|
+
The engine's pages have no inline scripts or inline event handlers, and the engine layout puts the request nonce on its script tags, so they work under a nonce-based `script-src`. The views still use inline `style` attributes, so keep `style-src` out of the nonce directives and allow `'unsafe-inline'` there for now.
|
|
82
107
|
|
|
83
|
-
|
|
108
|
+
Use a nonce that lasts the whole session. Turbo Drive re-creates scripts on each visit using the nonce from the `csp-nonce` meta tag, but the browser keeps enforcing the policy from the first page it loaded, so a fresh nonce per request blocks scripts after the first visit. The Rails default nonce, the session id, is empty on a new visitor's first response, so it blocks that first page's scripts. Keep a random nonce in the session instead, and skip API controllers so API and MCP calls don't get a session cookie:
|
|
84
109
|
|
|
85
110
|
```ruby
|
|
86
111
|
Rails.application.configure do
|
|
@@ -101,25 +126,25 @@ end
|
|
|
101
126
|
|
|
102
127
|
## Providers
|
|
103
128
|
|
|
104
|
-
CompletionKit
|
|
129
|
+
CompletionKit finds the available models from each provider's API.
|
|
105
130
|
|
|
106
131
|
| Provider | Env vars | What it covers |
|
|
107
132
|
|----------|----------|----------------|
|
|
108
|
-
| **OpenAI** | `OPENAI_API_KEY` | GPT-5, GPT-4.1, GPT-4o
|
|
133
|
+
| **OpenAI** | `OPENAI_API_KEY` | GPT-5, GPT-4.1, GPT-4o and the rest |
|
|
109
134
|
| **Anthropic** | `ANTHROPIC_API_KEY` | Claude Opus, Sonnet, Haiku |
|
|
110
|
-
| **Ollama
|
|
111
|
-
| **OpenRouter** | `OPENROUTER_API_KEY` | 100+ models from 30+ providers through one
|
|
112
|
-
| **Azure AI Foundry** |
|
|
135
|
+
| **Ollama or a local endpoint** | `OLLAMA_API_ENDPOINT` (default `http://localhost:11434/v1`), `OLLAMA_API_KEY` (optional) | Any model you've pulled with Ollama, or any OpenAI-compatible local server (vLLM, LM Studio, llama.cpp) |
|
|
136
|
+
| **OpenRouter** | `OPENROUTER_API_KEY` | 100+ models from 30+ providers through one key |
|
|
137
|
+
| **Azure AI Foundry** | None. Add it as a provider credential with `api_key` and `api_endpoint` (`api_version` is optional) | Azure OpenAI deployments and Foundry projects |
|
|
113
138
|
|
|
114
|
-
Set these as environment variables
|
|
139
|
+
Set these as environment variables, in the generated initializer, or as provider credentials under Settings in the web UI.
|
|
115
140
|
|
|
116
|
-
The Ollama key from `OLLAMA_API_KEY` or `config.ollama_api_key`
|
|
141
|
+
The Ollama key from `OLLAMA_API_KEY` or `config.ollama_api_key` is only ever sent to the Ollama endpoint you configured, or to `http://localhost:11434/v1` when you configured none and loopback endpoints are allowed. A provider credential without its own key borrows that key only while it points at that same endpoint. Point it anywhere else and CompletionKit sends no key, so store the key on the credential. A key stored on a credential always goes to that credential's endpoint. Endpoints match on scheme, host, port and path; letter case, a written-out default port, a trailing slash and a trailing `/v1` don't count. A blank stored key counts as no key.
|
|
117
142
|
|
|
118
|
-
|
|
143
|
+
Custom model endpoints and CSV imports by URL may reach the server's own loopback interface by default, so a local Ollama works out of the box. If the people using CompletionKit shouldn't reach services on the app server itself, set `config.allow_loopback_endpoints = false`. Private, link-local and reserved addresses are always refused.
|
|
119
144
|
|
|
120
|
-
|
|
145
|
+
### Encryption
|
|
121
146
|
|
|
122
|
-
Generate them:
|
|
147
|
+
Provider API keys are encrypted at rest with [Active Record encryption](https://guides.rubyonrails.org/active_record_encryption.html). The app won't boot in production until three encryption keys are set. Generate them:
|
|
123
148
|
|
|
124
149
|
```bash
|
|
125
150
|
bin/rails db:encryption:init
|
|
@@ -133,13 +158,13 @@ COMPLETION_KIT_ENCRYPTION_DETERMINISTIC_KEY=<generated value>
|
|
|
133
158
|
COMPLETION_KIT_ENCRYPTION_KEY_DERIVATION_SALT=<generated value>
|
|
134
159
|
```
|
|
135
160
|
|
|
136
|
-
|
|
161
|
+
You can put them in `config/credentials.yml.enc` under `active_record_encryption` instead. In development the standalone app falls back to built-in values, so you can skip this locally.
|
|
137
162
|
|
|
138
163
|
## Authentication
|
|
139
164
|
|
|
140
|
-
CompletionKit
|
|
165
|
+
CompletionKit needs authentication anywhere it's deployed. In development and test the routes are open, with a warning in the log. Every other environment returns 403 until you configure one of these two modes.
|
|
141
166
|
|
|
142
|
-
### Basic
|
|
167
|
+
### Basic auth
|
|
143
168
|
|
|
144
169
|
```ruby
|
|
145
170
|
CompletionKit.configure do |c|
|
|
@@ -148,7 +173,7 @@ CompletionKit.configure do |c|
|
|
|
148
173
|
end
|
|
149
174
|
```
|
|
150
175
|
|
|
151
|
-
###
|
|
176
|
+
### Your own auth (Devise and the like)
|
|
152
177
|
|
|
153
178
|
```ruby
|
|
154
179
|
CompletionKit.configure do |c|
|
|
@@ -156,11 +181,9 @@ CompletionKit.configure do |c|
|
|
|
156
181
|
end
|
|
157
182
|
```
|
|
158
183
|
|
|
159
|
-
|
|
160
|
-
|
|
161
|
-
### Reviewer name
|
|
184
|
+
### Reviewer names
|
|
162
185
|
|
|
163
|
-
When someone
|
|
186
|
+
When someone agrees or disagrees with a judge's score in the web UI, CompletionKit saves that verdict under a reviewer name. Each reviewer keeps one verdict per response and metric, so give each person their own name or their verdicts overwrite each other. Set `current_reviewer` to a callable that takes the controller and returns the signed-in person's name:
|
|
164
187
|
|
|
165
188
|
```ruby
|
|
166
189
|
CompletionKit.configure do |c|
|
|
@@ -169,7 +192,9 @@ CompletionKit.configure do |c|
|
|
|
169
192
|
end
|
|
170
193
|
```
|
|
171
194
|
|
|
172
|
-
|
|
195
|
+
It must return a String or nil. Anything else, such as a user record, raises `CompletionKit::ConfigurationError`. When `current_reviewer` is unset or returns a blank value, verdicts go under `username`, or `"operator"` if there's no username.
|
|
196
|
+
|
|
197
|
+
The web UI doesn't read the `X-Remote-User` header by itself. If a proxy in front of your app sets it, pass it through:
|
|
173
198
|
|
|
174
199
|
```ruby
|
|
175
200
|
CompletionKit.configure do |c|
|
|
@@ -177,71 +202,46 @@ CompletionKit.configure do |c|
|
|
|
177
202
|
end
|
|
178
203
|
```
|
|
179
204
|
|
|
180
|
-
Only
|
|
205
|
+
Only do this when a trusted proxy always overwrites that header. Otherwise any client can send it and claim any name.
|
|
181
206
|
|
|
182
207
|
The REST API and the MCP server take the reviewer name from their own `created_by` parameter.
|
|
183
208
|
|
|
184
|
-
##
|
|
209
|
+
## Limits
|
|
210
|
+
|
|
211
|
+
### Rate limits
|
|
185
212
|
|
|
186
|
-
The REST API, the MCP endpoint
|
|
213
|
+
The REST API, the MCP endpoint and the web UI are rate limited per IP, per minute. The defaults are generous:
|
|
187
214
|
|
|
188
215
|
```ruby
|
|
189
216
|
CompletionKit.configure do |c|
|
|
190
|
-
c.api_rate_limit = 120 # REST API
|
|
191
|
-
c.web_rate_limit = 300 # web UI, requests per minute
|
|
217
|
+
c.api_rate_limit = 120 # REST API and MCP, requests per minute
|
|
218
|
+
c.web_rate_limit = 300 # web UI, requests per minute
|
|
192
219
|
end
|
|
193
220
|
```
|
|
194
221
|
|
|
195
|
-
|
|
222
|
+
Limits are counted in `Rails.cache`. A shared store such as Solid Cache or Redis counts across all your app instances. A per-process store limits each instance on its own.
|
|
196
223
|
|
|
197
|
-
|
|
224
|
+
### Input limits
|
|
198
225
|
|
|
199
|
-
Uploads, prompt templates
|
|
226
|
+
Uploads, prompt templates and regex checks have limits, so one huge or hostile input can't tie up a worker:
|
|
200
227
|
|
|
201
228
|
```ruby
|
|
202
229
|
CompletionKit.configure do |c|
|
|
203
230
|
c.max_upload_bytes = 25 * 1024 * 1024 # largest dataset CSV or import file (default 25 MB)
|
|
204
231
|
c.max_template_bytes = 1024 * 1024 # largest prompt template (default 1 MB)
|
|
205
|
-
c.regex_timeout = 1.0 # seconds a regex check may spend
|
|
232
|
+
c.regex_timeout = 1.0 # seconds a regex check may spend on one row (default 1.0)
|
|
206
233
|
end
|
|
207
234
|
```
|
|
208
235
|
|
|
209
|
-
A prompt
|
|
210
|
-
|
|
211
|
-
The first line of a dataset's CSV is its header row. A dataset fails validation when its CSV is saved with a header row that is blank or longer than 64 KB. The 64 KB limit is fixed, not a setting.
|
|
236
|
+
A prompt over `max_template_bytes` fails validation when it's saved. Prompts saved before you lowered the limit keep working until their template changes.
|
|
212
237
|
|
|
213
|
-
A dataset
|
|
238
|
+
A dataset fails validation when its header row is blank or longer than 64 KB (a fixed limit), or when the CSV isn't valid UTF-8. Export spreadsheets as UTF-8 CSV.
|
|
214
239
|
|
|
215
|
-
A regex check that runs
|
|
216
|
-
|
|
217
|
-
## How it works
|
|
218
|
-
|
|
219
|
-
<p align="center">
|
|
220
|
-
<img src="https://raw.githubusercontent.com/homemade-software-inc/completion-kit/main/docs/diagrams/workflow.png" alt="CompletionKit workflow: a prompt and a dataset feed a run against a model, an LLM judge scores each output on your rubric, low scores drive an AI-suggested rewrite, and the new prompt version re-runs so you can compare" width="820" />
|
|
221
|
-
</p>
|
|
222
|
-
|
|
223
|
-
It's a loop. Each pass leaves you with a score you can compare against the last one.
|
|
224
|
-
|
|
225
|
-
1. **Create a prompt** with `{{variable}}` placeholders
|
|
226
|
-
2. **Upload a dataset.** A CSV where column headers match the variable names.
|
|
227
|
-
3. **Run it** against a model and score outputs with an LLM judge against criteria you define.
|
|
228
|
-
4. **Iterate.** Change the prompt, the model, the temperature, or the dataset and re-run. CompletionKit versions your prompts so you can always compare against previous results.
|
|
229
|
-
5. **Get suggestions.** When scores drop, ask CompletionKit for an AI-generated improvement. The suggestion is based on the judge's actual per-response feedback, not generic prompt-engineering advice. Inspect the diff and apply it as a new version.
|
|
230
|
-
|
|
231
|
-
## Concepts
|
|
232
|
-
|
|
233
|
-
- **Prompt.** A versioned template with `{{variable}}` placeholders. Editing a prompt that's already been run creates a new version, so earlier results stay reproducible.
|
|
234
|
-
- **Dataset.** A CSV of real inputs. Each row becomes one test case.
|
|
235
|
-
- **Run.** One execution of a prompt against a dataset. Captures every input (model, temperature, metrics) and stores all outputs and scores.
|
|
236
|
-
- **Response.** The model's output for one dataset row, with reviews attached.
|
|
237
|
-
- **Metric.** An evaluation dimension with a name, instruction, evaluation steps, and a 1-5 star scoring scale. The LLM judge uses this to score each response.
|
|
238
|
-
- **Metric Group.** A reusable group of metrics you can apply to a run as a set.
|
|
239
|
-
- **Tag.** A domain label you can attach to prompts, runs, metrics, and datasets. Auto-assigned from a 10-color palette. Filter any index page by tag (`?tag[]=...`).
|
|
240
|
-
- **Provider Credential.** An API key for a model provider. Encrypted at rest, never returned through the API.
|
|
240
|
+
A regex check that runs out of time fails that row and says so. The limit is `regex_timeout`, or your app's `Regexp.timeout` if that's shorter, so the engine never loosens a stricter limit you set. It sets the limit per pattern and never touches the process-wide `Regexp.timeout`. Set `regex_timeout` to at least `0.001` seconds, or to `nil` to rely on `Regexp.timeout` alone. Any other value, such as `0` or `Float::INFINITY`, raises an `ArgumentError` when the initializer runs.
|
|
241
241
|
|
|
242
242
|
## REST API
|
|
243
243
|
|
|
244
|
-
Every resource is
|
|
244
|
+
Every resource is available through a JSON API with a bearer token:
|
|
245
245
|
|
|
246
246
|
```ruby
|
|
247
247
|
CompletionKit.configure { |c| c.api_token = ENV["COMPLETION_KIT_API_TOKEN"] }
|
|
@@ -252,11 +252,11 @@ curl -H "Authorization: Bearer $TOKEN" \
|
|
|
252
252
|
http://localhost:3000/completion_kit/api/v1/prompts
|
|
253
253
|
```
|
|
254
254
|
|
|
255
|
-
Visit `/completion_kit/api_reference` in your running app for
|
|
255
|
+
Visit `/completion_kit/api_reference` in your running app for docs on every endpoint, with curl examples you can copy.
|
|
256
256
|
|
|
257
257
|
## MCP server
|
|
258
258
|
|
|
259
|
-
CompletionKit runs a [Model Context Protocol](https://modelcontextprotocol.io) server at `/completion_kit/mcp
|
|
259
|
+
CompletionKit runs a [Model Context Protocol](https://modelcontextprotocol.io) server at `/completion_kit/mcp`. It exposes every resource as tools that MCP clients such as Claude Code and Cursor can use directly:
|
|
260
260
|
|
|
261
261
|
```json
|
|
262
262
|
{
|
|
@@ -269,21 +269,21 @@ CompletionKit runs a [Model Context Protocol](https://modelcontextprotocol.io) s
|
|
|
269
269
|
}
|
|
270
270
|
```
|
|
271
271
|
|
|
272
|
-
The
|
|
272
|
+
The API reference page in the app has snippets you can paste into your MCP client's config.
|
|
273
273
|
|
|
274
274
|
## Deploying self-hosted
|
|
275
275
|
|
|
276
|
-
Any Rails
|
|
276
|
+
Any host that runs Rails will do: Fly, Render, Heroku, Docker and so on. Point it at Postgres with `DATABASE_URL`, set your provider env vars, and run `cd standalone && bin/rails db:migrate` on each deploy.
|
|
277
277
|
|
|
278
278
|
| Variable | Purpose | Default |
|
|
279
279
|
|----------|---------|---------|
|
|
280
|
-
| `COMPLETION_KIT_API_TOKEN` | Bearer token for REST API and MCP |
|
|
281
|
-
| `COMPLETION_KIT_USERNAME` | Web UI
|
|
282
|
-
| `COMPLETION_KIT_PASSWORD` | Web UI
|
|
280
|
+
| `COMPLETION_KIT_API_TOKEN` | Bearer token for the REST API and MCP | None, so the API is off |
|
|
281
|
+
| `COMPLETION_KIT_USERNAME` | Web UI username | `admin` |
|
|
282
|
+
| `COMPLETION_KIT_PASSWORD` | Web UI password | None, so it's open in development only |
|
|
283
283
|
|
|
284
|
-
You also need the three `COMPLETION_KIT_ENCRYPTION_*` keys from
|
|
284
|
+
You also need the three `COMPLETION_KIT_ENCRYPTION_*` keys from [Encryption](#encryption).
|
|
285
285
|
|
|
286
|
-
When
|
|
286
|
+
When a new gem version ships a migration, install it locally and commit it before you deploy:
|
|
287
287
|
|
|
288
288
|
```bash
|
|
289
289
|
cd standalone
|
|
@@ -294,13 +294,13 @@ git add db/migrate/ && git commit -m "install new engine migration"
|
|
|
294
294
|
|
|
295
295
|
### Docker
|
|
296
296
|
|
|
297
|
-
The standalone app ships a `Dockerfile`, so you can
|
|
297
|
+
The standalone app ships a `Dockerfile`, so you can run it without Ruby on the host. Build from the repository root, since the app needs the engine source next to it:
|
|
298
298
|
|
|
299
299
|
```bash
|
|
300
300
|
docker build -f standalone/Dockerfile -t completion-kit .
|
|
301
301
|
```
|
|
302
302
|
|
|
303
|
-
CompletionKit needs a Rails secret (`SECRET_KEY_BASE`) and three
|
|
303
|
+
CompletionKit needs a Rails secret (`SECRET_KEY_BASE`) and the three encryption keys. Without Ruby on the host you can't run `bin/rails db:encryption:init`, so generate them with `openssl` and write everything to an env file:
|
|
304
304
|
|
|
305
305
|
```bash
|
|
306
306
|
cat > completion-kit.env <<EOF
|
|
@@ -312,58 +312,25 @@ COMPLETION_KIT_ENCRYPTION_KEY_DERIVATION_SALT=$(openssl rand -hex 32)
|
|
|
312
312
|
EOF
|
|
313
313
|
```
|
|
314
314
|
|
|
315
|
-
|
|
315
|
+
Generate these **once** and keep them. If the encryption keys change, the provider keys already in the database can't be decrypted. Keep `completion-kit.env` out of version control and back it up somewhere safe.
|
|
316
316
|
|
|
317
|
-
Run the web process and a job worker from the same image, both
|
|
317
|
+
Run the web process and a job worker from the same image and the same env file, so both share the same secrets:
|
|
318
318
|
|
|
319
319
|
```bash
|
|
320
320
|
docker run -d -p 3000:3000 --env-file completion-kit.env completion-kit
|
|
321
321
|
docker run -d --env-file completion-kit.env completion-kit ./bin/jobs
|
|
322
322
|
```
|
|
323
323
|
|
|
324
|
-
|
|
325
|
-
|
|
326
|
-
## Multi-tenant host apps (advanced)
|
|
327
|
-
|
|
328
|
-
For hosts that mount CompletionKit in a multi-tenant app, two optional hooks scope engine records per tenant without forking the engine:
|
|
329
|
-
|
|
330
|
-
```ruby
|
|
331
|
-
CompletionKit.configure do |config|
|
|
332
|
-
config.tenant_scope = -> {
|
|
333
|
-
org = Current.organization&.id
|
|
334
|
-
org ? where(organization_id: org) : where("1=0")
|
|
335
|
-
}
|
|
336
|
-
config.tenant_scope_columns = [:organization_id]
|
|
337
|
-
end
|
|
338
|
-
```
|
|
339
|
-
|
|
340
|
-
`tenant_scope` runs as each engine model's `default_scope` (use `unscoped` to bypass). `tenant_scope_columns` is appended to every engine uniqueness validation. Adding the tenant columns and composite unique indexes lives in your host migrations. Both defaults (`nil`, `[]`) are no-ops. The `completion_kit:mark_interrupted_runs_failed` rake task bypasses `tenant_scope` and marks in-flight runs in every tenant, so a host that also enforces tenancy in the database, for example with row-level security, must run it as a database role that can see every tenant's rows.
|
|
341
|
-
|
|
342
|
-
Custom model endpoints and CSV imports by URL may reach the server's own loopback interface by default, so a local Ollama works out of the box. If the people using the engine should not reach services on the app server itself, set `config.allow_loopback_endpoints = false`. Private, link-local and reserved addresses are always refused.
|
|
343
|
-
|
|
344
|
-
One hook lets a host apply its own display rule everywhere the engine lists, counts, or traverses runs, without overriding controllers or views:
|
|
345
|
-
|
|
346
|
-
```ruby
|
|
347
|
-
CompletionKit.configure do |config|
|
|
348
|
-
config.runs_display_scope = -> { where(created_at: 90.days.ago..) }
|
|
349
|
-
config.runs_display_footer_partial = "runs/display_notice"
|
|
350
|
-
end
|
|
351
|
-
```
|
|
352
|
-
|
|
353
|
-
`runs_display_scope` is a callable evaluated against a `Run` relation, in the same bare-`where` style as `tenant_scope` (it runs via `instance_exec`, so write it zero-arg with the relation as `self`, like a Rails `scope` lambda). It must return a relation: a callable that returns `nil` or anything non-chainable raises when a list renders. The engine applies it through `Run.display_scoped` at every run list and count it owns (the runs index, prompt and dataset show pages, the compare picker, new-run tag defaults, the v1 API index and its `X-Total-Count`, the MCP `runs_list` tool, the dashboard and API reference recent-runs panels, the dashboard "Runs" stat-card count, and provider-credential usage stats) and through `Run.visible_run_ids` for child records that traverse runs (the metric trust-panel sample and the agreement examples shown on a metric page). Use it for a list-only display rule rather than a global `default_scope`, which would null `Run` associations everywhere they are traversed.
|
|
354
|
-
|
|
355
|
-
Deliberately exempt, because they must still see every run: id-addressed single-run lookups (`runs#show`, the MCP `runs_get` tool, the v1 API show), delete-confirmation cascade counts, the auto-generated run-name counter, the dashboard's stat-card gate (it keys off the unscoped run total so a workspace whose runs the display scope excludes entirely still sees its activity cards rather than a blank dashboard), and the judge few-shot seeding that learns from corrected examples even on runs the display scope excludes.
|
|
356
|
-
|
|
357
|
-
`runs_display_footer_partial` names a partial rendered below the runs list on the dashboard, the index, and the prompt and dataset show pages; it receives the shown runs as a `runs` local. When the display scope excludes every run one of those surfaces would list, the surface says "No runs to show." and the footer partial renders beneath it. The engine cannot know why your scope excludes runs, so use the partial to explain your display rule: your host owns that rule in `runs_display_scope` and is the only side that can describe or count what it left out. Both default to `nil` (no-ops), leaving standalone behaviour unchanged.
|
|
324
|
+
The web container runs `db:prepare` on boot, so migrations apply on first start and on every deploy.
|
|
358
325
|
|
|
359
326
|
## Contributing
|
|
360
327
|
|
|
361
|
-
See [CONTRIBUTING.md](CONTRIBUTING.md) for development setup, testing
|
|
328
|
+
See [CONTRIBUTING.md](CONTRIBUTING.md) for development setup, testing and pull request guidelines.
|
|
362
329
|
|
|
363
330
|
## License
|
|
364
331
|
|
|
365
|
-
CompletionKit 0.3.0 and later are licensed under the [Business Source License 1.1](LICENSE). You may use CompletionKit
|
|
332
|
+
CompletionKit 0.3.0 and later are licensed under the [Business Source License 1.1](LICENSE). You may use CompletionKit for any purpose, including production, except offering it (or a derivative) to others as a hosted or managed service whose main value is CompletionKit itself. Each version becomes GPL-3 three years after it's released. Versions 0.3.0 through 0.29.3 shipped with a fixed date and become GPL-3 on April 25, 2029.
|
|
366
333
|
|
|
367
334
|
CompletionKit 0.2.x and earlier remain available under the [MIT License](https://github.com/homemade-software-inc/completion-kit/blob/v0.2.0/MIT-LICENSE).
|
|
368
335
|
|
|
369
|
-
For
|
|
336
|
+
For other licensing, contact hello@homemade.software.
|
|
@@ -4165,6 +4165,35 @@ a.ck-metric-group-pill {
|
|
|
4165
4165
|
.ck-responses-table .ck-metric-bar--compact { flex-wrap: wrap; row-gap: 3px; }
|
|
4166
4166
|
|
|
4167
4167
|
|
|
4168
|
+
.ck-compare-picker td:first-child {
|
|
4169
|
+
overflow: hidden;
|
|
4170
|
+
text-overflow: ellipsis;
|
|
4171
|
+
}
|
|
4172
|
+
|
|
4173
|
+
.ck-compare-picker th:nth-child(2),
|
|
4174
|
+
.ck-compare-picker td:nth-child(2) {
|
|
4175
|
+
width: 9rem;
|
|
4176
|
+
white-space: nowrap;
|
|
4177
|
+
}
|
|
4178
|
+
|
|
4179
|
+
.ck-compare-picker th:nth-child(3),
|
|
4180
|
+
.ck-compare-picker td:nth-child(3) {
|
|
4181
|
+
width: 13rem;
|
|
4182
|
+
overflow: hidden;
|
|
4183
|
+
text-overflow: ellipsis;
|
|
4184
|
+
white-space: nowrap;
|
|
4185
|
+
}
|
|
4186
|
+
|
|
4187
|
+
.ck-compare-picker th:nth-child(4),
|
|
4188
|
+
.ck-compare-picker td:nth-child(4) {
|
|
4189
|
+
width: 9rem;
|
|
4190
|
+
}
|
|
4191
|
+
|
|
4192
|
+
.ck-compare-picker th:last-child,
|
|
4193
|
+
.ck-compare-picker td:last-child {
|
|
4194
|
+
width: 8rem;
|
|
4195
|
+
}
|
|
4196
|
+
|
|
4168
4197
|
table.ck-runs-table {
|
|
4169
4198
|
table-layout: fixed;
|
|
4170
4199
|
width: 100%;
|
|
@@ -3,6 +3,7 @@ module CompletionKit
|
|
|
3
3
|
module V1
|
|
4
4
|
class BaseController < ActionController::API
|
|
5
5
|
rate_limit to: CompletionKit.config.api_rate_limit, within: 1.minute,
|
|
6
|
+
by: -> { CompletionKit.config.api_rate_limit_key.call(request) },
|
|
6
7
|
with: -> { render_error("Rate limit exceeded", status: :too_many_requests) }
|
|
7
8
|
before_action :authenticate_api!
|
|
8
9
|
rescue_from ConfigurationError, with: :render_configuration_error
|
|
@@ -25,12 +25,15 @@ module CompletionKit
|
|
|
25
25
|
end
|
|
26
26
|
|
|
27
27
|
def update
|
|
28
|
-
|
|
28
|
+
publish = publish_flag
|
|
29
|
+
return render_error("publish must be true or false", status: :unprocessable_entity) if publish.nil?
|
|
30
|
+
|
|
31
|
+
if @prompt.runs.exists? || (!publish && @prompt.current? && @prompt.behavioral_change?(prompt_params))
|
|
29
32
|
new_prompt = @prompt.build_next_version(prompt_params.to_h)
|
|
30
33
|
if new_prompt.valid?
|
|
31
34
|
CompletionKit::ApplicationRecord.transaction do
|
|
32
35
|
new_prompt.save!
|
|
33
|
-
new_prompt.publish!
|
|
36
|
+
new_prompt.publish! if publish
|
|
34
37
|
end
|
|
35
38
|
render json: new_prompt.reload
|
|
36
39
|
else
|
|
@@ -68,6 +71,15 @@ module CompletionKit
|
|
|
68
71
|
def prompt_params
|
|
69
72
|
params.permit(:name, :description, :template, :llm_model, tag_names: [])
|
|
70
73
|
end
|
|
74
|
+
|
|
75
|
+
PUBLISH_VALUES = {"true" => true, "1" => true, "false" => false, "0" => false}.freeze
|
|
76
|
+
|
|
77
|
+
def publish_flag
|
|
78
|
+
value = params[:publish]
|
|
79
|
+
return true if value.blank? && value != false
|
|
80
|
+
|
|
81
|
+
PUBLISH_VALUES[value.to_s]
|
|
82
|
+
end
|
|
71
83
|
end
|
|
72
84
|
end
|
|
73
85
|
end
|
|
@@ -65,13 +65,8 @@ module CompletionKit
|
|
|
65
65
|
|
|
66
66
|
private
|
|
67
67
|
|
|
68
|
-
BEHAVIORAL_ATTRS = %w[template llm_model].freeze
|
|
69
|
-
|
|
70
68
|
def behavioral_change?
|
|
71
|
-
|
|
72
|
-
BEHAVIORAL_ATTRS.any? do |attr|
|
|
73
|
-
permitted.key?(attr) && permitted[attr].to_s != @prompt.public_send(attr).to_s
|
|
74
|
-
end
|
|
69
|
+
@prompt.behavioral_change?(prompt_params)
|
|
75
70
|
end
|
|
76
71
|
|
|
77
72
|
def set_prompt
|
|
@@ -88,9 +88,10 @@ module CompletionKit
|
|
|
88
88
|
def compare
|
|
89
89
|
other_id = params[:with]
|
|
90
90
|
if other_id.blank?
|
|
91
|
-
@other_runs = Run.where(dataset_id: @run.dataset_id, prompt_id:
|
|
91
|
+
@other_runs = Run.where(dataset_id: @run.dataset_id, prompt_id: comparable_prompt_ids)
|
|
92
92
|
.where.not(id: @run.id)
|
|
93
93
|
.display_scoped
|
|
94
|
+
.includes(:prompt)
|
|
94
95
|
.order(created_at: :desc)
|
|
95
96
|
.limit(50)
|
|
96
97
|
return render(:compare_picker)
|
|
@@ -171,6 +172,12 @@ module CompletionKit
|
|
|
171
172
|
|
|
172
173
|
private
|
|
173
174
|
|
|
175
|
+
def comparable_prompt_ids
|
|
176
|
+
return nil unless @run.prompt
|
|
177
|
+
|
|
178
|
+
@run.prompt.family_versions.select(:id)
|
|
179
|
+
end
|
|
180
|
+
|
|
174
181
|
def set_run
|
|
175
182
|
@run = Run.find(params[:id])
|
|
176
183
|
end
|
|
@@ -56,6 +56,13 @@ module CompletionKit
|
|
|
56
56
|
self.class.where(family_key: family_key).order(version_number: :desc, created_at: :desc)
|
|
57
57
|
end
|
|
58
58
|
|
|
59
|
+
BEHAVIORAL_ATTRS = %w[template llm_model].freeze
|
|
60
|
+
|
|
61
|
+
def behavioral_change?(attrs)
|
|
62
|
+
attrs = attrs.to_h.stringify_keys
|
|
63
|
+
BEHAVIORAL_ATTRS.any? { |attr| attrs.key?(attr) && attrs[attr].to_s != public_send(attr).to_s }
|
|
64
|
+
end
|
|
65
|
+
|
|
59
66
|
def build_next_version(overrides = {})
|
|
60
67
|
version = self.class.new(
|
|
61
68
|
{
|
|
@@ -5,7 +5,8 @@ module CompletionKit
|
|
|
5
5
|
|
|
6
6
|
TOOLS = {
|
|
7
7
|
"agreements_list" => {
|
|
8
|
-
description: "List
|
|
8
|
+
description: "List human reviews of the LLM judge's scores: each agree, disagree or borderline verdict, with any corrected score and note. Filter by run_id, response_id, metric_id, or created_by. Use it to see where people disagreed with the judge before improving a metric's rubric. It returns each verdict, oldest first, with its run, response, metric and metric version ids, who recorded it and when.",
|
|
9
|
+
annotations: Base::READ_ONLY,
|
|
9
10
|
inputSchema: {
|
|
10
11
|
type: "object",
|
|
11
12
|
properties: {
|
|
@@ -19,7 +20,8 @@ module CompletionKit
|
|
|
19
20
|
handler: :list
|
|
20
21
|
},
|
|
21
22
|
"agreements_create" => {
|
|
22
|
-
description: "
|
|
23
|
+
description: "Record whether a person agrees with the LLM judge's score on one response for one metric, so you can measure how far to trust the judge. The response must belong to the given run. Verdict is one of agree, disagree, borderline. corrected_score (1..5) is required when verdict is 'disagree'. This upserts an agreement for (run, response, metric, created_by): a new verdict with the same created_by (default \"mcp\") replaces the earlier one, including its corrected score and note, and leaving either out clears it. The verdict is filed under the metric's current judge version, which is the version judges_compare counts it for, even when an earlier version scored that response. It works only for llm_judge metrics, because checks have nothing to calibrate. It returns the saved verdict.",
|
|
24
|
+
annotations: Base::DESTRUCTIVE,
|
|
23
25
|
inputSchema: {
|
|
24
26
|
type: "object",
|
|
25
27
|
properties: {
|