xfuser 0.3.2__tar.gz → 0.3.4__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {xfuser-0.3.2/xfuser.egg-info → xfuser-0.3.4}/PKG-INFO +147 -72
- {xfuser-0.3.2 → xfuser-0.3.4}/README.md +143 -70
- {xfuser-0.3.2/comfyui-xdit → xfuser-0.3.4/http-service}/host.py +5 -5
- {xfuser-0.3.2/comfyui-xdit → xfuser-0.3.4/http-service}/launch_host.py +1 -1
- {xfuser-0.3.2 → xfuser-0.3.4}/setup.py +3 -1
- xfuser-0.3.4/xfuser/__version__.py +1 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/config/args.py +74 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/config/config.py +21 -0
- xfuser-0.3.4/xfuser/core/__init__.py +9 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/core/distributed/runtime_state.py +5 -5
- xfuser-0.3.4/xfuser/core/fast_attention/__init__.py +37 -0
- xfuser-0.3.4/xfuser/core/fast_attention/attn_layer.py +220 -0
- xfuser-0.3.4/xfuser/core/fast_attention/fast_attn_state.py +115 -0
- xfuser-0.3.4/xfuser/core/fast_attention/utils.py +232 -0
- xfuser-0.3.4/xfuser/core/long_ctx_attention/__init__.py +7 -0
- xfuser-0.3.4/xfuser/core/long_ctx_attention/hybrid/__init__.py +7 -0
- xfuser-0.3.4/xfuser/core/long_ctx_attention/hybrid/attn_layer.py +178 -0
- xfuser-0.3.4/xfuser/core/long_ctx_attention/ring/__init__.py +5 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/core/long_ctx_attention/ring/ring_flash_attn.py +4 -3
- xfuser-0.3.4/xfuser/model_executor/__init__.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/base_wrapper.py +2 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/layers/attention_processor.py +50 -27
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/layers/embeddings.py +42 -18
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/models/transformers/base_transformer.py +80 -33
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/models/transformers/cogvideox_transformer_3d.py +1 -1
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/models/transformers/hunyuan_transformer_2d.py +2 -1
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/models/transformers/transformer_flux.py +37 -15
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/models/transformers/transformer_sd3.py +1 -1
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/pipelines/base_pipeline.py +118 -8
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/pipelines/pipeline_cogvideox.py +31 -26
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/pipelines/pipeline_flux.py +315 -41
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/pipelines/pipeline_hunyuandit.py +15 -4
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/pipelines/pipeline_latte.py +3 -2
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/pipelines/pipeline_pixart_alpha.py +16 -4
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/pipelines/pipeline_pixart_sigma.py +18 -4
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/pipelines/pipeline_stable_diffusion_3.py +21 -10
- {xfuser-0.3.2 → xfuser-0.3.4/xfuser.egg-info}/PKG-INFO +147 -72
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser.egg-info/SOURCES.txt +7 -6
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser.egg-info/requires.txt +3 -1
- xfuser-0.3.4/xfuser.egg-info/top_level.txt +2 -0
- xfuser-0.3.2/comfyui-xdit/__init__.py +0 -2
- xfuser-0.3.2/comfyui-xdit/nodes.py +0 -176
- xfuser-0.3.2/comfyui-xdit/utils.py +0 -7
- xfuser-0.3.2/xfuser/__version__.py +0 -1
- xfuser-0.3.2/xfuser/core/__init__.py +0 -15
- xfuser-0.3.2/xfuser/core/long_ctx_attention/__init__.py +0 -13
- xfuser-0.3.2/xfuser/core/long_ctx_attention/hybrid/__init__.py +0 -11
- xfuser-0.3.2/xfuser/core/long_ctx_attention/hybrid/attn_layer.py +0 -327
- xfuser-0.3.2/xfuser/core/long_ctx_attention/hybrid/utils.py +0 -11
- xfuser-0.3.2/xfuser/core/long_ctx_attention/ring/__init__.py +0 -5
- xfuser-0.3.2/xfuser.egg-info/top_level.txt +0 -2
- {xfuser-0.3.2 → xfuser-0.3.4}/LICENSE.txt +0 -0
- {xfuser-0.3.2/xfuser/model_executor → xfuser-0.3.4/http-service}/__init__.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/setup.cfg +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/__init__.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/config/__init__.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/core/cache_manager/__init__.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/core/cache_manager/cache_manager.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/core/distributed/__init__.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/core/distributed/group_coordinator.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/core/distributed/parallel_state.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/core/distributed/utils.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/core/long_ctx_attention/ulysses/__init__.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/core/long_ctx_attention/ulysses/attn_layer.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/core/utils/__init__.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/core/utils/timer.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/envs.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/logger.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/layers/__init__.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/layers/base_layer.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/layers/conv.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/layers/feedforward.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/layers/register.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/models/__init__.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/models/base_model.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/models/transformers/__init__.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/models/transformers/latte_transformer_3d.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/models/transformers/pixart_transformer_2d.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/models/transformers/register.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/pipelines/__init__.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/pipelines/register.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/schedulers/__init__.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/schedulers/base_scheduler.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/schedulers/register.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/schedulers/scheduling_ddim.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/schedulers/scheduling_ddim_cogvideox.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/schedulers/scheduling_ddpm.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/schedulers/scheduling_dpm_cogvideox.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/schedulers/scheduling_dpmsolver_multistep.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/model_executor/schedulers/scheduling_flow_match_euler_discrete.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser/parallel.py +0 -0
- {xfuser-0.3.2 → xfuser-0.3.4}/xfuser.egg-info/dependency_links.txt +0 -0
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.1
|
|
2
2
|
Name: xfuser
|
|
3
|
-
Version: 0.3.
|
|
3
|
+
Version: 0.3.4
|
|
4
4
|
Summary: xDiT: A Scalable Inference Engine for Diffusion Transformers (DiTs) on multi-GPU Clusters
|
|
5
5
|
Home-page: https://github.com/xdit-project/xDiT.
|
|
6
6
|
Author: xDiT Team
|
|
@@ -12,7 +12,7 @@ Description-Content-Type: text/markdown
|
|
|
12
12
|
License-File: LICENSE.txt
|
|
13
13
|
Requires-Dist: torch>=2.1.0
|
|
14
14
|
Requires-Dist: accelerate>=0.33.0
|
|
15
|
-
Requires-Dist: diffusers>=0.
|
|
15
|
+
Requires-Dist: diffusers>=0.31
|
|
16
16
|
Requires-Dist: transformers>=4.39.1
|
|
17
17
|
Requires-Dist: sentencepiece>=0.1.99
|
|
18
18
|
Requires-Dist: beautifulsoup4>=4.12.3
|
|
@@ -21,6 +21,8 @@ Requires-Dist: yunchang>=0.3.0
|
|
|
21
21
|
Requires-Dist: pytest
|
|
22
22
|
Requires-Dist: flask
|
|
23
23
|
Requires-Dist: opencv-python
|
|
24
|
+
Requires-Dist: imageio
|
|
25
|
+
Requires-Dist: imageio-ffmpeg
|
|
24
26
|
Provides-Extra: flash-attn
|
|
25
27
|
Requires-Dist: flash_attn>=2.6.3; extra == "flash-attn"
|
|
26
28
|
|
|
@@ -29,12 +31,11 @@ Requires-Dist: flash_attn>=2.6.3; extra == "flash-attn"
|
|
|
29
31
|
<p align="center">
|
|
30
32
|
|
|
31
33
|
<picture>
|
|
32
|
-
<img alt="xDiT" src="
|
|
33
|
-
</picture>
|
|
34
|
+
<img alt="xDiT" src="https://raw.githubusercontent.com/xdit-project/xdit_assets/main/XDiTlogo.png" width="50%">
|
|
34
35
|
|
|
35
36
|
</p>
|
|
36
37
|
<h3>A Scalable Inference Engine for Diffusion Transformers (DiTs) on multi-GPU Clusters</h3>
|
|
37
|
-
<strong><a href="https://arxiv.org/abs/2405.14430">📃 Paper</a> | <a href="#QuickStart">🚀 Quick Start</a> | <a href="#support-dits">🎯 Supported DiTs</a> | <a href="#dev-guide">📚 Dev Guide </a> | <a href="https://github.com/xdit-project/xDiT/discussions">📈 Discussion </a> </strong>
|
|
38
|
+
<strong><a href="https://arxiv.org/abs/2405.14430">📃 Paper</a> | <a href="#QuickStart">🚀 Quick Start</a> | <a href="#support-dits">🎯 Supported DiTs</a> | <a href="#dev-guide">📚 Dev Guide </a> | <a href="https://github.com/xdit-project/xDiT/discussions">📈 Discussion </a> | <a href="https://medium.com/@xditproject">📝 Blogs</a></strong>
|
|
38
39
|
<p></p>
|
|
39
40
|
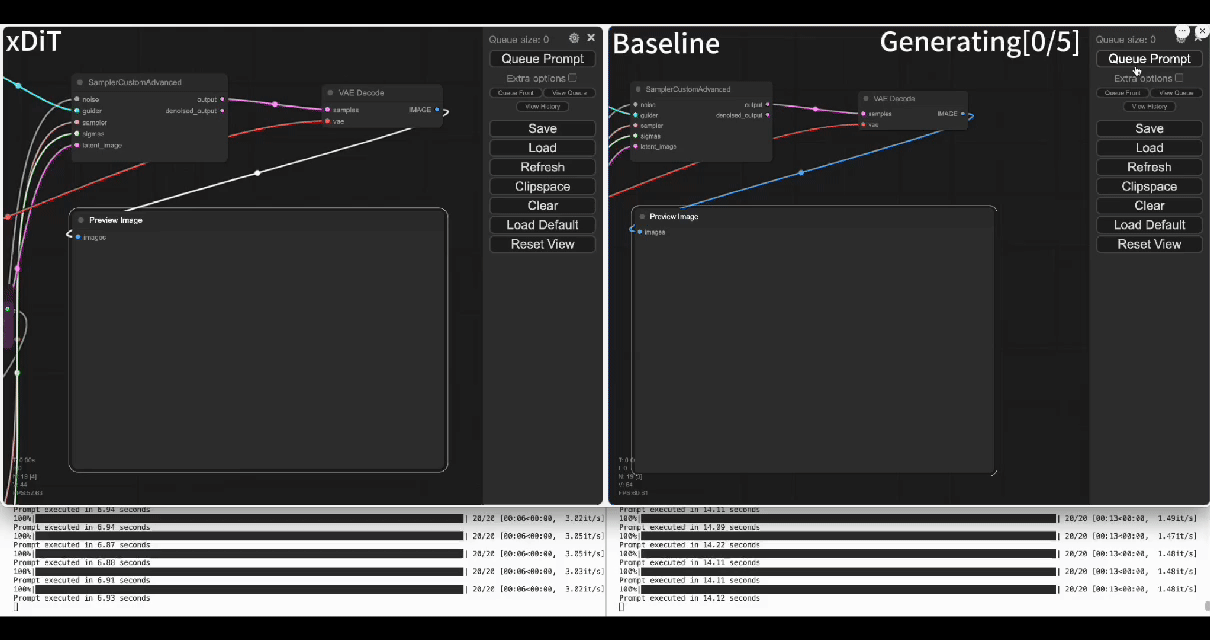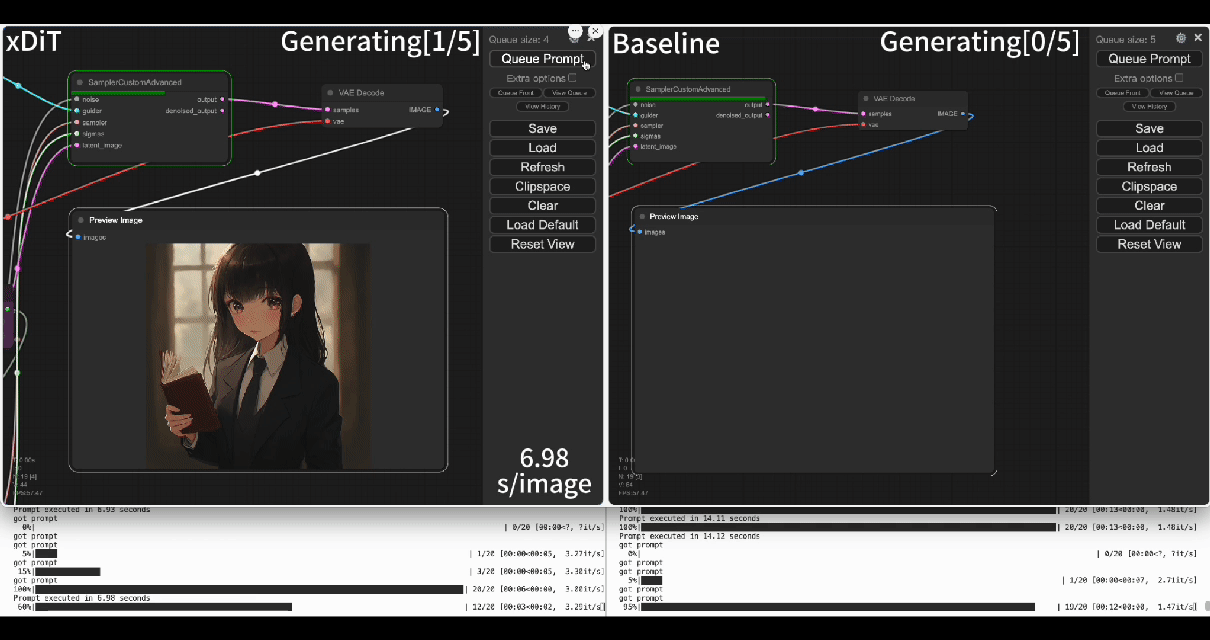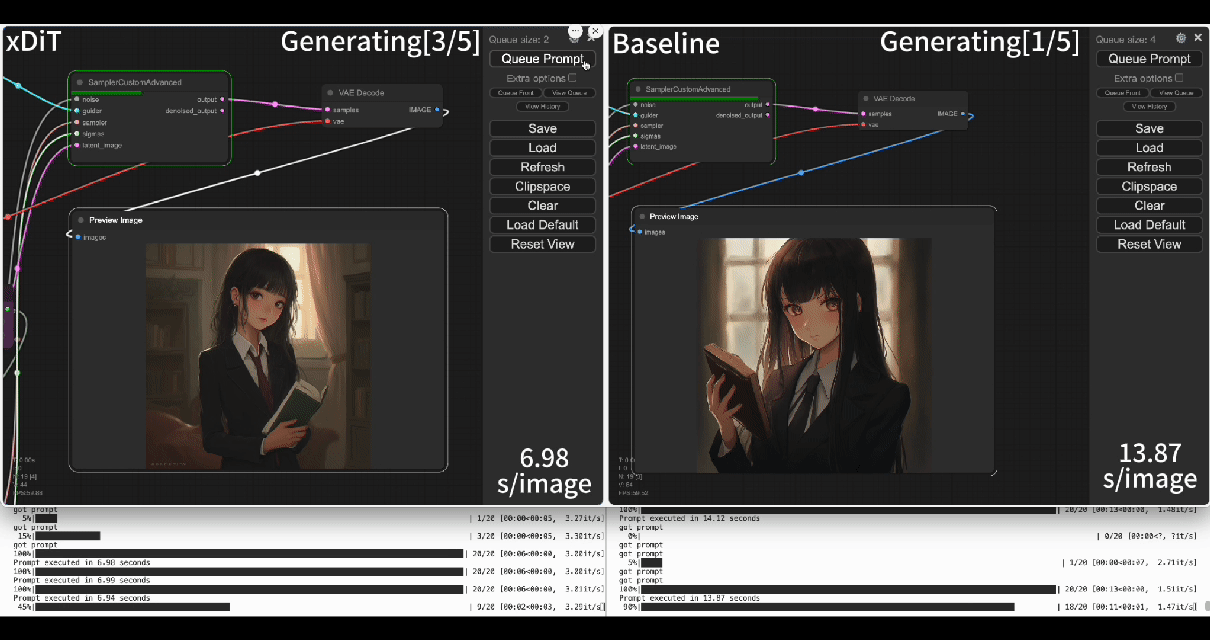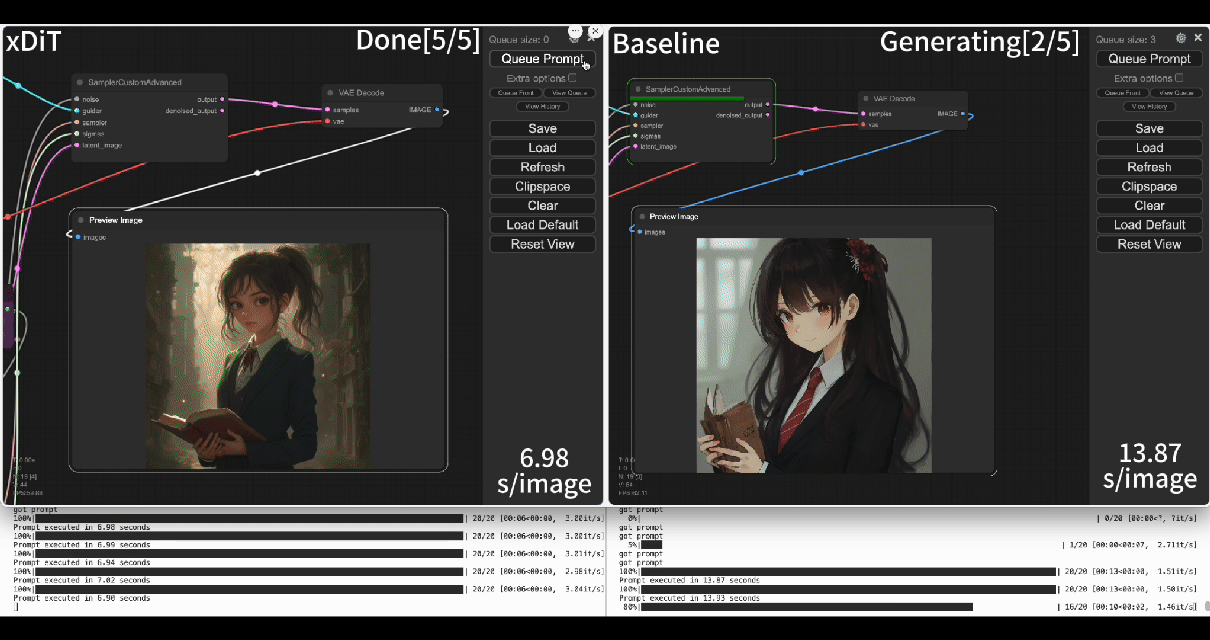
|
|
40
41
|
[](https://discord.gg/YEWzWfCF9S)
|
|
@@ -47,12 +48,14 @@ Requires-Dist: flash_attn>=2.6.3; extra == "flash-attn"
|
|
|
47
48
|
- [📢 Updates](#updates)
|
|
48
49
|
- [🎯 Supported DiTs](#support-dits)
|
|
49
50
|
- [📈 Performance](#perf)
|
|
51
|
+
- [CogVideoX](#perf_cogvideox)
|
|
50
52
|
- [Flux.1](#perf_flux)
|
|
51
53
|
- [HunyuanDiT](#perf_hunyuandit)
|
|
52
54
|
- [SD3](#perf_sd3)
|
|
53
55
|
- [Pixart](#perf_pixart)
|
|
54
56
|
- [Latte](#perf_latte)
|
|
55
57
|
- [🚀 QuickStart](#QuickStart)
|
|
58
|
+
- [🖼️ ComfyUI with xDiT](#comfyui)
|
|
56
59
|
- [✨ xDiT's Arsenal](#secrets)
|
|
57
60
|
- [Parallel Methods](#parallel)
|
|
58
61
|
- [1. PipeFusion](#PipeFusion)
|
|
@@ -60,7 +63,9 @@ Requires-Dist: flash_attn>=2.6.3; extra == "flash-attn"
|
|
|
60
63
|
- [3. Hybrid Parallel](#hybrid_parallel)
|
|
61
64
|
- [4. CFG Parallel](#cfg_parallel)
|
|
62
65
|
- [5. Parallel VAE](#parallel_vae)
|
|
63
|
-
- [
|
|
66
|
+
- [Single GPU Acceleration](#1gpuacc)
|
|
67
|
+
- [Compilation Acceleration](#compilation)
|
|
68
|
+
- [DiTFastAttn](#dittfastattn)
|
|
64
69
|
- [📚 Develop Guide](#dev-guide)
|
|
65
70
|
- [🚧 History and Looking for Contributions](#history)
|
|
66
71
|
- [📝 Cite Us](#cite-us)
|
|
@@ -72,14 +77,23 @@ Diffusion Transformers (DiTs) are driving advancements in high-quality image and
|
|
|
72
77
|
With the escalating input context length in DiTs, the computational demand of the Attention mechanism grows **quadratically**!
|
|
73
78
|
Consequently, multi-GPU and multi-machine deployments are essential to meet the **real-time** requirements in online services.
|
|
74
79
|
|
|
80
|
+
|
|
81
|
+
<h3 id="meet-xdit-parallel">Parallel Inference</h3>
|
|
82
|
+
|
|
75
83
|
To meet real-time demand for DiTs applications, parallel inference is a must.
|
|
76
84
|
xDiT is an inference engine designed for the parallel deployment of DiTs on large scale.
|
|
77
|
-
xDiT provides a suite of efficient parallel approaches for Diffusion Models, as well as
|
|
85
|
+
xDiT provides a suite of efficient parallel approaches for Diffusion Models, as well as computation accelerations.
|
|
86
|
+
|
|
87
|
+
The overview of xDiT is shown as follows.
|
|
88
|
+
|
|
89
|
+
<picture>
|
|
90
|
+
<img alt="xDiT" src="https://raw.githubusercontent.com/xdit-project/xdit_assets/main/methods/xdit_overview.png">
|
|
91
|
+
</picture>
|
|
78
92
|
|
|
79
93
|
|
|
80
|
-
1. Sequence Parallelism, [USP](https://arxiv.org/abs/2405.07719) is a unified sequence parallel approach combining DeepSpeed-Ulysses, Ring-Attention.
|
|
94
|
+
1. Sequence Parallelism, [USP](https://arxiv.org/abs/2405.07719) is a unified sequence parallel approach combining DeepSpeed-Ulysses, Ring-Attention proposed by use3.
|
|
81
95
|
|
|
82
|
-
2. [PipeFusion](https://arxiv.org/abs/2405.14430), a
|
|
96
|
+
2. [PipeFusion](https://arxiv.org/abs/2405.14430), a sequence-level pipeline parallelism, similar to [TeraPipe](https://arxiv.org/abs/2102.07988) but takes advantage of the input temporal redundancy characteristics of diffusion models.
|
|
83
97
|
|
|
84
98
|
3. Data Parallel: Processes multiple prompts or generates multiple images from a single prompt in parallel across images.
|
|
85
99
|
|
|
@@ -96,28 +110,27 @@ We also have implemented the following parallel stategies for reference:
|
|
|
96
110
|
2. [DistriFusion](https://arxiv.org/abs/2402.19481)
|
|
97
111
|
|
|
98
112
|
|
|
99
|
-
|
|
100
|
-
In addition to utilizing well-known Attention optimization libraries, we leverage compilation acceleration technologies such as `torch.compile` and `onediff`.
|
|
113
|
+
<h3 id="meet-xdit-perf">Computing Acceleration</h3>
|
|
101
114
|
|
|
102
|
-
|
|
115
|
+
Optimization orthogonal to parallel focuses on accelerating single GPU performance.
|
|
103
116
|
|
|
104
|
-
|
|
105
|
-
<img alt="xDiT" src="./assets/methods/xdit_overview.png">
|
|
106
|
-
</picture>
|
|
117
|
+
First, xDiT employs a series of kernel acceleration methods. In addition to utilizing well-known Attention optimization libraries, we leverage compilation acceleration technologies such as `torch.compile` and `onediff`.
|
|
107
118
|
|
|
119
|
+
Furthermore, xDiT incorporates optimization techniques from [DiTFastAttn](https://github.com/thu-nics/DiTFastAttn), which exploits computational redundancies between different steps of the Diffusion Model to accelerate inference on a single GPU.
|
|
108
120
|
|
|
109
121
|
<h2 id="updates">📢 Updates</h2>
|
|
110
122
|
|
|
111
|
-
*
|
|
123
|
+
* 🎉**October 10, 2024**: xDiT applied DiTFastAttn to accelerate single GPU inference for Pixart Models!
|
|
124
|
+
* 🎉**September 26, 2024**: xDiT has been officially used by [THUDM/CogVideo](https://github.com/THUDM/CogVideo)! The inference scripts are placed in [parallel_inference/](https://github.com/THUDM/CogVideo/blob/main/tools/parallel_inference) at their repository.
|
|
125
|
+
* 🎉**September 23, 2024**: Support CogVideoX. The inference scripts are [examples/cogvideox_example.py](examples/cogvideox_example.py).
|
|
112
126
|
* 🎉**August 26, 2024**: We apply torch.compile and [onediff](https://github.com/siliconflow/onediff) nexfort backend to accelerate GPU kernels speed.
|
|
113
|
-
* 🎉**August
|
|
114
|
-
* 🎉**August
|
|
115
|
-
* 🎉**August
|
|
127
|
+
* 🎉**August 15, 2024**: Support Hunyuan-DiT hybrid parallel version. The inference scripts are [examples/hunyuandit_example.py](examples/hunyuandit_example.py).
|
|
128
|
+
* 🎉**August 9, 2024**: Support Latte sequence parallel version. The inference scripts are [examples/latte_example.py](examples/latte_example.py).
|
|
129
|
+
* 🎉**August 8, 2024**: Support Flux sequence parallel version. The inference scripts are [examples/flux_example.py](examples/flux_example.py).
|
|
130
|
+
* 🎉**August 2, 2024**: Support Stable Diffusion 3 hybrid parallel version. The inference scripts are [examples/sd3_example.py](examples/sd3_example.py).
|
|
116
131
|
* 🎉**July 18, 2024**: Support PixArt-Sigma and PixArt-Alpha. The inference scripts are [examples/pixartsigma_example.py](examples/pixartsigma_example.py), [examples/pixartalpha_example.py](examples/pixartalpha_example.py).
|
|
117
132
|
* 🎉**July 17, 2024**: Rename the project to xDiT. The project has evolved from a collection of parallel methods into a unified inference framework and supported the hybrid parallel for DiTs.
|
|
118
|
-
* 🎉**
|
|
119
|
-
* 🎉**June 26, 2024**: Support Stable Diffusion 3. The inference script is [legacy/scripts/sd3_example.py](./legacy/scripts/sd3_example.py).
|
|
120
|
-
* 🎉**May 24, 2024**: PipeFusion is public released. It supports PixArt-alpha [legacy/scripts/pixart_example.py](./legacy/scripts/pixart_example.py), DiT [legacy/scripts/ditxl_example.py](./legacy/scripts/ditxl_example.py) and SDXL [legacy/scripts/sdxl_example.py](./legacy/scripts/sdxl_example.py).
|
|
133
|
+
* 🎉**May 24, 2024**: PipeFusion is public released. It supports PixArt-alpha [scripts/pixart_example.py](./scripts/pixart_example.py), DiT [scripts/ditxl_example.py](./scripts/ditxl_example.py) and SDXL [scripts/sdxl_example.py](./scripts/sdxl_example.py). This version is currently in the `legacy` branch.
|
|
121
134
|
|
|
122
135
|
|
|
123
136
|
<h2 id="support-dits">🎯 Supported DiTs</h2>
|
|
@@ -126,10 +139,10 @@ The overview of xDiT is shown as follows.
|
|
|
126
139
|
|
|
127
140
|
| Model Name | CFG | SP | PipeFusion |
|
|
128
141
|
| --- | --- | --- | --- |
|
|
129
|
-
| [🎬 CogVideoX](https://huggingface.co/THUDM/CogVideoX-2b) |
|
|
142
|
+
| [🎬 CogVideoX](https://huggingface.co/THUDM/CogVideoX-2b) | ✔️ | ✔️ | ❎ |
|
|
130
143
|
| [🎬 Latte](https://huggingface.co/maxin-cn/Latte-1) | ❎ | ✔️ | ❎ |
|
|
131
144
|
| [🔵 HunyuanDiT-v1.2-Diffusers](https://huggingface.co/Tencent-Hunyuan/HunyuanDiT-v1.2-Diffusers) | ✔️ | ✔️ | ✔️ |
|
|
132
|
-
| [🟠 Flux](https://huggingface.co/black-forest-labs/FLUX.1-schnell) | NA | ✔️ |
|
|
145
|
+
| [🟠 Flux](https://huggingface.co/black-forest-labs/FLUX.1-schnell) | NA | ✔️ | ✔️ |
|
|
133
146
|
| [🔴 PixArt-Sigma](https://huggingface.co/PixArt-alpha/PixArt-Sigma-XL-2-1024-MS) | ✔️ | ✔️ | ✔️ |
|
|
134
147
|
| [🟢 PixArt-alpha](https://huggingface.co/PixArt-alpha/PixArt-alpha) | ✔️ | ✔️ | ✔️ |
|
|
135
148
|
| [🟠 Stable Diffusion 3](https://huggingface.co/stabilityai/stable-diffusion-3-medium-diffusers) | ✔️ | ✔️ | ✔️ |
|
|
@@ -145,30 +158,34 @@ The overview of xDiT is shown as follows.
|
|
|
145
158
|
|
|
146
159
|
<h2 id="perf">📈 Performance</h2>
|
|
147
160
|
|
|
161
|
+
<h3 id="perf_cogvideox">CogVideo</h3>
|
|
162
|
+
|
|
163
|
+
1. [CogVideo Performance Report](./docs/performance/cogvideo.md)
|
|
164
|
+
|
|
148
165
|
<h3 id="perf_flux">Flux.1</h3>
|
|
149
166
|
|
|
150
|
-
|
|
167
|
+
2. [Flux Performance Report](./docs/performance/flux.md)
|
|
168
|
+
|
|
169
|
+
<h3 id="perf_latte">Latte</h3>
|
|
170
|
+
|
|
171
|
+
3. [Latte Performance Report](./docs/performance/latte.md)
|
|
151
172
|
|
|
152
173
|
<h3 id="perf_hunyuandit">HunyuanDiT</h3>
|
|
153
174
|
|
|
154
|
-
|
|
175
|
+
4. [HunyuanDiT Performance Report](./docs/performance/hunyuandit.md)
|
|
155
176
|
|
|
156
177
|
<h3 id="perf_sd3">SD3</h3>
|
|
157
178
|
|
|
158
|
-
|
|
179
|
+
5. [Stable Diffusion 3 Performance Report](./docs/performance/sd3.md)
|
|
159
180
|
|
|
160
181
|
<h3 id="perf_pixart">Pixart</h3>
|
|
161
182
|
|
|
162
|
-
|
|
163
|
-
|
|
164
|
-
<h3 id="perf_latte">Pixart</h3>
|
|
165
|
-
|
|
166
|
-
5. [Latte Performance Report](./docs/performance/latte.md)
|
|
183
|
+
6. [Pixart-Alpha Performance Report (legacy)](./docs/performance/pixart_alpha_legacy.md)
|
|
167
184
|
|
|
168
185
|
|
|
169
186
|
<h2 id="QuickStart">🚀 QuickStart</h2>
|
|
170
187
|
|
|
171
|
-
### 1. Install from pip
|
|
188
|
+
### 1. Install from pip
|
|
172
189
|
|
|
173
190
|
```
|
|
174
191
|
pip install xfuser
|
|
@@ -191,7 +208,11 @@ Note that we use two self-maintained packages:
|
|
|
191
208
|
|
|
192
209
|
The [flash_attn](https://github.com/Dao-AILab/flash-attention) used for yunchang should be >= 2.6.0
|
|
193
210
|
|
|
194
|
-
### 3.
|
|
211
|
+
### 3. Docker
|
|
212
|
+
|
|
213
|
+
We provide a docker image for developers to develop with xDiT. The docker image is [thufeifeibear/xdit-dev](https://hub.docker.com/r/thufeifeibear/xdit-dev).
|
|
214
|
+
|
|
215
|
+
### 4. Usage
|
|
195
216
|
|
|
196
217
|
We provide examples demonstrating how to run models with xDiT in the [./examples/](./examples/) directory.
|
|
197
218
|
You can easily modify the model type, model directory, and parallel options in the [examples/run.sh](examples/run.sh) within the script to run some already supported DiT models.
|
|
@@ -200,7 +221,10 @@ You can easily modify the model type, model directory, and parallel options in t
|
|
|
200
221
|
bash examples/run.sh
|
|
201
222
|
```
|
|
202
223
|
|
|
203
|
-
|
|
224
|
+
---
|
|
225
|
+
|
|
226
|
+
<details>
|
|
227
|
+
<summary>Click to see available options for the PixArt-alpha example</summary>
|
|
204
228
|
|
|
205
229
|
```bash
|
|
206
230
|
python ./examples/pixartalpha_example.py -h
|
|
@@ -260,10 +284,14 @@ Input Options:
|
|
|
260
284
|
Number of inference steps.
|
|
261
285
|
```
|
|
262
286
|
|
|
287
|
+
</details>
|
|
288
|
+
|
|
289
|
+
---
|
|
290
|
+
|
|
263
291
|
Hybriding multiple parallelism techniques togather is essential for efficiently scaling.
|
|
264
292
|
It's important that the product of all parallel degrees matches the number of devices.
|
|
265
|
-
For instance, you can combine CFG, PipeFusion, and sequence parallelism with the command below to generate an image of a cute dog through hybrid parallelism.
|
|
266
|
-
Here ulysses_degree * pipefusion_parallel_degree * cfg_degree(
|
|
293
|
+
Note use_cfg_parallel means cfg_parallel=2. For instance, you can combine CFG, PipeFusion, and sequence parallelism with the command below to generate an image of a cute dog through hybrid parallelism.
|
|
294
|
+
Here ulysses_degree * pipefusion_parallel_degree * cfg_degree(use_cfg_parallel) == number of devices == 8.
|
|
267
295
|
|
|
268
296
|
|
|
269
297
|
```bash
|
|
@@ -284,14 +312,26 @@ We observed that a warmup of 0 had no effect on the PixArt model.
|
|
|
284
312
|
Users can tune this value according to their specific tasks.
|
|
285
313
|
|
|
286
314
|
|
|
315
|
+
<h2 id="comfyui">🖼️ ComfyUI with xDiT</h2>
|
|
287
316
|
|
|
288
|
-
###
|
|
317
|
+
### 1. Launch ComfyUI
|
|
289
318
|
|
|
290
|
-
|
|
319
|
+
ComfyUI, is the most popular web-based Diffusion Model interface optimized for workflow.
|
|
320
|
+
It provides users with a UI platform for image generation, supporting plugins like LoRA, ControlNet, and IPAdaptor.
|
|
321
|
+
Yet, its design for native single-GPU usage leaves it struggling with the demands of today’s large DiTs, resulting in unacceptably high latency for users like Flux.1. Leveraging the power of xDiT, we’ve successfully implemented a multi-GPU parallel processing workflow within ComfyUI, effectively addressing Flux.1’s performance challenges.
|
|
322
|
+
Below is an example of using xDiT to accelerate a Flux workflow with LoRA:
|
|
323
|
+
|
|
324
|
+
|
|
325
|
+
|
|
326
|
+
More details can be found in our Medium article: [Supercharge Your AIGC Experience: Leverage xDiT for Multiple GPU Parallel in ComfyUI Flux.1 Workflow](https://medium.com/@xditproject/supercharge-your-aigc-experience-leverage-xdit-for-multiple-gpu-parallel-in-comfyui-flux-1-54b34e4bca05).
|
|
291
327
|
|
|
292
|
-
|
|
328
|
+
Currently, if you need the parallel version of ComfyUI applying xDiT, please contact us via email [jiaruifang@tencent.com](jiaruifang@tencent.com).
|
|
293
329
|
|
|
294
|
-
|
|
330
|
+
### 2. Launch a Http Service
|
|
331
|
+
|
|
332
|
+
You can also launch a http service to generate images with xDiT.
|
|
333
|
+
|
|
334
|
+
[Launching a Text-to-Image Http Service](./docs/developer/Http_Service.md)
|
|
295
335
|
|
|
296
336
|
|
|
297
337
|
<h2 id="secrets">✨ The xDiT's Arsenal</h2>
|
|
@@ -308,34 +348,32 @@ For the VAE module, xDiT offers a parallel implementation, [DistVAE](https://git
|
|
|
308
348
|
The (<span style="color: red;">xDiT</span>) highlights the methods first proposed by use.
|
|
309
349
|
|
|
310
350
|
<div align="center">
|
|
311
|
-
<img src="
|
|
351
|
+
<img src="https://raw.githubusercontent.com/xdit-project/xdit_assets/main/methods/xdit_method.png" alt="xdit methods">
|
|
312
352
|
</div>
|
|
313
353
|
|
|
314
354
|
The communication and memory costs associated with the aforementioned intra-image parallelism, except for the CFG and DP (they are inter-image parallel), in DiTs are detailed in the table below. (* denotes that communication can be overlapped with computation.)
|
|
315
355
|
|
|
316
356
|
As we can see, PipeFusion and Sequence Parallel achieve lowest communication cost on different scales and hardware configurations, making them suitable foundational components for a hybrid approach.
|
|
317
357
|
|
|
318
|
-
𝒑: Number of pixels
|
|
319
|
-
𝒉𝒔: Model hidden size
|
|
320
|
-
𝑳: Number of model layers
|
|
321
|
-
𝑷: Total model parameters
|
|
322
|
-
𝑵: Number of parallel devices
|
|
323
|
-
𝑴: Number of patch splits
|
|
324
|
-
𝑸𝑶: Query and Output parameter count
|
|
325
|
-
𝑲𝑽: KV Activation parameter count
|
|
358
|
+
𝒑: Number of pixels;\
|
|
359
|
+
𝒉𝒔: Model hidden size;\
|
|
360
|
+
𝑳: Number of model layers;\
|
|
361
|
+
𝑷: Total model parameters;\
|
|
362
|
+
𝑵: Number of parallel devices;\
|
|
363
|
+
𝑴: Number of patch splits;\
|
|
364
|
+
𝑸𝑶: Query and Output parameter count;\
|
|
365
|
+
𝑲𝑽: KV Activation parameter count;\
|
|
326
366
|
𝑨 = 𝑸 = 𝑶 = 𝑲 = 𝑽: Equal parameters for Attention, Query, Output, Key, and Value;
|
|
327
367
|
|
|
328
|
-
<div align="center">
|
|
329
368
|
|
|
330
|
-
|
|
|
331
|
-
|
|
332
|
-
| Tensor Parallel
|
|
333
|
-
| DistriFusion*
|
|
334
|
-
| Ring Sequence Parallel*
|
|
335
|
-
| Ulysses Sequence Parallel | fresh
|
|
336
|
-
| PipeFusion*
|
|
369
|
+
| | attn-KV | communication cost | param memory | activations memory | extra buff memory |
|
|
370
|
+
|:-------------------------:|:-------:|:----------------------------:|:--------------:|:------------------------------:|:----------------------------------:|
|
|
371
|
+
| Tensor Parallel | fresh | $4O(p \times hs)L$ | $\frac{1}{N}P$ | $\frac{2}{N}A = \frac{1}{N}QO$ | $\frac{2}{N}A = \frac{1}{N}KV$ |
|
|
372
|
+
| DistriFusion* | stale | $2O(p \times hs)L$ | $P$ | $\frac{2}{N}A = \frac{1}{N}QO$ | $2AL = (KV)L$ |
|
|
373
|
+
| Ring Sequence Parallel* | fresh | $2O(p \times hs)L$ | $P$ | $\frac{2}{N}A = \frac{1}{N}QO$ | $\frac{2}{N}A = \frac{1}{N}KV$ |
|
|
374
|
+
| Ulysses Sequence Parallel | fresh | $\frac{4}{N}O(p \times hs)L$ | $P$ | $\frac{2}{N}A = \frac{1}{N}QO$ | $\frac{2}{N}A = \frac{1}{N}KV$ |
|
|
375
|
+
| PipeFusion* | stale- | $2O(p \times hs)$ | $\frac{1}{N}P$ | $\frac{2}{M}A = \frac{1}{M}QO$ | $\frac{2L}{N}A = \frac{1}{N}(KV)L$ |
|
|
337
376
|
|
|
338
|
-
</div>
|
|
339
377
|
|
|
340
378
|
<h4 id="PipeFusion">1.1. PipeFusion</h4>
|
|
341
379
|
|
|
@@ -357,7 +395,10 @@ As we can see, PipeFusion and Sequence Parallel achieve lowest communication cos
|
|
|
357
395
|
|
|
358
396
|
[Patch Parallel VAE](./docs/methods/parallel_vae.md)
|
|
359
397
|
|
|
360
|
-
<h3 id="
|
|
398
|
+
<h3 id="1gpuacc">Single GPU Acceleration</h3>
|
|
399
|
+
|
|
400
|
+
|
|
401
|
+
<h4 id="compilation">Compilation Acceleration</h4>
|
|
361
402
|
|
|
362
403
|
We utilize two compilation acceleration techniques, [torch.compile](https://pytorch.org/tutorials/intermediate/torch_compile_tutorial.html) and [onediff](https://github.com/siliconflow/onediff), to enhance runtime speed on GPUs. These compilation accelerations are used in conjunction with parallelization methods.
|
|
363
404
|
|
|
@@ -371,6 +412,12 @@ pip install -U nexfort
|
|
|
371
412
|
For usage instructions, refer to the [example/run.sh](./examples/run.sh). Simply append `--use_torch_compile` or `--use_onediff` to your command. Note that these options are mutually exclusive, and their performance varies across different scenarios.
|
|
372
413
|
|
|
373
414
|
|
|
415
|
+
<h4 id="dittfastattn">DiTFastAttn</h4>
|
|
416
|
+
|
|
417
|
+
xDiT also provides DiTFastAttn for single GPU acceleration. It can reduce computation cost of attention layer by leveraging redundancies between different steps of the Diffusion Model.
|
|
418
|
+
|
|
419
|
+
[DiTFastAttn: Attention Compression for Diffusion Transformer Models](./docs/methods/ditfastattn.md)
|
|
420
|
+
|
|
374
421
|
<h2 id="dev-guide">📚 Develop Guide</h2>
|
|
375
422
|
|
|
376
423
|
[The implement and design of xdit framework](./docs/developer/The_implement_design_of_xdit_framework.md)
|
|
@@ -383,29 +430,57 @@ We conducted a major upgrade of this project in August 2024.
|
|
|
383
430
|
|
|
384
431
|
The latest APIs is located in the [xfuser/](./xfuser/) directory, supports hybrid parallelism. It offers clearer and more structured code but currently supports fewer models.
|
|
385
432
|
|
|
386
|
-
The legacy APIs is in the [legacy
|
|
433
|
+
The legacy APIs is in the [legacy](https://github.com/xdit-project/xDiT/tree/legacy) branch, limited to single parallelism. It supports a richer of parallel methods, including PipeFusion, Sequence Parallel, DistriFusion, and Tensor Parallel. CFG Parallel can be hybrid with PipeFusion but not with other parallel methods.
|
|
387
434
|
|
|
388
|
-
For models not yet supported by the latest APIs, you can run the examples in the [
|
|
435
|
+
For models not yet supported by the latest APIs, you can run the examples in the [scripts/](https://github.com/xdit-project/xDiT/tree/legacy/scripts) directory under branch `legacy`. If you wish to develop new features on a model or require hybrid parallelism, stay tuned for further project updates.
|
|
389
436
|
|
|
390
437
|
We also welcome developers to join and contribute more features and models to the project. Tell us which model you need in xDiT in [discussions](https://github.com/xdit-project/xDiT/discussions).
|
|
391
438
|
|
|
392
439
|
<h2 id="cite-us">📝 Cite Us</h2>
|
|
393
440
|
|
|
441
|
+
|
|
442
|
+
[xDiT: an Inference Engine for Diffusion Transformers (DiTs) with Massive Parallelism](https://arxiv.org/abs/2411.01738)
|
|
443
|
+
|
|
394
444
|
```
|
|
395
|
-
@
|
|
396
|
-
title={
|
|
397
|
-
author={
|
|
445
|
+
@misc{fang2024xditinferenceenginediffusion,
|
|
446
|
+
title={xDiT: an Inference Engine for Diffusion Transformers (DiTs) with Massive Parallelism},
|
|
447
|
+
author={Jiarui Fang and Jinzhe Pan and Xibo Sun and Aoyu Li and Jiannan Wang},
|
|
398
448
|
year={2024},
|
|
399
|
-
eprint={
|
|
449
|
+
eprint={2411.01738},
|
|
400
450
|
archivePrefix={arXiv},
|
|
401
|
-
primaryClass={cs.
|
|
451
|
+
primaryClass={cs.DC},
|
|
452
|
+
url={https://arxiv.org/abs/2411.01738},
|
|
402
453
|
}
|
|
403
454
|
|
|
404
|
-
|
|
405
|
-
|
|
406
|
-
|
|
407
|
-
|
|
408
|
-
|
|
455
|
+
```
|
|
456
|
+
|
|
457
|
+
[PipeFusion: Patch-level Pipeline Parallelism for Diffusion Transformers Inference](https://arxiv.org/abs/2405.14430)
|
|
458
|
+
|
|
459
|
+
```
|
|
460
|
+
@misc{fang2024pipefusionpatchlevelpipelineparallelism,
|
|
461
|
+
title={PipeFusion: Patch-level Pipeline Parallelism for Diffusion Transformers Inference},
|
|
462
|
+
author={Jiarui Fang and Jinzhe Pan and Jiannan Wang and Aoyu Li and Xibo Sun},
|
|
463
|
+
year={2024},
|
|
464
|
+
eprint={2405.14430},
|
|
465
|
+
archivePrefix={arXiv},
|
|
466
|
+
primaryClass={cs.CV},
|
|
467
|
+
url={https://arxiv.org/abs/2405.14430},
|
|
409
468
|
}
|
|
469
|
+
|
|
410
470
|
```
|
|
411
471
|
|
|
472
|
+
[USP: A Unified Sequence Parallelism Approach for Long Context Generative AI](https://arxiv.org/abs/2405.07719)
|
|
473
|
+
|
|
474
|
+
|
|
475
|
+
```
|
|
476
|
+
@misc{fang2024uspunifiedsequenceparallelism,
|
|
477
|
+
title={USP: A Unified Sequence Parallelism Approach for Long Context Generative AI},
|
|
478
|
+
author={Jiarui Fang and Shangchun Zhao},
|
|
479
|
+
year={2024},
|
|
480
|
+
eprint={2405.07719},
|
|
481
|
+
archivePrefix={arXiv},
|
|
482
|
+
primaryClass={cs.LG},
|
|
483
|
+
url={https://arxiv.org/abs/2405.07719},
|
|
484
|
+
}
|
|
485
|
+
|
|
486
|
+
```
|