whisper-memo 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- whisper_memo-0.1.0/.github/workflows/ci.yml +30 -0
- whisper_memo-0.1.0/.github/workflows/release.yml +26 -0
- whisper_memo-0.1.0/.gitignore +13 -0
- whisper_memo-0.1.0/CHANGELOG.md +17 -0
- whisper_memo-0.1.0/LICENSE +21 -0
- whisper_memo-0.1.0/PKG-INFO +115 -0
- whisper_memo-0.1.0/README.md +86 -0
- whisper_memo-0.1.0/docs/demo.gif +0 -0
- whisper_memo-0.1.0/pyproject.toml +57 -0
- whisper_memo-0.1.0/src/whisper_memo/__init__.py +5 -0
- whisper_memo-0.1.0/src/whisper_memo/__main__.py +3 -0
- whisper_memo-0.1.0/src/whisper_memo/cli.py +237 -0
- whisper_memo-0.1.0/tests/test_cli.py +47 -0
- whisper_memo-0.1.0/uv.lock +925 -0
|
@@ -0,0 +1,30 @@
|
|
|
1
|
+
name: CI
|
|
2
|
+
|
|
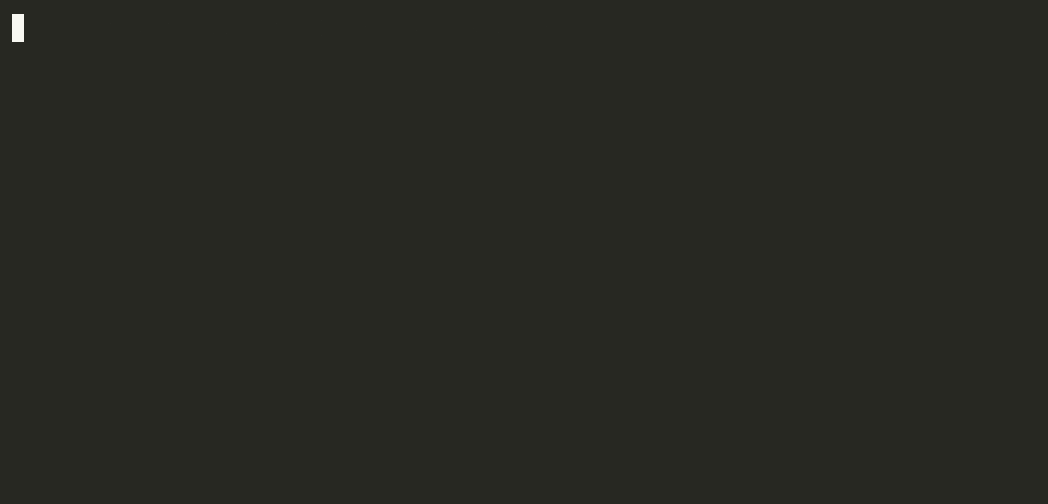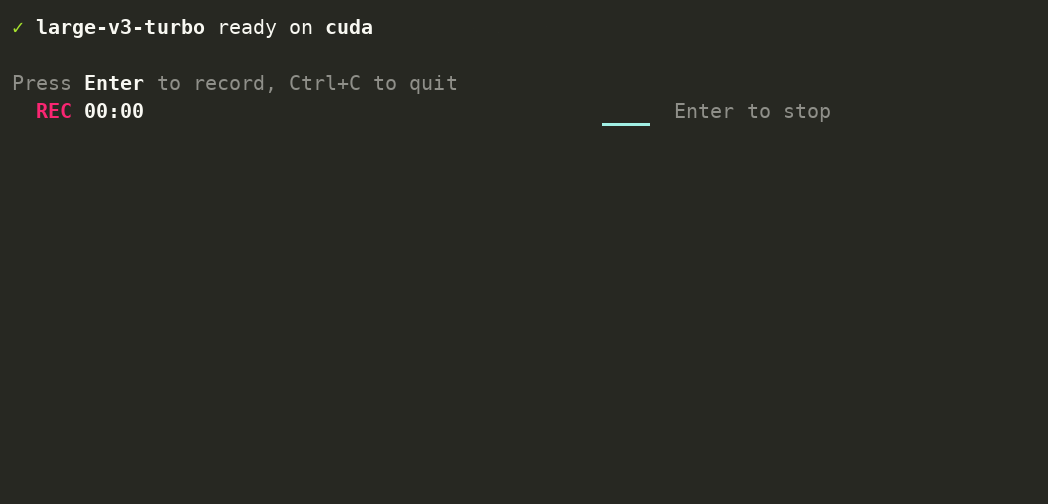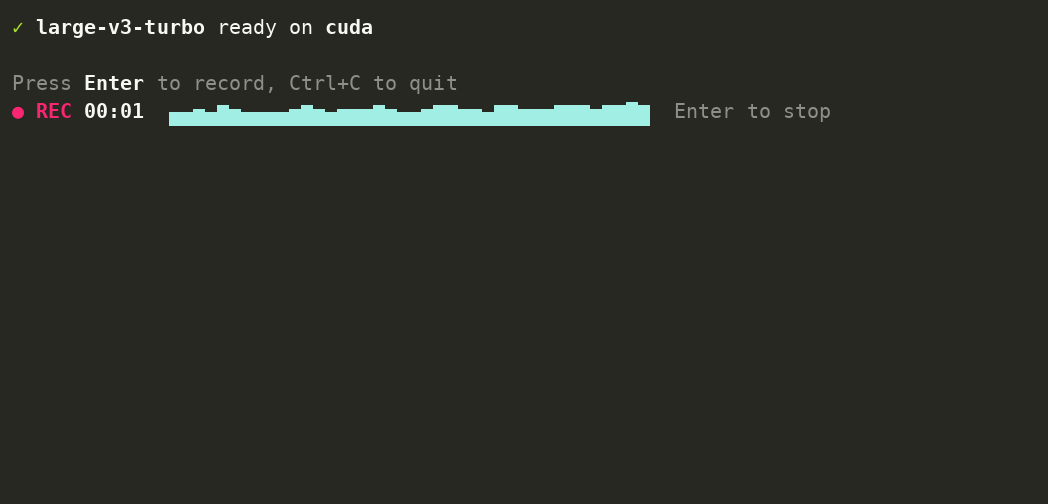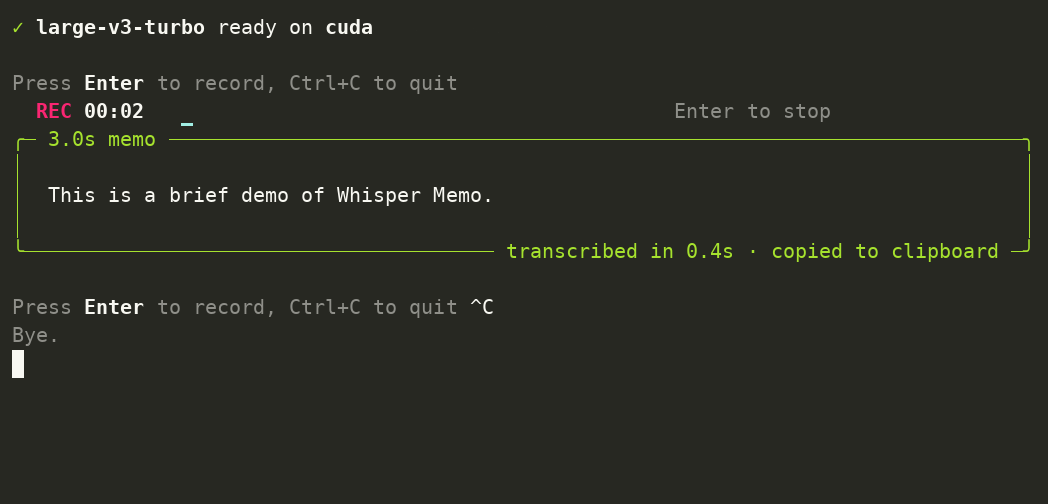
3
|
+
on:
|
|
4
|
+
push:
|
|
5
|
+
branches: [main]
|
|
6
|
+
pull_request:
|
|
7
|
+
|
|
8
|
+
jobs:
|
|
9
|
+
lint:
|
|
10
|
+
runs-on: ubuntu-latest
|
|
11
|
+
steps:
|
|
12
|
+
- uses: actions/checkout@v4
|
|
13
|
+
- uses: astral-sh/setup-uv@v6
|
|
14
|
+
- run: uv run --group dev ruff check
|
|
15
|
+
- run: uv run --group dev ruff format --check
|
|
16
|
+
|
|
17
|
+
test:
|
|
18
|
+
strategy:
|
|
19
|
+
fail-fast: false
|
|
20
|
+
matrix:
|
|
21
|
+
os: [ubuntu-latest, macos-latest, windows-latest]
|
|
22
|
+
python: ["3.11", "3.13"]
|
|
23
|
+
runs-on: ${{ matrix.os }}
|
|
24
|
+
steps:
|
|
25
|
+
- uses: actions/checkout@v4
|
|
26
|
+
- uses: astral-sh/setup-uv@v6
|
|
27
|
+
with:
|
|
28
|
+
python-version: ${{ matrix.python }}
|
|
29
|
+
- run: uv run --group dev pytest
|
|
30
|
+
- run: uv run whisper-memo --version
|
|
@@ -0,0 +1,26 @@
|
|
|
1
|
+
name: Release
|
|
2
|
+
|
|
3
|
+
# Push a tag like v0.1.0 to build and publish to PyPI.
|
|
4
|
+
# One-time setup: on pypi.org, add a "trusted publisher" for this repo,
|
|
5
|
+
# workflow release.yml, environment pypi. No API token is needed.
|
|
6
|
+
on:
|
|
7
|
+
push:
|
|
8
|
+
tags: ["v*"]
|
|
9
|
+
|
|
10
|
+
jobs:
|
|
11
|
+
publish:
|
|
12
|
+
runs-on: ubuntu-latest
|
|
13
|
+
environment: pypi
|
|
14
|
+
permissions:
|
|
15
|
+
id-token: write # trusted publishing
|
|
16
|
+
contents: write # create the GitHub release
|
|
17
|
+
steps:
|
|
18
|
+
- uses: actions/checkout@v4
|
|
19
|
+
- uses: astral-sh/setup-uv@v6
|
|
20
|
+
- name: Check tag matches package version
|
|
21
|
+
run: test "v$(uv version --short)" = "$GITHUB_REF_NAME"
|
|
22
|
+
- run: uv build
|
|
23
|
+
- run: uv publish --trusted-publishing always
|
|
24
|
+
- run: gh release create "$GITHUB_REF_NAME" dist/* --generate-notes
|
|
25
|
+
env:
|
|
26
|
+
GH_TOKEN: ${{ github.token }}
|
|
@@ -0,0 +1,17 @@
|
|
|
1
|
+
# Changelog
|
|
2
|
+
|
|
3
|
+
All notable changes to this project are documented here.
|
|
4
|
+
The format follows [Keep a Changelog](https://keepachangelog.com/en/1.1.0/),
|
|
5
|
+
and the project uses [Semantic Versioning](https://semver.org/).
|
|
6
|
+
|
|
7
|
+
## [Unreleased]
|
|
8
|
+
|
|
9
|
+
## [0.1.0] - 2026-11-14
|
|
10
|
+
|
|
11
|
+
### Added
|
|
12
|
+
|
|
13
|
+
- `whisper-memo` command: press Enter to record, Enter to stop; the transcript is printed and copied to the clipboard.
|
|
14
|
+
- Live recording display with a timer and a mic-level waveform.
|
|
15
|
+
- Say "new line" while recording to turn the transcript into bullet points.
|
|
16
|
+
- `--model`, `--device`, `--language` and `--no-clipboard` options.
|
|
17
|
+
- Optional `cuda` extra that installs the NVIDIA libraries for GPU transcription.
|
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 adamhp
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,115 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: whisper-memo
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Record voice memos in your terminal and transcribe them locally with Whisper.
|
|
5
|
+
Project-URL: Homepage, https://github.com/adamhp/whisper-memo
|
|
6
|
+
Project-URL: Issues, https://github.com/adamhp/whisper-memo/issues
|
|
7
|
+
Project-URL: Changelog, https://github.com/adamhp/whisper-memo/blob/main/CHANGELOG.md
|
|
8
|
+
Author: adamhp
|
|
9
|
+
License-Expression: MIT
|
|
10
|
+
License-File: LICENSE
|
|
11
|
+
Keywords: cli,offline,speech-to-text,transcription,voice-memo,whisper
|
|
12
|
+
Classifier: Development Status :: 4 - Beta
|
|
13
|
+
Classifier: Environment :: Console
|
|
14
|
+
Classifier: Intended Audience :: End Users/Desktop
|
|
15
|
+
Classifier: Operating System :: OS Independent
|
|
16
|
+
Classifier: Programming Language :: Python :: 3
|
|
17
|
+
Classifier: Topic :: Multimedia :: Sound/Audio :: Speech
|
|
18
|
+
Requires-Python: >=3.11
|
|
19
|
+
Requires-Dist: av<16
|
|
20
|
+
Requires-Dist: faster-whisper>=1.2.1
|
|
21
|
+
Requires-Dist: numpy>=1.24
|
|
22
|
+
Requires-Dist: pyperclip>=1.9
|
|
23
|
+
Requires-Dist: rich>=13
|
|
24
|
+
Requires-Dist: sounddevice>=0.5
|
|
25
|
+
Provides-Extra: cuda
|
|
26
|
+
Requires-Dist: nvidia-cublas-cu12<12.9; (sys_platform != 'darwin') and extra == 'cuda'
|
|
27
|
+
Requires-Dist: nvidia-cudnn-cu12<10,>=9; (sys_platform != 'darwin') and extra == 'cuda'
|
|
28
|
+
Description-Content-Type: text/markdown
|
|
29
|
+
|
|
30
|
+
# whisper-memo
|
|
31
|
+
|
|
32
|
+
Record a voice memo in your terminal, get the transcript on your clipboard.
|
|
33
|
+
Transcription runs entirely on your machine with [faster-whisper](https://github.com/SYSTRAN/faster-whisper).
|
|
34
|
+
No account, no API key, no audio leaves your computer.
|
|
35
|
+
|
|
36
|
+
|
|
37
|
+
|
|
38
|
+
## Why
|
|
39
|
+
|
|
40
|
+
I built this project as a simple way to capture changes I wanted to make during quality review checks on my Claude development.
|
|
41
|
+
While reviewing changes, I activate whisper-memo and just talk, then paste that into Claude.
|
|
42
|
+
There are many solutions to this problem, but I had some specific needs, so I built this small tool.
|
|
43
|
+
|
|
44
|
+
## Install
|
|
45
|
+
|
|
46
|
+
With [uv](https://docs.astral.sh/uv/) (recommended) or [pipx](https://pipx.pypa.io/):
|
|
47
|
+
|
|
48
|
+
```sh
|
|
49
|
+
uv tool install whisper-memo # CPU, works everywhere
|
|
50
|
+
uv tool install 'whisper-memo[cuda]' # NVIDIA GPU on Linux or Windows
|
|
51
|
+
```
|
|
52
|
+
|
|
53
|
+
Replace `uv tool install` with `pipx install` if you use pipx.
|
|
54
|
+
|
|
55
|
+
The first run downloads the Whisper model from Hugging Face (about 1.6 GB for the default `large-v3-turbo`).
|
|
56
|
+
After that, everything works offline.
|
|
57
|
+
|
|
58
|
+
### Platform notes
|
|
59
|
+
|
|
60
|
+
- **Linux:** install PortAudio for the microphone (`sudo apt install libportaudio2`)
|
|
61
|
+
and a clipboard tool (`xclip`, `xsel` or `wl-clipboard`).
|
|
62
|
+
- **macOS:** the terminal asks for microphone permission the first time. Transcription runs on the CPU;
|
|
63
|
+
pick a smaller model (`-m small`) if it feels slow.
|
|
64
|
+
- **Windows:** works out of the box. Add `[cuda]` for an NVIDIA GPU.
|
|
65
|
+
- **WSL:** microphone access depends on WSLg audio support and may not work.
|
|
66
|
+
|
|
67
|
+
## Usage
|
|
68
|
+
|
|
69
|
+
```sh
|
|
70
|
+
whisper-memo # default model, English
|
|
71
|
+
whisper-memo -m small # smaller, faster model
|
|
72
|
+
whisper-memo -l auto # detect the spoken language
|
|
73
|
+
whisper-memo -d cpu # force CPU even if a GPU is present
|
|
74
|
+
whisper-memo --no-clipboard # print only
|
|
75
|
+
```
|
|
76
|
+
|
|
77
|
+
Press **Enter** to start recording and **Enter** again to stop. **Ctrl+C** quits.
|
|
78
|
+
|
|
79
|
+
Say **"new line"** while recording to split the transcript into bullet points:
|
|
80
|
+
|
|
81
|
+
> "Rename the fetch helper to load user, new line, add a test for the empty list case, new line, drop the unused import in the CLI module"
|
|
82
|
+
|
|
83
|
+
```
|
|
84
|
+
- Rename the fetch helper to load user
|
|
85
|
+
- Add a test for the empty list case
|
|
86
|
+
- Drop the unused import in the CLI module
|
|
87
|
+
```
|
|
88
|
+
|
|
89
|
+
| Option | Default | |
|
|
90
|
+
| --- | --- | --- |
|
|
91
|
+
| `-m`, `--model` | `large-v3-turbo` | Any [faster-whisper model](https://huggingface.co/Systran) name or a local path. Also read from `WHISPER_MODEL`. |
|
|
92
|
+
| `-d`, `--device` | `auto` | `auto`, `cuda` or `cpu`. `auto` uses the GPU when one is available. |
|
|
93
|
+
| `-l`, `--language` | `en` | Language code (`de`, `ja`, ...) or `auto`. |
|
|
94
|
+
| `--no-clipboard` | off | Don't copy transcripts to the clipboard. |
|
|
95
|
+
|
|
96
|
+
## Development
|
|
97
|
+
|
|
98
|
+
```sh
|
|
99
|
+
git clone https://github.com/adamhp/whisper-memo
|
|
100
|
+
cd whisper-memo
|
|
101
|
+
uv run whisper-memo # run from source
|
|
102
|
+
uv run --group dev pytest # tests
|
|
103
|
+
uv run --group dev ruff check # lint
|
|
104
|
+
uv run --group dev ruff format # format
|
|
105
|
+
```
|
|
106
|
+
|
|
107
|
+
### Releasing
|
|
108
|
+
|
|
109
|
+
1. Bump `version` in `pyproject.toml` and move the `Unreleased` notes in `CHANGELOG.md` under the new version.
|
|
110
|
+
2. Commit, then tag and push: `git tag v0.2.0 && git push origin v0.2.0`.
|
|
111
|
+
3. The release workflow builds the package, publishes it to PyPI and creates a GitHub release.
|
|
112
|
+
|
|
113
|
+
## License
|
|
114
|
+
|
|
115
|
+
[MIT](LICENSE)
|
|
@@ -0,0 +1,86 @@
|
|
|
1
|
+
# whisper-memo
|
|
2
|
+
|
|
3
|
+
Record a voice memo in your terminal, get the transcript on your clipboard.
|
|
4
|
+
Transcription runs entirely on your machine with [faster-whisper](https://github.com/SYSTRAN/faster-whisper).
|
|
5
|
+
No account, no API key, no audio leaves your computer.
|
|
6
|
+
|
|
7
|
+

|
|
8
|
+
|
|
9
|
+
## Why
|
|
10
|
+
|
|
11
|
+
I built this project as a simple way to capture changes I wanted to make during quality review checks on my Claude development.
|
|
12
|
+
While reviewing changes, I activate whisper-memo and just talk, then paste that into Claude.
|
|
13
|
+
There are many solutions to this problem, but I had some specific needs, so I built this small tool.
|
|
14
|
+
|
|
15
|
+
## Install
|
|
16
|
+
|
|
17
|
+
With [uv](https://docs.astral.sh/uv/) (recommended) or [pipx](https://pipx.pypa.io/):
|
|
18
|
+
|
|
19
|
+
```sh
|
|
20
|
+
uv tool install whisper-memo # CPU, works everywhere
|
|
21
|
+
uv tool install 'whisper-memo[cuda]' # NVIDIA GPU on Linux or Windows
|
|
22
|
+
```
|
|
23
|
+
|
|
24
|
+
Replace `uv tool install` with `pipx install` if you use pipx.
|
|
25
|
+
|
|
26
|
+
The first run downloads the Whisper model from Hugging Face (about 1.6 GB for the default `large-v3-turbo`).
|
|
27
|
+
After that, everything works offline.
|
|
28
|
+
|
|
29
|
+
### Platform notes
|
|
30
|
+
|
|
31
|
+
- **Linux:** install PortAudio for the microphone (`sudo apt install libportaudio2`)
|
|
32
|
+
and a clipboard tool (`xclip`, `xsel` or `wl-clipboard`).
|
|
33
|
+
- **macOS:** the terminal asks for microphone permission the first time. Transcription runs on the CPU;
|
|
34
|
+
pick a smaller model (`-m small`) if it feels slow.
|
|
35
|
+
- **Windows:** works out of the box. Add `[cuda]` for an NVIDIA GPU.
|
|
36
|
+
- **WSL:** microphone access depends on WSLg audio support and may not work.
|
|
37
|
+
|
|
38
|
+
## Usage
|
|
39
|
+
|
|
40
|
+
```sh
|
|
41
|
+
whisper-memo # default model, English
|
|
42
|
+
whisper-memo -m small # smaller, faster model
|
|
43
|
+
whisper-memo -l auto # detect the spoken language
|
|
44
|
+
whisper-memo -d cpu # force CPU even if a GPU is present
|
|
45
|
+
whisper-memo --no-clipboard # print only
|
|
46
|
+
```
|
|
47
|
+
|
|
48
|
+
Press **Enter** to start recording and **Enter** again to stop. **Ctrl+C** quits.
|
|
49
|
+
|
|
50
|
+
Say **"new line"** while recording to split the transcript into bullet points:
|
|
51
|
+
|
|
52
|
+
> "Rename the fetch helper to load user, new line, add a test for the empty list case, new line, drop the unused import in the CLI module"
|
|
53
|
+
|
|
54
|
+
```
|
|
55
|
+
- Rename the fetch helper to load user
|
|
56
|
+
- Add a test for the empty list case
|
|
57
|
+
- Drop the unused import in the CLI module
|
|
58
|
+
```
|
|
59
|
+
|
|
60
|
+
| Option | Default | |
|
|
61
|
+
| --- | --- | --- |
|
|
62
|
+
| `-m`, `--model` | `large-v3-turbo` | Any [faster-whisper model](https://huggingface.co/Systran) name or a local path. Also read from `WHISPER_MODEL`. |
|
|
63
|
+
| `-d`, `--device` | `auto` | `auto`, `cuda` or `cpu`. `auto` uses the GPU when one is available. |
|
|
64
|
+
| `-l`, `--language` | `en` | Language code (`de`, `ja`, ...) or `auto`. |
|
|
65
|
+
| `--no-clipboard` | off | Don't copy transcripts to the clipboard. |
|
|
66
|
+
|
|
67
|
+
## Development
|
|
68
|
+
|
|
69
|
+
```sh
|
|
70
|
+
git clone https://github.com/adamhp/whisper-memo
|
|
71
|
+
cd whisper-memo
|
|
72
|
+
uv run whisper-memo # run from source
|
|
73
|
+
uv run --group dev pytest # tests
|
|
74
|
+
uv run --group dev ruff check # lint
|
|
75
|
+
uv run --group dev ruff format # format
|
|
76
|
+
```
|
|
77
|
+
|
|
78
|
+
### Releasing
|
|
79
|
+
|
|
80
|
+
1. Bump `version` in `pyproject.toml` and move the `Unreleased` notes in `CHANGELOG.md` under the new version.
|
|
81
|
+
2. Commit, then tag and push: `git tag v0.2.0 && git push origin v0.2.0`.
|
|
82
|
+
3. The release workflow builds the package, publishes it to PyPI and creates a GitHub release.
|
|
83
|
+
|
|
84
|
+
## License
|
|
85
|
+
|
|
86
|
+
[MIT](LICENSE)
|
|
Binary file
|
|
@@ -0,0 +1,57 @@
|
|
|
1
|
+
[project]
|
|
2
|
+
name = "whisper-memo"
|
|
3
|
+
version = "0.1.0"
|
|
4
|
+
description = "Record voice memos in your terminal and transcribe them locally with Whisper."
|
|
5
|
+
readme = "README.md"
|
|
6
|
+
license = "MIT"
|
|
7
|
+
license-files = ["LICENSE"]
|
|
8
|
+
authors = [{ name = "adamhp" }]
|
|
9
|
+
requires-python = ">=3.11"
|
|
10
|
+
keywords = ["whisper", "speech-to-text", "transcription", "voice-memo", "cli", "offline"]
|
|
11
|
+
classifiers = [
|
|
12
|
+
"Development Status :: 4 - Beta",
|
|
13
|
+
"Environment :: Console",
|
|
14
|
+
"Intended Audience :: End Users/Desktop",
|
|
15
|
+
"Operating System :: OS Independent",
|
|
16
|
+
"Programming Language :: Python :: 3",
|
|
17
|
+
"Topic :: Multimedia :: Sound/Audio :: Speech",
|
|
18
|
+
]
|
|
19
|
+
dependencies = [
|
|
20
|
+
"av<16",
|
|
21
|
+
"faster-whisper>=1.2.1",
|
|
22
|
+
"numpy>=1.24",
|
|
23
|
+
"pyperclip>=1.9",
|
|
24
|
+
"rich>=13",
|
|
25
|
+
"sounddevice>=0.5",
|
|
26
|
+
]
|
|
27
|
+
|
|
28
|
+
[project.optional-dependencies]
|
|
29
|
+
# GPU acceleration on Linux/Windows with an NVIDIA card. Large download; not needed for CPU.
|
|
30
|
+
cuda = [
|
|
31
|
+
"nvidia-cublas-cu12<12.9; sys_platform != 'darwin'",
|
|
32
|
+
"nvidia-cudnn-cu12>=9,<10; sys_platform != 'darwin'",
|
|
33
|
+
]
|
|
34
|
+
|
|
35
|
+
[project.scripts]
|
|
36
|
+
whisper-memo = "whisper_memo.cli:main"
|
|
37
|
+
|
|
38
|
+
[project.urls]
|
|
39
|
+
Homepage = "https://github.com/adamhp/whisper-memo"
|
|
40
|
+
Issues = "https://github.com/adamhp/whisper-memo/issues"
|
|
41
|
+
Changelog = "https://github.com/adamhp/whisper-memo/blob/main/CHANGELOG.md"
|
|
42
|
+
|
|
43
|
+
[dependency-groups]
|
|
44
|
+
dev = ["pytest>=8", "ruff>=0.8"]
|
|
45
|
+
|
|
46
|
+
[build-system]
|
|
47
|
+
requires = ["hatchling>=1.27"]
|
|
48
|
+
build-backend = "hatchling.build"
|
|
49
|
+
|
|
50
|
+
[tool.ruff]
|
|
51
|
+
line-length = 120
|
|
52
|
+
|
|
53
|
+
[tool.ruff.lint]
|
|
54
|
+
select = ["E", "F", "I", "UP", "B"]
|
|
55
|
+
|
|
56
|
+
[tool.pytest.ini_options]
|
|
57
|
+
testpaths = ["tests"]
|
|
@@ -0,0 +1,237 @@
|
|
|
1
|
+
"""Record voice memos from the default mic and transcribe them locally with faster-whisper.
|
|
2
|
+
|
|
3
|
+
Enter starts recording, Enter stops it. The transcript is printed and copied to the clipboard.
|
|
4
|
+
Ctrl+C quits.
|
|
5
|
+
"""
|
|
6
|
+
|
|
7
|
+
import argparse
|
|
8
|
+
import os
|
|
9
|
+
import re
|
|
10
|
+
import sys
|
|
11
|
+
import threading
|
|
12
|
+
import time
|
|
13
|
+
from collections import deque
|
|
14
|
+
from pathlib import Path
|
|
15
|
+
|
|
16
|
+
import numpy as np
|
|
17
|
+
from rich.console import Console
|
|
18
|
+
from rich.live import Live
|
|
19
|
+
from rich.panel import Panel
|
|
20
|
+
from rich.text import Text
|
|
21
|
+
|
|
22
|
+
from whisper_memo import __version__
|
|
23
|
+
|
|
24
|
+
SAMPLE_RATE = 16000 # Whisper's native rate
|
|
25
|
+
DEFAULT_MODEL = os.environ.get("WHISPER_MODEL", "large-v3-turbo")
|
|
26
|
+
STYLE_PROMPT = "Hello, welcome to my voice memo. Here are my thoughts, written in complete sentences."
|
|
27
|
+
|
|
28
|
+
console = Console()
|
|
29
|
+
|
|
30
|
+
BARS = " ▁▂▃▄▅▆▇█"
|
|
31
|
+
WAVE_WIDTH = 40
|
|
32
|
+
|
|
33
|
+
|
|
34
|
+
def preload_cuda_libs() -> None:
|
|
35
|
+
"""Make the cuBLAS/cuDNN libraries from the optional nvidia-* wheels visible to ctranslate2."""
|
|
36
|
+
import importlib.util
|
|
37
|
+
|
|
38
|
+
spec = importlib.util.find_spec("nvidia")
|
|
39
|
+
roots = [Path(r) for r in (spec.submodule_search_locations if spec else [])]
|
|
40
|
+
pkgs = ("cuda_nvrtc", "cublas", "cudnn")
|
|
41
|
+
|
|
42
|
+
if sys.platform == "win32":
|
|
43
|
+
# On Windows the wheels ship DLLs in nvidia/<pkg>/bin.
|
|
44
|
+
for dll_dir in (root / pkg / "bin" for root in roots for pkg in pkgs):
|
|
45
|
+
if dll_dir.is_dir():
|
|
46
|
+
os.add_dll_directory(str(dll_dir))
|
|
47
|
+
os.environ["PATH"] = str(dll_dir) + os.pathsep + os.environ["PATH"]
|
|
48
|
+
elif sys.platform.startswith("linux"):
|
|
49
|
+
# On Linux the wheels put .so files in nvidia/<pkg>/lib. LD_LIBRARY_PATH is read only at
|
|
50
|
+
# process start, so preload them globally; ctranslate2's later dlopen then finds them.
|
|
51
|
+
import ctypes
|
|
52
|
+
|
|
53
|
+
libs = [so for root in roots for pkg in pkgs for so in sorted((root / pkg / "lib").glob("lib*.so*"))]
|
|
54
|
+
# Retry passes resolve inter-library dependencies regardless of load order.
|
|
55
|
+
for _ in range(3):
|
|
56
|
+
failed = []
|
|
57
|
+
for so in libs:
|
|
58
|
+
try:
|
|
59
|
+
ctypes.CDLL(str(so), mode=ctypes.RTLD_GLOBAL)
|
|
60
|
+
except OSError:
|
|
61
|
+
failed.append(so)
|
|
62
|
+
if not failed or len(failed) == len(libs):
|
|
63
|
+
break
|
|
64
|
+
libs = failed
|
|
65
|
+
|
|
66
|
+
|
|
67
|
+
def load_model(name: str, device: str):
|
|
68
|
+
preload_cuda_libs()
|
|
69
|
+
import ctranslate2
|
|
70
|
+
from faster_whisper import WhisperModel
|
|
71
|
+
|
|
72
|
+
if device == "auto":
|
|
73
|
+
device = "cuda" if ctranslate2.get_cuda_device_count() > 0 else "cpu"
|
|
74
|
+
if device == "cuda":
|
|
75
|
+
try:
|
|
76
|
+
return WhisperModel(name, device="cuda", compute_type="float16"), "cuda"
|
|
77
|
+
except Exception as e:
|
|
78
|
+
console.print(f"[yellow]CUDA unavailable ({e}); falling back to CPU.[/]")
|
|
79
|
+
return WhisperModel(name, device="cpu", compute_type="int8"), "cpu"
|
|
80
|
+
|
|
81
|
+
|
|
82
|
+
def level_bar(rms: float) -> str:
|
|
83
|
+
"""Map a chunk's RMS to a bar glyph on a log scale (-60 dB silent, -10 dB full)."""
|
|
84
|
+
db = 20 * np.log10(rms + 1e-9)
|
|
85
|
+
frac = min(max((db + 60) / 50, 0.0), 1.0)
|
|
86
|
+
return BARS[round(frac * (len(BARS) - 1))]
|
|
87
|
+
|
|
88
|
+
|
|
89
|
+
class AudioError(RuntimeError):
|
|
90
|
+
"""The microphone or the PortAudio library is unavailable."""
|
|
91
|
+
|
|
92
|
+
|
|
93
|
+
def record() -> np.ndarray:
|
|
94
|
+
try:
|
|
95
|
+
import sounddevice as sd
|
|
96
|
+
except OSError as e: # raised when the PortAudio shared library is missing
|
|
97
|
+
raise AudioError(e) from e
|
|
98
|
+
|
|
99
|
+
chunks = []
|
|
100
|
+
levels = deque(" " * WAVE_WIDTH, maxlen=WAVE_WIDTH)
|
|
101
|
+
stop = threading.Event()
|
|
102
|
+
|
|
103
|
+
def callback(indata, *_):
|
|
104
|
+
chunks.append(indata.copy())
|
|
105
|
+
levels.append(level_bar(float(np.sqrt(np.mean(indata**2)))))
|
|
106
|
+
|
|
107
|
+
def render() -> Text:
|
|
108
|
+
secs = int(sum(len(c) for c in chunks) / SAMPLE_RATE)
|
|
109
|
+
blink = int(time.monotonic() * 2) % 2 == 0
|
|
110
|
+
return Text.assemble(
|
|
111
|
+
("● " if blink else " ", "bold red"),
|
|
112
|
+
("REC ", "bold red"),
|
|
113
|
+
(f"{secs // 60:02d}:{secs % 60:02d} ", "bold"),
|
|
114
|
+
("".join(levels), "cyan"),
|
|
115
|
+
(" Enter to stop", "dim"),
|
|
116
|
+
)
|
|
117
|
+
|
|
118
|
+
try:
|
|
119
|
+
stream = sd.InputStream(samplerate=SAMPLE_RATE, channels=1, dtype="float32", callback=callback)
|
|
120
|
+
except sd.PortAudioError as e:
|
|
121
|
+
raise AudioError(e) from e
|
|
122
|
+
with stream:
|
|
123
|
+
threading.Thread(target=lambda: (input(), stop.set()), daemon=True).start()
|
|
124
|
+
with Live(get_renderable=render, console=console, refresh_per_second=15, transient=True):
|
|
125
|
+
stop.wait()
|
|
126
|
+
|
|
127
|
+
return np.concatenate(chunks).flatten() if chunks else np.zeros(0, dtype=np.float32)
|
|
128
|
+
|
|
129
|
+
|
|
130
|
+
# Spoken "new line" (Whisper may render it "New line.", "new-line,", "newline" etc.).
|
|
131
|
+
NEW_LINE = re.compile(r"\bnew[\s-]?line\b[\s.,!?;:]*", re.IGNORECASE)
|
|
132
|
+
|
|
133
|
+
|
|
134
|
+
def format_bullets(text: str) -> str:
|
|
135
|
+
"""If the speaker said "new line", turn the pieces between them into bullet points."""
|
|
136
|
+
if not NEW_LINE.search(text):
|
|
137
|
+
return text
|
|
138
|
+
items = (p.strip(" ,;:") for p in NEW_LINE.split(text))
|
|
139
|
+
return "\n".join(f"- {item[0].upper()}{item[1:]}" for item in items if item)
|
|
140
|
+
|
|
141
|
+
|
|
142
|
+
def copy_to_clipboard(text: str) -> bool:
|
|
143
|
+
import pyperclip
|
|
144
|
+
|
|
145
|
+
try:
|
|
146
|
+
pyperclip.copy(text)
|
|
147
|
+
return True
|
|
148
|
+
except pyperclip.PyperclipException:
|
|
149
|
+
return False
|
|
150
|
+
|
|
151
|
+
|
|
152
|
+
def parse_args(argv: list[str] | None = None) -> argparse.Namespace:
|
|
153
|
+
parser = argparse.ArgumentParser(
|
|
154
|
+
prog="whisper-memo",
|
|
155
|
+
description="Record voice memos and transcribe them locally with Whisper.",
|
|
156
|
+
epilog='Say "new line" while recording to split the transcript into bullet points.',
|
|
157
|
+
)
|
|
158
|
+
parser.add_argument(
|
|
159
|
+
"-m",
|
|
160
|
+
"--model",
|
|
161
|
+
default=DEFAULT_MODEL,
|
|
162
|
+
help="Whisper model name or local path (default: %(default)s; env: WHISPER_MODEL)",
|
|
163
|
+
)
|
|
164
|
+
parser.add_argument("-d", "--device", choices=("auto", "cuda", "cpu"), default="auto", help="default: %(default)s")
|
|
165
|
+
parser.add_argument(
|
|
166
|
+
"-l", "--language", default="en", help='spoken language code, or "auto" to detect (default: %(default)s)'
|
|
167
|
+
)
|
|
168
|
+
parser.add_argument("--no-clipboard", action="store_true", help="don't copy transcripts to the clipboard")
|
|
169
|
+
parser.add_argument("-V", "--version", action="version", version=f"%(prog)s {__version__}")
|
|
170
|
+
return parser.parse_args(argv)
|
|
171
|
+
|
|
172
|
+
|
|
173
|
+
def run(args: argparse.Namespace) -> None:
|
|
174
|
+
language = None if args.language == "auto" else args.language
|
|
175
|
+
|
|
176
|
+
with console.status(f"Loading [bold]{args.model}[/] (first run downloads it)...", spinner="dots"):
|
|
177
|
+
model, device = load_model(args.model, args.device)
|
|
178
|
+
console.print(f"[green]✓[/] [bold]{args.model}[/] ready on [bold]{device}[/]")
|
|
179
|
+
|
|
180
|
+
while True:
|
|
181
|
+
console.input("\n[dim]Press[/] [bold]Enter[/] [dim]to record, Ctrl+C to quit[/] ")
|
|
182
|
+
audio = record()
|
|
183
|
+
duration = audio.size / SAMPLE_RATE
|
|
184
|
+
if audio.size < SAMPLE_RATE // 2:
|
|
185
|
+
console.print("[yellow]Too short, skipped.[/]")
|
|
186
|
+
continue
|
|
187
|
+
|
|
188
|
+
start = time.monotonic()
|
|
189
|
+
with console.status(f"Transcribing {duration:.1f}s of audio...", spinner="dots"):
|
|
190
|
+
segments, _ = model.transcribe(
|
|
191
|
+
audio,
|
|
192
|
+
language=language,
|
|
193
|
+
vad_filter=True,
|
|
194
|
+
beam_size=5,
|
|
195
|
+
# Whisper mimics the prompt's style; a punctuated prompt yields punctuated output.
|
|
196
|
+
# The prompt is English, so only use it when transcribing English.
|
|
197
|
+
initial_prompt=STYLE_PROMPT if language == "en" else None,
|
|
198
|
+
)
|
|
199
|
+
# segments is lazy; joining it runs the transcription, so keep it inside the spinner.
|
|
200
|
+
text = format_bullets(" ".join(s.text.strip() for s in segments).strip())
|
|
201
|
+
if not text:
|
|
202
|
+
console.print("[yellow]No speech detected.[/]")
|
|
203
|
+
continue
|
|
204
|
+
|
|
205
|
+
status = f"transcribed in {time.monotonic() - start:.1f}s"
|
|
206
|
+
if not args.no_clipboard:
|
|
207
|
+
if copy_to_clipboard(text):
|
|
208
|
+
status += " · copied to clipboard"
|
|
209
|
+
else:
|
|
210
|
+
status += " · [yellow]clipboard unavailable[/]"
|
|
211
|
+
console.print(
|
|
212
|
+
Panel(
|
|
213
|
+
Text(text),
|
|
214
|
+
title=f"{duration:.1f}s memo",
|
|
215
|
+
subtitle=status,
|
|
216
|
+
title_align="left",
|
|
217
|
+
subtitle_align="right",
|
|
218
|
+
border_style="green",
|
|
219
|
+
padding=(1, 2),
|
|
220
|
+
)
|
|
221
|
+
)
|
|
222
|
+
|
|
223
|
+
|
|
224
|
+
def main(argv: list[str] | None = None) -> None:
|
|
225
|
+
args = parse_args(argv)
|
|
226
|
+
try:
|
|
227
|
+
run(args)
|
|
228
|
+
except KeyboardInterrupt:
|
|
229
|
+
console.print("\n[dim]Bye.[/]")
|
|
230
|
+
except AudioError as e:
|
|
231
|
+
console.print(f"[red]Audio error:[/] {e}")
|
|
232
|
+
console.print("[dim]Check that a microphone is connected and PortAudio is installed.[/]")
|
|
233
|
+
sys.exit(1)
|
|
234
|
+
|
|
235
|
+
|
|
236
|
+
if __name__ == "__main__":
|
|
237
|
+
main()
|
|
@@ -0,0 +1,47 @@
|
|
|
1
|
+
import pytest
|
|
2
|
+
|
|
3
|
+
from whisper_memo.cli import BARS, format_bullets, level_bar, parse_args
|
|
4
|
+
|
|
5
|
+
|
|
6
|
+
def test_plain_text_is_unchanged():
|
|
7
|
+
assert format_bullets("Just one thought.") == "Just one thought."
|
|
8
|
+
|
|
9
|
+
|
|
10
|
+
@pytest.mark.parametrize(
|
|
11
|
+
"text",
|
|
12
|
+
[
|
|
13
|
+
"buy milk new line call mom",
|
|
14
|
+
"Buy milk. New line. Call mom.",
|
|
15
|
+
"buy milk, new-line, call mom",
|
|
16
|
+
"buy milk newline call mom",
|
|
17
|
+
],
|
|
18
|
+
)
|
|
19
|
+
def test_new_line_makes_bullets(text):
|
|
20
|
+
assert format_bullets(text).replace(".", "") == "- Buy milk\n- Call mom"
|
|
21
|
+
|
|
22
|
+
|
|
23
|
+
def test_trailing_new_line_adds_no_empty_bullet():
|
|
24
|
+
assert format_bullets("one thing new line") == "- One thing"
|
|
25
|
+
|
|
26
|
+
|
|
27
|
+
def test_new_line_inside_a_word_is_ignored():
|
|
28
|
+
assert format_bullets("renewlines are fine") == "renewlines are fine"
|
|
29
|
+
|
|
30
|
+
|
|
31
|
+
def test_level_bar_range():
|
|
32
|
+
assert level_bar(0.0) == BARS[0]
|
|
33
|
+
assert level_bar(1.0) == BARS[-1]
|
|
34
|
+
levels = [BARS.index(level_bar(r)) for r in (1e-4, 1e-3, 1e-2, 1e-1)]
|
|
35
|
+
assert levels == sorted(levels)
|
|
36
|
+
|
|
37
|
+
|
|
38
|
+
def test_defaults():
|
|
39
|
+
args = parse_args([])
|
|
40
|
+
assert (args.device, args.language, args.no_clipboard) == ("auto", "en", False)
|
|
41
|
+
|
|
42
|
+
|
|
43
|
+
def test_version_flag(capsys):
|
|
44
|
+
with pytest.raises(SystemExit) as exc:
|
|
45
|
+
parse_args(["--version"])
|
|
46
|
+
assert exc.value.code == 0
|
|
47
|
+
assert capsys.readouterr().out.startswith("whisper-memo ")
|