whensaid 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- whensaid-0.1.0/.github/workflows/ci.yml +57 -0
- whensaid-0.1.0/.github/workflows/publish.yml +20 -0
- whensaid-0.1.0/.gitignore +14 -0
- whensaid-0.1.0/LICENSE +21 -0
- whensaid-0.1.0/PKG-INFO +146 -0
- whensaid-0.1.0/README.md +114 -0
- whensaid-0.1.0/assets/demo.gif +0 -0
- whensaid-0.1.0/pyproject.toml +45 -0
- whensaid-0.1.0/scripts/bench_rerank.py +120 -0
- whensaid-0.1.0/scripts/compare_models.py +122 -0
- whensaid-0.1.0/scripts/eval.py +66 -0
- whensaid-0.1.0/scripts/make_demo.py +57 -0
- whensaid-0.1.0/scripts/smoke.py +33 -0
- whensaid-0.1.0/src/whensaid/__init__.py +1 -0
- whensaid-0.1.0/src/whensaid/chunk.py +46 -0
- whensaid-0.1.0/src/whensaid/cli.py +246 -0
- whensaid-0.1.0/src/whensaid/cudalibs.py +43 -0
- whensaid-0.1.0/src/whensaid/db.py +120 -0
- whensaid-0.1.0/src/whensaid/doctor.py +121 -0
- whensaid-0.1.0/src/whensaid/embed.py +30 -0
- whensaid-0.1.0/src/whensaid/export.py +50 -0
- whensaid-0.1.0/src/whensaid/fetch.py +196 -0
- whensaid-0.1.0/src/whensaid/indexer.py +335 -0
- whensaid-0.1.0/src/whensaid/models.py +260 -0
- whensaid-0.1.0/src/whensaid/paths.py +18 -0
- whensaid-0.1.0/src/whensaid/rerank.py +80 -0
- whensaid-0.1.0/src/whensaid/search.py +170 -0
- whensaid-0.1.0/src/whensaid/server.py +214 -0
- whensaid-0.1.0/src/whensaid/subtitles.py +99 -0
- whensaid-0.1.0/src/whensaid/transcribe.py +136 -0
- whensaid-0.1.0/src/whensaid/urls.py +104 -0
- whensaid-0.1.0/src/whensaid/util.py +55 -0
- whensaid-0.1.0/tests/data/README.md +25 -0
- whensaid-0.1.0/tests/data/jfk.wav +0 -0
- whensaid-0.1.0/tests/fixtures/autocaptions.vtt +43 -0
- whensaid-0.1.0/tests/golden.json +185 -0
- whensaid-0.1.0/tests/golden_noisy.json +220 -0
- whensaid-0.1.0/tests/golden_scale.json +262 -0
- whensaid-0.1.0/tests/test_chunk.py +48 -0
- whensaid-0.1.0/tests/test_doctor.py +49 -0
- whensaid-0.1.0/tests/test_export.py +69 -0
- whensaid-0.1.0/tests/test_indexer.py +287 -0
- whensaid-0.1.0/tests/test_models.py +272 -0
- whensaid-0.1.0/tests/test_search.py +111 -0
- whensaid-0.1.0/tests/test_server.py +132 -0
- whensaid-0.1.0/tests/test_split.py +58 -0
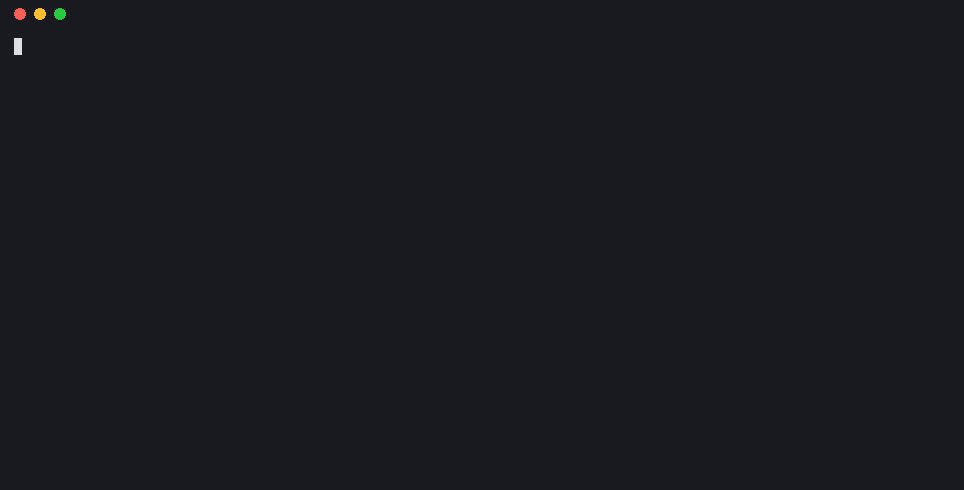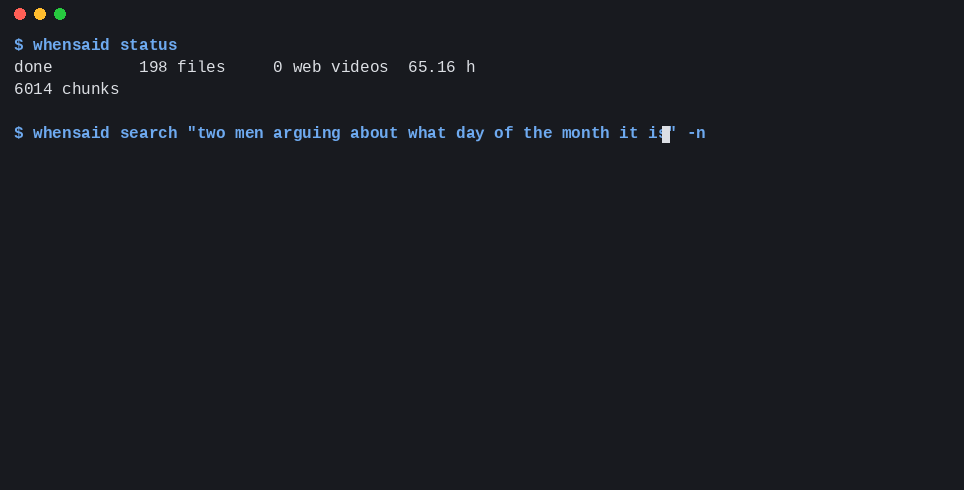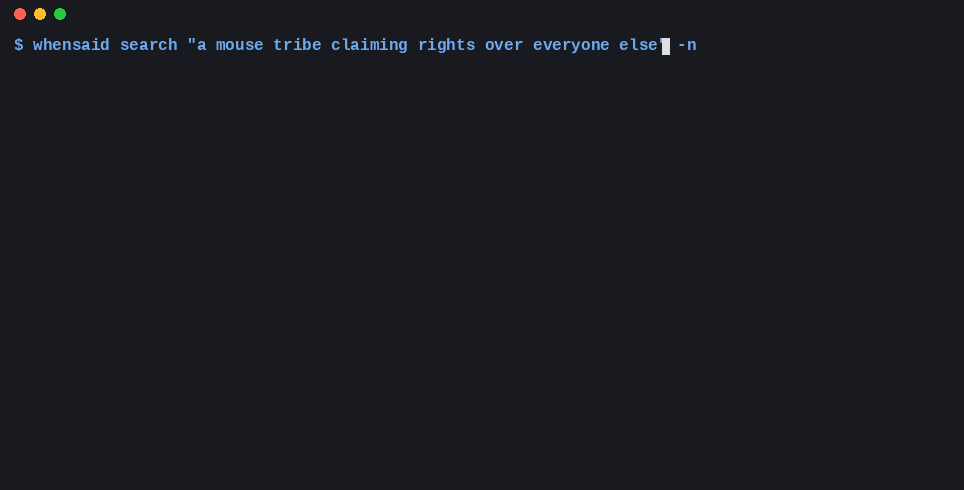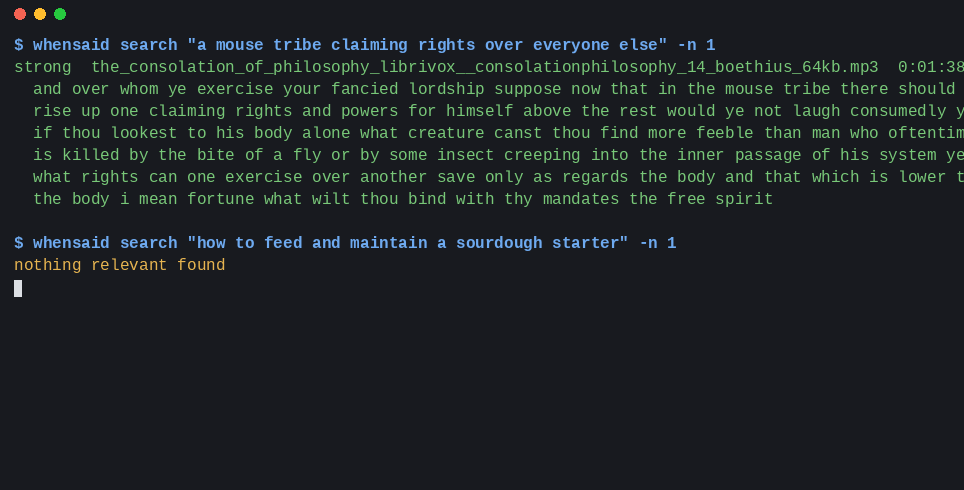
- whensaid-0.1.0/tests/test_subtitles.py +129 -0
- whensaid-0.1.0/tests/test_urls.py +351 -0
|
@@ -0,0 +1,57 @@
|
|
|
1
|
+
name: ci
|
|
2
|
+
|
|
3
|
+
on:
|
|
4
|
+
push:
|
|
5
|
+
pull_request:
|
|
6
|
+
workflow_dispatch:
|
|
7
|
+
|
|
8
|
+
concurrency:
|
|
9
|
+
group: ci-${{ github.ref }}
|
|
10
|
+
cancel-in-progress: true
|
|
11
|
+
|
|
12
|
+
jobs:
|
|
13
|
+
test:
|
|
14
|
+
runs-on: ${{ matrix.os }}
|
|
15
|
+
strategy:
|
|
16
|
+
fail-fast: false
|
|
17
|
+
matrix:
|
|
18
|
+
os: [ubuntu-latest, macos-latest]
|
|
19
|
+
python: ["3.12"]
|
|
20
|
+
include:
|
|
21
|
+
- os: ubuntu-latest
|
|
22
|
+
python: "3.11"
|
|
23
|
+
steps:
|
|
24
|
+
- uses: actions/checkout@v4
|
|
25
|
+
- uses: actions/setup-python@v5
|
|
26
|
+
with:
|
|
27
|
+
python-version: ${{ matrix.python }}
|
|
28
|
+
cache: pip
|
|
29
|
+
- run: pip install -e ".[dev]"
|
|
30
|
+
- run: pytest -q
|
|
31
|
+
|
|
32
|
+
# Installs the package as a user would (no GPU extras), downloads the real models and
|
|
33
|
+
# searches a real clip. Slow and heavy, so only on main and by hand. macOS minutes count
|
|
34
|
+
# ten times on a private repo.
|
|
35
|
+
smoke:
|
|
36
|
+
needs: test
|
|
37
|
+
if: github.event_name == 'workflow_dispatch' || (github.event_name == 'push' && github.ref == 'refs/heads/main')
|
|
38
|
+
runs-on: ${{ matrix.os }}
|
|
39
|
+
strategy:
|
|
40
|
+
fail-fast: false
|
|
41
|
+
matrix:
|
|
42
|
+
os: [ubuntu-latest, macos-latest]
|
|
43
|
+
env:
|
|
44
|
+
WHENSAID_HOME: ${{ github.workspace }}/.smoke-home
|
|
45
|
+
WHENSAID_WHISPER_MODEL: small.en # the default model is 1.5 GB; this one is enough to find a phrase
|
|
46
|
+
steps:
|
|
47
|
+
- uses: actions/checkout@v4
|
|
48
|
+
- uses: actions/setup-python@v5
|
|
49
|
+
with:
|
|
50
|
+
python-version: "3.12"
|
|
51
|
+
cache: pip
|
|
52
|
+
- uses: actions/cache@v4
|
|
53
|
+
with:
|
|
54
|
+
path: .smoke-home/models
|
|
55
|
+
key: models-${{ runner.os }}-small.en-v1
|
|
56
|
+
- run: pip install .
|
|
57
|
+
- run: python scripts/smoke.py tests/data
|
|
@@ -0,0 +1,20 @@
|
|
|
1
|
+
name: publish
|
|
2
|
+
|
|
3
|
+
on:
|
|
4
|
+
release:
|
|
5
|
+
types: [published]
|
|
6
|
+
workflow_dispatch:
|
|
7
|
+
|
|
8
|
+
jobs:
|
|
9
|
+
pypi:
|
|
10
|
+
runs-on: ubuntu-latest
|
|
11
|
+
environment: pypi
|
|
12
|
+
permissions:
|
|
13
|
+
id-token: write # trusted publishing, no API token stored anywhere
|
|
14
|
+
steps:
|
|
15
|
+
- uses: actions/checkout@v4
|
|
16
|
+
- uses: actions/setup-python@v5
|
|
17
|
+
with:
|
|
18
|
+
python-version: "3.12"
|
|
19
|
+
- run: pip install build && python -m build
|
|
20
|
+
- uses: pypa/gh-action-pypi-publish@release/v1
|
whensaid-0.1.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 VishnupiriyanV
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
whensaid-0.1.0/PKG-INFO
ADDED
|
@@ -0,0 +1,146 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: whensaid
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Local, offline search over your video and audio recordings, exposed to AI agents over MCP.
|
|
5
|
+
Project-URL: Homepage, https://github.com/VishnupiriyanV/whensaid
|
|
6
|
+
Project-URL: Issues, https://github.com/VishnupiriyanV/whensaid/issues
|
|
7
|
+
Author: VishnupiriyanV
|
|
8
|
+
License-Expression: MIT
|
|
9
|
+
License-File: LICENSE
|
|
10
|
+
Keywords: audio,local,mcp,offline,search,transcription,video,whisper
|
|
11
|
+
Classifier: Development Status :: 3 - Alpha
|
|
12
|
+
Classifier: Environment :: Console
|
|
13
|
+
Classifier: Intended Audience :: Developers
|
|
14
|
+
Classifier: Operating System :: POSIX :: Linux
|
|
15
|
+
Classifier: Programming Language :: Python :: 3
|
|
16
|
+
Classifier: Topic :: Multimedia :: Sound/Audio :: Speech
|
|
17
|
+
Classifier: Topic :: Text Processing :: Indexing
|
|
18
|
+
Requires-Python: >=3.11
|
|
19
|
+
Requires-Dist: av<17,>=14
|
|
20
|
+
Requires-Dist: fastembed<1,>=0.9
|
|
21
|
+
Requires-Dist: faster-whisper<2,>=1.2
|
|
22
|
+
Requires-Dist: mcp<3,>=2
|
|
23
|
+
Requires-Dist: numpy>=1.26
|
|
24
|
+
Provides-Extra: cuda
|
|
25
|
+
Requires-Dist: nvidia-cublas-cu12; extra == 'cuda'
|
|
26
|
+
Requires-Dist: nvidia-cudnn-cu12; extra == 'cuda'
|
|
27
|
+
Provides-Extra: dev
|
|
28
|
+
Requires-Dist: pytest; extra == 'dev'
|
|
29
|
+
Provides-Extra: url
|
|
30
|
+
Requires-Dist: yt-dlp; extra == 'url'
|
|
31
|
+
Description-Content-Type: text/markdown
|
|
32
|
+
|
|
33
|
+
# whensaid
|
|
34
|
+
|
|
35
|
+
Search what was *said* in your local video and audio files, from your AI agent.
|
|
36
|
+
|
|
37
|
+
Point it at folders of recordings (talks, courses, meetings, interviews, podcasts) or at a YouTube playlist.
|
|
38
|
+
Your agent (Claude Code, Cursor, ...) calls `search("when did they talk about X")` and gets back the file, the exact
|
|
39
|
+
timestamp and the passage; for web videos, a link that opens the video at that moment. Everything runs on your
|
|
40
|
+
machine, and nothing is uploaded.
|
|
41
|
+
|
|
42
|
+
**Status: pre-alpha.** Tested on Linux (CI also runs on macOS). Runs on an NVIDIA GPU or on CPU. English only.
|
|
43
|
+
|
|
44
|
+
## A worked example
|
|
45
|
+
|
|
46
|
+
|
|
47
|
+
|
|
48
|
+
The recording above is real `whensaid` output (rendered by `scripts/make_demo.py`), run in a terminal rather than from an agent session. Text version:
|
|
49
|
+
|
|
50
|
+
The index here is 198 public-domain recordings (65 hours of audiobooks and old radio). The question is paraphrased,
|
|
51
|
+
not a quote:
|
|
52
|
+
|
|
53
|
+
```
|
|
54
|
+
$ whensaid search "a mouse tribe claiming rights over everyone else" -n 1
|
|
55
|
+
strong the_consolation_of_philosophy_..._boethius_64kb.mp3 0:01:38 and over whom ye exercise your fancied
|
|
56
|
+
lordship suppose now that in the mouse tribe there should rise up one claiming rights and powers for himself above the rest ...
|
|
57
|
+
```
|
|
58
|
+
|
|
59
|
+
Through MCP the agent gets the same thing as JSON (`file`, `path`, `start`, `at`, `text`, `match`, `relevance`, and
|
|
60
|
+
`link` for web videos) and can call `get_transcript` to read around the hit. About half a second per search on CPU.
|
|
61
|
+
|
|
62
|
+
## Use it
|
|
63
|
+
|
|
64
|
+
```bash
|
|
65
|
+
pip install "whensaid[url]" # add cuda on an NVIDIA GPU: "whensaid[cuda,url]" (or: uv tool install "whensaid[url]")
|
|
66
|
+
whensaid doctor # checks the GPU, models, yt-dlp and the index, says how to fix problems
|
|
67
|
+
whensaid add ~/Videos/talks # register a folder of recordings
|
|
68
|
+
whensaid add-url https://www.youtube.com/playlist?list=... # or a video, playlist or channel
|
|
69
|
+
whensaid index # transcribe and index what is new (models download on first use)
|
|
70
|
+
whensaid index --watch # or keep running and pick up new files every 30 s
|
|
71
|
+
whensaid index --subtitles # use a .srt/.vtt next to a recording instead of transcribing it
|
|
72
|
+
whensaid remove ~/Videos/old # stop watching a folder, playlist or video and drop it from the index
|
|
73
|
+
whensaid status
|
|
74
|
+
```
|
|
75
|
+
|
|
76
|
+
The models (about 1.6 GB for the default set) are downloaded the first time they are needed. `whensaid models pull`
|
|
77
|
+
fetches them ahead of time, and `WHENSAID_OFFLINE=1` forbids any download.
|
|
78
|
+
|
|
79
|
+
Then give your agent the MCP server (stdio):
|
|
80
|
+
|
|
81
|
+
```bash
|
|
82
|
+
claude mcp add whensaid -- whensaid serve
|
|
83
|
+
```
|
|
84
|
+
|
|
85
|
+
Tools the agent gets (all read-only): `search`, `get_transcript`, `list_sources`, `index_status`.
|
|
86
|
+
Indexing is only ever done by the `whensaid index` command, never by the agent.
|
|
87
|
+
|
|
88
|
+
## How good is it
|
|
89
|
+
|
|
90
|
+
Measured on the 65-hour public-domain index above, with questions written as paraphrases (the question sets are in `tests/`, the scripts in `scripts/`):
|
|
91
|
+
|
|
92
|
+
- The right passage is the top result for 83-97% of questions and in the top 5 for 96-100%, depending on the question set.
|
|
93
|
+
- Off-topic questions: 33 of 40 return nothing, and 6 of the other 7 come back marked `weak`.
|
|
94
|
+
- Against an agent that greps plain transcript files (`whensaid export`), with Claude Sonnet agents answering 36
|
|
95
|
+
questions: grep got 33 right and whensaid 31. That is a tie within noise for one run each, **so whensaid is not
|
|
96
|
+
more accurate than grep at this size**. What it adds is speed (an agent finished a batch of 8 questions in about a
|
|
97
|
+
minute instead of about nine), no export step, timestamp links for web videos, and a library that persists between
|
|
98
|
+
sessions. One run per arm, questions written by
|
|
99
|
+
someone who had read the transcripts. An earlier run looked much worse (25 of 36) only because the CLI cut each
|
|
100
|
+
passage to 200 characters; that is fixed.
|
|
101
|
+
- Not measured: word error rate against human transcripts, noisy or multi-speaker recordings beyond old radio, and any
|
|
102
|
+
hardware other than one Linux laptop (12 cores, RTX 3050).
|
|
103
|
+
|
|
104
|
+
## Limits
|
|
105
|
+
|
|
106
|
+
- English only. Videos in other languages, and recordings the model is unsure of, are skipped (see below).
|
|
107
|
+
- Linux is the tested platform; macOS runs in CI but nobody has used it daily. Windows is untried.
|
|
108
|
+
- Speech only. It does not look at the picture.
|
|
109
|
+
- Transcription is the slow part: about 14x realtime on the GPU it was tested on, about 6x on 12 CPU cores with the
|
|
110
|
+
default model. `WHENSAID_WHISPER_MODEL=small.en` trades accuracy for speed.
|
|
111
|
+
- Web videos are for videos you are allowed to download; each site's terms still apply and are your responsibility.
|
|
112
|
+
|
|
113
|
+
## Details
|
|
114
|
+
|
|
115
|
+
`whensaid index` also drops files that were deleted or moved (unless their folder is missing or holds no media at all,
|
|
116
|
+
which looks like an unplugged drive). With `--watch`, files are indexed once they have stopped changing for 15 s, and
|
|
117
|
+
a file that failed is retried only after it changes.
|
|
118
|
+
|
|
119
|
+
Web videos use their captions when there are any (seconds, no GPU) and are transcribed from the audio otherwise.
|
|
120
|
+
Playlists and channels are checked for new videos at most once an hour.
|
|
121
|
+
|
|
122
|
+
Things that will never work are skipped once and not asked for again: live streams, private or removed videos, videos
|
|
123
|
+
that are not in English, and recordings whose transcript the model itself was unsure of (usually another language, or
|
|
124
|
+
music). `whensaid status` lists them with the reason; `whensaid index --retry-skipped` tries them again, and
|
|
125
|
+
`WHENSAID_MIN_CONFIDENCE=0` turns the transcript check off.
|
|
126
|
+
|
|
127
|
+
Set `WHENSAID_HOME` to keep the index somewhere other than `~/.whensaid`.
|
|
128
|
+
|
|
129
|
+
## How it works
|
|
130
|
+
|
|
131
|
+
ffmpeg-free decode (PyAV) -> faster-whisper with VAD and word timestamps -> ~45 s overlapping
|
|
132
|
+
chunks -> bge-small embeddings -> one SQLite file (FTS5 keyword index + vectors).
|
|
133
|
+
Search fuses keyword and vector ranks (reciprocal rank fusion), then a small cross-encoder reranks the top 20
|
|
134
|
+
(`WHENSAID_RERANK=0` skips it). Passages it scores as unrelated are dropped, so off-topic questions usually return
|
|
135
|
+
nothing, and borderline hits come back marked `weak` (`WHENSAID_MIN_RELEVANCE` tunes this, `off` disables).
|
|
136
|
+
|
|
137
|
+
## Develop
|
|
138
|
+
|
|
139
|
+
```bash
|
|
140
|
+
uv pip install -e ".[dev]" && pytest
|
|
141
|
+
WHENSAID_HOME=<index with tests/data indexed> python scripts/eval.py --verbose
|
|
142
|
+
```
|
|
143
|
+
|
|
144
|
+
Test media is public domain; see [tests/data/README.md](tests/data/README.md).
|
|
145
|
+
|
|
146
|
+
License: MIT
|
whensaid-0.1.0/README.md
ADDED
|
@@ -0,0 +1,114 @@
|
|
|
1
|
+
# whensaid
|
|
2
|
+
|
|
3
|
+
Search what was *said* in your local video and audio files, from your AI agent.
|
|
4
|
+
|
|
5
|
+
Point it at folders of recordings (talks, courses, meetings, interviews, podcasts) or at a YouTube playlist.
|
|
6
|
+
Your agent (Claude Code, Cursor, ...) calls `search("when did they talk about X")` and gets back the file, the exact
|
|
7
|
+
timestamp and the passage; for web videos, a link that opens the video at that moment. Everything runs on your
|
|
8
|
+
machine, and nothing is uploaded.
|
|
9
|
+
|
|
10
|
+
**Status: pre-alpha.** Tested on Linux (CI also runs on macOS). Runs on an NVIDIA GPU or on CPU. English only.
|
|
11
|
+
|
|
12
|
+
## A worked example
|
|
13
|
+
|
|
14
|
+

|
|
15
|
+
|
|
16
|
+
The recording above is real `whensaid` output (rendered by `scripts/make_demo.py`), run in a terminal rather than from an agent session. Text version:
|
|
17
|
+
|
|
18
|
+
The index here is 198 public-domain recordings (65 hours of audiobooks and old radio). The question is paraphrased,
|
|
19
|
+
not a quote:
|
|
20
|
+
|
|
21
|
+
```
|
|
22
|
+
$ whensaid search "a mouse tribe claiming rights over everyone else" -n 1
|
|
23
|
+
strong the_consolation_of_philosophy_..._boethius_64kb.mp3 0:01:38 and over whom ye exercise your fancied
|
|
24
|
+
lordship suppose now that in the mouse tribe there should rise up one claiming rights and powers for himself above the rest ...
|
|
25
|
+
```
|
|
26
|
+
|
|
27
|
+
Through MCP the agent gets the same thing as JSON (`file`, `path`, `start`, `at`, `text`, `match`, `relevance`, and
|
|
28
|
+
`link` for web videos) and can call `get_transcript` to read around the hit. About half a second per search on CPU.
|
|
29
|
+
|
|
30
|
+
## Use it
|
|
31
|
+
|
|
32
|
+
```bash
|
|
33
|
+
pip install "whensaid[url]" # add cuda on an NVIDIA GPU: "whensaid[cuda,url]" (or: uv tool install "whensaid[url]")
|
|
34
|
+
whensaid doctor # checks the GPU, models, yt-dlp and the index, says how to fix problems
|
|
35
|
+
whensaid add ~/Videos/talks # register a folder of recordings
|
|
36
|
+
whensaid add-url https://www.youtube.com/playlist?list=... # or a video, playlist or channel
|
|
37
|
+
whensaid index # transcribe and index what is new (models download on first use)
|
|
38
|
+
whensaid index --watch # or keep running and pick up new files every 30 s
|
|
39
|
+
whensaid index --subtitles # use a .srt/.vtt next to a recording instead of transcribing it
|
|
40
|
+
whensaid remove ~/Videos/old # stop watching a folder, playlist or video and drop it from the index
|
|
41
|
+
whensaid status
|
|
42
|
+
```
|
|
43
|
+
|
|
44
|
+
The models (about 1.6 GB for the default set) are downloaded the first time they are needed. `whensaid models pull`
|
|
45
|
+
fetches them ahead of time, and `WHENSAID_OFFLINE=1` forbids any download.
|
|
46
|
+
|
|
47
|
+
Then give your agent the MCP server (stdio):
|
|
48
|
+
|
|
49
|
+
```bash
|
|
50
|
+
claude mcp add whensaid -- whensaid serve
|
|
51
|
+
```
|
|
52
|
+
|
|
53
|
+
Tools the agent gets (all read-only): `search`, `get_transcript`, `list_sources`, `index_status`.
|
|
54
|
+
Indexing is only ever done by the `whensaid index` command, never by the agent.
|
|
55
|
+
|
|
56
|
+
## How good is it
|
|
57
|
+
|
|
58
|
+
Measured on the 65-hour public-domain index above, with questions written as paraphrases (the question sets are in `tests/`, the scripts in `scripts/`):
|
|
59
|
+
|
|
60
|
+
- The right passage is the top result for 83-97% of questions and in the top 5 for 96-100%, depending on the question set.
|
|
61
|
+
- Off-topic questions: 33 of 40 return nothing, and 6 of the other 7 come back marked `weak`.
|
|
62
|
+
- Against an agent that greps plain transcript files (`whensaid export`), with Claude Sonnet agents answering 36
|
|
63
|
+
questions: grep got 33 right and whensaid 31. That is a tie within noise for one run each, **so whensaid is not
|
|
64
|
+
more accurate than grep at this size**. What it adds is speed (an agent finished a batch of 8 questions in about a
|
|
65
|
+
minute instead of about nine), no export step, timestamp links for web videos, and a library that persists between
|
|
66
|
+
sessions. One run per arm, questions written by
|
|
67
|
+
someone who had read the transcripts. An earlier run looked much worse (25 of 36) only because the CLI cut each
|
|
68
|
+
passage to 200 characters; that is fixed.
|
|
69
|
+
- Not measured: word error rate against human transcripts, noisy or multi-speaker recordings beyond old radio, and any
|
|
70
|
+
hardware other than one Linux laptop (12 cores, RTX 3050).
|
|
71
|
+
|
|
72
|
+
## Limits
|
|
73
|
+
|
|
74
|
+
- English only. Videos in other languages, and recordings the model is unsure of, are skipped (see below).
|
|
75
|
+
- Linux is the tested platform; macOS runs in CI but nobody has used it daily. Windows is untried.
|
|
76
|
+
- Speech only. It does not look at the picture.
|
|
77
|
+
- Transcription is the slow part: about 14x realtime on the GPU it was tested on, about 6x on 12 CPU cores with the
|
|
78
|
+
default model. `WHENSAID_WHISPER_MODEL=small.en` trades accuracy for speed.
|
|
79
|
+
- Web videos are for videos you are allowed to download; each site's terms still apply and are your responsibility.
|
|
80
|
+
|
|
81
|
+
## Details
|
|
82
|
+
|
|
83
|
+
`whensaid index` also drops files that were deleted or moved (unless their folder is missing or holds no media at all,
|
|
84
|
+
which looks like an unplugged drive). With `--watch`, files are indexed once they have stopped changing for 15 s, and
|
|
85
|
+
a file that failed is retried only after it changes.
|
|
86
|
+
|
|
87
|
+
Web videos use their captions when there are any (seconds, no GPU) and are transcribed from the audio otherwise.
|
|
88
|
+
Playlists and channels are checked for new videos at most once an hour.
|
|
89
|
+
|
|
90
|
+
Things that will never work are skipped once and not asked for again: live streams, private or removed videos, videos
|
|
91
|
+
that are not in English, and recordings whose transcript the model itself was unsure of (usually another language, or
|
|
92
|
+
music). `whensaid status` lists them with the reason; `whensaid index --retry-skipped` tries them again, and
|
|
93
|
+
`WHENSAID_MIN_CONFIDENCE=0` turns the transcript check off.
|
|
94
|
+
|
|
95
|
+
Set `WHENSAID_HOME` to keep the index somewhere other than `~/.whensaid`.
|
|
96
|
+
|
|
97
|
+
## How it works
|
|
98
|
+
|
|
99
|
+
ffmpeg-free decode (PyAV) -> faster-whisper with VAD and word timestamps -> ~45 s overlapping
|
|
100
|
+
chunks -> bge-small embeddings -> one SQLite file (FTS5 keyword index + vectors).
|
|
101
|
+
Search fuses keyword and vector ranks (reciprocal rank fusion), then a small cross-encoder reranks the top 20
|
|
102
|
+
(`WHENSAID_RERANK=0` skips it). Passages it scores as unrelated are dropped, so off-topic questions usually return
|
|
103
|
+
nothing, and borderline hits come back marked `weak` (`WHENSAID_MIN_RELEVANCE` tunes this, `off` disables).
|
|
104
|
+
|
|
105
|
+
## Develop
|
|
106
|
+
|
|
107
|
+
```bash
|
|
108
|
+
uv pip install -e ".[dev]" && pytest
|
|
109
|
+
WHENSAID_HOME=<index with tests/data indexed> python scripts/eval.py --verbose
|
|
110
|
+
```
|
|
111
|
+
|
|
112
|
+
Test media is public domain; see [tests/data/README.md](tests/data/README.md).
|
|
113
|
+
|
|
114
|
+
License: MIT
|
|
Binary file
|
|
@@ -0,0 +1,45 @@
|
|
|
1
|
+
[project]
|
|
2
|
+
name = "whensaid"
|
|
3
|
+
version = "0.1.0"
|
|
4
|
+
description = "Local, offline search over your video and audio recordings, exposed to AI agents over MCP."
|
|
5
|
+
readme = "README.md"
|
|
6
|
+
license = "MIT"
|
|
7
|
+
license-files = ["LICENSE"]
|
|
8
|
+
authors = [{ name = "VishnupiriyanV" }]
|
|
9
|
+
keywords = ["mcp", "whisper", "transcription", "search", "video", "audio", "local", "offline"]
|
|
10
|
+
classifiers = [
|
|
11
|
+
"Development Status :: 3 - Alpha",
|
|
12
|
+
"Environment :: Console",
|
|
13
|
+
"Intended Audience :: Developers",
|
|
14
|
+
"Operating System :: POSIX :: Linux",
|
|
15
|
+
"Programming Language :: Python :: 3",
|
|
16
|
+
"Topic :: Multimedia :: Sound/Audio :: Speech",
|
|
17
|
+
"Topic :: Text Processing :: Indexing",
|
|
18
|
+
]
|
|
19
|
+
requires-python = ">=3.11"
|
|
20
|
+
dependencies = [
|
|
21
|
+
"mcp>=2,<3",
|
|
22
|
+
"faster-whisper>=1.2,<2",
|
|
23
|
+
"av>=14,<17", # faster-whisper 1.2.1 breaks on av>=19 (verified 2026-11-10)
|
|
24
|
+
"fastembed>=0.9,<1", # ONNX embeddings, no torch
|
|
25
|
+
"numpy>=1.26",
|
|
26
|
+
]
|
|
27
|
+
|
|
28
|
+
[project.optional-dependencies]
|
|
29
|
+
cuda = ["nvidia-cublas-cu12", "nvidia-cudnn-cu12"] # what ctranslate2 needs on an NVIDIA GPU
|
|
30
|
+
url = ["yt-dlp"] # for `whensaid add-url`
|
|
31
|
+
dev = ["pytest"]
|
|
32
|
+
|
|
33
|
+
[project.urls]
|
|
34
|
+
Homepage = "https://github.com/VishnupiriyanV/whensaid"
|
|
35
|
+
Issues = "https://github.com/VishnupiriyanV/whensaid/issues"
|
|
36
|
+
|
|
37
|
+
[project.scripts]
|
|
38
|
+
whensaid = "whensaid.cli:main"
|
|
39
|
+
|
|
40
|
+
[build-system]
|
|
41
|
+
requires = ["hatchling"]
|
|
42
|
+
build-backend = "hatchling.build"
|
|
43
|
+
|
|
44
|
+
[tool.hatch.build.targets.wheel]
|
|
45
|
+
packages = ["src/whensaid"]
|
|
@@ -0,0 +1,120 @@
|
|
|
1
|
+
"""Compare reranker variants for speed and accuracy on the golden sets.
|
|
2
|
+
|
|
3
|
+
WHENSAID_HOME=<home with everything indexed> python scripts/bench_rerank.py
|
|
4
|
+
|
|
5
|
+
The fused keyword+semantic candidates are computed once per query, then each variant only
|
|
6
|
+
reorders them, so differences between rows come from the reranker alone. Latency is measured
|
|
7
|
+
with a query embedding run just before each rerank, the way a real search does it.
|
|
8
|
+
"""
|
|
9
|
+
import argparse
|
|
10
|
+
import json
|
|
11
|
+
import os
|
|
12
|
+
import statistics
|
|
13
|
+
import time
|
|
14
|
+
from pathlib import Path
|
|
15
|
+
|
|
16
|
+
from fastembed.common.model_description import ModelSource
|
|
17
|
+
from fastembed.rerank.cross_encoder import TextCrossEncoder
|
|
18
|
+
|
|
19
|
+
from whensaid import db, paths
|
|
20
|
+
from whensaid.embed import Embedder
|
|
21
|
+
from whensaid.paths import models_dir
|
|
22
|
+
from whensaid.search import Searcher, rrf
|
|
23
|
+
|
|
24
|
+
TESTS = Path(__file__).resolve().parent.parent / "tests"
|
|
25
|
+
SETS = ["golden.json", "golden_noisy.json", "golden_scale.json"]
|
|
26
|
+
|
|
27
|
+
# name -> (hf repo, onnx file)
|
|
28
|
+
MODELS = {
|
|
29
|
+
"L12": ("Xenova/ms-marco-MiniLM-L-12-v2", "onnx/model.onnx"),
|
|
30
|
+
"L12-q": ("Xenova/ms-marco-MiniLM-L-12-v2", "onnx/model_quantized.onnx"),
|
|
31
|
+
"L6": ("Xenova/ms-marco-MiniLM-L-6-v2", "onnx/model.onnx"),
|
|
32
|
+
"L6-q": ("Xenova/ms-marco-MiniLM-L-6-v2", "onnx/model_quantized.onnx"),
|
|
33
|
+
}
|
|
34
|
+
|
|
35
|
+
|
|
36
|
+
def load(name, threads):
|
|
37
|
+
repo, file = MODELS[name]
|
|
38
|
+
custom = f"whensaid-bench/{name}"
|
|
39
|
+
try:
|
|
40
|
+
TextCrossEncoder.add_custom_model(model=custom, sources=ModelSource(hf=repo), model_file=file)
|
|
41
|
+
except ValueError:
|
|
42
|
+
pass # registered on an earlier call
|
|
43
|
+
return TextCrossEncoder(custom, cache_dir=str(models_dir() / "fastembed"), threads=threads)
|
|
44
|
+
|
|
45
|
+
|
|
46
|
+
def is_hit(row, q):
|
|
47
|
+
return any(
|
|
48
|
+
os.path.basename(row["path"]) == a["file"] and row["start"] < a["end"] and row["end"] > a["start"]
|
|
49
|
+
for a in [q, *q.get("alt", [])]
|
|
50
|
+
)
|
|
51
|
+
|
|
52
|
+
|
|
53
|
+
def first_hit(rows, q, limit=10):
|
|
54
|
+
kept = []
|
|
55
|
+
for r in rows:
|
|
56
|
+
if any(k["path"] == r["path"] and k["start"] < r["end"] and r["start"] < k["end"] for k in kept):
|
|
57
|
+
continue # same passage as a better hit, as the searcher does
|
|
58
|
+
kept.append(r)
|
|
59
|
+
if is_hit(r, q):
|
|
60
|
+
return len(kept)
|
|
61
|
+
if len(kept) >= limit:
|
|
62
|
+
break
|
|
63
|
+
return None
|
|
64
|
+
|
|
65
|
+
|
|
66
|
+
def main():
|
|
67
|
+
ap = argparse.ArgumentParser()
|
|
68
|
+
ap.add_argument("--variants", default="L12:0,L12:4,L12-q:4,L6:4,L6-q:4", help="model:threads, 0 = library default")
|
|
69
|
+
ap.add_argument("--depths", default="20,10")
|
|
70
|
+
args = ap.parse_args()
|
|
71
|
+
|
|
72
|
+
conn = db.connect_readonly(paths.db_path())
|
|
73
|
+
embedder = Embedder()
|
|
74
|
+
searcher = Searcher(conn, embedder)
|
|
75
|
+
queries = []
|
|
76
|
+
for name in SETS:
|
|
77
|
+
for q in json.load(open(TESTS / name))["queries"]:
|
|
78
|
+
queries.append((name, q))
|
|
79
|
+
|
|
80
|
+
# candidates once per query: fused order, with the rows needed to score a hit
|
|
81
|
+
cands = []
|
|
82
|
+
for _, q in queries:
|
|
83
|
+
qv = searcher.query_vector(q["query"])
|
|
84
|
+
fused = rrf({"keyword": searcher.keyword_ids(q["query"], 50), "semantic": searcher.semantic_ids(q["query"], 50, qv)})
|
|
85
|
+
ids = [cid for cid, _, _ in fused[:40]]
|
|
86
|
+
marks = ",".join("?" * len(ids))
|
|
87
|
+
rows = {r["id"]: r for r in conn.execute(
|
|
88
|
+
f"select c.id, c.start, c.end, c.text, s.path from chunks c join sources s on s.id = c.source_id where c.id in ({marks})", ids)}
|
|
89
|
+
cands.append([rows[i] for i in ids])
|
|
90
|
+
|
|
91
|
+
def report(label, ranked, ms=None):
|
|
92
|
+
cells = []
|
|
93
|
+
for name in SETS:
|
|
94
|
+
rs = [first_hit(r, q) for (n, q), r in zip(queries, ranked) if n == name]
|
|
95
|
+
cells.append(f"{sum(1 for r in rs if r == 1) / len(rs):.2f}/{sum(1 for r in rs if r and r <= 5) / len(rs):.2f}")
|
|
96
|
+
t = "" if ms is None else f"{statistics.median(ms):5.0f} {max(ms):5.0f}"
|
|
97
|
+
print(f"{label:16} {cells[0]:>10} {cells[1]:>10} {cells[2]:>10} {t}")
|
|
98
|
+
|
|
99
|
+
print(f"{len(queries)} queries, R@1/R@5 per set, then median and max rerank ms")
|
|
100
|
+
print(f"{'variant':16} {'clean':>10} {'noisy':>10} {'scale':>10} {'med':>5} {'max':>5}")
|
|
101
|
+
report("no reranker", cands)
|
|
102
|
+
for spec in args.variants.split(","):
|
|
103
|
+
name, threads = spec.split(":")
|
|
104
|
+
rr = load(name, int(threads) or None)
|
|
105
|
+
list(rr.rerank("warm up", ["warm up"]))
|
|
106
|
+
for depth in [int(d) for d in args.depths.split(",")]:
|
|
107
|
+
ranked, ms = [], []
|
|
108
|
+
for (_, q), rows in zip(queries, cands):
|
|
109
|
+
embedder.encode([q["query"]]) # a search embeds the query right before reranking
|
|
110
|
+
head = rows[:depth]
|
|
111
|
+
t = time.time()
|
|
112
|
+
scores = list(rr.rerank(q["query"], [r["text"] for r in head]))
|
|
113
|
+
ms.append((time.time() - t) * 1000)
|
|
114
|
+
order = [r for _, r in sorted(zip(scores, head), key=lambda x: -x[0])]
|
|
115
|
+
ranked.append(order + rows[depth:])
|
|
116
|
+
report(f"{name} t={threads} d={depth}", ranked, ms)
|
|
117
|
+
|
|
118
|
+
|
|
119
|
+
if __name__ == "__main__":
|
|
120
|
+
main()
|
|
@@ -0,0 +1,122 @@
|
|
|
1
|
+
"""Try other embedding models and rerankers on the golden set, without touching the index.
|
|
2
|
+
|
|
3
|
+
WHENSAID_HOME=<home> python scripts/compare_models.py --embedders bge-base,gte-base --rerankers jina-turbo
|
|
4
|
+
|
|
5
|
+
Chunks are re-embedded in memory for each candidate. Hybrid is keyword + semantic fused with
|
|
6
|
+
rrf as in the real searcher, and a reranker (if given) reorders the top 20 of that.
|
|
7
|
+
"""
|
|
8
|
+
import argparse
|
|
9
|
+
import json
|
|
10
|
+
import os
|
|
11
|
+
import time
|
|
12
|
+
from pathlib import Path
|
|
13
|
+
|
|
14
|
+
import numpy as np
|
|
15
|
+
from fastembed import TextEmbedding
|
|
16
|
+
from fastembed.rerank.cross_encoder import TextCrossEncoder
|
|
17
|
+
|
|
18
|
+
from whensaid import db, paths
|
|
19
|
+
from whensaid.search import Searcher, rrf
|
|
20
|
+
|
|
21
|
+
GOLDEN = Path(__file__).resolve().parent.parent / "tests" / "golden.json"
|
|
22
|
+
BGE = "Represent this sentence for searching relevant passages: "
|
|
23
|
+
|
|
24
|
+
# name -> (model id, query prefix, passage prefix)
|
|
25
|
+
EMBEDDERS = {
|
|
26
|
+
"bge-small": ("BAAI/bge-small-en-v1.5", BGE, ""),
|
|
27
|
+
"bge-base": ("BAAI/bge-base-en-v1.5", BGE, ""),
|
|
28
|
+
"bge-large": ("BAAI/bge-large-en-v1.5", BGE, ""),
|
|
29
|
+
"arctic-m": ("snowflake/snowflake-arctic-embed-m", BGE, ""),
|
|
30
|
+
"gte-base": ("thenlper/gte-base", "", ""),
|
|
31
|
+
"nomic-q": ("nomic-ai/nomic-embed-text-v1.5-Q", "search_query: ", "search_document: "),
|
|
32
|
+
"mxbai": ("mixedbread-ai/mxbai-embed-large-v1", BGE, ""),
|
|
33
|
+
}
|
|
34
|
+
RERANKERS = {
|
|
35
|
+
"minilm-12": "Xenova/ms-marco-MiniLM-L-12-v2",
|
|
36
|
+
"jina-turbo": "jinaai/jina-reranker-v1-turbo-en",
|
|
37
|
+
"bge-rr-base": "BAAI/bge-reranker-base",
|
|
38
|
+
}
|
|
39
|
+
|
|
40
|
+
|
|
41
|
+
def is_hit(path, start, end, q):
|
|
42
|
+
return any(os.path.basename(path) == a["file"] and start < a["end"] and end > a["start"] for a in [q, *q.get("alt", [])])
|
|
43
|
+
|
|
44
|
+
|
|
45
|
+
def score(ranked, golden):
|
|
46
|
+
"""ranked: one list of (path, start, end) per query, best first."""
|
|
47
|
+
rows = []
|
|
48
|
+
for q, hits in zip(golden, ranked):
|
|
49
|
+
r = next((i for i, h in enumerate(hits, 1) if is_hit(*h[:3], q)), None)
|
|
50
|
+
rows.append(r)
|
|
51
|
+
n = len(rows)
|
|
52
|
+
at = lambda k: sum(1 for r in rows if r and r <= k) / n
|
|
53
|
+
return at(1), at(5), at(10), sum(1 / r for r in rows if r) / n
|
|
54
|
+
|
|
55
|
+
|
|
56
|
+
def dedupe(hits, limit=10):
|
|
57
|
+
out = []
|
|
58
|
+
for h in hits:
|
|
59
|
+
if any(o[0] == h[0] and o[1] < h[2] and h[1] < o[2] for o in out):
|
|
60
|
+
continue
|
|
61
|
+
out.append(h)
|
|
62
|
+
return out[:limit]
|
|
63
|
+
|
|
64
|
+
|
|
65
|
+
def main():
|
|
66
|
+
ap = argparse.ArgumentParser()
|
|
67
|
+
ap.add_argument("--embedders", default="bge-small,bge-base,gte-base,arctic-m,nomic-q")
|
|
68
|
+
ap.add_argument("--rerankers", default="minilm-12,jina-turbo,bge-rr-base")
|
|
69
|
+
ap.add_argument("--depth", type=int, default=20, help="how many fused hits the reranker sees")
|
|
70
|
+
args = ap.parse_args()
|
|
71
|
+
|
|
72
|
+
golden = [q for q in json.load(open(GOLDEN))["queries"]]
|
|
73
|
+
conn = db.connect(paths.db_path())
|
|
74
|
+
chunks = conn.execute(
|
|
75
|
+
"select c.id, c.start, c.end, c.text, s.path from chunks c join sources s on s.id = c.source_id order by c.id"
|
|
76
|
+
).fetchall()
|
|
77
|
+
ids = [c["id"] for c in chunks]
|
|
78
|
+
by_id = {c["id"]: c for c in chunks}
|
|
79
|
+
print(f"{len(chunks)} chunks, {len(golden)} queries")
|
|
80
|
+
|
|
81
|
+
kw = Searcher(conn, None) # only used for its keyword side
|
|
82
|
+
keyword = [kw.keyword_ids(q["query"], 50) for q in golden]
|
|
83
|
+
|
|
84
|
+
def as_hits(chunk_ids):
|
|
85
|
+
return [(by_id[i]["path"], by_id[i]["start"], by_id[i]["end"], i) for i in chunk_ids]
|
|
86
|
+
|
|
87
|
+
rerank_models = {}
|
|
88
|
+
print(f"\n{'embedder':10} {'stage':22} {'R@1':>5} {'R@5':>5} {'R@10':>5} {'MRR':>5} {'embed s':>7}")
|
|
89
|
+
for name in args.embedders.split(","):
|
|
90
|
+
model_id, qp, pp = EMBEDDERS[name]
|
|
91
|
+
t0 = time.time()
|
|
92
|
+
emb = TextEmbedding(model_id)
|
|
93
|
+
mat = np.array(list(emb.embed([pp + c["text"] for c in chunks], batch_size=32)), dtype=np.float32)
|
|
94
|
+
mat /= np.linalg.norm(mat, axis=1, keepdims=True)
|
|
95
|
+
took = time.time() - t0
|
|
96
|
+
qv = np.array(list(emb.embed([qp + q["query"] for q in golden])), dtype=np.float32)
|
|
97
|
+
qv /= np.linalg.norm(qv, axis=1, keepdims=True)
|
|
98
|
+
|
|
99
|
+
sem = [[ids[j] for j in np.argsort(-(mat @ v))[:50]] for v in qv]
|
|
100
|
+
fused = [[cid for cid, _, _ in rrf({"keyword": k, "semantic": s})] for k, s in zip(keyword, sem)]
|
|
101
|
+
|
|
102
|
+
def show(stage, lists, t=None):
|
|
103
|
+
ranked = [dedupe(as_hits(l)) for l in lists]
|
|
104
|
+
r1, r5, r10, mrr = score(ranked, golden)
|
|
105
|
+
print(f"{name:10} {stage:22} {r1:5.2f} {r5:5.2f} {r10:5.2f} {mrr:5.2f} {t if t else '':>7}")
|
|
106
|
+
|
|
107
|
+
show("semantic", sem, f"{took:.0f}")
|
|
108
|
+
show("hybrid", fused)
|
|
109
|
+
for rname in filter(None, args.rerankers.split(",")):
|
|
110
|
+
if rname not in rerank_models:
|
|
111
|
+
rerank_models[rname] = TextCrossEncoder(RERANKERS[rname])
|
|
112
|
+
rr = rerank_models[rname]
|
|
113
|
+
out = []
|
|
114
|
+
for q, f in zip(golden, fused):
|
|
115
|
+
top = f[: args.depth]
|
|
116
|
+
scores = list(rr.rerank(q["query"], [by_id[i]["text"] for i in top]))
|
|
117
|
+
out.append([i for _, i in sorted(zip(scores, top), key=lambda x: -x[0])])
|
|
118
|
+
show(f"hybrid+{rname}", out)
|
|
119
|
+
|
|
120
|
+
|
|
121
|
+
if __name__ == "__main__":
|
|
122
|
+
main()
|