wavewash 0.1.0a1__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- wavewash-0.1.0a1/.github/workflows/tests.yml +21 -0
- wavewash-0.1.0a1/LICENSE +29 -0
- wavewash-0.1.0a1/MANIFEST.in +9 -0
- wavewash-0.1.0a1/PKG-INFO +153 -0
- wavewash-0.1.0a1/README.md +109 -0
- wavewash-0.1.0a1/docs/STEP_BY_STEP.md +85 -0
- wavewash-0.1.0a1/docs/USER_MANUAL.md +311 -0
- wavewash-0.1.0a1/docs/screenshot-setup.png +0 -0
- wavewash-0.1.0a1/frontend/.gitignore +24 -0
- wavewash-0.1.0a1/frontend/.oxlintrc.json +8 -0
- wavewash-0.1.0a1/frontend/index.html +16 -0
- wavewash-0.1.0a1/frontend/package-lock.json +2894 -0
- wavewash-0.1.0a1/frontend/package.json +31 -0
- wavewash-0.1.0a1/frontend/public/favicon.svg +1 -0
- wavewash-0.1.0a1/frontend/public/icons.svg +24 -0
- wavewash-0.1.0a1/frontend/src/App.jsx +208 -0
- wavewash-0.1.0a1/frontend/src/api.js +19 -0
- wavewash-0.1.0a1/frontend/src/components/AdvancedSettings.jsx +127 -0
- wavewash-0.1.0a1/frontend/src/components/FolderBrowser.jsx +109 -0
- wavewash-0.1.0a1/frontend/src/components/PathsPanel.jsx +88 -0
- wavewash-0.1.0a1/frontend/src/components/PurposeSelector.jsx +39 -0
- wavewash-0.1.0a1/frontend/src/components/QualityPresets.jsx +75 -0
- wavewash-0.1.0a1/frontend/src/components/ResultsDashboard.jsx +179 -0
- wavewash-0.1.0a1/frontend/src/components/RunOptions.jsx +50 -0
- wavewash-0.1.0a1/frontend/src/components/RunProgress.jsx +68 -0
- wavewash-0.1.0a1/frontend/src/index.css +49 -0
- wavewash-0.1.0a1/frontend/src/main.jsx +10 -0
- wavewash-0.1.0a1/frontend/src/presets.js +129 -0
- wavewash-0.1.0a1/frontend/vite.config.js +14 -0
- wavewash-0.1.0a1/pyproject.toml +56 -0
- wavewash-0.1.0a1/setup.cfg +4 -0
- wavewash-0.1.0a1/src/wavewash/__init__.py +2 -0
- wavewash-0.1.0a1/src/wavewash/__main__.py +2 -0
- wavewash-0.1.0a1/src/wavewash/alignment_checker.py +87 -0
- wavewash-0.1.0a1/src/wavewash/audio_fixer.py +283 -0
- wavewash-0.1.0a1/src/wavewash/audio_scanner.py +61 -0
- wavewash-0.1.0a1/src/wavewash/cli.py +83 -0
- wavewash-0.1.0a1/src/wavewash/config.py +208 -0
- wavewash-0.1.0a1/src/wavewash/dedup_detector.py +189 -0
- wavewash-0.1.0a1/src/wavewash/diversity_report.py +104 -0
- wavewash-0.1.0a1/src/wavewash/logger_setup.py +159 -0
- wavewash-0.1.0a1/src/wavewash/metadata_checker.py +172 -0
- wavewash-0.1.0a1/src/wavewash/pipeline.py +585 -0
- wavewash-0.1.0a1/src/wavewash/quality_checker.py +430 -0
- wavewash-0.1.0a1/src/wavewash/review_sampler.py +100 -0
- wavewash-0.1.0a1/src/wavewash/server.py +468 -0
- wavewash-0.1.0a1/src/wavewash/static/assets/index-CK5HsmPs.css +2 -0
- wavewash-0.1.0a1/src/wavewash/static/assets/index-DTvS4S6_.js +68 -0
- wavewash-0.1.0a1/src/wavewash/static/favicon.svg +1 -0
- wavewash-0.1.0a1/src/wavewash/static/icons.svg +24 -0
- wavewash-0.1.0a1/src/wavewash/static/index.html +17 -0
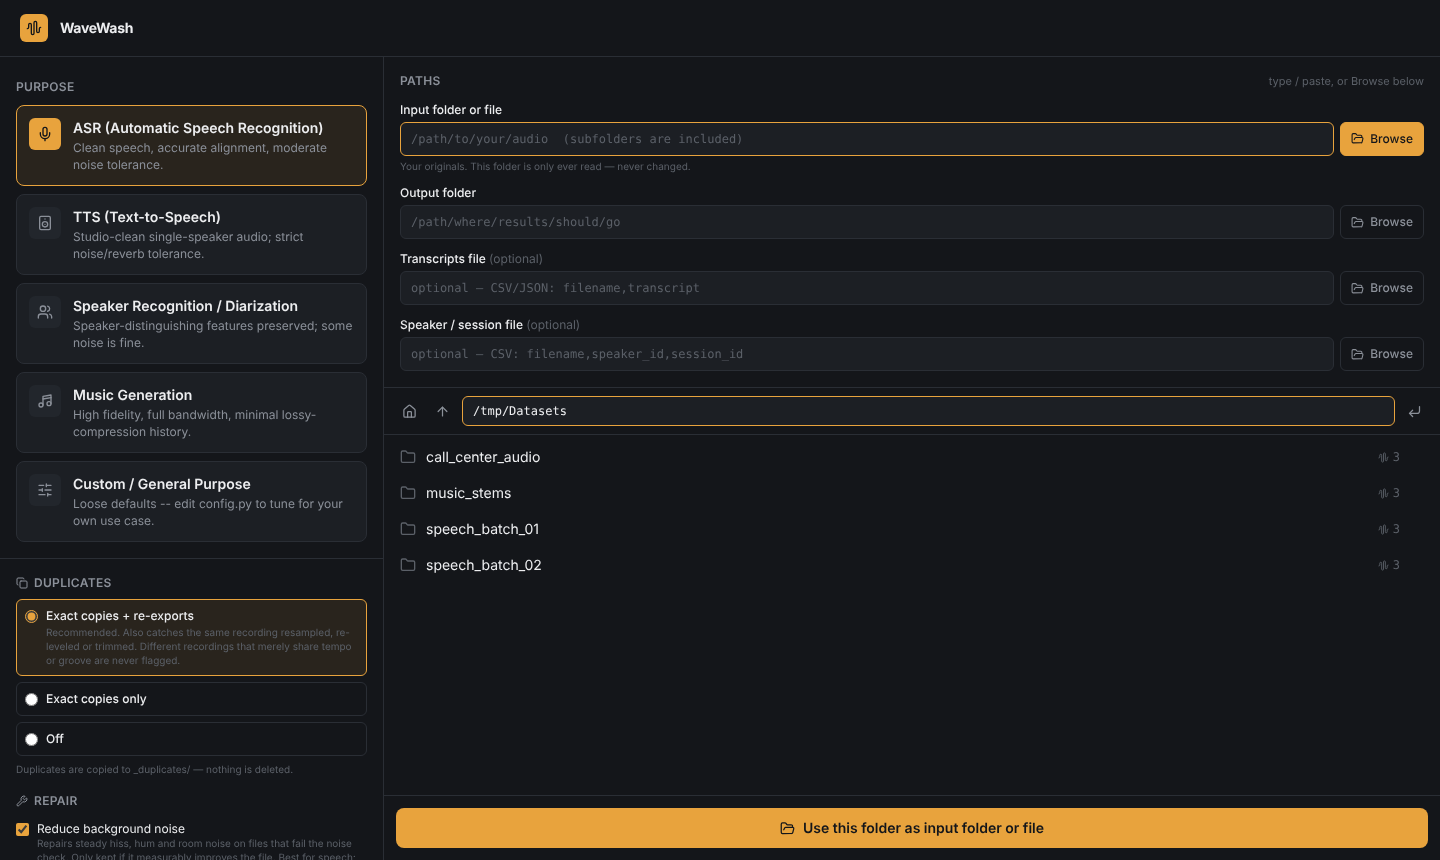
- wavewash-0.1.0a1/src/wavewash/transcript_checker.py +158 -0
- wavewash-0.1.0a1/src/wavewash/vad_module.py +105 -0
- wavewash-0.1.0a1/src/wavewash.egg-info/PKG-INFO +153 -0
- wavewash-0.1.0a1/src/wavewash.egg-info/SOURCES.txt +61 -0
- wavewash-0.1.0a1/src/wavewash.egg-info/dependency_links.txt +1 -0
- wavewash-0.1.0a1/src/wavewash.egg-info/entry_points.txt +2 -0
- wavewash-0.1.0a1/src/wavewash.egg-info/requires.txt +30 -0
- wavewash-0.1.0a1/src/wavewash.egg-info/top_level.txt +1 -0
- wavewash-0.1.0a1/tests/conftest.py +58 -0
- wavewash-0.1.0a1/tests/test_calibration.py +17 -0
- wavewash-0.1.0a1/tests/test_pipeline.py +138 -0
- wavewash-0.1.0a1/tests/test_server_and_cli.py +99 -0
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
name: tests
|
|
2
|
+
on:
|
|
3
|
+
push:
|
|
4
|
+
pull_request:
|
|
5
|
+
jobs:
|
|
6
|
+
test:
|
|
7
|
+
runs-on: ${{ matrix.os }}
|
|
8
|
+
strategy:
|
|
9
|
+
fail-fast: false
|
|
10
|
+
matrix:
|
|
11
|
+
os: [ubuntu-latest, macos-latest, windows-latest]
|
|
12
|
+
python: ["3.10", "3.12", "3.13"]
|
|
13
|
+
steps:
|
|
14
|
+
- uses: actions/checkout@v4
|
|
15
|
+
- uses: actions/setup-python@v5
|
|
16
|
+
with:
|
|
17
|
+
python-version: ${{ matrix.python }}
|
|
18
|
+
- run: python -m pip install --upgrade pip
|
|
19
|
+
- run: python -m pip install -e ".[dev]"
|
|
20
|
+
- run: wavewash doctor
|
|
21
|
+
- run: python -m pytest -q
|
wavewash-0.1.0a1/LICENSE
ADDED
|
@@ -0,0 +1,29 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Boobalan Arjunan
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
22
|
+
|
|
23
|
+
---
|
|
24
|
+
This project depends on third-party libraries (numpy, scipy, soundfile,
|
|
25
|
+
librosa, pyloudnorm, scikit-learn, tqdm, langdetect, matplotlib, and
|
|
26
|
+
optionally openai-whisper, torch/torchaudio). Each carries its own license
|
|
27
|
+
(mostly BSD/MIT/Apache-2.0) -- check requirements.txt and each package's own
|
|
28
|
+
license before redistributing, especially if your GTV program has its own
|
|
29
|
+
licensing rules.
|
|
@@ -0,0 +1,9 @@
|
|
|
1
|
+
include README.md LICENSE
|
|
2
|
+
recursive-include src/wavewash/static *
|
|
3
|
+
recursive-include frontend *
|
|
4
|
+
prune frontend/node_modules
|
|
5
|
+
prune frontend/dist
|
|
6
|
+
global-exclude __pycache__ *.pyc .DS_Store
|
|
7
|
+
recursive-include tests *.py
|
|
8
|
+
recursive-include docs *.md *.png
|
|
9
|
+
include .github/workflows/tests.yml
|
|
@@ -0,0 +1,153 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: wavewash
|
|
3
|
+
Version: 0.1.0a1
|
|
4
|
+
Summary: WaveWash: audio QC & data prep - check, repair, dedupe and audit audio datasets for ML training (ASR, TTS, speaker ID, music generation), with a local web UI.
|
|
5
|
+
Author-email: Boobalan Arjunan <boobalan.it@gmail.com>
|
|
6
|
+
Maintainer-email: Boobalan Arjunan <boobalan.it@gmail.com>
|
|
7
|
+
License: MIT
|
|
8
|
+
Project-URL: Homepage, https://github.com/BoobalanArjunan/wavewash
|
|
9
|
+
Project-URL: Source, https://github.com/BoobalanArjunan/wavewash
|
|
10
|
+
Project-URL: Issues, https://github.com/BoobalanArjunan/wavewash/issues
|
|
11
|
+
Keywords: audio,dataset,quality-control,asr,tts,machine-learning,data-preparation
|
|
12
|
+
Classifier: Programming Language :: Python :: 3
|
|
13
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
14
|
+
Classifier: Topic :: Multimedia :: Sound/Audio :: Analysis
|
|
15
|
+
Classifier: Intended Audience :: Science/Research
|
|
16
|
+
Requires-Python: >=3.10
|
|
17
|
+
Description-Content-Type: text/markdown
|
|
18
|
+
License-File: LICENSE
|
|
19
|
+
Requires-Dist: numpy>=1.23
|
|
20
|
+
Requires-Dist: scipy>=1.9
|
|
21
|
+
Requires-Dist: soundfile>=0.12
|
|
22
|
+
Requires-Dist: librosa>=0.10
|
|
23
|
+
Requires-Dist: pyloudnorm>=0.1.1
|
|
24
|
+
Requires-Dist: scikit-learn>=1.2
|
|
25
|
+
Requires-Dist: tqdm>=4.65
|
|
26
|
+
Requires-Dist: fastapi>=0.110
|
|
27
|
+
Requires-Dist: uvicorn>=0.29
|
|
28
|
+
Provides-Extra: lang
|
|
29
|
+
Requires-Dist: langdetect>=1.0.9; extra == "lang"
|
|
30
|
+
Provides-Extra: plots
|
|
31
|
+
Requires-Dist: matplotlib>=3.5; extra == "plots"
|
|
32
|
+
Provides-Extra: vad
|
|
33
|
+
Requires-Dist: torch>=2.0; extra == "vad"
|
|
34
|
+
Requires-Dist: torchaudio>=2.0; extra == "vad"
|
|
35
|
+
Provides-Extra: whisper
|
|
36
|
+
Requires-Dist: openai-whisper; extra == "whisper"
|
|
37
|
+
Provides-Extra: dev
|
|
38
|
+
Requires-Dist: pytest>=7; extra == "dev"
|
|
39
|
+
Requires-Dist: httpx>=0.25; extra == "dev"
|
|
40
|
+
Provides-Extra: all
|
|
41
|
+
Requires-Dist: langdetect>=1.0.9; extra == "all"
|
|
42
|
+
Requires-Dist: matplotlib>=3.5; extra == "all"
|
|
43
|
+
Dynamic: license-file
|
|
44
|
+
|
|
45
|
+
# WaveWash
|
|
46
|
+
|
|
47
|
+
[](https://github.com/BoobalanArjunan/wavewash/actions/workflows/tests.yml)
|
|
48
|
+

|
|
49
|
+

|
|
50
|
+
|
|
51
|
+
**Check, repair and clean audio datasets before you train on them.**
|
|
52
|
+
|
|
53
|
+
Point WaveWash at a folder of audio and tell it what you are training (speech recognition, voice synthesis, speaker ID, music generation). It checks every file, repairs what it can *verify* is fixed, moves the rest to an error folder with a labeled reason, sets duplicates aside, and writes a full audit log. Your original files are never modified.
|
|
54
|
+
|
|
55
|
+
> **Status: alpha (0.1.0a1).** It works on the cases in its test suite, but it has not yet been validated on large real-world speech corpora. Treat its verdicts as a first pass and listen to a sample of what it keeps and rejects. See [Limitations](#limitations).
|
|
56
|
+
|
|
57
|
+
|
|
58
|
+
|
|
59
|
+
## Why
|
|
60
|
+
|
|
61
|
+
Models inherit the flaws of their audio: clipped or distorted takes, DC offset, background noise, low-quality copies of better recordings, duplicates that quietly inflate test scores, empty or broken files. These are usually found by hand (listening to thousands of files) or not at all. WaveWash puts the common checks in one tool and tells you *why* each file was kept, repaired or rejected.
|
|
62
|
+
|
|
63
|
+
## Install
|
|
64
|
+
|
|
65
|
+
```bash
|
|
66
|
+
python3 -m venv ~/wavewash-env
|
|
67
|
+
source ~/wavewash-env/bin/activate # Windows: wavewash-env\Scripts\activate
|
|
68
|
+
pip install wavewash
|
|
69
|
+
wavewash doctor # confirms the install works
|
|
70
|
+
```
|
|
71
|
+
|
|
72
|
+
Python 3.10 or newer. No Node.js needed: the web app ships inside the package.
|
|
73
|
+
|
|
74
|
+
Optional extras: `pip install "wavewash[lang]"` (transcript language check), `[plots]` (spectrograms in review samples), `[vad]` (Silero VAD, pulls in PyTorch), `[whisper]` (WER check).
|
|
75
|
+
|
|
76
|
+
## Use it
|
|
77
|
+
|
|
78
|
+
**Web app** (runs only on your machine, at `http://127.0.0.1:8420`):
|
|
79
|
+
|
|
80
|
+
```bash
|
|
81
|
+
wavewash app
|
|
82
|
+
```
|
|
83
|
+
|
|
84
|
+
Pick a purpose, choose an input folder (subfolders are included) and an output folder, click run.
|
|
85
|
+
|
|
86
|
+
**Command line:**
|
|
87
|
+
|
|
88
|
+
```bash
|
|
89
|
+
wavewash run --input ./raw_audio --output ./out/clean --purpose asr
|
|
90
|
+
wavewash run --help
|
|
91
|
+
```
|
|
92
|
+
|
|
93
|
+
Purposes: `asr`, `tts`, `speaker_id`, `music_gen`, `custom`.
|
|
94
|
+
|
|
95
|
+
## What you get
|
|
96
|
+
|
|
97
|
+
```
|
|
98
|
+
out/
|
|
99
|
+
clean/ audio that passed, or was repaired and re-checked
|
|
100
|
+
_error/ rejected files, in folders named by reason (low_snr/, clipping/, corrupt_or_unreadable/ ...)
|
|
101
|
+
_duplicates/ duplicates, copied here (nothing is deleted)
|
|
102
|
+
_logs/ audit_log_*.csv and .json (one row per file: what was found, what was fixed, why rejected), summary_*.md
|
|
103
|
+
```
|
|
104
|
+
|
|
105
|
+
## What it checks and repairs
|
|
106
|
+
|
|
107
|
+
| Checks | Repairs (only kept if a re-check shows they helped) |
|
|
108
|
+
|---|---|
|
|
109
|
+
| Unreadable, empty or truncated files | DC offset removal |
|
|
110
|
+
| Too short / too long for the purpose | De-clipping of short clipped runs (up to 8 ms, spline interpolation) |
|
|
111
|
+
| Signal-to-noise ratio (estimate) | Noise reduction (spectral subtraction, kept only if the SNR estimate improves) |
|
|
112
|
+
| Clipping, DC offset, loudness | Loudness normalisation, resampling, channel conversion to the purpose's targets |
|
|
113
|
+
| Silence: mostly-silent files, long gaps | Trimming silence at the edges |
|
|
114
|
+
| Lossy or low-pass sources (sharp spectral cliff) | |
|
|
115
|
+
| Exact duplicates, same-samples duplicates, near-duplicates (same take, different level or format) | |
|
|
116
|
+
| Multiple speakers (heuristic) | |
|
|
117
|
+
| Optional: transcript language, WER against Whisper, speaker/session train-validation split | |
|
|
118
|
+
|
|
119
|
+
Repair is classical signal processing, **not** machine learning.
|
|
120
|
+
|
|
121
|
+
## Limitations
|
|
122
|
+
|
|
123
|
+
Please read these before trusting a result.
|
|
124
|
+
|
|
125
|
+
- **Alpha, tested on synthetic data.** The test suite plants known defects (DC offset, clipping, duplicates, broken, empty and stereo files, other sample rates) and checks the routing, that originals are never modified, the local server's safety rules and the command line. It has *not* been validated on large real speech corpora; thresholds are reasoned defaults.
|
|
126
|
+
- **"Repaired" means "passed the re-check", not "restored".** De-clipping interpolates over saturated samples. On heavily clipped audio the re-check can pass even though the result is far from the original recording. Listen to repaired files.
|
|
127
|
+
- **Reverb (RT60) is a warning only.** Measured against synthetic rooms of known reverb time, the blind estimate could not tell dry from reverberant audio, so it never rejects a file.
|
|
128
|
+
- **Heuristics, not trained models:** the SNR estimate, the multi-speaker check and the near-duplicate threshold. Check their verdicts on your own data.
|
|
129
|
+
- **Music:** mid-track silence is not flagged, and moderate noise can go unnoticed.
|
|
130
|
+
- **Not yet measured:** whether cleaned data improves a trained model; speed and memory on very large datasets; real Whisper and Silero runs.
|
|
131
|
+
- The web app has **no login** and binds to `127.0.0.1` only. Do not expose it to a network.
|
|
132
|
+
|
|
133
|
+
## Development
|
|
134
|
+
|
|
135
|
+
```bash
|
|
136
|
+
git clone https://github.com/BoobalanArjunan/wavewash.git
|
|
137
|
+
cd wavewash
|
|
138
|
+
python3 -m venv .venv && source .venv/bin/activate
|
|
139
|
+
pip install -e ".[dev]"
|
|
140
|
+
python -m pytest -q
|
|
141
|
+
```
|
|
142
|
+
|
|
143
|
+
The front-end source is in `frontend/` (React + Vite). The built app is committed in `src/wavewash/static/`; to rebuild it: `cd frontend && npm ci && npm run build`, then copy `dist/` over `src/wavewash/static/`.
|
|
144
|
+
|
|
145
|
+
Documentation: [step-by-step guide](docs/STEP_BY_STEP.md) · [user manual](docs/USER_MANUAL.md)
|
|
146
|
+
|
|
147
|
+
## Contributing
|
|
148
|
+
|
|
149
|
+
Bug reports with a small example file are the most useful contribution. If WaveWash rejects a good file or passes a bad one, please open an issue with the log row for that file (from `_logs/audit_log_*.csv`).
|
|
150
|
+
|
|
151
|
+
## License
|
|
152
|
+
|
|
153
|
+
MIT
|
|
@@ -0,0 +1,109 @@
|
|
|
1
|
+
# WaveWash
|
|
2
|
+
|
|
3
|
+
[](https://github.com/BoobalanArjunan/wavewash/actions/workflows/tests.yml)
|
|
4
|
+

|
|
5
|
+

|
|
6
|
+
|
|
7
|
+
**Check, repair and clean audio datasets before you train on them.**
|
|
8
|
+
|
|
9
|
+
Point WaveWash at a folder of audio and tell it what you are training (speech recognition, voice synthesis, speaker ID, music generation). It checks every file, repairs what it can *verify* is fixed, moves the rest to an error folder with a labeled reason, sets duplicates aside, and writes a full audit log. Your original files are never modified.
|
|
10
|
+
|
|
11
|
+
> **Status: alpha (0.1.0a1).** It works on the cases in its test suite, but it has not yet been validated on large real-world speech corpora. Treat its verdicts as a first pass and listen to a sample of what it keeps and rejects. See [Limitations](#limitations).
|
|
12
|
+
|
|
13
|
+

|
|
14
|
+
|
|
15
|
+
## Why
|
|
16
|
+
|
|
17
|
+
Models inherit the flaws of their audio: clipped or distorted takes, DC offset, background noise, low-quality copies of better recordings, duplicates that quietly inflate test scores, empty or broken files. These are usually found by hand (listening to thousands of files) or not at all. WaveWash puts the common checks in one tool and tells you *why* each file was kept, repaired or rejected.
|
|
18
|
+
|
|
19
|
+
## Install
|
|
20
|
+
|
|
21
|
+
```bash
|
|
22
|
+
python3 -m venv ~/wavewash-env
|
|
23
|
+
source ~/wavewash-env/bin/activate # Windows: wavewash-env\Scripts\activate
|
|
24
|
+
pip install wavewash
|
|
25
|
+
wavewash doctor # confirms the install works
|
|
26
|
+
```
|
|
27
|
+
|
|
28
|
+
Python 3.10 or newer. No Node.js needed: the web app ships inside the package.
|
|
29
|
+
|
|
30
|
+
Optional extras: `pip install "wavewash[lang]"` (transcript language check), `[plots]` (spectrograms in review samples), `[vad]` (Silero VAD, pulls in PyTorch), `[whisper]` (WER check).
|
|
31
|
+
|
|
32
|
+
## Use it
|
|
33
|
+
|
|
34
|
+
**Web app** (runs only on your machine, at `http://127.0.0.1:8420`):
|
|
35
|
+
|
|
36
|
+
```bash
|
|
37
|
+
wavewash app
|
|
38
|
+
```
|
|
39
|
+
|
|
40
|
+
Pick a purpose, choose an input folder (subfolders are included) and an output folder, click run.
|
|
41
|
+
|
|
42
|
+
**Command line:**
|
|
43
|
+
|
|
44
|
+
```bash
|
|
45
|
+
wavewash run --input ./raw_audio --output ./out/clean --purpose asr
|
|
46
|
+
wavewash run --help
|
|
47
|
+
```
|
|
48
|
+
|
|
49
|
+
Purposes: `asr`, `tts`, `speaker_id`, `music_gen`, `custom`.
|
|
50
|
+
|
|
51
|
+
## What you get
|
|
52
|
+
|
|
53
|
+
```
|
|
54
|
+
out/
|
|
55
|
+
clean/ audio that passed, or was repaired and re-checked
|
|
56
|
+
_error/ rejected files, in folders named by reason (low_snr/, clipping/, corrupt_or_unreadable/ ...)
|
|
57
|
+
_duplicates/ duplicates, copied here (nothing is deleted)
|
|
58
|
+
_logs/ audit_log_*.csv and .json (one row per file: what was found, what was fixed, why rejected), summary_*.md
|
|
59
|
+
```
|
|
60
|
+
|
|
61
|
+
## What it checks and repairs
|
|
62
|
+
|
|
63
|
+
| Checks | Repairs (only kept if a re-check shows they helped) |
|
|
64
|
+
|---|---|
|
|
65
|
+
| Unreadable, empty or truncated files | DC offset removal |
|
|
66
|
+
| Too short / too long for the purpose | De-clipping of short clipped runs (up to 8 ms, spline interpolation) |
|
|
67
|
+
| Signal-to-noise ratio (estimate) | Noise reduction (spectral subtraction, kept only if the SNR estimate improves) |
|
|
68
|
+
| Clipping, DC offset, loudness | Loudness normalisation, resampling, channel conversion to the purpose's targets |
|
|
69
|
+
| Silence: mostly-silent files, long gaps | Trimming silence at the edges |
|
|
70
|
+
| Lossy or low-pass sources (sharp spectral cliff) | |
|
|
71
|
+
| Exact duplicates, same-samples duplicates, near-duplicates (same take, different level or format) | |
|
|
72
|
+
| Multiple speakers (heuristic) | |
|
|
73
|
+
| Optional: transcript language, WER against Whisper, speaker/session train-validation split | |
|
|
74
|
+
|
|
75
|
+
Repair is classical signal processing, **not** machine learning.
|
|
76
|
+
|
|
77
|
+
## Limitations
|
|
78
|
+
|
|
79
|
+
Please read these before trusting a result.
|
|
80
|
+
|
|
81
|
+
- **Alpha, tested on synthetic data.** The test suite plants known defects (DC offset, clipping, duplicates, broken, empty and stereo files, other sample rates) and checks the routing, that originals are never modified, the local server's safety rules and the command line. It has *not* been validated on large real speech corpora; thresholds are reasoned defaults.
|
|
82
|
+
- **"Repaired" means "passed the re-check", not "restored".** De-clipping interpolates over saturated samples. On heavily clipped audio the re-check can pass even though the result is far from the original recording. Listen to repaired files.
|
|
83
|
+
- **Reverb (RT60) is a warning only.** Measured against synthetic rooms of known reverb time, the blind estimate could not tell dry from reverberant audio, so it never rejects a file.
|
|
84
|
+
- **Heuristics, not trained models:** the SNR estimate, the multi-speaker check and the near-duplicate threshold. Check their verdicts on your own data.
|
|
85
|
+
- **Music:** mid-track silence is not flagged, and moderate noise can go unnoticed.
|
|
86
|
+
- **Not yet measured:** whether cleaned data improves a trained model; speed and memory on very large datasets; real Whisper and Silero runs.
|
|
87
|
+
- The web app has **no login** and binds to `127.0.0.1` only. Do not expose it to a network.
|
|
88
|
+
|
|
89
|
+
## Development
|
|
90
|
+
|
|
91
|
+
```bash
|
|
92
|
+
git clone https://github.com/BoobalanArjunan/wavewash.git
|
|
93
|
+
cd wavewash
|
|
94
|
+
python3 -m venv .venv && source .venv/bin/activate
|
|
95
|
+
pip install -e ".[dev]"
|
|
96
|
+
python -m pytest -q
|
|
97
|
+
```
|
|
98
|
+
|
|
99
|
+
The front-end source is in `frontend/` (React + Vite). The built app is committed in `src/wavewash/static/`; to rebuild it: `cd frontend && npm ci && npm run build`, then copy `dist/` over `src/wavewash/static/`.
|
|
100
|
+
|
|
101
|
+
Documentation: [step-by-step guide](docs/STEP_BY_STEP.md) · [user manual](docs/USER_MANUAL.md)
|
|
102
|
+
|
|
103
|
+
## Contributing
|
|
104
|
+
|
|
105
|
+
Bug reports with a small example file are the most useful contribution. If WaveWash rejects a good file or passes a bad one, please open an issue with the log row for that file (from `_logs/audit_log_*.csv`).
|
|
106
|
+
|
|
107
|
+
## License
|
|
108
|
+
|
|
109
|
+
MIT
|
|
@@ -0,0 +1,85 @@
|
|
|
1
|
+
# WaveWash: step by step, from download to published
|
|
2
|
+
|
|
3
|
+
Everything below is for a Mac. Replace `BoobalanArjunan` with your own.
|
|
4
|
+
|
|
5
|
+
## Part A. Put it on your computer and try it
|
|
6
|
+
|
|
7
|
+
1. **Find the download.** Files you downloaded are in your `Downloads` folder.
|
|
8
|
+
You need `wavewash-source.zip`.
|
|
9
|
+
2. **Unzip it.** Double-click the zip. You get a folder called `wavewash-tool`.
|
|
10
|
+
3. **Move the folder** somewhere permanent, for example `Documents`.
|
|
11
|
+
4. **Open Terminal** (press Cmd+Space, type Terminal, press Enter).
|
|
12
|
+
5. **Go into the folder:**
|
|
13
|
+
`cd ~/Documents/wavewash-tool`
|
|
14
|
+
6. **Make a private Python space** (done once):
|
|
15
|
+
`python3 -m venv .venv`
|
|
16
|
+
then switch it on (every time you open a new Terminal):
|
|
17
|
+
`source .venv/bin/activate`
|
|
18
|
+
7. **Install WaveWash and the test tools:**
|
|
19
|
+
`pip install -e ".[dev]"`
|
|
20
|
+
8. **Run the tests.** This is the "does it work on my Mac?" check:
|
|
21
|
+
`python -m pytest -q`
|
|
22
|
+
You want to see `23 passed`. If something fails, copy the message and send it to me.
|
|
23
|
+
9. **Try the app:** `wavewash app`. Your browser opens. Choose an input folder with .wav files and
|
|
24
|
+
an output folder that is NOT inside the input folder, then click Run.
|
|
25
|
+
10. **Or use the command line:**
|
|
26
|
+
`wavewash run --input ~/Desktop/my_wavs --output ~/Desktop/my_wavs_clean/clean --purpose asr`
|
|
27
|
+
|
|
28
|
+
## Part B. Test it on real speech (the most important step)
|
|
29
|
+
|
|
30
|
+
11. Download a free sample of real speech, for example LibriSpeech **dev-clean** from openslr.org/12.
|
|
31
|
+
12. Run WaveWash on a few hundred files (step 10 with that folder).
|
|
32
|
+
13. Open the results. Look at the first 50 files it rejected and ask: *was it really bad?*
|
|
33
|
+
Write down: files checked, files rejected, how many of the rejects were really bad.
|
|
34
|
+
These real numbers go in the README. If many good files were rejected, tell me and we fix the settings.
|
|
35
|
+
|
|
36
|
+
## Part C. Put the code on GitHub
|
|
37
|
+
|
|
38
|
+
14. Make a free account at github.com.
|
|
39
|
+
15. Click **New repository**. Name it `wavewash`. Choose Public. Do not tick any extra files.
|
|
40
|
+
16. In Terminal, inside `wavewash-tool`:
|
|
41
|
+
```
|
|
42
|
+
git init
|
|
43
|
+
git add .
|
|
44
|
+
git commit -m "WaveWash 0.1.0a1"
|
|
45
|
+
git branch -M main
|
|
46
|
+
git remote add origin https://github.com/BoobalanArjunan/wavewash.git
|
|
47
|
+
git push -u origin main
|
|
48
|
+
```
|
|
49
|
+
17. In the README, replace `BoobalanArjunan` in the badge line.
|
|
50
|
+
18. On GitHub open the **Actions** tab. The tests now run by themselves on Mac, Windows and Linux.
|
|
51
|
+
Green tick means good. Red means something broke on that system, and we fix it.
|
|
52
|
+
|
|
53
|
+
## Part D. Publish to PyPI (so anyone can `pip install wavewash`)
|
|
54
|
+
|
|
55
|
+
18b. **Put your name on it.** Run this once, with your own details (the email is optional and becomes PUBLIC):
|
|
56
|
+
`python scripts/set_owner.py --name "Your Full Name" --github your-github-name`
|
|
57
|
+
It sets you as author and maintainer, fixes the project links and the licence holder, and replaces every
|
|
58
|
+
`BoobalanArjunan`. On PyPI you are the *owner* of the project because you upload it from your PyPI account.
|
|
59
|
+
|
|
60
|
+
19. Check the name is free: open pypi.org/project/wavewash. If the page says "not found", it is free.
|
|
61
|
+
20. Make accounts at **test.pypi.org** and **pypi.org** (turn on two-factor login on both).
|
|
62
|
+
On each, create an **API token** (Account settings, API tokens).
|
|
63
|
+
21. Build the files (inside `wavewash-tool`, with the venv switched on):
|
|
64
|
+
```
|
|
65
|
+
pip install build twine
|
|
66
|
+
python -m build
|
|
67
|
+
```
|
|
68
|
+
The files appear in the `dist` folder.
|
|
69
|
+
22. **Practice upload first** (uses the test site; username is `__token__`, password is your token):
|
|
70
|
+
`python -m twine upload --repository testpypi dist/*`
|
|
71
|
+
23. **Check it installs** in a fresh space:
|
|
72
|
+
```
|
|
73
|
+
python3 -m venv ~/try-wavewash && source ~/try-wavewash/bin/activate
|
|
74
|
+
pip install --index-url https://test.pypi.org/simple/ --extra-index-url https://pypi.org/simple wavewash
|
|
75
|
+
wavewash doctor
|
|
76
|
+
```
|
|
77
|
+
24. **Real upload.** You can't undo it, so only after step 23 works:
|
|
78
|
+
`python -m twine upload dist/*`
|
|
79
|
+
25. Anyone can now run `pip install wavewash`.
|
|
80
|
+
|
|
81
|
+
## What each part is for
|
|
82
|
+
- **Tests** protect users. A change that breaks something shows up before it reaches them.
|
|
83
|
+
- **Real-speech numbers** show it works on real data.
|
|
84
|
+
- **GitHub and the green tick** give people a reason to trust it.
|
|
85
|
+
- **TestPyPI first** because a mistake on real PyPI can't be erased.
|